Glama
benmonopoli

Greenhouse MCP

by benmonopoli

open-greenhouse-mcp

PyPI CI Python 3.10+ License: MIT open-greenhouse-mcp MCP server

Production-ready MCP server for Greenhouse, designed for recruiters and hiring teams.

Most Greenhouse MCP servers mirror the API endpoint by endpoint. This one is built for recruiting teams: safe defaults, role-based profiles, and workflow tools that turn multi-step API operations into single actions.

Choose a Profile

Profile

Tools

Can write?

Recommended for

read-only

104

No

First-time setup, reporting, hiring managers

recruiter

128

Yes (safe ops)

Day-to-day recruiting work

full

187

Yes (all)

Admins, ops, advanced automation

Harvest v3. Greenhouse retired Harvest v1/v2 on 31 Aug 2026. From 0.5.0 this server uses Harvest v3 with OAuth 2.0 credentials. Upgrading from 0.4 or earlier? See Migrating from v1/v2.

Related MCP server: Greenhouse MCP Server by CData

Quick Start

pip install open-greenhouse-mcp

Add to your MCP client config (Claude Desktop: ~/Library/Application Support/Claude/claude_desktop_config.json, Cursor: Settings > MCP):

{
  "mcpServers": {
    "greenhouse": {
      "command": "open-greenhouse-mcp",
      "env": {
        "GREENHOUSE_CLIENT_ID": "your-harvest-v3-client-id",
        "GREENHOUSE_CLIENT_SECRET": "your-harvest-v3-client-secret",
        "GREENHOUSE_TOOL_PROFILE": "read-only"
      }
    }
  }
}

Start in read-only mode to validate connectivity and tool behaviour, then switch to recruiter or full when you need write access.

Create the credentials in Greenhouse under Configure > Dev Center > API Credentials > Create new API credentials > Harvest V3 (OAuth), and grant the scopes for the tools you plan to use. The client secret is shown once. See Advanced Setup for how tokens and scopes work.

What You Can Ask

  • "Show me the pipeline for our Senior Engineer role"

  • "Who needs my attention this week?"

  • "What are our conversion rates for the Backend Intern role?"

  • "Find Sarah Chen and pull up her resume"

  • "Which sources are actually producing hires?"

  • "Bulk reject everything inactive for 30+ days on the Account Manager role"

  • "Screen this candidate for the Backend Engineer role — give me the full picture"

  • "Search our engineering pipelines for anyone with Rust and distributed systems experience"

  • "What new applications came in since yesterday?"

See more examples with full output.

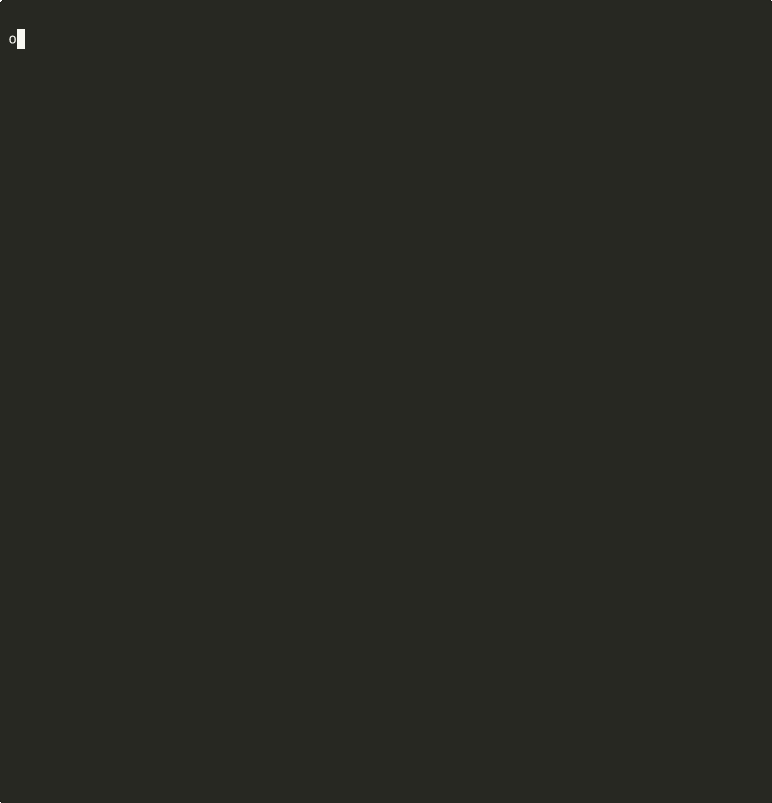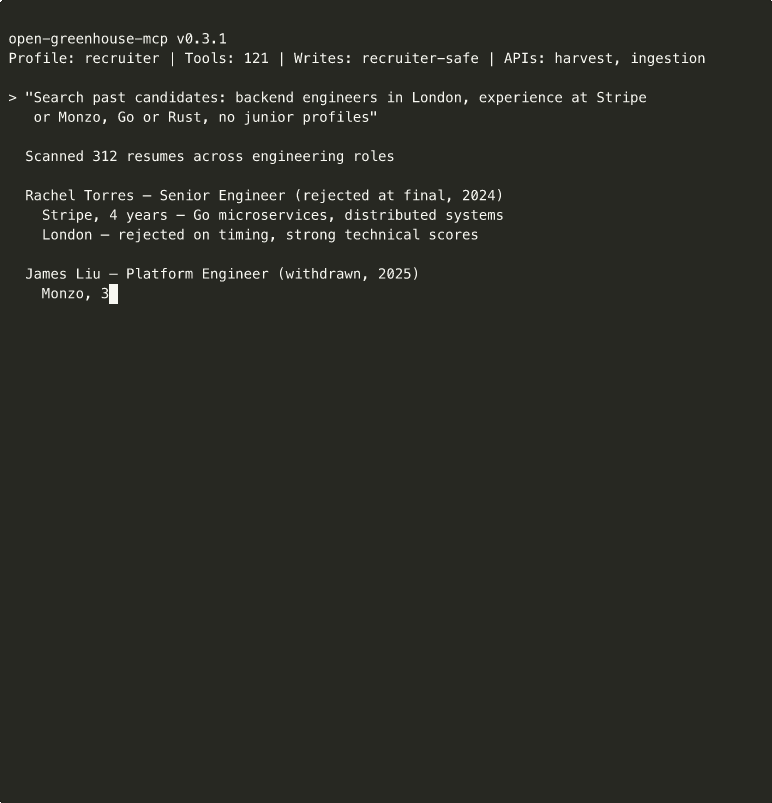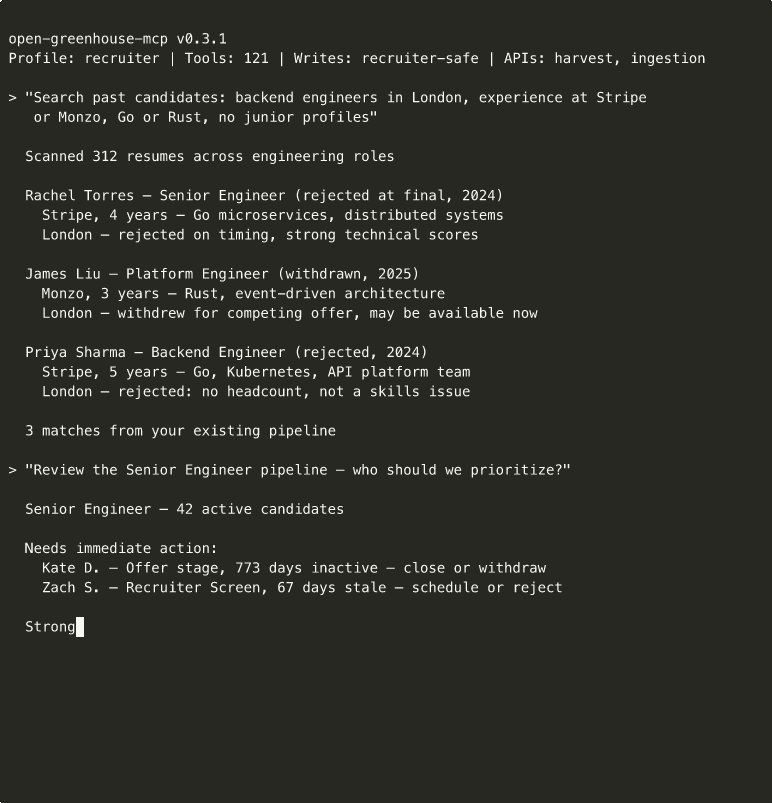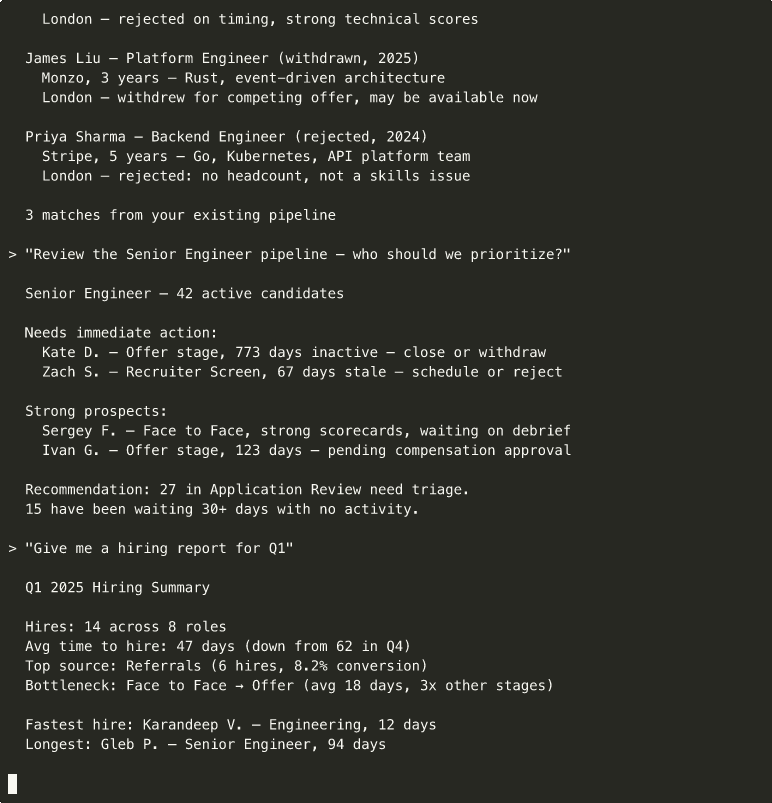
See it in action

Demo

Safety

  • Access is limited by the scopes on your Harvest v3 credential and the acting user's permissions

  • Read-only profile is recommended for first setup

  • Destructive actions require explicit IDs — the server never infers targets

  • Set GREENHOUSE_USER_ID and writes are made as that user (OAuth sub), so Greenhouse's audit trail shows who did what

  • Bulk actions are rate-limited to stay within API limits

Compatibility

Client

Status

Claude Desktop

Supported

Claude Code

Supported

Cursor

Supported

Transport

stdio

Python

3.10+

Startup

When the server starts, it logs its configuration:

open-greenhouse-mcp v0.5.0
Profile: recruiter | Tools: 128 | Writes: recruiter-safe | APIs: harvest-v3

What's Included

  • Screening & sourcing tools — 6 tools for candidate screening, resume search with boolean keywords, daily digest, and location detection

  • Recruiter workflow tools — 13 composite tools for pipeline views, analytics, search, and bulk operations

  • Harvest v3 API coverage — 154 tools across candidates, applications, jobs, offers, interviews, and more

  • Job Board API — 13 tools for public job listings and application submission

  • Optional webhooks and ingestion — 14 tools for event-driven workflows and partner integrations


Reference

Screening & Sourcing Tools

Tools for candidate evaluation and proactive talent search.

Tool

What it does

screen_candidate

Complete screening package — profile, resume text, location, screening answers, job description, history

fetch_new_applications

Applications since a date, grouped by job — the daily recruiter digest

scan_pipeline_resumes

Search resume text across pipelines with boolean keywords (required/preferred/exclude)

search_pipeline_candidates

Search pipelines by structured fields — title, company, education, experience, tags

scan_all_candidates

Database-wide candidate search by structured fields with date bounds

batch_read_resumes

Batch-fetch and extract resume text for multiple candidates

Composite Tools

High-level tools that combine multiple API calls into single operations.

Tool

What it does

pipeline_summary

Full pipeline view — candidates grouped by stage with names and days-in-stage

candidates_needing_action

Find stale applications and interviews missing scorecards

stale_applications

Applications with no activity for N days, sorted by stalest

pipeline_metrics

Conversion rates, hire/rejection rates, time-in-stage per stage

source_effectiveness

Which candidate sources produce the best hire rates

time_to_hire

Average, median, min, max days from application to hire

bulk_reject

Reject multiple applications in one call with rate-limit handling

bulk_tag

Tag multiple candidates in one call

bulk_advance

Advance multiple applications to next stage

get_bulk_request_status

Track a Greenhouse asynchronous bulk request (openings, custom field options)

search_candidates_by_name

Find candidates by first or last name

search_candidates_by_email

Look up a candidate by exact email

read_candidate_resume

Download and return a candidate's most recent resume

download_attachment

Download any Greenhouse attachment by URL

Profile Details

Recruiter includes all read tools, all screening/sourcing tools, all composite workflows, and recruiter-safe writes: reject, advance, hire, move, tag, notes, attachments, interviews, prospects, and bulk operations. It excludes job creation, user management, custom field configuration, candidate deletion, and webhook management.

Read-only skips all write operations. GREENHOUSE_READ_ONLY=true also works as a shorthand.

Configuration

Variable

Required

Description

GREENHOUSE_CLIENT_ID

Yes*

Harvest v3 OAuth client ID

GREENHOUSE_CLIENT_SECRET

Yes*

Harvest v3 OAuth client secret

GREENHOUSE_BOARD_TOKEN

Yes*

Job board URL slug. *Harvest credentials and/or a board token required

GREENHOUSE_USER_ID

No

Greenhouse user ID: writes are made as this user, and the tool profile is derived from their role

GREENHOUSE_TOOL_PROFILE

No

full (default), recruiter, or read-only (ignored when GREENHOUSE_USER_ID is set)

GREENHOUSE_BOARD_API_KEY

No

Job Board API key, for submitting applications through the board

GREENHOUSE_INGESTION_API_KEY

No

Ingestion API key, for partner candidate submission

GREENHOUSE_LOG_LEVEL

No

debug, info, warning (default), error

GREENHOUSE_LOG_FILE

No

Log file path (defaults to stderr)

Logging

Structured JSON logging for observability. Set GREENHOUSE_LOG_LEVEL=info to enable:

{"ts": "2026-04-14T12:31:58", "level": "info", "event": "api_call", "method": "GET", "url": "...", "status": 200, "latency_ms": 245.0}

More Documentation

  • API Reference — Full tool breakdown by category

  • Usage Examples — Real conversations with full output

  • Advanced Setup — Harvest v3 credentials and scopes, migrating from v1/v2, webhook receiver, ingestion API, board-token mode

  • Development — Contributing, testing, project structure

Feedback

License

MIT License -- Ben Monopoli. See LICENSE.

Available Tools

187 tools
add_attachmentA

Attach a file (resume, cover letter, etc.) to a candidate. Write operation.

Harvest v3 stores every attachment on an application, so this attaches to application_id if given, otherwise to the candidate's most recently active application (the response's application_id shows which). To get candidate_id: search_candidates_by_name. To choose the application, see get_candidate's applications array, or use add_attachment_to_application.

ParametersJSON Schema
NameRequiredDescriptionDefault
urlNoPublic URL to fetch the file from — provide this OR content, not both
typeYesType: 'resume', 'cover_letter', 'take_home_test', 'other', ... ('admin_only' = 'other' with admin-only visibility)
contentNoBase64-encoded file content — provide this OR url, not both
filenameYesFile name with extension, e.g. 'resume.pdf'
visibilityNoWho can see it: 'public', 'private', or 'admin_only'
candidate_idYesGreenhouse candidate ID
application_idNoApplication to attach to — omit to use the candidate's most recently active application

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the burden and does disclose the non-obvious default: attachments land on application_id if given, otherwise on the candidate's most recently active application, with the response's application_id indicating which. That is genuine behavioral value. It stops short of stating auth/permission requirements, failure modes, or the visibility default, so it isn't fully transparent.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the verb and the write-operation warning, and each following sentence carries routing or defaulting information. The hard line breaks make it slightly choppier than necessary, but there is no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values needn't be re-explained, and the description covers the mutation nature, the application-resolution default, and the sibling alternative. What remains thin is permission/auth context for a write operation with no annotations, but for a simple attach call the essentials are present.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so all seven parameters are already documented, including the url-vs-content exclusivity, type values, and application_id default. The description largely reiterates the application_id fallback and points at where to find candidate_id rather than adding new syntax or format detail. Baseline 3 is appropriate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Attach a file ... to a candidate') and immediately labels it a write operation. It distinguishes itself from the sibling add_attachment_to_application by naming that alternative explicitly, so an agent can pick the right tool without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives concrete when/when-not routing: use search_candidates_by_name to obtain candidate_id, and inspect get_candidate's applications array or switch to add_attachment_to_application when you need to pick the application. It also explains the omission case for application_id. Nothing is left to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

add_attachment_to_applicationA

Attach a file to a specific application. Write operation.

To find the application_id: search_candidates_by_name → get_candidate → match the application to the job. The file type is inferred from the filename extension. add_attachment does the same when you only know the candidate.

ParametersJSON Schema
NameRequiredDescriptionDefault
urlNoPublic URL to fetch the file from — provide this OR content, not both
typeYesType: 'resume', 'cover_letter', 'take_home_test', 'offer_letter', 'other', ... ('admin_only' = 'other' with admin-only visibility)
contentNoBase64-encoded file content — provide this OR url, not both
filenameYesFile name with extension, e.g. 'resume.pdf'
visibilityNoWho can see it: 'public', 'private', or 'admin_only'
application_idYesGreenhouse application ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden; it labels the operation a 'Write operation' and notes the type is inferred from the filename extension, which is useful. However it says nothing about permission/auth requirements, overwrite or duplicate-filename behavior, or whether the write is reversible. Adequate but thin for a mutation tool with zero annotation coverage.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Purpose is front-loaded in the first sentence, followed by the id-discovery workflow and the sibling note. Every sentence earns its place, though the arrow-chain workflow is slightly verbose.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation, and the schema fully documents parameters. The description supplies the two things structured fields can't: the id-discovery workflow and sibling disambiguation. Only the behavioral/permission context is missing for a write tool.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so all six parameters are already documented (including the url/content either-or and visibility values). The description adds only the filename-extension-to-type inference note, which is marginally useful but slightly at odds with 'type' being a required enum-like parameter. Baseline 3 is correct.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Attach a file to a specific application') and explicitly distinguishes itself from the sibling add_attachment ('does the same when you only know the candidate'). An agent can tell the two apart without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides a concrete workflow for obtaining the required application_id (search_candidates_by_name → get_candidate → match to job) and names the alternative tool plus the condition that selects it (candidate-only knowledge). Both when-to-use and the alternative are explicit.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

add_educationA

Add an education entry to a candidate. Write operation.

To find candidate_id: search_candidates_by_name. For school_id: list_schools; degree_id: list_degrees; discipline_id: list_disciplines (match by name — these are custom field option IDs in Harvest v3).

ParametersJSON Schema
NameRequiredDescriptionDefault
end_dateNoEnd date as 'YYYY-MM-DD'
degree_idNoDegree option ID — get from list_degrees
school_idNoSchool option ID — get from list_schools
start_dateNoStart date as 'YYYY-MM-DD'
candidate_idYesGreenhouse candidate ID
discipline_idNoDiscipline option ID — get from list_disciplines

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.6/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full behavioral burden. It discloses that this is a 'Write operation' and that IDs are custom field option IDs in Harvest v3, which is useful. But it omits required-permission/auth needs, duplicate-handling, reversibility, and which fields are mandatory beyond the schema's single required param.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Compact and front-loaded: the core action and 'Write operation' signal come first, followed by the ID lookup guidance. No wasted sentences, though the sentence fragments are slightly telegraphic.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation, and the schema fully documents parameters. The description supplies the lookup workflow needed to populate IDs. It is nearly complete for a write tool, with the only gap being mutation behavior (duplicates, effects on existing entries).

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the schema already documents every parameter, including date formats and the lookup source for each ID. The description's added value is mostly the Harvest v3 option-ID note, which is marginal. Baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource: 'Add an education entry to a candidate.' An agent immediately knows the action. However, it does not differentiate from the sibling remove_education or explain the relationship to other candidate sub-resource tools, so it falls short of a 5.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides concrete prerequisite chains for the ID parameters (search_candidates_by_name for candidate_id, list_schools/list_degrees/list_disciplines for the option IDs). This is clear usage context, though it offers no when-not-to-use guidance or alternatives among candidate-editing tools.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

add_email_note_to_candidateA

Log an email on a candidate's activity feed. Write operation.

Records an email exchange (to, from, cc, subject, body) as an activity entry. This logs the email — it does not send one. To get candidate_id: search_candidates_by_name.

ParametersJSON Schema
NameRequiredDescriptionDefault
ccNoCc email addresses
toYesRecipient email address
bodyYesEmail body content
from_YesSender email address
subjectYesEmail subject line
visibilityNo'public' (default), 'private', or 'admin_only'public
candidate_idYesGreenhouse candidate ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does disclose the key traits: it is a 'Write operation' and it records rather than sends an email. It omits permissions/authorization requirements and the side effects of the visibility setting, so it is not fully complete but adds meaningful behavioral context.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Purpose and write-nature are front-loaded in the first line, with supporting detail after. Slight redundancy between 'Log an email,' 'Records an email exchange,' and 'This logs the email,' but every line still carries a distinct point (purpose, fields, disambiguation, prerequisite).

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation, and the description covers the write semantics, the log-not-send distinction, and candidate_id acquisition. For a mutation tool with zero annotation coverage it is close to complete, lacking only permission/authorization context.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, and the description modestly exceeds it by listing the recorded fields (to, from, cc, subject, body) and explaining how to source the required candidate_id. It adds no format or validation detail beyond what the schema already documents.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (Log) and resource (an email on a candidate's activity feed) and immediately disambiguates the action with 'This logs the email — it does not send one,' which separates it from a real email-sending operation. An agent can identify the tool's intent without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives clear context (log vs. send) and a concrete prerequisite by routing the agent to search_candidates_by_name for the candidate_id. It does not explicitly contrast with the generic sibling add_note_to_candidate, so it stops short of full when-to-use guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

add_email_to_userA

Add a secondary email address to a Greenhouse user. Write operation.

To find user_id: list_users → match by name or email. The address stays unverified until the user confirms it.

ParametersJSON Schema
NameRequiredDescriptionDefault
emailYesEmail address to add
user_idYesGreenhouse user ID
send_verificationNoSend a verification email to the new address

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full behavioral burden. It discloses two useful traits: this is a write operation and the added address remains unverified until the user confirms. However, it omits permission requirements, uniqueness/conflict behavior, and reversibility, leaving meaningful gaps for a mutation tool.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, front-loaded with the operation and its write nature, followed by practical retrieval guidance and a behavioral note. No filler or repetition.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be explained. For a low-complexity write tool with no annotations, the description covers purpose, mutation nature, parameter sourcing, and verification behavior. Minor gaps remain around permissions and duplicate-email handling.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the schema already defines all three parameters. The description adds value by explaining how to source user_id and by clarifying the verification lifecycle that send_verification influences, going beyond the schema's terse labels.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific verb and resource: 'Add a secondary email address to a Greenhouse user.' This distinguishes it from sibling tools like add_email_note_to_candidate, which targets a different resource. An agent can identify the operation without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It explicitly tells the agent how to obtain the required user_id ('To find user_id: list_users → match by name or email'), which is actionable prerequisite guidance. It does not state when to use this tool versus alternatives like update_user, so it falls short of full when/when-not coverage.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

add_employmentA

Add an employment entry to a candidate. Write operation.

company_name, title and start_date are required by Greenhouse. To find candidate_id: search_candidates_by_name.

ParametersJSON Schema
NameRequiredDescriptionDefault
titleNoJob title at this employer
end_dateNoEnd date as 'YYYY-MM-DD' — omit for current role
start_dateNoStart date as 'YYYY-MM-DD'
candidate_idYesGreenhouse candidate ID
company_nameNoEmployer company name

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.8/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does disclose the key trait: 'Write operation.' It also reveals that Greenhouse requires company_name, title and start_date even though the schema marks them optional/null-defaulted — real behavioral information not visible in the schema. It omits what happens on duplicate entries or what the response contains, but the output schema covers returns.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Very short and front-loaded: purpose first, then the mutation nature, then the constraint and the lookup hint. Every sentence earns its place, though the line-break formatting is slightly choppy.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a write tool with no annotations, the description covers the mutation semantics, the effective required fields, and how to obtain the required candidate_id, and an output schema exists to explain returns. Remaining gaps (duplicate handling, permissions) are minor.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds meaning beyond the schema by stating that company_name, title and start_date are effectively required by Greenhouse despite the schema's null defaults and single-required-parameter list. That corrects a potentially misleading schema signal.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Add an employment entry to a candidate'), which cleanly separates it from sibling mutations like add_education and remove_employment. It does not explicitly name or contrast with those siblings, so it stops short of a 5.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides one concrete routing instruction for a prerequisite ('To find candidate_id: search_candidates_by_name'), which is genuinely useful. However, it gives no guidance on when to use this tool versus related tools (add_education, remove_employment) or any preconditions beyond the ID lookup.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

add_future_job_permissionA

Auto-grant a role on all future jobs. Write operation — admin only.

Users say "give Sarah recruiter access to all new Engineering jobs." For user_id: list_users. For user_role_id: list_user_roles. Scope with office_id (list_offices) or department_id (list_departments).

ParametersJSON Schema
NameRequiredDescriptionDefault
user_idYesGreenhouse user ID — get from list_users
office_idNoScope to jobs in this office — omit for all offices
user_role_idYesRole to auto-grant — get from list_user_roles
department_idNoScope to jobs in this department — omit for all departments

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.9/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full behavioral burden: it discloses that this is a write operation requiring admin privileges, which is genuinely useful. It stops short of saying what happens on duplicate grants, whether it affects existing jobs, or how the grant is reversed, leaving meaningful gaps for a mutation tool with zero annotation coverage.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the core operation and the admin-only constraint before any parameter detail, and every sentence is functional. The telegraphic one-line-per-parameter style is efficient but slightly abrupt, keeping it just below top marks.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Given a full output schema (return values need not be described), the description covers purpose, authorization level, scoping, and helper tools for every parameter. The only real omission is an explicit contrast with add_job_permission and the removal path for the grant.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the baseline is 3. The description's guidance for user_id/user_role_id/office_id/department_id largely restates what the schema already declares ('get from list_users', etc.); the only marginal addition is framing office_id and department_id as scoping levers.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb ('Auto-grant'), resource ('a role'), and scope ('on all future jobs'), which cleanly separates it from the sibling add_job_permission (current jobs) and remove_future_job_permission. An agent can identify the operation without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides a concrete user-utterance example that maps intent to this tool, plus explicit prerequisite lookups (list_users, list_user_roles, list_offices, list_departments) for building the call. It does not, however, state when NOT to use it versus add_job_permission, so the boundary is inferable rather than explicit.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

add_hiring_team_membersA

Add members to a hiring team without replacing existing ones. Write operation.

To find job_id: list_jobs → match by name. For member user_ids: list_users → match by name. Returns added and any per-member errors.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID
sourcersNoArray of {user_id: N} to add as sourcers
recruitersNoArray of {user_id: N, candidate_responsibility?: active|inactive|future|all} to add as recruiters
coordinatorsNoArray of {user_id: N, candidate_responsibility?: active|inactive|future|all} to add as coordinators
hiring_managersNoArray of {user_id: N} to add as hiring managers

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden, and it does useful work: it declares 'Write operation,' clarifies the additive (non-destructive) semantics, and discloses partial-failure behavior via per-member 'errors.' It omits permission/auth requirements, which is a minor gap for a mutation tool.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the core action and its key distinction, then the ID-lookup workflow and return shape. Every sentence earns its place with no redundancy.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Output schema exists, so return values need not be spelled out (though it helpfully summarizes 'added' and 'errors'). For a mutation tool with no annotations, it covers the essential write semantics and ID-sourcing prerequisites; only auth/permission context is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so all five parameters (job_id, sourcers, recruiters, coordinators, hiring_managers) are already documented, including the candidate_responsibility enum values. The description adds how to obtain IDs, but that is usage guidance rather than added meaning about the parameters themselves, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Add members to a hiring team') and immediately differentiates from the sibling replace_hiring_team with 'without replacing existing ones.' An agent can distinguish this from replace_hiring_team and remove_hiring_team_member without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives concrete guidance for sourcing required IDs ('list_jobs → match by name', 'list_users → match by name') and implies when this is the right tool via the additive-not-replacing framing. It stops short of explicitly naming replace_hiring_team as the alternative to use when replacement is intended, so it is strong but not fully explicit.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

add_job_permissionA

Grant a user a role on a specific job. Write operation — admin only.

Users say "give Sarah recruiter access to the Backend role." For user_id: list_users → match by name. For job_id: list_jobs → match by name. For user_role_id: list_user_roles → match by role name (role_type 'job_admin').

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesJob to grant access to — get from list_jobs
user_idYesGreenhouse user ID — get from list_users
user_role_idYesJob Admin role on this job — get valid IDs from list_user_roles

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.9/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full burden and does disclose the two most important traits: it is a write/mutation and it requires admin rights. It stops short of describing idempotency, behavior on existing grants, or what a failed grant returns.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the core action, then demotes the lookup mechanics to a secondary block. The 'give Sarah recruiter access' example earns its place by translating a natural user request into the tool call, though the id-resolution notes partially duplicate the schema.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a 3-parameter write tool with an output schema present, the description covers purpose, precondition, and argument sourcing, which is enough to invoke correctly. It need not explain return values, and the only real gap is sibling differentiation.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so each parameter is already documented in the schema (get from list_users / list_jobs / list_user_roles). The description mostly repeats that guidance; its only added value is the role_type 'job_admin' qualifier, so the baseline 3 is appropriate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (grant) and resource (a role on a job), so the operation is unambiguous. However, it does not distinguish itself from the near-identical sibling add_future_job_permission, so an agent can't tell the two apart from the description alone.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives a concrete routing workflow: use list_users to resolve user_id, list_jobs for job_id, and list_user_roles for user_role_id. It states the admin-only precondition but never says when to prefer this over add_future_job_permission or how it relates to remove_job_permission.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

add_job_post_locationA

Add a location to a job post. Write operation — admin only.

v3 job posts can have several locations. The post's job board must allow the location type. To find job_post_id: list_job_posts_for_job.

ParametersJSON Schema
NameRequiredDescriptionDefault
typeNo'free_text' (default), 'office', or 'custom_list'free_text
valueYesLocation value: the text (free_text), an office ID from list_offices (office), or a custom location ID from get_job_post_custom_locations (custom_list)
job_post_idYesJob post ID — get from list_job_posts

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.9/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does well: it discloses that this is a write operation and that it is admin-only, plus a validation constraint from the job board. It does not describe duplicate handling, failure modes, or reversibility, which keeps it below a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Four short lines, front-loaded with the action and the auth constraint, and no filler. The line breaks fragment related ideas slightly but nothing is wasted.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need no explanation, and the description covers purpose, mutation class, auth level, a precondition, and an ID-lookup path. It is close to complete; only edge-case behavior on duplicates or invalid location types is absent.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the baseline is 3. The description only touches job_post_id, and its suggestion ('list_job_posts_for_job') actually diverges from the schema's own guidance ('get from list_job_posts'), which muddies rather than clarifies the source tool.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description gives a specific verb and resource ('Add a location to a job post') and scopes it to v3 job posts that can have several locations. It is clearly distinct from remove_job_post_location and update_job_post, though it never names those siblings explicitly.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It supplies a concrete precondition ('The post's job board must allow the location type') and routes the agent to list_job_posts_for_job for obtaining job_post_id. There is no explicit when-not-to-use statement or comparison against the removal sibling, so it falls short of a 5.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

add_note_to_candidateA

Add a text note to a candidate's Notes tab / activity feed. Write operation.

Users say "add a note to Sarah's profile" or "log that I spoke with John." The note is authored by the configured Greenhouse user. To get candidate_id: search_candidates_by_name.

ParametersJSON Schema
NameRequiredDescriptionDefault
bodyYesNote text content (plain text)
visibilityNo'private' (default), 'public' (all users with access), or 'admin_only'private
candidate_idYesGreenhouse candidate ID
application_idNoOptionally anchor the note to one of the candidate's applications

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.8/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden. It discloses that this is a write operation and that the note is authored by the configured Greenhouse user, but says nothing about required permissions, editability/deletion, or rate limits.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Purpose is front-loaded in the first sentence, and each subsequent line (write-op flag, authorship, ID acquisition) earns its place. Slightly fragmented across lines, but no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With an output schema present, return values need not be explained, and the description covers purpose, authorship, and ID lookup for a write tool. The main gap is the absence of permission/authorization context, which matters for a mutation with no annotations.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the schema already documents all four parameters and the baseline is 3. The description adds real value by telling the agent how to source candidate_id via search_candidates_by_name, which is beyond what the schema states.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Add a text note to a candidate's Notes tab / activity feed'), which is clear. It distinguishes itself from the text-note family by specifying 'text note' and naming the destination surface, though it never explicitly rules out the close sibling add_email_note_to_candidate.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides concrete natural-language triggers ('add a note to Sarah's profile', 'log that I spoke with John') and points to search_candidates_by_name for obtaining candidate_id, which gives clear context. It lacks any explicit when-not or alternative-tool exclusion guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

add_prospectA

Create a sourced prospect in a prospect pool. Write operation.

Users say "add this person as a prospect for the Engineering pool." Unlike create_candidate with a job_id, this creates a prospect not yet in an active job pipeline. For pool/stage IDs: list_prospect_pools → match by name. To later convert to an active candidate, use convert_prospect.

ParametersJSON Schema
NameRequiredDescriptionDefault
titleNoCurrent job title
companyNoCurrent company name
job_idsNoJobs this prospect is being considered for — from list_jobs
last_nameYesProspect's last name
first_nameYesProspect's first name
phone_numbersNoArray of {value: '+1...', type: 'mobile'|'home'|'work'}
email_addressesNoArray of {value: 'x@y.com', type: 'personal'|'work'}
prospect_pool_idNoProspect pool to add to — get from list_prospect_pools
prospect_owner_idNoUser ID who owns this prospect — get from list_users
prospect_stage_idNoStage within the prospect pool

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden. It does disclose the key trait 'Write operation' and clarifies the object is a prospect not yet in an active pipeline. However it omits permission requirements, behavior on duplicate prospects, and any error/validation semantics that a mutation tool should surface.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Content is front-loaded with the operation and mutation flag, and each subsequent sentence adds routing value. Slightly verbose with a redundant restatement of the ID-sourcing already in the schema, but no dead weight.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be explained. Combined with 100% schema coverage, the description supplies the routing, mutation flag, and ID resolution an agent needs. Missing only edge-case behavior (duplicates, permissions) for full completeness.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so each of the 10 parameters is already documented in the schema (including the list_prospect_pools / list_users sourcing hints). The description's 'For pool/stage IDs: list_prospect_pools → match by name' largely restates that, adding little new meaning. Baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Create a sourced prospect in a prospect pool') and explicitly distinguishes itself from create_candidate (job_id → pipeline) and convert_prospect. An agent can select this correctly without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives explicit when-to-use ('Users say add this person as a prospect for the pool'), when-not (unlike create_candidate with job_id), the ID-resolution path (list_prospect_pools → match by name), and the follow-up tool (convert_prospect). Routing is fully specified.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

add_tag_to_candidateA

Apply a tag to a candidate. Write operation.

Users say "tag Sarah as 'referred'" or "mark John as strong hire." For candidate_id: search_candidates_by_name. For tag_id: list_tags → match by name. For bulk tagging, use bulk_tag instead.

ParametersJSON Schema
NameRequiredDescriptionDefault
tag_idYesTag ID to apply — get from list_tags or create_tag
candidate_idYesGreenhouse candidate ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full burden. It explicitly labels the operation as 'Write operation', which is useful, and implies tags must already exist (via 'list_tags → match by name'). However, it does not disclose idempotency, behavior on duplicate tags, permissions required, or error conditions, leaving notable gaps in behavioral transparency.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The description is compact and front-loaded: a one-sentence purpose, followed by terse usage examples, ID resolution tips, and a single alternative tool mention. Every sentence earns its place with no redundancy.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a simple two-parameter write operation with an output schema present, the description covers purpose, usage, ID resolution, and alternatives. It does not explain edge cases like duplicate tags or required permissions, but these are not essential for basic invocation. The explicit 'Write operation' flag partially compensates for missing annotations.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% with descriptions for both candidate_id and tag_id. The description adds value beyond the schema by recommending how to find each ID (search_candidates_by_name, list_tags → match by name) and providing real-world usage phrasing that helps the agent map user intent to parameters.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description clearly states 'Apply a tag to a candidate' with a specific verb and resource. It also distinguishes itself from the sibling tool bulk_tag by explicitly directing bulk tagging elsewhere, and the name itself differentiates from add_note_to_candidate.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description provides explicit when-to-use guidance with natural language examples ('tag Sarah as referred'), how to resolve candidate_id and tag_id via search_candidates_by_name and list_tags, and an explicit exclusion for bulk tagging ('use bulk_tag instead'). This fully covers usage context and alternatives.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

advance_applicationA

Move a candidate forward one stage in their job pipeline. Write operation.

Users say "advance Sarah to the next stage" or "move John forward." To get the application_id: search_candidates_by_name → get_candidate → match the application to the job. from_stage_id must be the application's current job_interview_stage_id (Greenhouse rejects stale moves); omit it and it is looked up for you. Omit to_stage_id to advance to the natural next stage. To skip stages, use move_application_same_job. For bulk advancing, use bulk_advance.

ParametersJSON Schema
NameRequiredDescriptionDefault
to_stage_idNoTarget stage — from list_job_stages_for_job. Omit for next stage
from_stage_idNoCurrent job_interview_stage_id (from get_application). Omit to look it up automatically
application_idYesGreenhouse application ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does disclose meaningful behavior: it flags 'Write operation', warns that Greenhouse rejects stale moves unless from_stage_id matches the current job_interview_stage_id, and notes that omitting from_stage_id triggers an automatic lookup. It stops short of covering permission/auth requirements or failure modes beyond the staleness check, so it is strong but not exhaustive.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the core action in the first sentence, then layers the ID-resolution workflow, parameter constraints, and alternatives. Every sentence earns its place; the quoted user utterances map directly to routing decisions rather than being filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a 3-param write tool with no annotations but with an output schema (so return values need no explanation) and full schema coverage, the description supplies the workflow, the key failure constraint, and the sibling alternatives. It omits permission/auth context and non-staleness error behavior, leaving a small but real gap.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds real semantic value beyond the schema: from_stage_id must equal the application's current job_interview_stage_id or the write is rejected, and omitting it is auto-resolved; omitting to_stage_id advances to the natural next stage. That constraint-level detail exceeds what the property descriptions state.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource+scope: 'Move a candidate forward one stage in their job pipeline.' It explicitly names and distinguishes the two nearest siblings, move_application_same_job (skipping stages) and bulk_advance (bulk), so an agent can route correctly without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides explicit when-to-use via user utterance examples ('advance Sarah to the next stage'), states the preconditions for the key input (how to obtain application_id via search_candidates_by_name → get_candidate → match to job), and names alternatives with the condition that selects them (skip stages, bulk advancing). Nothing is left to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

anonymize_candidateA

Anonymize a candidate's personal data for GDPR/privacy compliance. Write operation.

Scrubs the listed data groups (name, emails, phones, attachments, notes, etc.) while preserving the record and hiring activity for reporting. Irreversible; large scopes complete asynchronously. Greenhouse requires an explicit list of fields — confirm with the user what to remove. To get the candidate_id: search_candidates_by_name → get_candidate.

ParametersJSON Schema
NameRequiredDescriptionDefault
fieldsYesData groups to scrub (at least one), e.g. ['full_name', 'email_addresses', 'phone_numbers', 'addresses', 'attachments', 'notes', 'education', 'employment', 'scorecards_and_interviews', 'offers']
candidate_idYesGreenhouse candidate ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.5/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does well: it declares a write operation, irreversibility, asynchronous completion for large scopes, and the requirement for an explicit field list. It stops short of stating permission/auth requirements or rate limits.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Purpose is front-loaded in the first sentence, followed by the critical constraints (irreversible, async, explicit fields) in order of importance. Every sentence carries operational weight with no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a two-parameter destructive mutation with an output schema present, the description covers everything an agent needs to act correctly: what gets scrubbed, what is preserved, reversibility, async behavior, and how to source the ID.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so both parameters are already documented and the field list is enumerated in the schema. The description still adds value by warning that Greenhouse requires an explicit field list, advising confirmation with the user, and showing the search_candidates_by_name → get_candidate path for candidate_id.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific verb+resource ('Anonymize a candidate's personal data') with an explicit compliance motivation (GDPR/privacy). It distinguishes itself from the sibling delete_candidate by stating it preserves the record and hiring activity for reporting.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It gives clear context (GDPR/privacy compliance, the need to confirm scope with the user) and a navigation path to obtain candidate_id. It does not explicitly name delete_candidate as the alternative for a hard removal, leaving that contrast to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

batch_read_resumesA

Download and extract resume text for a list of candidates. Read-only.

Use after narrowing candidates with other sourcing tools. Pass candidate_ids from search_pipeline_candidates or scan_all_candidates. Uses each candidate's most recent resume across all their applications. Full resume text reveals career trajectory, scope of work, and skills that structured data doesn't capture.

ParametersJSON Schema
NameRequiredDescriptionDefault
candidate_idsYesCandidate IDs to fetch resumes for
max_candidatesNoMaximum resumes to download

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden, and it does disclose two meaningful traits: the operation is 'Read-only' and it selects each candidate's most recent resume across all applications. It does not cover rate limits, permissions, or failure behavior for large batches, so it stops short of full disclosure.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Four short sentences, front-loaded with the verb and read-only note, then usage, then behavior. The final sentence justifies why the tool is worth calling rather than padding.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation, and the description covers purpose, preconditions, and resume-selection semantics. It omits auth/permission requirements and any limits on batch size behavior, a minor gap for a batch download tool with no annotations.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3. The description adds real meaning beyond the schema by stating where candidate_ids should originate (search_pipeline_candidates or scan_all_candidates), which guides correct invocation. It says nothing extra about max_candidates, which the schema already documents.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb pair (download and extract) and resource (resume text) scoped to 'a list of candidates,' which distinguishes it from the singular read_candidate_resume sibling. An agent can tell what it produces without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly says to use it 'after narrowing candidates with other sourcing tools' and names the two siblings that produce valid candidate_ids (search_pipeline_candidates, scan_all_candidates). This is a clear precondition plus a routing rule, not vague guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

bulk_advanceA

Advance multiple applications to the next stage. Write operation — rate-limited.

Users say "move everyone past phone screen forward." Get application_ids from pipeline_summary or list_applications. Each application moves from its current stage to the next one on its job's interview plan. Optionally pass from_stage_id (list_job_stages_for_job → match by name) to only advance applications currently in that stage — others are skipped. Rejected, hired or prospect applications are skipped. Processes sequentially with rate-limit delays.

ParametersJSON Schema
NameRequiredDescriptionDefault
from_stage_idNoOnly advance apps currently in this job interview stage (list_job_stages_for_job → match by name); omit to advance each from its current stage
application_idsYesApplication IDs to advance

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.7/5.0
Behavior5/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full behavioral burden and does so: it declares this is a write operation, that it is rate-limited, that processing is sequential with rate-limit delays, and enumerates the skip rules (rejected/hired/prospect apps, and apps not currently in from_stage_id).

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the operation and its write/rate-limit nature, then adds usage, mechanics, and edge cases in compact sentences with no filler. Every sentence conveys a distinct fact an agent needs.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Both parameters are documented, an output schema exists so return values need no explanation, and the description covers the mutation semantics, rate limiting, and skip behavior for a bulk write tool with no annotations.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description goes further by explaining the skip consequence of from_stage_id ('others are skipped'), how to derive it (list_job_stages_for_job, match by name), and where to obtain application_ids, which the schema does not say.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (advance), resource (applications), and scope (multiple / bulk) in the first clause, which cleanly separates it from the single-application sibling advance_application. It also names the exact state transition: each app moves to the next stage on its job's interview plan.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives concrete routing for inputs ('Get application_ids from pipeline_summary or list_applications'), a real user phrasing that triggers it, and a clear condition for when to use from_stage_id. It never explicitly says to use advance_application for a single app, but the bulk framing and the source-tool pointers cover the practical decision.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

bulk_create_job_openingsA

Create many openings in one asynchronous request. Write operation — admin only.

Returns bulk_action_uuid and status; check progress with get_bulk_request_status. For one opening use create_job_opening.

ParametersJSON Schema
NameRequiredDescriptionDefault
openingsYesArray of {job_id (required), opening_id (external ID, optional), custom_fields (optional)}
callback_urlNoOptional HTTPS URL Greenhouse POSTs to when done

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does disclose meaningful traits: it is a write operation, it requires admin privileges, and it is asynchronous with a deferred result. It omits batch-size limits, partial-failure semantics, and idempotency, which matter for a bulk mutation, so it falls short of a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, front-loaded with the core operation, then permissions, then return/follow-up and the alternative. Every sentence earns its place with no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For an async bulk mutation, the description covers the operation, the auth requirement, the return artifact, and the polling tool, and an output schema exists so return structure needn't be spelled out. Missing only edge-case behavior such as partial failures or limits, which keeps it from a 5.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so both openings and callback_url are already documented in the schema, including the nested field breakdown and the callback's purpose. The description adds no syntax or format detail beyond the schema, which is the expected baseline when the schema does the work.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource with scope ('Create many openings in one asynchronous request'), and explicitly contrasts itself with the single-item sibling create_job_opening. An agent can distinguish it from bulk_update_job_openings and create_job_opening without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly routes the agent in both directions: 'For one opening use create_job_opening' for the alternative, and 'check progress with get_bulk_request_status' for the follow-up. The when-to-use condition (multiple openings, async) is stated rather than implied.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

bulk_delete_job_openingsA

Delete many openings in one asynchronous request. Destructive — cannot be undone.

Returns bulk_action_uuid; check progress with get_bulk_request_status.

ParametersJSON Schema
NameRequiredDescriptionDefault
opening_idsYesGreenhouse opening IDs to delete — from list_job_openings
callback_urlNoOptional HTTPS URL Greenhouse POSTs to when done

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does well: it flags the operation as destructive and irreversible, states it is asynchronous, and names the returned bulk_action_uuid plus the follow-up tool. It omits permission/auth requirements and rate limits, which would round it out.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two compact sentences, zero waste, with the destructive/irreversible warning front-loaded ahead of the follow-up guidance.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a destructive async bulk tool with an output schema present, the description supplies the essential context: irreversibility, async semantics, and the progress-check sibling. Nothing needed to call it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so both parameters (opening_ids, callback_url) are already documented in the schema. The description adds no syntax or format detail beyond what is structured, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (Delete) plus resource (openings) plus scope (many, in one asynchronous request). The bulk/async framing cleanly separates it from the singular delete_job_opening and from bulk_create/update_job_openings siblings.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Implies bulk use and explicitly routes the agent to get_bulk_request_status for progress. It doesn't name delete_job_opening as the alternative for single deletions, so the when-not case is left to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

bulk_rejectA

Reject multiple applications in one call. Write operation — rate-limited.

Users say "reject everyone who's been inactive for 30 days on the Backend role." First use stale_applications to identify the targets, then pass their application_ids here. rejection_reason_id is required: list_rejection_reasons → match by name. To email candidates, set rejection_email=true and pass email_template_id (list_email_templates). Processes sequentially with rate-limit delays.

ParametersJSON Schema
NameRequiredDescriptionDefault
notesNoInternal rejection notes (not sent to the candidate)
application_idsYesApplication IDs to reject — get from list_applications or pipeline_summary
rejection_emailNoSend a rejection email to each candidate
email_template_idNoRejection email template — list_email_templates → match by name
email_from_user_idNoUser the rejection email is sent from — list_users
rejection_reason_idYesRejection reason ID (required) — get from list_rejection_reasons

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.5/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the burden well: it declares this is a write operation, that it is rate-limited, and that it processes sequentially with rate-limit delays. It also distinguishes internal notes from candidate-facing email. It stops short of stating irreversibility or required permissions.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Purpose is front-loaded, followed by the write/rate-limit caveat and a concrete user-utterance example that aids semantic matching. Every sentence either instructs or routes; nothing is padding.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a 6-parameter bulk mutation with an output schema already present, the description covers prerequisites, the multi-step ID resolution, email behavior, and rate-limit processing. Nothing an agent needs to call it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds genuine resolution guidance — rejection_reason_id is required and must be looked up via list_rejection_reasons and matched by name, and email_template_id via list_email_templates. This goes beyond restating the schema.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ("Reject multiple applications in one call") and its plural scope distinguishes it from the singular reject_application sibling. An agent can identify the operation immediately.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives a concrete routing workflow: use stale_applications to find targets, then pass application_ids here, and it shows a real-world trigger ("reject everyone inactive for 30 days"). It never explicitly contrasts against reject_application for a single ID, leaving that boundary to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

bulk_tagA

Tag multiple candidates in one call. Write operation — rate-limited.

Users say "tag all the candidates from the hiring event." Pass candidate_ids from search or pipeline tools and a tag_name (created automatically if new). Candidates who already have the tag are skipped. Processes sequentially with rate-limit delays.

ParametersJSON Schema
NameRequiredDescriptionDefault
tag_nameYesTag name to apply — created on-the-fly if it doesn't exist
candidate_idsYesCandidate IDs to tag — get from list_candidates or search

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.8/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does well: it flags that this is a write operation, that it is rate-limited, that existing tags cause candidates to be skipped (idempotent-ish behavior), and that processing is sequential with delays. It omits permission/auth requirements and any failure semantics for invalid IDs.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the core action and the write/rate-limit caveat, then adds only the details an agent needs. Short, well-ordered sentences with no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Output schema exists, so return values need not be explained, and both params plus the mutation/rate-limit behavior are covered. Minor gaps remain around permissions and error handling for invalid candidate IDs, but the definition is sufficient to call correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so both parameters are already documented in the schema (including on-the-fly tag creation and where to source IDs). The description largely restates this, adding only 'pipeline tools' as an extra ID source, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (tag) plus resource (candidates) and scope (multiple in one call), which implicitly distinguishes it from the single-target sibling add_tag_to_candidate. It does not explicitly name that alternative, so it falls short of a 5.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives a source hint ('pass candidate_ids from search or pipeline tools') and a representative user utterance, which helps routing. However, it never explicitly states when to use this bulk tool versus add_tag_to_candidate, nor any exclusions or prerequisites, so usage is only implied.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

bulk_update_job_openingsA

Update or close many openings in one asynchronous request. Write operation.

Use to close all of a job's openings at once (list_job_openings → ids). Returns bulk_action_uuid; check progress with get_bulk_request_status.

ParametersJSON Schema
NameRequiredDescriptionDefault
openingsYesArray of {id (Greenhouse opening ID, required), status ('open'/'closed'), close_reason_id, opening_id (external ID), target_start_on, custom_fields}
callback_urlNoOptional HTTPS URL Greenhouse POSTs to when done

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the burden and does well: it declares this a write operation, flags the asynchronous execution model, and names the returned bulk_action_uuid with a pointer to get_bulk_request_status for progress. It omits permission requirements and reversibility, keeping it below 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, front-loaded with the core action, then usage, then return/polling guidance. Every sentence earns its place with no redundancy.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a no-annotation mutation tool with an output schema, the description covers the essentials: what it does, the async flow, and how to check progress. It leaves permission requirements and the scope of updatable fields to the schema, which is acceptable given the rich input schema.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the schema already documents both the openings object and callback_url. The description only adds a workflow hint on where to get ids; it adds no syntax or field-level meaning beyond the schema, matching the baseline 3.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Update or close many openings') plus the async batch nature, which naturally separates it from bulk_create_job_openings and bulk_delete_job_openings. It does not explicitly name those siblings, so it falls just short of a 5.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives a concrete use case ('close all of a job's openings at once') and a workflow hint ('list_job_openings → ids') for sourcing input. However it names no alternatives or when-not conditions, so it stops at clear context rather than explicit routing.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

candidates_needing_actionA

Find candidates that need attention — stale apps, missing scorecards. Read-only.

Users say "what needs my attention?" or "who's been sitting too long?" Pass job_id for one job (list_jobs → match by name) or omit for all active applications. Returns stale applications sorted by urgency and interviews awaiting feedback, with the interviewers whose scorecards are still missing.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idNoFilter to one job — list_jobs → match by name
stale_daysNoDays without activity to flag as stale

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the safety burden and does so by declaring 'Read-only' — the single most important behavioral fact. It also previews what comes back (stale applications sorted by urgency, interviews awaiting feedback, interviewers with missing scorecards). It stops short of permissions, pagination, or result limits, which an unannotated tool arguably should mention.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the one-line purpose, then usage phrasings, then parameter guidance, then return shape — a sensible ordering with no filler. The only mild redundancy is repeating the 'list_jobs → match by name' mapping already present in the schema.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so the description needn't explain return values, yet it does anyway, and it covers purpose, scoping, and both parameters. The remaining gap is the unaddressed relationship to the very similar 'stale_applications' sibling, which could cause an agent to pick the wrong tool.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds real meaning the schema lacks: omitting job_id returns 'all active applications' (the schema only shows a null default), and it explains how to obtain a job_id via list_jobs. stale_days is left to the schema, which is acceptable since the schema documents it.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description gives a specific verb and resource — 'find candidates that need attention' — and enumerates the concrete cases it covers (stale apps, missing scorecards, interviews awaiting feedback), which is far more than a restatement of the name. It does not, however, distinguish itself from the close sibling 'stale_applications' or 'pipeline_summary', leaving the agent to infer the boundary.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Usage context is made explicit through the user-intent phrasings ('what needs my attention?', 'who's been sitting too long?'), which tells an agent when this tool matches a request. It also explains the two scoping modes (job_id vs omit). What's missing is any when-not-to-use guidance or an explicit pointer to the overlapping sibling tools.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

change_user_permission_levelA

Demote a user to Basic, revoking all their permissions. Write operation — admin only.

Removes the user's Site Admin status and every job-level permission (Greenhouse "revoke permissions"). Promoting a user is not possible via the API — grant job roles with add_job_permission instead. To find user_id: list_users → match by name or email.

ParametersJSON Schema
NameRequiredDescriptionDefault
user_idYesGreenhouse user ID
permission_levelNoMust be 'basic' — the only change Greenhouse supports via the APIbasic

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does well: it declares this is a write operation, that it is admin-only, and that it destroys Site Admin status plus all job-level permissions. It stops short of stating reversibility or whether any residual access remains, which is a minor gap for a destructive permission change.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the effect and safety constraint, then alternatives, then parameter discovery. Well organized across a few short lines, though slightly more verbose than strictly necessary.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Covers the mutation's destructive scope, authorization requirement, the impossibility of the inverse operation, and the alternative tool, while an output schema handles return values. An agent has everything needed to decide and call correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% so the baseline is 3, but the description adds value the schema does not: how to locate user_id (list_users, match by name or email). The permission_level constraint is already fully documented in the schema, so this is additive rather than redundant.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource (demote a user to Basic) and immediately names the exact effect: removal of Site Admin status and every job-level permission. It is clearly distinguishable from siblings like add_job_permission or update_user, which the description explicitly contrasts.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicit when-to-use (demoting a user, admin only), explicit when-not (promotion is not possible via the API), and names the alternative (grant job roles with add_job_permission). It even supplies the discovery path for the required user_id via list_users.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

convert_prospectA

Convert a sourced prospect into an active candidate on a job. Write operation.

Users say "move this prospect into the Backend pipeline." The prospect's application_id comes from their prospect record (get_candidate → applications array, where prospect is true). Target job_id from list_jobs → match by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesJob ID to apply the prospect to — get from list_jobs
application_idYesProspect application ID to convert
initial_stage_idNoStarting interview stage on that job (list_job_stages_for_job) — defaults to the first stage

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.8/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden. It does disclose 'Write operation' and that the prospect becomes an active candidate on a target job, but says nothing about permissions required, reversibility, whether the prospect record is removed, or side effects such as notifications. Useful but incomplete for an unannotated mutation.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Purpose and write-nature are front-loaded in the first two short sentences, and the remaining sentences give input-sourcing workflow. The 'Users say...' sentence is slightly filler but does map natural language intent to the tool, so it earns most of its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness3/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need not be explained, but for an unannotated write tool the description omits key operational context: side effects of conversion, error cases, and prerequisite state (e.g., prospect must exist and not already be converted). Adequate rather than complete.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, and the schema already says job_id comes 'from list_jobs'. The description adds real meaning by specifying that application_id is the prospect's application (identified via get_candidate where prospect is true), but it leaves initial_stage_id entirely to the schema.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Convert a sourced prospect into an active candidate on a job'), which is distinguishable from siblings like create_candidate, create_application, and advance_application. An agent can tell what this does and that it is a state transition, not a creation.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description gives practical routing context — the user phrasing to expect ('move this prospect into the Backend pipeline'), plus where the two required IDs come from (get_candidate → applications array with prospect=true; list_jobs → match by name). It does not state when NOT to use this versus the many application/candidate siblings, so it stops short of full when/when-not guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

create_applicationA

Apply an existing candidate to a job. Write operation.

Users say "add Sarah to the Backend Engineer role." Resolve both IDs first: candidate — search_candidates_by_name; job — list_jobs → match by name. The candidate must already exist (create_candidate can also create the candidate and application in one step). Attachments are uploaded to the new application afterwards; their results are under attachment_results. For sourced prospects, use add_prospect. For partner submissions, use post_candidate.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesID of the job to apply to — get from list_jobs
source_idNoCandidate source ID — get from list_sources
attachmentsNoResume/files to add after creating: [{filename, type, content (base64) or url}]
referrer_idNoReferrer record ID to credit for this application
candidate_idYesID of an existing candidate — use create_candidate first if needed
recruiter_idNoUser ID of the recruiter — get from list_users
coordinator_idNoUser ID of the coordinator — get from list_users
initial_stage_idNoStarting interview stage ID (list_job_stages_for_job) — defaults to the first stage

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does well: it declares this is a write, states attachments are uploaded after creation and returned under attachment_results, and notes initial stage defaults to the first stage. It stops short of auth/permission requirements or idempotency behavior, so it is strong but not exhaustive.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the core action and write nature in the first two lines, then layers resolution steps, the existence precondition, attachment behavior, and sibling alternatives. Every sentence earns its place; the line breaks aid scanning without padding.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For an 8-parameter write tool with an output schema and no annotations, the description covers the workflow, preconditions, side effects (attachments), and routing to alternatives. It could say more about permission requirements or what the returned application record contains, but nothing essential to correct invocation is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds real meaning: it explains how to resolve candidate_id and job_id (which lookup tools to use) and clarifies that attachments are applied post-creation with results under attachment_results. That is workflow context the schema does not supply.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ("Apply an existing candidate to a job") and immediately labels it a write operation. It distinguishes itself from near-neighbors by naming create_candidate, add_prospect, and post_candidate as different flows, so an agent can route without opening schemas.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives explicit preconditions and resolution steps: candidate must already exist, resolve candidate via search_candidates_by_name and job via list_jobs. It also names the alternatives and the condition that selects each (create_candidate for one-step creation, add_prospect for sourced prospects, post_candidate for partner submissions).

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

create_candidateA

Create a new candidate record, optionally applying them to a job. Write operation.

Users say "add a new candidate — Jane Doe at Acme Corp for the Backend role." Check for duplicates first with search_candidates_by_name or search_candidates_by_email. Pass job_id (list_jobs) to create the application in the same call; the response then has both candidate and application. Without job_id, use create_application afterwards. For sourced prospects, use add_prospect instead.

ParametersJSON Schema
NameRequiredDescriptionDefault
tagsNoCandidate tag names to apply
titleNoCurrent job title
job_idNoAlso apply them to this job (list_jobs) in the same call
companyNoCurrent company name
addressesNoArray of {value: '123 Main St', type: 'home'|'work'|'other'}
last_nameYesCandidate's last name
source_idNoApplication source ID (list_sources) — needs job_id
first_nameYesCandidate's first name
referrer_idNoReferrer record ID — needs job_id
recruiter_idNoRecruiter user ID (list_users) — needs job_id
custom_fieldsNoArray of {custom_field_id (or name_key), value} — get field IDs from list_custom_fields
phone_numbersNoArray of {value: '+1...', type: 'mobile'|'home'|'work'|'other'}
coordinator_idNoCoordinator user ID (list_users) — needs job_id
email_addressesNoArray of {value: 'x@y.com', type: 'personal'|'work'|'other'}
initial_stage_idNoStarting interview stage (list_job_stages_for_job) — needs job_id

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden, and it does disclose the mutation nature ('Write operation'), the response shape when job_id is passed, and the duplicate-check prerequisite. It stops short of covering permissions/authorization requirements or what happens if a duplicate is detected (hard error vs. soft match).

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads purpose and write-type in the first line, then adds usage flow. The embedded user quote is slightly verbose but earns its place by illustrating the job_id-in-the-same-call pattern; otherwise tight.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return-value detail is unnecessary, and the description covers the create/apply fork, the duplicate-check step, and the sibling alternative. For a 15-param create tool with full schema coverage, nothing an agent needs to call it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds real meaning beyond the schema by explaining the job_id side effect (application created in the same call, response contains both) and the fallback to create_application when it is omitted. Other params are left to the rich schema descriptions.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

Opens with a specific verb+resource ('Create a new candidate record') and states scope ('optionally applying them to a job'). It explicitly differentiates from siblings, naming add_prospect and create_application, so an agent can route correctly without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives explicit when-to-use rules: check duplicates first with search_candidates_by_name or search_candidates_by_email; pass job_id to fold the application into the same call; without job_id use create_application afterwards. It also names the alternative tool (add_prospect) with the condition (sourced prospects) that selects it.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

create_custom_fieldB

Create a new custom field definition. Write operation — admin only.

Defines a new field available on candidates, applications, jobs, offers, openings or users.

ParametersJSON Schema
NameRequiredDescriptionDefault
nameYesDisplay name for the custom field
optionsNoInitial dropdown options for select fields: [{name, sort_order}]
privateNoIf true, only visible to users with private field access
field_typeYesEntity: candidate, application, job, offer, opening, user_attribute
value_typeYesshort_text, long_text, yes_no, single/multi_select, currency, date, number, url, user, currency_range, number_range
descriptionNoHelper text shown beneath the field label
generate_email_tokenNoIf true, generates an email token for this field

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

B3.4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden. It usefully discloses that this is a write operation requiring admin privileges, but says nothing about reversibility, whether the field name must be unique, side effects on existing records, or rate/validation constraints.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, front-loaded with the operation and then the critical admin constraint. No filler, though the line-broken entity list adds little and could be tighter.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness3/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be explained, and the admin/write framing covers the safety profile. Still, for a 7-parameter creation tool with several sibling field-management tools, the description omits how it relates to those siblings and any uniqueness/validation behavior an agent should anticipate.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so all seven parameters are documented in the schema itself, including the field_type entity list and value_type vocabulary. The description adds no parameter detail beyond repeating the entity list already present in field_type's schema description.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Create a new custom field definition') and lists the entity surfaces the field can attach to, which clarifies scope. It is distinguishable from list_custom_fields and get_custom_field, though it never explicitly names its mutation siblings (update_custom_field, delete_custom_field, create_custom_field_options).

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

'Write operation — admin only' gives a prerequisite, which is real guidance. However, there is no when-to-use vs. when-not guidance relative to the crowded sibling set of custom-field tools (e.g., create_custom_field_options for dropdown values, update_custom_field for existing definitions).

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

create_custom_field_optionsA

Add dropdown options to a custom field. Write operation — admin only.

To find custom_field_id: list_custom_fields → match by name. Up to 50 options are created immediately and returned; larger lists are sent as an asynchronous Greenhouse bulk request.

ParametersJSON Schema
NameRequiredDescriptionDefault
optionsYesArray of {name, sort_order, external_id?} — sort_order (or legacy priority) controls display order; defaults to list position
custom_field_idYesCustom field ID (must be a single_select or multi_select field)

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does well: it declares this is a write operation, that it is admin-only, and that lists up to 50 options are created synchronously and returned while larger lists go through an asynchronous Greenhouse bulk request. It omits reversibility (how options are removed) and error/permission failure behavior, keeping it out of the top band.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short lines, front-loaded with the operation and its write/admin constraint, then the ID lookup, then the sync/async threshold. Every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be explained, yet the description still covers the key behavioral surprise (sync vs async based on the 50-option threshold) plus the auth requirement and ID acquisition path. Nothing essential is missing for an agent to call this correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so baseline is 3, but the description adds procedural value the schema does not: how to obtain custom_field_id via list_custom_fields and matching by name. It adds nothing for the options array beyond what the schema already documents.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description gives a specific verb+resource ('Add dropdown options to a custom field'), making the operation unambiguous. It does not explicitly name the sibling tools it is distinguished from (update_custom_field_options, delete_custom_field_options, create_custom_field), so it stops just short of the top band.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It supplies real routing guidance for the hard part of calling it: 'To find custom_field_id: list_custom_fields → match by name.' It does not state when to use this instead of update_custom_field_options or delete_custom_field_options, nor any exclusions, so it is clear context without explicit alternatives.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

create_departmentA

Create a new department. Write operation — admin only.

For parent_id (optional): list_departments → find parent by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
nameYesDepartment name
parent_idNoParent department ID for hierarchy — get from list_departments
external_idNoYour HRIS/external identifier for this department

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.8/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full behavioral burden. It discloses that this is a write and that admin privileges are required, which is useful. However it says nothing about side effects, uniqueness/dedup behavior on name or external_id, idempotency, or error cases expected of a create operation.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, the core action front-loaded, followed only by the one genuinely needed hint. Nothing is wasted or redundant.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation, and the permission constraint plus parent_id sourcing hint cover the practical needs of a 3-parameter create tool. The remaining gap is behavioral edge cases (uniqueness, errors) rather than anything blocking correct invocation.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so baseline is 3. The description adds a pointer for parent_id (optional, obtained from list_departments by name), which is marginally useful, but says nothing about external_id beyond what the schema already provides.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ("Create a new department") so the agent knows exactly what it does, and the verb distinguishes it from siblings get_department, list_departments, and update_department. It doesn't explicitly name those siblings, so it stops short of full differentiation.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives concrete context: it is a write operation and admin-only, and it tells the agent how to source the optional parent_id via list_departments. There is no "when not to use" or mention of failure conditions, so it is clear guidance without exclusions.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

create_interviewA

Record a scheduled interview for an application. Write operation.

Users say "schedule an interview for Sarah on the Backend role." To get application_id: search_candidates_by_name → list_applications(candidate_id=...) → match app. For interviewer_ids: list_users → match by name. interview_id is the job interview from list_job_stages_for_job (interviews[].id). This records the interview in Greenhouse; it does not send calendar invites.

ParametersJSON Schema
NameRequiredDescriptionDefault
endYesEnd time as ISO 8601, e.g. '2024-03-15T11:00:00Z'
startYesStart time as ISO 8601, e.g. '2024-03-15T10:00:00Z'
locationNoRoom, address, or meeting link
interview_idYesJob interview ID (the interview on the job's plan) — from list_job_stages_for_job → stage interviews[].id
application_idYesApplication to schedule the interview for
interviewer_idsYesUser IDs of interviewers — get from list_users
external_event_idNoID of the matching event on the organizer's calendar (Google/Outlook). A placeholder is generated if omitted
video_conferencing_urlNoVideo call join URL

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description must carry behavioral disclosure, and it does the important part: it states this is a write operation and that it "does not send calendar invites," which prevents a false expectation of outbound notifications. It omits permission requirements, whether duplicate scheduling is possible, and any rate/validation constraints, so it is good but not exhaustive.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Purpose and write-operation warning are front-loaded in the first two sentences, followed by compact ID-resolution recipes. It is terse to the point of being telegraphic, but every sentence carries operational information and nothing is padded.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For an 8-parameter mutation tool this covers the crucial gaps: how to obtain the otherwise opaque IDs and the explicit absence of calendar-invite side effects. An output schema exists, so return-value documentation is not needed, though scheduling-conflict or permission behavior remains unaddressed.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the baseline is 3. The description restates the derivation for application_id, interviewer_ids, and interview_id, but the schema already documents those same sources (list_users, list_job_stages_for_job → interviews[].id), so it adds little beyond the structured fields.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description opens with a specific verb+resource ("Record a scheduled interview for an application") and explicitly labels it a write operation, which cleanly separates it from the read-oriented siblings get_interview, list_interviews, and list_interviews_for_application, and from delete_interview/update_interview.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It gives a concrete user-intent trigger ("schedule an interview for Sarah on the Backend role") and step-by-step ID-resolution recipes for application_id, interviewer_ids, and interview_id, so the agent knows the prerequisite lookups. It stops short of explicitly naming alternative tools or stating when NOT to use this (e.g., reschedule vs. create), so it is strong but not fully routing-aware.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

create_jobA

Create a new job from a template. Write operation — admin only.

Users say "create a new Backend Engineer role." Requires template_job_id — use list_jobs to find a similar existing job. For department_id: list_departments → match by name. For office_ids: list_offices → match. After creation, use update_job_post to set the public listing content.

ParametersJSON Schema
NameRequiredDescriptionDefault
notesNoInternal notes about the job (HTML supported)
job_nameNoInternal job name
office_idsNoOffice IDs — get from list_offices
opening_idsNoOptional external IDs for the new openings, one per opening
custom_fieldsNoArray of {id, value} — get field IDs from list_custom_fields
department_idNoDepartment ID — get from list_departments
job_post_nameNoTitle for the public job post
requisition_idNoExternal requisition/req ID for HRIS mapping
template_job_idYesExisting job ID to use as template — copies pipeline stages and settings
number_of_openingsNoNumber of openings to create on this job

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does disclose the two most important traits: it is a write operation and it is admin-only. It also fixes the required template_job_id and the post-creation workflow. It does not cover reversibility, error behavior, or how the template's pipeline/approvers propagate, which keeps it short of a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The write/admin declaration is front-loaded, followed by a concrete user example and then a compact ID-discovery workflow. Every sentence contributes a distinct, actionable instruction with no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need no explanation, and the schema documents all 10 parameters. The description supplies behavior (write, admin-only) and the cross-tool ID-discovery workflow, making it largely complete; it could note what the template copy creates (openings, stages) but that is a minor gap.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds genuine value beyond the schema by explaining how to derive FK values ('match by name' for department/office) and consolidating the discovery flow. It stops short of covering the remaining scalars (notes, job_name, requisition_id, number_of_openings), which the schema already documents.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Create a new job') and adds the distinguishing mechanism 'from a template', which separates it from siblings like create_job_opening and update_job. An agent can identify the operation without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives explicit prerequisites and alternatives: template_job_id via list_jobs, department_id via list_departments (match by name), office_ids via list_offices, and the follow-up step update_job_post. It also names the admin-only constraint and provides a user-phrasing example, leaving little to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

create_job_openingA

Add a new headcount to a job. Write operation.

Users say "add another opening to the Backend role." To find job_id: list_jobs → match by name. Openings are created open; with status='closed' the new opening is closed straight after (with close_reason_id if given).

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID
statusNoInitial status: 'open' (default) or 'closed'
opening_idNoCustom external opening identifier (not the Greenhouse ID)
custom_fieldsNoArray of {id, value} (or {custom_field_id, value}) — get field IDs from list_custom_fields
close_reason_idNoIf closing immediately — get from list_close_reasons

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does disclose meaningful behavior: it flags the operation as a write, states that openings default to open, and explains the non-obvious side effect that status='closed' closes the opening immediately, requiring close_reason_id. It omits permissions/error/rate-limit behavior, so not a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Four short segments, front-loaded with the operation and the write classification, then user-phrasing, then a lookup recipe, then default/edge-case behavior. No filler sentences; every clause carries information.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a 5-parameter mutation with an output schema, the description covers what it creates, the default and conditional status behavior, and how to resolve the required job_id. Missing only permission requirements and failure modes, which are minor given the output schema handles return values.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the baseline is 3, but the description adds real semantics beyond the schema: the default status value, the conditional dependency between status='closed' and close_reason_id, and how to obtain job_id. It does not clarify the custom_fields or opening_id semantics further.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

The opening sentence names a specific verb+resource ('Add a new headcount to a job') and even maps user phrasing ('add another opening to the Backend role') onto it, so the intent is unambiguous. It does not explicitly distinguish itself from close neighbors like bulk_create_job_openings or create_job, so it falls short of a 5.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It gives concrete activation context (the natural-language request it answers) and a prerequisite workflow: 'To find job_id: list_jobs → match by name.' That is more than implied usage, but it names no exclusions or explicit alternative tools for edge cases (e.g., bulk creation).

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

create_officeA

Create a new office. Write operation — admin only.

For parent_id (optional): list_offices → find parent by name. For the contact: list_users → match by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
nameYesOffice name
locationNoLocation string, e.g. 'San Francisco, CA'
parent_idNoParent office ID for hierarchy — get from list_offices
primary_contact_user_idNoUser ID of the office's primary in-house contact

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description must carry the behavioral burden. It discloses that this is a write operation and admin-restricted, which is valuable, but says nothing about reversibility, failure modes, or side effects beyond creation.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the core action and the safety-relevant fact (write, admin only), then adds only the two lines of dependency guidance. No redundant or filler content.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists and parameter coverage is full, so return values and field meanings are already documented. Together with the auth and lookup guidance, nothing an agent needs to invoke it correctly is missing. Adjusting to 5 given how little remains uncovered.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds procedural value beyond the schema by prescribing the lookup workflow (list_offices → find parent by name; list_users → match by name) for the two ID parameters.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Create a new office'), clearly distinct from sibling resources like create_department or create_user. It doesn't need to contrast with a near-identical sibling, so the lack of explicit differentiation is minor.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives clear operating context ('admin only') and dependency-gathering guidance — use list_offices to resolve parent_id and list_users to match the contact. It stops short of stating when-not-to-use this tool, but the prerequisites are explicit.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

create_or_replace_approval_flowA

Create or replace an approval flow for a job. Write operation — overwrites existing.

If the job already has a flow of this approval_type, its approver groups are replaced; otherwise a new flow is created (pending — call request_approvals to start it). To find job_id: list_jobs → match by name. For approver user IDs: list_users → match by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID
sequentialNoGroups approve one after another (true) or all at once
approval_typeYesFlow type: 'open_job', 'offer_job' or 'offer_candidate'
approver_groupsYesOrdered approver groups: [{approvals_required: N, approvers: [{user_id: N} | {email: '...'}]}]

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.5/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the burden and does well: it declares the write operation, warns that existing approver groups are overwritten, and discloses the resulting pending state requiring request_approvals. It omits permission/auth requirements and error behavior, which keeps it short of a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the verb, resource, and the critical 'overwrites existing' warning in the first sentence, then layers branch behavior and ID lookups. Every sentence earns its place; nothing is redundant.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need no explanation, and the description covers the mutation semantics, replacement behavior, pending state, and prerequisite lookups. An agent has everything needed to invoke this correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the baseline is 3, but the description adds real semantic help the schema lacks: how to obtain job_id (list_jobs → match by name) and approver user IDs (list_users → match by name). It doesn't clarify the nested approver_groups structure beyond the schema, so not a 5.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource with clear semantics: 'Create or replace an approval flow for a job.' It also implicitly distinguishes itself from siblings by noting the flow is created pending and that request_approvals starts it, versus get_approval_flow/list_approvals_for_job which read state.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explains the two branches (existing flow of this approval_type → groups replaced; otherwise new flow) and routes the agent to request_approvals for activation plus list_jobs/list_users for ID discovery. It does not explicitly say when to prefer this over replace_approver or get_approval_flow, but the context is clear.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

create_tagA

Create a new candidate tag. Write operation.

After creating, use add_tag_to_candidate to apply it. Note: bulk_tag creates tags on-the-fly, so pre-creation isn't needed for bulk ops.

ParametersJSON Schema
NameRequiredDescriptionDefault
nameYesTag name — must be unique across the organization

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden. It does declare 'Write operation', which is the key safety signal, and notes the two-step create-then-apply workflow. However it says nothing about permission requirements, what happens on a duplicate name, or idempotency — relevant gaps for a mutation with zero annotation coverage (return format is covered by the output schema, so that omission is acceptable).

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, front-loaded with the operation and its write nature, then the follow-up action, then the alternative. Every sentence earns its place and none is redundant with structured fields.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a one-parameter mutation with an output schema and a well-described parameter, the description is largely complete: it establishes the write nature and routes to the correct follow-up and sibling tools. It falls short only on operational behavior (permissions, duplicate-name handling) that an agent might need under failure conditions.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

There is a single parameter and schema description coverage is 100% — the schema already documents both the name field and the organization-wide uniqueness constraint. The description adds no syntax, format, or constraint detail beyond that, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Create a new candidate tag') and immediately differentiates from the two most confusable siblings: add_tag_to_candidate (applies an existing tag) and bulk_tag (creates tags implicitly). An agent can route correctly without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives explicit workflow ordering ('After creating, use add_tag_to_candidate to apply it') and an explicit exclusion ('bulk_tag creates tags on-the-fly, so pre-creation isn't needed for bulk ops'). This is exactly when-to-use / when-not-to-use with named alternatives.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

create_userA

Create a new Greenhouse user account. Write operation — admin only.

After creating, use add_job_permission to grant access to specific jobs, or add_future_job_permission for automatic access to new jobs.

ParametersJSON Schema
NameRequiredDescriptionDefault
emailYesUser's email address — must be unique in Greenhouse
job_titleNoJob title on the user's profile
last_nameYesUser's last name
first_nameYesUser's first name
office_idsNoOffices to assign the user to — get from list_offices
send_emailNoSend an invitation email to the new user
department_idsNoDepartments to assign the user to — get from list_departments

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden; it usefully discloses that this is a write operation and admin-restricted, which the agent needs. However, it omits other behavioral traits such as whether an invitation email is sent by default, error conditions (e.g., duplicate email), or what happens to permissions at creation time.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two sentences, zero waste, front-loaded with the core operation and the admin constraint before the follow-up workflow guidance.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be explained, and the description covers the mutation type, authorization requirement, and next-step workflow. It could do slightly more on side effects like the default invitation email, but is largely complete for a create tool.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so all seven parameters (including office_ids/department_ids sourcing hints and send_email default) are already documented in the schema. The description adds no parameter-level meaning beyond that, so baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Create a new Greenhouse user account'), clearly distinguishing it from siblings like update_user, disable_user, and create_candidate. An agent can identify the operation without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Adds explicit prerequisites ('admin only') and routes the agent to the two follow-up permission tools with the condition that separates them (specific jobs vs. automatic access to new jobs). It does not state when to prefer this over other creation tools, but the context is clear.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

delete_applicationA

Permanently delete an application. Destructive — cannot be undone.

To find the application_id: search_candidates_by_name → get_candidate → match the application to the job. Consider reject_application instead — it preserves history and can be reversed with unreject_application.

ParametersJSON Schema
NameRequiredDescriptionDefault
application_idYesGreenhouse application ID to delete

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does disclose the crucial trait: permanent, cannot be undone. It stops short of stating cascade scope (whether notes, attachments, interviews, or the candidate record survive) or any permission requirement, which matters for a destructive operation.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short, front-loaded statements: capability and risk first, ID discovery second, safer alternative third. No sentence is redundant and nothing is buried.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be described, and the destructive nature plus the safer sibling are covered. The remaining gap is blast radius — what else is removed along with the application — which an agent deciding between delete and reject would want.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% and there is only one parameter, so baseline is 3. The description adds genuine value beyond the schema's bare 'Greenhouse application ID to delete' by explaining how to derive that ID from a candidate-name search.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Permanently delete an application') and immediately qualifies the scope with irreversibility. It is clearly distinguishable from reject_application, which the description explicitly names.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives an explicit alternative ('Consider reject_application instead — it preserves history and can be reversed with unreject_application'), which is a when-not-to-use condition, plus a concrete lookup chain (search_candidates_by_name → get_candidate → match the application to the job) for obtaining the required ID.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

delete_candidateA

Permanently delete a candidate and all their applications. Destructive — cannot be undone.

To get the candidate_id: search_candidates_by_name → get_candidate. For GDPR compliance, consider anonymize_candidate instead — it preserves the record while removing personal data.

ParametersJSON Schema
NameRequiredDescriptionDefault
candidate_idYesGreenhouse candidate ID to delete

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.7/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full disclosure burden and does well: it states the operation is permanent, cannot be undone, and cascades to all applications. It does not mention permission requirements or any guardrails (e.g. candidates with active offers), which keeps it short of a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short, front-loaded segments: the destructive action first, then ID acquisition, then the compliant alternative. No filler sentences and nothing buried.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation. For a single-parameter destructive tool with no annotations, the description covers the action, its irreversibility, cascade scope, prerequisite lookup, and a safer alternative — everything needed to call it correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% and the schema already documents candidate_id, so the baseline would be 3. The description adds real value by explaining how the ID is acquired via search_candidates_by_name and get_candidate, which is meaning the schema cannot convey.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (delete), resource (candidate) and scope (and all their applications), plus the irreversible nature. It also distinguishes itself from the sibling anonymize_candidate by naming it explicitly, so an agent can route correctly without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives an explicit prerequisite chain for obtaining the required ID (search_candidates_by_name then get_candidate) and an explicit when-to-use-the-alternative condition ('For GDPR compliance, consider anonymize_candidate instead'). This is exactly the routing guidance an agent needs.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

delete_custom_fieldA

Delete a custom field and all its values. Destructive — cannot be undone. Admin only.

To find custom_field_id: list_custom_fields → match by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
custom_field_idYesCustom field ID to delete

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.7/5.0
Behavior5/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full burden and does so well: it discloses that the operation is destructive, irreversible ('cannot be undone'), cascades to all values, and requires admin permissions. These are exactly the behavioral traits an agent needs before invoking a delete tool.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The description is front-loaded and tightly structured: purpose first, then critical safety/permission warnings, then a parameter lookup hint. Every sentence earns its place with no redundancy.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a simple one-parameter delete tool with an output schema available, the description covers purpose, destructive irreversibility, permission requirements, and parameter acquisition. Nothing essential is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The schema fully documents the single custom_field_id parameter, so the baseline would be 3. The description adds useful meaning beyond the schema by explaining how to find the ID via list_custom_fields and name matching, which improves invocation accuracy.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description uses a specific verb and resource: 'Delete a custom field and all its values.' It clearly distinguishes this operation from siblings like update_custom_field and create_custom_field by focusing on deletion, and the scope of deleting all values is made explicit.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It provides clear context: 'Admin only' states a prerequisite, and 'To find custom_field_id: list_custom_fields → match by name' gives procedural guidance for obtaining the required parameter. However, it does not explicitly state when not to use this tool or name alternatives such as delete_custom_field_options for deleting only field options.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

delete_custom_field_optionsA

Delete dropdown options from a custom field. Destructive — cannot be undone. Admin only.

To find custom_field_id: list_custom_fields → match by name. For option IDs: list_custom_field_options → match by name. Historical selections keep the (now inactive) option. Up to 50 options are deleted immediately; larger lists use an asynchronous bulk request.

ParametersJSON Schema
NameRequiredDescriptionDefault
option_idsYesIDs of options to delete — get from list_custom_field_options
custom_field_idYesCustom field ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior5/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does so well: irreversible destructive operation, admin-only permission requirement, the side effect that historical selections retain the now-inactive option, and a 50-option threshold that switches to asynchronous bulk processing.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the action and its destructive/admin nature before the ID-resolution instructions. Dense and largely waste-free, though the telegraphic arrow notation is slightly terse.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need not be explained, and the description still covers the async-bulk edge case (with get_bulk_request_status available as a sibling). An agent has everything needed to call this correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so baseline is 3, but the description adds lookup provenance by naming the exact tools that produce custom_field_id and option_ids. It adds no array-size or ID-format detail beyond that.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource (delete dropdown options from a custom field) and immediately marks it destructive and admin-only. It is clearly distinguishable from siblings like update_custom_field_options, delete_custom_field, and list_custom_field_options.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives explicit prerequisite routing: use list_custom_fields to resolve custom_field_id and list_custom_field_options to resolve option_ids, both by name. It does not explicitly contrast when to delete vs. deactivate/update an option, so it stops short of full when/when-not guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

delete_interviewA

Cancel a scheduled interview. Write operation — cannot be undone.

To find interview_id: list_interviews_for_application on the candidate's app.

ParametersJSON Schema
NameRequiredDescriptionDefault
interview_idYesScheduled interview ID to cancel/delete

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations supplied, the description carries the full burden and does disclose the two most important traits: this is a write operation and it 'cannot be undone'. That is real destructive-behavior disclosure beyond a bare verb. It still omits permission requirements and side effects (candidate notification, fate of attached scorecards/feedback), which keeps it from a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short, front-loaded sentences: the action and its irreversibility come first, the ID-sourcing hint second. Nothing is padding, and the most decision-relevant fact (cannot be undone) is not buried.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need no explanation, and the single-parameter surface is fully covered. The description supplies purpose, destructiveness, and ID sourcing. The remaining gap is a subtle naming mismatch — the tool is delete_interview but the description says 'cancel', leaving the agent unsure whether the record is removed or merely marked cancelled.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds actionable meaning: it tells the agent that interview_id is the scheduled interview ID and, more importantly, how to obtain one via list_interviews_for_application on the candidate's application. That is genuinely useful retrieval guidance rather than restating the schema.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Cancel a scheduled interview') and is immediately distinguishable from sibling read/write interview tools like get_interview, list_interviews, or update_interview. It also names a sibling (list_interviews_for_application) so the agent can place the tool in the workflow.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Clearly conveys when to reach for this tool (cancelling a scheduled interview) and gives an explicit path for sourcing the required ID via list_interviews_for_application. It stops short of naming the alternative for non-destructive changes (e.g., update_interview to reschedule instead of cancel), so there are no explicit exclusions.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

delete_job_openingA

Delete a job opening. Destructive — cannot be undone.

To find job_id: list_jobs → match by name. To find opening_id: list_job_openings on the job.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID
opening_idYesOpening ID to delete

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.6/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full behavioral burden. It discloses the critical irreversibility ('Destructive — cannot be undone'), but does not mention required permissions, side effects on related applications, or failure conditions.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The description is two tight sentences: the destructive warning is front-loaded, and ID discovery instructions follow immediately. No wasted words.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness3/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Given the destructive mutation, no annotations, and an output schema that handles return values, the description covers the action, irreversibility, and ID lookup. However, it omits authorization requirements and side effects that an agent should know before deletion.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3. The description adds value beyond the schema by explaining how to discover the required job_id (via list_jobs, matched by name) and opening_id (via list_job_openings on the job).

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific verb and resource: 'Delete a job opening.' It is clear what the tool does, though it does not explicitly contrast itself with bulk_delete_job_openings or other sibling deletion tools.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description provides helpful prerequisite guidance for obtaining job_id and opening_id, but it does not state when to use this tool instead of alternatives such as bulk_delete_job_openings or delete_candidate.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

delete_tagA

Delete a tag from the organization. Destructive — removes it from all candidates.

To find tag_id: list_tags → match by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
tag_idYesTag ID to delete — get from list_tags

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full disclosure burden, and it does deliver the most important trait: "Destructive — removes it from all candidates," making the blast radius explicit. It stops short of stating irreversibility, required permissions, or behavior when the tag does not exist.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short lines, zero waste, with the destructive nature and scope front-loaded ahead of the procedural ID-lookup hint. Every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a single-parameter delete with an output schema, the description covers the essential scope and the prerequisite lookup. Missing only edge-case behavior (nonexistent tag, error semantics), which is a minor gap at this complexity.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

With one parameter and 100% schema description coverage, the schema already documents tag_id and even the list_tags lookup path, so the description largely repeats structured data. Baseline 3 is appropriate; no additional syntax or constraint detail is added.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ("Delete a tag") and pins the scope to "from the organization," which cleanly separates it from the sibling remove_tag_from_candidate (per-candidate removal) and from delete_candidate. An agent can pick the right tool without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description routes the agent to list_tags for obtaining tag_id and implies the org-wide blast radius, which hints at why one would choose this over remove_tag_from_candidate. However, it never explicitly states when to use this tool versus that sibling, so usage is inferred rather than spelled out.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

disable_userA

Deactivate (disable) a Greenhouse user, preventing login. Write operation.

Users say "deactivate John's account." To find user_id: list_users → match by name or email. Can be reversed with enable_user. Returns {"success": true} on success.

ParametersJSON Schema
NameRequiredDescriptionDefault
user_idYesGreenhouse user ID to disable

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.7/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden, and it does disclose that this is a mutation, that it is reversible via enable_user, and that it returns {"success": true}. It stops short of stating required permission level or side effects beyond login blocking (e.g. session termination, notification), so it is strong but not exhaustive.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Very short and front-loaded: purpose first, then lookup workflow, then reversibility and return shape. No filler sentences; every line carries usable information.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a one-parameter mutation with an output schema, the description covers purpose, effect, ID discovery, reversibility, and a return summary. Nothing an agent needs to invoke it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% and the single parameter is documented as "Greenhouse user ID to disable", so the baseline is 3. The description goes beyond the schema by explaining how to obtain the ID (list_users → match by name or email), which is genuine added value for the one parameter.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ("Deactivate (disable) a Greenhouse user") plus the concrete effect ("preventing login"), and labels it a write operation. This clearly distinguishes it from siblings like enable_user and the various list/get user tools.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides a natural-language trigger ("deactivate John's account"), an explicit prerequisite workflow for obtaining user_id (list_users → match by name or email), and names the reversing tool (enable_user). The agent is routed to the correct alternatives rather than having to infer them.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

download_attachmentA

Download content from a Greenhouse attachment URL. Read-only.

Use when you have a specific attachment URL from a candidate or application record (e.g., get_candidate's or get_application's attachments array). Attachment URLs are time-limited — if a download fails, fetch the record again for a fresh URL.

ParametersJSON Schema
NameRequiredDescriptionDefault
urlYesAttachment URL — from get_candidate's or get_application's attachments array

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.5/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries full disclosure burden. It declares 'Read-only' and adds genuinely useful behavior beyond structured data: attachment URLs are time-limited and a failed download should be retried by re-fetching the record for a fresh URL. It stops short of detailing response content types or auth requirements, but the core operational trait is disclosed.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two tight paragraphs, purpose front-loaded first, followed by usage and the retry caveat. No repetition or filler; every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With an output schema present, return-value explanation is unnecessary. The description covers purpose, source of the URL, and the retry-on-expiry behavior, which is everything an agent needs to invoke this single-parameter read tool correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3. The description goes beyond the schema by stating the URL is time-limited and should be re-obtained on failure, which adds real semantic meaning about the parameter's lifecycle that the schema description does not convey.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (download) and resource (content from a Greenhouse attachment URL), which is distinct from every sibling. An agent can immediately tell this is a content-fetch operation, not a metadata list or mutation.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Tells the agent exactly when to use it — 'when you have a specific attachment URL from a candidate or application record' — and cites the sources (get_candidate/get_application attachments arrays). It does not name explicit exclusions or alternatives, but the usage context is unambiguous.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

enable_userA

Re-activate (enable) a previously deactivated user. Write operation.

To find user_id: list_users → match by name or email. Returns {"success": true} on success.

ParametersJSON Schema
NameRequiredDescriptionDefault
user_idYesGreenhouse user ID to re-enable

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.7/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden. It usefully discloses that this is a write operation and returns {"success": true} on success, but it does not cover permissions required, side effects, error cases, or whether the operation is idempotent.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The description is front-loaded with the purpose and operation type, then gives a concrete lookup instruction and the return shape. Every sentence is short and earns its place, with no redundant or filler content.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a simple one-parameter enable tool with a full input schema, an output schema, and no annotations, the description is largely complete. It covers purpose, mutation behavior, how to find the required ID, and the success response, though it omits permission or side-effect details.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the schema already documents the single user_id parameter. The description adds meaning beyond the schema by explaining how to obtain the required ID: use list_users and match by name or email. That is useful operational context not present in the input schema.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific verb and resource: 'Re-activate (enable) a previously deactivated user.' It also labels the operation as a 'Write operation,' which clarifies it is not a read or update. However, it does not explicitly distinguish this tool from its closest sibling, disable_user, or explain why an agent should choose this over a general user update.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Usage is implied by 'previously deactivated user,' and the description gives practical prerequisite guidance for finding user_id via list_users. It does not, however, state when to use this tool versus alternatives such as disable_user or update_user, nor does it include any exclusions or conditions.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

fetch_new_applicationsA

Applications since a date, grouped by job — the daily digest. Read-only.

Users say "what new applications came in since yesterday?" Pass since as an ISO date (applications created on or after it). Optionally filter to one job with job_id (list_jobs → match by name). Returns applications grouped by job with candidate names, sources, stages, and screening answers.

ParametersJSON Schema
NameRequiredDescriptionDefault
sinceYesISO 8601 date — e.g. '2026-04-14' for yesterday
job_idNoFilter to one job — list_jobs → match by name
statusNoFilter by status: 'active', 'rejected', or 'hired'active
include_candidate_detailsNoInclude candidate names (adds API calls)

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations the description carries the full burden, and it delivers the two most important traits: it declares 'Read-only' up front and notes that include_candidate_details 'adds API calls', a cost signal. It omits auth/permission requirements and any pagination or result-limit behavior, which keeps it below 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the core definition, then the example query, then parameter notes — a sensible order. Every sentence is useful, though the return-value sentence partly duplicates the output schema.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With an output schema present the description needn't explain return values, yet it still summarizes the grouping. Combined with 100% schema coverage, read-only disclosure, and clear parameter intent, an agent has enough to call it correctly; only auth and pagination context are missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds real meaning: it clarifies the inclusive boundary ('applications created on or after it') and gives a workflow hint for job_id ('list_jobs → match by name'). It does not address the status parameter, so it does not fully rise to 5.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Applications since a date, grouped by job') and frames the use case as 'the daily digest'. It is clear what the tool does, but it never names the sibling it is not (e.g. list_applications, get_activity_feed), so an agent must infer the boundary itself.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The embedded user question ('what new applications came in since yesterday?') gives a concrete when-to-use context, and it explains the since and job_id usage. It stops short of explicit exclusions or naming an alternative tool, so it is clear context without routing guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_activity_feedA

Get a candidate's activity timeline. Read-only.

Users say "show me Sarah's history" or "what's happened with this candidate?" To find candidate_id: search_candidates_by_name. Returns three lists, newest first: notes (notes, interviews, follow-ups and other entries), emails (logged emails with subject, email_from/email_to/email_cc), and activities (system events such as stage changes). Every entry has type, body, created_at, application_id, visibility and user ({id, name}) when a person wrote it.

ParametersJSON Schema
NameRequiredDescriptionDefault
candidate_idYesGreenhouse candidate ID
created_afterNoISO 8601 datetime — only entries created after this

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations exist, so the description carries the full burden, and it does well: it declares 'Read-only,' describes the return shape (three lists, newest first), and enumerates entry fields. It omits permission/auth requirements and any pagination or result-size behavior, which keeps it short of a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the core purpose and read-only note, followed by trigger examples and return structure. Some return-field detail is arguably redundant given an output schema exists, but the text is dense and free of filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a read-only, two-parameter lookup, the description plus schema and output schema cover everything an agent needs to call it correctly. Nothing critical is missing, though it could note pagination or entry-volume behavior for large candidate histories.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the schema already documents both parameters. The description adds genuine meaning beyond the schema by telling the agent to resolve candidate_id via search_candidates_by_name, though it says nothing extra about created_after.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Get a candidate's activity timeline') and reinforces scope with 'Read-only.' An agent can distinguish this from list_candidates, get_candidate, or add_note_to_candidate without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides concrete trigger phrasing ('show me Sarah's history', 'what's happened with this candidate?') and routes the agent to search_candidates_by_name for resolving candidate_id. It lacks explicit when-not-to-use or named alternatives for timeline-style queries, but the positive usage context is clear.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_answerA

Get a single demographic survey response by ID. Read-only.

To find IDs: list_answers or list_answers_for_application.

ParametersJSON Schema
NameRequiredDescriptionDefault
answer_idYesDemographic answer ID — get from list_answers

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden. It does disclose the key behavioral trait ('Read-only'), which is valuable. However, it says nothing about not-found/error behavior or how missing IDs are handled, which would benefit an agent calling with a user-supplied ID.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two sentences, purpose front-loaded, followed by the practical ID-sourcing tip. No filler; every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be described, and the single parameter is fully documented. The only unaddressed edge is error/not-found behavior, a minor gap for a read getter.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% and the schema already documents answer_id and its type. The description reinforces 'by ID' and names the ID source, but adds little beyond the schema. Baseline 3 when the schema does the heavy lifting.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (Get), resource (a single demographic survey response), and scope (by ID, single). This clearly distinguishes it from the sibling list tools list_answers and list_answers_for_application that return multiple responses.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly routes the agent to the two alternatives (list_answers, list_answers_for_application) that supply the required ID, giving a concrete condition for their use. For a single-param getter, this is the needed guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_answer_optionA

Get a demographic answer option by ID. Read-only.

To find IDs: list_answer_options or list_answer_options_for_question.

ParametersJSON Schema
NameRequiredDescriptionDefault
answer_option_idYesAnswer option ID — get from list_answer_options

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full behavioral burden and does disclose the key trait ('Read-only'), which tells the agent this is a safe non-mutating call. However, it says nothing about what happens with an invalid or deleted ID (error vs. empty result) or any other behavioral edge case.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, zero waste, with the core purpose front-loaded and the ID-sourcing hint following immediately. Nothing extraneous.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

The tool is simple (one required param), an output schema exists so return values need no explanation, and the description covers purpose, safety posture, and ID acquisition. Only minor gap is the absence of failure-mode behavior for a bad ID.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and the schema already documents answer_option_id including the hint to get it from list_answer_options; the description only restates that sourcing hint. Per the baseline for full schema coverage, 3 is appropriate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific verb and resource ('Get a demographic answer option by ID'), which is precise enough to distinguish it from sibling list_answer_options, list_answer_options_for_question, and get_answer without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It explicitly names the two sibling tools (list_answer_options, list_answer_options_for_question) as the way to obtain the required ID, giving a clear precondition for calling it. It stops short of stating when to prefer this single-fetch over those list tools or when not to use it.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_applicationA

Get a single application by ID. Read-only.

Returns the application with job_name, its current stage (stage_name and job_interview_stage_id — the from_stage_id for moves), status, source_id, rejection_reason_id, custom fields, and its attachments (resume etc., with time-limited download URLs). Users rarely know application IDs. To find one: search_candidates_by_name → get_candidate → the applications array has each application's ID and job name. For a complete screening package with resume and location, use screen_candidate.

ParametersJSON Schema
NameRequiredDescriptionDefault
application_idYesGreenhouse application ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does declare 'Read-only' plus what the response contains (stage identifiers, status, source/rejection IDs, custom fields, attachments with time-limited download URLs). It does not cover auth/permission requirements or error cases, keeping it short of a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with purpose and read-only status, then return contents, then ID-discovery guidance. The enumerated return fields are somewhat redundant given an output schema exists, but the structure and ordering are efficient.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need not be re-explained, yet the description still supplies the essential workflow context (how to get an ID) and the sibling alternative. Nothing an agent needs to call it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% so the schema already documents application_id as a Greenhouse ID (baseline 3). The description adds genuine value by explaining how to locate an application ID, which the schema does not.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (get), resource (a single application), and lookup key (by ID), immediately distinguishing it from list_applications and get_candidate. An agent can identify the operation without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly notes that users rarely know application IDs and gives a concrete path to obtain one (search_candidates_by_name -> get_candidate -> applications array), plus names screen_candidate as the alternative when a full screening package is needed. This is true when-to-use/when-to-use-something-else guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_approval_flowA

Get a specific approval flow for a job. Read-only.

Returns flow type, approval_status, and approver groups with their approvers. To find job_id: list_jobs → match by name. For approval_flow_id: list_approvals_for_job.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID
approval_flow_idYesApproval flow ID — get from list_approvals_for_job

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.5/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations exist, so the description carries the full behavioral burden: it declares 'Read-only' (safety profile) and enumerates the returned payload (flow type, approval_status, approver groups with approvers). It omits error/not-found behavior and any authorization requirements, but for a simple read this is solid coverage.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three tight sentences, front-loaded with purpose and read-only flag, then discovery hints. No filler and nothing that restates the tool name.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a two-required-param read tool with an output schema present, the description covers purpose, safety, return shape, and the prerequisite lookup for both IDs. There is nothing an agent needs to invoke it correctly that is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is already 100%, so the baseline is 3. The description adds real value beyond the schema by supplying the lookup path for job_id (list_jobs → match by name), which the schema does not mention. It does not add integer/format constraints, so it lands just above baseline.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Get a specific approval flow for a job') and immediately distinguishes itself from the sibling write tools (create_or_replace_approval_flow) with 'Read-only.' An agent can tell this is a single-item fetch rather than a listing or mutation without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives concrete navigation for both identifiers: 'To find job_id: list_jobs → match by name' and 'For approval_flow_id: list_approvals_for_job.' That is strong routing to prerequisite calls, though it never states when NOT to use this tool or contrasts it against list_approvals_for_job/list_pending_approvals as alternatives.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_boardA

Get job board metadata — name, content, departments, offices. Read-only.

Returns the public-facing board info. For internal job management, use list_jobs instead.

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden; it does explicitly declare 'Read-only,' which is the key safety trait. However, it says nothing about authentication/permission requirements or the scope of 'public-facing' data exposure, which matters for a board-metadata call.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, front-loaded with what is returned and the key read-only trait, followed by the alternative. No filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With no parameters and an output schema already defining the return shape, the description only needs to state purpose and scope, which it does. Nothing an agent needs to call it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The tool takes zero parameters, so there is no parameter semantics to document and the baseline of 4 applies. The description's enumeration of returned fields is bonus context rather than a substitute for missing param docs.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ('Get job board metadata') and enumerates the returned fields (name, content, departments, offices), so the agent knows exactly what this retrieves. It differentiates from list_jobs, but not from the many other board-prefixed siblings (get_board_job, list_board_departments, get_board_office, etc.), leaving some ambiguity in a dense sibling set.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly frames this as the public-facing board metadata tool and names the alternative for the internal case ('For internal job management, use list_jobs instead'). Clear context and one concrete alternative, though it doesn't mention when to prefer the board-specific siblings like get_board_department.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_board_departmentB

Get a department from the public job board. Read-only.

ParametersJSON Schema
NameRequiredDescriptionDefault
department_idYesBoard department ID — from list_board_departments

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

B3.2/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full behavioral burden. It does disclose the single most important trait for a getter ('Read-only'), which is genuine signal. However it says nothing about authentication, whether the board is publicly accessible without a token, or error behavior on unknown IDs.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short fragments, zero waste, and the resource scope is front-loaded. It is appropriately sized for a simple read tool, though it is so terse that it reads more like a label than a specification.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness3/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be explained, and the single parameter is fully described in the schema. What is missing is usage context relative to the large sibling set and any behavioral detail beyond 'read-only', leaving it adequate but thin.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and the sole parameter is fully documented in the schema (including its provenance from list_board_departments). The description adds no additional meaning, so the baseline of 3 for high coverage applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ('Get a department') scoped to 'the public job board', which implicitly distinguishes it from the internal get_department and from the list-oriented list_board_departments. It does not name a sibling explicitly, but the 'board' qualifier gives enough scope to tell it apart.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines2/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

There is no guidance on when to use this versus the many sibling lookups (get_department, get_board_office, list_board_departments). No prerequisites, no exclusions, no mention of how the ID is obtained beyond what the schema already says.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_board_jobA

Get a published job with optional application questions. Read-only.

For internal job details (hiring team, custom fields), use get_job instead.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesBoard job ID — from list_board_jobs
questionsNoInclude application questions

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description must carry the behavioral burden, and it does declare 'Read-only' — a genuine safety signal. However it says nothing about permissions, pagination, or whether the operation can fail for unpublished jobs, so the disclosure stops at the most basic trait.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences with zero filler; the core purpose and the read-only trait are front-loaded, and the routing hint to get_job follows immediately.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values needn't be explained, and the description covers purpose, safety, and sibling routing adequately. Gaps remain around error/failure conditions and permissions, which an agent might want before calling.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so both parameters are already documented in the schema, including the note that job_id comes from list_board_jobs and that questions defaults to false. The description's phrase 'optional application questions' only restates the schema, so baseline 3 applies with no added value.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Get a published job') and adds scope ('with optional application questions'). It explicitly contrasts itself with the sibling get_job, so an agent can distinguish the two without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Names the alternative (get_job) and the exact condition that selects it (internal job details: hiring team, custom fields). The schema further anchors the source of job_id to list_board_jobs, leaving nothing to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_board_officeB

Get an office from the public job board. Read-only.

ParametersJSON Schema
NameRequiredDescriptionDefault
office_idYesBoard office ID — from list_board_offices

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

B3.2/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden, and 'Read-only' usefully discloses the safety profile that annotations would normally provide. Beyond that it says nothing about permissions, error behavior, or scoping; the output schema covers return values, so this is a minimum-viable 3.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, front-loaded with the operation and scope. No filler, though the 'Read-only' clause is a bare tag rather than an elaborated point.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a single-param read tool with a full output schema and 100% param coverage, the description supplies what's needed: the resource, its scope (public board), and the safety profile. Only richer usage routing would improve it.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and the single office_id param is documented in-schema as coming from list_board_offices. The description adds no syntax or format detail beyond the schema, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (Get) and resource (office) and scopes it to the 'public job board', which meaningfully distinguishes it from sibling get_office / list_offices. It stops short of naming the sibling alternatives explicitly, so it earns a 4 rather than a 5.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines2/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description offers no when-to-use or when-not guidance and no routing to alternatives like list_board_offices or get_office. 'Read-only' is a safety trait, not usage context, so the agent must infer selection from the name alone.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_bulk_request_statusA

Check the progress of any v3 bulk request. Read-only.

Use after a bulk tool returns a bulk_action_uuid (bulk job openings, custom field options in batches over 50). Returns status (building/pending/in_progress/completed/failed), record_count, success_count, failure_count, and short-lived result URLs.

ParametersJSON Schema
NameRequiredDescriptionDefault
bulk_action_uuidYesbulk_action_uuid returned by any bulk tool

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does useful work: it declares 'Read-only', enumerates the terminal and intermediate statuses, and warns that result URLs are 'short-lived'. However, it omits polling guidance (how often to re-check, when to give up) and permission requirements, leaving meaningful behavioral gaps for a status-polling tool.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three sentences, front-loaded with the core purpose and the read-only property, followed by the trigger condition and the return summary. No filler or repetition.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so the description is not obliged to enumerate return fields, yet it usefully summarizes the status lifecycle and counts. Combined with the explicit trigger condition, an agent has enough to call it correctly; only the absence of polling cadence guidance keeps it from a 5.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

There is only one parameter and schema coverage is 100%; the schema already documents bulk_action_uuid as 'returned by any bulk tool'. The description's mention of the same provenance adds no syntax or format detail beyond the schema, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb ('Check the progress') and resource ('v3 bulk request'), and the 'v3' qualifier plus 'bulk' scope cleanly distinguishes it from sibling reads like get_job_opening or list_applications. An agent can identify this as the polling companion to the bulk_* tools without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives an explicit trigger: 'Use after a bulk tool returns a bulk_action_uuid (bulk job openings, custom field options in batches over 50)', which tells the agent exactly when this tool becomes relevant. It stops short of naming alternatives or stating when not to use it (e.g. don't poll before a bulk call), so it does not reach a full 5.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_candidateA

Get a candidate's full profile by ID. Read-only.

Returns name, contact info, tags, custom fields, plus (fetched alongside, since v3 no longer embeds them) applications (each with id, job_id, job_name, stage_name, job_interview_stage_id, status), attachments (with time-limited download URLs), educations (with school/degree/discipline names) and employments. This is the central lookup — most workflows route through here after resolving a name via search_candidates_by_name. For a screening package with resume and location, use screen_candidate.

ParametersJSON Schema
NameRequiredDescriptionDefault
candidate_idYesGreenhouse candidate ID
include_relatedNoAlso fetch applications, attachments, educations and employments (default true; false returns the bare profile)

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the behavioral burden and does so well: it declares 'Read-only', notes the v3 change that applications are no longer embedded but fetched alongside, and warns that attachment download URLs are time-limited. It omits any auth/permission requirements, but for a read tool the disclosure is substantially richer than the structured fields alone.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with purpose and read-only status, then a scannable list of returned entities. The return enumeration is somewhat long and partially redundant given an output schema exists, but the time-limited-URL note and the routing sentence earn their place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a get-by-ID tool with a full output schema and fully documented parameters, the description covers read-only status, related-data fetching behavior, and workflow positioning. Nothing an agent needs to invoke it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so both candidate_id and include_related (including its default and false-behavior) are already documented. The description never explicitly discusses include_related, so it adds no meaning beyond the schema — the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description opens with a specific verb+resource ('Get a candidate's full profile by ID') and clearly distinguishes itself from siblings by naming search_candidates_by_name (name resolution) and screen_candidate (screening package). An agent can identify the tool's role without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It gives explicit routing guidance ('most workflows route through here after resolving a name via search_candidates_by_name') and states the alternative for a different need ('For a screening package with resume and location, use screen_candidate'). Both when-to-use and when-to-use-something-else are covered.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_current_offerA

Get the current (latest version) offer for an application. Read-only.

Returns 404 if the application has no offer. To find application_id: search_candidates_by_name → list_applications(candidate_id=...) → match the application to the job.

ParametersJSON Schema
NameRequiredDescriptionDefault
application_idYesGreenhouse application ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.8/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full behavioral burden and does disclose two meaningful traits: the operation is read-only and it returns 404 when the application has no offer. That error semantics is genuinely useful, but it omits permission/scope requirements and whether non-approved offer versions are included in 'current'.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The core action and read-only trait are front-loaded, and the follow-up sentences add ID-discovery and error context without padding. The arrow-chain workflow is terse and slightly cryptic, and 'match the application to the job' is a bit vague, keeping it from a 5.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation, and the description covers purpose, error behavior, and ID discovery. It is nearly complete for a simple one-parameter read tool, with only alternative-tool routing and permission scoping left unaddressed.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the parameter is already documented, but the description adds real value by explaining the retrieval workflow for obtaining application_id rather than just restating it. That goes beyond the schema's 'Greenhouse application ID' label.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource (get the current/latest offer for an application) and clarifies the version semantics with 'current (latest version)'. It does not name or differentiate itself from the sibling get_offer or list_offers_for_application, so it falls short of a 5.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It provides actionable context by explaining how to obtain application_id (search_candidates_by_name → list_applications → match) and notes the 404 case. However, it never says when to use this over the sibling get_offer (which likely takes an offer_id) or list_offers_for_application, leaving the alternative selection implicit.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_custom_fieldA

Get a custom field definition by ID. Read-only.

Returns field name, name_key, field type, value type, and configuration. For single/multi-select fields, custom_field_options lists the dropdown options. To find custom_field_id: list_custom_fields → match by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
custom_field_idYesCustom field ID — get from list_custom_fields

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the behavioral burden. It usefully discloses 'Read-only' and describes the returned shape, but omits auth/permission requirements and error behavior that would matter for a no-annotation tool.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the core purpose in the first sentence, then layers return format and the ID-lookup hint. Three short sentences with no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a single-parameter read-only getter with an output schema present, the description is complete: it names the resource, the safety profile, the returned fields, select-option behavior, and how to source the ID.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% and the single parameter is documented in the schema itself. The description's lookup hint (match by name) echoes what the schema description already says, adding only marginal value.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (Get) and resource (a custom field definition) scoped by ID, which cleanly separates it from list_custom_fields, create_custom_field, update_custom_field, and delete_custom_field. An agent can distinguish its role from the sibling set without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly routes the agent to the right way to obtain the required ID: 'To find custom_field_id: list_custom_fields → match by name.' It gives clear context for use but does not state when-not to use this tool vs. the option-related siblings.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_departmentA

Get a department by ID. Read-only.

Returns name, parent_id, external_id, and child_ids (direct child departments). To find department_id: list_departments → match by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
department_idYesDepartment ID — get from list_departments

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are supplied, so the description must carry the safety profile \u2014 and it does, explicitly labeling the call 'Read-only'. That is the key behavioral trait for a simple fetch. It adds no further context (auth scope, error behavior), but for a one-parameter read tool this is close to sufficient.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the verb and resource, then packs the read-only note, return shape, and ID-lookup tip into two tight sentences. The field enumeration is slightly redundant given an output schema exists, keeping it just short of ideal.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With 100% schema coverage and an output schema present, the description doesn't need to explain return values and is essentially complete: purpose, read-only nature, and how to source the ID are all covered. Only richer operational context (errors, permissions) is absent, which is minor for this tool.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the single parameter is already fully documented in the schema, establishing a baseline of 3. The description's 'match by name' hint mildly enriches the schema's 'get from list_departments' note but does not add substantive syntax or format detail.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Get a department by ID'), which unambiguously distinguishes it from siblings like list_departments, create_department, and update_department. An agent can select it without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides a concrete recovery path for the required input ('To find department_id: list_departments → match by name'), effectively routing to the correct alternative for ID discovery. It stops short of explicitly stating when a single lookup is preferable to listing all departments, so it's clear context rather than full when/when-not guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_eeoc_for_applicationA

Get EEOC data for a specific application. Read-only.

To find application_id: search_candidates_by_name → list_applications(candidate_id=...) → match the application to the job.

ParametersJSON Schema
NameRequiredDescriptionDefault
application_idYesGreenhouse application ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.7/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden. It discloses the key behavioral trait ('Read-only'), which is good, but says nothing about what EEOC data contains, permissions, or rate limits. Adequate but not rich.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short lines, front-loaded with purpose followed by the parameter-discovery workflow. No wasted words and everything earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With an output schema present, return values need not be explained, and the single-param getter is well covered. The only gap is lack of differentiation from the sibling list_eeoc.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the schema already documents application_id as the Greenhouse application ID (baseline 3). The description adds real value by explaining the multi-step workflow to obtain that ID, exceeding the schema.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Get EEOC data for a specific application'), so the agent knows exactly what it returns. It does not, however, distinguish itself from the sibling list_eeoc, leaving the boundary between the two to inference.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description gives a concrete discovery path for the required application_id (search_candidates_by_name -> list_applications -> match to job), which is genuinely useful. It offers no explicit when-to-use vs. when-not guidance, e.g., how it differs from list_eeoc or get_application.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_email_templateA

Get an email template by ID. Read-only.

Returns template name, subject, body or html_body, email_type and sender settings. To find template_id: list_email_templates → match by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
email_template_idYesEmail template ID — get from list_email_templates

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full behavioral burden, and it does declare 'Read-only' plus the returned fields (name, subject, body/html_body, email_type, sender settings). It does not cover auth requirements or error behavior (e.g. invalid ID), which is the main remaining gap.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Purpose is front-loaded in the first sentence, followed by behavior and then the ID-discovery hint. Three short, purposeful lines with essentially no waste.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a one-parameter read tool with an output schema already describing return values, the definition covers purpose, safety, and ID acquisition. It is essentially complete, with only minor omissions like error/not-found behavior.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the single parameter is already documented in the schema. The description's guidance ('get from list_email_templates') largely duplicates the schema description, so it adds little beyond the baseline.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Get an email template by ID') and implicitly separates itself from the sibling list_email_templates by emphasizing lookup by ID. An agent can distinguish this single-fetch tool from the listing tool without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly tells the agent how to obtain the required ID ('list_email_templates → match by name'), which is effectively a routing instruction to the sibling. It lacks an explicit when-not-to-use clause, but the discovery workflow is clearly spelled out.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_hiring_teamA

Get the hiring team for a job. Read-only.

Users say "who's on the hiring team for Backend Engineer?" To find job_id: list_jobs → match by name. Returns members grouped by role: hiring_managers, recruiters, coordinators and sourcers. Each member has id (user ID), name, first_name, last_name, employee_id, responsible (recruiters/coordinators) and assignment_id.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full safety burden and does disclose "Read-only," which is the most important behavioral trait. It also describes the returned grouping and member fields, though it omits permission requirements, error behavior, or pagination details.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The definition is front-loaded with purpose and read-only status, then provides a natural-language query example and job_id lookup instruction. The return-field enumeration is slightly redundant because an output schema exists, but it remains efficient and readable.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a simple single-parameter read-only getter with a 100%-covered schema and an output schema, the description supplies everything needed: purpose, safety signal, prerequisite lookup, and return shape. No critical invocation context is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is already 100% for the single job_id parameter, so the baseline is 3. The description adds meaningful guidance beyond the schema by explaining that job_id can be found via list_jobs and matched by job name.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description opens with a specific verb and resource: "Get the hiring team for a job." The added "Read-only" qualifier clearly distinguishes it from sibling mutation tools such as add_hiring_team_members, remove_hiring_team_member, and replace_hiring_team.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It gives a concrete prerequisite for obtaining the required job_id via list_jobs, which is useful. However, it does not explicitly state when to use this tool versus its add/remove/replace hiring-team siblings or any when-not-to-use conditions, leaving usage largely implied.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_interviewA

Get a scheduled interview by ID. Read-only.

Returns details: application, interview name, interviewers, organizer, times, location, and status. To find interview IDs: list_interviews_for_application on the candidate's app.

ParametersJSON Schema
NameRequiredDescriptionDefault
interview_idYesScheduled interview ID — from list_interviews_for_application

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden, and it does declare 'Read-only' up front plus the shape of the returned details (application, interviewers, organizer, times, status). It omits permission/auth requirements and any caveats about restricted or deleted interviews, so it is good but not exhaustive.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short lines, zero filler: purpose and read-only nature first, return contents second, ID-discovery route last. Every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a single-parameter read tool with an output schema present, the description covers the operation, its safety profile, and how to obtain the required ID. Nothing an agent needs to invoke it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% with a single integer parameter, and the description's note about where IDs come from ('list_interviews_for_application') repeats what the schema property description already says. Baseline 3 is appropriate — it adds no syntax or format detail beyond the schema.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Get a scheduled interview by ID'), plus a behavioral qualifier ('Read-only') and an enumeration of the returned fields. It is unambiguously distinct from list_interviews, list_interviews_for_application, and update_interview/delete_interview among the many siblings.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It explicitly routes the agent to the right companion tool for discovering the required ID ('list_interviews_for_application on the candidate's app'), which is exactly the prerequisite an agent needs. It does not phrase this as an explicit when-not-to-use statement, but the alternative is named and the condition that selects it is clear.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_jobA

Get full details for a job by ID. Read-only.

Returns name, status, requisition_id, notes, custom fields, department and offices ({id, name}), openings, and the hiring team (hiring_managers, recruiters, coordinators, sourcers as {id, name, email}). Use list_jobs to find the job_id by name first. For the public listing, use list_job_posts_for_job. For pipeline stages, use list_job_stages_for_job.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the load; it declares the operation 'Read-only' and enumerates the returned shape (fields, nested {id, name}, hiring team roles). It stops short of stating auth/permission requirements or rate limits, so it is strong but not fully exhaustive for a no-annotation tool.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the core purpose and read-only trait, then the return shape, then the alternatives. The return-field enumeration is long but each grouping (team roles, offices, custom fields) is genuinely informative, so it mostly earns its space.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a single required parameter read tool with 100% schema coverage and an output schema present, the description is complete: it covers the purpose, read-only nature, what is returned, and how to obtain the ID. Nothing an agent needs to invoke it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% and the schema already describes job_id as a Greenhouse job ID, so the baseline is 3. The description adds meaningful guidance beyond the schema by telling the agent to resolve the job_id via list_jobs by name first.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Get full details for a job by ID') and further scopes it against siblings, naming list_jobs, list_job_posts_for_job, and list_job_stages_for_job as the tools for their respective concerns. An agent can tell exactly what this returns versus the list/stage/post siblings.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly says to use list_jobs first to resolve a job name to a job_id, and routes the agent elsewhere for the public listing and pipeline stages. Both the when-to-use and the when-to-use-something-else conditions are stated.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_job_openingA

Get a specific opening on a job. Read-only.

Returns open/status, close_reason_id, custom fields, and the hired application_id if filled. To find job_id: list_jobs → match by name. To find opening_id: list_job_openings on the job.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID
opening_idYesOpening ID within the job — get from list_job_openings

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.5/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are supplied, so the description carries the full behavioral burden; it does declare 'Read-only' and enumerates what is returned (open/status, close_reason_id, custom fields, hired application_id), which is the key trait for a fetch tool. It omits error behavior (e.g., nonexistent opening_id) and permission requirements, keeping it below a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short lines: purpose and read-only first, return shape second, ID-acquisition recipes last. Every sentence is load-bearing and nothing is padded.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a simple two-parameter read tool with a full output schema, the description covers purpose, safety posture, return contract, and prerequisites. An agent has everything needed to call it correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3. The description adds value beyond the schema by explaining how to obtain job_id (list_jobs → match by name), which the schema only labels 'Greenhouse job ID', while opening_id guidance largely duplicates the schema text.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

Specific verb+resource ('Get a specific opening on a job'), scoped as a single-resource fetch. The description and the id hints clearly distinguish it from list_job_openings, create_job_opening, and update_job_opening, so an agent can select it without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It provides the concrete workflow for obtaining both required IDs ('list_jobs → match by name' and 'list_job_openings on the job'), which is real usage guidance rather than a bare statement. It stops short of explicit when-not-to-use or alternative-tool routing, so it does not reach a 5.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_job_postA

Get a job post by ID. Read-only.

Returns title, content (HTML), live status, job_id, job_board_id, public_url, application questions, and locations. To find post IDs: list_job_posts_for_job.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_post_idYesJob post ID — get from list_job_posts or list_job_posts_for_job

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.5/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full behavioral burden. It helpfully labels the operation 'Read-only' and enumerates the returned fields, which conveys a safe non-mutating profile. It says nothing about permissions, visibility rules for deactivated posts, or rate limits, so the disclosure is adequate but not rich.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The definition is brief and front-loads the core operation before the return list and the ID hint. Every sentence serves a purpose, though the enumerated return fields are partly redundant with the available output schema.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a single-parameter read tool with an output schema already present, the description covers the essentials: what it returns, that it is read-only, and where to get the ID. Nothing critical is missing, though clarifying its relationship to get_job_post_for_job would make it fully complete.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the single parameter's meaning and source are already documented in the schema. The description's 'by ID' and the ID-sourcing hint add marginal value but no syntax or format detail beyond the schema, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description gives a specific verb and resource ('Get a job post by ID'), making the operation immediately clear. It does not, however, distinguish itself from the close sibling get_job_post_for_job, so an agent still can't fully disambiguate from the description alone.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It provides a useful pointer for sourcing the required ID ('To find post IDs: list_job_posts_for_job'), which is implied usage guidance tied to the parameter. It stops short of stating when to prefer this tool over get_job_post_for_job or list_job_posts, so the when-to-use logic is only partially covered.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_job_post_custom_locationsA

Get the custom-list locations selected on a job post. Read-only.

Custom locations are per-job-board dropdown values. Returns {"items": [{id, value, active, greenhouse_job_board_id, job_post_location_id}]}. For all of a post's locations (free text, office, custom), use get_job_post. To find job_post_id: list_job_posts_for_job.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_post_idYesJob post ID — get from list_job_posts

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.5/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the burden: it declares 'Read-only' and discloses the exact return envelope, plus contextualizes custom locations as per-job-board dropdown values. It omits pagination/auth notes, but for a single read tool this is substantial disclosure.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the purpose, then adds scope, return shape, sibling routing, and ID sourcing in tight, non-redundant lines. Every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With one parameter, 100% schema coverage, a read-only nature, and sibling routing all covered, an agent has everything needed to select and invoke this correctly. An output schema exists, so return-shape detail is a bonus rather than a gap.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% and the sole parameter's description already documents where to get job_post_id. The description restates that sourcing hint but adds no syntax or format detail beyond the schema, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ('Get the custom-list locations selected on a job post') and explicitly distinguishes itself from get_job_post, which returns all location types. The agent can tell this narrow tool apart from its broad sibling without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Names the alternative and the condition that selects it ('For all of a post's locations ... use get_job_post') and gives the prerequisite for the ID ('To find job_post_id: list_job_posts_for_job'). When-to-use and how-to-source-the-argument are both explicit.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_job_post_for_jobA

Get a specific job post scoped to a job. Read-only.

Same as get_job_post, but returns 404 if the post doesn't belong to the job. To find job_id: list_jobs → match by name. To find post_id: list_job_posts_for_job.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID
job_post_idYesJob post ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.7/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden, and it delivers meaningfully: it declares 'Read-only' and specifies the 404 behavior when the post does not belong to the job. It omits auth/permission requirements and rate-limit behavior, which are the remaining gaps for a no-annotation tool.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, front-loaded with the core purpose and the differentiating 404 behavior, then prerequisite lookups. Every sentence earns its place with no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With an output schema present, the description needn't explain return values, and it covers what matters: scope, read-only nature, error semantics, and ID discovery. An agent has everything needed to call it correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3; the description goes beyond the schema by explaining how to obtain each required ID (list_jobs → match by name; list_job_posts_for_job), which is genuine operational value not present in the field descriptions.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (get) and resource (job post) with an explicit scope qualifier ('scoped to a job'). It directly names and contrasts with the sibling get_job_post, so the agent can select between them without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly says to use get_job_post for the general case and this tool when the post must belong to the job (404 otherwise). It also provides prerequisite routing for both required IDs (list_jobs, list_job_posts_for_job), leaving nothing to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_job_stageA

Get a single stage by ID. Read-only.

Returns stage name, sort_order, job_id, and its configured interviews. Usually list_job_stages_for_job is more useful — it gives all stages in pipeline order.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_stage_idYesJob stage ID — get from list_job_stages_for_job

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are supplied, so the description carries the full burden. It does declare the safety profile ('Read-only') and describes the returned payload, which is the key behavioral disclosure for a lookup tool. It omits any note on auth/permissions or error behavior for an invalid ID, keeping it below a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, front-loaded with the verb/resource, then the safety label, then the return fields and the sibling recommendation. Every sentence earns its place with no redundancy.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so the return-value enumeration is supplementary rather than required, and the description still covers what matters for invoking the tool correctly. It is complete for a simple read, though it could note the invalid-ID/error case.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and the single parameter already documents its origin ('get from list_job_stages_for_job'). The description adds no format or lookup detail beyond the schema, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Get a single stage by ID') and enumerates what is returned (name, sort_order, job_id, interviews). It also names the sibling tool list_job_stages_for_job, so an agent can distinguish this single-stage fetch from the list variant without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly routes the agent: 'Usually list_job_stages_for_job is more useful — it gives all stages in pipeline order.' This is clear conditional guidance toward the alternative. It stops short of stating when a single-stage fetch IS the right call (e.g., when the ID is already known), so it is not fully bidirectional guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_offerA

Get a single offer by ID. Read-only.

Returns offer status, version, starts_on, sent_on, resolved_at, opening_id, and custom fields.

ParametersJSON Schema
NameRequiredDescriptionDefault
offer_idYesOffer ID — get from list_offers or list_offers_for_application

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.6/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full behavioral burden and does disclose 'Read-only', which is a useful safety trait. However, it says nothing about permission requirements, behavior when the ID does not exist, or rate limits, and the listed return fields duplicate what the output schema already provides.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, front-loaded with the core action and scoping, followed by the safety note and return summary. No filler or redundancy.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a simple single-record lookup with a 100%-covered schema and an output schema, the description is largely sufficient, and it usefully adds the read-only guarantee that missing annotations would otherwise leave unstated. Minor gaps around not-found/error behavior keep it from a 5.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and the single parameter is fully documented in the schema, including where to source the ID. The description adds no syntax or format detail beyond 'by ID', so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific verb and resource ('Get a single offer by ID') and scopes it to one record, which distinguishes it from plural siblings like list_offers and the differently-scoped get_current_offer. An agent can identify the tool without opening its schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines2/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description gives no explicit when-to-use guidance, no when-not conditions, and does not name alternatives such as list_offers or get_current_offer. The only routing hint (fetch the ID from list_offers) lives in the schema's parameter description, not the tool description.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_officeA

Get an office by ID. Read-only.

Returns name, location, parent_id, and child_ids (direct child offices). To find office_id: list_offices → match by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
office_idYesOffice ID — get from list_offices

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden — and it does disclose the safety profile ('Read-only') plus the exact returned fields. It does not mention failure behavior for an unknown ID or any permission requirements, but for a trivial lookup this is near-complete disclosure.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Four short sentences, zero filler, with the core action and read-only nature front-loaded before the ID-acquisition hint. Every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so the description need not explain return values, and it already summarizes them as a bonus. For a one-parameter lookup, nothing an agent needs in order to invoke it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and the schema already states 'get from list_offices', which the description repeats rather than extends. Baseline 3 applies: the single integer parameter needs no additional semantic nuance beyond the schema.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Get an office by ID') and names what it returns (name, location, parent_id, child_ids). It also implicitly distinguishes itself from the list_offices sibling by describing single-record lookup, so an agent can tell the two apart without opening schemas.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives an explicit prerequisite workflow: 'To find office_id: list_offices → match by name.' That is clear context for when and how to call it. It stops short of naming exclusions (e.g., get_board_office for board-scoped data), so it is strong but not fully routing-aware.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_prospect_poolA

Get a prospect pool and its stages by ID. Read-only.

To find prospect_pool_id: list_prospect_pools → match by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
prospect_pool_idYesProspect pool ID — get from list_prospect_pools

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full behavioral burden. It does disclose the key trait ('Read-only') and hints that the payload includes stages, but says nothing about permissions, pagination, or behavior for a nonexistent ID. An output schema exists, so return-value detail is not required.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short lines with zero filler; the read-only qualifier and the ID-sourcing instruction are front-loaded and immediately actionable.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a single-parameter read tool with an output schema, the description covers purpose, safety profile, and prerequisite lookup. The only gap is not relating it to the overlapping retrieve_prospect_pools sibling, which an agent could plausibly confuse it with.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and the single parameter is already documented as coming from list_prospect_pools, so the description merely restates the schema's guidance. Baseline 3 applies when the schema does the heavy lifting and the description adds no new syntax or format meaning.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Get a prospect pool and its stages by ID'), and explicitly distinguishes itself from list_prospect_pools by casting that sibling as the lookup helper rather than the retrieval tool. An agent can tell it apart from list_prospect_pools and retrieve_prospect_pools without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives explicit routing guidance: to obtain the required ID, use list_prospect_pools and match by name. It does not, however, address when to prefer this tool over the similarly-named retrieve_prospect_pools sibling, leaving one alternative unaddressed.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_prospect_post_sectionB

Get a prospect post section by ID. Read-only.

ParametersJSON Schema
NameRequiredDescriptionDefault
section_idYesSection ID — from list_prospect_post_sections

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

B3.2/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description must carry the behavioral burden; 'Read-only' is a useful, explicit safety claim for a fetch operation. However, it says nothing about failure behavior (invalid/missing ID), permissions, or scoping, which is thin for a tool with no structured annotation coverage.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two very short sentences with the operation stated first and nothing wasted. It is efficiently front-loaded, though it stops short of being information-dense.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a one-parameter fetch with an output schema and full schema coverage, the definition is nearly sufficient, and 'Read-only' compensates for the absence of annotations. The main gap is that the provenance of the ID and its relationship to sibling tools is not stated in the description.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

There is a single parameter with 100% schema description coverage, and the schema already explains where the ID comes from. The description adds only 'by ID', which does not meaningfully extend the schema, so the baseline 3 is appropriate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Get a prospect post section by ID'), so an agent knows exactly what entity is fetched. It does not differentiate itself from the sibling list_prospect_post_sections, though that linkage appears only in the schema, not the description.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines2/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description gives no guidance on when to use this versus list_prospect_post_sections or other lookups. The only routing hint ('from list_prospect_post_sections') lives in the parameter schema description, not in the tool description itself.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_questionA

Get a demographic question by ID. Read-only.

To find IDs: list_questions or list_questions_for_question_set.

ParametersJSON Schema
NameRequiredDescriptionDefault
question_idYesDemographic question ID — get from list_questions

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.8/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden. It does disclose 'Read-only', which is the most important trait for a fetch tool, but says nothing about behavior on an invalid or missing ID, permissions, or scoping. Adequate but thin for a zero-annotation tool.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, purpose front-loaded and the ID-sourcing hint immediately after. No filler or restatement of the schema.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With one fully documented parameter, an output schema that covers return values, and an explicit read-only statement, the definition gives an agent everything needed to invoke it correctly. Only the absence of error/permission behavior keeps it from a 5.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and the single question_id parameter is documented with its own 'get from list_questions' note, so the schema already does the work. The description adds no syntax or format detail beyond that, making the baseline 3 appropriate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource with added specificity beyond the name ('Get a demographic question by ID'), so an agent knows it fetches one record rather than a list. It does not explicitly contrast itself with list_questions, but the ID-based retrieval makes the distinction inferable.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly tells the agent how to obtain the required input by pointing at list_questions and list_questions_for_question_set, which is exactly the prerequisite an agent needs before calling. It lacks any when-not guidance (e.g. when to prefer list_questions over this), keeping it short of a 5.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_question_setA

Get a demographic question set by ID. Read-only.

To find IDs: list_question_sets.

ParametersJSON Schema
NameRequiredDescriptionDefault
question_set_idYesQuestion set ID — get from list_question_sets

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.6/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden. It does disclose "Read-only," which is genuinely helpful for a fetch tool, but says nothing about failure behavior (e.g., unknown ID), permissions, or whether the set includes questions. An output schema exists, so return-value detail is not required.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short, front-loaded sentences with no filler; the core action leads and the ID-sourcing hint follows. Every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a simple single-parameter read with an output schema, the definition covers the essentials: what it returns, that it is read-only, and where the ID comes from. Only minor behavioral detail (error handling, permissions) is absent, which is acceptable given the low complexity.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% for the single parameter, which already documents "Question set ID — get from list_question_sets." The description restates the same ID-sourcing point, adding no format or type meaning beyond the schema, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ("Get a demographic question set by ID") and implicitly distinguishes itself from the sibling list_question_sets. The scope is unambiguous, though it does not explicitly frame the contrast beyond pointing at the list tool for IDs.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

"To find IDs: list_question_sets" is useful procedural guidance on sourcing the required argument, but the description never states when to use this tool versus the list or other question-related siblings. Usage is largely implied by the name.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_scorecardA

Get a single scorecard by ID. Read-only.

Returns the interviewer, interview, attribute ratings, question answers, notes, and overall recommendation (candidate_rating). To find scorecard IDs: list_scorecards_for_application.

ParametersJSON Schema
NameRequiredDescriptionDefault
scorecard_idYesScorecard ID — get from list_scorecards or list_scorecards_for_application

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the behavioral burden and does declare "Read-only," the single most important safety trait for this operation. It also scopes what comes back, but says nothing about permission requirements or failure modes (e.g., a nonexistent or unauthorized scorecard ID), leaving some behavioral gaps.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the verb+resource and the read-only flag, then the ID source, with no filler sentences. The enumerated return fields are partly redundant given an output schema exists, which is the only mild inefficiency.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

A one-parameter getter with a full output schema needs little description; the ID source, scope, and read-only nature are all present. Missing only auth/error context, which is a minor gap for a simple read.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% and the schema already documents that scorecard_id comes from list_scorecards or list_scorecards_for_application, so the description's ID hint is largely redundant. The description is actually slightly narrower than the schema, which names both list tools.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ("Get a single scorecard by ID") and the singular scope distinguishes it from the list_scorecards / list_scorecards_for_application siblings. An agent can route between the getter and the listers without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It tells the agent how to satisfy the required parameter ("To find scorecard IDs: list_scorecards_for_application"), which is the main usage question for a single-record fetch. It does not state when not to use it (e.g., when you need all scorecards for an application, use the lister), so it stops short of full routing guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

get_userA

Get a Greenhouse user's profile by ID. Read-only.

Returns name, primary_email, emails (all addresses with verified flag), site_admin, deactivated status, and the user's offices and departments (with names). To find user_id: list_users → match by name or email. For job-level access, see list_job_permissions.

ParametersJSON Schema
NameRequiredDescriptionDefault
user_idYesGreenhouse user ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden, and it does declare 'Read-only' plus enumerates returned fields, which is genuine context. It omits any permission/visibility requirements (e.g., whether admin scope is needed to see other users) and says nothing about the response envelope beyond the field list.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Purpose is front-loaded, followed by return fields, ID sourcing, and a related-tool pointer. The enumerated field list is somewhat redundant given an output schema exists, but the overall structure is efficient and scannable.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be re-explained, and the description still covers purpose, the single required parameter's origin, and a cross-reference to a related tool. Only the absence of auth/permission context for reading other users keeps it from being fully complete.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so baseline is 3, but the description adds real value by explaining how to derive user_id via list_users. It still doesn't clarify the ID's format/namespace, but the sourcing guidance goes beyond the bare 'Greenhouse user ID' schema text.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Get a Greenhouse user's profile by ID') and scopes it to a single user, distinguishing it from siblings like list_users, get_current_user, and list_user_roles. An agent can tell exactly what it returns and for whom.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly tells the agent how to obtain the required user_id (list_users → match by name or email) and redirects to list_job_permissions for job-level access. It does not, however, contrast with get_current_user, which is a plausible alternative when the caller wants their own profile.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

hire_applicationA

Mark a candidate as hired. Write operation — finalizes the hiring decision.

Users say "hire Sarah for the Backend role." To get the application_id: search_candidates_by_name → get_candidate → match the application to the job. Optionally fills a job opening (opening_id from list_job_openings) and records a close reason (close_reason_id from list_close_reasons).

ParametersJSON Schema
NameRequiredDescriptionDefault
opening_idNoJob opening to fill — get from list_job_openings
start_dateNoHire start date: 'YYYY-MM-DD' or an ISO 8601 date-time
application_idYesGreenhouse application ID
close_reason_idNoReason for closing the opening — get from list_close_reasons

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden. It does disclose the mutation ('Write operation — finalizes the hiring decision') and two side effects (filling a job opening, recording a close reason), which is useful. It omits reversibility, permission requirements, and what happens to the application's stage, leaving meaningful gaps for a destructive/final write.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the core action and its write nature, followed by the ID-sourcing guidance. The 'Users say...' line is a minor stylistic flourish but earns its place by anchoring the natural-language trigger, and the rest is terse.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be explained, and the description covers purpose, the required-parameter retrieval path, and the two optional side effects. It is close to complete for a four-parameter finalize tool, with only permission/reversibility context missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so all four parameters are already documented, including their sourcing tools. The description reinforces where opening_id and close_reason_id come from but adds no format or constraint detail beyond the schema. Baseline 3 is appropriate when the schema does the heavy lifting.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Mark a candidate as hired') and adds scope ('finalizes the hiring decision'), which distinguishes it from adjacent siblings like advance_application, reject_application, and update_application. An agent can identify the terminal hire action without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives a concrete retrieval chain for the required application_id (search_candidates_by_name → get_candidate → match to job) and points to list_job_openings and list_close_reasons for the optional IDs. It does not explicitly state when to use this versus advance_application or offer tools, but the 'finalizes the hiring decision' framing strongly implies the end-of-pipeline condition.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_answer_optionsB

List all demographic answer options across all questions. Read-only.

Each option has name, demographic_question_id, free_form, decline_to_answer, active and sort_order.

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

B3.4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations present, the description carries the full behavioral burden and does disclose the key trait 'Read-only', which is genuinely useful. However it says nothing about pagination, ordering guarantees (despite listing sort_order as a field), or volume, which matters for an unpaginated list across all questions.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with purpose, then the read-only trait, then the field inventory. Two short sentences, no filler; the 'Read-only.' fragment is terse but effective.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a zero-parameter read tool with an output schema present, the description is nearly complete — the field list is somewhat redundant with the output schema, and pagination behavior is the only real gap.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The tool takes zero parameters, so the baseline of 4 applies. The description correctly adds nothing on parameters because there are none to describe.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List all demographic answer options') and pins the scope as 'across all questions', which implicitly distinguishes it from the sibling list_answer_options_for_question. It never names that sibling, so differentiation is inferable rather than explicit.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines2/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

There is no statement of when to use this versus list_answer_options_for_question or get_answer_option. The 'across all questions' scope hints at the distinction but the description offers no routing guidance or exclusions.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_answer_options_for_questionA

List answer options for a specific demographic question. Read-only.

To find question_id: list_questions or list_questions_for_question_set.

ParametersJSON Schema
NameRequiredDescriptionDefault
question_idYesDemographic question ID — get from list_questions

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.8/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden, and it does disclose 'Read-only' — a genuinely useful trait. However it says nothing about pagination, result ordering, or whether an empty list is returned for questions with no options, leaving meaningful behavioral gaps.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences with the purpose front-loaded and the prerequisite note following. No filler, no restatement of the tool name.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a one-parameter read tool with an output schema, the description covers purpose, safety profile, and the ID prerequisite. Only minor behavioral details (pagination/empty results) are absent, which the output schema partly compensates for.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and the single parameter is already documented as 'Demographic question ID — get from list_questions'. The description's ID-sourcing note largely restates the schema, so baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (list) plus resource (answer options) scoped to 'a specific demographic question', which implicitly separates it from the unfiltered sibling list_answer_options. It does not name that sibling explicitly, so the differentiation is inferable rather than spelled out.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives concrete prerequisite guidance for obtaining question_id, naming two specific sibling tools (list_questions, list_questions_for_question_set). It stops short of stating when to prefer this over list_answer_options or get_answer_option, so no explicit exclusion is offered.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_answersA

List all demographic survey responses submitted by candidates. Read-only.

Each answer has application_id, demographic_question_id, demographic_answer_option_id and free_form_text. Resolve labels with list_questions and list_answer_options.

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)
created_afterNoISO 8601 datetime — only answers created after this

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.5/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations present, the description carries the full burden. It does disclose that the operation is 'Read-only' and enumerates the shape of each returned answer, which is meaningful behavioral context. It stops short of noting any auth/permission requirements or result-volume considerations for an all-records listing.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, front-loaded with the core purpose, then the read-only note, then the field shape and label-resolution tip. Very little waste, though the final sentence could be slightly tighter.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values needn't be explained, yet the description still helpfully summarizes the answer fields. Read-only status and label-resolution pointers are included. The one gap is the absence of differentiation from the closely named sibling list_answers_for_application.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, with cursor, paginate, per_page and created_after each documented in the schema, so the baseline is 3. The description adds no further parameter meaning (e.g., it never mentions date filtering), so it neither compensates nor detracts.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List all demographic survey responses submitted by candidates'), which is clear enough to identify the entity being read. It implies an unfiltered listing that contrasts with the sibling list_answers_for_application, but never names that sibling to make the distinction explicit.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The only routing guidance is 'Resolve labels with list_questions and list_answer_options,' which is genuinely useful for follow-up lookups. However, there is no when-to-use guidance versus the very similar list_answers_for_application, nor any stated prerequisites, so usage is only implied.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_answers_for_applicationA

List demographic responses for a specific application. Read-only.

To find application_id: search_candidates_by_name → list_applications(candidate_id=...) → match the application to the job.

ParametersJSON Schema
NameRequiredDescriptionDefault
application_idYesGreenhouse application ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.8/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full behavioral burden and it only declares 'Read-only'. That is a useful safety signal for a mutation-free tool, but no other traits (pagination, scope of 'demographic responses', auth needs) are disclosed. Adequate but thin.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short parts with zero waste; the purpose is front-loaded ahead of the workflow hint. Efficient, though very terse.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need no explanation, and the single-param signature is simple. The discovery workflow for application_id fills the main gap; minor behavioral detail (pagination) is the only omission.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% and the single parameter is documented as the Greenhouse application ID, so the baseline is 3. The description goes beyond the schema by explaining how to derive that ID via a chained lookup, adding real meaning.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb ('List'), resource ('demographic responses') and scope ('for a specific application'). This distinguishes it from the generic list_answers sibling, though it doesn't explicitly name that sibling for contrast.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides an explicit discovery workflow for obtaining the required application_id (search_candidates_by_name → list_applications → match to job), which is genuinely actionable. It doesn't state when to prefer this over list_answers or get_eeoc_for_application, but the context is clear.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_applicationsA

List applications with optional filters. Read-only.

Users say "show me applications for [job name]" or "what came in this week." To filter by job: list_jobs → find by name → use its job_id. To filter by candidate: search_candidates_by_name → candidate_id. Each application has job_id + job_name, the current stage (stage_name, and job_interview_stage_id for moves), status ('in_process', 'rejected', 'hired', 'converted'), source_id, recruiter_id/coordinator_id, rejection_reason_id and created_at (the applied date). For pipeline views grouped by stage, use pipeline_summary. For stale candidates, use stale_applications or candidates_needing_action.

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
job_idNoFilter to applications on this job
statusNoFilter by status: 'active', 'rejected', 'hired', or 'converted'
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)
candidate_idNoFilter to applications for this candidate
created_afterNoISO 8601 datetime — only applications created at/after this
created_beforeNoISO 8601 datetime — only applications created before this
last_activity_afterNoISO 8601 datetime — only applications with activity after this

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.5/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden, and it does declare 'Read-only' up front along with the semantics of the returned records (stage, status values, ids, created_at). It does not address auth/permission needs or rate limits, but for a non-destructive list tool the safety profile is adequately disclosed.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with purpose and safety, then routing and workflow, so the important parts come first. The mid-section enumerating application fields partially duplicates the existing output schema, which is slightly wasteful, but the routing content earns its space.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Covers usage, alternatives, and ID-acquisition workflows for a 9-parameter tool, and an output schema already documents the return shape. The field enumeration is redundant against that output schema but nothing critical for correct invocation is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3; the description goes beyond by explaining how to derive job_id and candidate_id, and clarifies that created_at is the applied date. Minor risk: it lists status values as 'in_process' while the schema filter documents 'active', a potential confusion worth flagging.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific verb and resource ('List applications with optional filters') and immediately scopes it as 'Read-only'. It distinguishes itself from siblings by explicitly naming pipeline_summary, stale_applications, and candidates_needing_action as different tools for different views.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It gives concrete trigger phrases ('show me applications for [job name]', 'what came in this week') and spells out the prerequisite workflows to obtain filters (list_jobs → find by name → job_id; search_candidates_by_name → candidate_id). It also names the alternatives to use for pipeline-by-stage and stale-candidate questions, covering when-not-to-use.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_approvals_for_jobA

List approval flows for a job. Read-only.

To find job_id: list_jobs → match by name. Each flow has approval_type (open_job, offer_job, offer_candidate), approval_status, sequential, requested_by_id, and approver_groups (ordered by sort_order), each with approvers (user_id, user_name, status: waiting/due/approved/rejected).

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.6/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden. It states 'Read-only,' which is a key safety trait, but does not mention auth requirements, pagination behavior, or any other operational details. The detailed output structure is more about return values than behavioral traits.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness3/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The first two sentences are essential and front-loaded. The final sentence detailing approval_type, approval_status, and approver_groups is redundant because an output schema exists, which makes the description longer than necessary for the information the agent actually needs from the text.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a simple list tool with one required parameter and an output schema, the description is complete enough. It covers purpose, read-only status, how to obtain the required job_id, and summarizes the output, so an agent has everything needed to invoke it correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage for job_id is 100%, so the baseline would be 3. The description adds value by explaining how to find job_id via 'list_jobs → match by name,' which is procedural guidance beyond the schema.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific verb and resource: 'List approval flows for a job.' It is clear what the tool does. However, it does not explicitly differentiate itself from siblings like get_approval_flow or list_pending_approvals, leaving the agent to infer the distinction.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description notes 'Read-only' and gives guidance on obtaining job_id via list_jobs, but it offers no explicit when-to-use vs alternatives, such as when to use this instead of list_pending_approvals or get_approval_flow. Usage is implied by the tool name and required job_id.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_board_degreesA

List degree types for board application forms. Read-only.

Provides the degree dropdown options shown to external applicants.

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.6/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden. It does disclose 'Read-only,' which is the key safety trait for a list tool, but says nothing about auth requirements, whether results are cached/static reference data, or ordering. Adequate but thin for zero annotation coverage.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, front-loaded with the core purpose, with no redundant restatement of the name. The mid-sentence 'Read-only.' fragment is slightly awkward but costs nothing.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return-value documentation is unnecessary, and with no parameters the surface is small. The description covers purpose and scope sufficiently; it would only be stronger if it clarified the relationship to list_degrees.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The tool takes zero parameters, so there is nothing for the description to clarify; the baseline for a parameterless tool is a 4. No misleading parameter claims are made.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List degree types for board application forms') and scopes it to external applicants via the board form. It distinguishes itself functionally from the similarly named list_degrees sibling, but never names that sibling explicitly, so an agent must infer which degree list is appropriate.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

'Provides the degree dropdown options shown to external applicants' implies the context (public board forms rather than internal admin), which is useful. However there is no explicit when-to-use statement and no mention of list_degrees as the alternative for internal degree lookups, leaving routing to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_board_departmentsA

List departments on the public job board. Read-only.

For internal department management, use list_departments instead.

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.5/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the burden; it does disclose the safety-critical trait ('Read-only') and the public-board scope. However, it says nothing about result ordering, pagination, or result size for a listing operation. Adequate but not rich.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, the core action is front-loaded, and the routing note follows. No filler, no restating of the name.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be described. For a zero-parameter, read-only listing tool, the description plus schema and sibling routing note gives the agent everything needed to call it correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The tool takes zero parameters, so there is no parameter semantics to explain — the baseline for a parameterless tool is 4. The description correctly adds no redundant parameter discussion.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb ('List') and resource ('departments') scoped to the 'public job board', and explicitly separates itself from the internal-management sibling list_departments. An agent can route correctly without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Names the alternative (list_departments) and the exact condition that selects it ('For internal department management'). This is explicit when-to-use / when-not-to-use guidance rather than implied context.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_board_disciplinesA

List academic disciplines for board application forms. Read-only.

Provides the discipline dropdown options shown to external applicants.

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full behavioral burden. It explicitly states 'Read-only', which is the key trait for a list operation, but provides no further behavioral context such as caching, authentication requirements, or rate limits.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The description is two sentences, front-loaded with the core action and scope, followed by a concise clarification. Every sentence earns its place with no redundancy.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a simple no-parameter list tool with an output schema, the description is nearly complete: it states what is listed, the read-only nature, and the target audience. It could be slightly improved by explicitly contrasting with 'list_disciplines', but it is otherwise sufficient.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The tool has zero parameters and 100% schema description coverage, so the baseline score of 4 applies. The description correctly adds no parameter information because there are none to describe.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific verb ('List') and resource ('academic disciplines') and adds a clear scope ('for board application forms', 'shown to external applicants') that distinguishes it from the general 'list_disciplines' sibling. An agent can confidently select this tool for board-related discipline options.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description implies usage context ('for board application forms', 'dropdown options shown to external applicants') but does not explicitly state when to use this tool versus alternatives like 'list_disciplines' or other board list tools. No exclusions or prerequisites are given.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_board_jobsA

List all published jobs on the public job board. Read-only.

Returns jobs visible to external candidates. For internal job data with pipeline info, use list_jobs instead.

ParametersJSON Schema
NameRequiredDescriptionDefault
contentNoInclude full job content/description

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.5/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden; it does disclose the read-only nature and the visibility constraint (only jobs visible to external candidates). It does not cover pagination or rate-limit behavior, but the safety-relevant disclosure is present and correct.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, zero filler, with the public-board scope front-loaded ahead of the disambiguation note. Every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a simple read-only list tool with an output schema covering return values, no further explanation is required. Scope, safety profile, and sibling routing are all present.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Only one parameter (content) exists and schema description coverage is 100%, so the schema already documents it fully. The description adds no meaning about the content toggle, making the baseline 3 appropriate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (list) plus resource (published jobs) and scope (public job board), and explicitly contrasts itself with the sibling list_jobs. An agent can distinguish it without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives an explicit routing rule: use this for externally visible board jobs, use list_jobs when internal pipeline data is needed. The alternative is named and the selecting condition is stated, leaving nothing to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_board_officesA

List offices on the public job board. Read-only.

For internal office management, use list_offices instead.

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the behavioral burden, and it does disclose the key trait: 'Read-only.' However, it says nothing about authentication requirements, whether the board must be published, or any rate/visibility constraints on public board data. The read-only disclosure is meaningful but the rest of the safety profile is unstated.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, zero filler. The purpose and scope come first, the disambiguation comes second — a well front-loaded structure for a trivially simple tool.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation, and with no parameters the input side is fully covered. The description covers purpose, scope, safety hint, and sibling routing, leaving only minor unstated details such as whether results are paginated or require a published board.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The tool takes zero parameters, so there is no parameter semantics to document; per the baseline this warrants a 4. The description correctly stays silent on inputs rather than inventing filtering semantics that do not exist.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List offices') and scopes it precisely to 'the public job board', which immediately separates it from internal office endpoints. The named sibling list_offices reinforces the distinction, so an agent can route without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly names the alternative ('use list_offices instead') and the condition that selects it ('For internal office management'), covering both when to use this tool and when not to. Nothing about the choice is left to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_board_schoolsA

List schools for board application forms. Read-only.

Provides the school dropdown options shown to external applicants.

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.9/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden. It usefully declares 'Read-only' and clarifies the audience-facing scope, which is real behavioral context. But it omits anything on permissions, result size, or pagination; for a simple 0-param list tool this is adequate but not rich.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, front-loaded with the core purpose, then the safety trait, then the audience clarification. No wasted words, though the 'Read-only' line is a fragment that could be folded in.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation, and there are no parameters to cover. Purpose, safety, and audience are all present; only the sibling-alternative routing is missing for full completeness.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The tool takes zero parameters, so the baseline of 4 applies; there is nothing for the description to disambiguate beyond what the empty schema already conveys.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (List) and resource (schools), and crucially scopes it to 'board application forms' / 'external applicants', which distinguishes it from the sibling list_schools. An agent can tell the two apart without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Implies the usage context well ('school dropdown options shown to external applicants'), which signals this is for board/external flows rather than internal admin. However, it never explicitly names list_schools as the alternative or states when NOT to use this tool, leaving the sibling choice to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_candidatesA

List candidates with optional filters. Read-only.

For finding a specific person, use search_candidates_by_name (by name) or search_candidates_by_email (by email) — faster and simpler. Use this tool for bulk operations: date-range queries, fetching by specific IDs, or paginating through the full database. Created and updated date filters can't be combined in one call. Candidates here are profile-only (no applications or attachments) — use get_candidate or list_applications(candidate_id=...) for those.

ParametersJSON Schema
NameRequiredDescriptionDefault
tagNoFilter by exact candidate tag name
emailNoFilter by exact email address
cursorNoPass next_cursor from the previous response to get the next page
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)
candidate_idsNoFilter to specific candidate IDs (max 50)
created_afterNoISO 8601 datetime — only candidates created at/after this
updated_afterNoISO 8601 datetime — only candidates updated at/after this
created_beforeNoISO 8601 datetime — only candidates created before this
updated_beforeNoISO 8601 datetime — only candidates updated before this

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.7/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations supplied, the description carries the safety burden itself and does so well: it declares 'Read-only', states that results are profile-only (no applications/attachments), and discloses a real constraint that created and updated date filters can't be combined. It stops short of auth/permission or rate-limit context, keeping it out of the top band.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the core purpose and read-only flag, then layers alternatives, use cases, and constraints in tight, waste-free sentences. Every sentence adds routing or constraint value.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return-value explanation is unneeded, and the description fills the remaining gaps: read-only scope, profile-only contents, sibling routing, and the date-filter combination limit. Nothing an agent needs to call this correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3. The description earns one more by adding a cross-parameter constraint the schema does not encode — that created_* and updated_* filters cannot be combined in a single call — which materially affects how an agent builds the request.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ('List candidates') and immediately distinguishes itself from siblings by naming search_candidates_by_name, search_candidates_by_email, get_candidate, and list_applications with the conditions that select each. An agent can route correctly without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly covers when to use this tool (bulk operations: date-range queries, fetching by specific IDs, pagination) vs. when not to (finding a specific person, retrieving applications/attachments), and names the alternatives for each case. Nothing is left to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_close_reasonsA

List all close reasons for job openings. Read-only.

Resolves close reason names to IDs for hire_application and update_job_opening.

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
per_pageNoResults per page (max 500)
force_refreshNoBypass cache and fetch fresh data

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full behavioral burden; it discloses 'Read-only,' which is the most important trait for a mutation-averse agent. It does not mention caching behavior (the schema's force_refresh implies caching) or whether the list is static, leaving some behavioral context to the schema.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences with zero filler; the core purpose is front-loaded and the downstream-use note follows immediately. Nothing could be removed without losing information.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return-value documentation is unnecessary, and the schema fully covers pagination and refresh parameters. The description is nearly complete, lacking only minor operational detail such as caching semantics implied by force_refresh.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and all three parameters (cursor, per_page, force_refresh) are documented in the schema itself. The description adds no parameter meaning beyond that, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (List) and resource (close reasons for job openings), and distinguishes itself from the similarly-named sibling list_rejection_reasons by scoping to close reasons. It also names the downstream consumers, making the tool's role unambiguous.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description explicitly says the tool 'Resolves close reason names to IDs for hire_application and update_job_opening,' which tells the agent when this lookup is needed. It stops short of stating exclusions or conditions where an alternative (e.g. list_rejection_reasons) applies.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_custom_field_optionsA

List dropdown options for a custom field. Read-only.

To find custom_field_id: list_custom_fields → match by name. Options have sort_order (was priority) and are returned in that order.

ParametersJSON Schema
NameRequiredDescriptionDefault
activeNotrue = selectable options only, false = archived only
custom_field_idYesCustom field ID (must be a single_select or multi_select field)

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden; it does so partially by declaring "Read-only" and disclosing that options are returned in sort_order sequence, a genuine behavioral trait. It omits auth/permission requirements and any pagination or result-size behavior, which keeps it from 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three tight sentences, front-loaded with purpose and read-only status, then the prerequisite, then the ordering note. The "(was `priority`)" parenthetical is genuinely useful vocabulary for an agent and nothing is wasted.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With an output schema present, return values need not be described, and the ordering claim plus the ID-acquisition path cover the main gaps. Missing only permission/scope context, which matters more here because no annotations backstop the safety profile.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% – both custom_field_id (single/multi-select constraint) and active (true=selectable, false=archived) are fully documented in the schema. The description adds only the lineage hint about list_custom_fields for obtaining the ID, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ("List dropdown options for a custom field") that an agent can immediately match to its intent. It also distinguishes itself from the create/update/delete_custom_field_options siblings by explicitly declaring "Read-only," and names the prerequisite tool explicitly.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explains how to obtain the required custom_field_id ("list_custom_fields → match by name"), which is actionable prerequisite guidance and effectively routes between the two tools. It stops short of stating when to prefer this over get_custom_field or when alternatives apply, so it does not reach 5.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_custom_fieldsA

List all custom field definitions. Read-only.

Resolves custom field names to IDs. When a user mentions a custom field by name, use this to find its ID (or name_key) for update_candidate, update_application, or update_current_offer. Filter by field_type to narrow results. Dropdown options are separate: list_custom_field_options.

ParametersJSON Schema
NameRequiredDescriptionDefault
activeNotrue = live fields only, false = archived only
field_typeNoFilter: candidate, application, job, offer, opening, rejection_question, referral_question, user_attribute

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden. It usefully declares 'Read-only', which is the single most important behavioral trait, but says nothing about authentication, pagination, or what the default (no active filter) returns. With an output schema present the return shape is covered elsewhere, so this is adequate but not rich.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the identity and read-only nature, then the use case, then the filter, then the sibling exclusion. Four short sentences, each adding distinct routing information with no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Covers purpose, trigger, filter, and sibling separation for a zero-required-parameter read tool with a full output schema. The only gap is the semantics of omitting the active filter (does it include archived fields?), which an agent might need to answer a user's question precisely.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the schema already documents both parameters fully (active = live vs archived, field_type with its allowed values). The description only restates that field_type narrows results and adds no syntax or default-behavior detail, so baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List all custom field definitions') and goes further to say what the list is FOR: resolving custom field names to IDs. It explicitly separates itself from list_custom_field_options ('Dropdown options are separate'), so an agent can distinguish it from the closest sibling without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives an explicit trigger condition ('When a user mentions a custom field by name, use this to find its ID'), names the downstream tools that consume the ID (update_candidate, update_application, update_current_offer), and names the sibling to use instead for options. Nothing is left to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_degreesA

List degree types (Bachelor's, Master's, PhD, etc.). Read-only.

Resolves degree names to IDs (degree_id) for add_education. Each item is a custom field option with id and name.

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)
force_refreshNoBypass cache and fetch fresh data

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.6/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden. It correctly declares 'Read-only', which is the single most important behavioral trait for a list tool. It also describes the return structure ('Each item is a custom field option with id and name') and hints at caching with 'force_refresh'. However, it does not mention pagination behavior (cursor, paginate, per_page) or rate limits, which are relevant for a tool with 4 parameters. The disclosure is adequate but not rich.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The description is three sentences, front-loaded with the core purpose and read-only nature, followed by the specific use case and return format. There is no filler. It could be slightly tighter by merging the usage and return structure, but it is efficient and well-structured.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness3/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a read-only list tool with 4 optional parameters and a full output schema, the description covers the essential purpose, safety, and return shape. However, it omits pagination guidance despite the tool having cursor/paginate/per_page params, and does not distinguish from 'list_board_degrees'. Given the complexity of the sibling set and the presence of pagination knobs, it is adequate but incomplete.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so all four parameters (cursor, paginate, per_page, force_refresh) are fully documented in the schema. The description adds no parameter-specific information beyond what the schema provides. Per the rubric, the baseline is 3 when the schema does the heavy lifting, and the description does not compensate further.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description clearly states a specific verb and resource: 'List degree types (Bachelor's, Master's, PhD, etc.)'. This distinguishes it from most siblings. However, it does not explicitly differentiate from the very similarly named 'list_board_degrees' in the sibling list, which likely serves a similar purpose in a different context (board vs. general). A note about that distinction would earn a 5.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description explicitly states the primary usage: 'Resolves degree names to IDs (degree_id) for add_education.' This is a strong, actionable usage guideline that tells the agent exactly why and when to call this tool. It lacks explicit when-not-to-use guidance or mention of the sibling 'list_board_degrees', but the context provided is clear and directly useful.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_departmentsA

List all departments. Read-only.

Resolves department names to IDs. When a user mentions a department ("Engineering"), use this to find its ID for list_jobs, create_job, or add_future_job_permission. Each department has parent_id (null for top level); rebuild the tree from parent_id.

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)
parent_idNoOnly departments directly under this parent department
force_refreshNoBypass cache and fetch fresh data

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations exist, so the description carries the behavioral burden. It declares read-only safety and adds a real output-shape fact not in the schema: each department has parent_id (null = top level) and the tree must be rebuilt from it. Cache/pagination behavior is only in the schema, not the description.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded purpose, then 'Read-only', then progressively optional detail. All three sentences earn a place. The phrasing is slightly terser than ideal but not padded.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a list/read tool with an output schema and full parameter coverage, this is nearly complete. The only gaps are explicit when-not-to-use guidance and cache/pagination context, both minor given schema coverage.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so cursor, paginate, per_page, parent_id, and force_refresh are already fully documented. The description adds no parameter-level detail beyond what the schema provides, so it sits at the baseline.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ('List all departments') and immediately clarifies the real-world purpose and downstream consumers (list_jobs, create_job, add_future_job_permission), which clearly distinguishes it from siblings like get_department, create_department, and list_board_departments.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly tells the agent when to reach for it: when a user mentions a department by name and its ID is needed. That is a strong use-case trigger. It doesn't mention when NOT to use it (e.g., single known ID vs get_department), so it falls just short of 5.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_disciplinesA

List academic disciplines (Computer Science, Business, etc.). Read-only.

Resolves discipline names to IDs (discipline_id) for add_education. Each item is a custom field option with id and name.

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)
force_refreshNoBypass cache and fetch fresh data

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.6/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full behavioral burden and does disclose the key trait ('Read-only'). It also notes the item shape, but says nothing about caching, auth requirements, or pagination, and the returned shape is already covered by the output schema.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short, front-loaded sentences that lead with purpose and follow with the practical use case. The closing note on item structure is mildly redundant given the output schema, but nothing is wasted overall.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a simple read-only list tool with 100% schema coverage and an output schema, the description supplies the purpose, the workflow use case, and the read-only trait. Only marginal extras (e.g., caching or pagination behavior) are absent, and those live in the schema.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and all four parameters (cursor, paginate, per_page, force_refresh) are documented in the schema itself. The description adds no parameter-level meaning beyond that, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ('List academic disciplines') with concrete examples (Computer Science, Business), so the agent knows exactly what comes back. It does not, however, distinguish itself from the very similar sibling list_board_disciplines, which keeps it short of a 5.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives a clear use context: 'Resolves discipline names to IDs (discipline_id) for add_education,' which tells the agent when this lookup is needed. It names no exclusions and does not mention the near-duplicate list_board_disciplines alternative, so it falls just short of explicit when/when-not guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_eeocA

List all EEOC data collected from applications. Read-only.

Compliance data — self-reported race, gender, veteran, and disability status ({id, description} each). Used for federal reporting, not for hiring decisions.

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)
submitted_afterNoISO 8601 datetime — only responses submitted after this
submitted_beforeNoISO 8601 datetime — only responses submitted before this

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.7/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full burden and does state 'Read-only', which is the safety-critical trait an agent needs. It also characterizes the payload (self-reported race, gender, veteran, disability) and flags the compliance sensitivity, though auth requirements and pagination semantics are left to the schema.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short, front-loaded lines with the operation and read-only flag first, then payload, then usage caveat. No filler, though the parenthetical field-shape note is marginally redundant with the output schema.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Output schema exists so return values needn't be re-explained, yet the description still summarizes the shape helpfully. Read-only status and the compliance context are covered; only auth/permission expectations are unstated, which is a minor gap for a read tool.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and all five parameters (cursor, paginate, per_page, submitted_after/before) are documented in the schema itself. The description adds no parameter-level meaning beyond that, so baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a clear verb+resource ('List all EEOC data') and scopes it to data 'collected from applications', which implicitly separates it from the sibling get_eeoc_for_application (single record). It doesn't explicitly name that sibling, so an agent must infer the aggregate-vs-single distinction.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

'Used for federal reporting, not for hiring decisions' gives a usage context and a soft exclusion, but no explicit when-to-use trigger or named alternative tool. The guidance is implied rather than directive.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_email_templatesA

List all email templates. Read-only.

Resolves template names to IDs. When a user wants to send a rejection email, use this (email_type='candidate_rejection') to find the template ID for reject_application's rejection_email parameter.

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
per_pageNoResults per page (max 500)
email_typeNoFilter by type, e.g. candidate_rejection, candidate_email
force_refreshNoBypass cache and fetch fresh data

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden. It correctly declares 'Read-only,' which is the most important safety trait, but it does not discuss pagination behavior, caching, force_refresh effects, or authorization requirements.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The description is front-loaded with the core action and read-only status, then briefly covers resolution and a concrete workflow. Every sentence adds value and there is no wasted wording.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a read-only list tool with a rich schema and an output schema, the description provides enough to select and call it correctly. Minor omissions around pagination and cache behavior are largely covered by structured fields, but would have been useful given the absence of annotations.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is already 100%, so the schema documents all four parameters well. The description reinforces email_type with a concrete example, but adds no meaning for cursor, per_page, or force_refresh beyond what the schema already provides.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific verb and resource ('List all email templates') and adds the purpose of resolving template names to IDs. This distinguishes it from single-template siblings like get_email_template and makes its output role clear.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It gives explicit when-to-use guidance by connecting the tool to rejection-email workflows and naming the downstream parameter on reject_application. It does not state when not to use it or compare it with get_email_template, but the primary usage context is clear.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_future_job_permissionsA

List auto-apply permission rules for a user. Read-only.

These rules automatically grant the user a role on new jobs matching criteria (office_id, department_id; null = any). Rows carry role_id and role_name. To find user_id: list_users → match by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
user_idYesGreenhouse user ID — get from list_users

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full burden and does disclose meaningful behavior: it is 'Read-only', explains the auto-apply rule semantics, notes that null criteria mean 'any', and states which fields rows carry. It does not mention pagination, required permissions, or error cases, but for a simple read-only list tool this is solid coverage.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three compact sentences with zero waste. Purpose is front-loaded, followed by rule semantics and the user_id lookup hint, in a logical order.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a one-parameter read-only list tool with an output schema, the description supplies everything an agent needs: purpose, read-only nature, rule semantics, and how to obtain the required user_id. Return values are covered by the output schema, so no further detail is required.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and the single user_id parameter is already documented in the schema. The description adds a concrete procedural step ('list_users → match by name') that slightly enriches the schema's 'get from list_users' note, justifying a small bump above the baseline 3.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List auto-apply permission rules for a user') and describes what makes these rules distinct from ordinary job permissions (they 'automatically grant the user a role on new jobs'). This lets an agent distinguish it from siblings like list_job_permissions without opening their schemas.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines2/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description explains what the rules are but never states when to use this tool versus alternatives such as list_job_permissions or add_future_job_permission. The only procedural guidance is for finding user_id via list_users, which is parameter help rather than tool-selection guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_interviewsA

List scheduled interviews across all applications. Read-only.

Each interview has id, application_id, job_id, starts_at/ends_at (or all_day_start_on/all_day_end_on), status, location, video_conferencing_url, plus (with include_details) interview {id, name}, interviewers [{id, name, email, response_status, scorecard_id}] and organizer. For a specific candidate's interviews, use list_interviews_for_application (search_candidates_by_name → list_applications(candidate_id=...) → match the application → use its ID).

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
job_idNoOnly interviews on this job — get ID from list_jobs
statusNoFilter by status, e.g. 'scheduled', 'awaiting_feedback', 'complete', 'to_be_scheduled'
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)
starts_afterNoISO 8601 datetime — only interviews starting at/after this
created_afterNoISO 8601 datetime — only interviews created at/after this
starts_beforeNoISO 8601 datetime — only interviews starting before this
created_beforeNoISO 8601 datetime — only interviews created before this
include_detailsNoResolve interview name, interviewers and organizer (extra calls)

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavior burden. It does declare 'Read-only' and discloses that include_details triggers 'extra calls,' which is useful cost context for a read tool. However it says nothing about auth/permission requirements or rate-limit behavior, leaving meaningful gaps for a tool with zero annotation coverage.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded purpose and the read-only qualifier lead, with field details and the sibling routing following. It is somewhat dense, and the field enumeration slightly overlaps what the output schema already covers, but no sentence is wasted.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Given the output schema exists, return values need not be spelled out, yet the description still summarizes them helpfully. Combined with read-only disclosure and sibling routing, it is nearly complete; auth/permission expectations are the one notable omission.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so all ten parameters are already documented in the schema, establishing a baseline of 3. The description adds the include_details return-shape effect (resolving interview name, interviewers, organizer), but that largely restates the schema's own note, so no credit above baseline.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

Opens with a specific verb and resource plus scope: 'List scheduled interviews across all applications.' It explicitly contrasts itself with list_interviews_for_application, so an agent can distinguish the two without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It names the alternative (list_interviews_for_application) and the exact condition that selects it (a specific candidate's interviews), even sketching the multi-step lookup path. That is explicit when-to-use and when-to-use-something-else guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_interviews_for_applicationA

List scheduled interviews for a specific application. Read-only.

To find the application_id: search_candidates_by_name → list_applications(candidate_id=...) → match the application to the job. Returns all interviews with times, interview name, interviewers (with their scorecard_id), and status.

ParametersJSON Schema
NameRequiredDescriptionDefault
application_idYesGreenhouse application ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.5/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the burden; it does declare 'Read-only' and enumerates the returned fields (times, interview name, interviewers with scorecard_id, status). It omits auth/permission requirements and error behavior, so it is solid but not exhaustive.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short paragraphs, front-loaded with the core purpose and safety note, followed by the id-derivation hint. Every sentence earns its place with no redundancy.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Output schema exists, so return values need not be explained (and the brief enumeration is a bonus). Single required param, read-only operation, and the id-sourcing workflow are all covered; nothing an agent needs to call it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% (single application_id documented as 'Greenhouse application ID'), so the baseline is 3. The description adds value beyond the schema by explaining how to obtain the id via the search → list_applications chain, which the schema does not convey.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource with clear scope: 'List scheduled interviews for a specific application.' The 'for a specific application' qualifier distinguishes it from the sibling list_interviews (which is broader), so an agent can route correctly without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides an explicit derivation chain for the required application_id (search_candidates_by_name → list_applications → match to job), which is genuine usage guidance. It does not explicitly name list_interviews as the alternative or state when-not-to-use this tool, so it stops short of 5.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_job_openingsA

List openings (headcount) for a job. Read-only.

An opening represents one position to fill — a job can have multiple. Each opening has id, opening_id (external ID), open (bool) and status ('open'/'closed'), close_reason_id, application_id (the hire, if filled), target_start_on, and custom_fields. To find job_id: list_jobs → match by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID
statusNoFilter by status: 'open' or 'closed'

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are supplied, so the description carries the full burden; it explicitly self-declares 'Read-only', which is the key safety signal, and explains the domain model (a job can have multiple openings, each with its own status). It says nothing about permissions, rate limits, or pagination, so it is not fully complete.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness3/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads purpose and the read-only flag well, but the middle sentence enumerates every returned field (id, opening_id, open, status, close_reason_id, application_id, target_start_on, custom_fields), which is largely duplicated by the existing output schema and adds length without new decision-relevant information.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

The description covers purpose, read-only behavior, the entity model, the parameter prerequisite, and field meaning; with an output schema present it need not describe return values, so nothing essential for correct invocation is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds meaning beyond the schema by explaining the optional status filter's domain context ('open'/'closed' lifecycle) and by telling the agent where to source job_id, which the schema only labels 'Greenhouse job ID'.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List openings (headcount) for a job') and immediately distinguishes itself from sibling mutations like create_job_opening, update_job_opening, and bulk_delete_job_openings as a read operation.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides real routing guidance: 'To find job_id: list_jobs → match by name', which tells the agent how to obtain the required parameter. It does not, however, contrast with alternatives such as get_job_opening for a single opening or explain when a status filter is preferable.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_job_permissionsA

List all job-level permissions for a user. Read-only.

To find user_id: list_users → match by name or email. Each row has its own id (needed for remove_job_permission), job_id, role_id (was user_role_id), role_name, and automated (true when created by a future-job rule). Site admins have no rows — they can access every job.

ParametersJSON Schema
NameRequiredDescriptionDefault
user_idYesGreenhouse user ID — get from list_users

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does disclose meaningful behavior: the operation is read-only, each row carries its own id, `automated` marks future-job-rule rows, and site admins return no rows because they implicitly access every job. It omits pagination and auth details, but the edge case and field semantics are strong for a list tool.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads purpose and read-only status, then prerequisite routing, then per-field meaning. Dense but each clause serves a function; the parenthetical field-by-field explanation is the only part that borders on verbose.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values needn't be enumerated, yet the description usefully explains row fields and the site-admin empty-result case. For a single-parameter read-only list tool this is close to complete, missing only pagination/volume expectations.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% (baseline 3), and the description adds a small amount beyond the schema by explaining how to resolve the single parameter ('match by name or email' via list_users). The addition over the schema's own 'get from list_users' note is modest but real.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List all job-level permissions for a user') and immediately flags 'Read-only,' which cleanly separates it from the sibling mutations add_job_permission, remove_job_permission, and add_future_job_permission. An agent can identify the tool's scope without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides prerequisite routing ('To find user_id: list_users → match by name or email') and points to a downstream consumer ('id' needed for remove_job_permission). It does not explicitly distinguish this from the closely related list_future_job_permissions sibling, so it falls short of a full when/when-not statement.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_job_postsA

List all job posts (public listings) across all jobs. Read-only.

A job post is the public-facing listing for a job. Each post includes its application form questions and a locations array (a post can have several locations in v3). For posts on a specific job, use list_job_posts_for_job (job_id from list_jobs → match by name).

ParametersJSON Schema
NameRequiredDescriptionDefault
liveNoFilter: true for published posts only, false for unpublished only, omit for all
cursorNoPass next_cursor from the previous response to get the next page
internalNotrue for internal (employee) board posts, false for external only
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the disclosure burden and does state "Read-only," which is the key safety signal. It further reveals response structure (application form questions, locations array, multi-location in v3), adding real context, though pagination behavior is left to the schema.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the core action and the read-only flag, then supporting definition and routing note. The three sentences all earn their place, though the multi-line formatting is slightly loose for the content volume.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be re-explained, and the description covers scope, the entity definition, and the sibling routing. It is complete enough for correct invocation; only explicit filter-usage guidance is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so every parameter (live, cursor, internal, paginate, per_page) is already documented in the schema. The description adds nothing about parameter semantics, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ("List all job posts") and explicitly scopes it to "across all jobs." It also defines what a job post is ("the public-facing listing for a job") and names the sibling it is not, so an agent can distinguish it from list_job_posts_for_job without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Names the alternative (list_job_posts_for_job) and the condition that selects it ("posts on a specific job"), including the practical note on obtaining job_id via list_jobs and matching by name. It does not, however, give guidance on when to use the live/internal filters.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_job_posts_for_jobA

List job posts for a specific job. Read-only.

To find job_id: list_jobs → match by name. Returns the public listing(s) including title, content, live status, public_url, application questions, and locations.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.7/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden. It does declare 'Read-only', which is a genuine safety disclosure, and enumerates the returned fields (title, content, live status, public_url, application questions, locations). It says nothing about pagination, result limits, or what happens when a job has no posts.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, front-loaded with the core action and the read-only guarantee, followed by the prerequisite hint and return contents. Every sentence earns its place with no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so the description is not obligated to enumerate return fields, yet it does so helpfully. Combined with the read-only declaration and job_id discovery hint, an agent has enough to invoke it correctly; only pagination/edge-case behavior is unaddressed.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

With 100% schema coverage the baseline would be 3, but the description adds meaning beyond the schema by explaining how to obtain job_id (via list_jobs and matching by name) — a navigation hint the schema does not provide. The single required integer parameter is otherwise fully documented in the schema.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb ('List') and resource ('job posts') and scopes it to 'a specific job', which implicitly separates it from the sibling list_job_posts (all posts) and get_job_post_for_job. However, it never names those siblings explicitly, so an agent must infer the boundary rather than being told it.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It gives a useful prerequisite hint — 'To find job_id: list_jobs → match by name' — which tells the agent how to satisfy the required parameter. But it offers no when-to-use/when-not guidance relative to list_job_posts or get_job_post_for_job, leaving the routing decision to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_jobsA

List all jobs with optional filters. Read-only.

This is the primary tool for resolving job titles to job IDs. When a user mentions a job by name ("Backend Engineer"), use this to find the matching job_id. Filter by status ('open'/'closed'/'draft'), department_id (list_departments), or office_id (list_offices). Each job includes department and offices as {id, name}. Openings are not embedded — use list_job_openings; the hiring team is on get_job. For pipeline views, use pipeline_summary with the job_id.

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
statusNoFilter by status: 'open', 'closed', or 'draft'
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)
office_idNoFilter to jobs in this office
created_afterNoISO 8601 datetime — only jobs created at/after this
department_idNoFilter to jobs in this department
created_beforeNoISO 8601 datetime — only jobs created before this
requisition_idNoOnly jobs with this exact external requisition ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.7/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations exist, so the description carries the full burden — and it delivers: it declares 'Read-only' and discloses the return shape (each job includes department and offices as {id, name}; openings and hiring team are NOT embedded and where to get them). It stops short of describing pagination semantics, though the schema's cursor/paginate/per_page fields partially cover that.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded purpose and safety in the first sentence, then use case, then filters, then exclusions — every sentence carries distinct information with no redundancy.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a 9-param, no-required-filter list tool with an output schema present, the description covers purpose, triggering context, filter sourcing, embedded vs. non-embedded fields, and sibling routing. Nothing an agent needs to call it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds cross-tool meaning: department_id is tied to list_departments and office_id to list_offices, and status values are restated with intent. This helps an agent source valid filter values rather than guess.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ('List all jobs with optional filters') and immediately differentiates itself from siblings by naming list_job_openings, get_job, and pipeline_summary with their respective roles. An agent can tell exactly what this tool does versus the other job-related tools.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly frames the primary use case (resolving job titles to job_ids), gives a concrete trigger ('When a user mentions a job by name'), and routes to alternatives with conditions: list_job_openings for openings, get_job for hiring team, pipeline_summary for pipeline views. Also points to list_departments/list_offices for the ID filters.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_job_stagesA

List all job stages across all jobs. Read-only.

Returns stage id, job_id, name, sort_order, and active. For stages on a specific job in pipeline order (with their interviews), use list_job_stages_for_job instead — it's more useful for resolving stage names to IDs.

ParametersJSON Schema
NameRequiredDescriptionDefault
activeNotrue for stages on current interview plans only, false for removed
cursorNoPass next_cursor from the previous response to get the next page
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden, and it does declare 'Read-only' plus the return fields (id, job_id, name, sort_order, active). It does not discuss pagination behavior or any rate/permission constraints, though cursor/paginate/per_page parameters in the schema partially cover paging. Strong but not exhaustive for an unannotated tool.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Very short and front-loaded: purpose and read-only status first, then the alternative-tool routing. Every sentence carries routing or scope information, with no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With an output schema present and 100% parameter coverage, the description only needs to handle scope and sibling routing, which it does. Listing the returned fields is slightly redundant against the output schema, but nothing an agent needs to call this correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% — the schema documents active, cursor, paginate, and per_page meaningfully. The description adds no parameter semantics beyond what is already there, so the baseline 3 is appropriate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List all job stages') plus the scope ('across all jobs'), which immediately distinguishes it from the per-job sibling list_job_stages_for_job. An agent can tell the two apart without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly names the alternative tool and the condition that selects it: use list_job_stages_for_job when you need stages on a specific job in pipeline order or need to resolve stage names to IDs. Nothing is left to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_job_stages_for_jobA

List pipeline stages for a specific job in order. Read-only.

This is the primary tool for resolving stage names to stage IDs. When a user says "move to the onsite stage," use this to find the stage_id (the job_interview_stage_id used by move/advance). Stages are sorted by sort_order, and each has an interviews array (the stage's configured interviews — their id is the interview_id that create_interview expects; scheduling_type 'needs_scheduling' means it is a calendared interview). To find the job_id first: list_jobs → match by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID
include_inactiveNoAlso return stages removed from the job's interview plan

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description must carry the behavioral burden; it explicitly declares 'Read-only' and discloses return ordering (sorted by sort_order) plus a semantic flag (scheduling_type 'needs_scheduling'). It omits auth/permission requirements and pagination/limit behavior, which keeps it short of a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with purpose, then supporting detail; every sentence carries actionable information (resolution role, sort order, interviews array, prerequisite lookup). The parenthetical nesting ('their id is the interview_id that create_interview expects') is dense but not wasteful.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Although an output schema exists, the description goes further by explaining the returned structures (sort_order ordering, interviews array, scheduling_type meaning) and how those fields feed other tools. For a two-parameter read tool with no annotations, nothing critical to correct invocation is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds meaning beyond the schema by tying job_id acquisition to list_jobs and explaining that the nested id fields map to move/advance and create_interview parameters. The include_inactive behavior is left to the schema description.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource with scope ('List pipeline stages for a specific job in order') and adds a role statement ('primary tool for resolving stage names to stage IDs'). An agent can distinguish this from get_job_stage, list_job_stages and list_jobs without opening schemas.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives a concrete trigger ('When a user says "move to the onsite stage"') and the downstream consumer of the result ('the job_interview_stage_id used by move/advance'). It also routes the agent to list_jobs as the prerequisite step for finding job_id, which is exactly the when-to-use guidance needed.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_offersA

List offers across all applications. Read-only.

Each offer has id, version, application_id, candidate_id, job_id, opening_id, status, starts_on, sent_on, resolved_at, and custom_fields. Every revision is returned (older ones have status 'Deprecated'); set current_only=true for just each application's current offer. For a specific candidate's offers, use list_offers_for_application (search_candidates_by_name → list_applications(candidate_id=...) → match the application → use its ID).

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
job_idNoOnly offers on this job — get ID from list_jobs
statusNoFilter by status: 'Created', 'Accepted', 'Rejected', or 'Deprecated'
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)
current_onlyNotrue to return only the latest version of each application's offer
created_afterNoISO 8601 datetime — only offers created at/after this
created_beforeNoISO 8601 datetime — only offers created before this

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are supplied, so the description carries the full behavioral burden, and it does disclose the key non-obvious trait: every revision is returned and older ones carry status 'Deprecated'. It also declares read-only explicitly. It does not cover auth/permission requirements or rate limits, which keeps it short of a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads purpose and read-only status, then behavior, then the alternative route — a sensible order with no filler. The parenthetical call chain is slightly verbose but earns its place by preventing a wrong tool choice.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With an output schema present, return values need no explanation, and the description still usefully previews the returned fields and revision semantics. Read-only status, filtering mode and the sibling route are all covered; only permission/auth prerequisites are absent.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the schema already documents cursor, job_id, status, paginate, per_page and date filters. The description's explanation of current_only largely restates the schema's own wording, so it adds little beyond the structured fields; baseline 3 is appropriate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List offers across all applications') and immediately distinguishes itself from the closely-named siblings get_offer, get_current_offer and list_offers_for_application. An agent can tell what this tool returns and at what scope without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly names the alternative for a narrower case ('For a specific candidate's offers, use list_offers_for_application') and even supplies the chained call path (search_candidates_by_name -> list_applications -> match application -> use its ID). It also gives the condition for switching modes (current_only=true for just the current offer), so routing is unambiguous.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_offers_for_applicationA

List all offers (every version) made on a specific application. Read-only.

Sorted newest version first. To find application_id: search_candidates_by_name → list_applications(candidate_id=...) → match the application to the job. For the current offer only, use get_current_offer.

ParametersJSON Schema
NameRequiredDescriptionDefault
application_idYesGreenhouse application ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.7/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the burden and does disclose the safety profile ('Read-only'), the ordering ('Sorted newest version first'), and the version scope ('every version'). It omits pagination and rate-limit behavior, but for a read-only list tool the disclosure is solid.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded purpose, then the read-only and ordering facts, then the id-resolution workflow and the alternative. Every sentence earns its place with no redundancy.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explaining. For a one-parameter read tool, the purpose, ordering, version scope, id-resolution path, and alternative tool are all present; nothing an agent needs is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds real value beyond the schema by explaining how to resolve application_id end-to-end. That materially helps an agent supply the single required parameter correctly.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

Specific verb (List) plus resource (offers, every version) plus scope (a specific application), and it names the sibling it is not (get_current_offer) and the alternative get_offer/list_offers. An agent can distinguish it from siblings without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly routes the agent: 'For the current offer only, use get_current_offer', and gives the full resolution path to obtain application_id (search_candidates_by_name → list_applications → match). Both when-to-use and the alternative are stated.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_officesA

List all offices. Read-only.

Resolves office/location names to IDs. When a user mentions an office or location, use this to find its ID for list_jobs, create_job, or add_future_job_permission. Each office has a flat location string, parent_id, and primary_in_house_contact_user_id.

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)
parent_idNoOnly offices directly under this parent office
force_refreshNoBypass cache and fetch fresh data

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the safety burden itself and does so by declaring 'Read-only' explicitly. It also discloses the shape of each returned record (flat `location`, `parent_id`, `primary_in_house_contact_user_id`), which is useful behavioral context beyond the parameters.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Extremely tight: purpose, safety, usage trigger, and return shape in three short sentences with zero filler. The most actionable line (the name-to-ID resolution and its consumers) is front-loaded.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be spelled out, and read-only status plus usage context are covered. The only omission is any hint about paging behavior defaults (per_page 500, paginate='single') for large office lists, which the schema mostly handles anyway.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so cursor, paginate, per_page, parent_id, and force_refresh are all documented in the schema. The description adds no parameter-level detail (e.g., that parent_id scopes the listing or that force_refresh bypasses cache), so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ('List all offices') and immediately adds the functional purpose: resolving office/location names to IDs. That distinction separates it from get_office, create_office, update_office, and list_board_offices in the sibling set.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives a concrete trigger ('When a user mentions an office or location') and names the downstream tools that consume the resulting ID (list_jobs, create_job, add_future_job_permission). It does not state when *not* to use it or point to get_office when the ID is already known, so it falls short of a full 5.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_pending_approvalsA

List all pending approvals for a user (or org-wide). Read-only.

By default returns approvers whose decision is due now. Each item has approver_id, user_id, user_name, status, request_sent_at, job_id, offer_id, approval_type and approval_flow_id. To find user_id: list_users → match by name or email. Omit user_id to see all pending approvals across the organization.

ParametersJSON Schema
NameRequiredDescriptionDefault
user_idNoFilter to approvals pending for this user — omit for all pending approvals
include_waitingNoAlso include approvers whose turn hasn't come yet (status 'waiting')

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does disclose 'Read-only.' plus the default filtering behavior ('approvers whose decision is due now') and how include_waiting extends that. It omits permissions/scope requirements and pagination on large result sets, which are the remaining behavioral gaps.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads purpose and read-only status in the first line, then adds defaults and lookup guidance. The enumerated field list is somewhat verbose given an output schema exists, but it is not padding.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Covers scope, defaults, the include_waiting extension, and user_id acquisition for a 2-parameter optional-arg read tool with an output schema. The field enumeration is partially redundant with the output schema, and auth/rate-limit context is absent.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% so the baseline is 3, but the description adds real meaning: it frames what the default result set is and how the user_id lookup should be performed (via list_users). That goes slightly beyond the schema's terse parameter blurbs.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List all pending approvals') plus scope (per-user or org-wide), which cleanly separates it from siblings like list_approvals_for_job and request_approvals. An agent can identify the tool without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives clear operational context: default is approvers due now, omit user_id for org-wide, and a concrete workflow for obtaining user_id (list_users → match by name/email). It does not name sibling alternatives or when-not-to-use cases, so it stops short of a 5.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_prospect_poolsA

List all prospect pools with their stages. Read-only.

Resolves pool names to IDs for add_prospect. Returns each pool's prospect_stages (ordered) for specifying a starting stage when adding prospects.

ParametersJSON Schema
NameRequiredDescriptionDefault
activeNotrue = active pools only, false = inactive only
cursorNoPass next_cursor from the previous response to get the next page
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does declare 'Read-only' plus what the response contains (ordered prospect_stages). It omits any note on pagination semantics or auth, though those are partly covered by the schema's paginate/cursor params.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the core action, followed by the read-only note and the two practical reasons to call it. No redundant or filler sentences.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values needn't be spelled out, yet the description usefully flags the prospect_stages field. Complete enough for an agent to select and invoke it, with only minor gaps around sibling routing and pagination behavior.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the four optional params (active, cursor, paginate, per_page) are already fully documented in the schema. The description adds no parameter-level detail, so the baseline of 3 is appropriate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List all prospect pools with their stages') and clarifies the payload includes ordered stages. It implicitly distinguishes itself from the singular get_prospect_pool, but never names that sibling explicitly, so the differentiation is left to inference.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives a concrete use case: resolve pool names to IDs for add_prospect and pick a starting stage. This is clear routing guidance. It stops short of stating exclusions or naming get_prospect_pool as the alternative for a single pool.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_prospect_post_sectionsA

List prospect post sections on the job board. Read-only.

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.5/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the behavioral burden; it does disclose 'Read-only', which is valuable safety context. However, it says nothing about pagination, result volume, or whether sections are scoped to a specific board/job, so the read-only hint is the only real behavioral signal.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, with the operation and its scope front-loaded and the safety property trailing. Nothing is padded, though the second sentence is fragmentary and could be folded into the first without loss.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a parameterless read-only list with an output schema that already documents return values, the description supplies what an agent needs: the resource, its scope, and that it is non-mutating. No further detail is required to call it correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The tool takes zero parameters, so there is nothing for the description to clarify beyond what the empty schema already conveys. Baseline 4 applies for a parameterless operation.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (List) and resource (prospect post sections on the job board), so the agent knows it returns a collection rather than a single item. It does not explicitly name the singular sibling get_prospect_post_section, so it stops short of full sibling differentiation.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines2/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

There is no when-to-use guidance, no mention of the related get_prospect_post_section / list_prospect_pools tools, and no stated preconditions. 'On the job board' is the only contextual hint, and it is implied rather than actionable.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_questionsA

List all demographic survey questions across all sets. Read-only.

Each question has name (the prompt), demographic_question_set_id, required, answer_type and sort_order.

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.6/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the burden. It does disclose 'Read-only', which is genuinely useful for a mutation-adjacent catalog, but says nothing about ordering, result size, or whether unanswered/inactive questions are included.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Short and front-loaded: the purpose leads, the read-only note follows, and the field list is compact. The field enumeration is somewhat redundant given the output schema, which keeps it from a 5.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a parameterless list tool with an output schema, the description covers purpose and read-only nature adequately. Enumerating returned fields is redundant with the output schema but not harmful.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The tool takes zero parameters, so per the rubric the baseline is 4. There is no parameter semantics to misdescribe.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List all demographic survey questions') plus a scope qualifier ('across all sets') that implicitly contrasts with the scoped sibling list_questions_for_question_set. It does not name that sibling explicitly, so it falls short of full differentiation.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

'Across all sets' hints at when to prefer this over a set-scoped listing, but the description never states when to use this versus list_question_sets or list_questions_for_question_set. Usage context is only implied.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_question_setsA

List all demographic survey question sets. Read-only.

Admin/compliance tool for managing demographic data collection. Each set has title, description, active and enabled.

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.6/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the burden, and it does disclose 'Read-only', which is genuinely useful behavioral context for a mutation-free tool. However, it says nothing about permissions required, pagination, or result ordering, and the field list (title, description, active, enabled) duplicates what the output schema already conveys.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, front-loaded with the core action and scope, with the read-only flag immediately after. The final sentence listing fields is slightly wasteful given an output schema exists, but it is brief.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a zero-parameter, read-only list tool with an output schema, the description supplies purpose, scope, and safety profile. It stops short of explaining pagination or admin-only access constraints, but nothing essential for correct invocation is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The tool takes zero parameters, so per the rubric the baseline is 4; there is no parameter semantics to clarify and the description does not confuse the matter by inventing inputs.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (List) and a specific resource (demographic survey question sets), with scope 'all' that implicitly distinguishes it from the singular get_question_set. It does not explicitly name or contrast with siblings like list_questions_for_question_set, so it falls just short of a 5.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

'Admin/compliance tool for managing demographic data collection' gives implied context for when this tool is relevant, but there is no explicit when-to-use vs when-not, no mention of the related get_question_set or list_questions_for_question_set alternatives, and no prerequisites.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_questions_for_question_setA

List questions in a specific demographic question set. Read-only.

To find question_set_id: list_question_sets.

ParametersJSON Schema
NameRequiredDescriptionDefault
question_set_idYesQuestion set ID — get from list_question_sets

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.6/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are supplied, so the description carries the full behavioral burden; it does disclose 'Read-only,' which is the essential safety trait for a retrieval tool. It says nothing about pagination, ordering, or what happens with an invalid/empty question set, but the presence of an output schema lowers the bar for return-value disclosure.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short lines with zero filler; the purpose is front-loaded and the ID-sourcing hint follows immediately. Every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a single-parameter read-only list with an output schema, the description covers the scope and how to source the required ID, which is enough to call it correctly. A brief note on ordering or page size would close the remaining gap but is not essential.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and the single parameter already documents 'Question set ID — get from list_question_sets', so the description's identical hint adds nothing new. Baseline 3 applies when the schema does the heavy lifting.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (List) and resource (questions) scoped to a demographic question set, which distinguishes it from the sibling list_questions that presumably lists all questions. However, it never names that sibling or any other alternative explicitly.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives actionable guidance on obtaining the required question_set_id via list_question_sets, which is genuine usage help. It stops short of stating when to prefer this over list_questions or any related retrieval tool, leaving the scoping choice to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_rejection_reasonsA

List all rejection reasons. Read-only.

Resolves rejection reason names to IDs. When a user says "reject for 'not enough experience'," use this to find the ID, then pass it to reject_application or bulk_reject. Each reason's type is an object {id, key, name} — key is WE_REJECTED_THEM, THEY_REJECTED_US, NONE_SPECIFIED or SECURITY_CONCERN.

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
per_pageNoResults per page (max 500)
force_refreshNoBypass cache and fetch fresh data
include_defaultsNoAlso include Greenhouse's built-in default reasons

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are supplied, so the description carries the burden and it does declare 'Read-only' plus explains the shape and enum keys of each reason's `type` object (WE_REJECTED_THEM, THEY_REJECTED_US, NONE_SPECIFIED, SECURITY_CONCERN). It does not mention pagination behavior or auth requirements, but the enum-key disclosure is genuine added context beyond the schema.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with purpose and read-only status in the first line, then the workflow, then the type-object detail. Slightly padded by the return-shape explanation, but every sentence is relevant and there is no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be re-explained, and the description covers purpose, safety profile and the downstream consumption pattern. Minor gaps remain around pagination and the default/refresh flags, but nothing an agent needs to invoke it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% — cursor, per_page, force_refresh and include_defaults are all documented in the schema itself. The description adds no parameter-level guidance (e.g. when to set include_defaults or force_refresh), so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List all rejection reasons') and adds the actual purpose — resolving reason names to IDs. It does not explicitly distinguish itself from the sibling list_close_reasons, so it stops short of a 5, but the resource is specific enough that an agent can tell it apart from the surrounding list_* tools.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly describes the triggering situation ('When a user says "reject for not enough experience"') and the follow-on action ('use this to find the ID, then pass it to reject_application or bulk_reject'). It names the concrete alternatives that consume the output, leaving nothing to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_schoolsA

List schools for education records. Read-only.

Resolves school names to IDs (school_id) for add_education. Each item is a custom field option with id and name.

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
paginateNo'single' for one page, 'all' to auto-fetch every page (the school list is long — use 'all' to search it by name)single
per_pageNoResults per page (max 500)
force_refreshNoBypass cache and fetch fresh data

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.9/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are supplied, so the description carries the full behavioral burden, and it does disclose the read-only nature plus the fact that entries are custom field options shaped as id/name. It says nothing about caching (force_refresh exists in the schema), authorization needs, or rate limits, which are the remaining traits an agent would want for a long enumerable list.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Short, front-loaded, and every sentence carries information; the purpose and read-only status come first. The final sentence on item shape is partly redundant with the existing output schema, which slightly dilutes the economy.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Purpose, read-only nature, and the name-to-ID resolution workflow are all covered, and an output schema exists so return values need not be spelled out. For a zero-required-parameter lookup tool this is nearly complete; only cross-caching/permission behavior is unaddressed.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and each of the four parameters is documented in-schema, including the useful hint that the school list is long and paginate='all' enables name search. The description adds no syntax or format detail beyond that, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ('List schools for education records') plus the scope ('education records'), which cleanly separates it from list_board_schools and the other list_* enumeration tools. The agent knows exactly what this returns without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly ties the tool to its downstream use: 'Resolves school names to IDs (school_id) for add_education', which tells the agent when this call is needed. It stops short of naming an exclusion or alternative (e.g. list_board_schools, list_degrees), so it is clear context rather than full routing guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_scorecardsA

List interview scorecards across all applications. Read-only.

Each scorecard has application_id, candidate_rating (also as overall_recommendation), notes, status, interviewed_at, submitted_at and, with include_details, interviewer/submitted_by {id, name, email}, interview name, attributes [{name, rating, note}], ratings grouped by rating, and questions [{question, answer}]. v3 scorecards carry no candidate_id — use application_id. For a specific candidate, use list_scorecards_for_application (search_candidates_by_name → list_applications(candidate_id=...) → match application → use its ID).

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
statusNo'complete' for submitted scorecards, 'draft' for drafts
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)
created_afterNoISO 8601 datetime — only scorecards created at/after this
created_beforeNoISO 8601 datetime — only scorecards created before this
include_detailsNoResolve interviewer, interview, attribute ratings and question answers (extra calls; set false for faster bulk listing)

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the safety burden and does so by declaring 'Read-only.' It also discloses a behavioral quirk that matters (v3 scorecards carry no candidate_id — use application_id) and enumerates what fields appear, including the conditional fields gated by include_details. It stops short of describing pagination or rate-limit behavior, but the core traits are covered.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness3/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Purpose and routing are front-loaded, which is good, but the middle sentence is a long enumeration of returned fields (application_id, candidate_rating, notes, status, timestamps, interviewer, attributes, questions, etc.). Since an output schema exists, this return-value catalogue is largely wasted text rather than earning its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Given the tool is a straightforward list with a 100% documented schema and an existing output schema, the description covers the essentials: purpose, read-only nature, the application_id caveat, and sibling routing. The only redundancy is re-listing return fields that the output schema already defines.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so every parameter (cursor, status, paginate, per_page, created_after/before, include_details) is already documented in the schema. The description's note that include_details adds interviewer/interview/attribute/question fields is largely redundant with the schema's own description, so it adds little beyond baseline.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (List), resource (interview scorecards), and scope (across all applications), and explicitly names the sibling it is not: 'For a specific candidate, use list_scorecards_for_application.' An agent can distinguish it from the sibling without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly routes the agent: use this tool for listing across all applications, and for a specific candidate use list_scorecards_for_application, even providing the discovery chain (search_candidates_by_name → list_applications(candidate_id=...) → match application). The when-not and alternative are both spelled out.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_scorecards_for_applicationA

List scorecards submitted for a specific application. Read-only.

To find application_id: search_candidates_by_name → list_applications(candidate_id=...) → match the application to the job. Returns each interviewer's attribute ratings, question answers, notes and overall recommendation (candidate_rating).

ParametersJSON Schema
NameRequiredDescriptionDefault
application_idYesGreenhouse application ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description must carry the behavioral burden. It explicitly states 'Read-only,' which is a key safety trait, and briefly describes the return content. It omits other behavioral details such as pagination, required scopes, or error behavior, leaving clear gaps.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The description is front-loaded with purpose and read-only status, then provides a retrieval workflow, and ends with return content. It is efficient and well-structured, though the return content sentence is somewhat redundant given the output schema exists.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a simple list tool with one required parameter and a 100% covered schema plus an output schema, the description covers purpose, safety (read-only), parameter retrieval, and return content. Nothing essential for correct invocation is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% and the parameter is documented as 'Greenhouse application ID'. The description adds meaning by explaining how to obtain the application_id via a lookup workflow, which goes beyond the schema's static description.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific verb (List) and resource (scorecards) scoped to a specific application, clearly distinguishing it from siblings like list_scorecards (all scorecards) and get_scorecard (single scorecard). An agent can tell its purpose without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description provides a workflow for finding the required application_id (search_candidates_by_name → list_applications → match), which is useful usage context. However, it does not explicitly state when to use this tool versus alternatives like list_scorecards or get_scorecard, leaving the choice implied.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_sourcesA

List all candidate sources (job boards, referrals, agencies). Read-only.

Resolves source names to IDs for create_application and update_application. When a user mentions where a candidate came from, use this to find the source_id. Each source has a type object ({id, name}) — the sourcing strategy it rolls up to (e.g. "Referral", "Agencies").

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
per_pageNoResults per page (max 500)
force_refreshNoBypass cache and fetch fresh data

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full behavioral burden and does state "Read-only," which is the key safety trait. It also describes the shape of the returned type object, but adds no note on pagination or cache behavior beyond what the schema already documents.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the core action and the "Read-only" trait, followed by a short usage note and a data-shape note. Every sentence earns its place with no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be explained, and the description covers purpose, read-only status, usage, and the type object. It is broadly complete for a discovery/list tool, with only minor omissions around volume or refresh behavior that the schema already handles.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so cursor, per_page, and force_refresh are fully documented in the schema. The description adds no parameter-level semantics beyond that, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ("List all candidate sources") with clarifying examples (job boards, referrals, agencies) and a downstream purpose (resolving names to IDs). Clear and specific, but it does not explicitly differentiate itself from source-adjacent siblings such as source_effectiveness.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives concrete when-to-use guidance: use it when a user mentions where a candidate came from, and it names the consumer tools (create_application, update_application) that need the source_id. No explicit when-not-use or exclusion cases are provided.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_tagsA

List all candidate tags in the organization. Read-only.

Resolves tag names to IDs. When a user says "tag Sarah as 'strong hire'," use this to find the tag_id, then add_tag_to_candidate.

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
per_pageNoResults per page (max 500)
force_refreshNoBypass cache and fetch fresh data

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does disclose the key trait: 'Read-only,' which is the equivalent of a readOnlyHint and rules out mutation risk. It adds that it 'resolves tag names to IDs,' explaining the practical output purpose, but says nothing about caching or rate limits – though the schema already documents force_refresh.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, front-loaded with the purpose, then the return semantics, then the workflow. No filler and every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Output schema exists, so return values need not be explained, and the read-only claim plus the schema's parameter docs cover the operational essentials. Minor gap: pagination behavior is only implied via the schema rather than described here.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so cursor, per_page and force_refresh are already fully documented in the schema; the description adds no parameter-level detail. Baseline 3 applies when the schema does all the work.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource with scope: 'List all candidate tags in the organization.' The scope distinguishes it from the per-candidate sibling list_tags_on_candidate without needing the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives a concrete when-to-use trigger ('When a user says "tag Sarah as ‘strong hire’"') and names the exact downstream tool (add_tag_to_candidate), making the lookup-then-mutate workflow unambiguous.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_tags_on_candidateA

List tags on a specific candidate. Read-only.

To find candidate_id: search_candidates_by_name. Each item has the tag id and name (as in list_tags) plus applied_tag_id, the id of the tag-on-candidate record.

ParametersJSON Schema
NameRequiredDescriptionDefault
candidate_idYesGreenhouse candidate ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.8/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden. It does disclose that the operation is read-only, which is meaningful safety context, but says nothing about pagination, permission requirements, or how many tags might return.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, front-loaded with purpose and the read-only note, with no filler. The parenthetical '(as in list_tags)' is a useful cross-reference rather than padding.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a single-parameter read tool with an output schema present, the description covers purpose, safety, ID acquisition, and the shape of returned items. Nothing essential is missing, though pagination/limits are not addressed.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the single parameter is already documented as a 'Greenhouse candidate ID' (baseline 3). The description adds value by explaining how to obtain that ID via search_candidates_by_name, going beyond the schema's bare type description.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource and scopes it ('tags on a specific candidate'), which implicitly distinguishes it from list_tags (all tags) and add_tag_to_candidate/remove_tag_from_candidate. It does not name those siblings explicitly, so it falls just short of full sibling differentiation.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives a concrete usage prerequisite: to obtain candidate_id, call search_candidates_by_name. That is real routing guidance an agent can act on. However, it offers no when-not conditions and no explicit comparison to list_tags or the tag-mutation siblings.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_user_rolesA

List all user roles in the organization. Read-only.

Resolves role names to IDs for add_job_permission and add_future_job_permission. Only roles with role_type 'job_admin' can be granted on jobs.

ParametersJSON Schema
NameRequiredDescriptionDefault
cursorNoPass next_cursor from the previous response to get the next page
per_pageNoResults per page (max 500)

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the burden and does declare 'Read-only' explicitly, plus the domain constraint that only role_type 'job_admin' roles can be granted on jobs. It omits permission/auth requirements and pagination behavior, but pagination is covered by the schema and an output schema exists for return values.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Four short sentences, front-loaded with purpose, followed by safety, use case, and constraint. Nothing is redundant and each sentence adds information.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Purpose, read-only nature, intended downstream use, and the role_type constraint are all present; parameters are fully covered by the schema and an output schema handles return values. An agent has everything needed to call this correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so cursor and per_page are fully documented in the schema and the description adds no syntax or format detail beyond that. Baseline 3 is appropriate when the schema does the heavy lifting.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific verb and resource ('List all user roles in the organization') and scopes it clearly enough to separate it from sibling list tools such as list_users, list_job_permissions, and list_future_job_permissions.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It names the downstream consumers of this data ('Resolves role names to IDs for add_job_permission and add_future_job_permission'), which tells the agent why and when to call it. It stops short of stating exclusions (e.g. when to use list_job_permissions instead), so it is clear context without full when-not guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

list_usersA

List all Greenhouse users (team members, not candidates). Read-only.

This is the primary tool for resolving team member names to user IDs. When another tool needs a user_id (interviewer, approver, hiring manager), use this to find the person by name or email. Filter by email for exact lookup (matches the primary email first, then any secondary address), or paginate to scan. Each user has deactivated (was disabled), primary_email, office_ids and department_ids (get_user adds names and secondary emails).

ParametersJSON Schema
NameRequiredDescriptionDefault
emailNoFilter by exact email address (primary or secondary)
cursorNoPass next_cursor from the previous response to get the next page
paginateNo'single' for one page, 'all' to auto-fetch every pagesingle
per_pageNoResults per page (max 500)
deactivatedNotrue = only deactivated users, false = only active; omit for both
created_afterNoISO 8601 datetime — only users created after this
created_beforeNoISO 8601 datetime — only users created before this

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the burden and discharges the key part by declaring 'Read-only' and explaining the deactivated/disabled field rename. It also notes get_user's richer return. It doesn't discuss rate limits or error behavior, but the safety and data-shape disclosures are solid for a read tool.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the core identity and safety ('List all Greenhouse users ... Read-only'), then purpose, then lookup mechanics. Each sentence contributes; it is slightly long but no sentence is filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a 7-parameter list tool with 100% schema coverage and an output schema, the description covers purpose, safety, routing, and lookup behavior. Nothing an agent needs to call it correctly is missing, and return-value detail is rightly delegated to the output schema.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so baseline is 3, but the description adds real meaning: email matches 'the primary email first, then any secondary address', and it frames paginate as a scan-vs-exact-lookup choice. The deactivated field semantics are also restated usefully.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ('List all Greenhouse users') and immediately disambiguates scope ('team members, not candidates'). It distinguishes itself from the sibling get_user by noting that get_user returns additional names and secondary emails, so an agent can route without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives clear when-to-use context: 'primary tool for resolving team member names to user IDs' and the trigger ('when another tool needs a user_id'). Also contrasts the email-lookup path vs the paginate-to-scan path. It stops short of an explicit exclusion ('do not use when X'), but the practical routing is unambiguous.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

merge_candidatesA

Merge a duplicate candidate into a primary record. Write operation — cannot be undone.

Users say "these two Sarah Chens are the same person." Find both records with search_candidates_by_name. The duplicate's applications, attachments, notes and tags move to the primary, and the duplicate record is deleted. Returns the merged primary candidate.

ParametersJSON Schema
NameRequiredDescriptionDefault
primary_candidate_idYesCandidate to keep — their record is preserved
duplicate_candidate_idYesCandidate to merge away — their record is removed after merge

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full behavioral burden and does well: it flags the operation as an irreversible write and specifies that applications, attachments, notes, and tags are moved and the duplicate is deleted. It does not cover permission requirements or how conflicting scalar fields are resolved.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the action and the irreversibility warning, then gives a user scenario and a concrete lookup step. Every sentence earns its place; no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a destructive merge tool with no annotations and an output schema, the description covers irreversibility, side effects, and return value. It leaves a gap around conflict resolution for scalar fields (e.g., which email wins) and permission requirements.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds consequence-level meaning to the two IDs: the duplicate's related records move and the duplicate is removed, which goes beyond the schema's keep/remove labels.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('merge a duplicate candidate into a primary record') and uses a concrete example, but does not explicitly name any sibling tool it differs from (e.g., delete_candidate or update_candidate).

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides a clear scenario ('Users say these two Sarah Chens are the same person') and a prerequisite step ('Find both records with search_candidates_by_name'), but does not state when not to use it or name alternative tools for related cleanup.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

move_applicationA

Transfer a candidate to a completely different job. Write operation.

Users say "move Sarah from Backend to Frontend Engineer." You need the application_id (search_candidates_by_name → get_candidate → match app) and the new_job_id (list_jobs → match by name). Optionally set a starting stage with new_stage_id (list_job_stages_for_job on the target job). The current stage is looked up automatically unless from_stage_id is given. To move within the SAME job, use move_application_same_job instead.

ParametersJSON Schema
NameRequiredDescriptionDefault
new_job_idYesTarget job ID — get from list_jobs
new_stage_idNoTarget stage in new job — defaults to first stage if omitted
from_stage_idNoCurrent job_interview_stage_id (from get_application). Omit to look it up automatically
application_idYesGreenhouse application ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.5/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does disclose meaningful behavior: it flags 'Write operation' and explains that the current stage is looked up automatically unless from_stage_id is supplied, and that new_stage_id defaults to the first stage. It stops short of stating permissions required or whether the application is detached from the original job, so it is not fully complete.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Purpose is front-loaded in the first two lines and each remaining sentence (id sourcing, stage defaults, sibling routing) earns its place. Slightly plumbing-heavy in the middle but no significant waste.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need not be described. The description covers purpose, required id sourcing, optional-stage behavior, and sibling disambiguation, leaving only permission/reversibility context unaddressed for an unannotated write tool.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is already 100%, so baseline is 3, but the description adds sourcing guidance ('list_jobs', 'list_job_stages_for_job on the target job') and clarifies the auto-lookup semantics of from_stage_id, going beyond the schema text.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Transfer a candidate to a completely different job') and immediately scopes it against the same-job sibling. The agent can distinguish move_application from move_application_same_job without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly routes the agent: 'To move within the SAME job, use move_application_same_job instead.' It also provides the resolution workflow for required ids (search_candidates_by_name → get_candidate → match app; list_jobs → match by name) and the optional stage lookup path.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

move_application_same_jobA

Skip a candidate to a specific stage within the same job. Write operation.

Users say "move Sarah straight to the onsite stage" or "skip phone screen." To get the application_id: search_candidates_by_name → get_candidate → match app to job. For stage IDs: list_job_stages_for_job → find by name. The current stage is looked up automatically unless from_stage_id is given. To advance to just the next stage, use advance_application instead.

ParametersJSON Schema
NameRequiredDescriptionDefault
to_stage_idYesTarget stage ID within the same job — get from list_job_stages_for_job
from_stage_idNoCandidate's current job_interview_stage_id. Omit to look it up automatically
application_idYesGreenhouse application ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the burden; it does declare 'Write operation' and discloses the non-obvious behavior that the current stage is auto-looked-up unless from_stage_id is given. It does not mention side effects such as notifications, stage-history entries, or permission requirements, leaving some behavioral gaps for a mutation tool.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the core action and write nature, then the user-phrasing examples and lookup workflow. Every line is useful, though the quoted user phrasings overlap slightly with the opening sentence and could be trimmed.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation. Between the purpose, the alternative-tool routing, and the ID-resolution workflow, an agent has everything needed to invoke this three-parameter mutation correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so baseline is 3, but the description adds genuine value by explaining how to obtain each ID (application_id via search_candidates_by_name → get_candidate, stage IDs via list_job_stages_for_job) and why from_stage_id is optional. This goes beyond the schema's terse field descriptions.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

Specific verb ('skip/move') plus a precise resource ('a candidate to a specific stage within the same job'), and it is explicitly distinguished from move_application (cross-job) and advance_application (next stage only). An agent can pick it correctly without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

States exactly when to use it ('skip phone screen', 'move straight to onsite') and when not to ('to advance to just the next stage, use advance_application instead'), naming the alternative tool. It also gives the prerequisite lookup chains for application_id and stage IDs.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

pipeline_metricsA

Conversion rates and stage metrics for a job. Read-only.

Users say "what are our conversion rates for the Backend role?" or "where are we losing candidates?" To find job_id: list_jobs → match by name. Returns, per interview stage in pipeline order: how many applications ever reached it, how many are there now, % of all applications, stage-to-next conversion, and average days spent in the stage (from stage history).

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID — list_jobs → match by name

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.9/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations supplied, the description still carries the safety profile by declaring 'Read-only', and it discloses a great deal about the response shape (ever-reached count, current count, % of all applications, stage-to-next conversion, average days from stage history). It does not mention permissions or limits, but for a read-only metric endpoint the disclosure is strong.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the purpose and the read-only guarantee, then user phrasing, then the identifier workflow, then return contents — a logical order with almost no wasted words. The job_id lookup hint is slightly redundant with the schema, costing it a point.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so the description is not obligated to explain returns, and it still does so usefully while covering call prerequisites. The only gap is sibling disambiguation among the other pipeline analytics tools, which an agent may need to choose correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% for the single job_id parameter, so baseline is 3. The description's 'To find job_id: list_jobs → match by name' merely restates the schema's own parameter description rather than adding format or type semantics.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource combination ('Conversion rates and stage metrics for a job') and enumerates exactly what is returned per stage, which is far more informative than a tautology. It does not, however, distinguish itself from close analytics siblings such as pipeline_summary, time_to_hire, or source_effectiveness, so an agent still has to infer the boundary.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives concrete user-intent phrasings ('what are our conversion rates for the Backend role?', 'where are we losing candidates?') and the prerequisite resolution path (list_jobs → match by name). It is clear on when to use it but offers no exclusion telling the agent when a sibling analytics tool is the better choice.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

pipeline_summaryA

Complete pipeline view for a job — candidates grouped by stage. Read-only.

Users say "show me the pipeline for Backend Engineer" or "how many candidates are in each stage." To find the job_id: list_jobs → match by name. Returns the job's interview stages in pipeline order, each with its active candidates: names, source, days in the current stage, and days since last activity. One call replaces 5-10 sequential API calls.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID — list_jobs → match by name

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does well: it declares 'Read-only' and describes the return shape (interview stages in pipeline order, each with active candidates, names, source, days in current stage, days since last activity), plus the efficiency note that one call replaces 5-10 sequential calls. It omits limits such as pagination, caps on candidates per stage, or the definition of 'active'.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads purpose, then usage, then return contents in a logical order. The quoted user phrasings are slightly verbose but earn their place as trigger guidance; overall it is tight and skimmable.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values needn't be re-explained, yet the description helpfully summarizes them anyway. Combined with the read-only declaration and the job_id discovery path, an agent has everything needed to invoke it correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% and the single job_id parameter is already documented as 'Greenhouse job ID — list_jobs → match by name'. The description repeats that same discovery path, adding no meaning beyond the schema, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Complete pipeline view for a job — candidates grouped by stage') and clearly distinguishes itself from analytics siblings like pipeline_metrics or stale_applications by emphasizing the per-job grouped-by-stage view. An agent can tell what this returns without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives concrete user phrasings that should trigger it ('show me the pipeline for Backend Engineer', 'how many candidates are in each stage') and explains how to obtain the required job_id (list_jobs → match by name). It does not explicitly state when to prefer a sibling such as pipeline_metrics or candidates_needing_action, so it stops short of full alternative routing.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

post_candidateA

Submit a candidate via the Ingestion API (partner integration). Write operation.

For internal candidate creation (as recruiter/admin), use create_candidate and create_application instead. This is the partner/integration endpoint.

ParametersJSON Schema
NameRequiredDescriptionDefault
emailYesCandidate's email address
phoneNoCandidate's phone number
job_idNoJob to apply to — retrieve_ingestion_jobs to find
resumeNoResume content or URL
sourceNoSource name (free text)
prospectNoTrue to create as prospect instead of applicant
last_nameYesCandidate's last name
first_nameYesCandidate's first name

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden, and it does disclose the key trait ('Write operation') plus the partner-endpoint framing. However it omits auth requirements, rate limits, idempotency, and duplicate-email behavior for a mutation tool, so meaningful behavioral gaps remain.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, no waste, and the verb and scope are front-loaded ahead of the alternative routing guidance. Every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema and full parameter coverage exist, so return values and params need no further explanation. The description closes the main routing gap versus siblings; only operational details like auth for the partner endpoint are left implicit.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the schema already documents all 8 parameters (including cross-references like 'retrieve_ingestion_jobs to find' for job_id). The description adds no parameter-level meaning beyond that, making the baseline 3 appropriate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Submit a candidate') and scopes it precisely ('via the Ingestion API (partner integration)'). It explicitly distinguishes itself from the sibling tools create_candidate and create_application, so an agent can route without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives an explicit when-not and names the alternatives: 'For internal candidate creation (as recruiter/admin), use create_candidate and create_application instead. This is the partner/integration endpoint.' The selecting condition (partner vs internal user) is clear, leaving nothing to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

post_tracking_linkB

Create a tracking link for source attribution on a job. Write operation.

Generates a URL that attributes future applications to this source.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesJob ID — retrieve_ingestion_jobs to find
sourceYesSource name for attribution
referrerNoReferrer name or identifier

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

B3.3/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden. It does disclose two useful traits: it is a write operation, and its output URL 'attributes future applications to this source', which explains its downstream effect. However, it omits permission requirements, whether a link can be regenerated or duplicated, and any uniqueness/idempotency behavior.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two compact sentences, front-loaded with the action and its scope, with zero filler. The downstream effect is stated in a single tight clause.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness3/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be explained, and the write nature plus attribution effect are covered. For a mutation tool with zero annotations, though, the description leaves permission/auth and edge-case behavior unaddressed, which is a moderate gap rather than a full one.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the schema already documents job_id (with a pointer to retrieve_ingestion_jobs), source, and the optional referrer. The description adds no syntax, format, or default information beyond what the schema provides, making the baseline 3 appropriate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb ('Create'), resource ('tracking link'), and scope ('for source attribution on a job'), so the agent knows exactly what the tool produces. It does not explicitly name the read-side sibling (get_tracking_link) to differentiate this create from that retrieve, so it stops short of a 5.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines2/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description gives no when-to-use guidance, no prerequisites, and no alternatives. The 'Write operation' line hints that this is the mutating counterpart to get_tracking_link, but that routing is left entirely to inference rather than stated.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

read_candidate_resumeA

Download and return a candidate's most recent resume text. Read-only.

Users say "pull up Sarah's resume" or "show me John's CV." To find candidate_id: search_candidates_by_name. Returns extracted text from the most recently uploaded resume across all the candidate's applications. For batch reading, use batch_read_resumes.

ParametersJSON Schema
NameRequiredDescriptionDefault
candidate_idYesGreenhouse candidate ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does well: it declares 'Read-only' and discloses the selection behavior ('most recently uploaded resume across all the candidate's applications'), which is non-obvious. It doesn't cover auth/permission requirements or rate limits, but the key behavioral traits are stated.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the core action and scoping constraint, then adds example phrasings and routing hints. Efficient overall, though the user-utterance examples ('pull up Sarah's resume') are somewhat decorative and could be trimmed.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return-value explanation is unnecessary; the description still notes that extracted text is returned. It fully covers the single parameter's provenance and the alternative tool, leaving no gaps for an agent to call it correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the candidate_id type and description are already documented (baseline 3). The description adds real value by routing the agent to search_candidates_by_name to resolve the ID, going beyond the schema's bare 'Greenhouse candidate ID'.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (download/return) and resource (candidate's most recent resume text), and explicitly distinguishes itself from sibling tools batch_read_resumes and download_attachment. An agent can tell it apart from other read tools without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides explicit when-to-use guidance, including how to obtain the required candidate_id ('To find candidate_id: search_candidates_by_name') and the alternative for bulk operations ('For batch reading, use batch_read_resumes'). Nothing is left to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

reject_applicationA

Reject a candidate from a job. Write operation.

Users say "reject Sarah from the Backend role." To get the application_id: search_candidates_by_name → get_candidate → match the application to the job. A rejection_reason_id is required: list_rejection_reasons → match by name. For email templates: list_email_templates; the email is sent from email_from_user_id, defaulting to the configured Greenhouse user. Can be reversed with unreject_application. For bulk rejections, use bulk_reject.

ParametersJSON Schema
NameRequiredDescriptionDefault
notesNoInternal rejection notes (not sent to candidate)
application_idYesGreenhouse application ID
rejection_emailNoOptional email to candidate: {email_template_id, send_email_at (ISO 8601), email_from_user_id}
rejection_reason_idYesReason ID (required) — get from list_rejection_reasons

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does substantial work: it declares the operation is a write, discloses reversibility via unreject_application, and explains that an email is sent from email_from_user_id defaulting to the configured Greenhouse user. Permission requirements and side effects on application state aren't fully detailed, keeping it below a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the verb, resource, and operation type, then layers the ID-resolution guidance. Dense but every sentence earns its place; the workflow arrows make it scannable rather than verbose.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Given an output schema exists, return values need not be explained. For a mutation tool with no annotations, the description still covers purpose, prerequisites, side effects, defaults, and alternatives, so an agent has everything needed to call it correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds real value: it tells the agent how to obtain application_id and rejection_reason_id (via search_candidates_by_name/get_candidate and list_rejection_reasons) and documents the default behavior of email_from_user_id, which the schema does not.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Reject a candidate from a job') and immediately flags the operation class with 'Write operation.' An agent can distinguish it from siblings like bulk_reject and unreject_application without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly maps the natural-language request to the required workflow (search_candidates_by_name → get_candidate → match application), names the alternative for bulk cases ('use bulk_reject'), and points to unreject_application for reversal. When/when-not and alternatives are all covered.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

remove_educationA

Remove an education entry from a candidate. Write operation.

To find candidate_id: search_candidates_by_name. For education_id: get_candidate → check the educations array. Checks the record belongs to this candidate before deleting it.

ParametersJSON Schema
NameRequiredDescriptionDefault
candidate_idYesGreenhouse candidate ID
education_idYesEducation record ID from the candidate's profile

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden, and it does disclose two meaningful traits: that this is a write (destructive) operation and that it validates record ownership before deleting. It still omits irreversibility, failure behavior, and required permissions, so it is strong but not exhaustive.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Four short sentences, front-loaded with the action and its nature, followed by lookup instructions and the safety check. No filler and nothing repeated from the schema.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need not be described, and the description covers the mutation's nature, ID discovery, and ownership validation. Given zero annotations and a destructive operation, it could say more about irreversibility or error cases, but it is close to sufficient.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline would be 3, but the description adds real value by explaining how each required ID is obtained (search_candidates_by_name for candidate_id, get_candidate's educations array for education_id) — provenance the schema itself does not convey.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Remove an education entry from a candidate') and identifies it as a write operation. It is clearly distinguishable from sibling tools like add_education, remove_employment, and delete_candidate without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides concrete routing guidance: use search_candidates_by_name for candidate_id and get_candidate to read the educations array for education_id. It does not, however, state when this tool should be preferred over alternatives or any exclusions, so it stops short of full when/when-not guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

remove_employmentA

Remove an employment entry from a candidate. Write operation.

To find candidate_id: search_candidates_by_name. For employment_id: get_candidate → check the employments array. Checks the record belongs to this candidate before deleting it.

ParametersJSON Schema
NameRequiredDescriptionDefault
candidate_idYesGreenhouse candidate ID
employment_idYesEmployment record ID from the candidate's profile

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does well: it labels the tool as a write operation and discloses a safety behavior ('Checks the record belongs to this candidate before deleting it'). It does not state whether the deletion is reversible, what permissions are required, or what happens on a mismatched ID.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short, front-loaded statements with no filler; the purpose and write-operation warning come first, followed by ID discovery. The trailing line break and fragment style is slightly ragged but nothing is wasted.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be described. The description covers purpose, destructive nature, ID sourcing, and a validation guarantee, leaving only reversibility/auth details unstated.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description goes beyond it by explaining how to obtain each ID and noting that employment_id comes from the candidate's employments array via get_candidate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb ('Remove') and resource ('an employment entry from a candidate'), and immediately classifies it as a write operation, distinguishing it from siblings like remove_education and add_employment.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives concrete discovery paths for both required parameters (search_candidates_by_name for candidate_id, get_candidate → employments array for employment_id), which is exactly the how-to-use guidance an agent needs. It stops short of stating when not to use it or what alternatives exist for employment edits.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

remove_future_job_permissionA

Revoke a future job permission rule. Write operation — admin only.

To find user_id: list_users → match by name. For the permission ID: list_future_job_permissions for the user. The permission ID alone identifies the rule; user_id is accepted for context.

ParametersJSON Schema
NameRequiredDescriptionDefault
user_idYesGreenhouse user ID — get from list_users
future_job_permission_idYesPermission ID to revoke — get from list_future_job_permissions

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations the description carries the full burden, and it discloses the two highest-value traits: this is a write operation and it is admin-only. It stops short of stating whether the revocation is reversible or the response format.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads purpose and the critical write/admin constraint in the first two clauses, then gives the ID-resolution steps efficiently. Every sentence is useful, though the ID lookup guidance is slightly verbose for two fully documented parameters.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Two required params are fully documented and an output schema exists so return values need no explanation. The description covers purpose, safety, and parameter sourcing, leaving only reversibility unstated.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is already 100%, but the description adds real meaning beyond it: it explains that user_id is resolved via list_users matched by name, that the permission ID comes from list_future_job_permissions, and notably that the permission ID alone identifies the rule while user_id is only contextual.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (Revoke) plus a precise resource (future job permission rule), and the 'future' qualifier cleanly distinguishes it from the sibling remove_job_permission. An agent can identify the target operation without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives clear invocation context: it is a write operation, requires admin, and provides a workflow for obtaining both IDs. It does not explicitly name when to prefer this over sibling removal tools, but the preconditions are concrete and actionable.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

remove_hiring_team_memberA

Remove someone from a job's hiring team. Write operation.

Removes the user from every hiring-team role they hold on the job. To find job_id: list_jobs → match by name. For user_id: list_users → match by name, or get_hiring_team to see current members and their IDs.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID
user_idYesUser ID to remove from the hiring team — get from get_hiring_team

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden. It discloses that this is a write operation and, importantly, that the removal spans every hiring-team role the user holds on the job. It omits permission requirements, reversibility, and error behavior, but the scope disclosure is the most decision-relevant trait.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Short and front-loaded: the operation and its scope come first, followed by the ID-sourcing guidance. The lookup instructions add length but each sentence is actionable, so little is wasted.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With an output schema present, return values need not be explained, and both parameters are documented. For a simple removal tool this is nearly complete; only auth/permission context is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds value beyond the schema by naming the tools that produce each ID (list_jobs, list_users, get_hiring_team). This resolves ambiguity about where job_id and user_id come from.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (remove) and resource (hiring team member on a job), and clarifies the exact scope: the user is removed from every hiring-team role on that job. This clearly distinguishes it from add_hiring_team_members, replace_hiring_team, and get_hiring_team.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives concrete lookup workflows for both required IDs (list_jobs for job_id, list_users or get_hiring_team for user_id), which tells the agent how to satisfy prerequisites. It does not, however, state when to prefer this over replace_hiring_team or add_hiring_team_members.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

remove_job_permissionA

Revoke a user's job-level permission. Write operation — admin only.

To find user_id: list_users → match by name. For the permission ID: list_job_permissions for the user → match the job. The permission ID alone identifies the row; user_id is accepted for context.

ParametersJSON Schema
NameRequiredDescriptionDefault
user_idYesGreenhouse user ID — get from list_users
job_permission_idYesPermission ID to revoke — get from list_job_permissions

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.8/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full burden and does well: it explicitly declares 'Write operation' and 'admin only', which is exactly the mutation/auth context an agent needs. It also explains that the permission ID alone identifies the row while user_id is contextual. It stops short of stating reversibility or failure behavior.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Purpose and the admin/write constraint are front-loaded, followed by the ID-lookup workflow. Sentences are dense but each earns its place; only the closing clause about user_id being 'accepted for context' is slightly redundant with the parameter clarification.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a two-parameter destructive tool with an output schema present, the description covers mutation semantics, authorization requirement, and parameter sourcing. The main gap is the absence of any disambiguation from remove_future_job_permission, which matters given how similar the sibling names are.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% and both params are documented there, so the baseline is 3. The description goes beyond the schema by stating how to source each ID and clarifying that user_id is not strictly needed for identification ('the permission ID alone identifies the row'), which meaningfully affects how the agent supplies arguments.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific verb and resource: 'Revoke a user's job-level permission.' That is clear and actionable. However, it does not differentiate from the close sibling remove_future_job_permission, so an agent cannot tell from the text alone which of the two permission-removal tools applies.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It gives a concrete retrieval workflow (list_users to find user_id, list_job_permissions to find the permission ID) and flags 'admin only'. But it offers no when-to-use/when-not guidance relative to add_job_permission, list_job_permissions, or remove_future_job_permission, leaving alternative selection to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

remove_job_post_locationA

Remove a location from a job post. Write operation.

To find job_post_location_id: get_job_post → locations[].id.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_post_location_idYesJob post location ID — the id in a post's locations array

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.7/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description must carry the behavioral load. It does disclose 'Write operation', which is genuinely useful, but it does not say whether the removal is permanent, whether it affects previously published job boards, or what happens if the location ID is already gone.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, no filler, with the action statement front-loaded ahead of the ID-discovery hint. Every clause earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a single-parameter tool with a 100%-covered schema and an output schema (so return values need no explanation), the description covers purpose, mutability, and ID sourcing. It is only missing confirmation of permanence and failure behavior.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% and there is only one parameter, so the baseline is 3; the description earns above baseline by giving a concrete retrieval path for the ID (get_job_post → locations[].id), which tells the agent where the value actually comes from.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific verb and resource ('Remove a location from a job post'), which is unambiguous and implicitly pairs against the sibling add_job_post_location. It stops short of naming any sibling explicitly, which is the only thing keeping it from a 5.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Usage is only implied: you call this when you want a location detached from a job post. There is no statement of when not to use it, no named alternative, and no note about prerequisites or side effects of removing a location.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

remove_tag_from_candidateA

Remove a tag from a candidate. Write operation.

For candidate_id: search_candidates_by_name. For tag_id: list_tags_on_candidate → find the tag, or list_tags → match by name.

ParametersJSON Schema
NameRequiredDescriptionDefault
tag_idYesTag ID to remove — get from list_tags_on_candidate
candidate_idYesGreenhouse candidate ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the disclosure burden, and it does flag this as a 'Write operation' — the minimum needed to signal mutation. However, it says nothing about whether the removal is idempotent, what happens if the tag is not on the candidate, or permission requirements. Informative but incomplete for a mutating tool.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short, front-loaded statements — action, operation type, then ID sourcing. Zero filler, every sentence carries information the caller needs.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be described, and the ID-acquisition paths are fully covered. The remaining gap is behavioral edge cases (tag not present, auth/permission needs) for a write operation with no annotations to fall back on.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the baseline is 3, and the description adds real value on top: it tells the agent how to source each ID (search_candidates_by_name for the candidate, list_tags_on_candidate / list_tags for the tag). The schema alone only says 'get from list_tags_on_candidate' for tag_id and offers nothing for candidate_id lookup.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a concrete verb and resource ('Remove a tag from a candidate') with no ambiguity, and the inverse relationship to the sibling add_tag_to_candidate is immediately obvious. An agent can distinguish this from delete_tag (which removes the tag itself, not an association) without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives explicit prerequisite routing: use search_candidates_by_name for candidate_id, and list_tags_on_candidate or list_tags for tag_id. This is genuinely actionable. It stops short of saying when NOT to use it (e.g., versus delete_tag or bulk_tag), so it is not a full 5.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

replace_approverA

Replace one approver with another in an approval flow. Write operation.

Users say "swap John for Sarah on the Backend approval." For user IDs: list_users → match by name. For job_id: list_jobs. For approval_flow_id: list_approvals_for_job. The approver being removed must not have approved or rejected yet.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID
add_user_idYesUser ID to add as replacement approver
remove_user_idYesUser ID to remove from the approver group
approval_flow_idYesApproval flow ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does disclose the core traits: 'Write operation' and the precondition that the removed approver must not have approved or rejected yet. It omits permissions required, whether the added approver inherits any pending state, and failure modes, so it is helpful but not complete.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The purpose and write-operation note are front-loaded, followed by the usage example and ID resolution. Every sentence is functional, though the lookup routing is slightly list-like and could be tightened.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation. The description covers purpose, trigger, ID resolution, and the key precondition; only permission/auth context is missing, which is a minor gap for this four-param mutation.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% (baseline 3), and the description adds real meaning by mapping each ID to its lookup path (job_id→list_jobs, approval_flow_id→list_approvals_for_job, user IDs→list_users) and by constraining remove_user_id semantically. This exceeds what the schema alone conveys.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource: 'Replace one approver with another in an approval flow.' The 'one approver with another' phrasing distinguishes it from the sibling create_or_replace_approval_flow, which replaces a whole flow. An agent can select it without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides a concrete trigger ('swap John for Sarah on the Backend approval') and routes ID resolution to the right tools (list_users, list_jobs, list_approvals_for_job), plus a precondition that the removed approver must not have acted yet. It does not name when to prefer a sibling like create_or_replace_approval_flow instead, so it stops short of full exclusion guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

replace_hiring_teamA

Replace the hiring team for a job. Write operation — overwrites existing members.

Only the roles you pass are replaced; omitted roles are left alone. Members missing from a passed list are removed and new ones are added. To find job_id: list_jobs → match by name. For member user_ids: list_users → match each person by name. Returns added, removed and any per-member errors.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID
sourcersNoArray of {user_id: N} — replaces all sourcers
recruitersNoArray of {user_id: N, candidate_responsibility?: active|inactive|future|all} — replaces all recruiters
coordinatorsNoArray of {user_id: N, candidate_responsibility?: active|inactive|future|all} — replaces all coordinators
hiring_managersNoArray of {user_id: N} — replaces all hiring managers

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does so well: it flags this as a write operation, states that existing members are overwritten, that omitted roles are left alone, and that members missing from a passed list are removed. It stops short of covering permission requirements or irreversibility guarantees.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the action and its destructive nature, then the replacement semantics, then the lookup recipes, then the return shape. Every sentence earns its place with no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a five-parameter mutation tool with no annotations, the description covers the risky semantics (overwrite, per-role replacement, removals) and even hints at the return payload despite an output schema existing. Auth/permission prerequisites are the only notable gap.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the schema already documents each array and its {user_id} shape, giving a baseline of 3. The description adds real meaning on top: it explains that each passed list fully replaces that role and that absent lists are no-ops, plus how to source job_id and user_ids.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (replace) and resource (hiring team for a job), and the semantics of replacement distinguish it clearly from the sibling add_hiring_team_members, get_hiring_team and remove_hiring_team_member without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description makes the selection condition clear implicitly: replacement is per-role and omitted roles are untouched, which is what separates it from the additive sibling. It also gives concrete discovery paths (list_jobs to find job_id, list_users to find user_ids), though it never explicitly names an alternative tool or a when-not-to-use case.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

request_approvalsA

Trigger an approval request for a flow on a job. Write operation.

Sends the approval request emails to the first approvers. To find job_id: list_jobs → match by name. For approval_flow_id: list_approvals_for_job.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID
approval_flow_idYesApproval flow ID to trigger — get from list_approvals_for_job

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the burden and it does disclose useful behavior: 'Write operation' plus the concrete side effect that approval request emails are sent to the first approvers. However, it omits permissions/auth requirements, idempotency (does re-triggering resend emails?), and error behavior, which matter for an email-firing mutation.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded purpose, then mutation/write flag, then side effect, then ID discovery paths. Short and every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need not be explained, and the description covers purpose, write nature, side effect, and ID sourcing for a simple 2-parameter tool. Only auth/permission context is missing, a minor gap at this complexity.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so baseline is 3, but the description adds a discovery path the schema lacks: for job_id it specifies list_jobs → match by name, whereas the schema only says 'Greenhouse job ID'. The approval_flow_id guidance duplicates the schema hint, so value is marginal but real.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource: 'Trigger an approval request for a flow on a job.' This is clearly distinct from siblings like create_or_replace_approval_flow (which defines flows) and list_approvals_for_job (which lists them). An agent can tell what this does without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives concrete prerequisites: how to obtain job_id (list_jobs, match by name) and approval_flow_id (list_approvals_for_job). Clear context for when to use it, but no explicit exclusions such as when to define a flow instead of triggering one.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

retrieve_current_userA

Get the current integration partner user. Read-only.

Returns the API user associated with the Ingestion API credentials.

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.6/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden, and it does supply a useful behavioral fact: "Read-only." It also clarifies the identity context (API user tied to Ingestion API credentials). However it omits any error/permission behavior for invalid credentials or what fields the user record contains, leaving the disclosure thin.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, front-loaded with the action and a read-only marker. The second sentence partially restates the first (partner user vs API user associated with credentials), but it adds the credential-scoping detail rather than pure redundancy.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no description, and there are no parameters to explain. For a zero-arg read tool the description covers purpose, scope, and safety adequately; only richer behavioral detail (auth failure, field list) is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The tool takes zero parameters and the schema is empty at 100% coverage, so there is nothing for the description to document. Baseline 4 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description gives a specific verb+resource ("Get the current integration partner user") and scopes it to the caller's own credentials, which distinguishes it from the sibling get_user that fetches an arbitrary user. It does not explicitly name that sibling, but the 'current/API user' framing is clear enough to route correctly.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Usage is implied by "the API user associated with the Ingestion API credentials" - an agent infers this is for identifying the authenticated caller. There is no explicit when-to-use, when-not-to-use, or pointer to the alternative get_user for other users.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

retrieve_ingestion_candidatesA

List candidates submitted through the Ingestion API. Read-only.

Shows candidates this integration has submitted. For the full candidate database, use list_candidates instead.

ParametersJSON Schema
NameRequiredDescriptionDefault
pageNoPage number
per_pageNoResults per page (max 500)

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden, and it does disclose the key behavioral trait: 'Read-only.' However, it says nothing about pagination behavior, authentication/integration requirements, or rate limits, so the disclosure is thinner than a mutation-free read tool with zero annotations could support.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The purpose and read-only nature are front-loaded in the first two lines, with the sibling routing last. Three short statements, no filler, and each one carries distinct information.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be explained, and the read-only nature plus the scope and sibling alternative are all covered. The only gap is minor: no mention of pagination behavior for a paged list endpoint.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so page and per_page are already documented in the schema and no required parameters exist. The description adds no meaning about parameter usage (e.g., how paging relates to the integration scope), so it sits at the baseline for fully covered schemas.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (List) and resource (candidates) and narrows the scope precisely: candidates submitted through the Ingestion API by this integration. It explicitly contrasts with the sibling list_candidates, so an agent can distinguish the two without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Names the alternative (list_candidates) and the condition that selects it ('full candidate database'), which is a genuine routing hint. It stops short of stating when this tool is the right choice beyond the implicit scoping to this integration's submissions.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

retrieve_ingestion_jobsA

List jobs visible to the integration partner. Read-only.

Partner-scoped version of list_jobs. Returns only jobs the integration has been granted access to.

ParametersJSON Schema
NameRequiredDescriptionDefault
pageNoPage number
per_pageNoResults per page (max 500)

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden. It usefully discloses 'Read-only' and the access-grant scoping behavior, but says nothing about pagination semantics, ordering, or what happens when the integration has no grants. Adequate but incomplete for a tool with zero annotation coverage.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, zero filler, with the core purpose and the read-only/safety note front-loaded. Every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With an output schema present and 100% parameter coverage, the description only needs to convey purpose, safety, and scope, which it does. It could go slightly further on pagination or no-access behavior, but nothing an agent needs to invoke it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so page and per_page are already fully documented in the schema. The description adds no syntax, default, or constraint detail beyond what the schema provides, which is the expected baseline when the schema does the heavy lifting.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (list), resource (jobs), and scope (visible to the integration partner), then explicitly distinguishes itself from the sibling list_jobs by calling itself the 'Partner-scoped version.' An agent can tell exactly what this returns and how it differs from list_jobs without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The phrase 'Partner-scoped version of list_jobs' and 'Returns only jobs the integration has been granted access to' give clear context for when this applies versus the general list_jobs. It does not spell out an explicit when-not condition, but the partner-scoping framing is enough for correct routing.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

retrieve_prospect_poolsA

List prospect pools via the Ingestion API. Read-only.

Partner-scoped version of list_prospect_pools.

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden. It usefully declares 'Read-only' and names the Ingestion API, which is real behavioral value, but says nothing about pagination, result limits, or authentication/partner-scope requirements.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short fragments, front-loaded with the action and resource, then the safety trait, then the sibling differentiation. No filler or repetition.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With no parameters, an output schema present, and read-only status disclosed, the description covers what an agent needs to call it correctly. The only minor gap is the absence of any partner-scope authentication context.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The tool takes zero parameters, so the baseline of 4 applies; there is nothing for the description to disambiguate and it does not attempt to invent parameter behavior.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List prospect pools') and explicitly differentiates itself from the sibling list_prospect_pools by naming itself the 'Partner-scoped version'. An agent can pick between the two without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The phrase 'Partner-scoped version of list_prospect_pools' gives a clear condition for choosing this tool over its sibling, and 'via the Ingestion API' indicates the calling context. It stops short of explicitly stating when NOT to use it or what a partner scope concretely means.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

scan_all_candidatesA

Database-wide candidate search by structured fields. Read-only.

Like search_pipeline_candidates but searches the full database, not just specific pipelines. Use when candidates might be in unexpected pipelines. Pass updated_after to limit scope on large databases (title, company and experience filters fetch employment history for every scanned page). Follow up with batch_read_resumes to validate matches.

ParametersJSON Schema
NameRequiredDescriptionDefault
tagsNoTag names to filter by
max_pagesNoMaximum pages to scan (500 candidates/page)
max_resultsNoMaximum candidates to return
updated_afterNoISO 8601 date — limit to recently updated candidates
title_keywordsNoJob title keywords — e.g. ['Engineer', 'Manager']
company_keywordsNoCompany name keywords
education_keywordsNoEducation keywords
min_experience_yearsNoMinimum years of work experience

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.7/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description must carry the burden, and it does declare 'Read-only' plus a real performance caveat: title/company/experience filters fetch employment history for every scanned page, and updated_after limits scope on large databases. It does not describe pagination or result caps beyond what the schema already states, keeping it short of a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with purpose and read-only status, then alternative, then performance guidance, then follow-up. Four short sentences, none wasted.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need not be explained; the description instead covers the things the schema can't: sibling differentiation, cost behavior, and the recommended next call. Complete for a broad scan tool.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so baseline is 3, but the description adds operational meaning beyond the schema: which parameters are expensive (title/company/experience) and why updated_after matters on large databases. That is genuine value over the field descriptions.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (search), resource (candidates), and scope (database-wide, by structured fields), and explicitly contrasts with the sibling search_pipeline_candidates. An agent can distinguish it from other candidate-search tools without opening schemas.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Names the alternative (search_pipeline_candidates), gives the selecting condition ('candidates might be in unexpected pipelines'), and prescribes a follow-up step (batch_read_resumes to validate matches). Explicit when-to-use and what-to-do-next.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

scan_pipeline_resumesA

Search resume text in pipelines for skills and qualifications. Read-only.

Users say "find Rust engineers in our pipelines" or "search for distributed systems experience." The primary sourcing tool — ~90% of candidate data lives in resumes. Pass job_ids (list_jobs → get IDs for similar roles). Supports boolean search: keywords (OR), required_keywords (AND), exclude_keywords (NOT with word-boundary matching).

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idsYesJob IDs to search — list_jobs → get IDs for similar roles
keywordsNoOR keywords — each hit boosts ranking
statusesNoFilter by status: 'active', 'rejected', 'hired'
max_resumesNoMaximum resumes to scan
exclude_keywordsNoNOT keywords — any match disqualifies (word-boundary matching)
required_keywordsNoAND keywords — ALL must appear or candidate is skipped

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

The description discloses 'Read-only' (since no annotations are provided) and details the boolean search behavior: keywords (OR), required_keywords (AND), exclude_keywords (NOT with word-boundary matching). This goes beyond the schema and gives the agent a clear picture of side effects and matching rules.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The description is well-structured: a clear purpose statement, a user-facing example, tool positioning, a prerequisite instruction, and a semantic explanation. It is compact with no unnecessary words, though it is slightly dense in one paragraph.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Given the output schema documents return values, the description covers the essential usage guidance, search logic, source scope (resumes in pipelines), and readonly nature. It does not cover all edge cases, but it is sufficiently complete for effective selection and invocation.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3. The description adds value by explaining the semantic of OR/AND/NOT for the keyword parameters and the word-boundary matching nuance for exclude_keywords, which is not evident from the schema alone.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description explicitly states the action ('Search resume text in pipelines for skills and qualifications') and provides example user queries ('find Rust engineers'). It distinguishes itself from siblings by positioning as 'the primary sourcing tool' with boolean search capabilities, making its purpose unmistakable.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It gives clear usage context: 'The primary sourcing tool — ~90% of candidate data lives in resumes' and instructs to 'Pass job_ids (list_jobs → get IDs for similar roles)'. It does not explicitly name alternatives, but the positioning makes it clear this is the go-to tool for resume search.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

screen_candidateA

Full screening package for one candidate application. Read-only.

Users say "screen Sarah for the Backend role" or "give me the full picture." To get application_id: search_candidates_by_name → list_applications (candidate_id=...) → match the application to the job name. Returns profile, resume text, location, screening answers, job description, and application history (with job names and rejection reasons) in one call.

ParametersJSON Schema
NameRequiredDescriptionDefault
application_idYesApplication ID — search_candidates_by_name → list_applications(candidate_id=...) → match the job

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are supplied, so the description carries the full disclosure burden, and it does state 'Read-only' and that everything is returned 'in one call' (no follow-up calls required). It does not cover permission requirements or any rate/volume limits, but the key safety trait and the single-call behavior are disclosed.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The identity of the tool and its read-only nature are front-loaded in the first two sentences, and the return-value list is compact. The middle 'Users say...' sentence is the softest part but still earns its place by supplying recognition triggers.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With a 100% covered single required parameter and an output schema present, the description need not explain return shapes, yet it still previews the payload so the agent knows this replaces several narrower calls. The only real gap is not positioning it against the adjacent single-purpose readers.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and the schema's own description already contains the search_candidates_by_name -> list_applications resolution chain, so the description's restatement adds no meaning beyond the structured field. Baseline 3 applies when the schema does the heavy lifting on a single-parameter tool.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description names a specific verb and resource ('Full screening package for one candidate application') and then enumerates exactly what the package contains (profile, resume text, location, screening answers, job description, application history). That enumeration distinguishes it from narrow siblings like get_application, get_candidate, and read_candidate_resume without the agent opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It gives concrete invocation triggers ('screen Sarah for the Backend role', 'give me the full picture') and an explicit ID-resolution path: search_candidates_by_name -> list_applications(candidate_id=...) -> match the application to the job name. What is missing is an explicit when-not-to-use, e.g. that get_application or read_candidate_resume should be preferred when only one piece of data is needed.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

search_candidates_by_emailA

Look up a candidate by exact email address. Read-only.

Use when the user provides an email instead of a name. Matches any email on the candidate's profile and returns the candidate record. For their applications, follow up with list_applications(candidate_id=...). For name-based lookup, use search_candidates_by_name.

ParametersJSON Schema
NameRequiredDescriptionDefault
emailYesExact email address to search for

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.7/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full behavioral burden and does disclose read-only status, exact-email matching, and that any email on the profile can match. It stops short of describing error cases, multiple-match handling, or permission requirements, so it is strong but not complete.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the core action and read-only status, then adds usage and alternatives in three short, well-structured sentences. Every sentence earns its place with no redundancy.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return format need not be explained; the description covers when to use the tool, the relevant alternative, and the logical next step. For a single required parameter lookup tool, nothing essential is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the baseline is 3; the description adds meaning by saying it 'matches any email on the candidate's profile,' which clarifies that the exact email can match against multiple email fields on the profile. It goes slightly beyond the schema's terse 'Exact email address to search for.'

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb ('look up') and resource ('candidate by exact email address'), and explicitly distinguishes from sibling tools such as search_candidates_by_name and the broader get_candidate/list_candidates. An agent can identify the tool's scope without reading the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives explicit when-to-use ('when the user provides an email instead of a name'), a clear alternative ('For name-based lookup, use search_candidates_by_name'), and a follow-up action for applications. Nothing about selecting this tool is left to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

search_candidates_by_nameA

Find candidates by name. Read-only — the starting point for most workflows.

Users always refer to candidates by name, not ID. Use this first whenever a user mentions a candidate, then list_applications(candidate_id=...) to find their application IDs (candidate records don't include applications). Case-insensitive substring match — "Sarah" finds "Sarah Chen", "Sarah O'Brien", etc. Greenhouse has no name filter, so this scans up to max_pages × per_page candidates; if has_more is true, pass next_cursor to keep scanning.

ParametersJSON Schema
NameRequiredDescriptionDefault
nameYesName to search — matches first, last or preferred name (case-insensitive substring)
cursorNoResume a scan: pass next_cursor from a previous response that had has_more=true
per_pageNoCandidates scanned per page (max 500)
max_pagesNoMaximum pages to scan before stopping

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.9/5.0
Behavior5/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does so: declares read-only, discloses case-insensitive substring matching, warns that Greenhouse has no name filter so the tool scans up to max_pages × per_page candidates, and explains next_cursor resumption. This is exactly the cost/pagination behavior an agent needs before calling.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the purpose in the first sentence, then layers routing, matching semantics, and pagination in short, scannable sentences. No sentence is filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Covers identity, matching behavior, the downstream call, and pagination, and an output schema exists so return values need no explanation. Nothing required to invoke it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds meaning beyond it by framing cursor/per_page/max_pages as a scan-and-paginate contract ('scans up to max_pages × per_page... pass next_cursor to keep scanning') rather than as isolated fields.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ('Find candidates by name') and immediately differentiates itself from list_candidates and search_candidates_by_email by anchoring on the name-based lookup that users actually perform. An agent can select this over its many siblings without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly says to use this first whenever a user mentions a candidate, then chains to list_applications(candidate_id=...) because candidate records don't include applications. It gives the when, the ordering, and the next step — nothing is left to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

search_pipeline_candidatesA

Search pipelines by structured fields — title, company, education, tags. Read-only.

Users say "find VP-level candidates in our pipelines" or "who do we have from Google?" Pass job_ids (list_jobs → get IDs for similar roles). Best when structured data (employment and education history) is populated. If few results, switch to scan_pipeline_resumes for resume-text search. Combine with batch_read_resumes to verify skill matches.

ParametersJSON Schema
NameRequiredDescriptionDefault
tagsNoTag names to filter by
job_idsYesJob IDs to search — list_jobs → get IDs for similar roles
statusesNoFilter by status: 'active', 'rejected', 'hired'
max_resultsNoMaximum candidates to return
title_keywordsNoJob title keywords — e.g. ['VP', 'Director']
company_keywordsNoCompany name keywords — e.g. ['Google', 'Stripe']
education_keywordsNoEducation keywords — e.g. ['Stanford', 'MIT']
min_experience_yearsNoMinimum years of work experience

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description must carry the behavioral burden; it discloses the key safety trait ('Read-only') and an effectiveness precondition ('Best when structured data is populated'). It does not cover permissions, rate limits, or pagination, but the presence of an output schema removes the need to describe returns.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads purpose before user phrasings and routing guidance, and each sentence contributes (purpose, examples, sourcing, fallback, combination). The user-quote examples are slightly verbose but genuinely aid matching.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For an 8-parameter read tool with full schema coverage and an output schema, the description covers purpose, routing, fallback, and combination guidance. Nothing needed to invoke it correctly is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the schema already documents all 8 parameters including job_ids, statuses, and keyword filters. The description adds only the field list and the job_ids sourcing hint, which the schema also states — the baseline 3 is appropriate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (search) and resource (pipelines/candidates) with the searchable scope (title, company, education, tags). It explicitly distinguishes itself from scan_pipeline_resumes (resume-text search) and batch_read_resumes, so an agent can route without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives explicit when-to-use (structured fields, when employment/education history is populated), a when-to-switch rule ('If few results, switch to scan_pipeline_resumes'), and a combination hint (batch_read_resumes). The user-phrasing examples further anchor the selection conditions.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

source_effectivenessA

Which candidate sources produce the best results. Read-only.

Users say "which sources are working?" or "where should we spend recruiting budget?" Pass job_id (list_jobs → match by name) for one role, or omit for org-wide analysis. Returns volume, active, rejected, hired and hire rate per source, with each source's strategy (e.g. Referral).

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idNoFilter to one job — list_jobs → match by name
created_afterNoISO 8601 date — only applications created after this

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.5/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the behavioral burden and does disclose the key trait explicitly: 'Read-only.' It also clarifies the scope switch (single role vs org-wide) and the returned metric shape. It omits permission requirements, rate limits, and result-size/pagination behavior.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the purpose, then read-only status, then usage triggers, then parameter guidance, then return shape — no filler sentences. The quoted user phrasings earn their place by aiding tool selection.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return-value documentation is not strictly required, yet the description still summarizes the key fields. Combined with the read-only declaration, the job_id sourcing hint, and the scope toggle, an agent has everything needed to call this correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is already 100%, so the baseline is 3, but the description adds real meaning beyond the schema: it tells the agent to obtain job_id via list_jobs by name, and that omitting it switches to org-wide analysis — a semantic the schema's 'Filter to one job' note does not convey. created_after is left entirely to the schema.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description states a specific analytical purpose — ranking candidate sources by results — and enumerates the exact metrics returned (volume, active, rejected, hired, hire rate, source strategy). That metric list clearly separates it from the sibling list_sources, which merely enumerates sources rather than measuring their performance.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It gives concrete routing context, quoting the user questions it answers ('which sources are working?', 'where should we spend recruiting budget?') and explaining the job_id-present vs job_id-omitted modes. It never names an alternative tool to use instead (e.g. pipeline_metrics, list_sources), so the when-not guidance is absent.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

stale_applicationsA

Applications with no activity for N days, sorted by stalest. Read-only.

Users say "who's been sitting untouched?" Use the results with bulk_reject for pipeline cleanup. Pass job_id (list_jobs → match by name) to filter to one job. Each row includes the current stage and job name.

ParametersJSON Schema
NameRequiredDescriptionDefault
daysNoMinimum days without activity
limitNoMax applications to return
job_idNoFilter to one job — list_jobs → match by name

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.6/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations present, the description carries the full behavioral burden, and it does declare "Read-only" plus the sort order — genuinely useful for a mutation-free query tool. It omits pagination behavior, what counts as "activity," permission requirements, and default values (14 days / 50 rows), leaving real gaps.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the core definition and the read-only note in the first two short sentences, then adds workflow context. Every sentence contributes, though the "Each row includes the current stage and job name" line is largely redundant with the existing output schema.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a parameterized read-only list tool with 100% schema coverage and an output schema, the description supplies the missing behavioral layer (read-only, sort order, workflow chaining). It falls short only on pagination and the definition of inactivity, which an agent might need before tuning days.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so all three parameters (days, limit, job_id) are already documented in the schema, including the list_jobs lookup hint for job_id. The description adds only the staleness-sorting concept and reuses the same job_id guidance, so the baseline 3 is appropriate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific resource (applications), a precise filter (no activity for N days), and an ordering guarantee (sorted by stalest), which is far beyond a restatement of the name. It does not explicitly name or contrast with the nearest siblings (candidates_needing_action, pipeline_summary, search_pipeline_candidates), so it stops short of full sibling differentiation.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives a concrete workflow cue ("Use the results with bulk_reject for pipeline cleanup") and a chaining instruction (list_jobs → match by name → pass job_id). It does not state when NOT to use it or name a competing tool, but the context for use is unambiguous.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

submit_applicationA

Submit an application through the public job board. Write operation.

For internal application creation (as a recruiter/admin), use create_application instead. This endpoint mirrors what external candidates do when they apply through the public board.

ParametersJSON Schema
NameRequiredDescriptionDefault
emailYesApplicant's email address
phoneNoApplicant's phone number
job_idYesBoard job ID — from list_board_jobs
resumeNoResume content or URL
last_nameYesApplicant's last name
first_nameYesApplicant's first name
cover_letterNoCover letter text
mapped_url_tokenNoTracking link token for source attribution

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden. It does disclose that this is a write operation and frames the semantics as an external-candidate submission, which is useful. However, it says nothing about side effects, duplicate-application handling, notification triggers, or auth requirements expected of a public endpoint.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, front-loaded with the core action and write nature before the routing advice. The closing sentence partly restates the 'public job board' framing of sentence one, a minor redundancy but not wasteful.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness3/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need no explanation, and all 8 parameters are documented in the schema. What remains missing is behavioral context for a write tool with zero annotations: side effects, whether it creates a candidate record, and duplicate handling are all unstated.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and each field (email, phone, job_id, resume, cover_letter, mapped_url_token) is documented in the schema, including that job_id comes from list_board_jobs. The description adds no parameter-level detail, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (submit) and resource (application) plus the channel (public job board), and explicitly contrasts itself with the sibling create_application. An agent can distinguish it from the internal-creation tool without opening either schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Names the alternative tool and the condition that selects it: internal recruiter/admin creation goes to create_application, while this mirrors the external candidate path. The when-not is implied by that same contrast, leaving little to inference.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

time_to_hireA

Time-to-hire metrics for hired candidates. Read-only.

Users say "how long does it take to hire?" or "what's our average days-to-offer?" Pass job_id (list_jobs → match by name) for one role, or omit for org-wide metrics. Returns average, median, min, max days from application to hire. The hire date is the accepted offer's resolved date when available, otherwise the application's last activity.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idNoFilter to one job — list_jobs → match by name
created_afterNoISO 8601 date — limit analysis window

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are supplied, so the description must carry the behavioral burden, and it does state 'Read-only' plus a non-obvious computation rule: the hire date is the accepted offer's resolved date, falling back to the application's last activity. That fallback semantics is exactly the kind of detail an agent cannot infer. It does not mention auth requirements or how created_after interacts with the hire-date window.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads purpose and read-only status, then usage, then the id lookup, then the return shape. Each sentence adds information, though the job_id guidance partially duplicates the schema's own parameter description.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be enumerated, yet the description still lists average/median/min/max and defines the measurement endpoints. Combined with the read-only note and the hire-date resolution rule, an agent has everything needed to call this correctly with or without job_id.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so both parameters are already documented in the schema, which sets the baseline at 3. The description adds real meaning for job_id (omitting it yields org-wide metrics, and the id comes from list_jobs name matching), but says nothing extra about created_after beyond the schema's ISO 8601 note.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific metric and scope: 'Time-to-hire metrics for hired candidates' — an agent can distinguish it from sibling analytics tools like pipeline_metrics or source_effectiveness immediately. It also names the population (hired candidates) and the unit (days from application to hire).

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives concrete triggers ('how long does it take to hire?', 'average days-to-offer') and explicitly routes the two modes — pass job_id for one role, omit for org-wide — including how to obtain the id (list_jobs → match by name). It stops short of naming which sibling metric tools to prefer over this one when the user actually wants funnel or source analysis.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

unreject_applicationA

Reverse a rejection, returning the candidate to active status. Write operation.

Users say "undo the rejection for Sarah" or "bring Sarah back." To get the application_id: search_candidates_by_name → get_candidate → find the rejected application in their applications array.

ParametersJSON Schema
NameRequiredDescriptionDefault
application_idYesGreenhouse application ID of a rejected application

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description must disclose behavior; it explicitly labels the operation as a 'Write operation,' which is critical for an agent to know. It also states the resulting state change ('returning the candidate to active status'), but doesn't address permissions, idempotency, or side effects beyond that.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The description is brief and front-loaded, with the purpose in the first sentence. The additional examples and workflow are purposeful and directly support usage, with no wasted words.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a single-parameter write operation with an output schema, the description covers the core purpose, the write nature, and the parameter acquisition workflow. It's sufficiently complete for an agent to understand and invoke, though it doesn't cover edge cases like calling on an active application.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The schema already describes application_id as a Greenhouse application ID, but the description enriches this by showing how to find it via search_candidates_by_name → get_candidate and how to map natural language to the parameter. This adds meaningful guidance beyond the schema.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description opens with 'Reverse a rejection, returning the candidate to active status,' which clearly states the action and its effect. It distinguishes from the sibling reject_application by being the inverse operation, and gives concrete user phrasings.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It provides explicit examples of user intents ('undo the rejection for Sarah' or 'bring Sarah back') that trigger this tool. It also specifies a workflow to obtain the required application_id, setting clear context for when to call this tool, though it doesn't explicitly mention exclusions or alternatives.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

update_applicationA

Update an application's source, referrer, recruiter, coordinator or custom fields. Write operation.

To find the application_id: search_candidates_by_name → get_candidate → match the application to the job. Only updates fields you provide. For source_id: list_sources. For custom field IDs: list_custom_fields. To change a rejection reason, use update_rejection_reason.

ParametersJSON Schema
NameRequiredDescriptionDefault
source_idNoNew source ID — get from list_sources
referrer_idNoReferrer record ID to credit for this application
recruiter_idNoUser ID of the new recruiter — get from list_users
custom_fieldsNoArray of {custom_field_id (or name_key), value} — get field IDs from list_custom_fields
application_idYesGreenhouse application ID
coordinator_idNoUser ID of the new coordinator — get from list_users

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden. It does disclose that this is a write operation and that it is a partial update ('Only updates fields you provide'), which is genuinely useful. However it omits permissions/auth requirements, what happens on invalid IDs, and reversibility, leaving meaningful gaps for a mutation tool.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the verb, resource, and mutable fields, then layers routing hints. Every sentence is functional, though the ID-sourcing hints partly duplicate the schema and could be tightened.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need no explanation. For a six-parameter mutation tool the description covers purpose, mutable fields, ID sourcing, partial-update semantics, and a sibling alternative — nearly everything an agent needs, with only auth/permission behavior left unstated.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the schema already documents every parameter. The description reinforces ID sourcing (list_sources, list_custom_fields) but adds little beyond what the schema descriptions already state, so the baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (Update) and resource (an application), and enumerates the exact mutable field categories: source, referrer, recruiter, coordinator, custom fields. It clearly differentiates from the sibling update_candidate and explicitly routes rejection-reason changes to update_rejection_reason.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides an explicit lookup chain for application_id (search_candidates_by_name → get_candidate → match application to job), names list_sources for source_id and list_custom_fields for custom field IDs, and names the alternative tool for a distinct use case. This is when-to-use and how-to-source guidance in full.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

update_candidateA

Update a candidate's profile. Write operation — only changes fields you provide.

Users say "update Sarah's title to Senior Engineer." To get the candidate_id: search_candidates_by_name → get_candidate. For custom field IDs: list_custom_fields → match by name. To add or remove a single tag without replacing the list, use add_tag_to_candidate / remove_tag_from_candidate.

ParametersJSON Schema
NameRequiredDescriptionDefault
tagsNoReplaces all tags — provide the full list, not just additions
titleNoNew job title
companyNoNew company name
last_nameNoNew last name
first_nameNoNew first name
candidate_idYesGreenhouse candidate ID
custom_fieldsNoArray of {custom_field_id (or name_key), value} — only the fields to change; other custom field values are kept. Get field IDs from list_custom_fields
phone_numbersNoReplaces all phones: [{value: '+1...', type: 'mobile'|'home'|'work'}]
email_addressesNoReplaces all emails: [{value: 'x@y.com', type: 'personal'|'work'}]

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full behavioral burden. It correctly discloses partial-update semantics ('only changes fields you provide'), which is the most important trait, but says nothing about permissions/auth, failure modes, or the fact that tags/phones/emails are wholesale replacements — that last point lives only in the schema descriptions, not the prose.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the operation and its key constraint, then a compact workflow block. The quoted user phrasing ('update Sarah's title to Senior Engineer') is mildly decorative but does aid intent matching, so the text is efficient without being minimal.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation, and the description covers the required lookup chain for candidate_id and custom field IDs. For a 9-parameter mutation it could still note auth/permission requirements, leaving a minor gap.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the schema already documents every parameter, including the replace-all semantics for tags, phones, and emails. The description adds only the routing hint that custom_field IDs come from list_custom_fields, which is a small increment over the baseline for a fully documented schema.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource (update a candidate's profile) and immediately scopes the behavior: 'only changes fields you provide.' It also distinguishes this tool from the single-tag siblings by naming add_tag_to_candidate / remove_tag_from_candidate as the alternative for tag edits.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives an explicit invocation workflow: to obtain candidate_id use search_candidates_by_name → get_candidate, and to obtain custom field IDs use list_custom_fields and match by name. It also names when to use the tag siblings instead, so both the setup path and the alternative-tool decision are spelled out.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

update_current_offerA

Update the current offer on an application. Write operation.

Looks up the application's latest offer version and patches it (start date → starts_on). To find application_id: search_candidates_by_name → list_applications(candidate_id=...) → match the application to the job. For custom field IDs: list_custom_fields.

ParametersJSON Schema
NameRequiredDescriptionDefault
sent_onNoDate the offer was sent, as 'YYYY-MM-DD'
starts_atNoNew start date as 'YYYY-MM-DD'
custom_fieldsNoArray of {id, value} (or {custom_field_id, value}) — get field IDs from list_custom_fields
application_idYesGreenhouse application ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.9/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries full behavioral burden. It declares 'Write operation' and the patch-not-create semantics (operates on the latest offer version), which is genuinely useful. However it omits permission/scope requirements, what happens to fields left null or omitted, and whether changes are reversible or auditable.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Purpose and write designation are front-loaded, followed by prerequisite navigation steps. Mostly economical, though the 'For custom field IDs: list_custom_fields' line repeats the schema's own note and could be dropped.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be described, and the description covers the mutation target, patch semantics, and ID-discovery workflow. It falls short only on error/permission behavior, which for an unannotated write tool leaves a modest gap.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the baseline is 3. The description adds a field-name mapping ('start date → starts_on') and restates the custom-field ID source, but this largely duplicates the schema descriptions rather than adding new syntactic or validation detail.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ('Update the current offer on an application') and differentiates from read siblings like get_current_offer/get_offer. It goes further by explaining the mechanism: it looks up the application's latest offer version and patches it, so an agent knows it does not create or version offers.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives an explicit prerequisite workflow for obtaining application_id (search_candidates_by_name → list_applications → match to job) and points to list_custom_fields for field IDs. It does not state when to prefer this over get_current_offer or other offer-related writes, so it stops short of full when/when-not guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

update_custom_fieldA

Update a custom field's name, privacy or description. Write operation — admin only.

To find custom_field_id: list_custom_fields → match by name. Renaming does not change the field's name_key.

ParametersJSON Schema
NameRequiredDescriptionDefault
nameNoNew display name
privateNoNew privacy setting
descriptionNoNew helper text
custom_field_idYesCustom field ID — get from list_custom_fields

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations present the description must carry the full burden, and it does disclose the two facts that matter most for a mutation: it is a write operation and it requires admin rights. It also notes the non-obvious invariant that renaming leaves name_key unchanged. It omits partial-update/merge semantics for the nullable params, which keeps it from a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three short sentences, front-loaded with the action and the field list, then the hard constraints and the ID-lookup hint. Nothing is repeated from the schema and no sentence is filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation, and the description covers the mutation type, auth requirement and ID provenance needed to invoke it correctly. The only gap is unstated behavior for omitted/null arguments versus explicit clears, minor for an update tool.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so baseline is 3; the description adds value beyond the schema by naming the three mutable attributes in line with the params and by documenting how to source the required custom_field_id. It still says nothing about what a null/omitted value does, so it does not fully compensate the remaining semantic gap.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

Specific verb+resource ("Update a custom field") followed immediately by the exact fields it can modify ("name, privacy or description"), which cleanly separates it from create_custom_field, delete_custom_field and update_custom_field_options. An agent can identify the right tool without opening a schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives the prerequisite workflow for obtaining the required parameter ("list_custom_fields → match by name") and the permission gate ("admin only"). It does not explicitly say when NOT to use it (e.g. use update_custom_field_options to touch the selectable values), so it stays just short of a full routing rule.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

update_custom_field_optionsA

Update dropdown options on a custom field. Write operation — admin only.

To find custom_field_id: list_custom_fields → match by name. For option IDs: list_custom_field_options → match by name. Up to 50 options are updated immediately; larger lists use an asynchronous bulk request.

ParametersJSON Schema
NameRequiredDescriptionDefault
optionsYesArray of {id, name?, sort_order?, external_id?} — get IDs from list_custom_field_options
custom_field_idYesCustom field ID

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full behavioral burden and does well: it declares this is a write operation, that it is admin-only, and that up to 50 options apply synchronously while larger sets go through an asynchronous bulk request. It omits whether the update merges or replaces existing options, which is the main remaining behavioral gap.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Four short sentences, front-loaded with purpose and the write/admin warning, then ID-resolution steps, then the batching rule. No filler and nothing that fails to earn its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists so return values need no explanation, and the admin-only plus sync/async details cover the operation's risk profile. The one thing an agent might still need, whether existing options are replaced or merged, is not addressed.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, and the description adds real value on top by explaining the lookup path for option IDs and the 50-item threshold that governs the options array. The custom_field_id parameter gets no extra semantics beyond what the schema already says.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Update dropdown options on a custom field') and is cleanly separable from the surrounding custom-field siblings (update_custom_field, create_custom_field_options, delete_custom_field_options). An agent can pick this tool without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

It explicitly routes the agent to list_custom_fields for the field ID and list_custom_field_options for option IDs, matching by name, which is exactly the precondition an agent needs. It does not state when to prefer create_custom_field_options or delete_custom_field_options instead, so it falls short of full when/when-not guidance.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

update_departmentA

Update a department's name, parent or external ID. Write operation — admin only.

To find department_id: list_departments → match by name. Greenhouse requires the name on every update, so the current name is kept when name is omitted.

ParametersJSON Schema
NameRequiredDescriptionDefault
nameNoNew department name
parent_idNoNew parent department ID — get from list_departments
external_idNoNew HRIS/external identifier
department_idYesDepartment ID to update

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full load and delivers the two facts that matter: this is a write operation requiring admin rights, and it is a partial update — Greenhouse requires the name, so the existing name is preserved when name is omitted. Reversibility and error behavior are not covered, keeping it short of a 5.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short paragraphs, front-loaded with the action and the fields, followed by the prerequisite and the ID-lookup path. Every sentence carries operational information; nothing is redundant.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation, and the description supplies auth requirements, ID sourcing, and partial-update behavior. What remains unstated — failure modes and whether parent/external_id can be cleared — is minor for a four-parameter update tool.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% so the baseline is 3, and the description earns more by clarifying the otherwise ambiguous optional-name semantics (current name retained when omitted) and by pointing to list_departments as the source of a valid department_id. It adds genuine meaning beyond the schema's per-field labels.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (Update) plus the resource (department) and enumerates the mutable fields (name, parent, external ID). Against siblings create_department / get_department / list_departments, the mutation intent is unmistakable.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives an explicit prerequisite ('admin only') and routes the agent to list_departments to obtain the required department_id, including the matching strategy (match by name). It does not state when to prefer create_department over an update, but the operational context is otherwise clear.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

update_interviewA

Update a scheduled interview's time, interviewers, or location. Write operation.

To find interview_id: list_interviews_for_application on the candidate's app. For new interviewer_ids: list_users → match by name. When replacing interviewers, existing panel members keep their RSVP; new ones start as needs_action.

ParametersJSON Schema
NameRequiredDescriptionDefault
endNoNew end time as ISO 8601
startNoNew start time as ISO 8601
locationNoNew location or meeting link
interview_idYesScheduled interview ID to update
interviewer_idsNoReplaces all interviewers — provide the full list
video_conferencing_urlNoNew video call join URL

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description must carry the behavioral load, and it does flag 'Write operation' plus a genuinely non-obvious side effect: replacing interviewers preserves existing members' RSVPs while new ones start as needs_action. It omits other write-relevant traits such as auth requirements, whether unspecified fields are left unchanged, and whether time changes re-notify participants.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the core action and write nature in the first sentence, then adds only actionable lookup and side-effect notes. No filler, though the two-line dependency hints are slightly terse.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be explained. For a 6-param unannotated mutation tool, the description covers the key lookup paths and the interviewer RSVP behavior; only partial-update and permission semantics remain implicit.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the baseline is 3. The description reinforces the destructive replacement semantics of interviewer_ids and the ISO 8601 time fields, but adds little beyond what the schema already documents.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (Update) and resource (scheduled interview) and enumerates the mutable fields (time, interviewers, location). The agent can immediately distinguish it from create_interview/delete_interview/get_interview without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides concrete prerequisite workflows: use list_interviews_for_application to obtain interview_id, and list_users to resolve interviewer_ids. It gives clear context for correct invocation but offers no explicit when-not guidance or routing between sibling update tools.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

update_jobA

Update a job's name, department, offices, notes, or custom fields. Write operation.

To find job_id: list_jobs → match by name. Only updates fields you provide. For department_id: list_departments. For office_ids: list_offices. To modify the public listing, use update_job_post instead. A job's open/closed status can't be set directly in Harvest v3: close its openings with update_job_opening(status='closed') (list_job_openings to find them).

ParametersJSON Schema
NameRequiredDescriptionDefault
nameNoNew internal job name
notesNoInternal notes about the job (HTML supported)
job_idYesGreenhouse job ID
statusNoNot settable in Harvest v3 — a job's status follows its openings. Use update_job_opening to close or reopen openings instead.
office_idsNoReplaces all office associations — get IDs from list_offices
custom_fieldsNoArray of {id, value} — replaces the job's custom field values
department_idNoNew department ID — get from list_departments
requisition_idNoExternal requisition/req ID
how_to_sell_this_jobNoInternal selling points recruiters use for the role
team_and_responsibilitiesNoInternal description of the team and responsibilities

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.6/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does well: it flags 'Write operation', discloses partial-update semantics ('Only updates fields you provide'), and surfaces a non-obvious guardrail (status not directly settable in Harvest v3). It stops short of mentioning auth/permission requirements or the irreversibility of replacements, which the schema hints at but the prose does not reinforce.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with purpose and write semantics, then structured guidance. Most sentences earn their place, though enumerating the updatable fields overlaps with what the schema already lists for a 10-parameter tool.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a 10-parameter mutation with no annotations and an existing output schema, the description fills the meaningful gaps: write semantics, partial-update behavior, ID sourcing, sibling routing, and a status constraint. Nothing an agent needs to invoke it correctly appears missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the baseline is 3, but the description adds meaning by naming the lookup tool for each ID parameter and calling out the status caveat. This goes beyond restating the schema by connecting parameters to their source tools.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (update) and resource (job), enumerates the mutable fields, and explicitly distinguishes itself from siblings update_job_post (public listing) and update_job_opening (status via openings). An agent can tell what this does and what it does not do without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides explicit lookup chains (list_jobs → match by name for job_id; list_departments for department_id; list_offices for office_ids), names an alternative for the public listing (update_job_post), and explains the status workaround (update_job_opening(status='closed')). When-to-use, when-not-to-use, and alternatives are all covered.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

update_job_openingA

Update a job opening's status, target start date, or custom fields. Write operation.

To find job_id: list_jobs → match by name. To find opening_id: list_job_openings on the job. For close_reason_id: list_close_reasons → match by name. Closing a job's last open opening closes the job.

ParametersJSON Schema
NameRequiredDescriptionDefault
job_idYesGreenhouse job ID
statusNoNew status: 'open' or 'closed'
opening_idYesOpening ID within the job
custom_fieldsNoArray of {id, value} (or {custom_field_id, value}) — get field IDs from list_custom_fields
close_reason_idNoReason for closing — get from list_close_reasons
target_start_onNoTarget start date as 'YYYY-MM-DD'
external_opening_idNoNew custom external opening identifier

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description must carry the behavioral load, and it does disclose that this is a 'Write operation' plus an important side effect ('Closing a job's last open opening closes the job'). It stops short of covering permissions, reversibility, or whether unspecified fields are preserved.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the purpose in the first sentence, then a compact resolution block. Every sentence earns its place, though the cascade note is awkwardly wrapped mid-sentence and could be grouped with the write-operation warning.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation, and the description covers the key relational inputs and one major side effect for a 7-parameter mutation. It is nearly complete; only permissions/reversibility context would round it out.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is already 100%, so the baseline is 3; the description exceeds it by supplying the lookup chains that give the ID parameters meaning (job_id via list_jobs, opening_id via list_job_openings, close_reason_id via list_close_reasons). It does not add value for target_start_on or external_opening_id beyond the schema.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

Names a specific verb and resource (update a job opening) and enumerates the mutable fields (status, target start date, custom fields). It is clearly distinguishable from create/delete/list siblings, though it never explicitly contrasts itself with the closest alternative, bulk_update_job_openings.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives concrete how-to-use routing: list_jobs to resolve job_id, list_job_openings for opening_id, and list_close_reasons for close_reason_id. It also warns about the cascade when closing an opening. What is missing is guidance on when to prefer this over bulk_update_job_openings or update_job.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

update_job_postA

Update a job post's title, location, or content. Write operation — admin only.

To find job_post_id: list_job_posts_for_job (job_id from list_jobs → match by name). In v3 locations are separate records: passing location adds it as a free-text location and then removes the post's previous locations. For multiple or office-based locations, use add_job_post_location / remove_job_post_location.

ParametersJSON Schema
NameRequiredDescriptionDefault
titleNoNew post title
contentNoNew post body content (HTML supported)
locationNoNew free-text location. Replaces the post's existing locations; use add_job_post_location to add one instead
job_post_idYesJob post ID to update

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.3/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full disclosure burden and does well: it declares a write operation, an admin-only permission requirement, and a non-obvious destructive side effect (passing location replaces and removes the post's existing locations). It does not address what happens when no editable field is supplied or whether updates are reversible, so it stops short of full coverage.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads purpose and the admin constraint in the first sentence, then layers in ID discovery and the location caveat. Every sentence carries information, though the multi-paragraph layout is slightly heavier than needed for four parameters.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need no explanation. Combined with full schema coverage, admin/auth disclosure, ID provenance, and the location-replacement caveat, an agent has enough to call this correctly; only the empty-update and reversibility cases are unaddressed.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the baseline is 3. The description's location semantics and ID-discovery guidance largely restate or reinforce what the schema already says ('Replaces the post's existing locations'), adding routing value rather than new per-parameter meaning.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (Update) plus resource (job post) and enumerates the mutable fields (title, location, content), immediately distinguishing it from neighbors like update_job_post_status and add_job_post_location. The 'Write operation — admin only' clause further narrows scope.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines5/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly routes the agent: how to obtain job_post_id (list_job_posts_for_job → job_id from list_jobs → match by name), and when to prefer alternatives (add_job_post_location / remove_job_post_location for multiple or office-based locations). This is the when/when-not/alternatives pattern in full.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

update_job_post_statusA

Publish or unpublish a job post. Write operation.

Controls visibility on job boards ('offline' sets the post back to draft). To find job_post_id: list_job_posts_for_job (job_id from list_jobs → match by name).

ParametersJSON Schema
NameRequiredDescriptionDefault
statusYesNew status: 'live' (published) or 'offline' (unpublished draft)
job_post_idYesJob post ID to update

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does disclose that this is a 'Write operation' and that setting 'offline' reverts the post to draft — a meaningful state side effect. It omits permission/auth requirements and reversibility details, so it is strong but not exhaustive.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Three tight segments: action first, then behavioral note, then ID-discovery hint. No filler and the operation is front-loaded.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a 2-parameter mutation tool with an output schema and full schema coverage, the description covers purpose, mutation nature, status semantics, and how to obtain the ID. Nothing essential is missing.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the baseline is 3, but the description adds value beyond the schema by explaining the real-world effect of the 'offline' value and how to source the job_post_id. This exceeds what the field descriptions alone convey.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Publish or unpublish a job post') and clarifies that it governs visibility/publish state, which distinguishes it from generic editing. It does not explicitly differentiate itself from the sibling update_job_post, so a 4 rather than a 5.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides a concrete discovery workflow for the required job_post_id ('list_job_posts_for_job (job_id from list_jobs → match by name)') and notes the 'offline' → draft behavior. It stops short of stating when to use this tool instead of update_job_post or other siblings, so it is clear context without explicit exclusions.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

update_officeA

Update an office's name, location, parent or contact. Write operation — admin only.

To find office_id: list_offices → match by name. Greenhouse requires the name on every update, so the current name is kept when name is omitted.

ParametersJSON Schema
NameRequiredDescriptionDefault
nameNoNew office name
locationNoNew location string
office_idYesOffice ID to update
parent_idNoNew parent office ID — get from list_offices
primary_contact_user_idNoUser ID of the new primary in-house contact

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.1/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations, the description carries the full burden and does disclose meaningful traits: it is a write operation, requires admin rights, and explains the non-obvious name-retention behavior ('current name is kept when name is omitted'). It does not address reversibility or what happens to unspecified fields, but it adds substantial context beyond structured data.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two sentences, front-loaded with the operation and constraints, followed by the practical lookup and name-retention notes. No wasted text; every sentence earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be explained. For an unannotated mutation tool, the description covers purpose, permissions, parameter sourcing, and a behavioral quirk; only minor gaps (reversibility, handling of omitted fields) remain.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the schema already documents all five parameters (baseline 3). The description adds real value beyond the schema: how to source office_id and the name-required workaround, both of which affect how parameters must be supplied.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource plus the updatable fields ('Update an office's name, location, parent or contact'). An agent can identify the operation immediately, though it does not explicitly differentiate itself from siblings like create_office or update_department.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides concrete routing guidance for the required parameter ('To find office_id: list_offices → match by name') and states the prerequisite ('admin only'). No explicit when-not guidance or comparison to alternative tools, but the context needed to invoke it is clear.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

update_rejection_reasonA

Change the rejection reason on an already-rejected application. Write operation.

To find the application_id: search_candidates_by_name → get_candidate → find the rejected application. For the new reason: list_rejection_reasons → match by name. Looks up the application's rejection details record and updates its reason.

ParametersJSON Schema
NameRequiredDescriptionDefault
application_idYesGreenhouse application ID (must be already rejected)
rejection_reason_idYesNew rejection reason ID — get from list_rejection_reasons

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.9/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden. It helpfully declares 'Write operation' and explains the mechanism (looks up the application's rejection details record and updates its reason), but it omits permission requirements, reversibility, and side effects on other rejection metadata. Adequate but incomplete for a mutation tool with zero annotation coverage.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the operation and its precondition in the first sentence, then details the lookup chains. Multi-line but each segment carries actionable information with little waste; the final sentence partly restates the opening.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be described. The description covers the precondition, the write nature, and how to resolve both IDs, leaving only permission and reversibility details uncovered for a mutation tool.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100% and both parameter descriptions already state the prerequisite ('must be already rejected') and the source ('get from list_rejection_reasons'). The description's lookup chain largely restates what the schema provides, so baseline 3 is appropriate.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Change the rejection reason') and pins the precondition ('on an already-rejected application'), which cleanly distinguishes it from reject_application and unreject_application in the sibling list. An agent can identify the correct tool without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Provides concrete procedural guidance for both parameters: search_candidates_by_name → get_candidate to locate the rejected application, and list_rejection_reasons to resolve the new reason ID. It clarifies the 'already-rejected' precondition but does not explicitly contrast with reject_application/unreject_application, so the alternatives clause is implicit.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

update_userA

Update a user's name, title, primary email, offices or departments. Write operation.

To find user_id: list_users → match by name or email. To make a new address primary, first add it with add_email_to_user and have it verified.

ParametersJSON Schema
NameRequiredDescriptionDefault
user_idYesGreenhouse user ID
job_titleNoNew job title
last_nameNoNew last name
first_nameNoNew first name
office_idsNoReplace the user's offices — get from list_offices
primary_emailNoNew primary email — must already be a verified email on the user
department_idsNoReplace the user's departments — get from list_departments

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full behavioral burden. It does label itself a 'Write operation' and discloses the verified-email prerequisite for primary_email, which is genuine context. However, it says nothing about required permission level (e.g., admin), reversibility of the replace-style office/department updates, or error behavior for a destructive-feeling mutation.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the action, affected fields, and write nature in the first sentence, then adds two tightly scoped workflow notes. No filler sentences; every line earns its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be explained. For a 7-parameter mutation with no annotations, the definition covers field scope, mutation nature, ID resolution, and the primary-email prerequisite. The main remaining gap is permission/authorization requirements.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the schema already documents each parameter, including the replace semantics and that primary_email must be verified. The description adds the list_users lookup path and the add_email_to_user prerequisite, but largely restates what the schema provides, so baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb (Update) plus the resource (user) and enumerates the mutable fields (name, title, primary email, offices, departments). This clearly distinguishes it from siblings like update_candidate, update_department, and update_office without needing to open any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives actionable prerequisites: route the agent to list_users to resolve user_id, and instructs that a new primary address must first be added via add_email_to_user and verified. It names concrete alternatives/prerequisites, though it stops short of any explicit 'when not to use this' exclusions.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

webhook_create_ruleA

Create a webhook routing rule. Write operation.

Use webhook_list_events to see available event types. Set event_type to '*' to match all events, or a specific type like 'candidate_stage_change'. Use webhook_test_rule to dry-run after creating.

ParametersJSON Schema
NameRequiredDescriptionDefault
action_urlNoURL to forward events to (required if action_type='forward')
event_typeYesGreenhouse event type or '*' for all — see webhook_list_events
action_typeYes'forward' (requires action_url) or 'log'
filter_fieldNoJSON field to filter on (e.g., 'application.job.id')
filter_valueNoRequired value for the filter field

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.9/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are supplied, so the description carries the full disclosure burden. It does the most important thing by declaring 'Write operation', which tells the agent this mutates persistent state, and it notes the dry-run alternative. However, it says nothing about idempotency, whether the created rule is immediately active, or what authorization is needed for a webhook-forwarding rule.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Four short sentences, front-loaded with the operation and its write nature, then the workflow hints. Slightly fragmented but every sentence contributes information; no filler.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With an output schema present, return values need no explanation, and the description plus full schema coverage covers the input contract and the recommended workflow. The only gap is behavioral depth for a mutation tool lacking annotations.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so all five parameters are already documented, setting the baseline at 3. The description adds useful semantic detail for event_type ('*' matches all, example 'candidate_stage_change') but does not extend meaning for action_url, filter_field, or filter_value beyond what the schema states.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Create a webhook routing rule') that cleanly separates it from the sibling mutation tools webhook_update_rule and webhook_delete_rule. The second sentence names the operation class. An agent can identify this tool's function without opening the schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly routes the agent to webhook_list_events for enumerating event types and to webhook_test_rule for a dry-run after creation, establishing a clear workflow context. It falls short of a 5 because it doesn't state when NOT to use this tool (e.g. when a rule already exists) or any prerequisites such as required permissions.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

webhook_delete_ruleB

Delete a webhook routing rule. Write operation.

To find rule_id: webhook_list_rules.

ParametersJSON Schema
NameRequiredDescriptionDefault
rule_idYesRule ID — from webhook_list_rules

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

B3.4/5.0
Behavior2/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are supplied, so the description carries the full behavioral burden. It labels the operation 'Write operation,' which is the only trait disclosed; it says nothing about permanence/irreversibility, required permissions, whether deleting a rule affects in-flight webhook deliveries, or failure behavior. For a destructive delete with zero annotation coverage this is a notable gap.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short, front-loaded sentences with no filler; the core action leads. 'Write operation' and the rule_id pointer overlap slightly with the schema and annotation-adjacent semantics, so it is not perfectly waste-free.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness3/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

A single-parameter delete with an output schema and no annotations. The description covers purpose, mutation class, and how to source the ID, and the output schema handles return values, but it omits the risk information an agent needs before invoking an irreversible delete. Adequate but thin for a destructive operation.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%: the rule_id parameter is already documented as 'Rule ID — from webhook_list_rules.' The description adds no syntax, format, or range detail beyond restating that same provenance, so the 3 baseline applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

Names a specific verb and resource ('Delete a webhook routing rule'), which is immediately distinguishable from the sibling verbs webhook_create_rule, webhook_update_rule, and webhook_list_rules. It stops short of explicitly contrasting itself with those siblings, but the verb+resource pairing is unambiguous.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description explicitly routes the agent to webhook_list_rules as the way to obtain the required rule_id, which is real selection guidance for the prerequisite step. It gives no guidance on when not to delete or on alternative tools for removal scenarios, so it falls short of the top band.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

webhook_list_eventsA

List all Greenhouse webhook event types with descriptions. Read-only.

Reference for webhook_create_rule — shows available event types like 'candidate_stage_change', 'hire_candidate', 'new_candidate_application', etc.

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

Output Schema

ParametersJSON Schema
NameRequiredDescription

No output parameters

TDQS

A4.4/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the burden; it does declare 'Read-only' and characterizes the output as a static catalogue of event types with descriptions. It stops short of stating auth requirements or whether the list is cached, but for a zero-parameter read-only lookup there is little else to disclose.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the purpose, then the read-only note, then the sibling relationship. The concrete event-type examples earn their place by making the return content tangible, though the trailing 'etc.' list is slightly more than strictly needed.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness5/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

With zero parameters, an output schema covering return values, and the sibling relationship spelled out, an agent has everything needed to select and call this tool correctly.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The tool takes no parameters, so the baseline is 4 and there is nothing for the description to compensate for.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource (list webhook event types) with the added scope that each entry includes a description. Clearly distinguishable from sibling webhook tools like webhook_list_rules and webhook_list_recent, which list different entities.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Explicitly frames itself as a 'Reference for webhook_create_rule', which tells the agent the condition that selects this tool (discovering valid event types before creating a rule). No explicit when-not guidance, but the context is unambiguous.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

webhook_list_recentB

List recent webhook events received by the receiver. Read-only.

Shows the latest events captured by the webhook receiver, useful for debugging and verifying webhook delivery.

ParametersJSON Schema
NameRequiredDescriptionDefault
limitNoMaximum events to return

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

B3.3/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden; it does state 'Read-only', which is a genuine safety disclosure. But it says nothing about ordering guarantees, retention window, pagination, or auth requirements, and the meaning of 'recent' is left undefined.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness3/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loaded with the core action and the read-only flag, which is good, but the second sentence ('Shows the latest events captured by the webhook receiver') largely restates the first, and the third adds only a generic debugging rationale. It is not bloated, but it does not fully earn its length.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness3/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return-value explanation is unnecessary, and the tool is low complexity with one optional parameter. Still, the description omits any differentiation from the sibling webhook_list_events and gives no 'recent' definition, which an agent would need to call it confidently.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and the single 'limit' parameter is documented in the schema with a default of 50, so the baseline is 3. The description adds no guidance on the limit, such as a maximum or the effect of omitting it.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

Names a specific verb (List) and resource (recent webhook events received by the receiver), and the second sentence clarifies it returns the latest captured events. However, it never distinguishes itself from the sibling 'webhook_list_events', which sounds nearly identical, so an agent cannot tell which to pick without opening both schemas.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

'useful for debugging and verifying webhook delivery' implies a use case but gives no explicit when-to-use versus when-not, and no mention of the near-identical sibling 'webhook_list_events' or 'webhook_test_rule'. Usage is suggested rather than specified.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

webhook_list_rulesA

List all webhook routing rules. Read-only.

Returns all configured rules with their event types, actions, and status.

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.5/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full disclosure burden. It does state 'Read-only' and indicates the returned content (event types, actions, status), which is useful, but it says nothing about permissions, scoping, or ordering/limits on the returned rules.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences with the read-only qualifier placed immediately after the action statement. No filler, no repetition of the tool name, and the key trait is front-loaded.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a zero-parameter, read-only listing tool with an output schema that documents the return shape, the description covers what an agent needs. The only shortfall is the absent guidance on how this differs from the other webhook listing tools.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The input schema is an empty object with zero parameters, so there is nothing for the description to disambiguate. Baseline of 4 applies for a parameterless tool.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('List all webhook routing rules'), which is enough to separate it from the create/update/delete rule siblings. However, it never explicitly contrasts itself with webhook_list_events or webhook_list_recent, so the agent must infer the distinction from the noun 'rules' alone.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines2/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

There is no when-to-use guidance, no exclusions, and no named alternative among the four sibling webhook read/query tools (list_events, list_recent, test_rule, setup_guide). The description simply declares what the tool is, leaving routing entirely to the agent.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

webhook_setup_guideA

Generate webhook configuration instructions for Greenhouse. Read-only.

Produces the exact values to enter in Greenhouse UI (Configure > Dev Center

Webhooks) and stores the generated secret key in the local database.

ParametersJSON Schema
NameRequiredDescriptionDefault
eventsNoEvent types to subscribe to — omit for all events
receiver_urlYesPublic URL where the webhook receiver is hosted

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A3.9/5.0
Behavior3/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full behavioral burden. It discloses a key side effect, 'stores the generated secret key in the local database', and asserts 'Read-only' – but it's ambiguous whether 'read-only' refers to the GitHub operation or the fact that it persists a secret. It doesn't mention secret handling, persistence/overwrite behavior, or return shape. This is helpful but not rich.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Short and front-loaded: a one-line purpose followed by a brief detail about what it produces and where. Slightly elliptical phrasing ('Produces the exact values...') but no wasted words.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a 2-param generator tool with an output schema, the description is nearly complete: it names the resource (Greenhouse webhooks), the output (values to enter in the UI), and a key behavioral side effect (secret stored locally). It stops short of naming where the UI path lives in this product vs GitHub, but that's minor.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema coverage is 100%, so the schema documents receiver_url ('Public URL where the webhook receiver is hosted') and events ('Event types to subscribe to — omit for all events'). The description adds no new parameter semantics but the baseline for full coverage is 3; the 'exact values to enter' hint about generated output nudges it to a 4 since it clarifies what the tool produces from the params.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource: 'Generate webhook configuration instructions for Greenhouse.' An agent can readily distinguish this from siblings like webhook_create_rule, webhook_list_rules, or webhook_test_rule, which manage rules rather than produce setup instructions.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description implies a setup context but doesn't explicitly say when to use this versus alternatives such as webhook_create_rule (to create a rule) or webhook_test_rule (to test). The usage case is inferable from the name and purpose, but no explicit when/when-not or alternatives are named.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

webhook_test_ruleA

Dry-run a rule against the most recent matching event. Read-only.

Shows what would happen without actually executing the action. Use after webhook_create_rule or webhook_update_rule to verify behavior. To find rule_id: webhook_list_rules.

ParametersJSON Schema
NameRequiredDescriptionDefault
rule_idYesRule ID — from webhook_list_rules

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

A4.2/5.0
Behavior4/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description must carry the behavioral burden, and it does disclose the key traits: it is a dry-run that 'shows what would happen without actually executing the action' and is 'Read-only.' It omits auth/permission requirements and rate-limit behavior, but covers the safety-critical disclosure well.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Front-loads the purpose and read-only nature, then behavior, then usage and the rule_id pointer. Four short sentences, none redundant, nothing wasted.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness4/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

For a simple 1-param read-only tool with an output schema (so return values need not be explained) and no annotations, the description supplies enough to invoke it correctly. Only minor gaps remain, such as what happens if no matching event exists.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100% and the single rule_id param is already documented as coming 'from webhook_list_rules.' The description repeats that pointer ('To find rule_id: webhook_list_rules') rather than adding new meaning, so baseline 3 applies.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb+resource ('Dry-run a rule') plus the scope ('against the most recent matching event'), and immediately marks it 'Read-only.' An agent can distinguish this from webhook_create/update/delete/list_rules without opening any schema.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines4/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

Gives an explicit when-to-use ('after webhook_create_rule or webhook_update_rule to verify behavior') and routes the agent to webhook_list_rules for the required rule_id. It lacks an explicit when-not/exclusion, but the context is clear.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

webhook_update_ruleB

Update a webhook routing rule. Write operation.

To find rule_id: webhook_list_rules.

ParametersJSON Schema
NameRequiredDescriptionDefault
activeNoEnable or disable the rule
rule_idYesRule ID — from webhook_list_rules
action_urlNoNew forward URL
event_typeNoNew event type or '*'
action_typeNo'forward' or 'log'

Output Schema

ParametersJSON Schema
NameRequiredDescription
resultYes

TDQS

B3.3/5.0
Behavior2/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full behavioral burden, yet it only declares 'Write operation.' It says nothing about whether omitted fields are preserved or cleared (the schema's nullable-with-null-default parameters make this genuinely ambiguous), whether updates are reversible, or what permissions are required.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

Two short sentences, correctly front-loaded with the action and the write-operation warning, and the rule_id hint is secondary. Nothing wasteful.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness3/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

An output schema exists, so return values need not be explained, but for a write tool with zero annotation coverage the partial-update semantics (null default means ignore vs. clear) and permission requirements remain unstated. Adequate but with a clear gap.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so every one of the 5 parameters is already documented in the schema, and the description adds no parameter meaning beyond it. Baseline 3 applies when the schema does the heavy lifting.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

States a specific verb and resource ('Update a webhook routing rule'), which clearly distinguishes it from webhook_create_rule and webhook_delete_rule. It does not, however, differentiate against other update_* siblings or describe the scope of the update.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The only guidance is a prerequisite pointer for obtaining rule_id ('To find rule_id: webhook_list_rules'), which is useful but is dependency resolution rather than when-to-use guidance. No conditions, alternatives (e.g., create vs. update), or exclusions are given.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

Tool Schema Changelog

Recent tool additions, removals, and schema changes observed during successful MCP inspections.

  1. 173 tool updatesv0.5.0
    • Changedadd_attachment8 fields changed
      • addedInput schema / properties / application_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Application to attach to — omit to use the candidate's most recently active application",
        +  "title": "Application Id"
        +}
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
      • addedInput schema / properties / content / description
        Added value: +"Base64-encoded file content — provide this OR url, not both"
      • removedInput schema / properties / content_type
        Removed value: -{
        -  "default": "application/pdf",
        -  "title": "Content Type",
        -  "type": "string"
        -}
      • addedInput schema / properties / filename / description
        Added value: +"File name with extension, e.g. 'resume.pdf'"
      • addedInput schema / properties / type / description
        Added value: +"Type: 'resume', 'cover_letter', 'take_home_test', 'other', ... ('admin_only' = 'other' with admin-only visibility)"
      • addedInput schema / properties / url / description
        Added value: +"Public URL to fetch the file from — provide this OR content, not both"
      • addedInput schema / properties / visibility
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Who can see it: 'public', 'private', or 'admin_only'",
        +  "title": "Visibility"
        +}
    • Changedadd_attachment_to_application7 fields changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
      • addedInput schema / properties / content / description
        Added value: +"Base64-encoded file content — provide this OR url, not both"
      • removedInput schema / properties / content_type
        Removed value: -{
        -  "default": "application/pdf",
        -  "title": "Content Type",
        -  "type": "string"
        -}
      • addedInput schema / properties / filename / description
        Added value: +"File name with extension, e.g. 'resume.pdf'"
      • addedInput schema / properties / type / description
        Added value: +"Type: 'resume', 'cover_letter', 'take_home_test', 'offer_letter', 'other', ... ('admin_only' = 'other' with admin-only visibility)"
      • addedInput schema / properties / url / description
        Added value: +"Public URL to fetch the file from — provide this OR content, not both"
      • addedInput schema / properties / visibility
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Who can see it: 'public', 'private', or 'admin_only'",
        +  "title": "Visibility"
        +}
    • Changedadd_education6 fields changed
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
      • addedInput schema / properties / degree_id / description
        Added value: +"Degree option ID — get from list_degrees"
      • addedInput schema / properties / discipline_id / description
        Added value: +"Discipline option ID — get from list_disciplines"
      • addedInput schema / properties / end_date / description
        Added value: +"End date as 'YYYY-MM-DD'"
      • addedInput schema / properties / school_id / description
        Added value: +"School option ID — get from list_schools"
      • addedInput schema / properties / start_date / description
        Added value: +"Start date as 'YYYY-MM-DD'"
    • Changedadd_email_note_to_candidate7 fields changed
      • addedInput schema / properties / body / description
        Added value: +"Email body content"
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
      • addedInput schema / properties / cc
        Added value: +{
        +  "anyOf": [
        +    {
        +      "items": {
        +        "type": "string"
        +      },
        +      "type": "array"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Cc email addresses",
        +  "title": "Cc"
        +}
      • addedInput schema / properties / from_ / description
        Added value: +"Sender email address"
      • addedInput schema / properties / subject / description
        Added value: +"Email subject line"
      • addedInput schema / properties / to / description
        Added value: +"Recipient email address"
      • addedInput schema / properties / visibility
        Added value: +{
        +  "default": "public",
        +  "description": "'public' (default), 'private', or 'admin_only'",
        +  "title": "Visibility",
        +  "type": "string"
        +}
    • Changedadd_email_to_user3 fields changed
      • addedInput schema / properties / email / description
        Added value: +"Email address to add"
      • addedInput schema / properties / send_verification / description
        Added value: +"Send a verification email to the new address"
      • addedInput schema / properties / user_id / description
        Added value: +"Greenhouse user ID"
    • Changedadd_employment5 fields changed
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
      • addedInput schema / properties / company_name / description
        Added value: +"Employer company name"
      • addedInput schema / properties / end_date / description
        Added value: +"End date as 'YYYY-MM-DD' — omit for current role"
      • addedInput schema / properties / start_date / description
        Added value: +"Start date as 'YYYY-MM-DD'"
      • addedInput schema / properties / title / description
        Added value: +"Job title at this employer"
    • Changedadd_future_job_permission4 fields changed
      • addedInput schema / properties / department_id / description
        Added value: +"Scope to jobs in this department — omit for all departments"
      • addedInput schema / properties / office_id / description
        Added value: +"Scope to jobs in this office — omit for all offices"
      • addedInput schema / properties / user_id / description
        Added value: +"Greenhouse user ID — get from list_users"
      • addedInput schema / properties / user_role_id / description
        Added value: +"Role to auto-grant — get from list_user_roles"
    • Addedadd_hiring_team_members
    • Changedadd_job_permission3 fields changed
      • addedInput schema / properties / job_id / description
        Added value: +"Job to grant access to — get from list_jobs"
      • addedInput schema / properties / user_id / description
        Added value: +"Greenhouse user ID — get from list_users"
      • addedInput schema / properties / user_role_id / description
        Added value: +"Job Admin role on this job — get valid IDs from list_user_roles"
    • Addedadd_job_post_location
    • Changedadd_note_to_candidate4 fields changed
      • addedInput schema / properties / application_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Optionally anchor the note to one of the candidate's applications",
        +  "title": "Application Id"
        +}
      • addedInput schema / properties / body / description
        Added value: +"Note text content (plain text)"
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
      • addedInput schema / properties / visibility / description
        Added value: +"'private' (default), 'public' (all users with access), or 'admin_only'"
    • Changedadd_prospect10 fields changed
      • addedInput schema / properties / company / description
        Added value: +"Current company name"
      • addedInput schema / properties / email_addresses / description
        Added value: +"Array of {value: 'x@y.com', type: 'personal'|'work'}"
      • addedInput schema / properties / first_name / description
        Added value: +"Prospect's first name"
      • addedInput schema / properties / job_ids
        Added value: +{
        +  "anyOf": [
        +    {
        +      "items": {
        +        "type": "integer"
        +      },
        +      "type": "array"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Jobs this prospect is being considered for — from list_jobs",
        +  "title": "Job Ids"
        +}
      • addedInput schema / properties / last_name / description
        Added value: +"Prospect's last name"
      • addedInput schema / properties / phone_numbers / description
        Added value: +"Array of {value: '+1...', type: 'mobile'|'home'|'work'}"
      • addedInput schema / properties / prospect_owner_id / description
        Added value: +"User ID who owns this prospect — get from list_users"
      • addedInput schema / properties / prospect_pool_id / description
        Added value: +"Prospect pool to add to — get from list_prospect_pools"
      • addedInput schema / properties / prospect_stage_id / description
        Added value: +"Stage within the prospect pool"
      • addedInput schema / properties / title / description
        Added value: +"Current job title"
    • Changedadd_tag_to_candidate2 fields changed
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
      • addedInput schema / properties / tag_id / description
        Added value: +"Tag ID to apply — get from list_tags or create_tag"
    • Changedadvance_application7 fields changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
      • addedInput schema / properties / from_stage_id / anyOf
        Added value: +[
        +  {
        +    "type": "integer"
        +  },
        +  {
        +    "type": "null"
        +  }
        +]
      • addedInput schema / properties / from_stage_id / default
        Added value: +null
      • addedInput schema / properties / from_stage_id / description
        Added value: +"Current job_interview_stage_id (from get_application). Omit to look it up automatically"
      • removedInput schema / properties / from_stage_id / type
        Removed value: -"integer"
      • addedInput schema / properties / to_stage_id / description
        Added value: +"Target stage — from list_job_stages_for_job. Omit for next stage"
      • changedInput schema / required
        Previous value: -[
        -  "application_id",
        -  "from_stage_id"
        -]New value: +[
        +  "application_id"
        +]
    • Changedanonymize_candidate7 fields changed
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
      • removedInput schema / properties / fields / anyOf
        Removed value: -[
        -  {
        -    "items": {
        -      "type": "string"
        -    },
        -    "type": "array"
        -  },
        -  {
        -    "type": "null"
        -  }
        -]
      • removedInput schema / properties / fields / default
        Removed value: -null
      • addedInput schema / properties / fields / description
        Added value: +"Data groups to scrub (at least one), e.g. ['full_name', 'email_addresses', 'phone_numbers', 'addresses', 'attachments', 'notes', 'education', 'employment', 'scorecards_and_interviews', 'offers']"
      • addedInput schema / properties / fields / items
        Added value: +{
        +  "type": "string"
        +}
      • addedInput schema / properties / fields / type
        Added value: +"array"
      • changedInput schema / required
        Previous value: -[
        -  "candidate_id"
        -]New value: +[
        +  "candidate_id",
        +  "fields"
        +]
    • Addedbatch_read_resumes
    • Changedbulk_advance2 fields changed
      • addedInput schema / properties / application_ids / description
        Added value: +"Application IDs to advance"
      • addedInput schema / properties / from_stage_id / description
        Added value: +"Only advance apps currently in this job interview stage (list_job_stages_for_job → match by name); omit to advance each from its current stage"
    • Addedbulk_create_job_openings
    • Addedbulk_delete_job_openings
    • Changedbulk_reject10 fields changed
      • addedInput schema / properties / application_ids / description
        Added value: +"Application IDs to reject — get from list_applications or pipeline_summary"
      • addedInput schema / properties / email_from_user_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "User the rejection email is sent from — list_users",
        +  "title": "Email From User Id"
        +}
      • addedInput schema / properties / email_template_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Rejection email template — list_email_templates → match by name",
        +  "title": "Email Template Id"
        +}
      • addedInput schema / properties / notes
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Internal rejection notes (not sent to the candidate)",
        +  "title": "Notes"
        +}
      • addedInput schema / properties / rejection_email / description
        Added value: +"Send a rejection email to each candidate"
      • removedInput schema / properties / rejection_reason_id / anyOf
        Removed value: -[
        -  {
        -    "type": "integer"
        -  },
        -  {
        -    "type": "null"
        -  }
        -]
      • removedInput schema / properties / rejection_reason_id / default
        Removed value: -null
      • addedInput schema / properties / rejection_reason_id / description
        Added value: +"Rejection reason ID (required) — get from list_rejection_reasons"
      • addedInput schema / properties / rejection_reason_id / type
        Added value: +"integer"
      • changedInput schema / required
        Previous value: -[
        -  "application_ids"
        -]New value: +[
        +  "application_ids",
        +  "rejection_reason_id"
        +]
    • Changedbulk_tag2 fields changed
      • addedInput schema / properties / candidate_ids / description
        Added value: +"Candidate IDs to tag — get from list_candidates or search"
      • addedInput schema / properties / tag_name / description
        Added value: +"Tag name to apply — created on-the-fly if it doesn't exist"
    • Addedbulk_update_job_openings
    • Changedcandidates_needing_action2 fields changed
      • addedInput schema / properties / job_id / description
        Added value: +"Filter to one job — list_jobs → match by name"
      • addedInput schema / properties / stale_days / description
        Added value: +"Days without activity to flag as stale"
    • Changedchange_user_permission_level4 fields changed
      • addedInput schema / properties / permission_level / default
        Added value: +"basic"
      • addedInput schema / properties / permission_level / description
        Added value: +"Must be 'basic' — the only change Greenhouse supports via the API"
      • addedInput schema / properties / user_id / description
        Added value: +"Greenhouse user ID"
      • changedInput schema / required
        Previous value: -[
        -  "user_id",
        -  "permission_level"
        -]New value: +[
        +  "user_id"
        +]
    • Changedconvert_prospect3 fields changed
      • addedInput schema / properties / application_id / description
        Added value: +"Prospect application ID to convert"
      • addedInput schema / properties / initial_stage_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Starting interview stage on that job (list_job_stages_for_job) — defaults to the first stage",
        +  "title": "Initial Stage Id"
        +}
      • addedInput schema / properties / job_id / description
        Added value: +"Job ID to apply the prospect to — get from list_jobs"
    • Changedcreate_application9 fields changed
      • addedInput schema / properties / attachments / description
        Added value: +"Resume/files to add after creating: [{filename, type, content (base64) or url}]"
      • addedInput schema / properties / candidate_id / description
        Added value: +"ID of an existing candidate — use create_candidate first if needed"
      • addedInput schema / properties / coordinator_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "User ID of the coordinator — get from list_users",
        +  "title": "Coordinator Id"
        +}
      • addedInput schema / properties / initial_stage_id / description
        Added value: +"Starting interview stage ID (list_job_stages_for_job) — defaults to the first stage"
      • addedInput schema / properties / job_id / description
        Added value: +"ID of the job to apply to — get from list_jobs"
      • addedInput schema / properties / recruiter_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "User ID of the recruiter — get from list_users",
        +  "title": "Recruiter Id"
        +}
      • removedInput schema / properties / referrer
        Removed value: -{
        -  "anyOf": [
        -    {
        -      "additionalProperties": true,
        -      "type": "object"
        -    },
        -    {
        -      "type": "null"
        -    }
        -  ],
        -  "default": null,
        -  "title": "Referrer"
        -}
      • addedInput schema / properties / referrer_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Referrer record ID to credit for this application",
        +  "title": "Referrer Id"
        +}
      • addedInput schema / properties / source_id / description
        Added value: +"Candidate source ID — get from list_sources"
    • Changedcreate_candidate15 fields changed
      • addedInput schema / properties / addresses / description
        Added value: +"Array of {value: '123 Main St', type: 'home'|'work'|'other'}"
      • addedInput schema / properties / company / description
        Added value: +"Current company name"
      • addedInput schema / properties / coordinator_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Coordinator user ID (list_users) — needs job_id",
        +  "title": "Coordinator Id"
        +}
      • addedInput schema / properties / custom_fields / description
        Added value: +"Array of {custom_field_id (or name_key), value} — get field IDs from list_custom_fields"
      • addedInput schema / properties / email_addresses / description
        Added value: +"Array of {value: 'x@y.com', type: 'personal'|'work'|'other'}"
      • addedInput schema / properties / first_name / description
        Added value: +"Candidate's first name"
      • addedInput schema / properties / initial_stage_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Starting interview stage (list_job_stages_for_job) — needs job_id",
        +  "title": "Initial Stage Id"
        +}
      • addedInput schema / properties / job_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Also apply them to this job (list_jobs) in the same call",
        +  "title": "Job Id"
        +}
      • addedInput schema / properties / last_name / description
        Added value: +"Candidate's last name"
      • addedInput schema / properties / phone_numbers / description
        Added value: +"Array of {value: '+1...', type: 'mobile'|'home'|'work'|'other'}"
      • addedInput schema / properties / recruiter_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Recruiter user ID (list_users) — needs job_id",
        +  "title": "Recruiter Id"
        +}
      • addedInput schema / properties / referrer_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Referrer record ID — needs job_id",
        +  "title": "Referrer Id"
        +}
      • addedInput schema / properties / source_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Application source ID (list_sources) — needs job_id",
        +  "title": "Source Id"
        +}
      • addedInput schema / properties / tags / description
        Added value: +"Candidate tag names to apply"
      • addedInput schema / properties / title / description
        Added value: +"Current job title"
    • Changedcreate_custom_field7 fields changed
      • addedInput schema / properties / description
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Helper text shown beneath the field label",
        +  "title": "Description"
        +}
      • addedInput schema / properties / field_type / description
        Added value: +"Entity: candidate, application, job, offer, opening, user_attribute"
      • addedInput schema / properties / generate_email_token / description
        Added value: +"If true, generates an email token for this field"
      • addedInput schema / properties / name / description
        Added value: +"Display name for the custom field"
      • addedInput schema / properties / options
        Added value: +{
        +  "anyOf": [
        +    {
        +      "items": {
        +        "additionalProperties": true,
        +        "type": "object"
        +      },
        +      "type": "array"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Initial dropdown options for select fields: [{name, sort_order}]",
        +  "title": "Options"
        +}
      • addedInput schema / properties / private / description
        Added value: +"If true, only visible to users with private field access"
      • addedInput schema / properties / value_type / description
        Added value: +"short_text, long_text, yes_no, single/multi_select, currency, date, number, url, user, currency_range, number_range"
    • Changedcreate_custom_field_options2 fields changed
      • addedInput schema / properties / custom_field_id / description
        Added value: +"Custom field ID (must be a single_select or multi_select field)"
      • addedInput schema / properties / options / description
        Added value: +"Array of {name, sort_order, external_id?} — sort_order (or legacy priority) controls display order; defaults to list position"
    • Changedcreate_department3 fields changed
      • addedInput schema / properties / external_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Your HRIS/external identifier for this department",
        +  "title": "External Id"
        +}
      • addedInput schema / properties / name / description
        Added value: +"Department name"
      • addedInput schema / properties / parent_id / description
        Added value: +"Parent department ID for hierarchy — get from list_departments"
    • Changedcreate_interview8 fields changed
      • addedInput schema / properties / application_id / description
        Added value: +"Application to schedule the interview for"
      • addedInput schema / properties / end / description
        Added value: +"End time as ISO 8601, e.g. '2024-03-15T11:00:00Z'"
      • addedInput schema / properties / external_event_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "ID of the matching event on the organizer's calendar (Google/Outlook). A placeholder is generated if omitted",
        +  "title": "External Event Id"
        +}
      • addedInput schema / properties / interview_id / description
        Added value: +"Job interview ID (the interview on the job's plan) — from list_job_stages_for_job → stage interviews[].id"
      • addedInput schema / properties / interviewer_ids / description
        Added value: +"User IDs of interviewers — get from list_users"
      • addedInput schema / properties / location
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Room, address, or meeting link",
        +  "title": "Location"
        +}
      • addedInput schema / properties / start / description
        Added value: +"Start time as ISO 8601, e.g. '2024-03-15T10:00:00Z'"
      • addedInput schema / properties / video_conferencing_url
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Video call join URL",
        +  "title": "Video Conferencing Url"
        +}
    • Changedcreate_job10 fields changed
      • addedInput schema / properties / custom_fields
        Added value: +{
        +  "anyOf": [
        +    {
        +      "items": {
        +        "additionalProperties": true,
        +        "type": "object"
        +      },
        +      "type": "array"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Array of {id, value} — get field IDs from list_custom_fields",
        +  "title": "Custom Fields"
        +}
      • addedInput schema / properties / department_id / description
        Added value: +"Department ID — get from list_departments"
      • addedInput schema / properties / job_name / description
        Added value: +"Internal job name"
      • addedInput schema / properties / job_post_name / description
        Added value: +"Title for the public job post"
      • addedInput schema / properties / notes
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Internal notes about the job (HTML supported)",
        +  "title": "Notes"
        +}
      • addedInput schema / properties / number_of_openings / description
        Added value: +"Number of openings to create on this job"
      • addedInput schema / properties / office_ids / description
        Added value: +"Office IDs — get from list_offices"
      • addedInput schema / properties / opening_ids
        Added value: +{
        +  "anyOf": [
        +    {
        +      "items": {
        +        "type": "string"
        +      },
        +      "type": "array"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Optional external IDs for the new openings, one per opening",
        +  "title": "Opening Ids"
        +}
      • addedInput schema / properties / requisition_id / description
        Added value: +"External requisition/req ID for HRIS mapping"
      • addedInput schema / properties / template_job_id / description
        Added value: +"Existing job ID to use as template — copies pipeline stages and settings"
    • Changedcreate_job_opening5 fields changed
      • addedInput schema / properties / close_reason_id / description
        Added value: +"If closing immediately — get from list_close_reasons"
      • addedInput schema / properties / custom_fields / description
        Added value: +"Array of {id, value} (or {custom_field_id, value}) — get field IDs from list_custom_fields"
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID"
      • addedInput schema / properties / opening_id / description
        Added value: +"Custom external opening identifier (not the Greenhouse ID)"
      • addedInput schema / properties / status / description
        Added value: +"Initial status: 'open' (default) or 'closed'"
    • Changedcreate_office4 fields changed
      • addedInput schema / properties / location / description
        Added value: +"Location string, e.g. 'San Francisco, CA'"
      • addedInput schema / properties / name / description
        Added value: +"Office name"
      • addedInput schema / properties / parent_id / description
        Added value: +"Parent office ID for hierarchy — get from list_offices"
      • addedInput schema / properties / primary_contact_user_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "User ID of the office's primary in-house contact",
        +  "title": "Primary Contact User Id"
        +}
    • Changedcreate_or_replace_approval_flow4 fields changed
      • addedInput schema / properties / approval_type / description
        Added value: +"Flow type: 'open_job', 'offer_job' or 'offer_candidate'"
      • addedInput schema / properties / approver_groups / description
        Added value: +"Ordered approver groups: [{approvals_required: N, approvers: [{user_id: N} | {email: '...'}]}]"
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID"
      • addedInput schema / properties / sequential
        Added value: +{
        +  "default": true,
        +  "description": "Groups approve one after another (true) or all at once",
        +  "title": "Sequential",
        +  "type": "boolean"
        +}
    • Changedcreate_tag1 field changed
      • addedInput schema / properties / name / description
        Added value: +"Tag name — must be unique across the organization"
    • Changedcreate_user7 fields changed
      • addedInput schema / properties / department_ids
        Added value: +{
        +  "anyOf": [
        +    {
        +      "items": {
        +        "type": "integer"
        +      },
        +      "type": "array"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Departments to assign the user to — get from list_departments",
        +  "title": "Department Ids"
        +}
      • addedInput schema / properties / email / description
        Added value: +"User's email address — must be unique in Greenhouse"
      • addedInput schema / properties / first_name / description
        Added value: +"User's first name"
      • addedInput schema / properties / job_title
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Job title on the user's profile",
        +  "title": "Job Title"
        +}
      • addedInput schema / properties / last_name / description
        Added value: +"User's last name"
      • addedInput schema / properties / office_ids
        Added value: +{
        +  "anyOf": [
        +    {
        +      "items": {
        +        "type": "integer"
        +      },
        +      "type": "array"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Offices to assign the user to — get from list_offices",
        +  "title": "Office Ids"
        +}
      • addedInput schema / properties / send_email / description
        Added value: +"Send an invitation email to the new user"
    • Changeddelete_application1 field changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID to delete"
    • Changeddelete_candidate1 field changed
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID to delete"
    • Changeddelete_custom_field1 field changed
      • addedInput schema / properties / custom_field_id / description
        Added value: +"Custom field ID to delete"
    • Changeddelete_custom_field_options2 fields changed
      • addedInput schema / properties / custom_field_id / description
        Added value: +"Custom field ID"
      • addedInput schema / properties / option_ids / description
        Added value: +"IDs of options to delete — get from list_custom_field_options"
    • Changeddelete_interview1 field changed
      • addedInput schema / properties / interview_id / description
        Added value: +"Scheduled interview ID to cancel/delete"
    • Changeddelete_job_opening2 fields changed
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID"
      • addedInput schema / properties / opening_id / description
        Added value: +"Opening ID to delete"
    • Changeddelete_tag1 field changed
      • addedInput schema / properties / tag_id / description
        Added value: +"Tag ID to delete — get from list_tags"
    • Changeddisable_user1 field changed
      • addedInput schema / properties / user_id / description
        Added value: +"Greenhouse user ID to disable"
    • Changeddownload_attachment1 field changed
      • addedInput schema / properties / url / description
        Added value: +"Attachment URL — from get_candidate's or get_application's attachments array"
    • Changedenable_user1 field changed
      • addedInput schema / properties / user_id / description
        Added value: +"Greenhouse user ID to re-enable"
    • Addedfetch_new_applications
    • Changedget_activity_feed2 fields changed
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
      • addedInput schema / properties / created_after
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "ISO 8601 datetime — only entries created after this",
        +  "title": "Created After"
        +}
    • Changedget_answer1 field changed
      • addedInput schema / properties / answer_id / description
        Added value: +"Demographic answer ID — get from list_answers"
    • Changedget_answer_option1 field changed
      • addedInput schema / properties / answer_option_id / description
        Added value: +"Answer option ID — get from list_answer_options"
    • Changedget_application1 field changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
    • Changedget_approval_flow2 fields changed
      • addedInput schema / properties / approval_flow_id / description
        Added value: +"Approval flow ID — get from list_approvals_for_job"
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID"
    • Changedget_board_department1 field changed
      • addedInput schema / properties / department_id / description
        Added value: +"Board department ID — from list_board_departments"
    • Changedget_board_job2 fields changed
      • addedInput schema / properties / job_id / description
        Added value: +"Board job ID — from list_board_jobs"
      • addedInput schema / properties / questions / description
        Added value: +"Include application questions"
    • Changedget_board_office1 field changed
      • addedInput schema / properties / office_id / description
        Added value: +"Board office ID — from list_board_offices"
    • Addedget_bulk_request_status
    • Changedget_candidate2 fields changed
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
      • addedInput schema / properties / include_related
        Added value: +{
        +  "default": true,
        +  "description": "Also fetch applications, attachments, educations and employments (default true; false returns the bare profile)",
        +  "title": "Include Related",
        +  "type": "boolean"
        +}
    • Changedget_current_offer1 field changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
    • Changedget_custom_field1 field changed
      • addedInput schema / properties / custom_field_id / description
        Added value: +"Custom field ID — get from list_custom_fields"
    • Changedget_department1 field changed
      • addedInput schema / properties / department_id / description
        Added value: +"Department ID — get from list_departments"
    • Changedget_eeoc_for_application1 field changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
    • Changedget_email_template1 field changed
      • addedInput schema / properties / email_template_id / description
        Added value: +"Email template ID — get from list_email_templates"
    • Addedget_hiring_team
    • Changedget_interview1 field changed
      • addedInput schema / properties / interview_id / description
        Added value: +"Scheduled interview ID — from list_interviews_for_application"
    • Changedget_job1 field changed
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID"
    • Changedget_job_opening2 fields changed
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID"
      • addedInput schema / properties / opening_id / description
        Added value: +"Opening ID within the job — get from list_job_openings"
    • Changedget_job_post1 field changed
      • addedInput schema / properties / job_post_id / description
        Added value: +"Job post ID — get from list_job_posts or list_job_posts_for_job"
    • Changedget_job_post_custom_locations1 field changed
      • addedInput schema / properties / job_post_id / description
        Added value: +"Job post ID — get from list_job_posts"
    • Changedget_job_post_for_job2 fields changed
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID"
      • addedInput schema / properties / job_post_id / description
        Added value: +"Job post ID"
    • Changedget_job_stage1 field changed
      • addedInput schema / properties / job_stage_id / description
        Added value: +"Job stage ID — get from list_job_stages_for_job"
    • Changedget_offer1 field changed
      • addedInput schema / properties / offer_id / description
        Added value: +"Offer ID — get from list_offers or list_offers_for_application"
    • Changedget_office1 field changed
      • addedInput schema / properties / office_id / description
        Added value: +"Office ID — get from list_offices"
    • Addedget_prospect_pool
    • Changedget_prospect_post_section1 field changed
      • addedInput schema / properties / section_id / description
        Added value: +"Section ID — from list_prospect_post_sections"
    • Changedget_question1 field changed
      • addedInput schema / properties / question_id / description
        Added value: +"Demographic question ID — get from list_questions"
    • Changedget_question_set1 field changed
      • addedInput schema / properties / question_set_id / description
        Added value: +"Question set ID — get from list_question_sets"
    • Changedget_scorecard1 field changed
      • addedInput schema / properties / scorecard_id / description
        Added value: +"Scorecard ID — get from list_scorecards or list_scorecards_for_application"
    • Changedget_tracking_link1 field changed
      • addedInput schema / properties / token / description
        Added value: +"Tracking link token string"
    • Changedget_user1 field changed
      • addedInput schema / properties / user_id / description
        Added value: +"Greenhouse user ID"
    • Changedhire_application4 fields changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
      • addedInput schema / properties / close_reason_id / description
        Added value: +"Reason for closing the opening — get from list_close_reasons"
      • addedInput schema / properties / opening_id / description
        Added value: +"Job opening to fill — get from list_job_openings"
      • addedInput schema / properties / start_date / description
        Added value: +"Hire start date: 'YYYY-MM-DD' or an ISO 8601 date-time"
    • Changedlist_answer_options_for_question1 field changed
      • addedInput schema / properties / question_id / description
        Added value: +"Demographic question ID — get from list_questions"
    • Changedlist_answers5 fields changed
      • addedInput schema / properties / created_after
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "ISO 8601 datetime — only answers created after this",
        +  "title": "Created After"
        +}
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate / description
        Added value: +"'single' for one page, 'all' to auto-fetch every page"
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedlist_answers_for_application1 field changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
    • Changedlist_applications10 fields changed
      • addedInput schema / properties / candidate_id / description
        Added value: +"Filter to applications for this candidate"
      • addedInput schema / properties / created_after / description
        Added value: +"ISO 8601 datetime — only applications created at/after this"
      • addedInput schema / properties / created_before / description
        Added value: +"ISO 8601 datetime — only applications created before this"
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / job_id / description
        Added value: +"Filter to applications on this job"
      • addedInput schema / properties / last_activity_after / description
        Added value: +"ISO 8601 datetime — only applications with activity after this"
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate / description
        Added value: +"'single' for one page, 'all' to auto-fetch every page"
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
      • addedInput schema / properties / status / description
        Added value: +"Filter by status: 'active', 'rejected', 'hired', or 'converted'"
    • Changedlist_approvals_for_job1 field changed
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID"
    • Changedlist_board_jobs1 field changed
      • addedInput schema / properties / content / description
        Added value: +"Include full job content/description"
    • Changedlist_candidates11 fields changed
      • addedInput schema / properties / candidate_ids / description
        Added value: +"Filter to specific candidate IDs (max 50)"
      • addedInput schema / properties / created_after / description
        Added value: +"ISO 8601 datetime — only candidates created at/after this"
      • addedInput schema / properties / created_before / description
        Added value: +"ISO 8601 datetime — only candidates created before this"
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / email / description
        Added value: +"Filter by exact email address"
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate / description
        Added value: +"'single' for one page, 'all' to auto-fetch every page"
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
      • addedInput schema / properties / tag
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Filter by exact candidate tag name",
        +  "title": "Tag"
        +}
      • addedInput schema / properties / updated_after / description
        Added value: +"ISO 8601 datetime — only candidates updated at/after this"
      • addedInput schema / properties / updated_before / description
        Added value: +"ISO 8601 datetime — only candidates updated before this"
    • Changedlist_close_reasons4 fields changed
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / force_refresh / description
        Added value: +"Bypass cache and fetch fresh data"
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedlist_custom_field_options2 fields changed
      • addedInput schema / properties / active
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "boolean"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "true = selectable options only, false = archived only",
        +  "title": "Active"
        +}
      • addedInput schema / properties / custom_field_id / description
        Added value: +"Custom field ID (must be a single_select or multi_select field)"
    • Changedlist_custom_fields2 fields changed
      • addedInput schema / properties / active
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "boolean"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "true = live fields only, false = archived only",
        +  "title": "Active"
        +}
      • addedInput schema / properties / field_type / description
        Added value: +"Filter: candidate, application, job, offer, opening, rejection_question, referral_question, user_attribute"
    • Changedlist_degrees5 fields changed
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / force_refresh / description
        Added value: +"Bypass cache and fetch fresh data"
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate
        Added value: +{
        +  "default": "single",
        +  "description": "'single' for one page, 'all' to auto-fetch every page",
        +  "title": "Paginate",
        +  "type": "string"
        +}
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedlist_departments6 fields changed
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / force_refresh / description
        Added value: +"Bypass cache and fetch fresh data"
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate / description
        Added value: +"'single' for one page, 'all' to auto-fetch every page"
      • addedInput schema / properties / parent_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Only departments directly under this parent department",
        +  "title": "Parent Id"
        +}
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedlist_disciplines5 fields changed
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / force_refresh / description
        Added value: +"Bypass cache and fetch fresh data"
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate
        Added value: +{
        +  "default": "single",
        +  "description": "'single' for one page, 'all' to auto-fetch every page",
        +  "title": "Paginate",
        +  "type": "string"
        +}
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedlist_eeoc6 fields changed
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate / description
        Added value: +"'single' for one page, 'all' to auto-fetch every page"
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
      • addedInput schema / properties / submitted_after
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "ISO 8601 datetime — only responses submitted after this",
        +  "title": "Submitted After"
        +}
      • addedInput schema / properties / submitted_before
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "ISO 8601 datetime — only responses submitted before this",
        +  "title": "Submitted Before"
        +}
    • Changedlist_email_templates5 fields changed
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / email_type
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Filter by type, e.g. candidate_rejection, candidate_email",
        +  "title": "Email Type"
        +}
      • addedInput schema / properties / force_refresh / description
        Added value: +"Bypass cache and fetch fresh data"
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedlist_future_job_permissions1 field changed
      • addedInput schema / properties / user_id / description
        Added value: +"Greenhouse user ID — get from list_users"
    • Changedlist_interviews11 fields changed
      • addedInput schema / properties / created_after / description
        Added value: +"ISO 8601 datetime — only interviews created at/after this"
      • addedInput schema / properties / created_before / description
        Added value: +"ISO 8601 datetime — only interviews created before this"
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / include_details
        Added value: +{
        +  "default": true,
        +  "description": "Resolve interview name, interviewers and organizer (extra calls)",
        +  "title": "Include Details",
        +  "type": "boolean"
        +}
      • addedInput schema / properties / job_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Only interviews on this job — get ID from list_jobs",
        +  "title": "Job Id"
        +}
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate / description
        Added value: +"'single' for one page, 'all' to auto-fetch every page"
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
      • addedInput schema / properties / starts_after
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "ISO 8601 datetime — only interviews starting at/after this",
        +  "title": "Starts After"
        +}
      • addedInput schema / properties / starts_before
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "ISO 8601 datetime — only interviews starting before this",
        +  "title": "Starts Before"
        +}
      • addedInput schema / properties / status
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Filter by status, e.g. 'scheduled', 'awaiting_feedback', 'complete', 'to_be_scheduled'",
        +  "title": "Status"
        +}
    • Changedlist_interviews_for_application1 field changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
    • Changedlist_job_openings2 fields changed
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID"
      • addedInput schema / properties / status / description
        Added value: +"Filter by status: 'open' or 'closed'"
    • Changedlist_job_permissions1 field changed
      • addedInput schema / properties / user_id / description
        Added value: +"Greenhouse user ID — get from list_users"
    • Changedlist_job_posts6 fields changed
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / internal
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "boolean"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "true for internal (employee) board posts, false for external only",
        +  "title": "Internal"
        +}
      • addedInput schema / properties / live / description
        Added value: +"Filter: true for published posts only, false for unpublished only, omit for all"
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate / description
        Added value: +"'single' for one page, 'all' to auto-fetch every page"
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedlist_job_posts_for_job1 field changed
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID"
    • Changedlist_job_stages5 fields changed
      • addedInput schema / properties / active
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "boolean"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "true for stages on current interview plans only, false for removed",
        +  "title": "Active"
        +}
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate / description
        Added value: +"'single' for one page, 'all' to auto-fetch every page"
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedlist_job_stages_for_job2 fields changed
      • addedInput schema / properties / include_inactive
        Added value: +{
        +  "default": false,
        +  "description": "Also return stages removed from the job's interview plan",
        +  "title": "Include Inactive",
        +  "type": "boolean"
        +}
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID"
    • Changedlist_jobs10 fields changed
      • addedInput schema / properties / created_after / description
        Added value: +"ISO 8601 datetime — only jobs created at/after this"
      • addedInput schema / properties / created_before / description
        Added value: +"ISO 8601 datetime — only jobs created before this"
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / department_id / description
        Added value: +"Filter to jobs in this department"
      • addedInput schema / properties / office_id / description
        Added value: +"Filter to jobs in this office"
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate / description
        Added value: +"'single' for one page, 'all' to auto-fetch every page"
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
      • addedInput schema / properties / requisition_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Only jobs with this exact external requisition ID",
        +  "title": "Requisition Id"
        +}
      • addedInput schema / properties / status / description
        Added value: +"Filter by status: 'open', 'closed', or 'draft'"
    • Changedlist_offers9 fields changed
      • addedInput schema / properties / created_after / description
        Added value: +"ISO 8601 datetime — only offers created at/after this"
      • addedInput schema / properties / created_before / description
        Added value: +"ISO 8601 datetime — only offers created before this"
      • addedInput schema / properties / current_only
        Added value: +{
        +  "default": false,
        +  "description": "true to return only the latest version of each application's offer",
        +  "title": "Current Only",
        +  "type": "boolean"
        +}
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / job_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Only offers on this job — get ID from list_jobs",
        +  "title": "Job Id"
        +}
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate / description
        Added value: +"'single' for one page, 'all' to auto-fetch every page"
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
      • addedInput schema / properties / status
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Filter by status: 'Created', 'Accepted', 'Rejected', or 'Deprecated'",
        +  "title": "Status"
        +}
    • Changedlist_offers_for_application1 field changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
    • Changedlist_offices6 fields changed
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / force_refresh / description
        Added value: +"Bypass cache and fetch fresh data"
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate / description
        Added value: +"'single' for one page, 'all' to auto-fetch every page"
      • addedInput schema / properties / parent_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Only offices directly under this parent office",
        +  "title": "Parent Id"
        +}
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedlist_pending_approvals2 fields changed
      • addedInput schema / properties / include_waiting
        Added value: +{
        +  "default": false,
        +  "description": "Also include approvers whose turn hasn't come yet (status 'waiting')",
        +  "title": "Include Waiting",
        +  "type": "boolean"
        +}
      • addedInput schema / properties / user_id / description
        Added value: +"Filter to approvals pending for this user — omit for all pending approvals"
    • Addedlist_prospect_pools
    • Changedlist_questions_for_question_set1 field changed
      • addedInput schema / properties / question_set_id / description
        Added value: +"Question set ID — get from list_question_sets"
    • Changedlist_rejection_reasons5 fields changed
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / force_refresh / description
        Added value: +"Bypass cache and fetch fresh data"
      • addedInput schema / properties / include_defaults
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "boolean"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Also include Greenhouse's built-in default reasons",
        +  "title": "Include Defaults"
        +}
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedlist_schools5 fields changed
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / force_refresh / description
        Added value: +"Bypass cache and fetch fresh data"
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate
        Added value: +{
        +  "default": "single",
        +  "description": "'single' for one page, 'all' to auto-fetch every page (the school list is long — use 'all' to search it by name)",
        +  "title": "Paginate",
        +  "type": "string"
        +}
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedlist_scorecards8 fields changed
      • addedInput schema / properties / created_after / description
        Added value: +"ISO 8601 datetime — only scorecards created at/after this"
      • addedInput schema / properties / created_before / description
        Added value: +"ISO 8601 datetime — only scorecards created before this"
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / include_details
        Added value: +{
        +  "default": true,
        +  "description": "Resolve interviewer, interview, attribute ratings and question answers (extra calls; set false for faster bulk listing)",
        +  "title": "Include Details",
        +  "type": "boolean"
        +}
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate / description
        Added value: +"'single' for one page, 'all' to auto-fetch every page"
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
      • addedInput schema / properties / status
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "'complete' for submitted scorecards, 'draft' for drafts",
        +  "title": "Status"
        +}
    • Changedlist_scorecards_for_application1 field changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
    • Changedlist_sources4 fields changed
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / force_refresh / description
        Added value: +"Bypass cache and fetch fresh data"
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedlist_tags4 fields changed
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / force_refresh / description
        Added value: +"Bypass cache and fetch fresh data"
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedlist_tags_on_candidate1 field changed
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
    • Changedlist_user_roles3 fields changed
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedlist_users8 fields changed
      • addedInput schema / properties / created_after / description
        Added value: +"ISO 8601 datetime — only users created after this"
      • addedInput schema / properties / created_before / description
        Added value: +"ISO 8601 datetime — only users created before this"
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Pass next_cursor from the previous response to get the next page",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / deactivated
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "boolean"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "true = only deactivated users, false = only active; omit for both",
        +  "title": "Deactivated"
        +}
      • addedInput schema / properties / email / description
        Added value: +"Filter by exact email address (primary or secondary)"
      • removedInput schema / properties / page
        Removed value: -{
        -  "default": 1,
        -  "title": "Page",
        -  "type": "integer"
        -}
      • addedInput schema / properties / paginate / description
        Added value: +"'single' for one page, 'all' to auto-fetch every page"
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedmerge_candidates2 fields changed
      • addedInput schema / properties / duplicate_candidate_id / description
        Added value: +"Candidate to merge away — their record is removed after merge"
      • addedInput schema / properties / primary_candidate_id / description
        Added value: +"Candidate to keep — their record is preserved"
    • Changedmove_application4 fields changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
      • addedInput schema / properties / from_stage_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Current job_interview_stage_id (from get_application). Omit to look it up automatically",
        +  "title": "From Stage Id"
        +}
      • addedInput schema / properties / new_job_id / description
        Added value: +"Target job ID — get from list_jobs"
      • addedInput schema / properties / new_stage_id / description
        Added value: +"Target stage in new job — defaults to first stage if omitted"
    • Changedmove_application_same_job7 fields changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
      • addedInput schema / properties / from_stage_id / anyOf
        Added value: +[
        +  {
        +    "type": "integer"
        +  },
        +  {
        +    "type": "null"
        +  }
        +]
      • addedInput schema / properties / from_stage_id / default
        Added value: +null
      • addedInput schema / properties / from_stage_id / description
        Added value: +"Candidate's current job_interview_stage_id. Omit to look it up automatically"
      • removedInput schema / properties / from_stage_id / type
        Removed value: -"integer"
      • addedInput schema / properties / to_stage_id / description
        Added value: +"Target stage ID within the same job — get from list_job_stages_for_job"
      • changedInput schema / required
        Previous value: -[
        -  "application_id",
        -  "from_stage_id",
        -  "to_stage_id"
        -]New value: +[
        +  "application_id",
        +  "to_stage_id"
        +]
    • Changedpipeline_metrics1 field changed
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID — list_jobs → match by name"
    • Changedpipeline_summary1 field changed
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID — list_jobs → match by name"
    • Changedpost_candidate8 fields changed
      • addedInput schema / properties / email / description
        Added value: +"Candidate's email address"
      • addedInput schema / properties / first_name / description
        Added value: +"Candidate's first name"
      • addedInput schema / properties / job_id / description
        Added value: +"Job to apply to — retrieve_ingestion_jobs to find"
      • addedInput schema / properties / last_name / description
        Added value: +"Candidate's last name"
      • addedInput schema / properties / phone / description
        Added value: +"Candidate's phone number"
      • addedInput schema / properties / prospect / description
        Added value: +"True to create as prospect instead of applicant"
      • addedInput schema / properties / resume / description
        Added value: +"Resume content or URL"
      • addedInput schema / properties / source / description
        Added value: +"Source name (free text)"
    • Changedpost_tracking_link3 fields changed
      • addedInput schema / properties / job_id / description
        Added value: +"Job ID — retrieve_ingestion_jobs to find"
      • addedInput schema / properties / referrer / description
        Added value: +"Referrer name or identifier"
      • addedInput schema / properties / source / description
        Added value: +"Source name for attribution"
    • Changedread_candidate_resume1 field changed
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
    • Changedreject_application8 fields changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
      • addedInput schema / properties / notes / description
        Added value: +"Internal rejection notes (not sent to candidate)"
      • addedInput schema / properties / rejection_email / description
        Added value: +"Optional email to candidate: {email_template_id, send_email_at (ISO 8601), email_from_user_id}"
      • removedInput schema / properties / rejection_reason_id / anyOf
        Removed value: -[
        -  {
        -    "type": "integer"
        -  },
        -  {
        -    "type": "null"
        -  }
        -]
      • removedInput schema / properties / rejection_reason_id / default
        Removed value: -null
      • addedInput schema / properties / rejection_reason_id / description
        Added value: +"Reason ID (required) — get from list_rejection_reasons"
      • addedInput schema / properties / rejection_reason_id / type
        Added value: +"integer"
      • changedInput schema / required
        Previous value: -[
        -  "application_id"
        -]New value: +[
        +  "application_id",
        +  "rejection_reason_id"
        +]
    • Changedremove_education2 fields changed
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
      • addedInput schema / properties / education_id / description
        Added value: +"Education record ID from the candidate's profile"
    • Changedremove_employment2 fields changed
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
      • addedInput schema / properties / employment_id / description
        Added value: +"Employment record ID from the candidate's profile"
    • Changedremove_future_job_permission2 fields changed
      • addedInput schema / properties / future_job_permission_id / description
        Added value: +"Permission ID to revoke — get from list_future_job_permissions"
      • addedInput schema / properties / user_id / description
        Added value: +"Greenhouse user ID — get from list_users"
    • Addedremove_hiring_team_member
    • Changedremove_job_permission2 fields changed
      • addedInput schema / properties / job_permission_id / description
        Added value: +"Permission ID to revoke — get from list_job_permissions"
      • addedInput schema / properties / user_id / description
        Added value: +"Greenhouse user ID — get from list_users"
    • Addedremove_job_post_location
    • Changedremove_tag_from_candidate2 fields changed
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
      • addedInput schema / properties / tag_id / description
        Added value: +"Tag ID to remove — get from list_tags_on_candidate"
    • Addedreplace_approver
    • Addedreplace_hiring_team
    • Addedrequest_approvals
    • Changedretrieve_ingestion_candidates2 fields changed
      • addedInput schema / properties / page / description
        Added value: +"Page number"
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Changedretrieve_ingestion_jobs2 fields changed
      • addedInput schema / properties / page / description
        Added value: +"Page number"
      • addedInput schema / properties / per_page / description
        Added value: +"Results per page (max 500)"
    • Addedscan_all_candidates
    • Addedscan_pipeline_resumes
    • Addedscreen_candidate
    • Changedsearch_candidates_by_email1 field changed
      • addedInput schema / properties / email / description
        Added value: +"Exact email address to search for"
    • Changedsearch_candidates_by_name4 fields changed
      • addedInput schema / properties / cursor
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Resume a scan: pass next_cursor from a previous response that had has_more=true",
        +  "title": "Cursor"
        +}
      • addedInput schema / properties / max_pages / description
        Added value: +"Maximum pages to scan before stopping"
      • addedInput schema / properties / name / description
        Added value: +"Name to search — matches first, last or preferred name (case-insensitive substring)"
      • addedInput schema / properties / per_page / description
        Added value: +"Candidates scanned per page (max 500)"
    • Addedsearch_pipeline_candidates
    • Changedsource_effectiveness2 fields changed
      • addedInput schema / properties / created_after / description
        Added value: +"ISO 8601 date — only applications created after this"
      • addedInput schema / properties / job_id / description
        Added value: +"Filter to one job — list_jobs → match by name"
    • Changedstale_applications3 fields changed
      • addedInput schema / properties / days / description
        Added value: +"Minimum days without activity"
      • addedInput schema / properties / job_id / description
        Added value: +"Filter to one job — list_jobs → match by name"
      • addedInput schema / properties / limit / description
        Added value: +"Max applications to return"
    • Changedsubmit_application8 fields changed
      • addedInput schema / properties / cover_letter / description
        Added value: +"Cover letter text"
      • addedInput schema / properties / email / description
        Added value: +"Applicant's email address"
      • addedInput schema / properties / first_name / description
        Added value: +"Applicant's first name"
      • addedInput schema / properties / job_id / description
        Added value: +"Board job ID — from list_board_jobs"
      • addedInput schema / properties / last_name / description
        Added value: +"Applicant's last name"
      • addedInput schema / properties / mapped_url_token / description
        Added value: +"Tracking link token for source attribution"
      • addedInput schema / properties / phone / description
        Added value: +"Applicant's phone number"
      • addedInput schema / properties / resume / description
        Added value: +"Resume content or URL"
    • Changedtime_to_hire2 fields changed
      • addedInput schema / properties / created_after / description
        Added value: +"ISO 8601 date — limit analysis window"
      • addedInput schema / properties / job_id / description
        Added value: +"Filter to one job — list_jobs → match by name"
    • Changedunreject_application1 field changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID of a rejected application"
    • Changedupdate_application7 fields changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
      • addedInput schema / properties / coordinator_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "User ID of the new coordinator — get from list_users",
        +  "title": "Coordinator Id"
        +}
      • addedInput schema / properties / custom_fields / description
        Added value: +"Array of {custom_field_id (or name_key), value} — get field IDs from list_custom_fields"
      • addedInput schema / properties / recruiter_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "User ID of the new recruiter — get from list_users",
        +  "title": "Recruiter Id"
        +}
      • removedInput schema / properties / referrer
        Removed value: -{
        -  "anyOf": [
        -    {
        -      "additionalProperties": true,
        -      "type": "object"
        -    },
        -    {
        -      "type": "null"
        -    }
        -  ],
        -  "default": null,
        -  "title": "Referrer"
        -}
      • addedInput schema / properties / referrer_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Referrer record ID to credit for this application",
        +  "title": "Referrer Id"
        +}
      • addedInput schema / properties / source_id / description
        Added value: +"New source ID — get from list_sources"
    • Changedupdate_candidate9 fields changed
      • addedInput schema / properties / candidate_id / description
        Added value: +"Greenhouse candidate ID"
      • addedInput schema / properties / company / description
        Added value: +"New company name"
      • addedInput schema / properties / custom_fields / description
        Added value: +"Array of {custom_field_id (or name_key), value} — only the fields to change; other custom field values are kept. Get field IDs from list_custom_fields"
      • addedInput schema / properties / email_addresses / description
        Added value: +"Replaces all emails: [{value: 'x@y.com', type: 'personal'|'work'}]"
      • addedInput schema / properties / first_name / description
        Added value: +"New first name"
      • addedInput schema / properties / last_name / description
        Added value: +"New last name"
      • addedInput schema / properties / phone_numbers / description
        Added value: +"Replaces all phones: [{value: '+1...', type: 'mobile'|'home'|'work'}]"
      • addedInput schema / properties / tags / description
        Added value: +"Replaces all tags — provide the full list, not just additions"
      • addedInput schema / properties / title / description
        Added value: +"New job title"
    • Changedupdate_current_offer4 fields changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID"
      • addedInput schema / properties / custom_fields / description
        Added value: +"Array of {id, value} (or {custom_field_id, value}) — get field IDs from list_custom_fields"
      • addedInput schema / properties / sent_on
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Date the offer was sent, as 'YYYY-MM-DD'",
        +  "title": "Sent On"
        +}
      • addedInput schema / properties / starts_at / description
        Added value: +"New start date as 'YYYY-MM-DD'"
    • Changedupdate_custom_field4 fields changed
      • addedInput schema / properties / custom_field_id / description
        Added value: +"Custom field ID — get from list_custom_fields"
      • addedInput schema / properties / description
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "New helper text",
        +  "title": "Description"
        +}
      • addedInput schema / properties / name / description
        Added value: +"New display name"
      • addedInput schema / properties / private / description
        Added value: +"New privacy setting"
    • Changedupdate_custom_field_options2 fields changed
      • addedInput schema / properties / custom_field_id / description
        Added value: +"Custom field ID"
      • addedInput schema / properties / options / description
        Added value: +"Array of {id, name?, sort_order?, external_id?} — get IDs from list_custom_field_options"
    • Changedupdate_department4 fields changed
      • addedInput schema / properties / department_id / description
        Added value: +"Department ID to update"
      • addedInput schema / properties / external_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "New HRIS/external identifier",
        +  "title": "External Id"
        +}
      • addedInput schema / properties / name / description
        Added value: +"New department name"
      • addedInput schema / properties / parent_id / description
        Added value: +"New parent department ID — get from list_departments"
    • Changedupdate_interview6 fields changed
      • addedInput schema / properties / end / description
        Added value: +"New end time as ISO 8601"
      • addedInput schema / properties / interview_id / description
        Added value: +"Scheduled interview ID to update"
      • addedInput schema / properties / interviewer_ids / description
        Added value: +"Replaces all interviewers — provide the full list"
      • addedInput schema / properties / location
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "New location or meeting link",
        +  "title": "Location"
        +}
      • addedInput schema / properties / start / description
        Added value: +"New start time as ISO 8601"
      • addedInput schema / properties / video_conferencing_url
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "New video call join URL",
        +  "title": "Video Conferencing Url"
        +}
    • Changedupdate_job10 fields changed
      • addedInput schema / properties / custom_fields
        Added value: +{
        +  "anyOf": [
        +    {
        +      "items": {
        +        "additionalProperties": true,
        +        "type": "object"
        +      },
        +      "type": "array"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Array of {id, value} — replaces the job's custom field values",
        +  "title": "Custom Fields"
        +}
      • addedInput schema / properties / department_id / description
        Added value: +"New department ID — get from list_departments"
      • addedInput schema / properties / how_to_sell_this_job
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Internal selling points recruiters use for the role",
        +  "title": "How To Sell This Job"
        +}
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID"
      • addedInput schema / properties / name / description
        Added value: +"New internal job name"
      • addedInput schema / properties / notes / description
        Added value: +"Internal notes about the job (HTML supported)"
      • addedInput schema / properties / office_ids / description
        Added value: +"Replaces all office associations — get IDs from list_offices"
      • addedInput schema / properties / requisition_id / description
        Added value: +"External requisition/req ID"
      • addedInput schema / properties / status / description
        Added value: +"Not settable in Harvest v3 — a job's status follows its openings. Use update_job_opening to close or reopen openings instead."
      • addedInput schema / properties / team_and_responsibilities
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Internal description of the team and responsibilities",
        +  "title": "Team And Responsibilities"
        +}
    • Changedupdate_job_opening7 fields changed
      • addedInput schema / properties / close_reason_id / description
        Added value: +"Reason for closing — get from list_close_reasons"
      • addedInput schema / properties / custom_fields / description
        Added value: +"Array of {id, value} (or {custom_field_id, value}) — get field IDs from list_custom_fields"
      • addedInput schema / properties / external_opening_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "New custom external opening identifier",
        +  "title": "External Opening Id"
        +}
      • addedInput schema / properties / job_id / description
        Added value: +"Greenhouse job ID"
      • addedInput schema / properties / opening_id / description
        Added value: +"Opening ID within the job"
      • addedInput schema / properties / status / description
        Added value: +"New status: 'open' or 'closed'"
      • addedInput schema / properties / target_start_on
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Target start date as 'YYYY-MM-DD'",
        +  "title": "Target Start On"
        +}
    • Changedupdate_job_post4 fields changed
      • addedInput schema / properties / content / description
        Added value: +"New post body content (HTML supported)"
      • addedInput schema / properties / job_post_id / description
        Added value: +"Job post ID to update"
      • addedInput schema / properties / location / description
        Added value: +"New free-text location. Replaces the post's existing locations; use add_job_post_location to add one instead"
      • addedInput schema / properties / title / description
        Added value: +"New post title"
    • Changedupdate_job_post_status2 fields changed
      • addedInput schema / properties / job_post_id / description
        Added value: +"Job post ID to update"
      • addedInput schema / properties / status / description
        Added value: +"New status: 'live' (published) or 'offline' (unpublished draft)"
    • Changedupdate_office5 fields changed
      • addedInput schema / properties / location / description
        Added value: +"New location string"
      • addedInput schema / properties / name / description
        Added value: +"New office name"
      • addedInput schema / properties / office_id / description
        Added value: +"Office ID to update"
      • addedInput schema / properties / parent_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "New parent office ID — get from list_offices",
        +  "title": "Parent Id"
        +}
      • addedInput schema / properties / primary_contact_user_id
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "integer"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "User ID of the new primary in-house contact",
        +  "title": "Primary Contact User Id"
        +}
    • Changedupdate_rejection_reason2 fields changed
      • addedInput schema / properties / application_id / description
        Added value: +"Greenhouse application ID (must be already rejected)"
      • addedInput schema / properties / rejection_reason_id / description
        Added value: +"New rejection reason ID — get from list_rejection_reasons"
    • Changedupdate_user7 fields changed
      • addedInput schema / properties / department_ids
        Added value: +{
        +  "anyOf": [
        +    {
        +      "items": {
        +        "type": "integer"
        +      },
        +      "type": "array"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Replace the user's departments — get from list_departments",
        +  "title": "Department Ids"
        +}
      • addedInput schema / properties / first_name / description
        Added value: +"New first name"
      • addedInput schema / properties / job_title
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "New job title",
        +  "title": "Job Title"
        +}
      • addedInput schema / properties / last_name / description
        Added value: +"New last name"
      • addedInput schema / properties / office_ids
        Added value: +{
        +  "anyOf": [
        +    {
        +      "items": {
        +        "type": "integer"
        +      },
        +      "type": "array"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "Replace the user's offices — get from list_offices",
        +  "title": "Office Ids"
        +}
      • addedInput schema / properties / primary_email
        Added value: +{
        +  "anyOf": [
        +    {
        +      "type": "string"
        +    },
        +    {
        +      "type": "null"
        +    }
        +  ],
        +  "default": null,
        +  "description": "New primary email — must already be a verified email on the user",
        +  "title": "Primary Email"
        +}
      • addedInput schema / properties / user_id / description
        Added value: +"Greenhouse user ID"
    • Changedwebhook_create_rule5 fields changed
      • addedInput schema / properties / action_type / description
        Added value: +"'forward' (requires action_url) or 'log'"
      • addedInput schema / properties / action_url / description
        Added value: +"URL to forward events to (required if action_type='forward')"
      • addedInput schema / properties / event_type / description
        Added value: +"Greenhouse event type or '*' for all — see webhook_list_events"
      • addedInput schema / properties / filter_field / description
        Added value: +"JSON field to filter on (e.g., 'application.job.id')"
      • addedInput schema / properties / filter_value / description
        Added value: +"Required value for the filter field"
    • Changedwebhook_delete_rule1 field changed
      • addedInput schema / properties / rule_id / description
        Added value: +"Rule ID — from webhook_list_rules"
    • Changedwebhook_list_recent1 field changed
      • addedInput schema / properties / limit / description
        Added value: +"Maximum events to return"
    • Changedwebhook_setup_guide2 fields changed
      • addedInput schema / properties / events / description
        Added value: +"Event types to subscribe to — omit for all events"
      • addedInput schema / properties / receiver_url / description
        Added value: +"Public URL where the webhook receiver is hosted"
    • Changedwebhook_test_rule1 field changed
      • addedInput schema / properties / rule_id / description
        Added value: +"Rule ID — from webhook_list_rules"
    • Changedwebhook_update_rule5 fields changed
      • addedInput schema / properties / action_type / description
        Added value: +"'forward' or 'log'"
      • addedInput schema / properties / action_url / description
        Added value: +"New forward URL"
      • addedInput schema / properties / active / description
        Added value: +"Enable or disable the rule"
      • addedInput schema / properties / event_type / description
        Added value: +"New event type or '*'"
      • addedInput schema / properties / rule_id / description
        Added value: +"Rule ID — from webhook_list_rules"
  2. 16 tool updatesv0.3.3
    • Removedadd_hiring_team_members
    • Addedbulk_advance
    • Addedbulk_reject
    • Addedbulk_tag
    • Addeddownload_attachment
    • Removedget_hiring_team
    • Removedget_prospect_pool
    • Removedlist_prospect_pools
    • Removedremove_hiring_team_member
    • Removedreplace_approver
    • Removedreplace_hiring_team
    • Removedrequest_approvals
    • Addedsearch_candidates_by_email
    • Addedsearch_candidates_by_name
    • Addedsource_effectiveness
    • Addedtime_to_hire
  3. 167 tool updatesv0.3.4
    • Addedadd_attachment
    • Addedadd_attachment_to_application
    • Addedadd_education
    • Addedadd_email_note_to_candidate
    • Addedadd_email_to_user
    • Addedadd_employment
    • Addedadd_future_job_permission
    • Addedadd_hiring_team_members
    • Addedadd_job_permission
    • Addedadd_note_to_candidate
    • Addedadd_prospect
    • Addedadd_tag_to_candidate
    • Addedadvance_application
    • Addedanonymize_candidate
    • Addedcandidates_needing_action
    • Addedchange_user_permission_level
    • Addedconvert_prospect
    • Addedcreate_application
    • Addedcreate_candidate
    • Addedcreate_custom_field
    • Addedcreate_custom_field_options
    • Addedcreate_department
    • Addedcreate_interview
    • Addedcreate_job
    • Addedcreate_job_opening
    • Addedcreate_office
    • Addedcreate_or_replace_approval_flow
    • Addedcreate_tag
    • Addedcreate_user
    • Addeddelete_application
    • Addeddelete_candidate
    • Addeddelete_custom_field
    • Addeddelete_custom_field_options
    • Addeddelete_interview
    • Addeddelete_job_opening
    • Addeddelete_tag
    • Addeddisable_user
    • Addedenable_user
    • Addedget_activity_feed
    • Addedget_answer
    • Addedget_answer_option
    • Addedget_application
    • Addedget_approval_flow
    • Addedget_board
    • Addedget_board_department
    • Addedget_board_job
    • Addedget_board_office
    • Addedget_candidate
    • Addedget_current_offer
    • Addedget_custom_field
    • Addedget_department
    • Addedget_eeoc_for_application
    • Addedget_email_template
    • Addedget_hiring_team
    • Addedget_interview
    • Addedget_job
    • Addedget_job_opening
    • Addedget_job_post
    • Addedget_job_post_custom_locations
    • Addedget_job_post_for_job
    • Addedget_job_stage
    • Addedget_offer
    • Addedget_office
    • Addedget_prospect_pool
    • Addedget_prospect_post_section
    • Addedget_question
    • Addedget_question_set
    • Addedget_scorecard
    • Addedget_tracking_link
    • Addedget_user
    • Addedhire_application
    • Addedlist_answer_options
    • Addedlist_answer_options_for_question
    • Addedlist_answers
    • Addedlist_answers_for_application
    • Addedlist_applications
    • Addedlist_approvals_for_job
    • Addedlist_board_degrees
    • Addedlist_board_departments
    • Addedlist_board_disciplines
    • Addedlist_board_jobs
    • Addedlist_board_offices
    • Addedlist_board_schools
    • Addedlist_candidates
    • Addedlist_close_reasons
    • Addedlist_custom_field_options
    • Addedlist_custom_fields
    • Addedlist_degrees
    • Addedlist_departments
    • Addedlist_disciplines
    • Addedlist_eeoc
    • Addedlist_email_templates
    • Addedlist_future_job_permissions
    • Addedlist_interviews
    • Addedlist_interviews_for_application
    • Addedlist_job_openings
    • Addedlist_job_permissions
    • Addedlist_job_posts
    • Addedlist_job_posts_for_job
    • Addedlist_job_stages
    • Addedlist_job_stages_for_job
    • Addedlist_jobs
    • Addedlist_offers
    • Addedlist_offers_for_application
    • Addedlist_offices
    • Addedlist_pending_approvals
    • Addedlist_prospect_pools
    • Addedlist_prospect_post_sections
    • Addedlist_question_sets
    • Addedlist_questions
    • Addedlist_questions_for_question_set
    • Addedlist_rejection_reasons
    • Addedlist_schools
    • Addedlist_scorecards
    • Addedlist_scorecards_for_application
    • Addedlist_sources
    • Addedlist_tags
    • Addedlist_tags_on_candidate
    • Addedlist_user_roles
    • Addedlist_users
    • Addedmerge_candidates
    • Addedmove_application
    • Addedmove_application_same_job
    • Addedpipeline_metrics
    • Addedpipeline_summary
    • Addedpost_candidate
    • Addedpost_tracking_link
    • Addedread_candidate_resume
    • Addedreject_application
    • Addedremove_education
    • Addedremove_employment
    • Addedremove_future_job_permission
    • Addedremove_hiring_team_member
    • Addedremove_job_permission
    • Addedremove_tag_from_candidate
    • Addedreplace_approver
    • Addedreplace_hiring_team
    • Addedrequest_approvals
    • Addedretrieve_current_user
    • Addedretrieve_ingestion_candidates
    • Addedretrieve_ingestion_jobs
    • Addedretrieve_prospect_pools
    • Addedstale_applications
    • Addedsubmit_application
    • Addedunreject_application
    • Addedupdate_application
    • Addedupdate_candidate
    • Addedupdate_current_offer
    • Addedupdate_custom_field
    • Addedupdate_custom_field_options
    • Addedupdate_department
    • Addedupdate_interview
    • Addedupdate_job
    • Addedupdate_job_opening
    • Addedupdate_job_post
    • Addedupdate_job_post_status
    • Addedupdate_office
    • Addedupdate_rejection_reason
    • Addedupdate_user
    • Addedwebhook_create_rule
    • Addedwebhook_delete_rule
    • Addedwebhook_list_events
    • Addedwebhook_list_recent
    • Addedwebhook_list_rules
    • Addedwebhook_setup_guide
    • Addedwebhook_test_rule
    • Addedwebhook_update_rule

TDQS

A3.6/5.0

Scored across 187 tools

Disambiguation3/5

Several tools have overlapping purposes, such as multiple candidate search/scan tools (search_candidates_by_name, search_candidates_by_email, list_candidates, scan_all_candidates, search_pipeline_candidates, scan_pipeline_resumes) and overlapping analytics (pipeline_metrics vs source_effectiveness, candidates_needing_action vs stale_applications). Descriptions provide cross-references and clarifications, but the sheer volume and similarity of some tools still create misselection risk.

Naming Consistency4/5

Tool names mostly follow a consistent snake_case verb_noun pattern (e.g., list_jobs, get_candidate, create_application, update_interview). A few exceptions exist, such as noun-phrase names (pipeline_summary, candidates_needing_action) and prefixed families (webhook_*, board_*), but the overall convention is predictable and readable.

Tool Count1/5

187 tools is an extreme mismatch for a single MCP server, far exceeding the 50+ threshold that indicates poor scoping. Many tools are thin CRUD wrappers or context-specific duplicates (e.g., board vs internal vs ingestion versions) that could be consolidated into fewer, more versatile tools.

Completeness5/5

The tool surface covers the entire Greenhouse ATS domain comprehensively: candidates, applications, jobs, interviews, offers, approvals, users, departments, offices, custom fields, tags, sources, rejection reasons, EEOC, webhooks, and ingestion. CRUD lifecycle operations are present for most resources, with no obvious dead ends for core workflows.

Maintenance

ActivityMaintained
ResponsivenessUnresponsive

Related MCP Connectors

Related MCP Servers

  • F
    license
    Not graded
    quality
    D
    maintenance
    A server implementation that enables interaction with Greenhouse's recruitment and applicant tracking system through Model Context Protocol, providing tools for job listings, candidate management, application filtering, and stage transitions.
    1
    -
  • A
    license
    Not graded
    quality
    D
    maintenance
    This project builds a read-only MCP server. For full read, write, update, delete, and action capabilities and a simplified setup, check out our free CData MCP Server for Greenhouse (beta): https://www.cdata.com/download/download.aspx?sku=PGZK-V&type=beta
    MIT
  • F
    license
    Not graded
    quality
    D
    maintenance
    Full-coverage, read-only MCP server for the Teamtailor recruitment API. Exposes 18 tools covering candidates, jobs, applications, offers, stages, departments, locations, users, and activities with strict input validation.
    -