Greenhouse MCP
This server provides a production-ready MCP interface to Greenhouse for recruiters and hiring teams, with read-only, recruiter, and full tool profiles.
Manage candidates: create, update, delete, merge, anonymize, notes, attachments, education, employment, tags, search by name/email.
Manage applications: create, update, delete, advance, move, reject/unreject, hire, bulk operations.
Manage jobs and job posts: create, update, list, stages, openings, job board listings.
Manage interviews, offers, and scorecards.
Manage users, permissions, departments, offices, custom fields, sources, rejection reasons, email templates.
Screening & sourcing: screen candidates, fetch new applications, scan resumes with boolean keywords, search pipelines, batch read resumes.
Composite workflows: pipeline summary, stale applications, candidates needing action, pipeline metrics, source effectiveness, time to hire.
Safety: scoped access, read-only mode, audit trail via GREENHOUSE_USER_ID, rate-limited bulk actions.
Provides tools for interacting with Greenhouse's recruitment platform, enabling AI agents to manage candidates, applications, jobs, interviews, offers, and perform bulk operations with role-based access control.
open-greenhouse-mcp
Production-ready MCP server for Greenhouse, designed for recruiters and hiring teams.
Most Greenhouse MCP servers mirror the API endpoint by endpoint. This one is built for recruiting teams: safe defaults, role-based profiles, and workflow tools that turn multi-step API operations into single actions.
Choose a Profile
Profile | Tools | Can write? | Recommended for |
| 104 | No | First-time setup, reporting, hiring managers |
| 128 | Yes (safe ops) | Day-to-day recruiting work |
| 187 | Yes (all) | Admins, ops, advanced automation |
Harvest v3. Greenhouse retired Harvest v1/v2 on 31 Aug 2026. From 0.5.0 this server uses Harvest v3 with OAuth 2.0 credentials. Upgrading from 0.4 or earlier? See Migrating from v1/v2.
Related MCP server: Greenhouse MCP Server by CData
Quick Start
pip install open-greenhouse-mcpAdd to your MCP client config (Claude Desktop: ~/Library/Application Support/Claude/claude_desktop_config.json, Cursor: Settings > MCP):
{
"mcpServers": {
"greenhouse": {
"command": "open-greenhouse-mcp",
"env": {
"GREENHOUSE_CLIENT_ID": "your-harvest-v3-client-id",
"GREENHOUSE_CLIENT_SECRET": "your-harvest-v3-client-secret",
"GREENHOUSE_TOOL_PROFILE": "read-only"
}
}
}
}Start in read-only mode to validate connectivity and tool behaviour, then switch to recruiter or full when you need write access.
Create the credentials in Greenhouse under Configure > Dev Center > API Credentials > Create new API credentials > Harvest V3 (OAuth), and grant the scopes for the tools you plan to use. The client secret is shown once. See Advanced Setup for how tokens and scopes work.
What You Can Ask
"Show me the pipeline for our Senior Engineer role"
"Who needs my attention this week?"
"What are our conversion rates for the Backend Intern role?"
"Find Sarah Chen and pull up her resume"
"Which sources are actually producing hires?"
"Bulk reject everything inactive for 30+ days on the Account Manager role"
"Screen this candidate for the Backend Engineer role — give me the full picture"
"Search our engineering pipelines for anyone with Rust and distributed systems experience"
"What new applications came in since yesterday?"
See more examples with full output.
See it in action
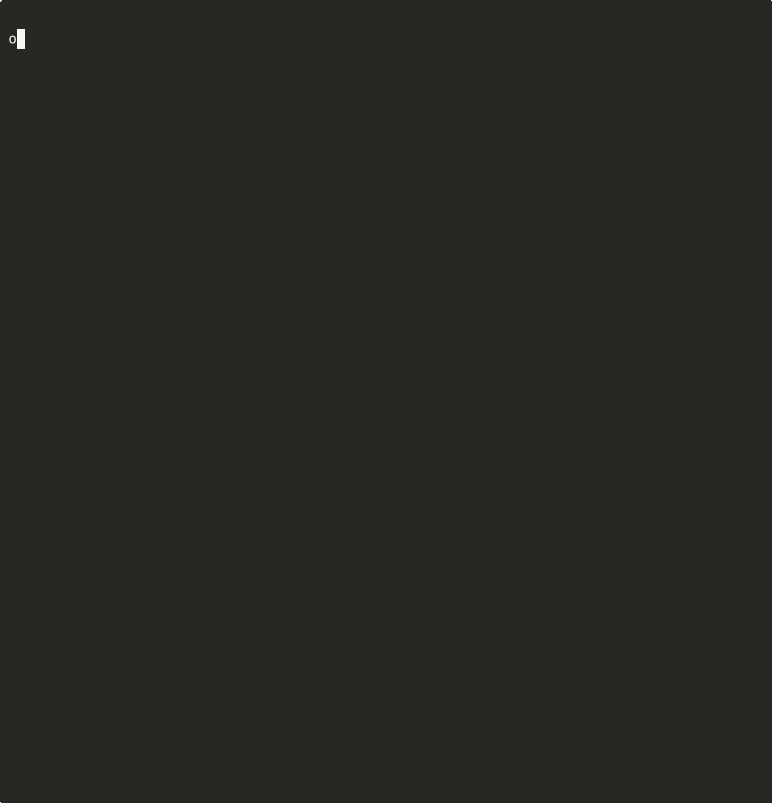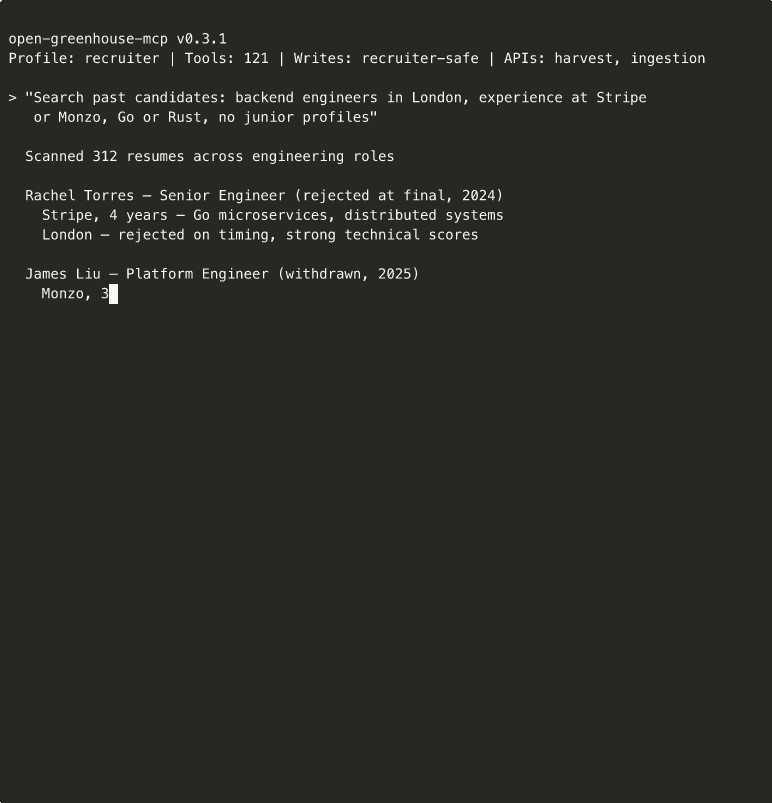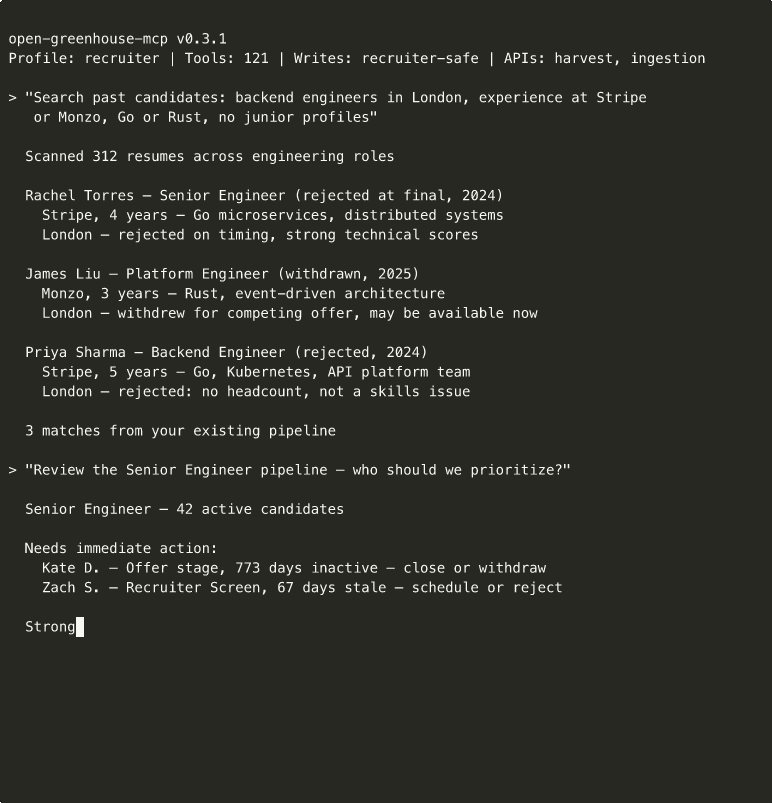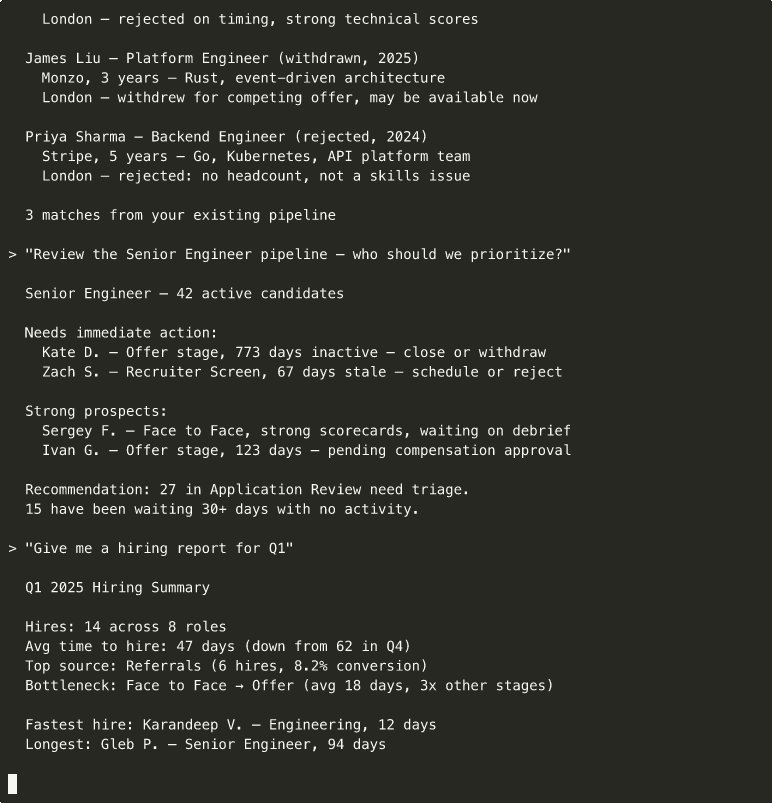
Safety
Access is limited by the scopes on your Harvest v3 credential and the acting user's permissions
Read-only profile is recommended for first setup
Destructive actions require explicit IDs — the server never infers targets
Set
GREENHOUSE_USER_IDand writes are made as that user (OAuthsub), so Greenhouse's audit trail shows who did whatBulk actions are rate-limited to stay within API limits
Compatibility
Client | Status |
Supported | |
Supported | |
Supported | |
Transport | stdio |
Python | 3.10+ |
Startup
When the server starts, it logs its configuration:
open-greenhouse-mcp v0.5.0
Profile: recruiter | Tools: 128 | Writes: recruiter-safe | APIs: harvest-v3What's Included
Screening & sourcing tools — 6 tools for candidate screening, resume search with boolean keywords, daily digest, and location detection
Recruiter workflow tools — 13 composite tools for pipeline views, analytics, search, and bulk operations
Harvest v3 API coverage — 154 tools across candidates, applications, jobs, offers, interviews, and more
Job Board API — 13 tools for public job listings and application submission
Optional webhooks and ingestion — 14 tools for event-driven workflows and partner integrations
Reference
Screening & Sourcing Tools
Tools for candidate evaluation and proactive talent search.
Tool | What it does |
| Complete screening package — profile, resume text, location, screening answers, job description, history |
| Applications since a date, grouped by job — the daily recruiter digest |
| Search resume text across pipelines with boolean keywords (required/preferred/exclude) |
| Search pipelines by structured fields — title, company, education, experience, tags |
| Database-wide candidate search by structured fields with date bounds |
| Batch-fetch and extract resume text for multiple candidates |
Composite Tools
High-level tools that combine multiple API calls into single operations.
Tool | What it does |
| Full pipeline view — candidates grouped by stage with names and days-in-stage |
| Find stale applications and interviews missing scorecards |
| Applications with no activity for N days, sorted by stalest |
| Conversion rates, hire/rejection rates, time-in-stage per stage |
| Which candidate sources produce the best hire rates |
| Average, median, min, max days from application to hire |
| Reject multiple applications in one call with rate-limit handling |
| Tag multiple candidates in one call |
| Advance multiple applications to next stage |
| Track a Greenhouse asynchronous bulk request (openings, custom field options) |
| Find candidates by first or last name |
| Look up a candidate by exact email |
| Download and return a candidate's most recent resume |
| Download any Greenhouse attachment by URL |
Profile Details
Recruiter includes all read tools, all screening/sourcing tools, all composite workflows, and recruiter-safe writes: reject, advance, hire, move, tag, notes, attachments, interviews, prospects, and bulk operations. It excludes job creation, user management, custom field configuration, candidate deletion, and webhook management.
Read-only skips all write operations. GREENHOUSE_READ_ONLY=true also works as a shorthand.
Configuration
Variable | Required | Description |
| Yes* | Harvest v3 OAuth client ID |
| Yes* | Harvest v3 OAuth client secret |
| Yes* | Job board URL slug. *Harvest credentials and/or a board token required |
| No | Greenhouse user ID: writes are made as this user, and the tool profile is derived from their role |
| No |
|
| No | Job Board API key, for submitting applications through the board |
| No | Ingestion API key, for partner candidate submission |
| No |
|
| No | Log file path (defaults to stderr) |
Logging
Structured JSON logging for observability. Set GREENHOUSE_LOG_LEVEL=info to enable:
{"ts": "2026-04-14T12:31:58", "level": "info", "event": "api_call", "method": "GET", "url": "...", "status": 200, "latency_ms": 245.0}More Documentation
API Reference — Full tool breakdown by category
Usage Examples — Real conversations with full output
Advanced Setup — Harvest v3 credentials and scopes, migrating from v1/v2, webhook receiver, ingestion API, board-token mode
Development — Contributing, testing, project structure
Feedback
Bugs and features: Open an issue
Questions: Start a discussion
Security: See SECURITY.md
Contributing: See CONTRIBUTING.md
License
MIT License -- Ben Monopoli. See LICENSE.
Available Tools
187 toolsadd_attachmentA
Attach a file (resume, cover letter, etc.) to a candidate. Write operation.
Harvest v3 stores every attachment on an application, so this attaches to application_id if given, otherwise to the candidate's most recently active application (the response's application_id shows which). To get candidate_id: search_candidates_by_name. To choose the application, see get_candidate's applications array, or use add_attachment_to_application.
Inputs: type (required), filename (required), candidate_id (required), url, +3 more. Returns: result
add_attachment_to_applicationA
Attach a file to a specific application. Write operation.
To find the application_id: search_candidates_by_name → get_candidate → match the application to the job. The file type is inferred from the filename extension. add_attachment does the same when you only know the candidate.
Inputs: type (required), filename (required), application_id (required), url, +2 more. Returns: result
add_educationA
Add an education entry to a candidate. Write operation.
To find candidate_id: search_candidates_by_name. For school_id: list_schools; degree_id: list_degrees; discipline_id: list_disciplines (match by name — these are custom field option IDs in Harvest v3).
Inputs: candidate_id (required), end_date, degree_id, school_id, +2 more. Returns: result
add_email_note_to_candidateA
Log an email on a candidate's activity feed. Write operation.
Records an email exchange (to, from, cc, subject, body) as an activity entry. This logs the email — it does not send one. To get candidate_id: search_candidates_by_name.
Inputs: to (required), body (required), from_ (required), subject (required), +3 more. Returns: result
add_email_to_userA
Add a secondary email address to a Greenhouse user. Write operation.
To find user_id: list_users → match by name or email. The address stays unverified until the user confirms it.
Inputs: email (required), user_id (required), send_verification. Returns: result
add_employmentA
Add an employment entry to a candidate. Write operation.
company_name, title and start_date are required by Greenhouse. To find candidate_id: search_candidates_by_name.
Inputs: candidate_id (required), title, end_date, start_date, +1 more. Returns: result
add_future_job_permissionA
Auto-grant a role on all future jobs. Write operation — admin only.
Users say "give Sarah recruiter access to all new Engineering jobs." For user_id: list_users. For user_role_id: list_user_roles. Scope with office_id (list_offices) or department_id (list_departments).
Inputs: user_id (required), user_role_id (required), office_id, department_id. Returns: result
add_hiring_team_membersA
Add members to a hiring team without replacing existing ones. Write operation.
To find job_id: list_jobs → match by name. For member user_ids: list_users
→ match by name. Returns added and any per-member errors.
Inputs: job_id (required), sourcers, recruiters, coordinators, +1 more. Returns: result
add_job_permissionA
Grant a user a role on a specific job. Write operation — admin only.
Users say "give Sarah recruiter access to the Backend role." For user_id: list_users → match by name. For job_id: list_jobs → match by name. For user_role_id: list_user_roles → match by role name (role_type 'job_admin').
Inputs: job_id (required), user_id (required), user_role_id (required). Returns: result
add_job_post_locationA
Add a location to a job post. Write operation — admin only.
v3 job posts can have several locations. The post's job board must allow the location type. To find job_post_id: list_job_posts_for_job.
Inputs: value (required), job_post_id (required), type. Returns: result
add_note_to_candidateA
Add a text note to a candidate's Notes tab / activity feed. Write operation.
Users say "add a note to Sarah's profile" or "log that I spoke with John." The note is authored by the configured Greenhouse user. To get candidate_id: search_candidates_by_name.
Inputs: body (required), candidate_id (required), visibility, application_id. Returns: result
add_prospectA
Create a sourced prospect in a prospect pool. Write operation.
Users say "add this person as a prospect for the Engineering pool." Unlike create_candidate with a job_id, this creates a prospect not yet in an active job pipeline. For pool/stage IDs: list_prospect_pools → match by name. To later convert to an active candidate, use convert_prospect.
Inputs: last_name (required), first_name (required), title, company, +6 more. Returns: result
add_tag_to_candidateA
Apply a tag to a candidate. Write operation.
Users say "tag Sarah as 'referred'" or "mark John as strong hire." For candidate_id: search_candidates_by_name. For tag_id: list_tags → match by name. For bulk tagging, use bulk_tag instead.
Inputs: tag_id (required), candidate_id (required). Returns: result
advance_applicationA
Move a candidate forward one stage in their job pipeline. Write operation.
Users say "advance Sarah to the next stage" or "move John forward." To get the application_id: search_candidates_by_name → get_candidate → match the application to the job. from_stage_id must be the application's current job_interview_stage_id (Greenhouse rejects stale moves); omit it and it is looked up for you. Omit to_stage_id to advance to the natural next stage. To skip stages, use move_application_same_job. For bulk advancing, use bulk_advance.
Inputs: application_id (required), to_stage_id, from_stage_id. Returns: result
anonymize_candidateA
Anonymize a candidate's personal data for GDPR/privacy compliance. Write operation.
Scrubs the listed data groups (name, emails, phones, attachments, notes, etc.) while preserving the record and hiring activity for reporting. Irreversible; large scopes complete asynchronously. Greenhouse requires an explicit list of fields — confirm with the user what to remove. To get the candidate_id: search_candidates_by_name → get_candidate.
Inputs: fields (required), candidate_id (required). Returns: result
batch_read_resumesA
Download and extract resume text for a list of candidates. Read-only.
Use after narrowing candidates with other sourcing tools. Pass candidate_ids from search_pipeline_candidates or scan_all_candidates. Uses each candidate's most recent resume across all their applications. Full resume text reveals career trajectory, scope of work, and skills that structured data doesn't capture.
Inputs: candidate_ids (required), max_candidates. Returns: result
bulk_advanceA
Advance multiple applications to the next stage. Write operation — rate-limited.
Users say "move everyone past phone screen forward." Get application_ids from pipeline_summary or list_applications. Each application moves from its current stage to the next one on its job's interview plan. Optionally pass from_stage_id (list_job_stages_for_job → match by name) to only advance applications currently in that stage — others are skipped. Rejected, hired or prospect applications are skipped. Processes sequentially with rate-limit delays.
Inputs: application_ids (required), from_stage_id. Returns: result
bulk_create_job_openingsA
Create many openings in one asynchronous request. Write operation — admin only.
Returns bulk_action_uuid and status; check progress with get_bulk_request_status. For one opening use create_job_opening.
Inputs: openings (required), callback_url. Returns: result
bulk_delete_job_openingsA
Delete many openings in one asynchronous request. Destructive — cannot be undone.
Returns bulk_action_uuid; check progress with get_bulk_request_status.
Inputs: opening_ids (required), callback_url. Returns: result
bulk_rejectA
Reject multiple applications in one call. Write operation — rate-limited.
Users say "reject everyone who's been inactive for 30 days on the Backend role." First use stale_applications to identify the targets, then pass their application_ids here. rejection_reason_id is required: list_rejection_reasons → match by name. To email candidates, set rejection_email=true and pass email_template_id (list_email_templates). Processes sequentially with rate-limit delays.
Inputs: application_ids (required), rejection_reason_id (required), notes, rejection_email, +2 more. Returns: result
bulk_tagA
Tag multiple candidates in one call. Write operation — rate-limited.
Users say "tag all the candidates from the hiring event." Pass candidate_ids from search or pipeline tools and a tag_name (created automatically if new). Candidates who already have the tag are skipped. Processes sequentially with rate-limit delays.
Inputs: tag_name (required), candidate_ids (required). Returns: result
bulk_update_job_openingsA
Update or close many openings in one asynchronous request. Write operation.
Use to close all of a job's openings at once (list_job_openings → ids). Returns bulk_action_uuid; check progress with get_bulk_request_status.
Inputs: openings (required), callback_url. Returns: result
candidates_needing_actionA
Find candidates that need attention — stale apps, missing scorecards. Read-only.
Users say "what needs my attention?" or "who's been sitting too long?" Pass job_id for one job (list_jobs → match by name) or omit for all active applications. Returns stale applications sorted by urgency and interviews awaiting feedback, with the interviewers whose scorecards are still missing.
Inputs: job_id, stale_days. Returns: result
change_user_permission_levelA
Demote a user to Basic, revoking all their permissions. Write operation — admin only.
Removes the user's Site Admin status and every job-level permission (Greenhouse "revoke permissions"). Promoting a user is not possible via the API — grant job roles with add_job_permission instead. To find user_id: list_users → match by name or email.
Inputs: user_id (required), permission_level. Returns: result
convert_prospectA
Convert a sourced prospect into an active candidate on a job. Write operation.
Users say "move this prospect into the Backend pipeline." The prospect's application_id comes from their prospect record (get_candidate → applications array, where prospect is true). Target job_id from list_jobs → match by name.
Inputs: job_id (required), application_id (required), initial_stage_id. Returns: result
create_applicationA
Apply an existing candidate to a job. Write operation.
Users say "add Sarah to the Backend Engineer role." Resolve both IDs first: candidate — search_candidates_by_name; job — list_jobs → match by name. The candidate must already exist (create_candidate can also create the candidate and application in one step). Attachments are uploaded to the new application afterwards; their results are under attachment_results. For sourced prospects, use add_prospect. For partner submissions, use post_candidate.
Inputs: job_id (required), candidate_id (required), source_id, attachments, +4 more. Returns: result
create_candidateA
Create a new candidate record, optionally applying them to a job. Write operation.
Users say "add a new candidate — Jane Doe at Acme Corp for the Backend role." Check for duplicates first with search_candidates_by_name or search_candidates_by_email. Pass job_id (list_jobs) to create the application in the same call; the response then has both candidate and application. Without job_id, use create_application afterwards. For sourced prospects, use add_prospect instead.
Inputs: last_name (required), first_name (required), tags, title, +11 more. Returns: result
create_custom_fieldB
Create a new custom field definition. Write operation — admin only.
Defines a new field available on candidates, applications, jobs, offers, openings or users.
Inputs: name (required), field_type (required), value_type (required), options, +3 more. Returns: result
create_custom_field_optionsA
Add dropdown options to a custom field. Write operation — admin only.
To find custom_field_id: list_custom_fields → match by name. Up to 50 options are created immediately and returned; larger lists are sent as an asynchronous Greenhouse bulk request.
Inputs: options (required), custom_field_id (required). Returns: result
create_departmentA
Create a new department. Write operation — admin only.
For parent_id (optional): list_departments → find parent by name.
Inputs: name (required), parent_id, external_id. Returns: result
create_interviewA
Record a scheduled interview for an application. Write operation.
Users say "schedule an interview for Sarah on the Backend role." To get application_id: search_candidates_by_name → list_applications(candidate_id=...) → match app. For interviewer_ids: list_users → match by name. interview_id is the job interview from list_job_stages_for_job (interviews[].id). This records the interview in Greenhouse; it does not send calendar invites.
Inputs: end (required), start (required), interview_id (required), application_id (required), +4 more. Returns: result
create_jobA
Create a new job from a template. Write operation — admin only.
Users say "create a new Backend Engineer role." Requires template_job_id — use list_jobs to find a similar existing job. For department_id: list_departments → match by name. For office_ids: list_offices → match. After creation, use update_job_post to set the public listing content.
Inputs: template_job_id (required), notes, job_name, office_ids, +6 more. Returns: result
create_job_openingA
Add a new headcount to a job. Write operation.
Users say "add another opening to the Backend role." To find job_id: list_jobs → match by name. Openings are created open; with status='closed' the new opening is closed straight after (with close_reason_id if given).
Inputs: job_id (required), status, opening_id, custom_fields, +1 more. Returns: result
create_officeA
Create a new office. Write operation — admin only.
For parent_id (optional): list_offices → find parent by name. For the contact: list_users → match by name.
Inputs: name (required), location, parent_id, primary_contact_user_id. Returns: result
create_or_replace_approval_flowA
Create or replace an approval flow for a job. Write operation — overwrites existing.
If the job already has a flow of this approval_type, its approver groups are replaced; otherwise a new flow is created (pending — call request_approvals to start it). To find job_id: list_jobs → match by name. For approver user IDs: list_users → match by name.
Inputs: job_id (required), approval_type (required), approver_groups (required), sequential. Returns: result
create_tagA
Create a new candidate tag. Write operation.
After creating, use add_tag_to_candidate to apply it. Note: bulk_tag creates tags on-the-fly, so pre-creation isn't needed for bulk ops.
Inputs: name (required). Returns: result
create_userA
Create a new Greenhouse user account. Write operation — admin only.
After creating, use add_job_permission to grant access to specific jobs, or add_future_job_permission for automatic access to new jobs.
Inputs: email (required), last_name (required), first_name (required), job_title, +3 more. Returns: result
delete_applicationA
Permanently delete an application. Destructive — cannot be undone.
To find the application_id: search_candidates_by_name → get_candidate → match the application to the job. Consider reject_application instead — it preserves history and can be reversed with unreject_application.
Inputs: application_id (required). Returns: result
delete_candidateA
Permanently delete a candidate and all their applications. Destructive — cannot be undone.
To get the candidate_id: search_candidates_by_name → get_candidate. For GDPR compliance, consider anonymize_candidate instead — it preserves the record while removing personal data.
Inputs: candidate_id (required). Returns: result
delete_custom_fieldA
Delete a custom field and all its values. Destructive — cannot be undone. Admin only.
To find custom_field_id: list_custom_fields → match by name.
Inputs: custom_field_id (required). Returns: result
delete_custom_field_optionsA
Delete dropdown options from a custom field. Destructive — cannot be undone. Admin only.
To find custom_field_id: list_custom_fields → match by name. For option IDs: list_custom_field_options → match by name. Historical selections keep the (now inactive) option. Up to 50 options are deleted immediately; larger lists use an asynchronous bulk request.
Inputs: option_ids (required), custom_field_id (required). Returns: result
delete_interviewA
Cancel a scheduled interview. Write operation — cannot be undone.
To find interview_id: list_interviews_for_application on the candidate's app.
Inputs: interview_id (required). Returns: result
delete_job_openingA
Delete a job opening. Destructive — cannot be undone.
To find job_id: list_jobs → match by name. To find opening_id: list_job_openings on the job.
Inputs: job_id (required), opening_id (required). Returns: result
delete_tagA
Delete a tag from the organization. Destructive — removes it from all candidates.
To find tag_id: list_tags → match by name.
Inputs: tag_id (required). Returns: result
disable_userA
Deactivate (disable) a Greenhouse user, preventing login. Write operation.
Users say "deactivate John's account." To find user_id: list_users → match by name or email. Can be reversed with enable_user. Returns {"success": true} on success.
Inputs: user_id (required). Returns: result
download_attachmentA
Download content from a Greenhouse attachment URL. Read-only.
Use when you have a specific attachment URL from a candidate or application record (e.g., get_candidate's or get_application's attachments array). Attachment URLs are time-limited — if a download fails, fetch the record again for a fresh URL.
Inputs: url (required). Returns: result
enable_userA
Re-activate (enable) a previously deactivated user. Write operation.
To find user_id: list_users → match by name or email. Returns {"success": true} on success.
Inputs: user_id (required). Returns: result
fetch_new_applicationsA
Applications since a date, grouped by job — the daily digest. Read-only.
Users say "what new applications came in since yesterday?" Pass since as an ISO date (applications created on or after it). Optionally filter to one job with job_id (list_jobs → match by name). Returns applications grouped by job with candidate names, sources, stages, and screening answers.
Inputs: since (required), job_id, status, include_candidate_details. Returns: result
get_activity_feedA
Get a candidate's activity timeline. Read-only.
Users say "show me Sarah's history" or "what's happened with this candidate?"
To find candidate_id: search_candidates_by_name. Returns three lists,
newest first: notes (notes, interviews, follow-ups and other entries),
emails (logged emails with subject, email_from/email_to/email_cc), and
activities (system events such as stage changes). Every entry has
type, body, created_at, application_id, visibility and user
({id, name}) when a person wrote it.
Inputs: candidate_id (required), created_after. Returns: result
get_answerA
Get a single demographic survey response by ID. Read-only.
To find IDs: list_answers or list_answers_for_application.
Inputs: answer_id (required). Returns: result
get_answer_optionA
Get a demographic answer option by ID. Read-only.
To find IDs: list_answer_options or list_answer_options_for_question.
Inputs: answer_option_id (required). Returns: result
get_applicationA
Get a single application by ID. Read-only.
Returns the application with job_name, its current stage (stage_name and job_interview_stage_id — the from_stage_id for moves), status, source_id, rejection_reason_id, custom fields, and its attachments (resume etc., with time-limited download URLs). Users rarely know application IDs. To find one: search_candidates_by_name → get_candidate → the applications array has each application's ID and job name. For a complete screening package with resume and location, use screen_candidate.
Inputs: application_id (required). Returns: result
get_approval_flowA
Get a specific approval flow for a job. Read-only.
Returns flow type, approval_status, and approver groups with their approvers. To find job_id: list_jobs → match by name. For approval_flow_id: list_approvals_for_job.
Inputs: job_id (required), approval_flow_id (required). Returns: result
get_boardA
Get job board metadata — name, content, departments, offices. Read-only.
Returns the public-facing board info. For internal job management, use list_jobs instead.
Inputs: no named parameters. Returns: result
get_board_departmentB
Get a department from the public job board. Read-only.
Inputs: department_id (required). Returns: result
get_board_jobA
Get a published job with optional application questions. Read-only.
For internal job details (hiring team, custom fields), use get_job instead.
Inputs: job_id (required), questions. Returns: result
get_board_officeB
Get an office from the public job board. Read-only.
Inputs: office_id (required). Returns: result
get_bulk_request_statusA
Check the progress of any v3 bulk request. Read-only.
Use after a bulk tool returns a bulk_action_uuid (bulk job openings, custom field options in batches over 50). Returns status (building/pending/in_progress/completed/failed), record_count, success_count, failure_count, and short-lived result URLs.
Inputs: bulk_action_uuid (required). Returns: result
get_candidateA
Get a candidate's full profile by ID. Read-only.
Returns name, contact info, tags, custom fields, plus (fetched alongside, since v3 no longer embeds them) applications (each with id, job_id, job_name, stage_name, job_interview_stage_id, status), attachments (with time-limited download URLs), educations (with school/degree/discipline names) and employments. This is the central lookup — most workflows route through here after resolving a name via search_candidates_by_name. For a screening package with resume and location, use screen_candidate.
Inputs: candidate_id (required), include_related. Returns: result
get_current_offerA
Get the current (latest version) offer for an application. Read-only.
Returns 404 if the application has no offer. To find application_id: search_candidates_by_name → list_applications(candidate_id=...) → match the application to the job.
Inputs: application_id (required). Returns: result
get_custom_fieldA
Get a custom field definition by ID. Read-only.
Returns field name, name_key, field type, value type, and configuration.
For single/multi-select fields, custom_field_options lists the
dropdown options. To find custom_field_id: list_custom_fields → match by name.
Inputs: custom_field_id (required). Returns: result
get_departmentA
Get a department by ID. Read-only.
Returns name, parent_id, external_id, and child_ids (direct child
departments). To find department_id: list_departments → match by name.
Inputs: department_id (required). Returns: result
get_eeoc_for_applicationA
Get EEOC data for a specific application. Read-only.
To find application_id: search_candidates_by_name → list_applications(candidate_id=...) → match the application to the job.
Inputs: application_id (required). Returns: result
get_email_templateA
Get an email template by ID. Read-only.
Returns template name, subject, body or html_body, email_type and sender settings. To find template_id: list_email_templates → match by name.
Inputs: email_template_id (required). Returns: result
get_hiring_teamA
Get the hiring team for a job. Read-only.
Users say "who's on the hiring team for Backend Engineer?" To find job_id:
list_jobs → match by name. Returns members grouped by role:
hiring_managers, recruiters, coordinators and sourcers. Each member has
id (user ID), name, first_name, last_name, employee_id, responsible
(recruiters/coordinators) and assignment_id.
Inputs: job_id (required). Returns: result
get_interviewA
Get a scheduled interview by ID. Read-only.
Returns details: application, interview name, interviewers, organizer, times, location, and status. To find interview IDs: list_interviews_for_application on the candidate's app.
Inputs: interview_id (required). Returns: result
get_jobA
Get full details for a job by ID. Read-only.
Returns name, status, requisition_id, notes, custom fields, department and offices ({id, name}), openings, and the hiring team (hiring_managers, recruiters, coordinators, sourcers as {id, name, email}). Use list_jobs to find the job_id by name first. For the public listing, use list_job_posts_for_job. For pipeline stages, use list_job_stages_for_job.
Inputs: job_id (required). Returns: result
get_job_openingA
Get a specific opening on a job. Read-only.
Returns open/status, close_reason_id, custom fields, and the hired application_id if filled. To find job_id: list_jobs → match by name. To find opening_id: list_job_openings on the job.
Inputs: job_id (required), opening_id (required). Returns: result
get_job_postA
Get a job post by ID. Read-only.
Returns title, content (HTML), live status, job_id, job_board_id, public_url, application questions, and locations. To find post IDs: list_job_posts_for_job.
Inputs: job_post_id (required). Returns: result
get_job_post_custom_locationsA
Get the custom-list locations selected on a job post. Read-only.
Custom locations are per-job-board dropdown values. Returns {"items": [{id, value, active, greenhouse_job_board_id, job_post_location_id}]}. For all of a post's locations (free text, office, custom), use get_job_post. To find job_post_id: list_job_posts_for_job.
Inputs: job_post_id (required). Returns: result
get_job_post_for_jobA
Get a specific job post scoped to a job. Read-only.
Same as get_job_post, but returns 404 if the post doesn't belong to the job. To find job_id: list_jobs → match by name. To find post_id: list_job_posts_for_job.
Inputs: job_id (required), job_post_id (required). Returns: result
get_job_stageA
Get a single stage by ID. Read-only.
Returns stage name, sort_order, job_id, and its configured interviews. Usually list_job_stages_for_job is more useful — it gives all stages in pipeline order.
Inputs: job_stage_id (required). Returns: result
get_offerA
Get a single offer by ID. Read-only.
Returns offer status, version, starts_on, sent_on, resolved_at, opening_id, and custom fields.
Inputs: offer_id (required). Returns: result
get_officeA
Get an office by ID. Read-only.
Returns name, location, parent_id, and child_ids (direct child
offices). To find office_id: list_offices → match by name.
Inputs: office_id (required). Returns: result
get_prospect_poolA
Get a prospect pool and its stages by ID. Read-only.
To find prospect_pool_id: list_prospect_pools → match by name.
Inputs: prospect_pool_id (required). Returns: result
get_prospect_post_sectionB
Get a prospect post section by ID. Read-only.
Inputs: section_id (required). Returns: result
get_questionA
Get a demographic question by ID. Read-only.
To find IDs: list_questions or list_questions_for_question_set.
Inputs: question_id (required). Returns: result
get_question_setA
Get a demographic question set by ID. Read-only.
To find IDs: list_question_sets.
Inputs: question_set_id (required). Returns: result
get_scorecardA
Get a single scorecard by ID. Read-only.
Returns the interviewer, interview, attribute ratings, question answers, notes, and overall recommendation (candidate_rating). To find scorecard IDs: list_scorecards_for_application.
Inputs: scorecard_id (required). Returns: result
get_tracking_linkA
Get a tracking link by its token. Read-only.
Returns the link's source_id, referrer_id, job_id, job_board_id and
job_post_id, plus source ({id, name, type}) resolved from the source.
The token is the gh_src value from the tracking URL.
Inputs: token (required). Returns: result
get_userA
Get a Greenhouse user's profile by ID. Read-only.
Returns name, primary_email, emails (all addresses with verified flag),
site_admin, deactivated status, and the user's offices and departments
(with names). To find user_id:
list_users → match by name or email. For job-level access, see
list_job_permissions.
Inputs: user_id (required). Returns: result
hire_applicationA
Mark a candidate as hired. Write operation — finalizes the hiring decision.
Users say "hire Sarah for the Backend role." To get the application_id: search_candidates_by_name → get_candidate → match the application to the job. Optionally fills a job opening (opening_id from list_job_openings) and records a close reason (close_reason_id from list_close_reasons).
Inputs: application_id (required), opening_id, start_date, close_reason_id. Returns: result
list_answer_optionsB
List all demographic answer options across all questions. Read-only.
Each option has name, demographic_question_id, free_form, decline_to_answer, active and sort_order.
Inputs: no named parameters. Returns: result
list_answer_options_for_questionA
List answer options for a specific demographic question. Read-only.
To find question_id: list_questions or list_questions_for_question_set.
Inputs: question_id (required). Returns: result
list_answersA
List all demographic survey responses submitted by candidates. Read-only.
Each answer has application_id, demographic_question_id, demographic_answer_option_id and free_form_text. Resolve labels with list_questions and list_answer_options.
Inputs: cursor, paginate, per_page, created_after. Returns: result
list_answers_for_applicationA
List demographic responses for a specific application. Read-only.
To find application_id: search_candidates_by_name → list_applications(candidate_id=...) → match the application to the job.
Inputs: application_id (required). Returns: result
list_applicationsA
List applications with optional filters. Read-only.
Users say "show me applications for [job name]" or "what came in this week." To filter by job: list_jobs → find by name → use its job_id. To filter by candidate: search_candidates_by_name → candidate_id. Each application has job_id + job_name, the current stage (stage_name, and job_interview_stage_id for moves), status ('in_process', 'rejected', 'hired', 'converted'), source_id, recruiter_id/coordinator_id, rejection_reason_id and created_at (the applied date). For pipeline views grouped by stage, use pipeline_summary. For stale candidates, use stale_applications or candidates_needing_action.
Inputs: cursor, job_id, status, paginate, +5 more. Returns: result
list_approvals_for_jobA
List approval flows for a job. Read-only.
To find job_id: list_jobs → match by name. Each flow has approval_type
(open_job, offer_job, offer_candidate), approval_status, sequential,
requested_by_id, and approver_groups (ordered by sort_order), each with
approvers (user_id, user_name, status: waiting/due/approved/rejected).
Inputs: job_id (required). Returns: result
list_board_degreesA
List degree types for board application forms. Read-only.
Provides the degree dropdown options shown to external applicants.
Inputs: no named parameters. Returns: result
list_board_departmentsA
List departments on the public job board. Read-only.
For internal department management, use list_departments instead.
Inputs: no named parameters. Returns: result
list_board_disciplinesA
List academic disciplines for board application forms. Read-only.
Provides the discipline dropdown options shown to external applicants.
Inputs: no named parameters. Returns: result
list_board_jobsA
List all published jobs on the public job board. Read-only.
Returns jobs visible to external candidates. For internal job data with pipeline info, use list_jobs instead.
Inputs: content. Returns: result
list_board_officesA
List offices on the public job board. Read-only.
For internal office management, use list_offices instead.
Inputs: no named parameters. Returns: result
list_board_schoolsA
List schools for board application forms. Read-only.
Provides the school dropdown options shown to external applicants.
Inputs: no named parameters. Returns: result
list_candidatesA
List candidates with optional filters. Read-only.
For finding a specific person, use search_candidates_by_name (by name) or search_candidates_by_email (by email) — faster and simpler. Use this tool for bulk operations: date-range queries, fetching by specific IDs, or paginating through the full database. Created and updated date filters can't be combined in one call. Candidates here are profile-only (no applications or attachments) — use get_candidate or list_applications(candidate_id=...) for those.
Inputs: tag, email, cursor, paginate, +6 more. Returns: result
list_close_reasonsA
List all close reasons for job openings. Read-only.
Resolves close reason names to IDs for hire_application and update_job_opening.
Inputs: cursor, per_page, force_refresh. Returns: result
list_custom_field_optionsA
List dropdown options for a custom field. Read-only.
To find custom_field_id: list_custom_fields → match by name. Options
have sort_order (was priority) and are returned in that order.
Inputs: custom_field_id (required), active. Returns: result
list_custom_fieldsA
List all custom field definitions. Read-only.
Resolves custom field names to IDs. When a user mentions a custom field
by name, use this to find its ID (or name_key) for update_candidate,
update_application, or update_current_offer. Filter by field_type to
narrow results. Dropdown options are separate: list_custom_field_options.
Inputs: active, field_type. Returns: result
list_degreesA
List degree types (Bachelor's, Master's, PhD, etc.). Read-only.
Resolves degree names to IDs (degree_id) for add_education. Each item is a custom field option with id and name.
Inputs: cursor, paginate, per_page, force_refresh. Returns: result
list_departmentsA
List all departments. Read-only.
Resolves department names to IDs. When a user mentions a department
("Engineering"), use this to find its ID for list_jobs, create_job,
or add_future_job_permission. Each department has parent_id (null for
top level); rebuild the tree from parent_id.
Inputs: cursor, paginate, per_page, parent_id, +1 more. Returns: result
list_disciplinesA
List academic disciplines (Computer Science, Business, etc.). Read-only.
Resolves discipline names to IDs (discipline_id) for add_education. Each item is a custom field option with id and name.
Inputs: cursor, paginate, per_page, force_refresh. Returns: result
list_eeocA
List all EEOC data collected from applications. Read-only.
Compliance data — self-reported race, gender, veteran, and disability status ({id, description} each). Used for federal reporting, not for hiring decisions.
Inputs: cursor, paginate, per_page, submitted_after, +1 more. Returns: result
list_email_templatesA
List all email templates. Read-only.
Resolves template names to IDs. When a user wants to send a rejection email, use this (email_type='candidate_rejection') to find the template ID for reject_application's rejection_email parameter.
Inputs: cursor, per_page, email_type, force_refresh. Returns: result
list_future_job_permissionsA
List auto-apply permission rules for a user. Read-only.
These rules automatically grant the user a role on new jobs matching
criteria (office_id, department_id; null = any). Rows carry role_id
and role_name. To find user_id: list_users → match by name.
Inputs: user_id (required). Returns: result
list_interviewsA
List scheduled interviews across all applications. Read-only.
Each interview has id, application_id, job_id, starts_at/ends_at (or all_day_start_on/all_day_end_on), status, location, video_conferencing_url, plus (with include_details) interview {id, name}, interviewers [{id, name, email, response_status, scorecard_id}] and organizer. For a specific candidate's interviews, use list_interviews_for_application (search_candidates_by_name → list_applications(candidate_id=...) → match the application → use its ID).
Inputs: cursor, job_id, status, paginate, +6 more. Returns: result
list_interviews_for_applicationA
List scheduled interviews for a specific application. Read-only.
To find the application_id: search_candidates_by_name → list_applications(candidate_id=...) → match the application to the job. Returns all interviews with times, interview name, interviewers (with their scorecard_id), and status.
Inputs: application_id (required). Returns: result
list_job_openingsA
List openings (headcount) for a job. Read-only.
An opening represents one position to fill — a job can have multiple. Each opening has id, opening_id (external ID), open (bool) and status ('open'/'closed'), close_reason_id, application_id (the hire, if filled), target_start_on, and custom_fields. To find job_id: list_jobs → match by name.
Inputs: job_id (required), status. Returns: result
list_job_permissionsA
List all job-level permissions for a user. Read-only.
To find user_id: list_users → match by name or email. Each row has its
own id (needed for remove_job_permission), job_id, role_id (was
user_role_id), role_name, and automated (true when created by a
future-job rule). Site admins have no rows — they can access every job.
Inputs: user_id (required). Returns: result
list_job_postsA
List all job posts (public listings) across all jobs. Read-only.
A job post is the public-facing listing for a job. Each post includes its application form questions and a locations array (a post can have several locations in v3). For posts on a specific job, use list_job_posts_for_job (job_id from list_jobs → match by name).
Inputs: live, cursor, internal, paginate, +1 more. Returns: result
list_job_posts_for_jobA
List job posts for a specific job. Read-only.
To find job_id: list_jobs → match by name. Returns the public listing(s) including title, content, live status, public_url, application questions, and locations.
Inputs: job_id (required). Returns: result
list_jobsA
List all jobs with optional filters. Read-only.
This is the primary tool for resolving job titles to job IDs. When a user mentions a job by name ("Backend Engineer"), use this to find the matching job_id. Filter by status ('open'/'closed'/'draft'), department_id (list_departments), or office_id (list_offices). Each job includes department and offices as {id, name}. Openings are not embedded — use list_job_openings; the hiring team is on get_job. For pipeline views, use pipeline_summary with the job_id.
Inputs: cursor, status, paginate, per_page, +5 more. Returns: result
list_job_stagesA
List all job stages across all jobs. Read-only.
Returns stage id, job_id, name, sort_order, and active. For stages on a specific job in pipeline order (with their interviews), use list_job_stages_for_job instead — it's more useful for resolving stage names to IDs.
Inputs: active, cursor, paginate, per_page. Returns: result
list_job_stages_for_jobA
List pipeline stages for a specific job in order. Read-only.
This is the primary tool for resolving stage names to stage IDs. When a user says "move to the onsite stage," use this to find the stage_id (the job_interview_stage_id used by move/advance). Stages are sorted by sort_order, and each has an interviews array (the stage's configured interviews — their id is the interview_id that create_interview expects; scheduling_type 'needs_scheduling' means it is a calendared interview). To find the job_id first: list_jobs → match by name.
Inputs: job_id (required), include_inactive. Returns: result
list_offersA
List offers across all applications. Read-only.
Each offer has id, version, application_id, candidate_id, job_id, opening_id, status, starts_on, sent_on, resolved_at, and custom_fields. Every revision is returned (older ones have status 'Deprecated'); set current_only=true for just each application's current offer. For a specific candidate's offers, use list_offers_for_application (search_candidates_by_name → list_applications(candidate_id=...) → match the application → use its ID).
Inputs: cursor, job_id, status, paginate, +4 more. Returns: result
list_offers_for_applicationA
List all offers (every version) made on a specific application. Read-only.
Sorted newest version first. To find application_id: search_candidates_by_name → list_applications(candidate_id=...) → match the application to the job. For the current offer only, use get_current_offer.
Inputs: application_id (required). Returns: result
list_officesA
List all offices. Read-only.
Resolves office/location names to IDs. When a user mentions an office
or location, use this to find its ID for list_jobs, create_job, or
add_future_job_permission. Each office has a flat location string,
parent_id, and primary_in_house_contact_user_id.
Inputs: cursor, paginate, per_page, parent_id, +1 more. Returns: result
list_pending_approvalsA
List all pending approvals for a user (or org-wide). Read-only.
By default returns approvers whose decision is due now. Each item has approver_id, user_id, user_name, status, request_sent_at, job_id, offer_id, approval_type and approval_flow_id. To find user_id: list_users → match by name or email. Omit user_id to see all pending approvals across the organization.
Inputs: user_id, include_waiting. Returns: result
list_prospect_poolsA
List all prospect pools with their stages. Read-only.
Resolves pool names to IDs for add_prospect. Returns each pool's
prospect_stages (ordered) for specifying a starting stage when adding
prospects.
Inputs: active, cursor, paginate, per_page. Returns: result
list_prospect_post_sectionsA
List prospect post sections on the job board. Read-only.
Inputs: no named parameters. Returns: result
list_questionsA
List all demographic survey questions across all sets. Read-only.
Each question has name (the prompt), demographic_question_set_id, required, answer_type and sort_order.
Inputs: no named parameters. Returns: result
list_question_setsA
List all demographic survey question sets. Read-only.
Admin/compliance tool for managing demographic data collection. Each set has title, description, active and enabled.
Inputs: no named parameters. Returns: result
list_questions_for_question_setA
List questions in a specific demographic question set. Read-only.
To find question_set_id: list_question_sets.
Inputs: question_set_id (required). Returns: result
list_rejection_reasonsA
List all rejection reasons. Read-only.
Resolves rejection reason names to IDs. When a user says "reject for
'not enough experience'," use this to find the ID, then pass it to
reject_application or bulk_reject. Each reason's type is an object
{id, key, name} — key is WE_REJECTED_THEM,
THEY_REJECTED_US, NONE_SPECIFIED or SECURITY_CONCERN.
Inputs: cursor, per_page, force_refresh, include_defaults. Returns: result
list_schoolsA
List schools for education records. Read-only.
Resolves school names to IDs (school_id) for add_education. Each item is a custom field option with id and name.
Inputs: cursor, paginate, per_page, force_refresh. Returns: result
list_scorecardsA
List interview scorecards across all applications. Read-only.
Each scorecard has application_id, candidate_rating (also as overall_recommendation), notes, status, interviewed_at, submitted_at and, with include_details, interviewer/submitted_by {id, name, email}, interview name, attributes [{name, rating, note}], ratings grouped by rating, and questions [{question, answer}]. v3 scorecards carry no candidate_id — use application_id. For a specific candidate, use list_scorecards_for_application (search_candidates_by_name → list_applications(candidate_id=...) → match application → use its ID).
Inputs: cursor, status, paginate, per_page, +3 more. Returns: result
list_scorecards_for_applicationA
List scorecards submitted for a specific application. Read-only.
To find application_id: search_candidates_by_name → list_applications(candidate_id=...) → match the application to the job. Returns each interviewer's attribute ratings, question answers, notes and overall recommendation (candidate_rating).
Inputs: application_id (required). Returns: result
list_sourcesA
List all candidate sources (job boards, referrals, agencies). Read-only.
Resolves source names to IDs for create_application and update_application.
When a user mentions where a candidate came from, use this to find the
source_id. Each source has a type object ({id, name}) — the sourcing
strategy it rolls up to (e.g. "Referral", "Agencies").
Inputs: cursor, per_page, force_refresh. Returns: result
list_tagsA
List all candidate tags in the organization. Read-only.
Resolves tag names to IDs. When a user says "tag Sarah as 'strong hire'," use this to find the tag_id, then add_tag_to_candidate.
Inputs: cursor, per_page, force_refresh. Returns: result
list_tags_on_candidateA
List tags on a specific candidate. Read-only.
To find candidate_id: search_candidates_by_name. Each item has the tag
id and name (as in list_tags) plus applied_tag_id, the id of the
tag-on-candidate record.
Inputs: candidate_id (required). Returns: result
list_user_rolesA
List all user roles in the organization. Read-only.
Resolves role names to IDs for add_job_permission and add_future_job_permission. Only roles with role_type 'job_admin' can be granted on jobs.
Inputs: cursor, per_page. Returns: result
list_usersA
List all Greenhouse users (team members, not candidates). Read-only.
This is the primary tool for resolving team member names to user IDs.
When another tool needs a user_id (interviewer, approver, hiring manager),
use this to find the person by name or email. Filter by email for exact
lookup (matches the primary email first, then any secondary address), or
paginate to scan. Each user has deactivated (was disabled),
primary_email, office_ids and department_ids (get_user adds names
and secondary emails).
Inputs: email, cursor, paginate, per_page, +3 more. Returns: result
merge_candidatesA
Merge a duplicate candidate into a primary record. Write operation — cannot be undone.
Users say "these two Sarah Chens are the same person." Find both records with search_candidates_by_name. The duplicate's applications, attachments, notes and tags move to the primary, and the duplicate record is deleted. Returns the merged primary candidate.
Inputs: primary_candidate_id (required), duplicate_candidate_id (required). Returns: result
move_applicationA
Transfer a candidate to a completely different job. Write operation.
Users say "move Sarah from Backend to Frontend Engineer." You need the application_id (search_candidates_by_name → get_candidate → match app) and the new_job_id (list_jobs → match by name). Optionally set a starting stage with new_stage_id (list_job_stages_for_job on the target job). The current stage is looked up automatically unless from_stage_id is given. To move within the SAME job, use move_application_same_job instead.
Inputs: new_job_id (required), application_id (required), new_stage_id, from_stage_id. Returns: result
move_application_same_jobA
Skip a candidate to a specific stage within the same job. Write operation.
Users say "move Sarah straight to the onsite stage" or "skip phone screen." To get the application_id: search_candidates_by_name → get_candidate → match app to job. For stage IDs: list_job_stages_for_job → find by name. The current stage is looked up automatically unless from_stage_id is given. To advance to just the next stage, use advance_application instead.
Inputs: to_stage_id (required), application_id (required), from_stage_id. Returns: result
pipeline_metricsA
Conversion rates and stage metrics for a job. Read-only.
Users say "what are our conversion rates for the Backend role?" or "where are we losing candidates?" To find job_id: list_jobs → match by name. Returns, per interview stage in pipeline order: how many applications ever reached it, how many are there now, % of all applications, stage-to-next conversion, and average days spent in the stage (from stage history).
Inputs: job_id (required). Returns: result
pipeline_summaryA
Complete pipeline view for a job — candidates grouped by stage. Read-only.
Users say "show me the pipeline for Backend Engineer" or "how many candidates are in each stage." To find the job_id: list_jobs → match by name. Returns the job's interview stages in pipeline order, each with its active candidates: names, source, days in the current stage, and days since last activity. One call replaces 5-10 sequential API calls.
Inputs: job_id (required). Returns: result
post_candidateA
Submit a candidate via the Ingestion API (partner integration). Write operation.
For internal candidate creation (as recruiter/admin), use create_candidate and create_application instead. This is the partner/integration endpoint.
Inputs: email (required), last_name (required), first_name (required), phone, +4 more. Returns: result
post_tracking_linkB
Create a tracking link for source attribution on a job. Write operation.
Generates a URL that attributes future applications to this source.
Inputs: job_id (required), source (required), referrer. Returns: result
read_candidate_resumeA
Download and return a candidate's most recent resume text. Read-only.
Users say "pull up Sarah's resume" or "show me John's CV." To find candidate_id: search_candidates_by_name. Returns extracted text from the most recently uploaded resume across all the candidate's applications. For batch reading, use batch_read_resumes.
Inputs: candidate_id (required). Returns: result
reject_applicationA
Reject a candidate from a job. Write operation.
Users say "reject Sarah from the Backend role." To get the application_id: search_candidates_by_name → get_candidate → match the application to the job. A rejection_reason_id is required: list_rejection_reasons → match by name. For email templates: list_email_templates; the email is sent from email_from_user_id, defaulting to the configured Greenhouse user. Can be reversed with unreject_application. For bulk rejections, use bulk_reject.
Inputs: application_id (required), rejection_reason_id (required), notes, rejection_email. Returns: result
remove_educationA
Remove an education entry from a candidate. Write operation.
To find candidate_id: search_candidates_by_name. For education_id: get_candidate → check the educations array. Checks the record belongs to this candidate before deleting it.
Inputs: candidate_id (required), education_id (required). Returns: result
remove_employmentA
Remove an employment entry from a candidate. Write operation.
To find candidate_id: search_candidates_by_name. For employment_id: get_candidate → check the employments array. Checks the record belongs to this candidate before deleting it.
Inputs: candidate_id (required), employment_id (required). Returns: result
remove_future_job_permissionA
Revoke a future job permission rule. Write operation — admin only.
To find user_id: list_users → match by name. For the permission ID: list_future_job_permissions for the user. The permission ID alone identifies the rule; user_id is accepted for context.
Inputs: user_id (required), future_job_permission_id (required). Returns: result
remove_hiring_team_memberA
Remove someone from a job's hiring team. Write operation.
Removes the user from every hiring-team role they hold on the job. To find job_id: list_jobs → match by name. For user_id: list_users → match by name, or get_hiring_team to see current members and their IDs.
Inputs: job_id (required), user_id (required). Returns: result
remove_job_permissionA
Revoke a user's job-level permission. Write operation — admin only.
To find user_id: list_users → match by name. For the permission ID: list_job_permissions for the user → match the job. The permission ID alone identifies the row; user_id is accepted for context.
Inputs: user_id (required), job_permission_id (required). Returns: result
remove_job_post_locationA
Remove a location from a job post. Write operation.
To find job_post_location_id: get_job_post → locations[].id.
Inputs: job_post_location_id (required). Returns: result
remove_tag_from_candidateA
Remove a tag from a candidate. Write operation.
For candidate_id: search_candidates_by_name. For tag_id: list_tags_on_candidate → find the tag, or list_tags → match by name.
Inputs: tag_id (required), candidate_id (required). Returns: result
replace_approverA
Replace one approver with another in an approval flow. Write operation.
Users say "swap John for Sarah on the Backend approval." For user IDs: list_users → match by name. For job_id: list_jobs. For approval_flow_id: list_approvals_for_job. The approver being removed must not have approved or rejected yet.
Inputs: job_id (required), add_user_id (required), remove_user_id (required), approval_flow_id (required). Returns: result
replace_hiring_teamA
Replace the hiring team for a job. Write operation — overwrites existing members.
Only the roles you pass are replaced; omitted roles are left alone.
Members missing from a passed list are removed and new ones are added.
To find job_id: list_jobs → match by name. For member user_ids:
list_users → match each person by name. Returns added, removed and
any per-member errors.
Inputs: job_id (required), sourcers, recruiters, coordinators, +1 more. Returns: result
request_approvalsA
Trigger an approval request for a flow on a job. Write operation.
Sends the approval request emails to the first approvers. To find job_id: list_jobs → match by name. For approval_flow_id: list_approvals_for_job.
Inputs: job_id (required), approval_flow_id (required). Returns: result
retrieve_current_userA
Get the current integration partner user. Read-only.
Returns the API user associated with the Ingestion API credentials.
Inputs: no named parameters. Returns: result
retrieve_ingestion_candidatesA
List candidates submitted through the Ingestion API. Read-only.
Shows candidates this integration has submitted. For the full candidate database, use list_candidates instead.
Inputs: page, per_page. Returns: result
retrieve_ingestion_jobsA
List jobs visible to the integration partner. Read-only.
Partner-scoped version of list_jobs. Returns only jobs the integration has been granted access to.
Inputs: page, per_page. Returns: result
retrieve_prospect_poolsA
List prospect pools via the Ingestion API. Read-only.
Partner-scoped version of list_prospect_pools.
Inputs: no named parameters. Returns: result
scan_all_candidatesA
Database-wide candidate search by structured fields. Read-only.
Like search_pipeline_candidates but searches the full database, not just specific pipelines. Use when candidates might be in unexpected pipelines. Pass updated_after to limit scope on large databases (title, company and experience filters fetch employment history for every scanned page). Follow up with batch_read_resumes to validate matches.
Inputs: tags, max_pages, max_results, updated_after, +4 more. Returns: result
scan_pipeline_resumesA
Search resume text in pipelines for skills and qualifications. Read-only.
Users say "find Rust engineers in our pipelines" or "search for distributed systems experience." The primary sourcing tool — ~90% of candidate data lives in resumes. Pass job_ids (list_jobs → get IDs for similar roles). Supports boolean search: keywords (OR), required_keywords (AND), exclude_keywords (NOT with word-boundary matching).
Inputs: job_ids (required), keywords, statuses, max_resumes, +2 more. Returns: result
screen_candidateA
Full screening package for one candidate application. Read-only.
Users say "screen Sarah for the Backend role" or "give me the full picture." To get application_id: search_candidates_by_name → list_applications (candidate_id=...) → match the application to the job name. Returns profile, resume text, location, screening answers, job description, and application history (with job names and rejection reasons) in one call.
Inputs: application_id (required). Returns: result
search_candidates_by_emailA
Look up a candidate by exact email address. Read-only.
Use when the user provides an email instead of a name. Matches any email on the candidate's profile and returns the candidate record. For their applications, follow up with list_applications(candidate_id=...). For name-based lookup, use search_candidates_by_name.
Inputs: email (required). Returns: result
search_candidates_by_nameA
Find candidates by name. Read-only — the starting point for most workflows.
Users always refer to candidates by name, not ID. Use this first whenever a user mentions a candidate, then list_applications(candidate_id=...) to find their application IDs (candidate records don't include applications). Case-insensitive substring match — "Sarah" finds "Sarah Chen", "Sarah O'Brien", etc. Greenhouse has no name filter, so this scans up to max_pages × per_page candidates; if has_more is true, pass next_cursor to keep scanning.
Inputs: name (required), cursor, per_page, max_pages. Returns: result
search_pipeline_candidatesA
Search pipelines by structured fields — title, company, education, tags. Read-only.
Users say "find VP-level candidates in our pipelines" or "who do we have from Google?" Pass job_ids (list_jobs → get IDs for similar roles). Best when structured data (employment and education history) is populated. If few results, switch to scan_pipeline_resumes for resume-text search. Combine with batch_read_resumes to verify skill matches.
Inputs: job_ids (required), tags, statuses, max_results, +4 more. Returns: result
source_effectivenessA
Which candidate sources produce the best results. Read-only.
Users say "which sources are working?" or "where should we spend recruiting budget?" Pass job_id (list_jobs → match by name) for one role, or omit for org-wide analysis. Returns volume, active, rejected, hired and hire rate per source, with each source's strategy (e.g. Referral).
Inputs: job_id, created_after. Returns: result
stale_applicationsA
Applications with no activity for N days, sorted by stalest. Read-only.
Users say "who's been sitting untouched?" Use the results with bulk_reject for pipeline cleanup. Pass job_id (list_jobs → match by name) to filter to one job. Each row includes the current stage and job name.
Inputs: days, limit, job_id. Returns: result
submit_applicationA
Submit an application through the public job board. Write operation.
For internal application creation (as a recruiter/admin), use create_application instead. This endpoint mirrors what external candidates do when they apply through the public board.
Inputs: email (required), job_id (required), last_name (required), first_name (required), +4 more. Returns: result
time_to_hireA
Time-to-hire metrics for hired candidates. Read-only.
Users say "how long does it take to hire?" or "what's our average days-to-offer?" Pass job_id (list_jobs → match by name) for one role, or omit for org-wide metrics. Returns average, median, min, max days from application to hire. The hire date is the accepted offer's resolved date when available, otherwise the application's last activity.
Inputs: job_id, created_after. Returns: result
unreject_applicationA
Reverse a rejection, returning the candidate to active status. Write operation.
Users say "undo the rejection for Sarah" or "bring Sarah back." To get the application_id: search_candidates_by_name → get_candidate → find the rejected application in their applications array.
Inputs: application_id (required). Returns: result
update_applicationA
Update an application's source, referrer, recruiter, coordinator or custom fields. Write operation.
To find the application_id: search_candidates_by_name → get_candidate → match the application to the job. Only updates fields you provide. For source_id: list_sources. For custom field IDs: list_custom_fields. To change a rejection reason, use update_rejection_reason.
Inputs: application_id (required), source_id, referrer_id, recruiter_id, +2 more. Returns: result
update_candidateA
Update a candidate's profile. Write operation — only changes fields you provide.
Users say "update Sarah's title to Senior Engineer." To get the candidate_id: search_candidates_by_name → get_candidate. For custom field IDs: list_custom_fields → match by name. To add or remove a single tag without replacing the list, use add_tag_to_candidate / remove_tag_from_candidate.
Inputs: candidate_id (required), tags, title, company, +5 more. Returns: result
update_current_offerA
Update the current offer on an application. Write operation.
Looks up the application's latest offer version and patches it (start date → starts_on). To find application_id: search_candidates_by_name → list_applications(candidate_id=...) → match the application to the job. For custom field IDs: list_custom_fields.
Inputs: application_id (required), sent_on, starts_at, custom_fields. Returns: result
update_custom_fieldA
Update a custom field's name, privacy or description. Write operation — admin only.
To find custom_field_id: list_custom_fields → match by name. Renaming does not change the field's name_key.
Inputs: custom_field_id (required), name, private, description. Returns: result
update_custom_field_optionsA
Update dropdown options on a custom field. Write operation — admin only.
To find custom_field_id: list_custom_fields → match by name. For option IDs: list_custom_field_options → match by name. Up to 50 options are updated immediately; larger lists use an asynchronous bulk request.
Inputs: options (required), custom_field_id (required). Returns: result
update_departmentA
Update a department's name, parent or external ID. Write operation — admin only.
To find department_id: list_departments → match by name. Greenhouse requires the name on every update, so the current name is kept when name is omitted.
Inputs: department_id (required), name, parent_id, external_id. Returns: result
update_interviewA
Update a scheduled interview's time, interviewers, or location. Write operation.
To find interview_id: list_interviews_for_application on the candidate's app. For new interviewer_ids: list_users → match by name. When replacing interviewers, existing panel members keep their RSVP; new ones start as needs_action.
Inputs: interview_id (required), end, start, location, +2 more. Returns: result
update_jobA
Update a job's name, department, offices, notes, or custom fields. Write operation.
To find job_id: list_jobs → match by name. Only updates fields you provide. For department_id: list_departments. For office_ids: list_offices. To modify the public listing, use update_job_post instead. A job's open/closed status can't be set directly in Harvest v3: close its openings with update_job_opening(status='closed') (list_job_openings to find them).
Inputs: job_id (required), name, notes, status, +6 more. Returns: result
update_job_openingA
Update a job opening's status, target start date, or custom fields. Write operation.
To find job_id: list_jobs → match by name. To find opening_id: list_job_openings on the job. For close_reason_id: list_close_reasons → match by name. Closing a job's last open opening closes the job.
Inputs: job_id (required), opening_id (required), status, custom_fields, +3 more. Returns: result
update_job_postA
Update a job post's title, location, or content. Write operation — admin only.
To find job_post_id: list_job_posts_for_job (job_id from list_jobs → match by name). In v3 locations are separate records: passing location adds it as a free-text location and then removes the post's previous locations. For multiple or office-based locations, use add_job_post_location / remove_job_post_location.
Inputs: job_post_id (required), title, content, location. Returns: result
update_job_post_statusA
Publish or unpublish a job post. Write operation.
Controls visibility on job boards ('offline' sets the post back to draft). To find job_post_id: list_job_posts_for_job (job_id from list_jobs → match by name).
Inputs: status (required), job_post_id (required). Returns: result
update_officeA
Update an office's name, location, parent or contact. Write operation — admin only.
To find office_id: list_offices → match by name. Greenhouse requires the name on every update, so the current name is kept when name is omitted.
Inputs: office_id (required), name, location, parent_id, +1 more. Returns: result
update_rejection_reasonA
Change the rejection reason on an already-rejected application. Write operation.
To find the application_id: search_candidates_by_name → get_candidate → find the rejected application. For the new reason: list_rejection_reasons → match by name. Looks up the application's rejection details record and updates its reason.
Inputs: application_id (required), rejection_reason_id (required). Returns: result
update_userA
Update a user's name, title, primary email, offices or departments. Write operation.
To find user_id: list_users → match by name or email. To make a new address primary, first add it with add_email_to_user and have it verified.
Inputs: user_id (required), job_title, last_name, first_name, +3 more. Returns: result
webhook_create_ruleA
Create a webhook routing rule. Write operation.
Use webhook_list_events to see available event types. Set event_type to '*' to match all events, or a specific type like 'candidate_stage_change'. Use webhook_test_rule to dry-run after creating.
Inputs: event_type (required), action_type (required), action_url, filter_field, +1 more. Returns: result
webhook_delete_ruleB
Delete a webhook routing rule. Write operation.
To find rule_id: webhook_list_rules.
Inputs: rule_id (required). Returns: result
webhook_list_eventsA
List all Greenhouse webhook event types with descriptions. Read-only.
Reference for webhook_create_rule — shows available event types like 'candidate_stage_change', 'hire_candidate', 'new_candidate_application', etc.
Inputs: no named parameters. Returns: object
webhook_list_recentB
List recent webhook events received by the receiver. Read-only.
Shows the latest events captured by the webhook receiver, useful for debugging and verifying webhook delivery.
Inputs: limit. Returns: result
webhook_list_rulesA
List all webhook routing rules. Read-only.
Returns all configured rules with their event types, actions, and status.
Inputs: no named parameters. Returns: result
webhook_setup_guideA
Generate webhook configuration instructions for Greenhouse. Read-only.
Produces the exact values to enter in Greenhouse UI (Configure > Dev Center
Webhooks) and stores the generated secret key in the local database.
Inputs: receiver_url (required), events. Returns: result
webhook_test_ruleA
Dry-run a rule against the most recent matching event. Read-only.
Shows what would happen without actually executing the action. Use after webhook_create_rule or webhook_update_rule to verify behavior. To find rule_id: webhook_list_rules.
Inputs: rule_id (required). Returns: result
webhook_update_ruleB
Update a webhook routing rule. Write operation.
To find rule_id: webhook_list_rules.
Inputs: rule_id (required), active, action_url, event_type, +1 more. Returns: result
Tool Schema Changelog
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
Loading tool schema changelog…
TDQS
Scored across 187 tools
Several tools have overlapping purposes, such as multiple candidate search/scan tools (search_candidates_by_name, search_candidates_by_email, list_candidates, scan_all_candidates, search_pipeline_candidates, scan_pipeline_resumes) and overlapping analytics (pipeline_metrics vs source_effectiveness, candidates_needing_action vs stale_applications). Descriptions provide cross-references and clarifications, but the sheer volume and similarity of some tools still create misselection risk.
Tool names mostly follow a consistent snake_case verb_noun pattern (e.g., list_jobs, get_candidate, create_application, update_interview). A few exceptions exist, such as noun-phrase names (pipeline_summary, candidates_needing_action) and prefixed families (webhook_*, board_*), but the overall convention is predictable and readable.
187 tools is an extreme mismatch for a single MCP server, far exceeding the 50+ threshold that indicates poor scoping. Many tools are thin CRUD wrappers or context-specific duplicates (e.g., board vs internal vs ingestion versions) that could be consolidated into fewer, more versatile tools.
The tool surface covers the entire Greenhouse ATS domain comprehensively: candidates, applications, jobs, interviews, offers, approvals, users, departments, offices, custom fields, tags, sources, rejection reasons, EEOC, webhooks, and ingestion. CRUD lifecycle operations are present for most resources, with no obvious dead ends for core workflows.
Maintenance
Related MCP Connectors
One OAuth connector for your team's remote MCP servers, with Tool Packs, guardrails and logs.
Search 1,000+ recruiting, HR and sales tools: prices, MCP servers, alternatives, ATS links.
MCP server for your apps' tools and custom tools, plus hosted AI agents and approval-gated workflows
isolved and ApplicantPro jobs, tenant discovery, and change detection as an MCP server.
Related MCP Servers
- FlicenseNot gradedqualityDmaintenanceA server implementation that enables interaction with Greenhouse's recruitment and applicant tracking system through Model Context Protocol, providing tools for job listings, candidate management, application filtering, and stage transitions.1-
- AlicenseNot gradedqualityDmaintenanceThis project builds a read-only MCP server. For full read, write, update, delete, and action capabilities and a simplified setup, check out our free CData MCP Server for Greenhouse (beta): https://www.cdata.com/download/download.aspx?sku=PGZK-V&type=betaMIT
- AlicenseNot gradedqualityDmaintenanceEnables querying and managing Greenhouse recruiting data through MCP, including applications, candidates, jobs, and rejection operations.MIT
- AlicenseAqualityBmaintenanceProduction-ready MCP server for Greenhouse ATS that provides comprehensive recruitment tools—screening, pipeline analytics, search, and safe write operations—across read-only, recruiter, and full profiles.33MIT