Glama

多模型顾问

(锵锵四人行)

铁匠徽章

模型上下文协议 (MCP) 服务器可查询多个 Ollama 模型并整合它们的响应,从而针对单个问题提供不同的 AI 视角。这创建了一种“顾问委员会”模式,Claude 可以将多种观点与自身观点相结合,从而提供更全面的答案。

graph TD
    A[Start] --> B[Worker Local AI 1 Opinion]
    A --> C[Worker Local AI 2 Opinion]
    A --> D[Worker Local AI 3 Opinion]
    B --> E[Manager AI]
    C --> E
    D --> E
    E --> F[Decision Made]

Related MCP server: mcp-second-opinion

特征

  • 通过一个问题查询多个 Ollama 模型

  • 为每个模型分配不同的角色/人物

  • 查看系统上所有可用的 Ollama 型号

  • 为每个模型定制系统提示

  • 通过环境变量配置

  • 与 Claude for Desktop 无缝集成

先决条件

  • Node.js 16.x 或更高版本

  • Ollama 已安装并正在运行(请参阅Ollama 安装)

  • Claude 桌面版(提供完整的咨询体验)

安装

通过 Smithery 安装

要通过Smithery自动为 Claude Desktop 安装 multi-ai-advisor-mcp:

npx -y @smithery/cli install @YuChenSSR/multi-ai-advisor-mcp --client claude

手动安装

  1. 克隆此存储库:

    git clone https://github.com/YuChenSSR/multi-ai-advisor-mcp.git 
    cd multi-ai-advisor-mcp
  2. 安装依赖项:

    npm install
  3. 构建项目:

    npm run build
  4. 安装所需的 Ollama 模型:

    ollama pull gemma3:1b
    ollama pull llama3.2:1b
    ollama pull deepseek-r1:1.5b

配置

使用您所需的配置在项目根目录中创建一个.env文件:

# Server configuration
SERVER_NAME=multi-model-advisor
SERVER_VERSION=1.0.0
DEBUG=true

# Ollama configuration
OLLAMA_API_URL=http://localhost:11434
DEFAULT_MODELS=gemma3:1b,llama3.2:1b,deepseek-r1:1.5b

# System prompts for each model
GEMMA_SYSTEM_PROMPT=You are a creative and innovative AI assistant. Think outside the box and offer novel perspectives.
LLAMA_SYSTEM_PROMPT=You are a supportive and empathetic AI assistant focused on human well-being. Provide considerate and balanced advice.
DEEPSEEK_SYSTEM_PROMPT=You are a logical and analytical AI assistant. Think step-by-step and explain your reasoning clearly.

连接到 Claude 桌面版

  1. 找到您的 Claude for Desktop 配置文件:

    • MacOS: ~/Library/Application Support/Claude/claude_desktop_config.json

    • Windows: %APPDATA%\Claude\claude_desktop_config.json

  2. 编辑文件以添加多模型顾问 MCP 服务器:

{
  "mcpServers": {
    "multi-model-advisor": {
      "command": "node",
      "args": ["/absolute/path/to/multi-ai-advisor-mcp/build/index.js"]
    }
  }
}
  1. 将/absolute/path/to/替换为项目目录的实际路径

  2. 重启 Claude 桌面版

用法

连接到 Claude for Desktop 后,您可以通过多种方式使用多模型顾问:

列出可用模型

您可以看到系统上所有可用的模型:

Show me which Ollama models are available on my system

这将显示所有已安装的 Ollama 模型并指示哪些模型配置为默认模型。

基本用法

只需要求 Claude 使用多模型顾问:

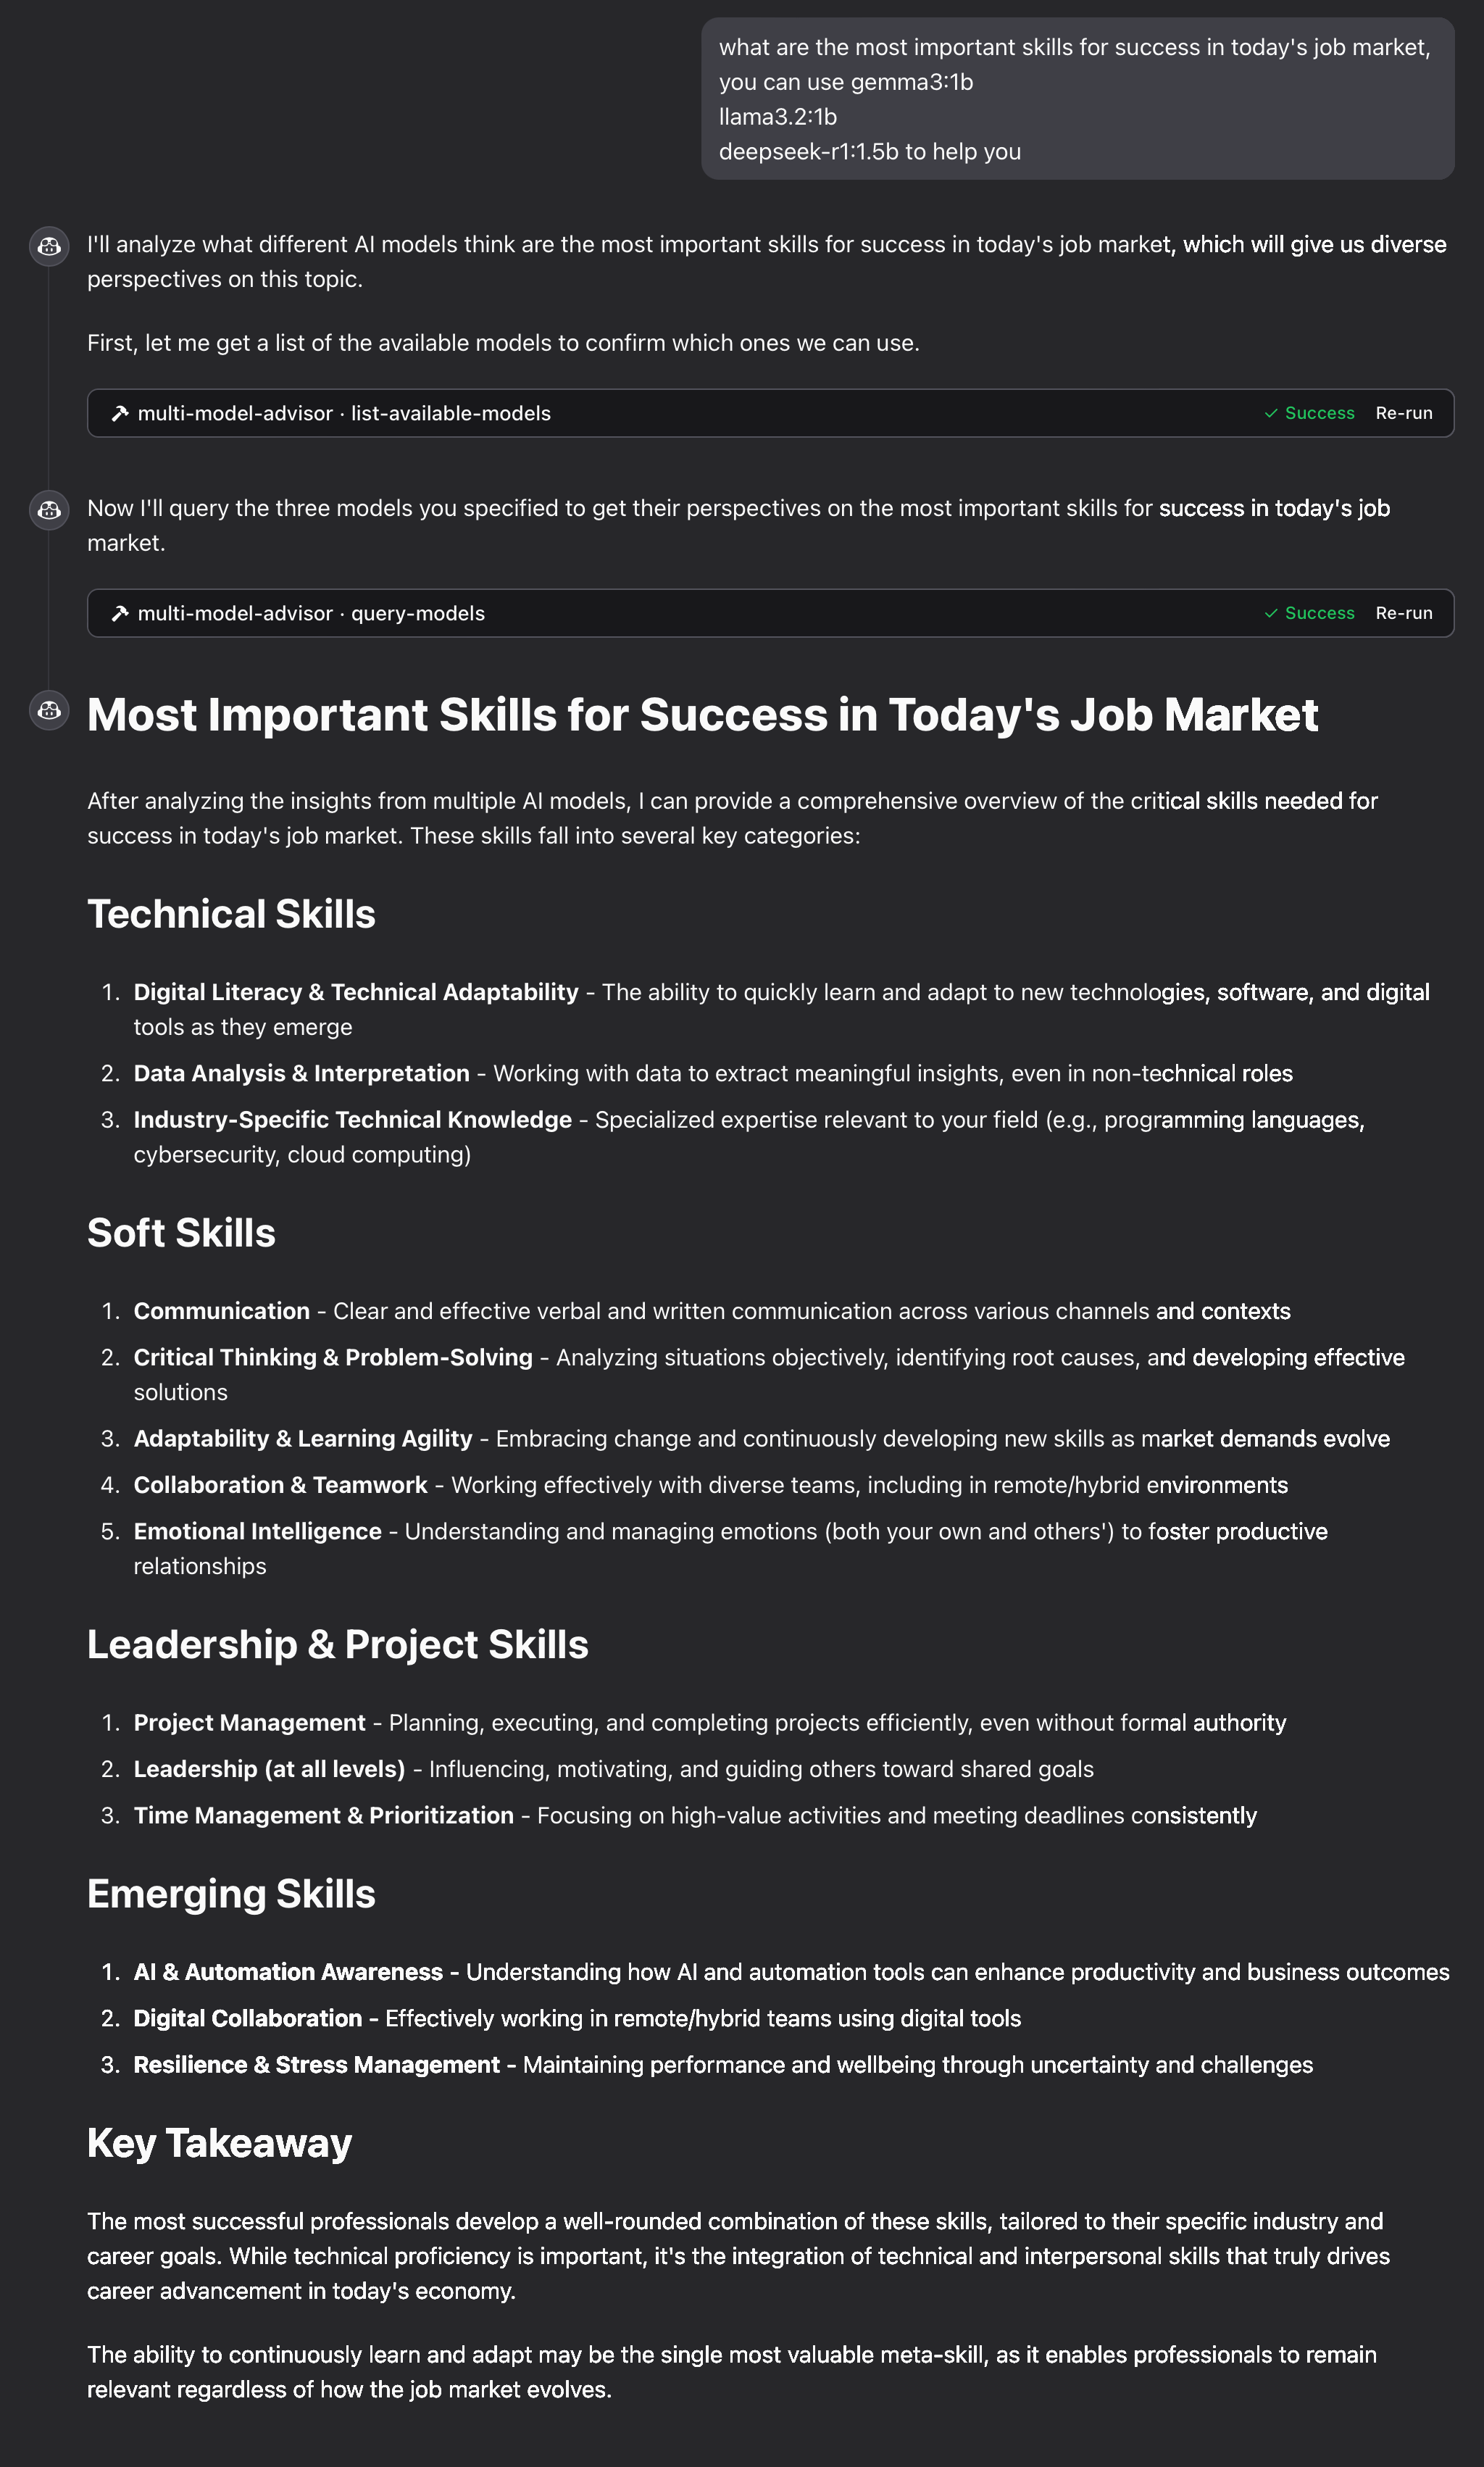
what are the most important skills for success in today's job market, 
you can use gemma3:1b, llama3.2:1b, deepseek-r1:1.5b to help you 

Claude 将查询所有默认模型并根据它们的不同观点提供综合响应。

例子

工作原理

  1. MCP 服务器公开了两个工具:

    • list-available-models :显示系统上的所有 Ollama 模型

    • query-models :使用问题查询多个模型

  2. 当你向克劳德询问有关多模型顾问的问题时:

    • Claude 决定使用query-models工具

    • 服务器将您的问题发送给多个 Ollama 模型

    • 每个模型都以其视角做出回应

    • 克劳德收到所有回复并综合出一个全面的答案

  3. 每个模型可以分配不同的“角色”或作用,以鼓励不同的观点。

故障排除

Ollama连接问题

如果服务器无法连接到 Ollama:

  • 确保 Ollama 正在运行( ollama serve )

  • 检查 .env 文件中的 OLLAMA_API_URL 是否正确

  • 尝试在浏览器中访问http://localhost:11434来验证 Ollama 是否响应

未找到模型

如果报告某个模型不可用:

  • 检查您是否已使用ollama pull <model-name>拉取模型

  • 使用ollama list验证确切的模型名称

  • 使用list-available-models工具查看所有可用模型

Claude 未显示 MCP 工具

如果 Claude 中没有出现这些工具:

  • 确保在更新配置后重新启动 Claude

  • 检查claude_desktop_config.json中的绝对路径是否正确

  • 查看 Claude 的日志中的错误消息

RAM 不够

部分经理的 AI 模型可能选择了较大的模型,但内存不足。您可以尝试指定较小的模型(参见基本使用方法)或升级内存。

执照

MIT 许可证

有关详细信息,请参阅此项目存储库中的 LICENSE 文件

贡献

欢迎贡献代码!欢迎提交 Pull 请求。

Available Tools

2 tools
list-available-modelsB

List all available models in Ollama that can be used with query-models

ParametersJSON Schema
NameRequiredDescriptionDefault

No parameters

TDQS

B3.4/5.0
Behavior2/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden of behavioral disclosure. It states it 'List all available models' but doesn't describe what 'available' means (e.g., locally installed, remote, with status), how results are returned (e.g., format, pagination), or any constraints (e.g., permissions, rate limits). This leaves significant gaps in understanding the tool's behavior.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The description is a single, efficient sentence that directly states the tool's purpose and references the sibling tool. It is front-loaded with the core action and resource, with no wasted words or unnecessary elaboration, making it highly concise and well-structured.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness3/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Given the tool has 0 parameters, no annotations, and no output schema, the description is minimally adequate by stating what it does. However, it lacks details on behavior (e.g., output format, what 'available' entails) and doesn't leverage the low complexity to provide more context, making it incomplete for fully informed use without additional assumptions.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The input schema has 0 parameters with 100% coverage, so no parameter documentation is needed. The description doesn't add parameter details, which is appropriate here. A baseline of 4 is applied as it effectively handles the lack of parameters without introducing confusion or redundancy.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description clearly states the verb 'List' and the resource 'all available models in Ollama', which provides a specific purpose. It distinguishes from the sibling tool 'query-models' by indicating these models are 'used with' it, though it doesn't explicitly differentiate their functions beyond that implied relationship.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description implies usage by mentioning the sibling tool 'query-models', suggesting this tool is for discovering models to use with it. However, it lacks explicit guidance on when to use this tool versus alternatives or any prerequisites, leaving usage context somewhat inferred rather than clearly stated.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

query-modelsB

Query multiple AI models via Ollama and get their responses to compare perspectives

ParametersJSON Schema
NameRequiredDescriptionDefault
questionYesThe question to ask all models
modelsNoArray of model names to query (defaults to configured models)
system_promptNoOptional system prompt to provide context to all models (overridden by model_system_prompts if provided)
model_system_promptsNoOptional object mapping model names to specific system prompts

TDQS

B3.4/5.0
Behavior2/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

No annotations are provided, so the description carries the full burden of behavioral disclosure. It mentions querying multiple models and getting responses for comparison, but fails to disclose critical behavioral traits such as whether this is a read-only operation, potential rate limits, authentication needs, error handling, or the format of responses. For a tool with no annotations and complex functionality, this is a significant gap.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness5/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The description is a single, well-structured sentence that efficiently conveys the core functionality without waste. It is front-loaded with the main action ('query multiple AI models') and includes essential context ('via Ollama', 'to compare perspectives'), making every word earn its place.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness2/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Given the tool's complexity (querying multiple models with optional prompts), lack of annotations, and no output schema, the description is incomplete. It does not explain return values, error conditions, or behavioral constraints, leaving significant gaps for an AI agent to understand how to invoke and interpret results effectively.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters3/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

Schema description coverage is 100%, so the schema already documents all parameters thoroughly. The description adds minimal value beyond the schema by implying the tool queries 'multiple' models and compares responses, but does not provide additional semantics, syntax, or format details for parameters. Baseline 3 is appropriate when the schema does the heavy lifting.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose5/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description clearly states the tool's purpose with specific verbs ('query multiple AI models', 'get their responses') and resources ('via Ollama'), and distinguishes it from the sibling tool 'list-available-models' by focusing on querying rather than listing models. It explicitly mentions the comparative aspect ('to compare perspectives'), which adds valuable context beyond basic querying.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines3/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description implies usage for comparing model responses to a question, but provides no explicit guidance on when to use this tool versus alternatives (e.g., querying a single model) or any prerequisites. It mentions 'defaults to configured models' for the models parameter, which offers some contextual hint, but lacks clear when/when-not directives or named alternatives.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

Tool Schema Changelog

Recent tool additions, removals, and schema changes observed during successful MCP inspections.

  1. 1 tool updatev1.0.0
    • Changedlist-available-models1 field changed
      • removedInput schema / additionalProperties
        Removed value: -false
  2. 2 tool updates
    • First observedlist-available-models
    • First observedquery-models

TDQS

B3.4/5.0

Scored across 2 tools

Disambiguation5/5

The two tools have clearly distinct purposes: one lists available models, while the other queries models for responses. There is no overlap in functionality, making it easy for an agent to choose the correct tool for each task without confusion.

Naming Consistency4/5

Both tools use a verb_noun pattern (list-available-models and query-models), which is consistent and readable. However, the hyphenation in 'list-available-models' slightly deviates from the simpler 'query-models', but overall the naming is predictable and follows a clear convention.

Tool Count2/5

With only 2 tools, the server feels thin for its purpose of advising on multiple models. While the tools cover listing and querying, the scope suggests potential gaps in operations like model management or comparison analysis, making the count too low for a comprehensive multi-model advisory system.

Completeness2/5

The tool surface is significantly incomplete for a multi-model advisor. It lacks operations such as managing models (e.g., adding or removing models), comparing responses in a structured way, or handling model configurations. This will likely cause agent failures when trying to perform full advisory workflows beyond basic listing and querying.

Maintenance

ActivityInactive
ResponsivenessNo issues

Related MCP Connectors

Related MCP Servers