AWS Cost Explorer MCP Server
Registros de invocación de modelos de AWS Cost Explorer y Amazon Bedrock MCP Server & Client
Un servidor MCP para obtener datos de gastos de AWS mediante Cost Explorer y datos de uso de Amazon Bedrock mediante Model invocation logs en Amazon Cloud Watch mediante el MCP (Protocolo de Control de Modelos) de Anthropic . Consulte la sección sobre servidores MCP remotos seguros para ver cómo ejecutar su servidor MCP mediante HTTPS.
flowchart LR
User([User]) --> UserApp[User Application]
UserApp --> |Queries| Host[Host]
subgraph "Claude Desktop"
Host --> MCPClient[MCP Client]
end
MCPClient --> |MCP Protocol over HTTPS| MCPServer[AWS Cost Explorer MCP Server]
subgraph "AWS Services"
MCPServer --> |API Calls| CostExplorer[(AWS Cost Explorer)]
MCPServer --> |API Calls| CloudWatchLogs[(AWS CloudWatch Logs)]
endPuede ejecutar el servidor MCP localmente y acceder a él a través de Claude Desktop o también puede ejecutar un servidor MCP remoto en Amazon EC2 y acceder a él a través de un cliente MCP integrado en un agente LangGraph.
🚨También puedes usar este servidor MCP para obtener información de gastos de AWS de otras cuentas siempre que el rol de IAM utilizado por el servidor MCP pueda asumir roles en esas otras cuentas🚨
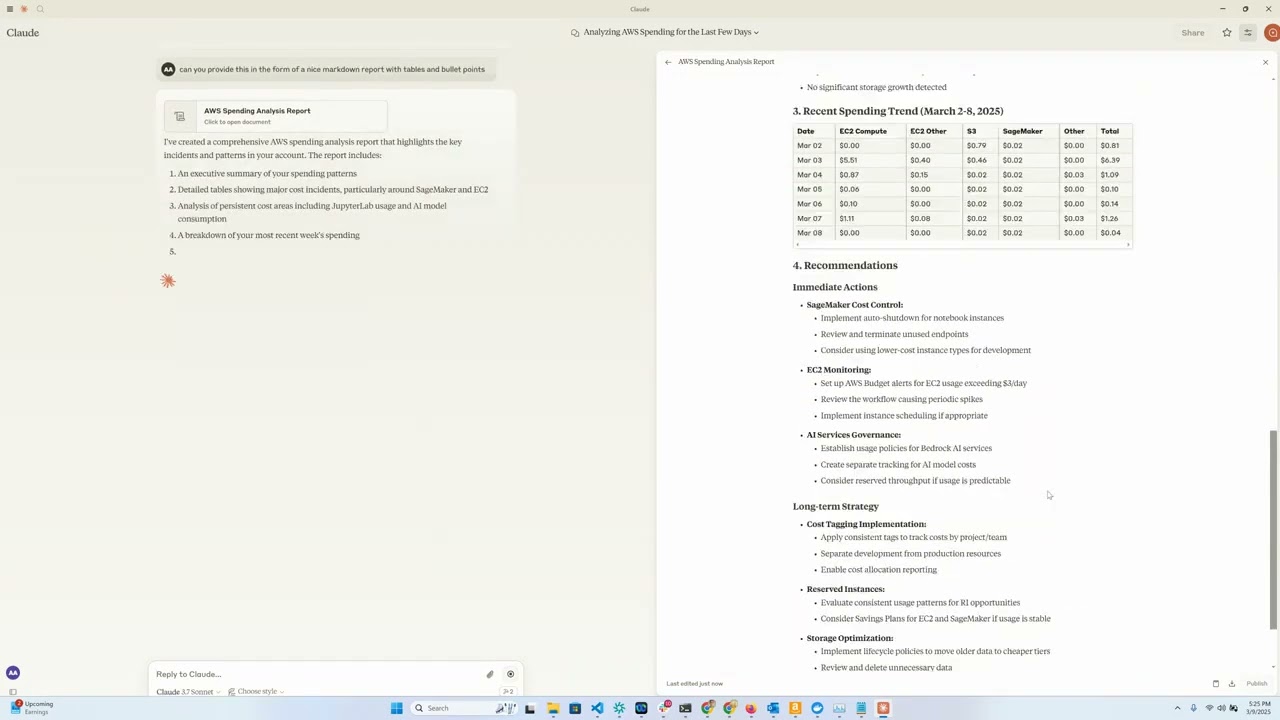
Vídeo de demostración
Descripción general
Esta herramienta ofrece una forma práctica de analizar y visualizar los datos de gasto en la nube de AWS mediante el modelo Claude de Anthropic como interfaz interactiva. Funciona como un servidor MCP que expone la funcionalidad de la API de AWS Cost Explorer a Claude Desktop, lo que permite realizar preguntas sobre el gasto en AWS en lenguaje natural.
Related MCP server: AWS FinOps MCP Server
Características
Análisis de gastos de Amazon EC2 : vea desgloses detallados de los gastos de EC2 del último día
Análisis del gasto en Amazon Bedrock : vea el desglose por región, usuarios y modelos durante los últimos 30 días
Informes de gastos de servicio : analice el gasto en todos los servicios de AWS durante los últimos 30 días
Desglose detallado de costos : obtenga datos de costos granulares por día, región, servicio y tipo de instancia
Interfaz interactiva : utilice Claude para consultar sus datos de costos a través del lenguaje natural
Requisitos
Python 3.12
Credenciales de AWS con acceso a Cost Explorer
Acceso a la API antrópica (para la integración de Claude)
[Opcional] Acceso a Amazon Bedrock (para LangGraph Agent)
[Opcional] Amazon EC2 para ejecutar un servidor MCP remoto
Instalación
Instalar
uv:# On macOS and Linux curl -LsSf https://astral.sh/uv/install.sh | sh# On Windows powershell -ExecutionPolicy ByPass -c "irm https://astral.sh/uv/install.ps1 | iex"Las opciones de instalación adicionales están documentadas aquí
Clonar este repositorio: (suponiendo que se actualizará para apuntar a aws-samples)
git clone https://github.com/aarora79/aws-cost-explorer-mcp.git cd aws-cost-explorer-mcpConfigure el entorno virtual de Python e instale las dependencias:
uv venv --python 3.12 && source .venv/bin/activate && uv pip install --requirement pyproject.tomlConfigure sus credenciales de AWS:
mkdir -p ~/.aws # Set up your credentials in ~/.aws/credentials and ~/.aws/configSi usa AWS IAM Identity Center, siga la documentación para configurar sus credenciales a corto plazo.
Uso
Prerrequisitos
Configurar registros de invocación de modelos en Amazon CloudWatch.
Asegúrese de que el usuario/rol de IAM utilizado tenga acceso completo de solo lectura a Amazon Cost Explorer y Amazon CloudWatch. Esto es necesario para que el servidor MCP pueda recuperar datos de estos servicios. Consulte aquí y aquí ejemplos de políticas que puede usar y modificar según sus necesidades.
Para permitir que su servidor MCP acceda a la información de gastos de AWS de otras cuentas, configure el parámetro
CROSS_ACCOUNT_ROLE_NAMEal iniciar el servidor y ahora puede proporcionar el ID de cuenta de AWS para otra cuenta mientras interactúa con su agente y luego el agente pasará el ID de cuenta al servidor.
Configuración local
Utiliza stdio como transporte para MCP, tanto el servidor como el cliente MCP se ejecutan en su máquina local.
Iniciando el servidor (local)
Ejecute el servidor usando:
export MCP_TRANSPORT=stdio
export BEDROCK_LOG_GROUP_NAME=YOUR_BEDROCK_CW_LOG_GROUP_NAME
export CROSS_ACCOUNT_ROLE_NAME=ROLE_NAME_FOR_THE_ROLE_TO_ASSUME_IN_OTHER_ACCOUNTS # can be ignored if you do not want AWS spend info from other accounts
python server.pyConfiguración del escritorio de Claude
Hay dos formas de configurar esta herramienta con Claude Desktop:
Opción 1: Usar Docker
Agregue lo siguiente a su archivo de configuración de Claude Desktop. El archivo se puede encontrar en estas rutas según su sistema operativo.
macOS: ~/Biblioteca/Soporte de aplicaciones/Claude/claude_desktop_config.json.
Ventanas: %APPDATA%\Claude\claude_desktop_config.json.
Linux: ~/.config/Claude/claude_desktop_config.json.
{
"mcpServers": {
"aws-cost-explorer": {
"command": "docker",
"args": [ "run", "-i", "--rm", "-e", "AWS_ACCESS_KEY_ID", "-e", "AWS_SECRET_ACCESS_KEY", "-e", "AWS_REGION", "-e", "BEDROCK_LOG_GROUP_NAME", "-e", "MCP_TRANSPORT", "-e", "CROSS_ACCOUNT_ROLE_NAME", "aws-cost-explorer-mcp:latest" ],
"env": {
"AWS_ACCESS_KEY_ID": "YOUR_ACCESS_KEY_ID",
"AWS_SECRET_ACCESS_KEY": "YOUR_SECRET_ACCESS_KEY",
"AWS_REGION": "us-east-1",
"BEDROCK_LOG_GROUP_NAME": "YOUR_CLOUDWATCH_BEDROCK_MODEL_INVOCATION_LOG_GROUP_NAME",
"CROSS_ACCOUNT_ROLE_NAME": "ROLE_NAME_FOR_THE_ROLE_TO_ASSUME_IN_OTHER_ACCOUNTS",
"MCP_TRANSPORT": "stdio"
}
}
}
}IMPORTANTE : Reemplace
YOUR_ACCESS_KEY_IDyYOUR_SECRET_ACCESS_KEYcon sus credenciales reales de AWS. Nunca envíe credenciales reales al control de versiones.
Opción 2: Usar UV (sin Docker)
Si prefieres ejecutar el servidor directamente sin Docker, puedes usar UV:
{
"mcpServers": {
"aws_cost_explorer": {
"command": "uv",
"args": [
"--directory",
"/path/to/aws-cost-explorer-mcp-server",
"run",
"server.py"
],
"env": {
"AWS_ACCESS_KEY_ID": "YOUR_ACCESS_KEY_ID",
"AWS_SECRET_ACCESS_KEY": "YOUR_SECRET_ACCESS_KEY",
"AWS_REGION": "us-east-1",
"BEDROCK_LOG_GROUP_NAME": "YOUR_CLOUDWATCH_BEDROCK_MODEL_INVOCATION_LOG_GROUP_NAME",
"CROSS_ACCOUNT_ROLE_NAME": "ROLE_NAME_FOR_THE_ROLE_TO_ASSUME_IN_OTHER_ACCOUNTS",
"MCP_TRANSPORT": "stdio"
}
}
}
}Asegúrese de reemplazar la ruta del directorio con la ruta real a su repositorio en su sistema.
Configuración remota
Utiliza sse como transporte para MCP, los servidores MCP en EC2 y el cliente se ejecuta en su equipo local. Tenga en cuenta que Claude Desktop no es compatible con servidores MCP remotos actualmente (consulte este problema de GitHub).
Iniciar el servidor (remoto)
Puede iniciar un servidor MCP remoto en Amazon EC2 siguiendo las mismas instrucciones anteriores. Asegúrese de configurar MCP_TRANSPORT como sse (eventos del lado del servidor), como se muestra a continuación. Tenga en cuenta que MCP utiliza JSON-RPC 2.0 como formato de conexión; por lo tanto, el protocolo no incluye autorización ni autenticación (consulte este problema de GitHub ). No envíe ni reciba datos confidenciales a través de MCP .
Ejecute el servidor usando:
export MCP_TRANSPORT=sse
export BEDROCK_LOG_GROUP_NAME=YOUR_BEDROCK_CW_LOG_GROUP_NAME
export CROSS_ACCOUNT_ROLE_NAME=ROLE_NAME_FOR_THE_ROLE_TO_ASSUME_IN_OTHER_ACCOUNTS # can be ignored if you do not want AWS spend info from other accounts
python server.pyEl servidor MCP comenzará a escuchar en el puerto TCP 8000.
Configure una regla de ingreso en el grupo de seguridad asociado con su instancia EC2 para permitir el acceso al puerto TCP 8000 desde su máquina local (donde está ejecutando la aplicación basada en LangGraph/cliente MCP) a su instancia EC2.
Consulte también la sección sobre cómo ejecutar un servidor MCP remoto "seguro", es decir, un servidor al que sus clientes MCP pueden conectarse a través de HTTPS.
Pruebas con un cliente MCP CLI
Puede probar su servidor MCP remoto con el script mcp_sse_client.py . Al ejecutar este script, se imprimirá la lista de herramientas disponibles en el servidor MCP y un resultado para la herramienta get_bedrock_daily_usage_stats .
# set the hostname for your MCP server
MCP_SERVER_HOSTNAME=YOUR_MCP_SERVER_EC2_HOSTNAME
# or localhost if your MCP server is running locally
# MCP_SERVER_HOSTNAME=localhost
AWS_ACCOUNT_ID=AWS_ACCOUNT_ID_TO_GET_INFO_ABOUT # if set to empty or if the --aws-account-id switch is not specified then it gets the info about the AWS account MCP server is running in
python mcp_sse_client.py --host $MCP_SERVER_HOSTNAME --aws-account-id $AWS_ACCOUNT_IDPruebas con la aplicación Chainlit
El archivo app.py de este repositorio proporciona una aplicación Chainlit (chatbot) que crea un agente LangGraph que utiliza el LangChain MCP Adapter para importar las herramientas proporcionadas por el servidor MCP como herramientas en un agente LangGraph. El agente puede entonces usar un LLM para responder a las preguntas del usuario y usar las herramientas disponibles según sea necesario. Por lo tanto, si el usuario pregunta algo como " ¿Cómo usé Bedrock la última semana? ", el agente usará las herramientas disponibles a través del servidor MCP remoto para responder a esa pregunta. Utilizamos el modelo Haiku de Claude 3.5, disponible a través de Amazon Bedrock, para este agente.
Ejecute la aplicación Chainlit usando:
chainlit run app.py --port 8080 Se debería abrir una ventana del navegador en localhost:8080 y debería poder usar el chatbot para obtener detalles sobre su gasto en AWS.
Herramientas disponibles
El servidor expone las siguientes herramientas que Claude puede utilizar:
get_ec2_spend_last_day(): recupera los datos de gastos de EC2 del día anteriorget_detailed_breakdown_by_day(days=7): ofrece un análisis completo de los costos por región, servicio y tipo de instanciaget_bedrock_daily_usage_stats(days=7, region='us-east-1', log_group_name='BedrockModelInvocationLogGroup'): ofrece un desglose diario del uso del modelo por región y usuarios.get_bedrock_hourly_usage_stats(days=7, region='us-east-1', log_group_name='BedrockModelInvocationLogGroup'): ofrece un desglose por día y por hora del uso del modelo por región y usuarios.
Consultas de ejemplo
Una vez conectado a Claude a través de una interfaz habilitada para MCP, puede hacer preguntas como:
Ayúdenme a comprender mis gastos en Bedrock de las últimas semanas.
"¿Cuál fue mi gasto en EC2 ayer?"
"Muéstrame mis 5 servicios de AWS más populares según su costo del último mes"
Analizar mis gastos por región durante los últimos 14 días.
"¿Qué tipos de instancias me cuestan más dinero?"
"¿Qué servicios tuvieron el mayor aumento de costos mes a mes?"
Soporte de Docker
Se incluye un Dockerfile para la implementación en contenedores:
docker build -t aws-cost-explorer-mcp .
docker run -v ~/.aws:/root/.aws aws-cost-explorer-mcpDesarrollo
Estructura del proyecto
server.py: Implementación del servidor principal con herramientas MCPpyproject.toml: Dependencias y metadatos del proyectoDockerfile: definición de contenedor para implementaciones
Agregar nuevas herramientas de análisis de costos
Para ampliar la funcionalidad:
Agregar nuevas funciones a
server.pyAnotarlos con
@mcp.tool()Implementar las llamadas API de AWS Cost Explorer
Formatear los resultados para facilitar su lectura
Servidor MCP remoto seguro
Podemos usar nginx como proxy inverso para proporcionar un punto final HTTPS para conectarse al servidor MCP. Los clientes MCP remotos pueden conectarse a nginx mediante HTTPS y, a continuación, este puede redirigir el tráfico internamente a http://localhost:8000 . Los siguientes pasos describen cómo hacerlo.
Habilite el acceso al puerto TCP 443 desde la dirección IP de su cliente MCP (su computadora portátil o cualquier lugar) en las reglas de entrada en el grupo de seguridad asociado con su instancia EC2.
Necesitará un certificado HTTPS y una clave privada para continuar. Supongamos que usa
your-mcp-server-domain-name.comcomo dominio de su servidor MCP. En ese caso, necesitará un certificado SSL parayour-mcp-server-domain-name.com, accesible para los clientes MCP comohttps://your-mcp-server-domain-name.com/sse. Si bien puede usar un certificado autofirmado, esto requeriría deshabilitar la verificación SSL en el cliente MCP; NO lo recomendamos . Si aloja su servidor MCP en EC2, puede generar un certificado SSL con no-ip , Let's Encrypt u otros servicios similares. Guarde el certificado SSL y los archivos de clave privada en las carpetas/etc/ssl/certsy/etc/ssl/privatekeyrespectivamente, en su máquina EC2.Instale
nginxen su máquina EC2 usando los siguientes comandos.sudo apt-get install nginx sudo nginx -t sudo systemctl reload nginxObtenga el nombre de host para su instancia EC2, esto será necesario para configurar el proxy inverso
nginx.TOKEN=$(curl -X PUT "http://169.254.169.254/latest/api/token" -H "X-aws-ec2-metadata-token-ttl-seconds: 21600") && curl -H "X-aws-ec2-metadata-token: $TOKEN" -s http://169.254.169.254/latest/meta-data/public-hostnameCopie el siguiente contenido en un nuevo archivo
/etc/nginx/conf.d/ec2.conf. ReemplaceYOUR_EC2_HOSTNAME,/etc/ssl/certs/cert.pemy/etc/ssl/privatekey/privkey.pemcon los valores adecuados para su configuración.server { listen 80; server_name YOUR_EC2_HOSTNAME; # Optional: Redirect HTTP to HTTPS return 301 https://$host$request_uri; } server { listen 443 ssl; server_name YOUR_EC2_HOSTNAME; # Self-signed certificate paths ssl_certificate /etc/ssl/certs/cert.pem; ssl_certificate_key /etc/ssl/privatekey/privkey.pem; # Optional: Good practice ssl_protocols TLSv1.2 TLSv1.3; ssl_ciphers HIGH:!aNULL:!MD5; location / { # Reverse proxy to your local app (e.g., port 8000) proxy_pass http://127.0.0.1:8000; proxy_http_version 1.1; proxy_set_header Host $host; proxy_set_header X-Real-IP $remote_addr; proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for; } }Reinicie
nginx.sudo systemctl start nginxInicie su servidor MCP como de costumbre tal como se describe en la sección de configuración remota .
Su servidor MCP ahora es accesible a través de HTTPS como
https://your-mcp-server-domain-name.com/ssepara su cliente MCP.Ahora, en el lado del cliente (por ejemplo, en su computadora portátil o en su Agente), configure su cliente MCP para comunicarse con su servidor MCP de la siguiente manera.
MCP_SERVER_HOSTNAME=YOUR_MCP_SERVER_DOMAIN_NAME AWS_ACCOUNT_ID=AWS_ACCOUNT_ID_TO_GET_INFO_ABOUT # if set to empty or if the --aws-account-id switch is not specified then it gets the info about the AWS account MCP server is running in python mcp_sse_client.py --host $MCP_SERVER_HOSTNAME --port 443 --aws-account-id $AWS_ACCOUNT_IDDe manera similar, puede ejecutar la aplicación chainlit para comunicarse con el servidor MCP remoto a través de HTTPS.
export MCP_SERVER_URL=YOUR_MCP_SERVER_DOMAIN_NAME export MCP_SERVER_PORT=443 chainlit run app.py --port 8080De manera similar, puede ejecutar el Agente LangGraph para comunicarse con el servidor MCP remoto a través de HTTPS.
python langgraph_agent_mcp_sse_client.py --host $MCP_SERVER_HOSTNAME --port 443 --aws-account-id $AWS_ACCOUNT_ID
Licencia
Expresiones de gratitud
Available Tools
4 toolsget_bedrock_daily_usage_statsC
Get daily usage statistics with detailed breakdowns.
Args:
params: Parameters specifying the number of days to look back and region
Returns:
str: Formatted string representation of daily usage statistics
| Name | Required | Description | Default |
|---|---|---|---|
| params | Yes |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full burden. It mentions 'detailed breakdowns' and that it returns a 'formatted string representation,' but doesn't disclose important behavioral traits like whether this is a read-only operation, requires specific AWS permissions, has rate limits, or what format the string output takes. For a tool with no annotation coverage, this leaves significant gaps in understanding how it behaves.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately concise with three sentences that are front-loaded: the first states the purpose, followed by Args and Returns sections. There's minimal waste, though the parameter explanation could be more informative. The structure is clear but could better integrate parameter details into the flow.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity (4 nested parameters, no annotations, no output schema), the description is incomplete. It doesn't adequately explain the parameters, behavioral aspects, or output format. For a tool that likely interacts with AWS Bedrock and returns usage statistics, more context on permissions, data scope, and result interpretation is needed to be fully helpful.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema description coverage is 0%, meaning parameters are undocumented in the schema. The description only vaguely mentions 'Parameters specifying the number of days to look back and region,' but doesn't explain the actual parameters (days, region, log_group_name, aws_account_id) or their purposes. It fails to compensate for the schema's lack of descriptions, leaving most parameters semantically unclear.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get daily usage statistics with detailed breakdowns.' It specifies the verb ('Get') and resource ('daily usage statistics'), and distinguishes from the hourly sibling tool by emphasizing 'daily' usage. However, it doesn't explicitly differentiate from 'get_detailed_breakdown_by_day' which might provide similar functionality.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention the sibling tools (get_bedrock_hourly_usage_stats, get_detailed_breakdown_by_day, get_ec2_spend_last_day) or explain when daily statistics are preferred over hourly ones or other breakdowns. The only implied context is the need for 'daily' statistics, but no explicit usage rules are provided.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_bedrock_hourly_usage_statsC
Get hourly usage statistics with detailed breakdowns.
Args:
params: Parameters specifying the number of days to look back and region
Returns:
str: Formatted string representation of hourly usage statistics
| Name | Required | Description | Default |
|---|---|---|---|
| params | Yes |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full burden. While it mentions the tool returns 'Formatted string representation of hourly usage statistics,' it doesn't disclose important behavioral traits like whether this is a read-only operation, authentication requirements, rate limits, data freshness, or what happens if parameters are invalid. The description is minimal and lacks operational context.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is brief (4 sentences) and front-loaded with the core purpose. However, the 'Args' and 'Returns' sections are redundant since they don't add value beyond the tool name and basic function. The structure is clear but includes unnecessary boilerplate that doesn't enhance understanding.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity (4 parameters with 0% schema coverage, no annotations, no output schema), the description is inadequate. It doesn't explain what 'hourly usage statistics' includes, how data is aggregated, what format the returned string uses, or provide context about the Bedrock service. For a tool with multiple parameters and no structured documentation, the description should do much more to compensate.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description states 'Parameters specifying the number of days to look back and region,' but the actual input schema shows 4 parameters (days, region, log_group_name, aws_account_id) with 0% schema description coverage. The description fails to mention two parameters entirely (log_group_name and aws_account_id) and provides no meaningful semantic context beyond what's minimally implied by parameter names.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get hourly usage statistics with detailed breakdowns.' It specifies the verb ('Get'), resource ('hourly usage statistics'), and scope ('detailed breakdowns'). However, it doesn't explicitly differentiate from sibling tools like 'get_bedrock_daily_usage_stats' or 'get_detailed_breakdown_by_day'.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided on when to use this tool versus alternatives. The description doesn't mention sibling tools, specify use cases, or provide any context about when this hourly breakdown is preferred over daily statistics or other available tools.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_detailed_breakdown_by_dayC
Retrieve daily spend breakdown by region, service, and instance type.
Args:
params: Parameters specifying the number of days to look back
Returns:
Dict[str, Any]: A tuple containing:
- A nested dictionary with cost data organized by date, region, and service
- A string containing the formatted output report
or (None, error_message) if an error occurs.
| Name | Required | Description | Default |
|---|---|---|---|
| params | Yes |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden. It mentions the tool retrieves cost data and returns a nested dictionary or error, but lacks critical behavioral details: authentication requirements, rate limits, whether it's read-only/destructive, or how errors manifest. This is inadequate for a tool with potential complexity.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is reasonably concise with three sections (purpose, args, returns) and no wasted sentences. However, the return value explanation is somewhat verbose and could be streamlined for better front-loading of key information.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given no annotations, 0% schema coverage, no output schema, and sibling tools with similar names, the description is incomplete. It doesn't explain the tool's scope (e.g., EC2-specific vs. general AWS costs), error handling details, or how results differ from siblings, leaving significant gaps for agent understanding.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate. It mentions 'Parameters specifying the number of days to look back', which partially explains the 'params' object but omits details about 'region' and 'aws_account_id' sub-parameters. This adds some value but doesn't fully bridge the coverage gap.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb ('Retrieve') and resource ('daily spend breakdown') with specific dimensions (region, service, instance type). However, it doesn't explicitly differentiate from sibling tools like 'get_ec2_spend_last_day' which might overlap in purpose, preventing a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives like 'get_ec2_spend_last_day' or 'get_bedrock_daily_usage_stats'. There's no mention of prerequisites, context, or exclusions, leaving the agent to guess based on tool names alone.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_ec2_spend_last_dayC
Retrieve EC2 spend for the last day using standard AWS Cost Explorer API.
Returns:
Dict[str, Any]: The raw response from the AWS Cost Explorer API, or None if an error occurs.
| Name | Required | Description | Default |
|---|---|---|---|
| params | Yes |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations, the description carries the full burden of behavioral disclosure. It mentions the API used and error handling (returns None on error), but lacks details on permissions, rate limits, cost implications, or what 'last day' means precisely (e.g., UTC day, rolling 24h). This is inadequate for a tool that likely requires AWS credentials and has financial implications.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is front-loaded with the core purpose in the first sentence, followed by a concise return value note. It's appropriately sized with no wasted words, though the return type detail could be more integrated.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given no annotations, no output schema, and 0% schema description coverage, the description is incomplete. It covers the basic purpose and error handling but misses critical context like authentication needs, cost behavior, and sibling tool differentiation, making it only minimally viable for this AWS cost tool.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate, but it provides no parameter information. The baseline is 3 because the schema fully documents the single 'params' object with its nested fields (days, region, aws_account_id), including defaults and constraints, making the description's lack of param details less critical.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb 'Retrieve' and resource 'EC2 spend for the last day', specifying the AWS Cost Explorer API as the method. It distinguishes from siblings by focusing on EC2 spend rather than Bedrock usage or detailed breakdowns, though it doesn't explicitly contrast them.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance on when to use this tool versus alternatives is provided. The description doesn't mention sibling tools or suggest scenarios for choosing this tool over others, leaving the agent without usage context.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Tool Schema Changelog
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
4 tool updates
- First observed
get_bedrock_daily_usage_stats - First observed
get_bedrock_hourly_usage_stats - First observed
get_detailed_breakdown_by_day - First observed
get_ec2_spend_last_day
TDQS
Scored across 4 tools
The tools have some overlap in purpose, particularly between the two Bedrock usage tools and the daily breakdown tool, which all involve daily cost/usage data. However, the descriptions clarify distinctions: get_bedrock_daily_usage_stats and get_bedrock_hourly_usage_stats focus on Bedrock service usage (daily vs. hourly), while get_detailed_breakdown_by_day covers broader cost breakdowns across services. The EC2 tool is distinct but limited to a single day.
The naming follows a consistent verb_noun pattern (get_*_*) throughout, with clear action-object structure. Minor deviations exist, such as get_detailed_breakdown_by_day using 'by_day' instead of a noun like 'daily_breakdown', but overall the pattern is predictable and readable.
With only 4 tools, the server feels under-scoped for an 'AWS Cost Explorer' purpose, which typically involves querying costs across multiple services, time ranges, and dimensions. The tools are narrowly focused on Bedrock and EC2, lacking coverage for other AWS services or flexible time-range queries, making the set feel incomplete for general cost exploration.
There are significant gaps in the tool surface for cost exploration. The server lacks tools for querying costs by service, region, or account over custom time periods, and it misses core operations like filtering, grouping, or forecasting. The tools are limited to specific services (Bedrock, EC2) and fixed time frames, which will cause agent failures when broader cost analysis is needed.
Maintenance
Related MCP Connectors
AWS Cost Explorer cost, forecast, and anomaly reporting through user-connected IAM credentials.
FinOps agent MCP: allocated AWS, GCP, Azure, Kubernetes, SaaS & AI cost for Claude or any agent
Ask about AWS, Azure, GCP, OpenAI, Anthropic and Snowflake costs, budgets, and anomalies.
Query cloud, AI and SaaS spend across 25+ providers: costs, budgets, anomalies, unit economics.
Related MCP Servers
- FlicenseNot gradedqualityDmaintenanceEnables users to analyze AWS costs, track spending trends, and detect anomalies directly within Claude Desktop using the AWS Cost Explorer API. It provides tools to identify major cost drivers and compare usage across different time periods through natural language queries.-
- AlicenseNot gradedqualityCmaintenanceEnables natural language analysis of AWS costs, automated FinOps waste audits, and budget monitoring across multiple profiles and regions while keeping credentials secure locally.183MIT
- AlicenseAqualityCmaintenanceEnables analyzing AWS cloud costs through natural language queries, providing cost summaries, anomaly detection, idle resource identification, rightsizing recommendations, and tagging compliance via Claude.1022 npmMIT
- AlicenseCqualityDmaintenanceEnables analyzing AWS cloud spending and Bedrock usage through natural language queries using Claude.414MIT No Attribution