MCP Sentry
mcp-sentry: Un servidor Sentry MCP
Descripción general
Un servidor de Protocolo de Contexto de Modelo para recuperar y analizar incidencias de Sentry.io. Este servidor proporciona herramientas para inspeccionar informes de errores, seguimientos de pila y otra información de depuración de su cuenta de Sentry.
Herramientas
get_sentry_issueRecupere y analice un problema de Sentry por ID o URL
Aporte:
issue_id_or_url(cadena): ID del problema de Sentry o URL para analizar
Devoluciones: Detalles de la emisión, incluidos:
Título
Identificación del problema
Estado
Nivel
Marca de tiempo de primera visualización
Marca de tiempo de la última vez que se vio
Recuento de eventos
Seguimiento de pila completo
get_list_issuesRecuperar y analizar problemas de Sentry por slug de proyecto
Aporte:
project_slug(cadena): slug del proyecto Sentry que se va a analizarorganization_slug(cadena): slug de la organización centinela que se va a analizar
Devoluciones: Lista de problemas con detalles que incluyen:
Título
Identificación del problema
Estado
Nivel
Marca de tiempo de primera visualización
Marca de tiempo de la última vez que se vio
Recuento de eventos
Información básica del problema
Indicaciones
sentry-issueRecuperar detalles del problema de Sentry
Aporte:
issue_id_or_url(cadena): ID o URL del problema de Sentry
Devoluciones: Detalles del problema formateados como contexto de conversación
Related MCP server: MCP Server Sentry
Instalación
Instalación mediante herrería
Para instalar mcp-sentry para Claude Desktop automáticamente a través de Smithery :
npx -y @smithery/cli install @qianniuspace/mcp-sentry --client claudeUso de uv (recomendado)
Al usar uv , no se requiere ninguna instalación específica. Usaremos uvx para ejecutar mcp-sentry directamente.
Uso de PIP
Alternativamente, puede instalar mcp-sentry a través de pip:
pip install mcp-sentryo usar uv
uv pip install -e .Después de la instalación, puedes ejecutarlo como un script usando:
python -m mcp_sentryConfiguración
Uso con Claude Desktop
Agregue esto a su claude_desktop_config.json :
"mcpServers": {
"sentry": {
"command": "uvx",
"args": ["mcp-sentry", "--auth-token", "YOUR_SENTRY_TOKEN","--project-slug" ,"YOUR_PROJECT_SLUG", "--organization-slug","YOUR_ORGANIZATION_SLUG"]
}
}"mcpServers": {
"sentry": {
"command": "docker",
"args": ["run", "-i", "--rm", "mcp/sentry", "--auth-token", "YOUR_SENTRY_TOKEN","--project-slug" ,"YOUR_PROJECT_SLUG", "--organization-slug","YOUR_ORGANIZATION_SLUG"]
}
}"mcpServers": {
"sentry": {
"command": "python",
"args": ["-m", "mcp_sentry", "--auth-token", "YOUR_SENTRY_TOKEN","--project-slug" ,"YOUR_PROJECT_SLUG", "--organization-slug","YOUR_ORGANIZATION_SLUG"]
}
}Uso con Zed
Añade a tu configuración Zed settings.json:
Por ejemplo Curson
"context_servers": [
"mcp-sentry": {
"command": {
"path": "uvx",
"args": ["mcp-sentry", "--auth-token", "YOUR_SENTRY_TOKEN","--project-slug" ,"YOUR_PROJECT_SLUG", "--organization-slug","YOUR_ORGANIZATION_SLUG"]
}
}
],"context_servers": {
"mcp-sentry": {
"command": "python",
"args": ["-m", "mcp_sentry", "--auth-token", "YOUR_SENTRY_TOKEN","--project-slug" ,"YOUR_PROJECT_SLUG", "--organization-slug","YOUR_ORGANIZATION_SLUG"]
}
},"context_servers": {
"sentry": {
"command": "python",
"args": [
"-m",
"mcp_sentry",
"--auth-token",
"YOUR_SENTRY_TOKEN",
"--project-slug",
"YOUR_PROJECT_SLUG",
"--organization-slug",
"YOUR_ORGANIZATION_SLUG"
],
"env": {
"PYTHONPATH": "path/to/mcp-sentry/src"
}
}
},Depuración
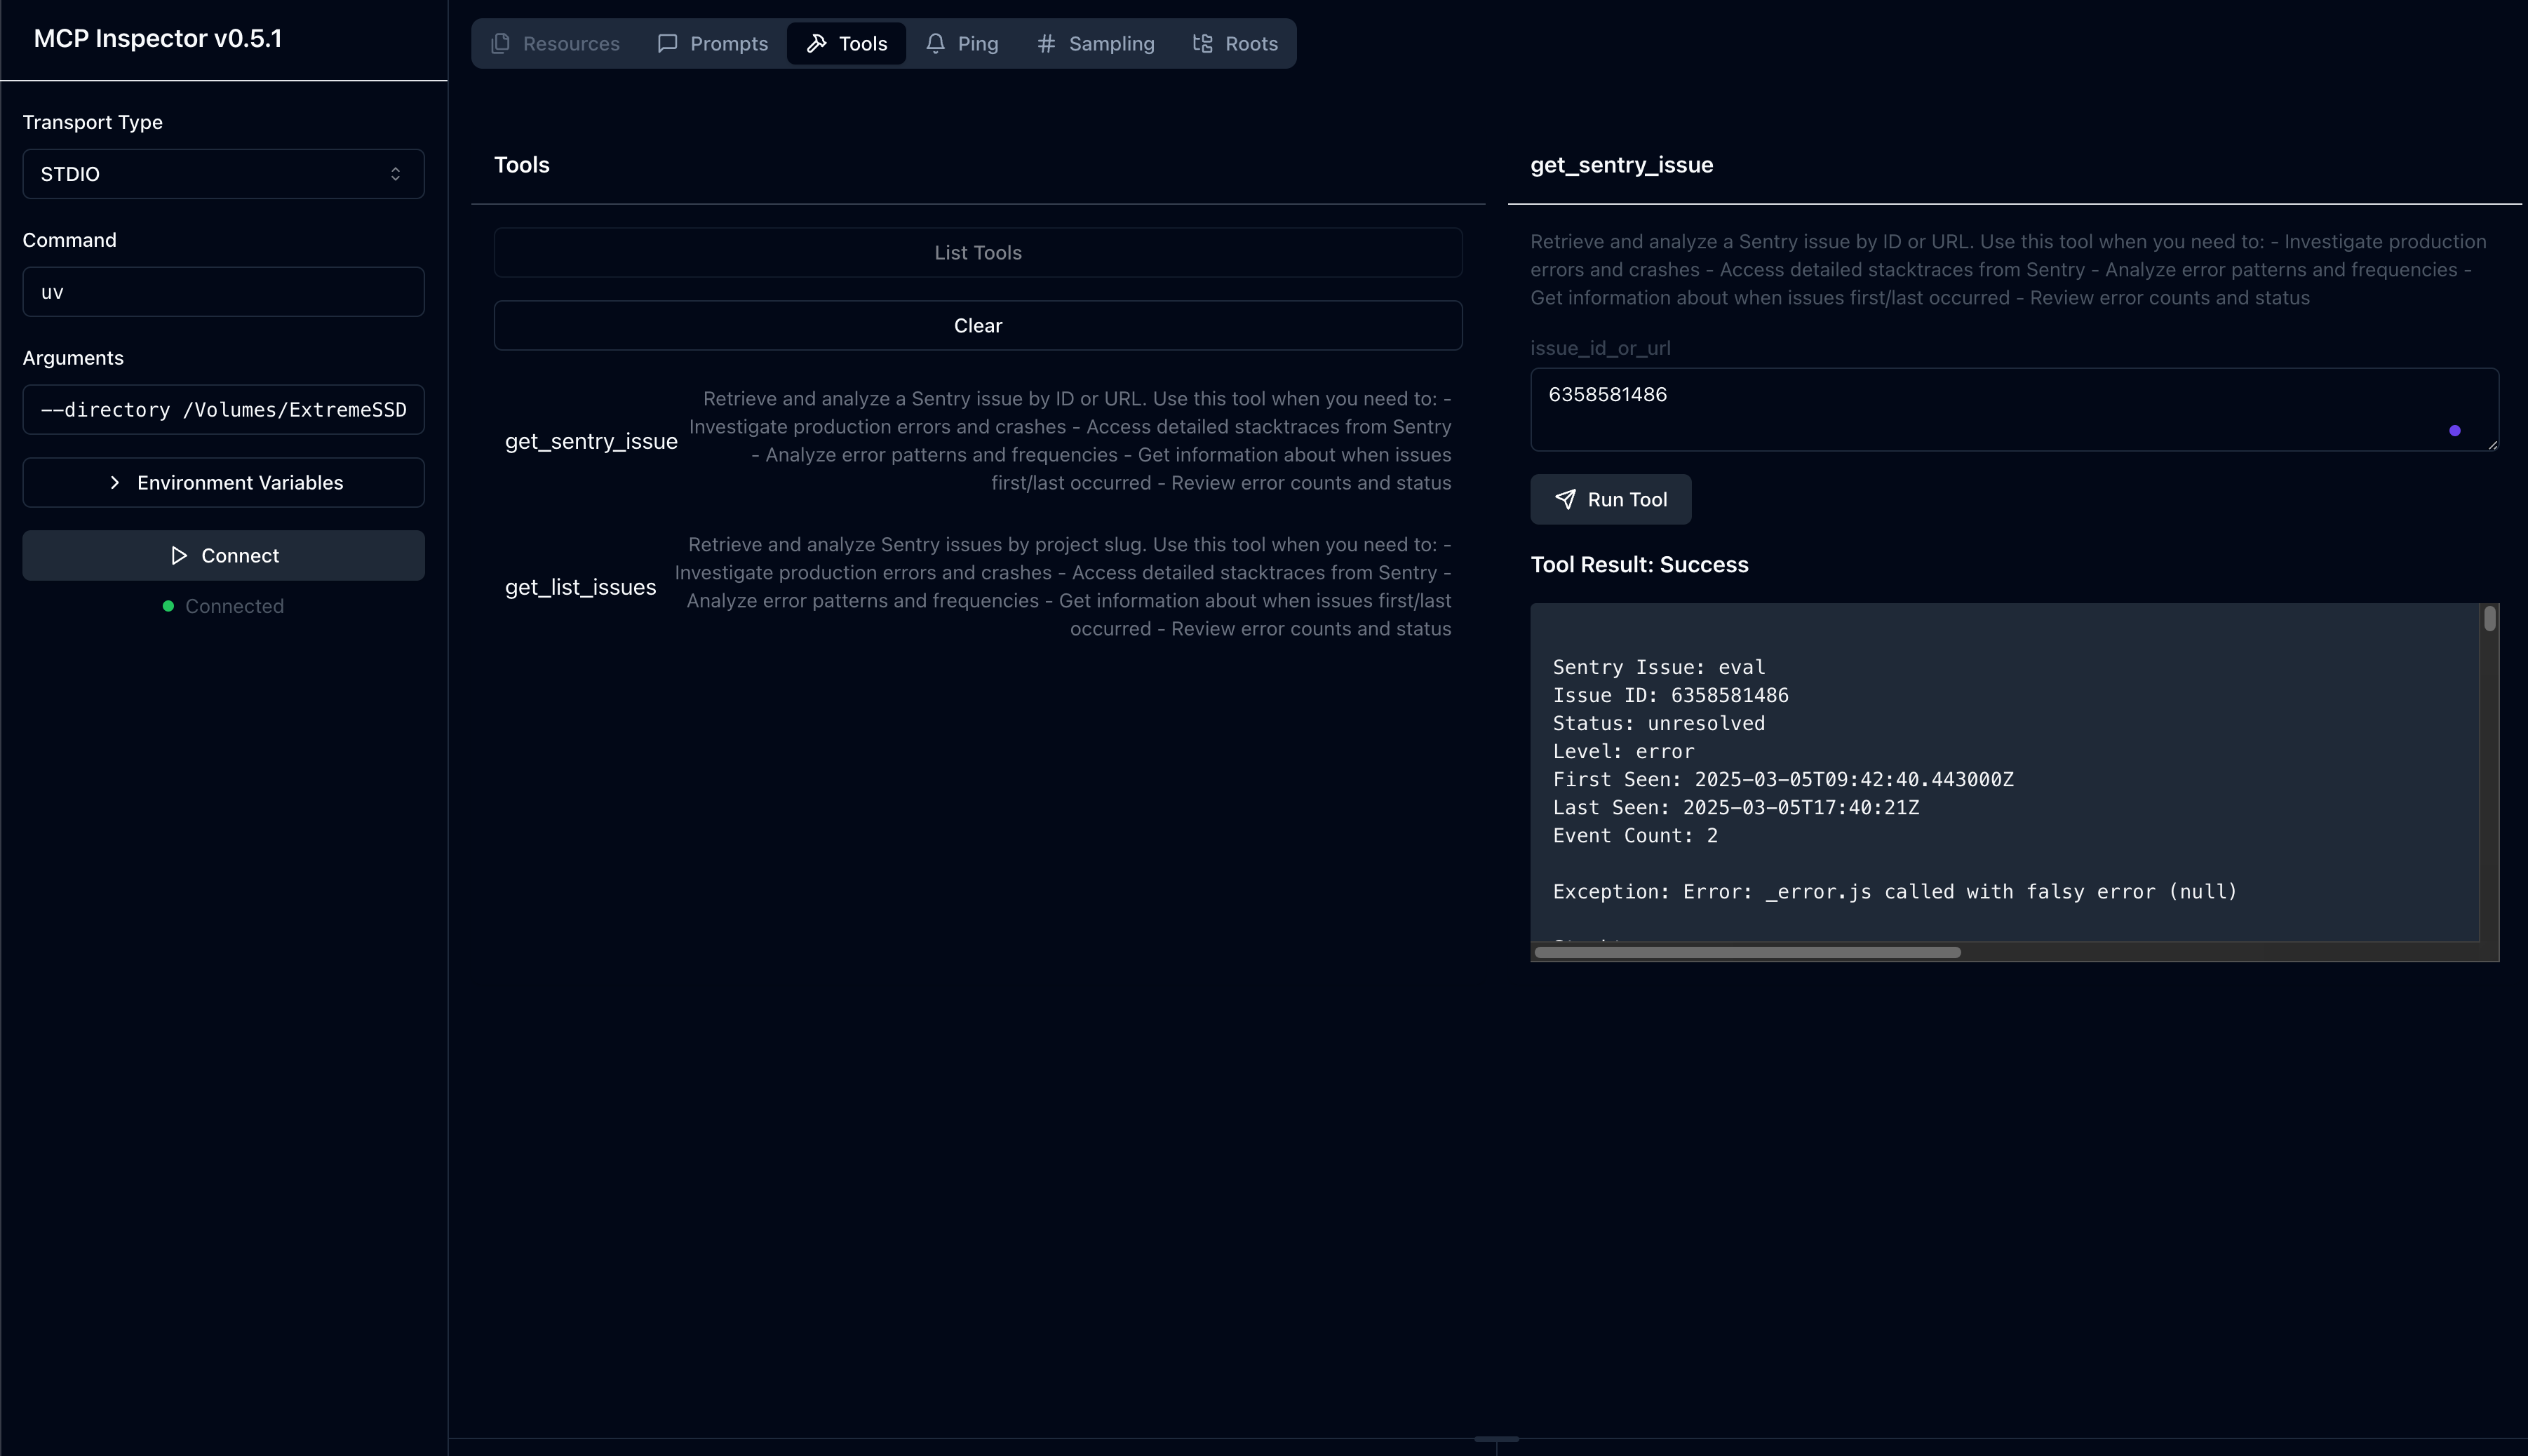
Puede usar el inspector MCP para depurar el servidor. Para instalaciones uvx:
npx @modelcontextprotocol/inspector uvx mcp-sentry --auth-token YOUR_SENTRY_TOKEN --project-slug YOUR_PROJECT_SLUG --organization-slug YOUR_ORGANIZATION_SLUGO si ha instalado el paquete en un directorio específico o está desarrollando en él:
cd path/to/servers/src/sentry
npx @modelcontextprotocol/inspector uv run mcp-sentry --auth-token YOUR_SENTRY_TOKEN --project-slug YOUR_PROJECT_SLUG --organization-slug YOUR_ORGANIZATION_SLUG o en término
npx @modelcontextprotocol/inspector uv --directory /Volumes/ExtremeSSD/MCP/mcp-sentry/src run mcp_sentry --auth-token YOUR_SENTRY_TOKEN
--project-slug YOUR_PROJECT_SLUG --organization-slug YOUR_ORGANIZATION_SLUG
Tenedor desde
Licencia
Este servidor MCP cuenta con la licencia MIT. Esto significa que puede usar, modificar y distribuir el software libremente, sujeto a los términos y condiciones de la licencia MIT. Para más detalles, consulte el archivo de LICENCIA en el repositorio del proyecto.
Available Tools
2 toolsget_list_issuesA
Retrieve and analyze Sentry issues by project slug. Use this tool when you need to: - Investigate production errors and crashes - Access detailed stacktraces from Sentry - Analyze error patterns and frequencies - Get information about when issues first/last occurred - Review error counts and status
| Name | Required | Description | Default |
|---|---|---|---|
| project_slug | No | Sentry project slug to analyze | |
| organization_slug | No | Sentry organization slug to analyze |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations provided, so description carries full burden. Details what the tool retrieves (stacktraces, error patterns, frequencies, timestamps, counts, status). Does not mention side effects, rate limits, or pagination, but for a read-like operation, it is sufficiently transparent.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Single sentence followed by bullet list that is easy to scan. No extraneous information. Well front-loaded with main purpose.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Tool has 2 optional parameters, no output schema. Description covers functionality well but does not explain what happens if parameters are omitted or describe return value format. Minor gaps.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema covers 100% of parameters with descriptions. Description does not add extra meaning beyond the schema. Baseline of 3 is appropriate as schema is adequate.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
Description clearly states 'Retrieve and analyze Sentry issues by project slug' and lists specific use cases like investigating errors and accessing stacktraces. Effectively distinguishes from sibling 'get_sentry_issue' by implying this tool returns a list.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Provides explicit scenarios for when to use the tool via bullet points. Does not explicitly state when not to use, but the contrast with the sibling tool is implicit. Good guidance overall.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_sentry_issueA
Retrieve and analyze a Sentry issue by ID or URL. Use this tool when you need to: - Investigate production errors and crashes - Access detailed stacktraces from Sentry - Analyze error patterns and frequencies - Get information about when issues first/last occurred - Review error counts and status
| Name | Required | Description | Default |
|---|---|---|---|
| issue_id_or_url | Yes | Sentry issue ID or URL to analyze |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full burden. It discloses what information the tool returns (stacktraces, first/last occurred, counts, status), which is helpful, but does not mention potential rate limits, authentication requirements, or data freshness. Adequate but not comprehensive.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is concise with two sentences plus a bullet list, front-loading the purpose. The bullet list could be slightly more compact, but overall well structured and easy to scan.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a simple retrieval tool with one parameter, no output schema, and no annotations, the description covers key use cases and return information. However, it lacks behavioral details (e.g., error handling, data freshness) that would make it fully complete for an agent.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema coverage for the single parameter is 100%, and the schema already describes 'Sentry issue ID or URL'. The description repeats 'by ID or URL' in the first sentence, adding minimal additional meaning beyond the schema. Baseline 3 is appropriate.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states 'Retrieve and analyze a Sentry issue by ID or URL' and lists specific use cases (investigate errors, access stacktraces, etc.), which distinguishes it from the sibling tool 'get_list_issues' that deals with multiple issues.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description explicitly says 'Use this tool when you need to:' followed by a list of scenarios, providing clear usage context. However, it does not explicitly state when not to use it or mention the sibling tool as an alternative, though the sibling context from the environment suggests differentiation.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Tool Schema Changelog
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
2 tool updates
v0.6.2- First observed
get_list_issues - First observed
get_sentry_issue
TDQS
Scored across 2 tools
The two tools are essentially indistinguishable in purpose. Both descriptions are identical, listing the exact same use cases (investigate errors, access stacktraces, analyze patterns, get timing info, review counts). An agent would have no way to determine when to use get_list_issues versus get_sentry_issue since they appear to serve the same function.
Both tools follow a similar get_ prefix pattern, which provides some consistency. However, the naming is confusingly similar (get_list_issues vs get_sentry_issue) rather than clearly differentiated, and the verb-noun structure is mixed (list_issues vs sentry_issue).
With only 2 tools, this feels severely under-scoped for a Sentry integration. A production error monitoring system would typically need tools for creating issues, updating statuses, searching/filtering, accessing events, or managing projects. Two tools is too few to cover meaningful workflows.
The tool surface is severely incomplete for Sentry's domain. There are no tools for creating issues, updating issue status (resolve/ignore), searching across projects, accessing event details, managing alerts, or any administrative functions. The two existing tools appear redundant rather than complementary.
Maintenance
Related MCP Connectors
Enable secure connectivity between Sentry issues and debugging data, and LLM clients, using a Model Context Protocol (MCP) server.
MCP server for Sentry - error monitoring, issue tracking, and debugging for AI assistants
A Model Context Protocol (MCP) application for automated GitHub PR analysis and issue management.…
A comprehensive Model Context Protocol (MCP) server that enables AI assistants to interact with yo…
Related MCP Servers
- AlicenseBqualityFmaintenanceA Model Context Protocol server that enables AI assistants to interact with Sentry for error tracking and monitoring, allowing retrieval and analysis of error data, project management, and performance monitoring through the Sentry API.1121ISC
- AlicenseNot gradedqualityDmaintenanceA TypeScript implementation of a Model Context Protocol server that connects to Sentry error tracking service, allowing AI models to query and analyze error reports and events.2 npmMIT
- FlicenseNot gradedqualityDmaintenanceAn MCP server that connects to Sentry.io or self-hosted Sentry instances to retrieve and analyze error reports, stack traces, and debugging information.3-

Sentry MCP Serverofficial
AlicenseBqualityFmaintenanceA Model Context Protocol server that lets AI assistants interact with the Sentry API to retrieve and analyze error data, manage projects, and monitor application performance.1112ISC