A
licenseC
qualityD
maintenanceAn MCP server that converts Markdown content to Notion API-compatible formats, suitable for content management and development integration.
1
1
Apache 2.0

The Deepwiki MCP Server fetches and processes content from deepwiki.com repositories, converting it to Markdown format. It offers:
Content Retrieval: Fetch from Deepwiki URLs or user/repo shortforms
Output Options: Return content as either a single aggregated document or structured page data
Depth Control: Limit fetching to a single page (maxDepth 0) or include linked pages (maxDepth 1)
Safety Features: Process only deepwiki.com domains for security
HTML Sanitization: Remove headers, footers, navigation elements, scripts, and ads
Link Rewriting: Ensure links work correctly in Markdown output
Debugging: Optional verbose logging for troubleshooting
Customization: Support for environment variables controlling concurrency, retries, and timeouts
Integration: Compatible with MCP clients via JSON requests
Mentioned as a contact method for the author through their Bluesky handle, but no explicit integration functionality is described.
Provides deployment options through Docker containers, allowing the MCP server to be containerized and run in various environments.
Supports configuration through environment variables loaded via .env files, enabling customization of server behavior like concurrency and timeout settings.
Allows fetching documentation from GitHub repositories on Deepwiki using a shortform syntax like 'user/repo', making it easy to retrieve documentation for open source projects.
Mentioned as a related project for AI prompts, but no direct integration functionality is described in the MCP server itself.
Converts Deepwiki content to Markdown format, allowing for easy consumption of documentation in AI tools and other Markdown-compatible environments.
Click on "Deploy Server".
Wait a few minutes for the server to deploy. Once ready, it will show a "Started" state.
In the chat, type @ followed by the MCP server name and your instructions, e.g., "@Deepwiki MCP Server fetch how to use shadcn components with Tailwind CSS"
That's it! The server will respond to your query, and you can continue using it as needed.
Here is a step-by-step guide with screenshots.
⚠️ IMPORTANT NOTICE: This server is currently not working since DeepWiki has cut off the possibility to scrape it. We recommend using the official DeepWiki MCP server at https://docs.devin.ai/work-with-devin/deepwiki-mcp for the time being.
This is an unofficial Deepwiki MCP Server
It takes a Deepwiki URL via MCP, crawls all relevant pages, converts them to Markdown, and returns either one document or a list by page.
🔒 Domain Safety: Only processes URLs from deepwiki.com
🧹 HTML Sanitization: Strips headers, footers, navigation, scripts, and ads
🔗 Link Rewriting: Adjusts links to work in Markdown
📄 Multiple Output Formats: Get one document or structured pages
🚀 Performance: Fast crawling with adjustable concurrency and depth
NLP: It's to search just for the library name
Related MCP server: Crawl4AI MCP Server
Prompts you can use:
deepwiki fetch how can i use gpt-image-1 with "vercel ai" sdkdeepwiki fetch how can i create new blocks in shadcn?deepwiki fetch i want to understand how X worksFetch complete Documentation (Default)
use deepwiki https://deepwiki.com/shadcn-ui/ui
use deepwiki multiple pages https://deepwiki.com/shadcn-ui/ui
Single Page
use deepwiki fetch single page https://deepwiki.com/tailwindlabs/tailwindcss/2.2-theme-systemGet by shortform
use deepwiki fetch tailwindlabs/tailwindcssdeepwiki fetch library
deepwiki fetch url
deepwiki fetch <name>/<repo>
deepwiki multiple pages ...
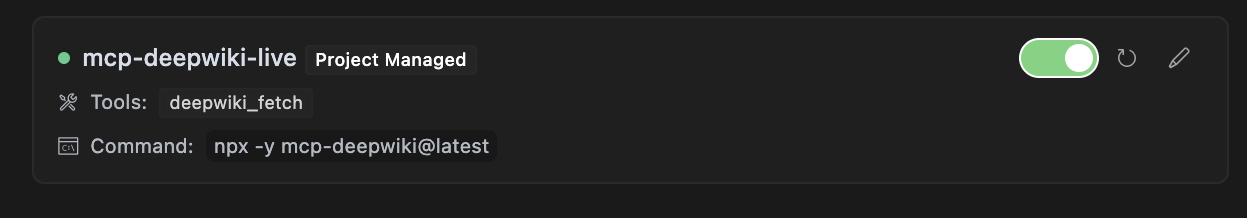
deepwiki single page url ...Add this to .cursor/mcp.json file.
{
  "mcpServers": {
    "mcp-deepwiki": {
      "command": "npx",
      "args": ["-y", "mcp-deepwiki@latest"]
    }
  }
}
The package registers a tool named deepwiki_fetch that you can use with any MCP-compatible client:
{
  "action": "deepwiki_fetch",
  "params": {
    "url": "https://deepwiki.com/user/repo",
    "mode": "aggregate",
    "maxDepth": "1"
  }
}url (required): The starting URL of the Deepwiki repository
mode (optional): Output mode, either "aggregate" for a single Markdown document (default) or "pages" for structured page data
maxDepth (optional): Maximum depth of pages to crawl (default: 10)
{
  "status": "ok",
  "data": "# Page Title\n\nPage content...\n\n---\n\n# Another Page\n\nMore content...",
  "totalPages": 5,
  "totalBytes": 25000,
  "elapsedMs": 1200
}{
"status": "ok",
"data": [
{
"path": "index",
"markdown": "# Home Page\n\nWelcome to the repository."
},
{
"path": "section/page1",
"markdown": "# First Page\n\nThis is the first page content."
}
],
"totalPages": 2,
"totalBytes": 12000,
"elapsedMs": 800
}{
"status": "error",
"code": "DOMAIN_NOT_ALLOWED",
"message": "Only deepwiki.com domains are allowed"
}{
"status": "partial",
"data": "# Page Title\n\nPage content...",
"errors": [
{
"url": "https://deepwiki.com/user/repo/page2",
"reason": "HTTP error: 404"
}
],
"totalPages": 1,
"totalBytes": 5000,
"elapsedMs": 950
}When using the tool, you'll receive progress events during crawling:
Fetched https://deepwiki.com/user/repo: 12500 bytes in 450ms (status: 200)
Fetched https://deepwiki.com/user/repo/page1: 8750 bytes in 320ms (status: 200)
Fetched https://deepwiki.com/user/repo/page2: 6200 bytes in 280ms (status: 200){
"mcpServers": {
"mcp-deepwiki": {
"command": "node",
"args": ["./bin/cli.mjs"]
}
}
}# Clone the repository
git clone https://github.com/regenrek/deepwiki-mcp.git
cd deepwiki-mcp
# Install dependencies
npm install
# Build the package
npm run buildFor HTTP transport, you can make direct API calls:
curl -X POST http://localhost:3000/mcp \
  -H "Content-Type: application/json" \
  -d '{
    "id": "req-1",
    "action": "deepwiki_fetch",
    "params": {
      "url": "https://deepwiki.com/user/repo",
      "mode": "aggregate"
    }
}'DEEPWIKI_MAX_CONCURRENCY: Maximum concurrent requests (default: 5)
DEEPWIKI_REQUEST_TIMEOUT: Request timeout in milliseconds (default: 30000)
DEEPWIKI_MAX_RETRIES: Maximum retry attempts for failed requests (default: 3)
DEEPWIKI_RETRY_DELAY: Base delay for retry backoff in milliseconds (default: 250)
To configure these, create a .env file in the project root:
DEEPWIKI_MAX_CONCURRENCY=10
DEEPWIKI_REQUEST_TIMEOUT=60000
DEEPWIKI_MAX_RETRIES=5
DEEPWIKI_RETRY_DELAY=500Build and run the Docker image:
# Build the image
docker build -t mcp-deepwiki .

# Run with stdio transport (for development)
docker run -it --rm mcp-deepwiki

# Run with HTTP transport (for production)
docker run -d -p 3000:3000 mcp-deepwiki --http --port 3000

# Run with environment variables
docker run -d -p 3000:3000 \
  -e DEEPWIKI_MAX_CONCURRENCY=10 \
  -e DEEPWIKI_REQUEST_TIMEOUT=60000 \
mcp-deepwiki --http --port 3000# Install dependencies
pnpm install
# Run in development mode with stdio
pnpm run dev-stdio
# Run tests
pnpm test
# Run linter
pnpm run lint
# Build the package
pnpm run buildPermission Denied: If you get EACCES errors when running the CLI, make sure to make the binary executable:
chmod +x ./node_modules/.bin/mcp-deepwikiConnection Refused: Make sure the port is available and not blocked by a firewall:
# Check if port is in use
lsof -i :3000
Timeout Errors: For large repositories, consider increasing the timeout and concurrency:
DEEPWIKI_REQUEST_TIMEOUT=60000 DEEPWIKI_MAX_CONCURRENCY=10 npx mcp-deepwikiWe welcome contributions! Please see CONTRIBUTING.md for details.
MIT
X/Twitter: @kregenrek
Bluesky: @kevinkern.dev
Learn Cursor AI: Ultimate Cursor Course
Learn to build software with AI: instructa.ai
AI Prompts - Curated AI Prompts for Cursor AI, Cline, Windsurf and Github Copilot
codefetch - Turn code into Markdown for LLMs with one simple terminal command
aidex A CLI tool that provides detailed information about AI language models, helping developers choose the right model for their needs.# tool-starter
Fetch a deepwiki.com repo and return Markdown
Inputs: url (required), maxDepth, mode, verbose.
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
Loading tool schema changelog…
Scored across 1 tool
With only one tool, there is no possibility of ambiguity or overlap between tools. The tool's purpose is clearly defined as fetching a Deepwiki repo and returning Markdown, making it impossible to confuse with any other tool.
The single tool name follows a consistent verb_noun pattern (deepwiki_fetch), and with only one tool, there is no inconsistency to evaluate. The naming is clear and adheres to a predictable structure.
A single tool is generally too few for a server's purpose, as it limits functionality and may indicate an incomplete surface. For a Deepwiki server, one tool feels thin and under-scoped, lacking operations like search, update, or list repos that might be expected.
The server is severely incomplete for interacting with Deepwiki repos. It only provides a fetch operation, missing essential CRUD/lifecycle coverage such as creating, updating, deleting, or searching repos, which are likely needed for full agent workflows in this domain.
MCP server for opencode documentation, generated by doc2mcp.
Web scraping MCP server: any URL to Markdown or JSON, with JavaScript rendering and batch jobs.
Document-to-Markdown MCP server — convert PDF, Office and HTML into LLM-ready Markdown.
MCP server for innovationlab documentation, generated by doc2mcp.