

A
licenseB
qualityD
maintenanceThis server allows users to perform web searches using Perplexity AI, providing a tool for retrieving search results through a simple API interface.
1
88 npm
3
Apache 2.0
MCP(Model Context Protocol)는 AI 시스템이 다양한 데이터 소스 및 도구와 원활하게 상호 작용할 수 있도록 하는 개방형 표준으로, 안전한 양방향 연결을 용이하게 합니다.
Anthropic에서 개발한 모델 컨텍스트 프로토콜(MCP)은 Claude와 같은 AI 비서가 Tavily의 고급 검색 및 데이터 추출 기능과 원활하게 통합될 수 있도록 지원합니다. 이러한 통합을 통해 AI 모델은 정교한 필터링 옵션과 도메인별 검색 기능을 갖춘 웹 정보에 실시간으로 접근할 수 있습니다.
Tavily MCP 서버는 다음을 제공합니다.
검색, 추출, 매핑, 크롤링 도구
tavily-search 도구를 통한 실시간 웹 검색 기능
tavily-extract 도구를 통한 웹 페이지에서 지능형 데이터 추출
웹사이트의 구조화된 지도를 생성하는 강력한 웹 매핑 도구
웹사이트를 체계적으로 탐색하는 웹 크롤러
Related MCP server: Tavily MCP Server
시작하기 전에 다음 사항을 확인하세요.
Tavily API 키가 없으면 여기에서 무료 계정에 가입할 수 있습니다.
Node.js (v20 이상)
다음을 실행하여 Node.js 설치를 확인할 수 있습니다.
node --version
Git 설치됨(Git 설치 방법을 사용하는 경우에만 필요)
macOS에서: brew install git
Linux의 경우:
Debian/Ubuntu: sudo apt install git
RedHat/CentOS: sudo yum install git
Windows에서: Windows용 Git 다운로드
지엑스피1
Smithery를 통해 Claude Desktop에 Tavily MCP Server를 자동으로 설치하려면:
npx -y @smithery/cli install @tavily-ai/tavily-mcp --client claude서버를 단독으로 실행할 수는 있지만, 단독으로는 그다지 유용하지 않습니다. 대신 MCP 클라이언트에 통합하는 것이 좋습니다. 아래는 Claude Desktop 앱을 tavily-mcp 서버와 함께 사용하도록 구성하는 방법의 예입니다.
이 저장소에서는 tavily-mcp 서버와 함께 작동하도록 VS Code , Cursor 및 Claude Desktop을 구성하는 방법을 설명합니다.
한 번의 클릭으로 설치하려면 아래 설치 버튼 중 하나를 클릭하세요.
먼저 이 섹션 상단에 필요에 맞는 설치 버튼이 있는지 확인하세요. 수동 설치를 원하시면 다음 단계를 따르세요.
VS Code의 사용자 설정(JSON) 파일에 다음 JSON 블록을 추가합니다. Ctrl + Shift + P (macOS에서는 Cmd + Shift + P )를 누르고 Preferences: Open User Settings (JSON) 입력하면 됩니다.
{
  "mcp": {
    "inputs": [
      {
        "type": "promptString",
        "id": "tavily_api_key",
        "description": "Tavily API Key",
        "password": true
      }
    ],
    "servers": {
      "tavily": {
        "command": "npx",
        "args": ["-y", "tavily-mcp@0.2.1"],
        "env": {
          "TAVILY_API_KEY": "${input:tavily_api_key}"
        }
      }
    }
  }
}
선택적으로 작업 공간의 .vscode/mcp.json 이라는 파일에 추가할 수 있습니다.
{
  "inputs": [
    {
      "type": "promptString",
      "id": "tavily_api_key",
      "description": "Tavily API Key",
      "password": true
    }
  ],
  "servers": {
    "tavily": {
      "command": "npx",
      "args": ["-y", "tavily-mcp@0.2.1"],
      "env": {
        "TAVILY_API_KEY": "${input:tavily_api_key}"
      }
    }
  }
}클라인에 Tavily MCP 서버를 설정하는 가장 쉬운 방법은 마켓플레이스를 통해 한 번의 클릭으로 설정하는 것입니다.
VS Code에서 Cline 열기
사이드바에서 Cline 아이콘을 클릭하세요
"MCP 서버" 탭으로 이동합니다(4개의 사각형)
"Tavily"를 검색하고 "설치"를 클릭하세요.
메시지가 표시되면 Tavily API 키를 입력하세요.
또는 Cline에서 Tavily MCP 서버를 수동으로 설정할 수 있습니다.
Cline MCP 설정 파일을 엽니다.
# Using Visual Studio Code
code ~/Library/Application\ Support/Code/User/globalStorage/saoudrizwan.claude-dev/settings/cline_mcp_settings.json

# Or using TextEdit
open -e ~/Library/Application\ Support/Code/User/globalStorage/saoudrizwan.claude-dev/settings/cline_mcp_settings.jsoncode %APPDATA%\Code\User\globalStorage\saoudrizwan.claude-dev\settings\cline_mcp_settings.jsonTavily 서버 구성을 파일에 추가합니다.
your-api-key-here 실제 Tavily API 키로 바꾸세요.
{
  "mcpServers": {
    "tavily-mcp": {
      "command": "npx",
      "args": ["-y", "tavily-mcp@0.2.1"],
      "env": {
        "TAVILY_API_KEY": "your-api-key-here"
      },
      "disabled": false,
      "autoApprove": []
    }
  }
}
파일을 저장하고 Cline이 이미 실행 중이면 다시 시작합니다.
Cline을 사용하면 이제 Tavily MCP 도구를 이용할 수 있습니다. Cline에게 대화에서 tavily-search 및 tavily-extract 도구를 직접 사용해 달라고 요청할 수 있습니다.
참고 : 커서 버전 0.45.6 이상이 필요합니다.
Cursor에서 Tavily MCP 서버를 설정하려면:
커서 설정 열기
기능 > MCP 서버로 이동
"+ 새 MCP 서버 추가" 버튼을 클릭하세요
다음 정보를 입력하세요:
이름 : 서버의 별명을 입력하세요(예: "tavily-mcp")
유형 : 유형으로 "명령"을 선택하세요
명령어 : 서버를 실행하기 위한 명령어를 입력하세요:
env TAVILY_API_KEY=your-api-key npx -y tavily-mcp@0.2.1중요 :
your-api-keyTavily API 키로 바꾸세요. app.tavily.com/home 에서 발급받으실 수 있습니다.
서버를 추가하면 MCP 서버 목록에 나타납니다. 도구 목록을 채우려면 MCP 서버 오른쪽 상단에 있는 새로 고침 버튼을 직접 눌러야 할 수도 있습니다.
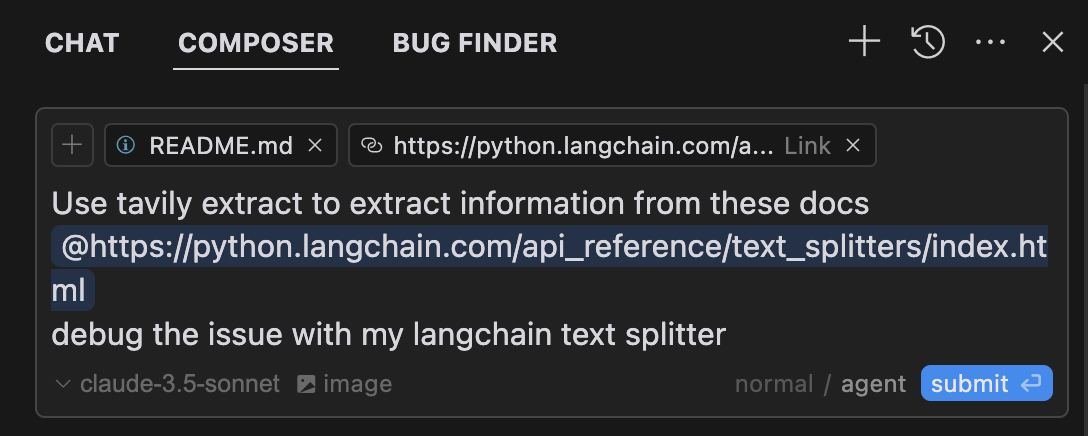
Composer Agent는 귀하의 질의와 관련이 있을 경우 Tavily MCP 도구를 자동으로 사용합니다. 도구 사용을 요청하려면 원하는 작업을 명확하게 설명하는 것이 좋습니다(예: "웹에서 AI 관련 최신 뉴스를 검색하려면 tavily-search를 사용하세요"). Mac에서는 Command + L을 눌러 채팅을 열고, 화면 상단의 Composer 옵션을 선택한 후 제출 버튼 옆의 Agent를 선택하고 준비가 되면 질의를 제출하세요.
# Create the config file if it doesn't exist
touch "$HOME/Library/Application Support/Claude/claude_desktop_config.json"

# Opens the config file in TextEdit
open -e "$HOME/Library/Application Support/Claude/claude_desktop_config.json"

# Alternative method using Visual Studio Code (requires VS Code to be installed)
code "$HOME/Library/Application Support/Claude/claude_desktop_config.json"code %APPDATA%\Claude\claude_desktop_config.jsonyour-api-key-here 실제 Tavily API 키로 바꾸세요.
{
  "mcpServers": {
    "tavily-mcp": {
      "command": "npx",
      "args": ["-y", "tavily-mcp@0.2.1"],
      "env": {
        "TAVILY_API_KEY": "your-api-key-here"
      }
    }
  }
}저장소를 복제합니다.
git clone https://github.com/tavily-ai/tavily-mcp.git
cd tavily-mcp
종속성 설치:
npm install프로젝트를 빌드하세요:
npm run build위의 Claude Desktop 앱 구성 섹션에 설명된 구성 단계를 따르고 아래 JSON 구성을 사용하세요.
your-api-key-here 실제 Tavily API 키로 바꾸고 /path/to/tavily-mcp 시스템에서 저장소를 복제한 실제 경로로 바꾸세요.
{
  "mcpServers": {
    "tavily": {
      "command": "npx",
      "args": ["/path/to/tavily-mcp/build/index.js"],
      "env": {
        "TAVILY_API_KEY": "your-api-key-here"
      }
    }
  }
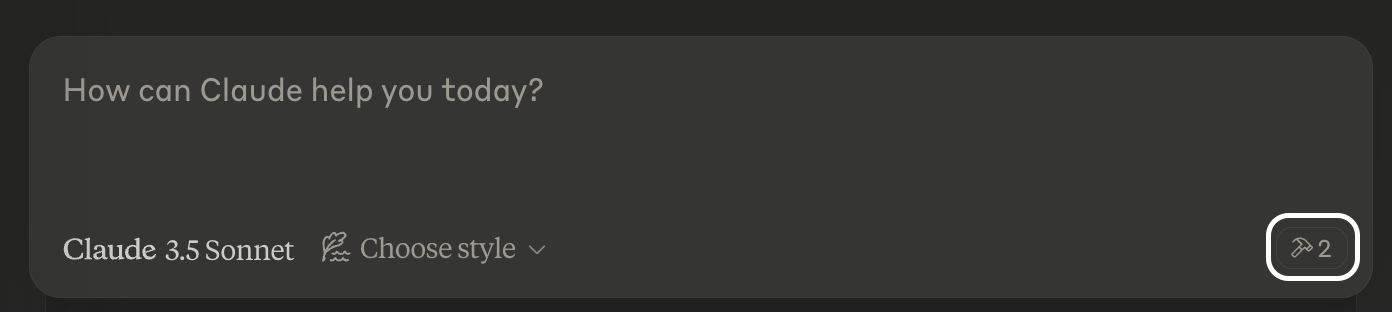
}설치가 완료되고 Claude 데스크톱 앱 구성이 완료되면 Claude 데스크톱 앱을 완전히 닫았다가 다시 열어야 tavily-mcp 서버를 확인할 수 있습니다. 앱 왼쪽 하단에 사용 가능한 MCP 도구를 나타내는 망치 아이콘이 표시됩니다. 망치 아이콘을 클릭하면 tavily-search 및 tavily-extract 도구에 대한 자세한 내용을 확인할 수 있습니다.
이제 Claude는 tavily-search 및 tavily-extract 도구를 포함하여 tavily-mcp 서버에 완전히 접근할 수 있습니다. 아래 예제를 Claude 데스크톱 앱에 삽입하면 tavily-mcp 서버 도구가 작동하는 모습을 볼 수 있습니다.
일반 웹 검색 :
Can you search for recent developments in quantum computing?뉴스 검색 :
Search for news articles about AI startups from the last 7 days.도메인별 검색 :
Search for climate change research on nature.com and sciencedirect.com기사 내용 추출 :
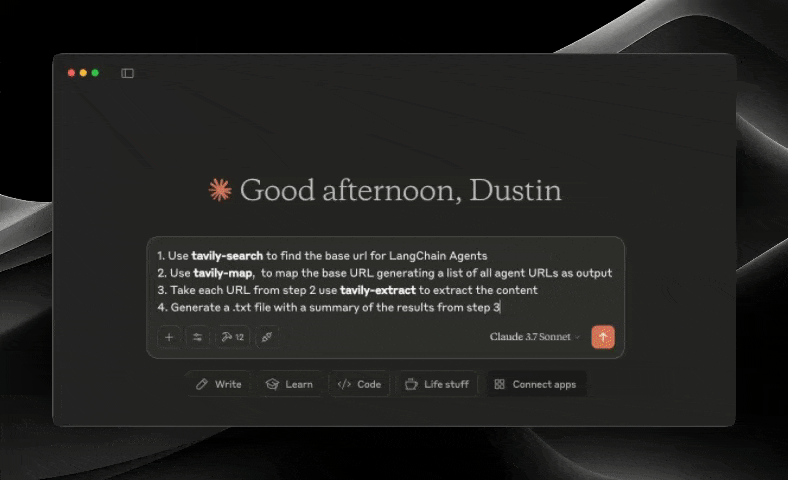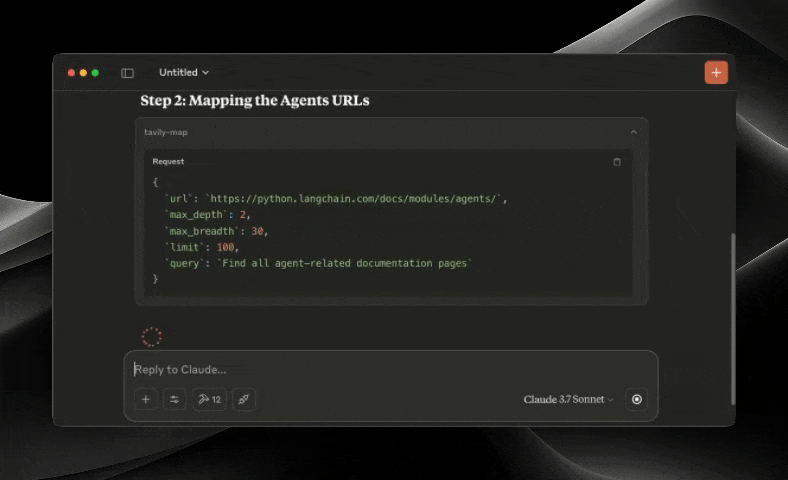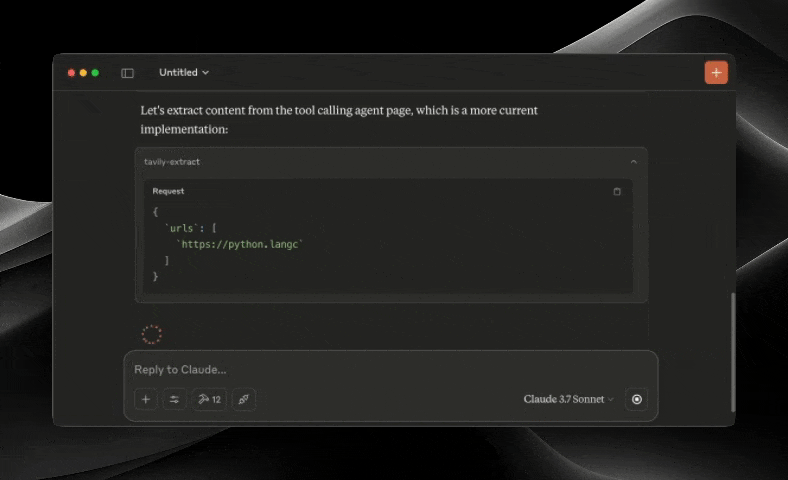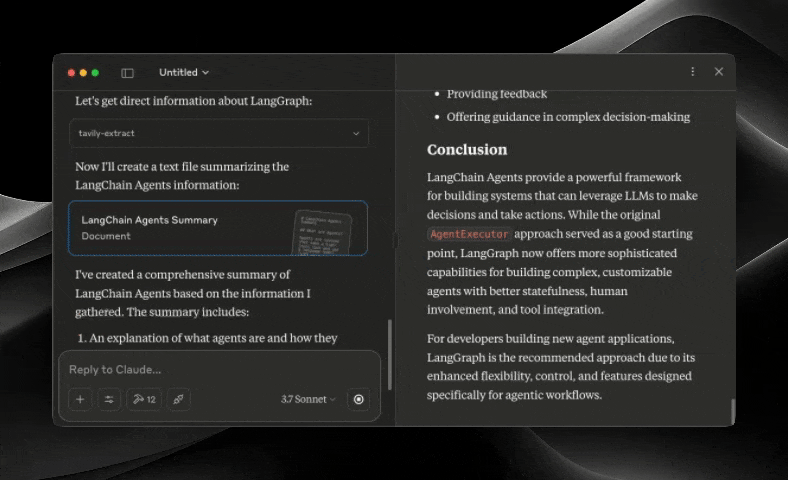
Extract the main content from this article: https://example.com/article또한, tavily-search와 tavily-extract 도구를 결합하여 더욱 복잡한 작업을 수행할 수 있습니다.
Search for news articles about AI startups from the last 7 days and extract the main content from each article to generate a detailed report.서버를 찾을 수 없습니다
npm --verison 실행하여 npm 설치를 확인하세요.
code ~/Library/Application\ Support/Claude/claude_desktop_config.json 실행하여 Claude Desktop 구성 구문을 확인하세요.
node --version 실행하여 Node.js가 제대로 설치되었는지 확인하세요.
NPX 관련 문제
npx 와 관련된 오류가 발생하는 경우, 대신 npx 실행 파일의 전체 경로를 사용해야 할 수 있습니다.
터미널에서 which npx 실행한 다음 구성에서 "command": "npx" 줄을 "command": "/full/path/to/npx" 로 바꾸면 이 경로를 찾을 수 있습니다.
API 키 문제
Tavily API 키가 유효한지 확인하세요
구성에서 API 키가 올바르게 설정되었는지 확인하세요.
API 키 주위에 공백이나 따옴표가 없는지 확인하세요.
MCP 사양을 위한 모델 컨텍스트 프로토콜
클로드 데스크탑을 위한 인류학
A powerful web crawler that initiates a structured web crawl starting from a specified base URL. The crawler expands from that point like a graph, following internal links across pages. You can control how deep and wide it goes, and guide it to focus on specific sections of the site.
| Name | Required | Description | Default |
|---|---|---|---|
| url | Yes | The root URL to begin the crawl | |
| max_depth | No | Max depth of the crawl. Defines how far from the base URL the crawler can explore. | |
| max_breadth | No | Max number of links to follow per level of the tree (i.e., per page) | |
| limit | No | Total number of links the crawler will process before stopping | |
| instructions | No | Natural language instructions for the crawler. Instructions specify which types of pages the crawler should return. | |
| select_paths | No | Regex patterns to select only URLs with specific path patterns (e.g., /docs/.*, /api/v1.*) | |
| select_domains | No | Regex patterns to restrict crawling to specific domains or subdomains (e.g., ^docs\.example\.com$) | |
| allow_external | No | Whether to return external links in the final response | |
| extract_depth | No | Advanced extraction retrieves more data, including tables and embedded content, with higher success but may increase latency | basic |
| format | No | The format of the extracted web page content. markdown returns content in markdown format. text returns plain text and may increase latency. | markdown |
| include_favicon | No | Whether to include the favicon URL for each result |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full burden. It explains the crawler's graph-like expansion and control over depth/breadth, but omits behavioral details such as asynchronicity, rate limits, or side effects. It provides adequate but not comprehensive transparency.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is three sentences long, front-loads the core purpose, and contains no redundant information. Every sentence contributes meaning.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Despite 100% schema coverage and no output schema, the description is somewhat light for a complex 11-parameter tool. It does not mention the output format or any operational constraints (e.g., timeouts, error handling), leaving some gaps in completeness.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so the baseline is 3. The description adds meaningful context beyond the schema by describing the crawler's graph expansion and ability to focus on sections, which enhances understanding of how parameters like max_depth and max_breadth work together.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states it is a web crawler that starts from a base URL and expands like a graph, distinguishing it from sibling tools like extract, map, and search. It specifies the core action (initiates a structured crawl) and the resource (URL).
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description implies usage for structured web crawling but does not explicitly state when to use it versus alternatives (e.g., tavily-search). It lacks explicit when-not or alternative suggestions.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
A powerful web content extraction tool that retrieves and processes raw content from specified URLs, ideal for data collection, content analysis, and research tasks.
| Name | Required | Description | Default |
|---|---|---|---|
| urls | Yes | List of URLs to extract content from | |
| extract_depth | No | Depth of extraction - 'basic' or 'advanced', if usrls are linkedin use 'advanced' or if explicitly told to use advanced | basic |
| include_images | No | Include a list of images extracted from the urls in the response | |
| format | No | The format of the extracted web page content. markdown returns content in markdown format. text returns plain text and may increase latency. | markdown |
| include_favicon | No | Whether to include the favicon URL for each result | |
| query | No | User intent query for reranking extracted chunks based on relevance |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden for behavioral disclosure. It mentions the tool 'retrieves and processes raw content' but doesn't disclose critical behavioral traits: whether it requires authentication, rate limits, error handling, pagination, or what the response structure looks like. The description adds minimal context beyond the basic operation.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized with two concise sentences. The first sentence states the core functionality, and the second provides use cases. There's no wasted text, though it could be slightly more front-loaded with sibling differentiation.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given 6 parameters, no annotations, and no output schema, the description is incomplete. It doesn't explain what the tool returns, error conditions, or behavioral constraints. For a web extraction tool with multiple configuration options and no structured output documentation, the description should provide more context about the extraction results and limitations.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so the schema already documents all 6 parameters thoroughly. The description doesn't add any parameter-specific information beyond what's in the schema. It mentions general purpose but no parameter semantics. Baseline 3 is appropriate when schema does the heavy lifting.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'retrieves and processes raw content from specified URLs' with specific verbs and resource. It mentions use cases like 'data collection, content analysis, and research tasks' which helps understanding. However, it doesn't explicitly differentiate from sibling tools like tavily-crawl or tavily-search, which likely have overlapping web-related functionality.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus its siblings (tavily-crawl, tavily-map, tavily-search). It mentions the tool is 'ideal for data collection, content analysis, and research tasks' but doesn't specify contexts where alternatives might be better. There's no explicit when/when-not guidance or named alternatives.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
A powerful web mapping tool that creates a structured map of website URLs, allowing you to discover and analyze site structure, content organization, and navigation paths. Perfect for site audits, content discovery, and understanding website architecture.
| Name | Required | Description | Default |
|---|---|---|---|
| url | Yes | The root URL to begin the mapping | |
| max_depth | No | Max depth of the mapping. Defines how far from the base URL the crawler can explore | |
| max_breadth | No | Max number of links to follow per level of the tree (i.e., per page) | |
| limit | No | Total number of links the crawler will process before stopping | |
| instructions | No | Natural language instructions for the crawler | |
| select_paths | No | Regex patterns to select only URLs with specific path patterns (e.g., /docs/.*, /api/v1.*) | |
| select_domains | No | Regex patterns to restrict crawling to specific domains or subdomains (e.g., ^docs\.example\.com$) | |
| allow_external | No | Whether to return external links in the final response |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations, the description must cover behavioral traits. It mentions 'crawler' but does not disclose how it handles JavaScript, rate limits, robot.txt, or data retention. The description is insufficient for an agent to understand side effects or constraints.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is concise, consisting of two sentences that efficiently convey the tool's value. However, it could be structured to front-load the core action more clearly.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given 8 parameters, no output schema, and no annotations, the description should explain the output structure (e.g., tree vs. list) and how the map is presented. It omits these critical details, making it incomplete for effective use.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so baseline is 3. The description adds no additional meaning beyond the schema, simply restating the overall purpose without elaborating on parameters.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states it creates a structured map of website URLs for discovering site structure, content organization, and navigation paths. It distinguishes from siblings (crawl, extract, search) by focusing on mapping and analysis.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides some usage context ('Perfect for site audits, content discovery, and understanding website architecture') but lacks explicit guidance on when not to use or how it compares to siblings, leaving the agent to infer.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
A powerful web search tool that provides comprehensive, real-time results using Tavily's AI search engine. Returns relevant web content with customizable parameters for result count, content type, and domain filtering. Ideal for gathering current information, news, and detailed web content analysis.
| Name | Required | Description | Default |
|---|---|---|---|
| query | Yes | Search query | |
| search_depth | No | The depth of the search. It can be 'basic' or 'advanced' | basic |
| topic | No | The category of the search. This will determine which of our agents will be used for the search | general |
| days | No | The number of days back from the current date to include in the search results. This specifies the time frame of data to be retrieved. Please note that this feature is only available when using the 'news' search topic | |
| time_range | No | The time range back from the current date to include in the search results. This feature is available for both 'general' and 'news' search topics | |
| start_date | No | Will return all results after the specified start date. Required to be written in the format YYYY-MM-DD. | |
| end_date | No | Will return all results before the specified end date. Required to be written in the format YYYY-MM-DD | |
| max_results | No | The maximum number of search results to return | |
| include_images | No | Include a list of query-related images in the response | |
| include_image_descriptions | No | Include a list of query-related images and their descriptions in the response | |
| include_raw_content | No | Include the cleaned and parsed HTML content of each search result | |
| include_domains | No | A list of domains to specifically include in the search results, if the user asks to search on specific sites set this to the domain of the site | |
| exclude_domains | No | List of domains to specifically exclude, if the user asks to exclude a domain set this to the domain of the site | |
| country | No | Boost search results from a specific country. This will prioritize content from the selected country in the search results. Available only if topic is general. Country names MUST be written in lowercase, plain English, with spaces and no underscores. | |
| include_favicon | No | Whether to include the favicon URL for each result |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden. It mentions 'real-time results' and 'customizable parameters' but omits important behavioral traits such as rate limits, result count limits, pagination, or whether the operation is read-only. The description implies a read operation but does not explicitly state it.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is two sentences, front-loaded with the primary purpose, and each sentence contributes value without repetition or fluff.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a tool with 15 parameters and no output schema, the description is somewhat brief. It gives a high-level overview but lacks details on return format, result structure, or pagination behavior. The description is adequate but not comprehensive.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so the schema already documents all parameters. The description adds general context by summarizing parameter categories (result count, content type, domain filtering), but does not provide additional meaning beyond what is in the schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly identifies the tool as a web search tool with real-time results and customizable parameters. However, it does not distinguish it from sibling tools like tavily-crawl, tavily-extract, or tavily-map, which may also perform web content retrieval.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No explicit guidance on when to use this tool versus alternatives. The description states it is 'ideal for gathering current information, news, and detailed web content analysis,' but does not specify when to avoid it or mention any exclusions or prerequisites.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
v1.0.0tavily-crawltavily-extracttavily-maptavily-searchScored across 4 tools
Each tool has a clearly distinct purpose: crawling (tavily-crawl) focuses on structured exploration from a base URL, extraction (tavily-extract) retrieves raw content from specific URLs, mapping (tavily-map) analyzes site structure, and search (tavily-search) provides real-time web results. There is no overlap in functionality, making tool selection straightforward for an agent.
All tool names follow a consistent 'tavily-' prefix with a descriptive action suffix (crawl, extract, map, search), using a uniform hyphenated style. This predictable pattern enhances readability and reduces confusion, with no deviations in naming conventions.
With 4 tools, the server is well-scoped for its web-related domain, covering key operations like crawling, extraction, mapping, and search without bloat. Each tool earns its place by addressing a distinct aspect of web interaction, making the count appropriate and manageable.
The tool set provides complete coverage for web-based tasks, including discovery (crawl, map), content retrieval (extract, search), and analysis. There are no obvious gaps; agents can perform end-to-end workflows from finding sites to extracting and analyzing content without dead ends.
The Octagon MCP server provides specialized AI-powered financial research and analysis by integrating with the Octagon Market Intelligence API. It enables users to analyze public market data (SEC filings, earnings transcripts, financial metrics, and stock data for 8000+ companies), private market data (3M+ companies, 500k+ funding rounds, 2M+ M&A/IPO transactions), and conduct deep research including web scraping capabilities. The server also features autonomous research agents that search hundreds of sources and return fully cited reports in approximately one minute.
Driflyte MCP server which lets AI assistants query topic-specific knowledge from web and GitHub.
Web search, browser automation, scraping, crawling and CAPTCHA solving for AI agents.
The Dappier MCP server connects LLMs and AI agents to real-time, rights-cleared, proprietary data from trusted sources across various domains. It provides specialized knowledge through real-time web search, financial stock market and crypto data access, AI-powered content recommendations from premium publishers, and structured outputs with sub-300ms response times, enabling AI systems to respond to current events and trends.