Glama
podaac

CMR Model Context Protocol

Official
by podaac

Protocolo de Contexto de Modelo (MCP) para la Búsqueda de Datos Terrestres de la NASA (CMR)

Este módulo es un protocolo de contexto modelo (MCP) para el repositorio común de metadatos (CMR) de Earthdata de la NASA. El objetivo de este servidor MCP es integrar las recuperaciones de IA con el catálogo de conjuntos de datos de la NASA mediante Earthaccess.

Dependencias

uv: un administrador de paquetes de Python basado en Rust, un cliente LLM, como el escritorio Claude o el escritorio chatGPT (para consumir el MCP)

Related MCP server: Google Earth Engine MCP Server

Instalar y ejecutar

Clone el repositorio en su entorno local o donde se ejecuta su cliente LLM.

git clone https://github.com/podaac/cmr-mcp.git
cd cmr-mcp

Instalar uv

curl -LsSf https://astral.sh/uv/install.sh | sh
uv venv
source .venv/bin/activate

Instalar paquetes con uv

uv sync

Utilice las salidas de which uv (UV_LIB) y PWD (CMR_MCP_INSTALL) para actualizar la siguiente configuración.

Añadiendo al marco de IA

En este ejemplo utilizaremos el escritorio Claude.

Actualice el archivo claude_desktop_config.json (a veces es necesario crearlo). En Mac, suele encontrarse en ~/Library/Application\ Support/Claude/claude_desktop_config.json

Agregue la siguiente configuración, completando los valores de UV_LIB y CMR_MCP_INSTALL; no utilice variables de entorno aquí.

{
    "mcpServers": {
        "cmr": {
            "command": "$UV_LIB$",
            "args": [
                "--directory",
                "$CMR_MCP_INSTALL$",
                "run",
                "cmr-search.py"
            ]
        }
    }
}

Utilice el servidor MCP

Simplemente pídale a su agente que search cmr for... . A continuación, se muestra un ejemplo sencillo de cómo funciona esto.
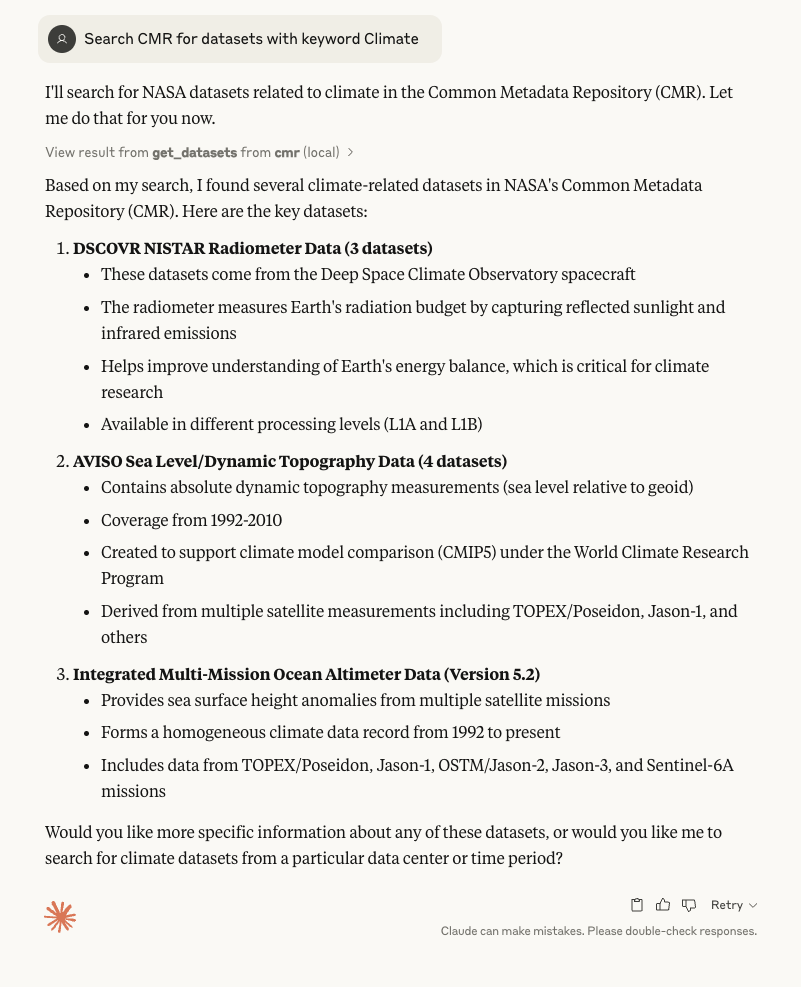
Uso de Claude MCP

Otras indicaciones que pueden funcionar:

  1. Buscar en CMR conjuntos de datos de 2024 a 2025

  2. Busque en CMR conjuntos de datos PO.DAAC de 2020 a 2024 con la palabra clave Clima
Available Tools

1 tool
get_datasetsB

Get a list of datasets form CMR based on keywords.

Args:
    startdate: (Optional) Start date of search request (like "2002" or "2022-03-22")
    stopdate: (Optional) Stop date of search request (like "2002" or "2022-03-22")
    daac: the daac to search, e.g. NSIDC or PODAAC
    keywords: A list of keyword arguments to search collections for.
ParametersJSON Schema
NameRequiredDescriptionDefault
daacNo
keywordNo
startdateNo
stopdateNo

TDQS

B3.1/5.0
Behavior2/5

Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?

With no annotations provided, the description carries the full burden of behavioral disclosure. It mentions the tool retrieves data ('Get a list'), implying a read-only operation, but fails to detail critical behaviors like error handling, rate limits, authentication needs, or response format. This leaves significant gaps in understanding how the tool behaves in practice.

Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.

Conciseness4/5

Is the description appropriately sized, front-loaded, and free of redundancy?

The description is efficiently structured with a clear purpose statement followed by parameter explanations. Each sentence adds value without redundancy. However, the minor typo ('form' instead of 'from') slightly detracts from polish, and the parameter list could be more integrated into the flow rather than a separate block.

Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.

Completeness3/5

Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?

Given the tool's moderate complexity (4 parameters, no output schema, no annotations), the description is partially complete. It covers the purpose and parameters adequately but lacks details on behavioral traits, usage context, and return values. This makes it functional but insufficient for fully informed use without additional assumptions or trial-and-error.

Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.

Parameters4/5

Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?

The description adds meaningful context for all parameters beyond the schema, which has 0% coverage. It explains that 'startdate' and 'stopdate' are for search requests with format examples, 'daac' specifies the source to search, and 'keywords' are for searching collections. This compensates well for the lack of schema descriptions, though it could clarify parameter interactions or constraints.

Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.

Purpose4/5

Does the description clearly state what the tool does and how it differs from similar tools?

The description clearly states the tool's purpose: 'Get a list of datasets from CMR based on keywords.' It specifies the verb ('Get'), resource ('datasets'), and source ('CMR'), making it easy to understand what the tool does. However, with no sibling tools mentioned, there's no explicit differentiation from alternatives, preventing a perfect score.

Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.

Usage Guidelines2/5

Does the description explain when to use this tool, when not to, or what alternatives exist?

The description provides no guidance on when to use this tool versus alternatives, prerequisites, or context for its application. It only lists parameters without explaining the tool's role in workflows or decision criteria for invocation, leaving users to infer usage from the purpose alone.

Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.

Tool Schema Changelog

Recent tool additions, removals, and schema changes observed during successful MCP inspections.

  1. 1 tool updatev1.0.0
    • First observedget_datasets

TDQS

B3.2/5.0

Scored across 1 tool

Disambiguation5/5

With only one tool, there is no possibility of confusion or overlap between tools. The tool has a clear, singular purpose of retrieving datasets from CMR based on search parameters.

Naming Consistency5/5

The single tool name 'get_datasets' follows a clear verb_noun pattern, and there are no other tools to create inconsistency. The naming is straightforward and descriptive.

Tool Count2/5

A single tool is too few for a server named 'CMR Model Context Protocol', which suggests a broader scope for interacting with CMR datasets. This minimal toolset feels thin and incomplete for the apparent domain.

Completeness2/5

The tool surface is severely incomplete for a CMR dataset server. There are obvious gaps: no tools for creating, updating, deleting, or managing datasets, and no support for operations like filtering, sorting, or detailed metadata retrieval beyond basic search.

Maintenance

ActivityInactive
ResponsivenessNo issues

Related MCP Connectors

Related MCP Servers

  • A
    license
    B
    quality
    C
    maintenance
    An MCP server that enables LLMs to query data from various NASA APIs, allowing access to astronomical data, space weather information, Earth imagery, and exoplanet information directly from compatible AI clients.
    21
    6
    MIT
  • F
    license
    Not graded
    quality
    D
    maintenance
    MCP server for accessing SPEAR model output from various sources (AWS, STAC API, local) and integrating with AI assistants like Claude Desktop or a SPEAR Climate Chatbot.
    -