Cyberbro MCP Server
Model Context Protocol-Server für Cyberbro.
Dieses Projekt ist als Standard-Python-Distribution verpackt und kann wie folgt gestartet werden:
uvx mcp-cyberbropip install mcp-cyberbrodannmcp-cyberbro
Warum dieser Server
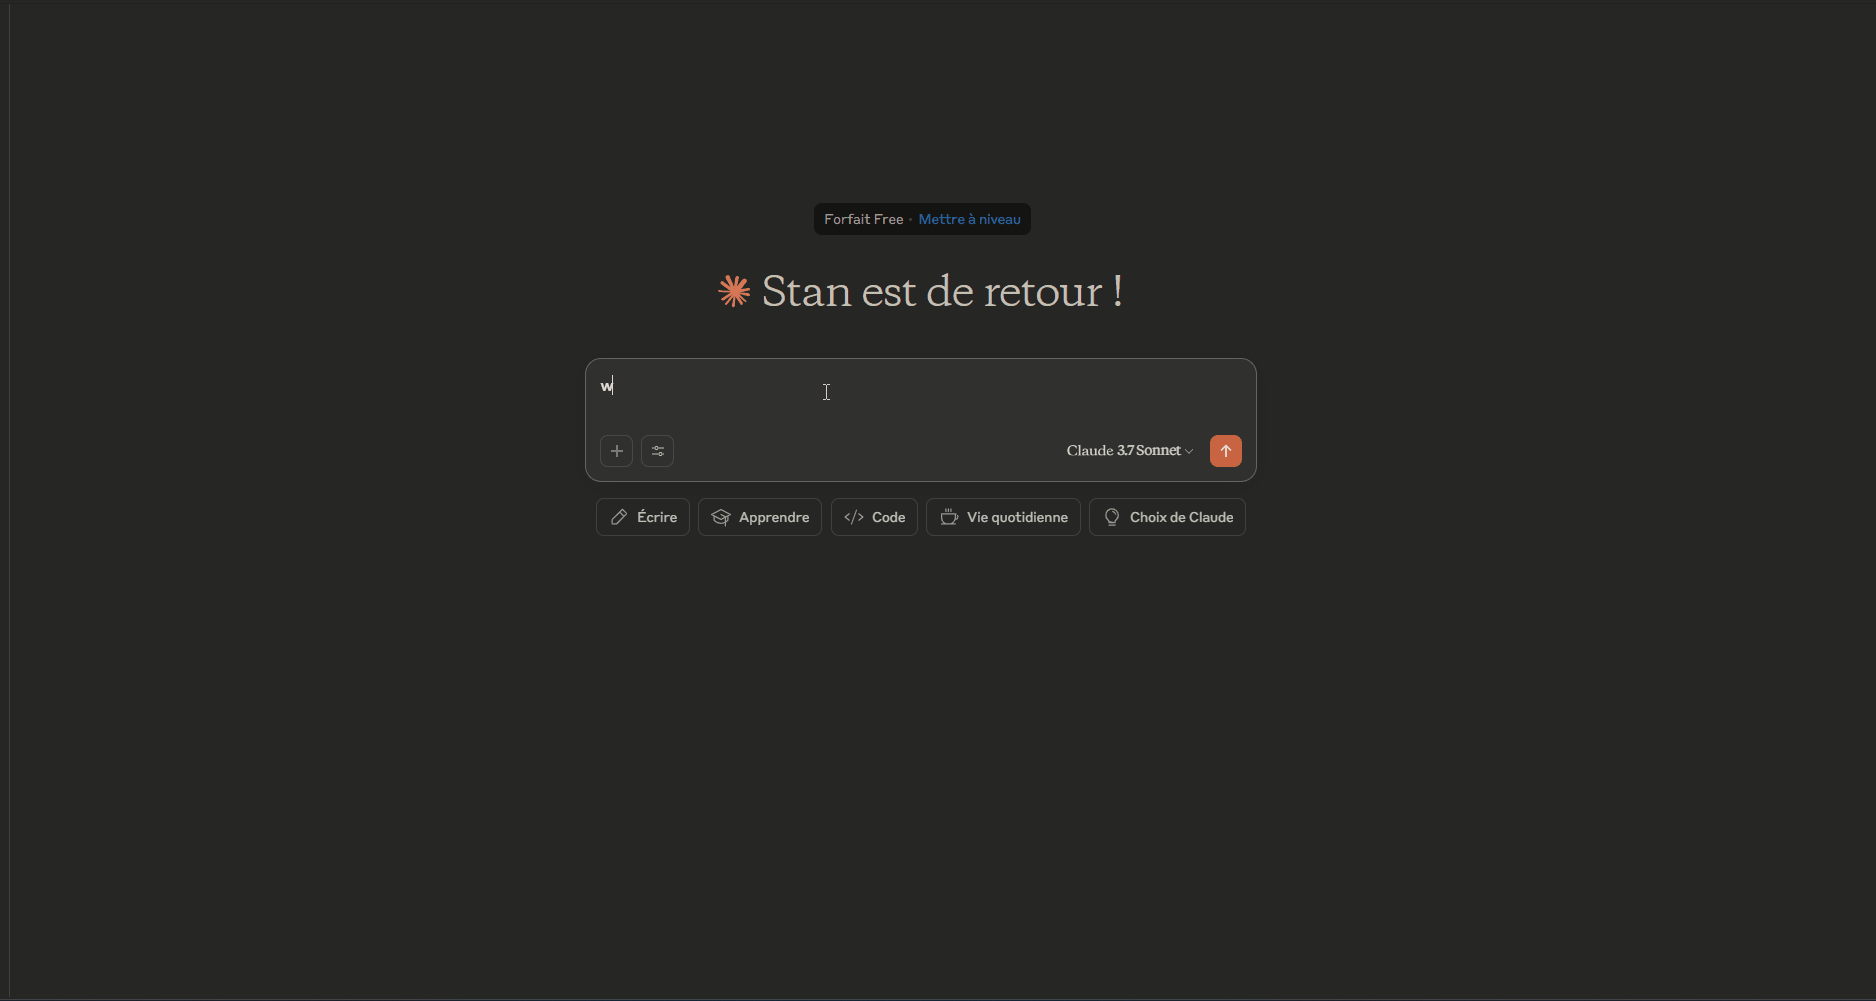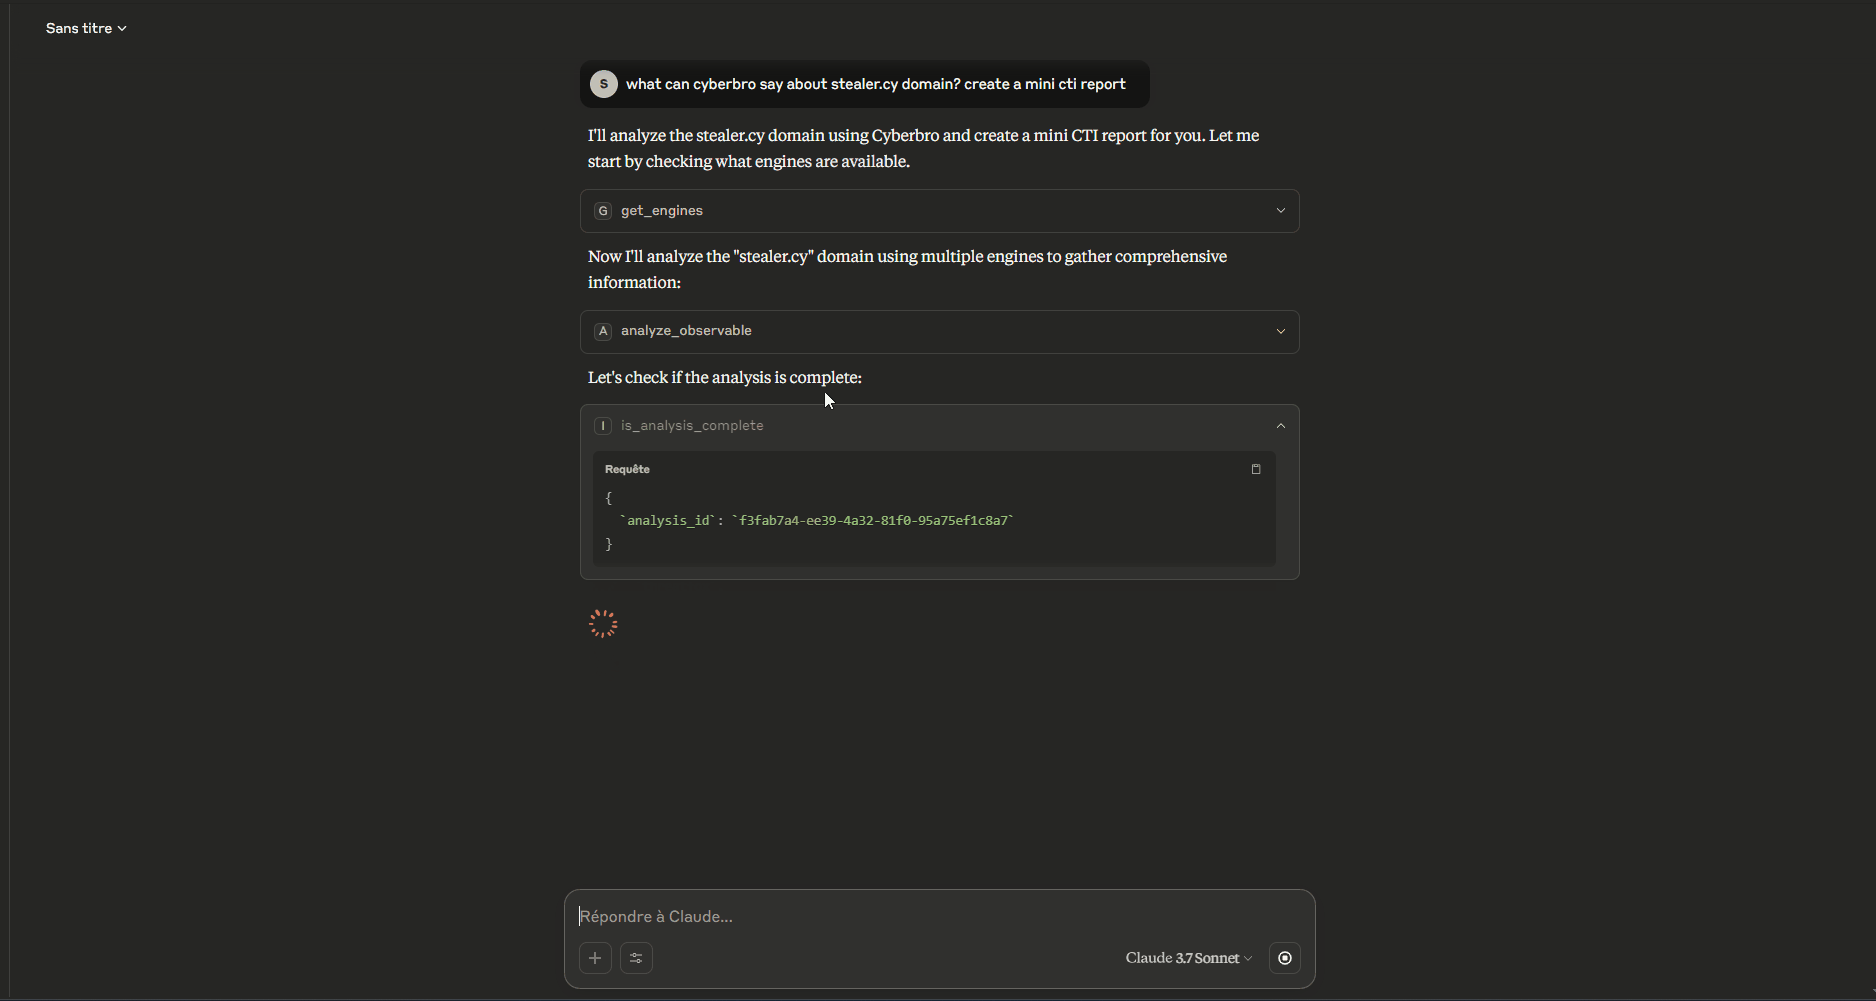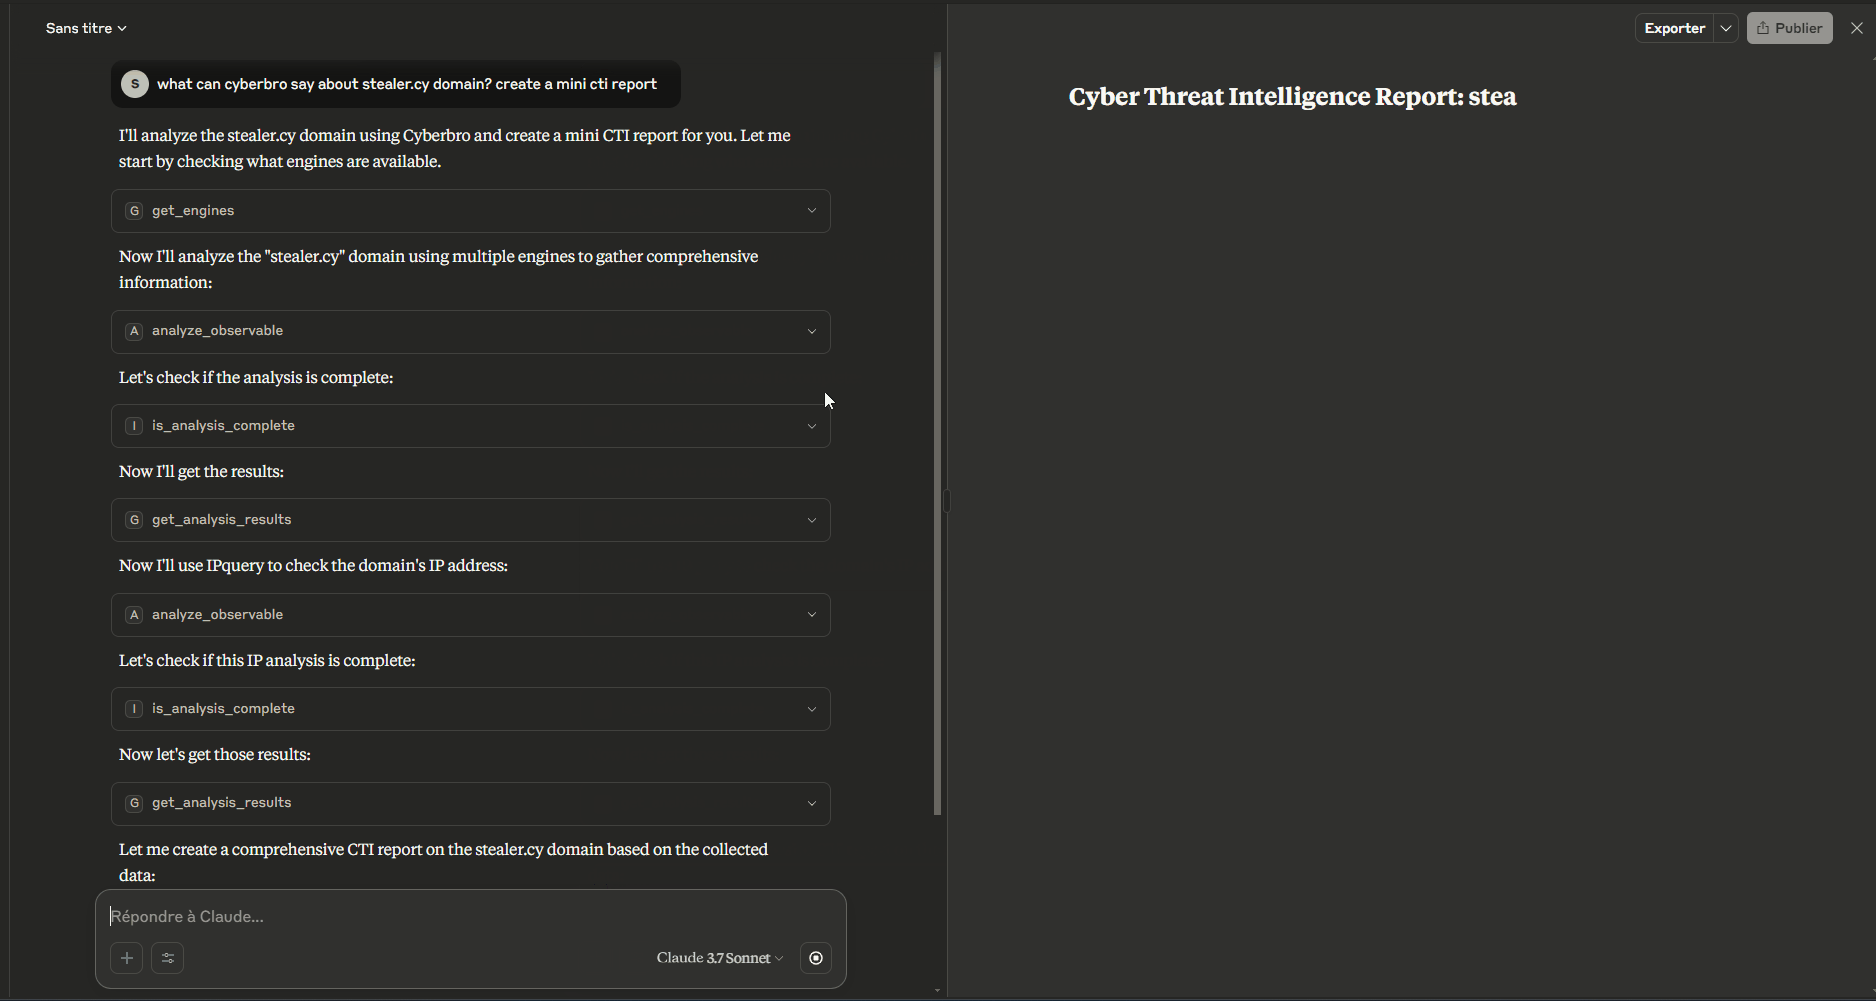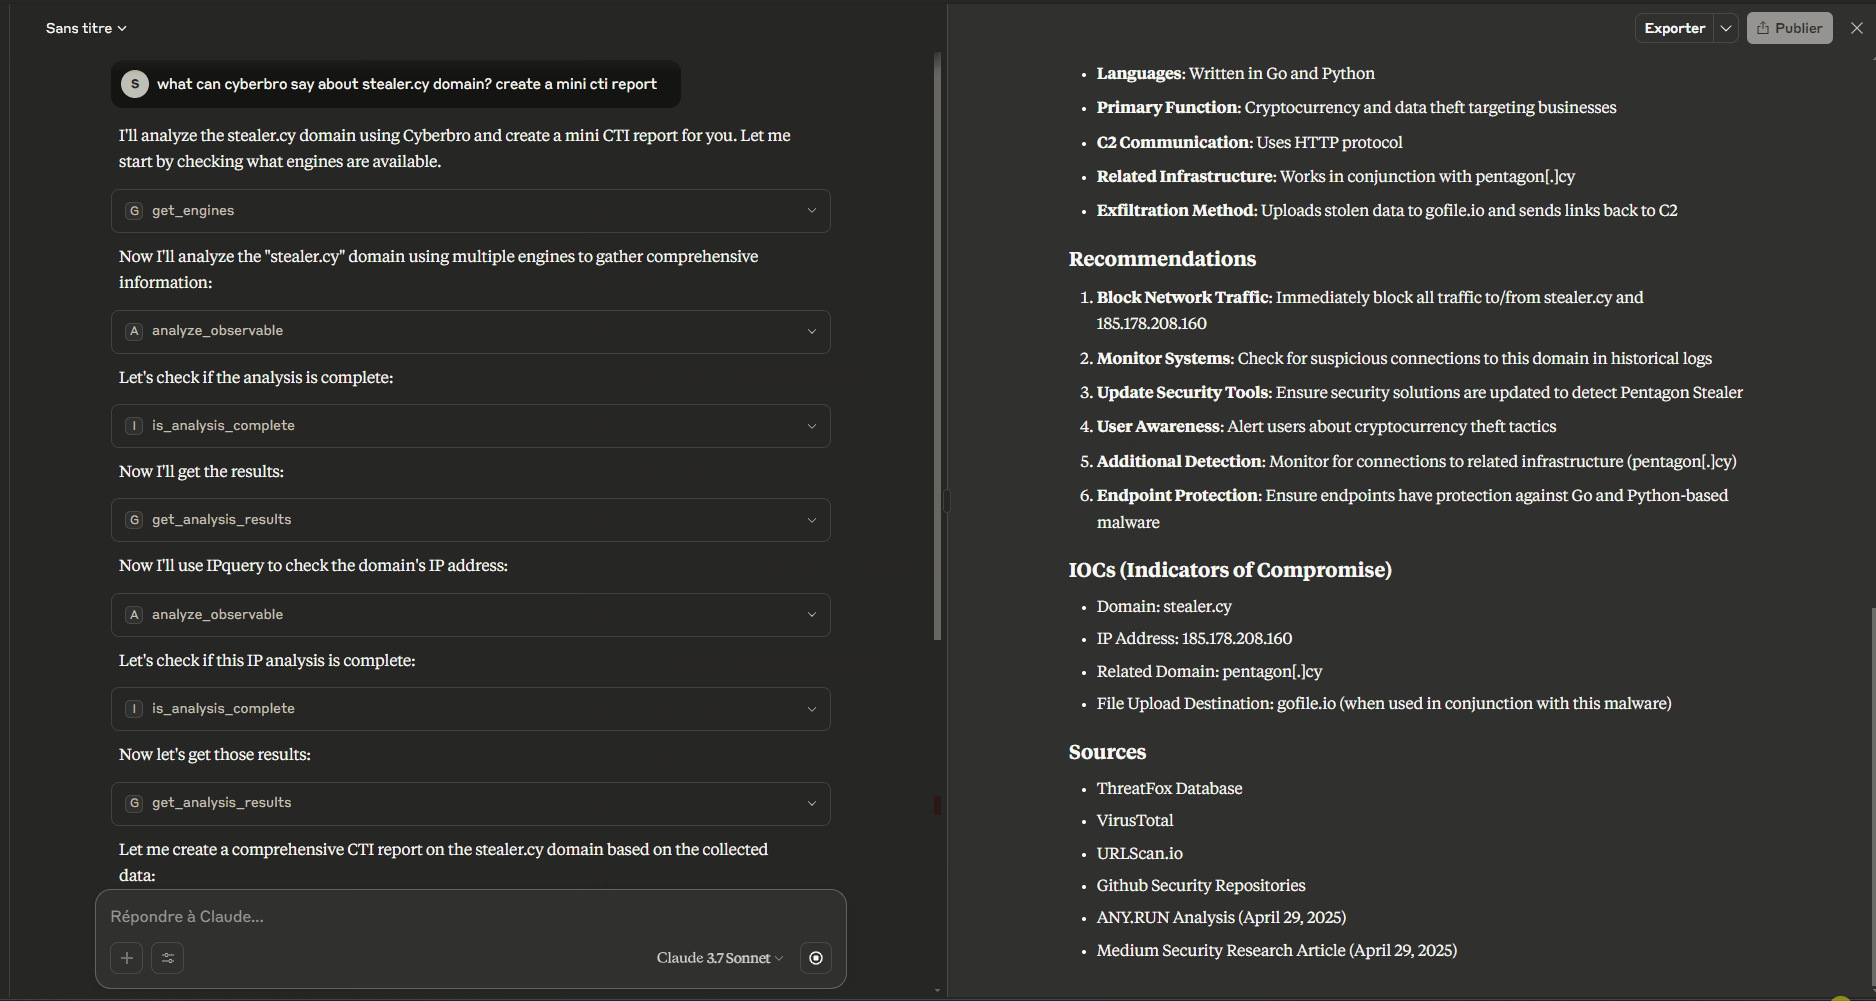
Analysiere Observables (IP, Domain, URL, Hash, etc.) über Cyberbro-Engines.
Integriere Bedrohungsanalyse-Aktionen direkt in MCP-fähige Assistenten.
Ausführung mit
stdio-,sse- oderstreamable-http-Transporten.Kompatibel mit jedem MCP-Client, der einen dieser Transporte unterstützt.
Related MCP server: cortex-mcp
Installation
Verwendung mit uvx (eigenständig)
uvx mcp-cyberbro --cyberbro_url http://localhost:5000Verwendung mit pip
pip install mcp-cyberbro
mcp-cyberbro --cyberbro_url http://localhost:5000Lokale Entwicklung
pip install -e .
mcp-cyberbro --cyberbro_url http://localhost:5000Docker
Der Standard-Container-Befehl startet im streamable-http-Modus auf Port 8000.
docker run --rm -p 8000:8000 \
-e CYBERBRO_URL=http://host.docker.internal:5000 \
ghcr.io/stanfrbd/mcp-cyberbro:latestUm den stdio-Transport zu erzwingen:
docker run -i --rm \
-e CYBERBRO_URL=http://host.docker.internal:5000 \
ghcr.io/stanfrbd/mcp-cyberbro:latest \
--transport stdioKonfiguration
Kopiere .env.example und setze mindestens:
CYBERBRO_URL(erforderlich)
Unterstützte Umgebungsvariablen:
CYBERBRO_URLAPI_PREFIX(Standard:api)SSL_VERIFY(true/false)MCP_TRANSPORT(stdio,sse,streamable-http)MCP_HOSTMCP_PORTMCP_MOUNT_PATHMCP_SSE_PATHMCP_STREAMABLE_HTTP_PATH
CLI-Flags sind ebenfalls verfügbar und überschreiben Umgebungsvariablen.
MCP-Client-Integration
Du kannst diesen Server mit Claude Desktop, Claude Code, Cursor, OpenAI-kompatiblen MCP-Clients oder jedem anderen MCP-Client verwenden.
Beispielkonfiguration mit uvx:
{
"mcpServers": {
"cyberbro": {
"command": "uvx",
"args": ["mcp-cyberbro"],
"env": {
"CYBERBRO_URL": "http://localhost:5000"
}
}
}
}Beispiel mit Docker + stdio:
{
"mcpServers": {
"cyberbro": {
"command": "docker",
"args": [
"run",
"-i",
"--rm",
"-e",
"CYBERBRO_URL",
"ghcr.io/stanfrbd/mcp-cyberbro:latest",
"--transport",
"stdio"
],
"env": {
"CYBERBRO_URL": "http://localhost:5000"
}
}
}
}Verwendung in VSCode - Beispiel
Erstelle .vscode/mcp.json
{
"servers": {
"mcp-cyberbro": {
"type": "stdio",
"command": "uvx",
"args": [
"mcp-cyberbro"
],
"env": {
"CYBERBRO_URL": "http://127.0.0.1:5000"
}
}
}
}MCP-Registry-Metadaten
server.json ist für die Veröffentlichung in der MCP-Registry enthalten und verweist auf das PyPI-Paket mcp-cyberbro.
Release-Pipelines
Release-erstellte Workflows:
.github/workflows/publish-test-pypi.yml.github/workflows/publish-pypi.yml.github/workflows/publish-mcp-plugin.yml
Verfügbare Tools
analyze_observableis_analysis_completeget_analysis_resultsget_enginesget_web_url
Beispiel-Prompts
Hier sind praktische Prompt-Beispiele, die du mit jedem MCP-fähigen Assistenten verwenden kannst, der mit Cyberbro verbunden ist.
Details zu Indikatoren abrufen
Cyberbro: Prüfe Indikatoren für target.com
Kannst du die Reputation dieser IP mit Cyberbro prüfen? 192.168.1.1. Verwende die Engines github, google und virustotal.
Ich möchte die Domain example.com analysieren. Was kann mir Cyberbro darüber sagen? Verwende maximal 3 Engines.
Analysiere diese Observables mit Cyberbro: suspicious-domain.com, 8.8.8.8 und 44d88612fea8a8f36de82e1278abb02f. Verwende alle verfügbaren Engines.
Analyse von Observables
Ich habe dies gefunden (hash|domain|url|ip|extension). Kannst du es zur Analyse an Cyberbro übermitteln und die Ergebnisse analysieren?
OSINT-Untersuchung
Erstelle einen OSINT-Bericht für die Domain example.com mit Cyberbro. Verwende alle verfügbaren Engines und nutze die Ergebnisse für weitere Informationen. Verwende maximal 10 Analyseanfragen.
Danksagungen
Lizenz
MIT
Available Tools
5 toolsanalyze_observableB
Trigger an analysis for a given observable (IP, domain, URL, hash, chrome extension id) using Cyberbro. It can support multiple observables at once separated by spaces. Args: text: Observable(s) to analyze. engines: List of engine names. Returns: The analysis response from Cyberbro API.
| Name | Required | Description | Default |
|---|---|---|---|
| text | Yes | ||
| engines | Yes |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations provided, so description must fully disclose behavior. It lacks details on error handling, rate limits, response time, or side effects. Simply states it triggers analysis and returns response.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Short and direct, with front-loaded purpose. Uses Args/Returns structure but still efficient. No redundant sentences.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Missing key context: no output schema, no explanation of asynchronous behavior, no details on response format. With siblings like get_analysis_results, description should clarify that this returns initial response, not final results.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Adds meaning to parameters by explaining 'text' as observable(s) and 'engines' as list of engine names. Notes multiple observables separated by spaces, but does not specify engine source or format constraints beyond schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states it triggers analysis for observables (IP, domain, URL, hash, chrome extension id) using Cyberbro. It distinguishes from siblings like get_analysis_results and get_engines by indicating it initiates analysis.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Implies usage for initiating analysis, but no explicit when-to-use or alternatives compared to siblings. Mentions support for multiple observables, offering some guidance.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_analysis_resultsB
Retrieve the results of a previous analysis by analysis_id. Args: analysis_id: Analysis ID to retrieve results for. Returns: The analysis results from Cyberbro API.
| Name | Required | Description | Default |
|---|---|---|---|
| analysis_id | Yes |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full disclosure burden. It describes a read operation ('retrieve') but does not disclose error behavior (e.g., if analysis_id is invalid), idempotency, or any side effects. The description adds minimal value beyond the tool name and schema.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is short and uses a clear docstring format with Args and Returns sections. Every sentence serves a purpose, but the Returns section is vague ('analysis results from Cyberbro API'). Still, it is front-loaded and efficient.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a tool with one parameter and no output schema, the description should cover the return format, error cases, and lifecycle expectations. It only states 'the analysis results' generically. Combined with no annotations, the agent lacks context on when results are available or how to interpret them.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate. It restates the parameter as 'analysis_id: Analysis ID to retrieve results for', which adds little meaning beyond the schema's 'title'. No constraints, formats, or examples are provided, leaving the parameter under-documented.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states 'Retrieve the results of a previous analysis by analysis_id', specifying the verb, resource, and key parameter. This distinguishes it from siblings like analyze_observable (starts analysis) and is_analysis_complete (checks status), making the purpose unambiguous.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description implies usage after an analysis is started, but does not explicitly state when to use it versus alternatives such as is_analysis_complete or get_web_url. No conditions, prerequisites, or when-not-to-use information is provided.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_enginesB
List available Cyberbro engines. This is the first tool to be called to get the usable engines. Returns: The list of engines.
| Name | Required | Description | Default |
|---|---|---|---|
No parameters | |||
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations, the description carries the full burden. It only states that the tool lists engines, lacking details on side effects, caching, or any constraints. The return info is minimal.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is short but contains redundancy (the returns line repeats the purpose). It could be more concise by merging the last sentence.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given zero parameters and no output schema, the description adequately covers the tool's purpose and usage order. It is sufficient for such a simple tool.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Input schema has no parameters (0 params), so description compensation is unnecessary. Baseline for zero parameters is 4, and no additional param info is needed.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool lists available Cyberbro engines and positions it as the first tool to call. It distinguishes from siblings like analyze_observable, but does not explicitly contrast them.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides a clear usage hint (call this first), but does not specify when not to use it or offer alternatives. Usage context is implied rather than explicit.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_web_urlB
Get the web GUI URL for a given analysis ID. Args: analysis_id: Analysis ID to get the web URL for. Returns: The web URL from Cyberbro API - Useful for the user to check the results.
| Name | Required | Description | Default |
|---|---|---|---|
| analysis_id | Yes |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Without annotations, the description carries full burden. It only mentions the return value ('web URL from Cyberbro API') but does not disclose read-only nature, authentication needs, or side effects. Behavioral traits are inadequately addressed.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is concise with two sentences and clearly separated args/returns. It is front-loaded with the core purpose. Minor improvement possible by structuring the return statement.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a simple tool with one parameter and no output schema, the description is mostly adequate but lacks guidance on when to use vs siblings and does not explain if the URL requires authentication. A more complete description would mention usage context.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
With 0% schema description coverage, the description adds only a restatement of the parameter purpose ('Analysis ID to get the web URL for'). No format, constraints, or examples are provided, leaving the agent with minimal additional meaning.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool retrieves a web GUI URL for a given analysis ID, using a specific verb and resource. It distinguishes from siblings like get_analysis_results (raw data) and is_analysis_complete (status check).
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No explicit guidance on when to use this tool versus alternatives like get_analysis_results or analyze_observable. The description merely states the function without context for selection.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
is_analysis_completeB
Check if the analysis is complete for the given analysis_id. Args: analysis_id: Analysis ID to check. Returns: The completion status from Cyberbro API.
| Name | Required | Description | Default |
|---|---|---|---|
| analysis_id | Yes |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, and the description lacks behavioral details such as whether the operation is read-only, error handling (e.g., if analysis_id is invalid), or rate limits. It only states that it returns completion status without specifying the format or possible values.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is extremely concise, with the main purpose stated upfront. However, it could include more details without becoming overly long. The structure is clear but minimal.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a simple tool with one parameter and no output schema, the description is somewhat complete. It explains the action and return type ('completion status'), but lacks specifics on the possible status values and error scenarios. Given the simplicity, it is adequate but could be improved.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema has 0% description coverage, and the description only repeats the parameter name and purpose ('analysis_id: Analysis ID to check') without adding any new semantic information beyond what the schema's title already provides. It does not explain constraints, allowed values, or provide examples.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the action ('Check if the analysis is complete') and the resource ('for the given analysis_id'). The tool name itself is specific, and it is distinct from sibling tools like get_analysis_results which retrieve full results.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives (e.g., get_analysis_results). It does not specify that it should be used for polling or as a prerequisite before retrieving results.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Tool Schema Changelog
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
4 tool updates
v0.0.4- Added
get_analysis_results - Added
get_engines - Added
get_web_url - Added
is_analysis_complete
1 tool update
v0.0.3- First observed
analyze_observable
TDQS
Scored across 5 tools
Each tool serves a distinct function: triggering analysis, retrieving results, listing engines, getting web URL, and checking completion. No overlapping purposes.
All tool names follow the consistent verb_noun pattern in snake_case (e.g., analyze_observable, get_analysis_results), making them predictable and easy to distinguish.
With 5 tools, the set is well-scoped for the purpose of observable analysis via Cyberbro. Each tool fills a clear role without redundancy.
The workflow from listing engines to triggering analysis, checking completion, and retrieving results is fully covered. A minor gap is the lack of a tool to list past analyses by date or filter, but core operations are complete.
Maintenance
Related MCP Connectors
Enrich, search, assess, and manage threat intelligence through 80+ typed MCP tools.
Cybersecurity MCP server for URL scanning, threat intelligence, and domain reputation.
Email safety MCP server. Detects phishing, prompt injection, CEO fraud for AI agents.
Security scanner for MCP servers. Detect vulnerabilities, prompt injection, and tool poisoning.
Related MCP Servers
- AlicenseNot gradedqualityDmaintenanceAn MCP server that integrates ThreatBook's threat intelligence API, offering 15 specialized tools for security analysis. It enables AI models to perform IP reputation checks, domain investigations, file sandbox analysis, and vulnerability intelligence lookups.51MIT
- AlicenseAqualityAmaintenanceAn MCP server for the Cortex observable analysis and active response engine. It enables LLMs to automate security investigations by running analyzers on observables like IPs and URLs and executing automated response actions.319 npm1MIT
- AlicenseAqualityAmaintenanceAn MCP server that enables LLMs to interact with MISP for threat intelligence sharing, IOC lookups, and event management. It provides tools for investigating indicators, discovering correlations, and exporting intelligence in formats like STIX and Suricata.367 npm2MIT
- FlicenseNot gradedqualityDmaintenanceA security-focused MCP server that enables automated log retrieval and threat analysis using LangGraph orchestration and RAG. It allows users to detect suspicious activity and generate structured security insights by integrating LLM reasoning with log data and runbook documentation.-