
A
licenseA
qualityD
maintenanceA powerful MCP server for fetching and transforming web content into various formats (HTML, JSON, Markdown, Plain Text) with ease.
4
4,875 npm
42
MIT

Это неофициальный сервер Deepwiki MCP
Он принимает URL-адрес Deepwiki через MCP, сканирует все соответствующие страницы, преобразует их в Markdown и возвращает либо один документ, либо список страниц.
🔒 Безопасность домена : обрабатывает только URL-адреса из deepwiki.com
🧹 Очистка HTML : удаление заголовков, нижних колонтитулов, навигации, скриптов и рекламы.
🔗 Переписывание ссылок : настраивает ссылки для работы в Markdown
📄 Несколько форматов вывода : получите один документ или структурированные страницы
🚀 Производительность : быстрое сканирование с регулируемой конкуренцией и глубиной
НЛП : Это поиск только по названию библиотеки.
Related MCP server: Markdown-To-Notion
Подсказки, которые вы можете использовать:
deepwiki fetch how can i use gpt-image-1 with "vercel ai" sdkdeepwiki fetch how can i create new blocks in shadcn?deepwiki fetch i want to understand how X worksПолучить полную документацию (по умолчанию)
use deepwiki https://deepwiki.com/shadcn-ui/ui
use deepwiki multiple pages https://deepwiki.com/shadcn-ui/ui
Одна страница
use deepwiki fetch single page https://deepwiki.com/tailwindlabs/tailwindcss/2.2-theme-systemПолучить по короткой форме
use deepwiki fetch tailwindlabs/tailwindcssdeepwiki fetch library
deepwiki fetch url
deepwiki fetch <name>/<repo>
deepwiki multiple pages ...
deepwiki single page url ...Добавьте это в файл .cursor/mcp.json .
{
  "mcpServers": {
    "mcp-deepwiki": {
      "command": "npx",
      "args": ["-y", "mcp-deepwiki@latest"]
    }
  }
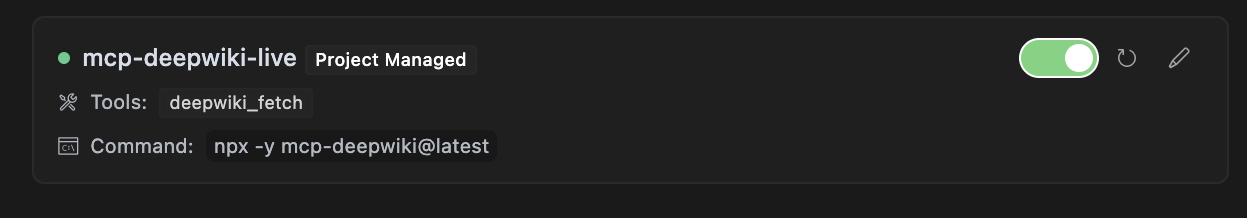
}
Пакет регистрирует инструмент deepwiki_fetch , который можно использовать с любым клиентом, совместимым с MCP:
{
  "action": "deepwiki_fetch",
  "params": {
    "url": "https://deepwiki.com/user/repo",
    "mode": "aggregate",
    "maxDepth": "1"
  }
}url (обязательно): начальный URL-адрес репозитория Deepwiki
mode (необязательно): режим вывода, либо «агрегированный» для одного документа Markdown (по умолчанию), либо «страницы» для структурированных данных страницы.
maxDepth (необязательно): максимальная глубина сканирования страниц (по умолчанию: 10)
{
  "status": "ok",
  "data": "# Page Title\n\nPage content...\n\n---\n\n# Another Page\n\nMore content...",
  "totalPages": 5,
  "totalBytes": 25000,
  "elapsedMs": 1200
}{
"status": "ok",
"data": [
{
"path": "index",
"markdown": "# Home Page\n\nWelcome to the repository."
},
{
"path": "section/page1",
"markdown": "# First Page\n\nThis is the first page content."
}
],
"totalPages": 2,
"totalBytes": 12000,
"elapsedMs": 800
}{
"status": "error",
"code": "DOMAIN_NOT_ALLOWED",
"message": "Only deepwiki.com domains are allowed"
}{
"status": "partial",
"data": "# Page Title\n\nPage content...",
"errors": [
{
"url": "https://deepwiki.com/user/repo/page2",
"reason": "HTTP error: 404"
}
],
"totalPages": 1,
"totalBytes": 5000,
"elapsedMs": 950
}При использовании инструмента вы будете получать события прогресса во время сканирования:
Fetched https://deepwiki.com/user/repo: 12500 bytes in 450ms (status: 200)
Fetched https://deepwiki.com/user/repo/page1: 8750 bytes in 320ms (status: 200)
Fetched https://deepwiki.com/user/repo/page2: 6200 bytes in 280ms (status: 200){
"mcpServers": {
"mcp-deepwiki": {
"command": "node",
"args": ["./bin/cli.mjs"]
}
}
}# Clone the repository
git clone https://github.com/regenrek/deepwiki-mcp.git
cd deepwiki-mcp
# Install dependencies
npm install
# Build the package
npm run buildДля HTTP-транспорта вы можете выполнять прямые вызовы API:
curl -X POST http://localhost:3000/mcp \
  -H "Content-Type: application/json" \
  -d '{
    "id": "req-1",
    "action": "deepwiki_fetch",
    "params": {
      "url": "https://deepwiki.com/user/repo",
      "mode": "aggregate"
    }
}'DEEPWIKI_MAX_CONCURRENCY : Максимальное количество одновременных запросов (по умолчанию: 5)
DEEPWIKI_REQUEST_TIMEOUT : Время ожидания запроса в миллисекундах (по умолчанию: 30000)
DEEPWIKI_MAX_RETRIES : Максимальное количество попыток повтора для неудачных запросов (по умолчанию: 3)
DEEPWIKI_RETRY_DELAY : Базовая задержка для повторной попытки в миллисекундах (по умолчанию: 250)
Чтобы настроить их, создайте файл .env в корне проекта:
DEEPWIKI_MAX_CONCURRENCY=10
DEEPWIKI_REQUEST_TIMEOUT=60000
DEEPWIKI_MAX_RETRIES=5
DEEPWIKI_RETRY_DELAY=500Соберите и запустите образ Docker:
# Build the image
docker build -t mcp-deepwiki .

# Run with stdio transport (for development)
docker run -it --rm mcp-deepwiki

# Run with HTTP transport (for production)
docker run -d -p 3000:3000 mcp-deepwiki --http --port 3000

# Run with environment variables
docker run -d -p 3000:3000 \
  -e DEEPWIKI_MAX_CONCURRENCY=10 \
  -e DEEPWIKI_REQUEST_TIMEOUT=60000 \
mcp-deepwiki --http --port 3000# Install dependencies
pnpm install
# Run in development mode with stdio
pnpm run dev-stdio
# Run tests
pnpm test
# Run linter
pnpm run lint
# Build the package
pnpm run buildОтказано в доступе : если при запуске CLI возникают ошибки EACCES, обязательно сделайте двоичный файл исполняемым:
chmod +x ./node_modules/.bin/mcp-deepwikiВ подключении отказано : убедитесь, что порт доступен и не заблокирован брандмауэром:
# Check if port is in use
lsof -i :3000
Ошибки тайм-аута : для больших репозиториев рассмотрите возможность увеличения тайм-аута и параллелизма:
DEEPWIKI_REQUEST_TIMEOUT=60000 DEEPWIKI_MAX_CONCURRENCY=10 npx mcp-deepwikiМы приветствуем ваши вклады! Подробности смотрите на CONTRIBUTING.md .
Массачусетский технологический институт
X/Твиттер: @kregenrek
Bluesky: @kevinkern.dev
Изучите искусственный интеллект курсора: окончательный курс по курсору
Научитесь создавать программное обеспечение с помощью ИИ: instructa.ai
Подсказки ИИ — тщательно подобранные подсказки ИИ для Cursor AI, Cline, Windsurf и Github Copilot
codefetch — преобразуйте код в Markdown для LLM с помощью одной простой команды терминала
aidex Инструмент CLI, предоставляющий подробную информацию о языковых моделях ИИ, помогающий разработчикам выбрать правильную модель для своих нужд.# tool-starter
Fetch a deepwiki.com repo and return Markdown
| Name | Required | Description | Default |
|---|---|---|---|
| url | Yes | should be a URL, owner/repo name (e.g. "vercel/ai"), a two-word "owner repo" form (e.g. "vercel ai"), or a single library keyword | |
| maxDepth | No | Can fetch a single site => maxDepth 0 or multiple/all sites => maxDepth 1 | |
| mode | No | aggregate | |
| verbose | No |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It mentions fetching and returning Markdown but omits critical details like authentication requirements, rate limits, error handling, or whether this is a read-only operation. For a tool with no annotation coverage, this is insufficient.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is extremely concise—a single sentence that directly states the tool's purpose. Every word earns its place, with no unnecessary elaboration. It's front-loaded and efficiently communicates the core functionality.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (4 parameters, 50% schema coverage, no output schema, no annotations), the description is inadequate. It doesn't explain what 'fetching' entails, how the Markdown is structured, error conditions, or usage constraints. For a tool with significant undocumented aspects, more context is needed.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 50%, with only the 'url' parameter well-documented in the schema. The description adds no parameter-specific information beyond what the schema provides. It doesn't explain the meaning of 'maxDepth', 'mode', or 'verbose' parameters, leaving gaps in understanding.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the action ('fetch') and resource ('deepwiki.com repo'), and specifies the output format ('return Markdown'). It distinguishes the tool by mentioning the specific domain (deepwiki.com) and output type. However, without sibling tools, there's no explicit differentiation from alternatives.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus other methods or tools. It lacks context about prerequisites, typical use cases, or limitations. With no sibling tools mentioned, it doesn't address alternatives within the server.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
deepwiki_fetchScored across 1 tool
With only one tool, there is no possibility of ambiguity or overlap between tools. The tool's purpose is clearly defined as fetching a Deepwiki repo and returning Markdown, making it impossible to confuse with any other tool.
The single tool name follows a consistent verb_noun pattern (deepwiki_fetch), and with only one tool, there is no inconsistency to evaluate. The naming is clear and adheres to a predictable structure.
A single tool is generally too few for a server's purpose, as it limits functionality and may indicate an incomplete surface. For a Deepwiki server, one tool feels thin and under-scoped, lacking operations like search, update, or list repos that might be expected.
The server is severely incomplete for interacting with Deepwiki repos. It only provides a fetch operation, missing essential CRUD/lifecycle coverage such as creating, updating, deleting, or searching repos, which are likely needed for full agent workflows in this domain.
MCP server for opencode documentation, generated by doc2mcp.
Document-to-Markdown MCP server — convert PDF, Office and HTML into LLM-ready Markdown.
MCP server for innovationlab documentation, generated by doc2mcp.
MCP server for accessing curated awesome list documentation