
A
licenseA
qualityD
maintenanceA powerful MCP server for fetching and transforming web content into various formats (HTML, JSON, Markdown, Plain Text) with ease.
4
4,875 npm
42
MIT

이것은 비공식 Deepwiki MCP 서버 입니다.
MCP를 통해 Deepwiki URL을 가져와서 모든 관련 페이지를 크롤링하고 이를 마크다운으로 변환한 다음, 페이지별로 하나의 문서나 목록을 반환합니다.
🔒 도메인 안전 : deepwiki.com의 URL만 처리합니다.
🧹 HTML 정리 : 헤더, 푸터, 탐색, 스크립트 및 광고를 제거합니다.
🔗 링크 재작성 : 마크다운에서 작동하도록 링크를 조정합니다.
📄 다양한 출력 형식 : 하나의 문서 또는 구조화된 페이지를 가져옵니다.
🚀 성능 : 조정 가능한 동시성 및 깊이를 갖춘 빠른 크롤링
NLP : 도서관 이름만으로 검색하는 것입니다.
Related MCP server: Markdown-To-Notion
사용할 수 있는 프롬프트:
지엑스피1
deepwiki fetch how can i create new blocks in shadcn?deepwiki fetch i want to understand how X works전체 문서 가져오기(기본값)
use deepwiki https://deepwiki.com/shadcn-ui/ui
use deepwiki multiple pages https://deepwiki.com/shadcn-ui/ui
단일 페이지
use deepwiki fetch single page https://deepwiki.com/tailwindlabs/tailwindcss/2.2-theme-system단축형으로 받으세요
use deepwiki fetch tailwindlabs/tailwindcssdeepwiki fetch library
deepwiki fetch url
deepwiki fetch <name>/<repo>
deepwiki multiple pages ...
deepwiki single page url ...이것을 .cursor/mcp.json 파일에 추가하세요.
{
  "mcpServers": {
    "mcp-deepwiki": {
      "command": "npx",
      "args": ["-y", "mcp-deepwiki@latest"]
    }
  }
}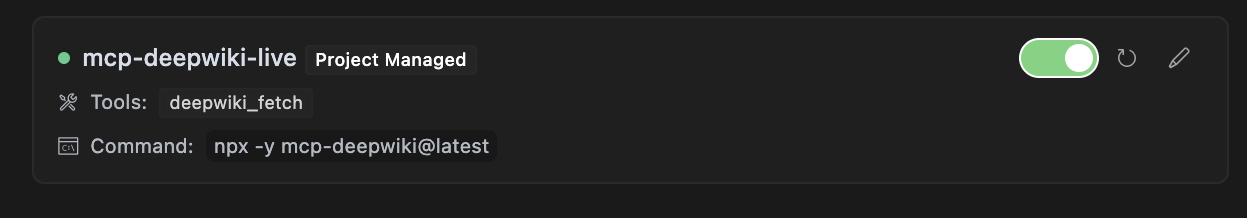
이 패키지는 MCP 호환 클라이언트와 함께 사용할 수 있는 deepwiki_fetch 라는 도구를 등록합니다.
{
  "action": "deepwiki_fetch",
  "params": {
    "url": "https://deepwiki.com/user/repo",
    "mode": "aggregate",
    "maxDepth": "1"
  }
}url (필수): Deepwiki 저장소의 시작 URL
mode (선택 사항): 단일 마크다운 문서의 경우 "집계"(기본값) 또는 구조화된 페이지 데이터의 경우 "페이지" 출력 모드
maxDepth (선택 사항): 크롤링할 페이지의 최대 깊이(기본값: 10)
{
  "status": "ok",
  "data": "# Page Title\n\nPage content...\n\n---\n\n# Another Page\n\nMore content...",
  "totalPages": 5,
  "totalBytes": 25000,
  "elapsedMs": 1200
}{
"status": "ok",
"data": [
{
"path": "index",
"markdown": "# Home Page\n\nWelcome to the repository."
},
{
"path": "section/page1",
"markdown": "# First Page\n\nThis is the first page content."
}
],
"totalPages": 2,
"totalBytes": 12000,
"elapsedMs": 800
}{
"status": "error",
"code": "DOMAIN_NOT_ALLOWED",
"message": "Only deepwiki.com domains are allowed"
}{
"status": "partial",
"data": "# Page Title\n\nPage content...",
"errors": [
{
"url": "https://deepwiki.com/user/repo/page2",
"reason": "HTTP error: 404"
}
],
"totalPages": 1,
"totalBytes": 5000,
"elapsedMs": 950
}이 도구를 사용하면 크롤링 중에 진행률 이벤트를 받게 됩니다.
Fetched https://deepwiki.com/user/repo: 12500 bytes in 450ms (status: 200)
Fetched https://deepwiki.com/user/repo/page1: 8750 bytes in 320ms (status: 200)
Fetched https://deepwiki.com/user/repo/page2: 6200 bytes in 280ms (status: 200){
"mcpServers": {
"mcp-deepwiki": {
"command": "node",
"args": ["./bin/cli.mjs"]
}
}
}# Clone the repository
git clone https://github.com/regenrek/deepwiki-mcp.git
cd deepwiki-mcp
# Install dependencies
npm install
# Build the package
npm run buildHTTP 전송의 경우 직접 API 호출을 할 수 있습니다.
curl -X POST http://localhost:3000/mcp \
  -H "Content-Type: application/json" \
  -d '{
    "id": "req-1",
    "action": "deepwiki_fetch",
    "params": {
      "url": "https://deepwiki.com/user/repo",
      "mode": "aggregate"
    }
}'DEEPWIKI_MAX_CONCURRENCY : 최대 동시 요청 수(기본값: 5)
DEEPWIKI_REQUEST_TIMEOUT : 요청 시간 초과(밀리초) (기본값: 30000)
DEEPWIKI_MAX_RETRIES : 실패한 요청에 대한 최대 재시도 횟수(기본값: 3)
DEEPWIKI_RETRY_DELAY : 재시도 백오프에 대한 기본 지연 시간(밀리초)(기본값: 250)
이를 구성하려면 프로젝트 루트에 .env 파일을 만듭니다.
DEEPWIKI_MAX_CONCURRENCY=10
DEEPWIKI_REQUEST_TIMEOUT=60000
DEEPWIKI_MAX_RETRIES=5
DEEPWIKI_RETRY_DELAY=500
Docker 이미지를 빌드하고 실행합니다.
# Build the image
docker build -t mcp-deepwiki .

# Run with stdio transport (for development)
docker run -it --rm mcp-deepwiki

# Run with HTTP transport (for production)
docker run -d -p 3000:3000 mcp-deepwiki --http --port 3000

# Run with environment variables
docker run -d -p 3000:3000 \
  -e DEEPWIKI_MAX_CONCURRENCY=10 \
  -e DEEPWIKI_REQUEST_TIMEOUT=60000 \
mcp-deepwiki --http --port 3000# Install dependencies
pnpm install
# Run in development mode with stdio
pnpm run dev-stdio
# Run tests
pnpm test
# Run linter
pnpm run lint
# Build the package
pnpm run build권한 거부 : CLI를 실행할 때 EACCES 오류가 발생하면 바이너리를 실행 가능하게 만들어야 합니다.
chmod +x ./node_modules/.bin/mcp-deepwiki연결 거부 : 포트가 사용 가능하고 방화벽으로 차단되지 않았는지 확인하세요.
# Check if port is in use
lsof -i :3000
시간 초과 오류 : 대규모 저장소의 경우 시간 초과 및 동시성을 늘리는 것을 고려하세요.
DEEPWIKI_REQUEST_TIMEOUT=60000 DEEPWIKI_MAX_CONCURRENCY=10 npx mcp-deepwiki기여를 환영합니다! 자세한 내용은 CONTRIBUTING.md를 참조하세요.
MIT
X/트위터: @kregenrek
블루스카이: @kevinkern.dev
커서 AI 배우기: 궁극의 커서 코스
AI를 활용한 소프트웨어 구축 방법 배우기: instructa.ai
Fetch a deepwiki.com repo and return Markdown
| Name | Required | Description | Default |
|---|---|---|---|
| url | Yes | should be a URL, owner/repo name (e.g. "vercel/ai"), a two-word "owner repo" form (e.g. "vercel ai"), or a single library keyword | |
| maxDepth | No | Can fetch a single site => maxDepth 0 or multiple/all sites => maxDepth 1 | |
| mode | No | aggregate | |
| verbose | No |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It mentions fetching and returning Markdown but omits critical details like authentication requirements, rate limits, error handling, or whether this is a read-only operation. For a tool with no annotation coverage, this is insufficient.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is extremely concise—a single sentence that directly states the tool's purpose. Every word earns its place, with no unnecessary elaboration. It's front-loaded and efficiently communicates the core functionality.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (4 parameters, 50% schema coverage, no output schema, no annotations), the description is inadequate. It doesn't explain what 'fetching' entails, how the Markdown is structured, error conditions, or usage constraints. For a tool with significant undocumented aspects, more context is needed.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 50%, with only the 'url' parameter well-documented in the schema. The description adds no parameter-specific information beyond what the schema provides. It doesn't explain the meaning of 'maxDepth', 'mode', or 'verbose' parameters, leaving gaps in understanding.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the action ('fetch') and resource ('deepwiki.com repo'), and specifies the output format ('return Markdown'). It distinguishes the tool by mentioning the specific domain (deepwiki.com) and output type. However, without sibling tools, there's no explicit differentiation from alternatives.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus other methods or tools. It lacks context about prerequisites, typical use cases, or limitations. With no sibling tools mentioned, it doesn't address alternatives within the server.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
deepwiki_fetchScored across 1 tool
With only one tool, there is no possibility of ambiguity or overlap between tools. The tool's purpose is clearly defined as fetching a Deepwiki repo and returning Markdown, making it impossible to confuse with any other tool.
The single tool name follows a consistent verb_noun pattern (deepwiki_fetch), and with only one tool, there is no inconsistency to evaluate. The naming is clear and adheres to a predictable structure.
A single tool is generally too few for a server's purpose, as it limits functionality and may indicate an incomplete surface. For a Deepwiki server, one tool feels thin and under-scoped, lacking operations like search, update, or list repos that might be expected.
The server is severely incomplete for interacting with Deepwiki repos. It only provides a fetch operation, missing essential CRUD/lifecycle coverage such as creating, updating, deleting, or searching repos, which are likely needed for full agent workflows in this domain.
MCP server for opencode documentation, generated by doc2mcp.
Document-to-Markdown MCP server — convert PDF, Office and HTML into LLM-ready Markdown.
MCP server for innovationlab documentation, generated by doc2mcp.
MCP server for accessing curated awesome list documentation