Glama
MCP Scholarly Server

MCP Scholarly Server

by adityak74

mcp-scholarly MCP server

A MCP server to search for accurate academic articles. More scholarly vendors will be added soon.

Search tools

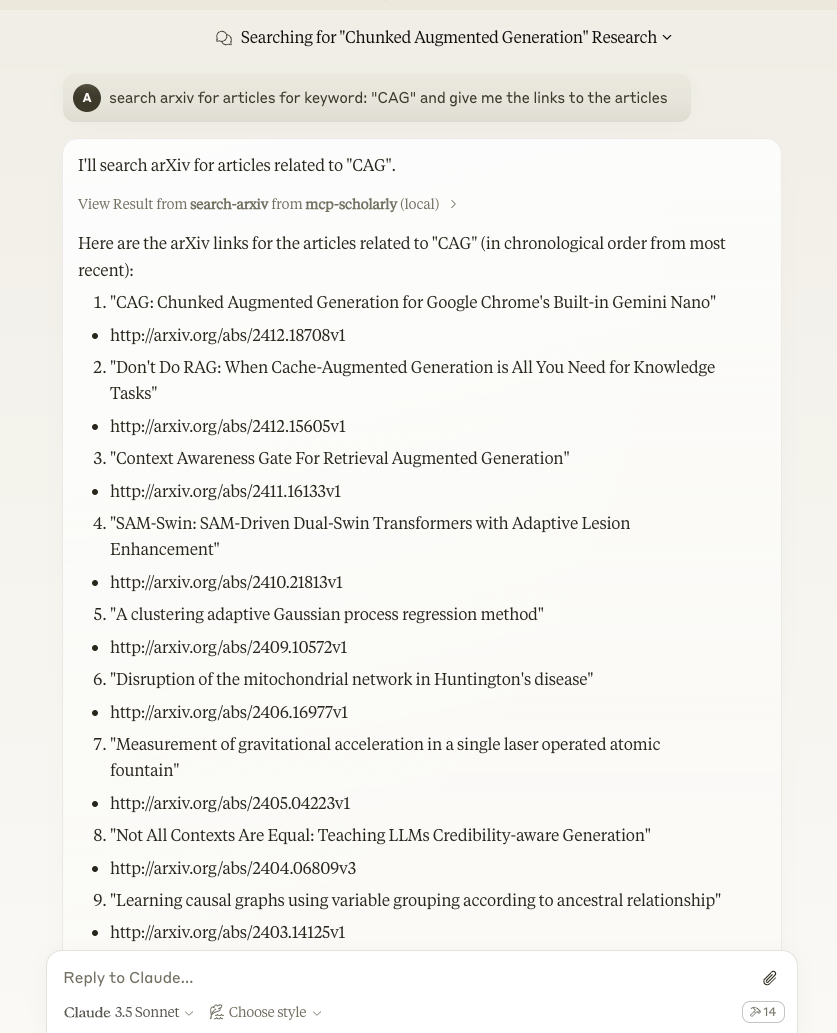
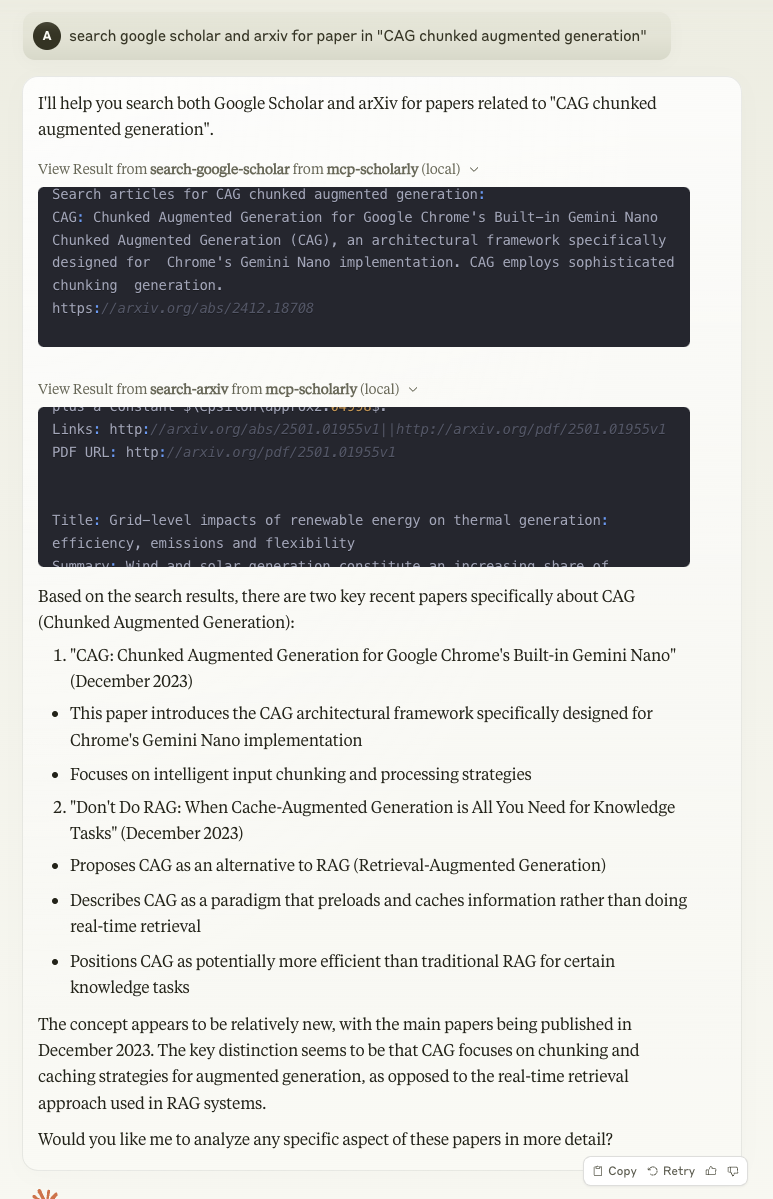
  • search-arxiv — arXiv search (no key needed)

  • search-google-scholar — Google Scholar via the scholarly library (free proxy pool)

  • search-google-web — Google web search via the SerpBase API. Optional; only registered when SERPBASE_API_KEY is set. Get a key at https://serpbase.dev/dashboard/api-keys (free tier available).
demo1.jpeg

image

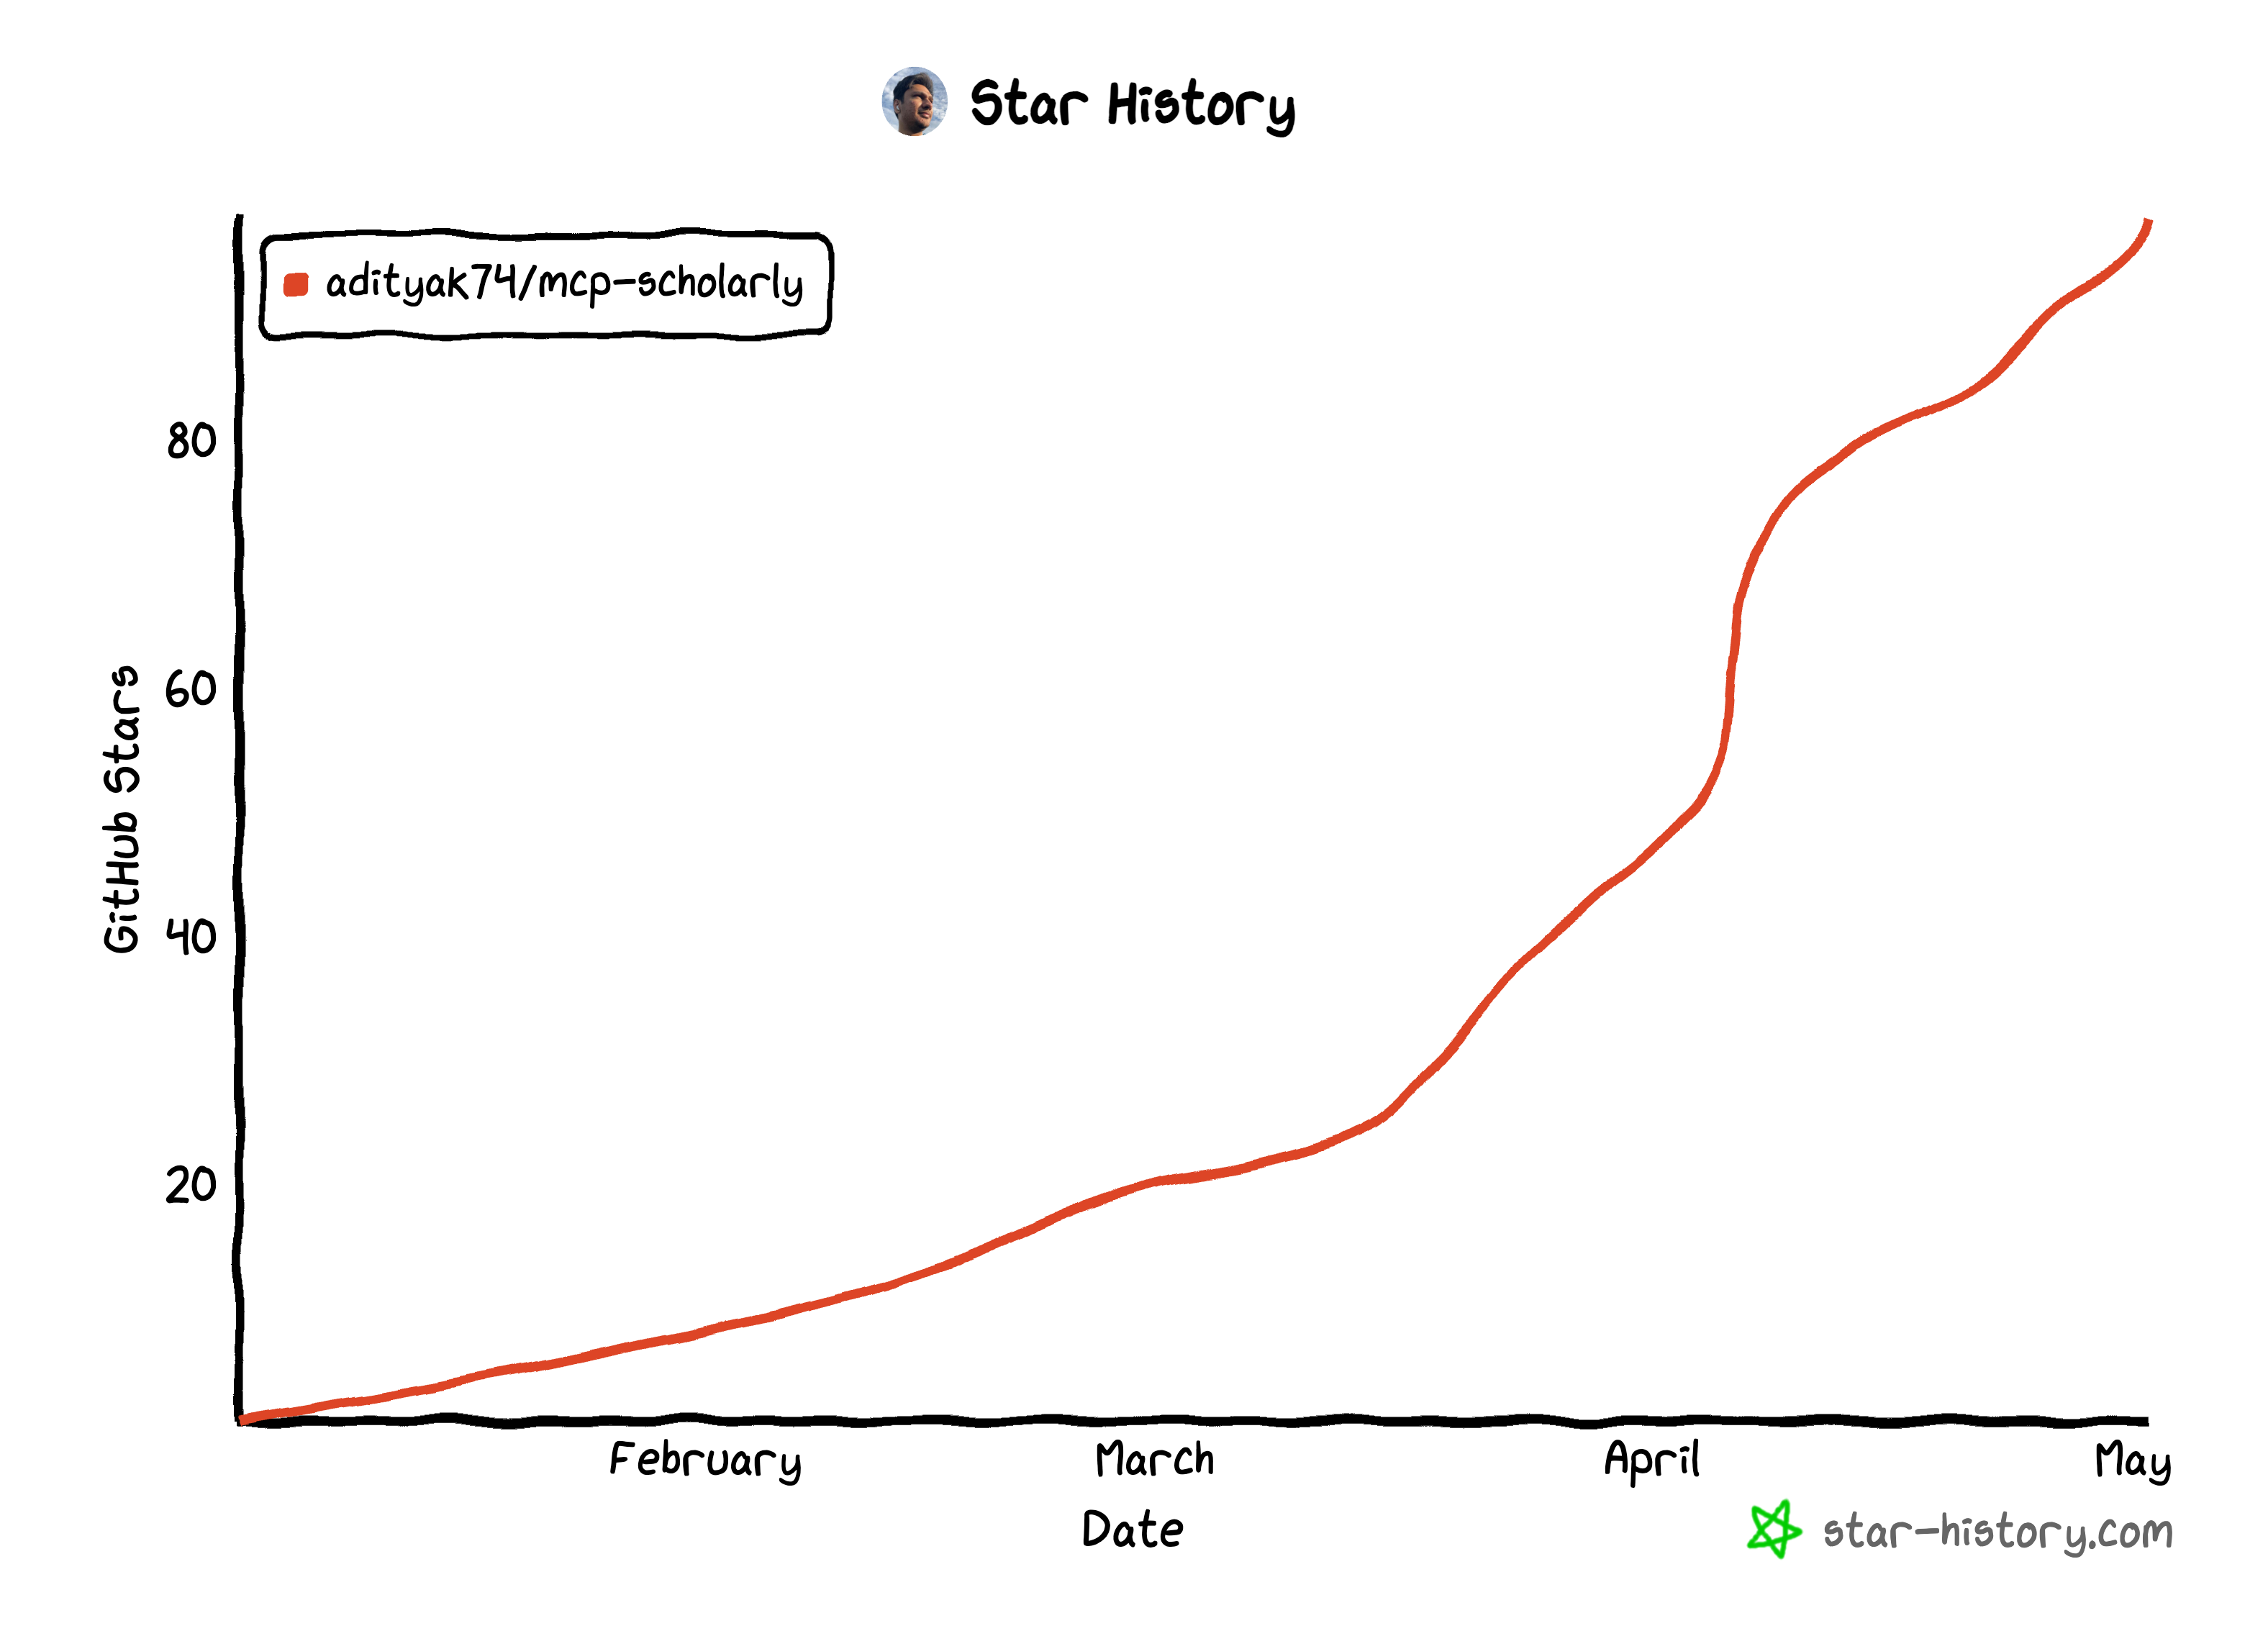
star-history-202551

Related MCP server: arXiv MCP Server

Components

Tools

The server implements one tool:

  • search-arxiv: Search arxiv for articles related to the given keyword.

    • Takes "keyword" as required string arguments

Quickstart

Install

Claude Desktop

On MacOS: ~/Library/Application\ Support/Claude/claude_desktop_config.json On Windows: %APPDATA%/Claude/claude_desktop_config.json

or if you are using Docker

Installing via Smithery

To install mcp-scholarly for Claude Desktop automatically via Smithery:

npx -y @smithery/cli install mcp-scholarly --client claude

Development

Building and Publishing

To prepare the package for distribution:

  1. Sync dependencies and update lockfile:

uv sync
  1. Build package distributions:

uv build

This will create source and wheel distributions in the dist/ directory.

  1. Publish to PyPI:

uv publish

Note: You'll need to set PyPI credentials via environment variables or command flags:

  • Token: --token or UV_PUBLISH_TOKEN

  • Or username/password: --username/UV_PUBLISH_USERNAME and --password/UV_PUBLISH_PASSWORD

Debugging

Since MCP servers run over stdio, debugging can be challenging. For the best debugging experience, we strongly recommend using the MCP Inspector.

You can launch the MCP Inspector via npm with this command:

npx @modelcontextprotocol/inspector uv --directory /Users/adityakarnam/PycharmProjects/mcp-scholarly/mcp-scholarly run mcp-scholarly

Upon launching, the Inspector will display a URL that you can access in your browser to begin debugging.

Using with zorp

zorp needs a search-capable MCP tool before validate will run. This server satisfies that check, because zorp matches on a search verb in the tool name and these tools are called search-arxiv and search-google-scholar.

zorp-agent --yes \
  --mcp "stdio:scholarly:uv:run:mcp-scholarly" \
  validate "<your research question>"

Or configure it once, so every run picks it up:

# .zorp/mcp.toml
[[server]]
name = "scholarly"
transport = "stdio"
command = "uv"
args = ["run", "mcp-scholarly"]
trust = "sandbox"
timeout_secs = 60

Notes measured against zorp's transport, not assumed:

  • search-arxiv answers in about 1 second. zorp's default stdio read budget is 30 seconds, so the default is comfortable. timeout_secs = 60 above is headroom for search-google-scholar, which goes through scholarly and a free proxy pool and is far less predictable.

  • Logging goes to stderr. Nothing but JSON-RPC reaches stdout, which is what zorp's newline-delimited framing requires.

  • An empty keyword comes back as an MCP tool error rather than an empty result set. zorp cares about that distinction: a failed search that looks like "no prior work" would put a wrong novelty score into an evidence record.

  • arxiv returns best-effort matches for any query, including nonsense, so a non-empty result set is not by itself evidence that prior work exists. The tool description says so, since that is the text the model reads.

Available Tools

2 tools
search-arxivC

Search arxiv for articles related to the given keyword.

Inputs: keyword (required).

search-google-scholarC

Search google scholar for articles related to the given keyword.

Inputs: keyword (required).

Tool Schema Changelog

Recent tool additions, removals, and schema changes observed during successful MCP inspections.

Loading tool schema changelog…

    TDQS

    B3/5.0

    Scored across 2 tools

    Disambiguation5/5

    The two tools have clearly distinct purposes: one searches ArXiv specifically, while the other searches Google Scholar. There is no overlap in their functionality, and an agent can easily choose the appropriate tool based on the desired academic database.

    Naming Consistency5/5

    Both tools follow a consistent verb_noun pattern with 'search' as the verb and the database name as the noun (arxiv, google-scholar). The naming is uniform and predictable across the set.

    Tool Count2/5

    With only 2 tools, the server feels thin for a 'Scholarly Server' that might be expected to handle broader academic tasks. While search is a core function, typical scholarly workflows could benefit from additional tools like fetching article details, citations, or managing references.

    Completeness2/5

    The server is severely incomplete for a scholarly domain, as it only provides search functionality without any tools for retrieving full articles, accessing metadata, or performing follow-up actions like citation analysis. This leaves significant gaps that could hinder agent workflows.

    Maintenance

    ActivityStale
    ResponsivenessLimited data

    Related MCP Connectors

    Related MCP Servers

    • F
      license
      Not graded
      quality
      D
      maintenance
      Enables querying and discovering the latest arXiv papers by category or keyword, providing structured metadata including titles, authors, summaries, and links for research assistance and literature review workflows.
      -
    • A
      license
      B
      quality
      D
      maintenance
      Enables searching and retrieving academic papers from arXiv by various criteria including title, author, and category, with support for extracting full text content from PDFs.
      4
      MIT
    • F
      license
      Not graded
      quality
      D
      maintenance
      Enables searching and retrieving academic papers from arXiv by topic, allowing users to discover research papers and extract their metadata including titles, authors, abstracts, and PDF links through natural language queries.
      -
    • F
      license
      Not graded
      quality
      D
      maintenance
      Enables searching, downloading, and analyzing academic papers from arXiv and Semantic Scholar to extract key insights and citation metrics. It facilitates autonomous knowledge acquisition by processing research findings and integrating them into persistent AI memory systems.
      -