NocturnusAI
NocturnusAI is a deterministic context engineering engine for AI agents that reduces LLM token usage by sending only changed information through logical inference and truth maintenance.
Knowledge Management
tell— Assert facts with optional confidence scores, TTL/expiration, negation, and conflict resolution strategies (REJECT, NEWEST_WINS, CONFIDENCE, KEEP_BOTH)bulk_assert— Assert multiple facts in a single call with per-fact error reportingforget/retract_pattern— Retract specific facts or wildcard-matched patterns with automatic cascading removal of all derived knowledge
Logical Reasoning
teach— Define logical rules supporting backward-chaining inference and Negation-as-Failureask— Query the knowledge base via multi-step backward chaining with unification, variable bindings, confidence filtering, and optional proof chain output
Context & Memory Optimization
context— Retrieve goal-driven, salience-ranked context (recency × frequency × priority) with incremental diffs showing only what changed since the last turn, inpredicate,natural, orstructuredoutput formatscompress— Consolidate repeated episodic patterns into semantic summaries to reduce memory footprintcleanup— Expire TTL-based facts and evict low-salience facts to prevent unbounded memory growth
Temporal & Historical Queries
recall— Time-travel query to reconstruct what was known at a specific past timestamp, respectingvalidFrom,validUntil, and TTL bounds
Schema Discovery & Analytics
predicates— Discover all relationship types with arity, fact counts, and rule associationsaggregate— Compute COUNT, SUM, MIN, MAX, or AVG over facts matching a pattern
Hypothetical / Scoped Reasoning
fork_scope— Branch the knowledge base into an isolated copy for hypothetical reasoning without affecting the main knowledge basemerge_scope— Commit results from a hypothetical scope back with configurable conflict strategies (SOURCE_WINS, TARGET_WINS, KEEP_BOTH, REJECT)list_scopes/delete_scope— Manage active reasoning branches
Integration & Developer Experience
Integrates with LangChain, CrewAI, AutoGen, and other AI frameworks
Python and TypeScript SDKs, REST API, CLI, and MCP-compliant server
Multi-tenancy support via scope and tenant isolation
Integrates with CrewAI framework for agent-based workflows using NocturnusAI's turn reduction and context management
Provides Docker deployment options for running NocturnusAI server with persistent data storage
Supports Google's LLM models as a provider for natural-language turn extraction and fact extraction
Integrates with LangChain framework for building LLM applications with NocturnusAI's context optimization
Integrates with LangGraph for building stateful, multi-agent applications with NocturnusAI's context management
Enables natural-language turn extraction using Ollama's local LLM models for fact extraction from conversational turns
Supports OpenAI's LLM models as a provider for natural-language turn extraction and fact extraction
NocturnusAI
The context engineering engine for AI agents: send only what changed.
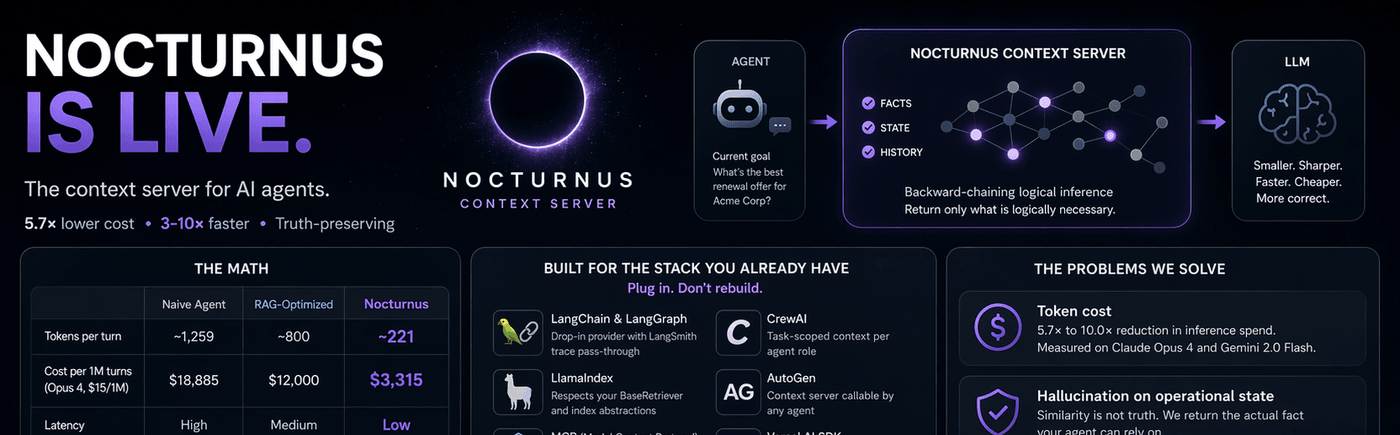
Before / After
# ❌ Without NocturnusAI — replay everything, every turn
messages = system_prompt + full_history + tool_outputs # ~1,259 tokens/turn
response = llm(messages) # $13,600/mo at scale
# ✅ With NocturnusAI — send only what changed
ctx = nocturnus.process_turns(raw_turns) # extract → infer → delta
messages = system_prompt + ctx.briefing_delta # ~221 tokens/turn
response = llm(messages) # $2,400/mo. Same accuracy.Related MCP server: RelayPlane
The Numbers
Measured on live APIs. 15-turn product support conversation. Real usage.input_tokens counts. Run it yourself.
Naive replay | RAG-optimized | NocturnusAI | |
Tokens per turn | ~1,259 | ~800 | ~221 |
Cost per month (1K req/hr, Opus 4, $15/1M) | $13,600 | $12,000 | $2,400 |
Latency | high | medium | low |
Truth-preserving | no | no | yes |
Claude Opus 4: 5.7× reduction. Gemini 2.0 Flash: 10.0×. Full calculations.
Install
pip install nocturnusai # Python
npm install nocturnusai-sdk # TypeScript
docker run -p 9300:9300 ghcr.io/auctalis/nocturnusai:latest # DockerOr use the setup wizard:
curl -fsSL https://raw.githubusercontent.com/Auctalis/nocturnusai/main/install.sh | bashWhy Developers Star This Repo
Reproducible token reduction — benchmark in the repo, methodology published, run it against your own workload
Deterministic inference — same query, same result, every time. No embedding drift, no cosine similarity lottery
Truth maintenance — retract a fact, all derived conclusions auto-retract. No stale context, no hallucination on operational state
Plugs into existing stacks — LangChain, LlamaIndex, CrewAI, AutoGen, MCP, Vercel AI SDK, OpenAI Agents SDK, Mastra
Benchmarkable against naive replay — numbers derived, not invented. Every claim traces to a notebook cell
Framework Quickstarts
Framework | Integration | Link |
LangChain / LangGraph | Drop-in | |
CrewAI | Task-scoped context per agent role | |
AutoGen | Context server callable by any agent | |
MCP | Spec-compliant server for Claude Desktop, Cursor, Continue | |
OpenAI Agents SDK | Context middleware, no tool modifications | |
Vercel AI SDK | Edge-compatible adapter for Next.js, Nuxt, SvelteKit | |
Python SDK |
| |
TypeScript SDK |
|
How It Works
Three steps. Every turn.
Extract — raw conversation turns → structured facts via LLM extraction
Infer — backward-chaining logical inference finds only the facts reachable from the agent's current goal
Return the delta — a
briefingDeltacontaining only what changed since the last turn
This is not vector search. It is not summarization. It is deterministic inference on a logic engine — Hexastore indexing, backward chaining, and truth maintenance.
The Working Loop
LLM required for natural-language turns. The examples below send raw text turns through an LLM to extract structured facts. If you start the server without an LLM provider, natural-language turns will return zero facts. See Quick Start for setup options, or use predicate syntax (e.g.,
"customer_tier(acme_corp, enterprise)") which works without any LLM.
1. First reduction: POST /context
curl -X POST http://localhost:9300/context \
-H 'Content-Type: application/json' \
-H 'X-Tenant-ID: default' \
-d '{
"turns": [
"user: Customer says they are enterprise and blocked on SLA credits.",
"tool: CRM says account is Acme Corp with a 2M ARR contract.",
"agent: Last week support promised to review SLA eligibility.",
"tool: Billing note says renewal is due next month."
],
"maxFacts": 12
}'2. Goal-driven pass: POST /memory/context
curl -X POST http://localhost:9300/memory/context \
-H 'Content-Type: application/json' \
-H 'X-Tenant-ID: default' \
-d '{
"goals": [{"predicate":"eligible_for_sla","args":["acme_corp"]}],
"maxFacts": 12,
"sessionId": "ticket-42"
}'3. Later turns: POST /context/diff
curl -X POST http://localhost:9300/context/diff \
-H 'Content-Type: application/json' \
-H 'X-Tenant-ID: default' \
-d '{"sessionId": "ticket-42", "maxFacts": 12}'Returns only added and removed entries between snapshots.
4. End of thread: POST /context/session/clear
curl -X POST http://localhost:9300/context/session/clear \
-H 'Content-Type: application/json' \
-H 'X-Tenant-ID: default' \
-d '{"sessionId":"ticket-42"}'Choose Your Surface
from nocturnusai import SyncNocturnusAIClient
with SyncNocturnusAIClient("http://localhost:9300") as client:
ctx = client.process_turns(
turns=[
"user: Customer says they are enterprise and blocked on SLA credits.",
"tool: CRM says account is Acme Corp with a 2M ARR contract.",
],
scope="ticket-42",
session_id="ticket-42",
)
diff = client.diff_context(session_id="ticket-42", max_facts=12)
client.clear_context_session("ticket-42")
print(ctx.briefing_delta)import { NocturnusAIClient } from 'nocturnusai-sdk';
const client = new NocturnusAIClient({
baseUrl: 'http://localhost:9300',
tenantId: 'default',
});
const ctx = await client.processTurns({
turns: [
'user: Customer says they are enterprise and blocked on SLA credits.',
'tool: CRM says account is Acme Corp with a 2M ARR contract.',
],
scope: 'ticket-42',
sessionId: 'ticket-42',
});
const diff = await client.diffContext({ sessionId: 'ticket-42', maxFacts: 12 });
await client.clearContextSession('ticket-42');
console.log(ctx.briefingDelta);{
"mcpServers": {
"nocturnus": {
"url": "http://localhost:9300/mcp/sse",
"transport": "sse"
}
}
}Use the context tool each turn for a salience-ranked working set. Pair MCP with the HTTP context endpoints when you need goal-driven assembly and diffs.
What Lives Behind The Workflow
When you do need backend mechanics, NocturnusAI provides them:
Deterministic fact and rule storage
Backward-chaining inference with proof chains
Truth maintenance and contradiction handling
Temporal facts with
ttl,validFrom, andvalidUntilMulti-tenancy via
X-DatabaseandX-Tenant-IDMCP, REST, Python SDK, TypeScript SDK, and CLI surfaces over the same engine
Quick Start
Docker (fastest)
docker run -d --name nocturnusai -p 9300:9300 \
--restart unless-stopped \
-v nocturnusai-data:/data \
ghcr.io/auctalis/nocturnusai:latestcurl http://localhost:9300/health # Verify it's runningDocker with Ollama (enables natural-language extraction)
docker run -d --name nocturnusai -p 9300:9300 \
--add-host=host.docker.internal:host-gateway \
-e LLM_PROVIDER=ollama \
-e LLM_MODEL=granite3.3:8b \
-e LLM_BASE_URL=http://host.docker.internal:11434/v1 \
-e EXTRACTION_ENABLED=true \
ghcr.io/auctalis/nocturnusai:latestFrom this repo
make up-ollama && make smokeCLI
nocturnusai # Interactive REPL
nocturnusai -e "context 10" # Salience-ranked working set
nocturnusai -e "compress" # POST /memory/compress
nocturnusai -e "cleanup 0.05" # POST /memory/cleanupDocumentation
Full docs: nocturnus.ai
The turn-reduction workflow | |
Raw turns → optimize → diff → clear | |
REST endpoints and response shapes | |
Python and TypeScript client methods | |
LangChain, CrewAI, AutoGen, MCP, and more | |
Measured token reduction on live APIs | |
Every number, derived | |
The extraction → inference → delta pipeline |
Docker Compose (advanced)
git clone https://github.com/Auctalis/nocturnusai.git && cd nocturnusai
make up # Server using .env.example defaults
make up-ollama # + Ollama (reuses host or starts bundled)
make up-monitoring # + Prometheus + Grafana
make smoke # Verify health + context endpointBuild from Source
Requires JDK 17+.
./gradlew :nocturnusai-server:run # HTTP server on :9300
./gradlew :nocturnusai-cli:run # Interactive REPL (JVM)
./gradlew :nocturnusai-cli:nativeCompile # Build native binary
./gradlew test # Full test suiteContributing
See CONTRIBUTING.md. Issues labelled good first issue are good entry points.
Security
Report vulnerabilities privately via GitHub Security Advisories. See SECURITY.md.
License
Business Source License 1.1 (SPDX: BUSL-1.1). Free for internal use — including internal production — inside your own organization. Offering NocturnusAI or substantial functionality as a product/hosted service to third parties requires a commercial license (licensing@nocturnus.ai). Converts to Apache 2.0 on 2030-02-19. See LICENSE and DISCLAIMER.md.
LEGAL & SAFETY NOTICE
NocturnusAI is a deterministic reasoning engine, but its output is only as reliable as the facts provided to it.
No Warranty of Truth. "Verified" refers to logical consistency of inference, not accuracy of real-world claims.
Not for Autonomous High-Stakes Decisions. Do not use this engine for unsupervised medical, financial, legal, or physical-safety decisions without an independent human verification step.
Logic Layer Only. NocturnusAI provides information and inference; it does not execute actions.
No Liability. See DISCLAIMER.md and LICENSE.
Available Tools
16 toolsaggregateA
Compute aggregations over matching facts. Supports COUNT, SUM, MIN, MAX, and AVG over a numeric argument at a specified position. Example: COUNT all score(player, ?) facts, or AVG scores at argIndex=1. Side effects: none (read-only). Auth: requires X-Tenant-ID header; FACT_READ permission when auth is enabled. Rate-limited per principal. Errors: VALIDATION_ERROR on unknown operation or missing argIndex for numeric ops.
Inputs: predicate (required), args (required), operation (required), argIndex, +1 more.
askA
Query the knowledge base using multi-step logical reasoning (backward chaining with unification). Finds all provable answers by applying rules and matching facts. Use ?-prefixed variables for unknowns; optionally returns full proof chains. Side effects: none (read-only). Auth: requires X-Tenant-ID header; FACT_READ permission when auth is enabled. Rate-limited per principal. Errors: VALIDATION_ERROR on bad args; result set bounded by INFERENCE_MAX_RESULTS (default 10,000) to prevent OOM.
Inputs: predicate (required), args (required), scope, withProof, +1 more.
bulk_assertA
Assert multiple facts in a single call for efficiency. Non-transactional: each fact is attempted independently — contradictions are reported without aborting the batch. Returns counts of successful and failed assertions. Side effects: mutates state (additive) — partial successes persist even if other facts in the batch fail. Auth: requires X-Tenant-ID header; FACT_WRITE permission when auth is enabled. Rate-limited per principal. Errors: VALIDATION_ERROR on malformed input; per-fact failures returned in the response's errors array.
Inputs: facts (required).
cleanupA
Run memory decay and eviction. Expires facts past their TTL and evicts low-salience facts when memory exceeds capacity. Call periodically in long-running agent sessions to prevent unbounded growth. Side effects: DESTRUCTIVE — permanently removes evicted and expired facts (irreversible). Auth: requires X-Tenant-ID header; FACT_WRITE permission when auth is enabled. Rate-limited per principal. Errors: VALIDATION_ERROR on bad threshold.
Inputs: threshold.
compressA
Run memory consolidation: detects repeated episodic patterns (e.g., 'user asked about X five times') and creates semantic summaries. Reduces memory footprint in long-running sessions while preserving essential knowledge. Side effects: mutates state (additive) — creates new summary facts; original facts remain intact. Auth: requires X-Tenant-ID header; FACT_WRITE permission when auth is enabled. Rate-limited per principal. Errors: VALIDATION_ERROR on bad args.
Inputs: no named parameters.
contextA
Get the most relevant knowledge for the current reasoning step, ranked by composite salience (recency × frequency × priority). Returns a token-optimized context window in 'predicate', 'natural', or 'structured' format. Pass goals for goal-driven selection, sessionId for incremental diffs across turns. Side effects: read-only for stored facts (salience access counters may update internally). Auth: requires X-Tenant-ID header; FACT_READ permission when auth is enabled. Rate-limited per principal. Errors: VALIDATION_ERROR on bad args.
Inputs: maxFacts, minSalience, predicates, scope, +6 more.
delete_scopeA
Delete a named scope and all facts within it. Use to clean up completed or abandoned hypothetical reasoning branches. Side effects: DESTRUCTIVE and IRREVERSIBLE — permanently removes all facts in the scope; cascades TMS retraction for any derived facts. Auth: requires X-Tenant-ID header; FACT_WRITE permission when auth is enabled. Rate-limited per principal. Errors: VALIDATION_ERROR if scope name is blank.
Inputs: scope (required).
forgetA
Retract a fact from the knowledge base. Inverse of 'tell'. Side effects: DESTRUCTIVE — triggers cascading retraction of any knowledge derived from this fact via the Truth Maintenance System (irreversible). Auth: requires X-Tenant-ID header; FACT_WRITE permission when auth is enabled. Rate-limited per principal. Errors: VALIDATION_ERROR on bad args (no error if the fact was not present).
Inputs: predicate (required), args (required), scope.
fork_scopeA
Fork a knowledge base scope — creates an independent copy of all facts in the source scope under a new target scope name. Use for hypothetical reasoning ('What if Alice moves to London?') without modifying the main knowledge base. Similar to git branch for knowledge. Side effects: mutates state (additive) — creates a new scope with copied facts; source scope is unchanged. Auth: requires X-Tenant-ID header; FACT_WRITE permission when auth is enabled. Rate-limited per principal. Errors: VALIDATION_ERROR if targetScope is blank or already exists.
Inputs: targetScope (required), sourceScope.
list_scopesA
List all named scopes in the knowledge base. Shows what hypothetical contexts or reasoning branches exist. The global (unscoped) partition is always present but not listed. Side effects: none (read-only). Auth: requires X-Tenant-ID header; FACT_READ permission when auth is enabled. Rate-limited per principal. Errors: none under normal operation.
Inputs: no named parameters.
merge_scopeA
Merge facts from one scope into another (default: global). Use to commit hypothetical reasoning back into the main knowledge base. Strategy controls conflict handling: SOURCE_WINS overwrites, TARGET_WINS keeps existing, KEEP_BOTH retains both, REJECT aborts on conflict. Side effects: mutates the target scope; may overwrite existing facts depending on strategy (potentially destructive under SOURCE_WINS). Auth: requires X-Tenant-ID header; FACT_WRITE permission when auth is enabled. Rate-limited per principal. Errors: VALIDATION_ERROR on unknown strategy; CONFLICT_ERROR when strategy=REJECT and conflicts are found.
Inputs: sourceScope (required), targetScope, strategy.
predicatesA
Discover the knowledge base schema. Lists all predicates currently stored with arity (argument count), fact count, and whether they have associated rules. Use this before querying to understand what knowledge is available. Side effects: none (read-only). Auth: requires X-Tenant-ID header; FACT_READ permission when auth is enabled. Rate-limited per principal. Errors: none under normal operation.
Inputs: scope.
recallA
Time-travel query: recall what was known at a specific point in time. Returns facts valid at the given timestamp, respecting temporal bounds (validFrom, validUntil, ttl). Useful for debugging agent behavior or reconstructing past state. Side effects: none (read-only). Auth: requires X-Tenant-ID header; FACT_READ permission when auth is enabled. Rate-limited per principal. Errors: VALIDATION_ERROR on bad args or missing timestamp.
Inputs: predicate (required), args (required), timestamp (required), scope.
retract_patternA
Retract all facts matching a pattern in a single call. Use ?-prefixed variables as wildcards to retract multiple facts at once. Returns the count and list of retracted facts. Side effects: DESTRUCTIVE — removes multiple facts and cascades TMS retraction for each removed fact (irreversible). Auth: requires X-Tenant-ID header; FACT_WRITE permission when auth is enabled. Rate-limited per principal. Errors: VALIDATION_ERROR on bad args.
Inputs: predicate (required), args (required), scope.
teachA
Define a logical rule for automatic reasoning. When body conditions hold, head becomes derivable via backward chaining. Use ?-prefixed variables; supports Negation-as-Failure. Example: 'If ?x is human AND NOT god(?x), THEN ?x is mortal'. Side effects: mutates state (additive) — rules remain active until explicitly removed. Auth: requires X-Tenant-ID header; RULE_WRITE permission when auth is enabled. Rate-limited per principal. Errors: VALIDATION_ERROR on malformed rules.
Inputs: head (required), body (required), scope.
tellA
Assert a fact into the knowledge base. Stores knowledge queryable via logical reasoning. Supports TTL expiration, confidence scoring, and configurable conflict resolution. Side effects: mutates state (additive) — stored facts persist until retracted or expired. Auth: requires X-Tenant-ID header for tenant isolation; FACT_WRITE permission when auth is enabled. Rate-limited per principal. Errors: VALIDATION_ERROR on bad args, CONFLICT_ERROR on contradictions when conflictStrategy=REJECT.
Inputs: predicate (required), args (required), scope, negated, +4 more.
Tool Schema Changelog
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
Loading tool schema changelog…
TDQS
Scored across 16 tools
Each tool targets a distinct operation: tell/forget/retract_pattern for facts, teach for rules, ask/aggregate/context/recall for queries, scope management tools, and memory maintenance tools. No two tools have overlapping purposes; clear boundaries between them.
Naming is mixed: some tools use verb_noun (bulk_assert, delete_scope), others are single verbs (ask, forget), and one is a noun (context). While each name is individually clear, the lack of a consistent pattern reduces predictability.
16 tools is slightly above the typical range but justified by the complexity of the knowledge base domain (fact management, rules, queries, scopes, memory). Each tool serves a clear purpose.
The surface covers core CRUD for facts, queries, scopes, schema discovery, and memory management. A minor gap is the absence of a tool to list or remove defined rules, but the overall coverage is strong.
Maintenance
Related MCP Connectors
Cuts coding agent token burn up to 72% continuously via contradiction-free memory & verification.
Up to 90% fewer tokens: deterministic, declared tool calls, each with a receipt and an audit trail.
Reduce your AI bills by up to 99% locally: focused code, warm prompt caches & zero secret leaks.
Universal memory for AI agents and tools. Save, organize and search context anywhere.
Related MCP Servers
- AlicenseAqualityDmaintenanceAn implementation of persistent memory for Claude using a local knowledge graph, allowing the AI to remember information about users across conversations with customizable storage location.11301 npm62JavaScriptMIT

RelayPlaneofficial
AlicenseAqualityDmaintenanceEnables efficient AI workflow orchestration by chaining multi-step LLM operations while keeping intermediate results out of the context window, reducing token usage by 90%+ and supporting multiple AI providers.741 npm1MIT- FlicenseNot gradedqualityDmaintenanceA production-ready reasoning engine that integrates Claude AI with specialized MCP tools for knowledge retrieval, schema validation, and domain-specific rubric evaluation. It enables structured RAG-based analysis across legal, health, and science domains via a RESTful API.-
- AlicenseAqualityDmaintenanceProvides versioned, structured memory for AI agents, allowing them to store facts, detect conflicts, and track knowledge history via a hosted SaaS platform. It enables efficient hierarchical information retrieval and semantic search while keeping token usage constant as memory scales.741 npm8Apache 2.0