
F
licenseNot graded
qualityD
maintenanceThis server implements the Model Context Protocol to facilitate meaningful interaction and understanding development between humans and AI through structured tools and progressive interaction patterns.
57
-
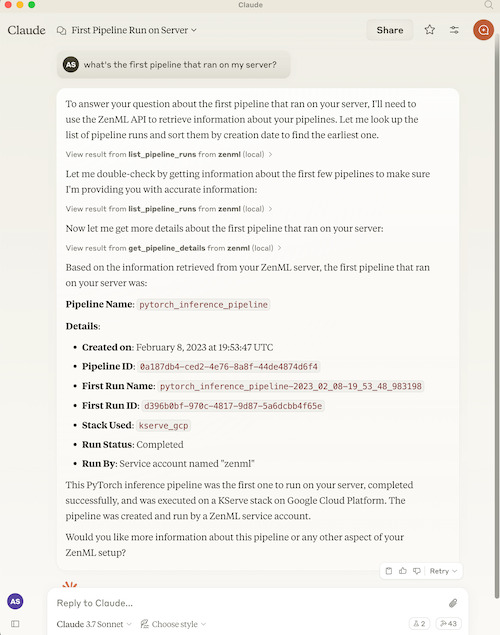
Dieses Projekt implementiert einen Model Context Protocol (MCP) -Server für die Interaktion mit der ZenML -API.
Das Model Context Protocol (MCP) ist ein offenes Protokoll, das die Bereitstellung von Kontext für Large Language Models (LLMs) durch Anwendungen standardisiert. Es fungiert als „USB-C-Anschluss für KI-Anwendungen“ und bietet eine standardisierte Möglichkeit, KI-Modelle mit verschiedenen Datenquellen und Tools zu verbinden.
MCP folgt einer Client-Server-Architektur, bei der:
MCP-Hosts : Programme wie Claude Desktop oder IDEs, die über MCP auf Daten zugreifen möchten
MCP-Clients : Protokoll-Clients, die 1:1-Verbindungen mit Servern aufrechterhalten
MCP-Server : Leichtgewichtige Programme, die über das standardisierte Protokoll spezifische Funktionen bereitstellen
Lokale Datenquellen : Die Dateien, Datenbanken und Dienste Ihres Computers, auf die MCP-Server sicher zugreifen können
Remote Services : Externe Systeme, die über das Internet verfügbar sind und mit denen sich MCP-Server verbinden können
Related MCP server: MCP Server for continue.dev
ZenML ist eine Open-Source-Plattform zum Erstellen und Verwalten von ML- und KI-Pipelines. Sie bietet eine einheitliche Schnittstelle für die Verwaltung von Daten, Modellen und Experimenten.
Weitere Informationen finden Sie auf der ZenML-Website und in unserer Dokumentation .
Der Server bietet MCP-Tools für den Zugriff auf die Kernlesefunktionalität des ZenML-Servers und ermöglicht so den Abruf von Live-Informationen zu folgenden Themen:
Benutzer
Stapel
Rohrleitungen
Pipelineläufe
Pipeline-Schritte
Leistungen
Stapelkomponenten
Geschmacksrichtungen
Vorlagen für Pipelineausführungen
Zeitpläne
Artefakte (Metadaten zu Datenartefakten, nicht die Daten selbst)
Service-Anschlüsse
Schrittcode
Schrittprotokolle (wenn der Schritt auf einem Cloud-basierten Stack ausgeführt wurde)
Außerdem können Sie damit neue Pipeline-Läufe auslösen (sofern eine Laufvorlage vorhanden ist).
Hinweis: Dies ist eine Beta-/Experimentalversion. Wir testen noch, wie die Integration genutzt wird. Wir freuen uns daher über Ihr Feedback und Ihre Vorschläge! Treten Sie unserer Slack-Community bei, teilen Sie Ihre Erfahrungen und helfen Sie uns, uns zu verbessern.
Sie benötigen Zugriff auf einen bereitgestellten ZenML-Server. Falls Sie keinen haben, können Sie sich für eine kostenlose Testversion bei ZenML Pro anmelden. Wir übernehmen dann die Bereitstellung für Sie.
Sie müssen (wahrscheinlich) auch uv lokal installieren. Weitere Informationen finden Sie in der uv Dokumentation . Wir empfehlen die Installation über das Installationsskript oder über brew , wenn Sie einen Mac verwenden. (Technisch gesehen ist dies nicht erforderlich , aber es vereinfacht die Installation und Einrichtung.)
Sie müssen dieses Repository auch irgendwo lokal klonen:
git clone https://github.com/zenml-io/mcp-zenml.gitDie MCP-Konfigurationsdatei ist eine JSON-Datei, die dem MCP-Client mitteilt, wie er sich mit Ihrem MCP-Server verbinden soll. Verschiedene MCP-Clients verwenden oder spezifizieren dies unterschiedlich. Zwei häufig verwendete MCP-Clients sind Claude Desktop und Cursor , für die wir unten Installationsanweisungen bereitstellen.
Sie müssen Ihren ZenML MCP-Server im folgenden Format angeben:
{
    "mcpServers": {
        "zenml": {
            "command": "/usr/local/bin/uv",
            "args": ["run", "path/to/zenml_server.py"],
            "env": {
                "LOGLEVEL": "INFO",
                "NO_COLOR": "1",
                "PYTHONUNBUFFERED": "1",
                "PYTHONIOENCODING": "UTF-8",
                "ZENML_STORE_URL": "https://your-zenml-server-goes-here.com",
                "ZENML_STORE_API_KEY": "your-api-key-here"
            }
        }
    }
}
Es gibt vier Dummy-Werte, die Sie ersetzen müssen:
der Pfad zu Ihrem lokal installierten uv (der oben aufgeführte Pfad ist der Pfad, der auf einem Mac angezeigt würde, wenn Sie es über brew installiert hätten)
Der Pfad zur Datei zenml_server.py (dies ist die Datei, die ausgeführt wird, wenn Sie sich mit dem MCP-Server verbinden). Diese Datei befindet sich im Stammverzeichnis dieses Repositorys. Sie müssen den genauen Pfad zu dieser Datei angeben.
die ZenML-Server-URL (dies ist die URL Ihres ZenML-Servers. Sie finden diese in der ZenML Cloud-Benutzeroberfläche). Sie sieht in etwa so aus: https://d534d987a-zenml.cloudinfra.zenml.io .
den API-Schlüssel des ZenML-Servers (dies ist der API-Schlüssel für Ihren ZenML-Server. Sie finden ihn in der ZenML Cloud-Benutzeroberfläche oder lesen diese Dokumentation zur Erstellung. Für die Zwecke des ZenML MCP-Servers empfehlen wir die Verwendung eines Dienstkontos.)
Sie können die Art und Weise, wie Sie die Python-Datei des MCP-Servers ausführen, frei ändern, aber die Verwendung von uv ist wahrscheinlich die einfachste Option, da es die Umgebung und die Installation der Abhängigkeiten für Sie übernimmt.
Sie müssen Claude Desktop installiert haben.
Nachdem Sie Claude Desktop installiert und geöffnet haben, öffnen Sie das Menü „Einstellungen“ und klicken Sie auf die Registerkarte „Entwickler“. Dort finden Sie die Schaltfläche „Konfiguration bearbeiten“, die einen Datei-Explorer öffnet, der Ihnen den Speicherort Ihrer Konfigurationsdatei anzeigt.
Fügen Sie den Inhalt der (korrekt ausgefüllten) Konfigurationsdatei oben in die im Datei-Explorer angezeigte JSON-Datei ein. Starten Sie anschließend Claude Desktop neu, und die neue Konfiguration wird verwendet. Der ZenML-Server sollte im Entwicklereinstellungsmenü angezeigt werden. Chatten Sie mit Claude, und er wird alle neuen Tools verwenden, auf die Sie ihm Zugriff gewährt haben.
Für ein besseres Erlebnis mit den Ergebnissen des ZenML-Tools können Sie Claude so konfigurieren, dass die JSON-Antworten in einem besser lesbaren Format angezeigt werden. Gehen Sie in Claude Desktop zu Einstellungen → Profil und fügen Sie im Abschnitt „Welche persönlichen Präferenzen sollte Claude bei Antworten berücksichtigen?“ Folgendes hinzu (oder verwenden Sie genau diese Worte!):
When using zenml tools which return JSON strings and you're asked a question, you might want to consider using markdown tables to summarize the results or make them easier to view!Dies wird Claude dazu ermutigen, die Ausgaben des ZenML-Tools als Markdown-Tabellen zu formatieren, wodurch die Informationen viel einfacher zu lesen und zu verstehen sind.
Sie müssen Cursor installiert haben.
Cursor funktioniert etwas anders als Claude Desktop, da Sie die Konfigurationsdatei pro Repository angeben. Das bedeutet: Wenn Sie den ZenML MCP-Server in mehreren Repositorys verwenden möchten, müssen Sie die Konfigurationsdatei in jedem dieser Repositorys angeben.
Um es für ein einzelnes Repository einzurichten, müssen Sie:
Erstellen Sie einen .cursor -Ordner im Stammverzeichnis Ihres Repositorys
Erstellen Sie darin eine mcp.json Datei mit dem oben genannten Inhalt
Gehen Sie in Ihre Cursoreinstellungen und klicken Sie auf den ZenML-Server, um ihn zu „aktivieren“.
Unserer Erfahrung nach wird manchmal eine rote Fehleranzeige angezeigt, obwohl es funktioniert. Sie können es ausprobieren, indem Sie im Cursor-Chatfenster chatten. Dort erfahren Sie, ob auf die ZenML-Tools zugegriffen werden kann oder nicht.
Diagnose ZenML MCP server setup (env vars, connectivity, auth, versions).
Returns structured diagnostics about the server's configuration and connectivity. This tool works even when the ZenML SDK is not installed or environment variables are missing - use it to troubleshoot setup issues.
| Name | Required | Description | Default |
|---|---|---|---|
No parameters | |||
| Name | Required | Description |
|---|---|---|
No output parameters | ||
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the behavioral disclosure burden. It reveals that the tool works without the SDK or env vars and that it returns structured diagnostics, which is valuable context. It does not explicitly state side-effect-free behavior, but the 'diagnose' and 'Returns diagnostics' language strongly implies a read-only operation.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is short and front-loaded with the core purpose, followed by the key operational caveat and a clear use case. Every sentence earns its place without redundancy.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a zero-parameter diagnostic tool with an output schema available, the description covers the essential context: what it diagnoses, what it returns, and when to use it. Nothing important appears to be missing for an agent to invoke it correctly.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
This tool has zero parameters, so there is nothing the description needs to clarify about arguments. The baseline for no-parameter tools is 4, and the description appropriately makes no unsupported parameter claims.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description states a specific verb and resource: 'Diagnose ZenML MCP server setup' and lists the areas covered (env vars, connectivity, auth, versions). It is clear and specific, but it does not explicitly differentiate itself from sibling tools, so it misses the top score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description gives clear usage context: 'use it to troubleshoot setup issues' and notes it works even when the ZenML SDK is not installed or environment variables are missing. It does not mention exclusions or alternative tools, but the intended scenario is well established.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get the currently active project.
Projects are organizational containers for ZenML resources. Most SDK methods are project-scoped, and this tool returns the default project context.
| Name | Required | Description | Default |
|---|---|---|---|
No parameters | |||
| Name | Required | Description |
|---|---|---|
No output parameters | ||
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It states the operation ('Get the currently active project') but does not disclose behaviors such as what happens if no active project exists, whether project context must be explicitly set, potential errors, or permission requirements. The phrase 'default project context' adds slight context but leaves key behavioral details undisclosed.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is two sentences with no filler. The primary operation is front-loaded, and the second sentence provides essential context about what a project is and why the active project matters. Every sentence earns its place.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a zero-parameter tool with an output schema and a clear domain concept, the description provides sufficient context: it defines projects, explains their role in ZenML, and clarifies that this returns the default context. It stops short of describing edge cases or setup prerequisites, but given the tool's simplicity and the presence of an output schema, the coverage is adequate but not exhaustive.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The tool has 0 parameters, so the description does not need to add parameter semantics. Per the rubric, 0 params warrants a baseline score of 4. The description appropriately focuses on the operation itself rather than inventing parameter details.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states 'Get the currently active project' with a specific verb and resource, and explains that projects are organizational containers. It does not explicitly contrast with siblings like get_active_user, but the resource (project vs user) is unambiguous from the name and description.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no direct guidance on when to use this tool versus alternatives. It mentions that 'most SDK methods are project-scoped' and that this returns the default project context, which implies a use case, but there is no explicit when-to-use or when-not-to-use guidance, nor any mention of sibling tools that might be more appropriate for specific scenarios.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get the currently active user.
| Name | Required | Description | Default |
|---|---|---|---|
No parameters | |||
| Name | Required | Description |
|---|---|---|
No output parameters | ||
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full responsibility for behavioral disclosure. It only says 'get', which implies a read operation, but it doesn't disclose what happens if no user is active, error handling, or any side effects. The output schema exists but is not referenced in the description, so the agent is left to infer behavior beyond the basic action.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single, short sentence with no unnecessary words. It is front-loaded with the action and resource, and every word contributes to the meaning. This is appropriately sized for a tool with no parameters.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has no parameters, an output schema exists (providing return value structure), and the description clearly states the purpose, it is largely complete. It doesn't elaborate on edge cases or the meaning of 'active' in context, but these are minor gaps for such a simple getter. The description adequately covers what an agent needs to call it correctly.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The tool has zero parameters, and the schema reflects that with 100% coverage. Per the rubric, a baseline of 4 is appropriate for 0 parameters since there is nothing for the description to add. The description is consistent with the schema, providing no additional parameter information needed.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly identifies the action (get) and the resource (active user). It is distinct from sibling tools like get_active_project, which targets a different resource. However, it doesn't explicitly contrast itself with any sibling, so it misses a point for proactive differentiation.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description implies that this tool is used when you need the currently active user, but it doesn't explicitly state when to use it versus alternatives (e.g., get_active_project) or any conditions. It provides no explicit exclusions or context, falling into the 'implied usage' category.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get logs for a specific deployment.
Retrieves logs from the deployment's underlying infrastructure. This is useful
for debugging deployment issues or monitoring deployment behavior.

Note: Log availability depends on the deployer plugin being installed and
the deployment infrastructure supporting log retrieval.

Args:
    name_id_or_prefix: The name, ID or prefix of the deployment
    project: Optional project scope (defaults to active project)
    tail: Number of recent log lines to retrieve (default: 100, max recommended: 500)

Returns:
    Dict with 'logs' (string) and metadata about truncation if applicable
| Name | Required | Description | Default |
|---|---|---|---|
| tail | No | ||
| project | No | ||
| name_id_or_prefix | Yes |
| Name | Required | Description |
|---|---|---|
No output parameters | ||
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations, the description carries the transparency burden. It discloses dependencies (deployer plugin, infrastructure support) and mentions return structure and truncation metadata, but does not explicitly state that the operation is read-only or mention any side effects. This is adequate but not exhaustive.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is well-structured with a clear purpose, a dependency note, and a bulleted parameter list. Each sentence earns its place; it is not overly verbose and front-loads the core action.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's moderate complexity, the description covers key aspects: dependencies, return format, and parameter semantics. An output schema exists, so the explicit return summary is a bonus. It does not address error handling or performance characteristics, but these are not critical for a log retrieval tool.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema coverage is 0%, so the description must compensate. It explains all three parameters in the Args section, including purpose, defaults, and a recommended max for 'tail'. This adds meaningful context beyond the bare schema, though it could go deeper on edge cases (e.g., behavior with non-existent deployment).
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
States a specific verb 'Get' with a clear resource 'logs for a specific deployment'. Differentiates from sibling get_step_logs implicitly via 'deployment' but does not name it explicitly, leaving a small gap in differentiation.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Provides general context ('useful for debugging deployment issues or monitoring deployment behavior') but offers no explicit guidance on when to use this tool versus get_step_logs or other siblings. No exclusions or alternative routing are mentioned, leaving the agent to infer the distinction.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get the code for a step.
Args:
    step_run_id: The ID of the step to retrieve
| Name | Required | Description | Default |
|---|---|---|---|
| step_run_id | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations, the description must disclose behavioral traits. It only says 'Get the code' and provides no information about read-only nature, error conditions, or what happens if the step run ID is invalid. It doesn't state whether the operation is safe or has side effects. This is a significant gap for a tool with no annotation support.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is very concise—two sentences with no fluff. It is appropriately sized for a simple getter, though it might be under-specified rather than concise. The structure is front-loaded with the main action, but the parameter description is minimal.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the simplicity (one required parameter), one might expect a basic description to suffice, but there is no output schema information provided, no error handling, and no details about what 'code' means (e.g., source code, generated code, etc.). With no annotations and minimal description, the tool is incomplete for an agent to use confidently.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description includes a line for step_run_id: 'The ID of the step to retrieve', which adds a minimal semantic hint beyond the schema's property name and type. However, schema description coverage is 0% and the description doesn't explain the format or constraints of the ID, nor how to obtain it. It barely compensates for the missing schema descriptions.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description states a clear action ('Get the code') and resource ('for a step'), which distinguishes it from siblings like get_step_logs (logs vs code). However, it doesn't explicitly mention the ZenML pipeline context, but the sibling names imply it. Slight ambiguity about what 'step' refers to, but given the parameter step_run_id, it's understandable.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance on when to use this tool versus alternatives. It doesn't mention when to prefer this over get_step_logs or other resource tools. The description simply states the function without any contextual use cases or exclusions.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get the logs for a specific step run.
Args:
    step_run_id: The ID of the step run to get logs for.
    source: Optional log source. Defaults to ZenML's ordinary ``step`` source.
    logs_id: Optional exact log record ID. Cannot be combined with ``source``.
| Name | Required | Description | Default |
|---|---|---|---|
| source | No | ||
| logs_id | No | ||
| step_run_id | Yes |
| Name | Required | Description |
|---|---|---|
No output parameters | ||
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations, the description carries the behavioral burden. It discloses the optional source default and the mutual exclusion between source and logs_id, which is useful. It does not mention return format, pagination, or error behavior, though the presence of an output schema mitigates the return-format gap.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is concise and front-loaded with the purpose. The Args section is terse and each line adds specific meaning without filler or redundant restatement of the schema.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a focused retrieval tool with an output schema, the description is largely complete: it covers the operation and all parameters. Minor gaps remain around possible source values and behavior when no logs exist, but these are not critical for a typical call.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description is the only source of parameter meaning. It explains all three parameters clearly, including the default behavior of source and the exclusivity constraint on logs_id. This fully compensates for the schema's lack of descriptions.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description begins with a specific verb and resource: 'Get the logs for a specific step run.' This clearly distinguishes it from related tools such as get_deployment_logs or get_step_code by targeting step-run-scoped log records. The purpose is unambiguous.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description gives clear context for when the tool is appropriate and includes useful parameter usage constraints (logs_id cannot be combined with source). However, it does not explicitly contrast this tool with sibling tools like get_deployment_logs or get_step_code, leaving the selection decision partly to inference.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Open an interactive dashboard of recent ZenML pipeline runs.
The dashboard shows pipeline runs with status indicators, expandable step details, filtering, and drill-down into step logs — all in an interactive UI. The dashboard fetches its own data dynamically.
| Name | Required | Description | Default |
|---|---|---|---|
No parameters | |||
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations, the description must carry behavioral disclosure. It states the dashboard 'fetches its own data dynamically,' which is a useful behavior, and implies a read-only interactive view. However, it does not explicitly state whether it is non-destructive, how the dashboard is presented (e.g., opens in a browser or returns a URL), or any side effects. This partial disclosure warrants a 3.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is concise and front-loaded, with the core purpose in the first sentence and supporting details in the second. Every sentence adds value, and there is no redundancy or filler. The structure is efficient and easy to parse.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
The description is largely complete given the tool has no parameters and an output schema is present. It explains what the dashboard shows and that it fetches data dynamically, which covers the essential behavior. However, it could be improved by explicitly mentioning how the dashboard is delivered (e.g., opens in a browser, returns a link) and by clarifying its relationship to open_run_activity_chart. Minor gaps prevent a 5.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The tool has zero parameters, so the description does not need to explain parameter semantics. The schema is trivially covered (empty object). The baseline for 0 parameters is 4, and the description correctly avoids adding unnecessary parameter details.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool opens an interactive dashboard of recent ZenML pipeline runs, with a specific verb and resource. It lists the dashboard's features (status indicators, expandable step details, filtering, drill-down into logs), which distinguishes it from general resource tools. However, it does not explicitly differentiate from the sibling open_run_activity_chart, which could be a similar dashboard, so it loses a point.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It does not mention any conditions, prerequisites, or contrasts with sibling tools like open_run_activity_chart or get_step_logs. The only implicit cue is the name and the general purpose, but no explicit usage direction is given.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Open an interactive chart showing pipeline run activity over the last 30 days.
Shows a bar chart with daily run counts, hover tooltips, and status breakdown (completed in green, failed in red, other in amber).
| Name | Required | Description | Default |
|---|---|---|---|
No parameters | |||
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden. It discloses the interactive elements (hover tooltips, status breakdown) and color coding, which are useful behavioral hints, but it does not state whether the operation is read-only, has side effects, or requires any setup. For a 0-param tool, this is adequate but not rich.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Two sentences with no filler. The primary action is front-loaded, and the second sentence adds specific details about the chart's interactivity and color coding. Every word earns its place.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a parameterless tool, the description fully covers what the agent needs to know to invoke it: what the chart shows and its scope. The existence of an output schema fills in any return-value details, so nothing essential is missing. It could mention what happens with no data, but that's minor.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The tool has zero parameters, so the baseline is 4. There is no parameter ambiguity to resolve, and the description's mention of 'last 30 days' is a fixed behavior, not a parameter.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description states a specific verb ('Open') and a specific resource ('interactive chart showing pipeline run activity over the last 30 days'), clearly going beyond the name. However, it does not explicitly differentiate from the sibling open_pipeline_run_dashboard, so it earns a 4 rather than a 5.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description clearly states the chart's scope (last 30 days) and content, giving the agent a clear context for when to use it. It does not name any alternative or provide exclusion criteria, so it falls short of a 5.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Trigger a pipeline to run from the server.
Args:
    pipeline_name_or_id: Optional name or ID of the pipeline to trigger. A
        snapshot or template can be triggered without it.
    snapshot_name_or_id: The name or ID of a specific snapshot to run (preferred)
    stack_name_or_id: Optional stack override for the run
    template_id: Deprecated template-based trigger parameter. Use
        `snapshot_name_or_id` for new integrations. ZenML 0.96.4 still
        retains run-template CRUD APIs.

Usage examples:
    * Run the latest runnable snapshot for a pipeline:
    ```python
    trigger_pipeline(pipeline_name_or_id=<NAME>)
    ```
    * Run the latest runnable snapshot for a pipeline on a specific stack:
    ```python
    trigger_pipeline(
        pipeline_name_or_id=<NAME>,
        stack_name_or_id=<STACK_NAME_OR_ID>
    )
    ```
    * Run a specific snapshot (RECOMMENDED):
    ```python
    trigger_pipeline(
        snapshot_name_or_id=<SNAPSHOT_NAME_OR_ID>
    )
    ```
    * Run a specific template (DEPRECATED - use snapshot_name_or_id instead):
    ```python
    trigger_pipeline(template_id=<ID>)
    ```
| Name | Required | Description | Default |
|---|---|---|---|
| template_id | No | ||
| stack_name_or_id | No | ||
| pipeline_name_or_id | No | ||
| snapshot_name_or_id | No |
| Name | Required | Description |
|---|---|---|
No output parameters | ||
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are present, so the description must carry all behavioral disclosure. It states the tool triggers a run 'from the server' but does not say whether the call blocks until completion, what side effects are created (a new pipeline run), or what authentication/configuration is required. For an action that starts a run, this is a meaningful omission.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is well-structured with an Args block and four usage examples, but it is longer than necessary. The first two examples are nearly identical except for the stack override, and the content could be tightened without losing information.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given four optional parameters and no annotation support, the description provides enough parameter semantics, conditionals, and examples to call the tool correctly. The main gap is behavioral context (sync vs async, side effects), but the presence of an output schema partially covers return expectations. It is largely complete for invocation.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema properties have no descriptions (0% coverage), so the description is the sole source of parameter meaning. It explains all four parameters, including the conditional relationship (pipeline_name_or_id optional if snapshot/template given), the preferred status of snapshot_name_or_id, and the deprecation of template_id, going well beyond the bare schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description opens with "Trigger a pipeline to run from the server" — a specific verb and resource that tells the agent exactly what happens. It is clearly distinguished from sibling tools like zenml_list_resources or open_pipeline_run_dashboard because it is the only one about starting a run.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The Args section and usage examples explicitly describe when to use each parameter path: pipeline_name_or_id runs the latest runnable snapshot, snapshot_name_or_id runs a specific snapshot (RECOMMENDED), and template_id is marked DEPRECATED with a pointer to snapshot_name_or_id. This is strong internal guidance, though it does not contrast with sibling tools or mention prerequisites like needing a server connection.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Run one finite ZenML lifecycle or relation action.
Inspect ``zenml_describe_resources(resource_type, "action")`` for the exact
action names and payload schema. Every identifier must be an exact UUID.
Actions may have effects outside the ZenML server and are never retried.
| Name | Required | Description | Default |
|---|---|---|---|
| action | Yes | ||
| payload | No | ||
| project_id | No | ||
| resource_id | Yes | ||
| resource_type | Yes |
| Name | Required | Description |
|---|---|---|
No output parameters | ||
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Annotations already flag destructive, non-read-only, non-idempotent behavior. The description adds genuinely useful context by warning that effects may occur outside the ZenML server and that actions are never retried, which goes beyond what the structured annotations state alone. There is no contradiction with the annotations.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Three short sentences, each earning its place: what the tool does, where to get exact action/payload details, and the key cautions about external effects and retries. The most important information is front-loaded and there is no boilerplate.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a destructive arbitrary-action tool with strong annotations and an output schema, the description covers the critical facts: finite scope, lookup procedure, exact identifiers, external side effects, and no retries. The only omitted details, such as specific action names, are intentionally delegated to zenml_describe_resources, which is the correct source.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
With 0% schema description coverage, the description compensates by telling the agent to use zenml_describe_resources for exact action names and payload schema, and by clarifying that every identifier must be an exact UUID. This adds real meaning to resource_id/project_id and provides a lookup mechanism for action/payload. It still leaves resource_type values and project_id requirements somewhat implicit.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description opens with a concrete verb ('Run') and identifies the target as a single finite ZenML lifecycle/relation action, which is enough to communicate the tool's core function. It does not explicitly name or contrast a sibling tool, so it stops short of full sibling differentiation.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description gives a concrete prerequisite: consult zenml_describe_resources(resource_type, "action") to discover exact action names and payload schema. It also warns that actions are never retried and may have effects outside the server. It does not explicitly compare against CRUD siblings like zenml_create_resource or zenml_delete_resource, but the usage context is clear.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Create one allowlisted ZenML resource with a strict typed payload.
Inspect ``zenml_describe_resources(resource_type, "create")`` first.
Project-scoped creates require an exact project UUID and never change the
client's active project.
| Name | Required | Description | Default |
|---|---|---|---|
| payload | No | ||
| model_id | No | ||
| project_id | No | ||
| resource_type | Yes |
| Name | Required | Description |
|---|---|---|
No output parameters | ||
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Annotations already indicate readOnlyHint=false and idempotentHint=false, so mutation and non-idempotency are known. The description adds valuable behavioral context beyond annotations: creates require an exact project UUID, never change the active project, and demand a 'strict typed payload.' There is no contradiction with the annotations.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is two sentences with no filler. The primary action is front-loaded, and the supporting guidance about inspecting describe_resources and project UUID handling earns its place. It is compact without sacrificing essential context.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
The description covers the key side-effect warning and directs the agent to the describe tool for full creation payload details, which is a sound pattern. However, as a standalone description, it leaves resource_type semantics, model_id, and payload structure largely unexplained. The output schema helps with return values, but parameter coverage remains incomplete.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description carries the burden of explaining parameters. It clarifies project_id ('exact project UUID') and hints at payload ('strict typed payload'), but it does not explain resource_type values, model_id, or how to structure the payload. The instruction to inspect describe_resources helps, but the description itself under-specifies the parameters.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the action ('Create') and the resource ('one allowlisted ZenML resource'), and it distinguishes this as a creation operation versus sibling update/delete/list tools. However, it doesn't explicitly contrast with siblings like zenml_update_resource or zenml_delete_resource, so it stops short of a 5.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
It gives a concrete preparatory step: 'Inspect zenml_describe_resources(resource_type, "create") first.' It also adds a crucial usage constraint about project-scoped creates requiring an exact project UUID and never changing the active project. It does not explicitly state when not to use this tool, but the create/update/delete sibling structure makes that mostly clear.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Delete or archive one exact UUID using bounded destructive options.
| Name | Required | Description | Default |
|---|---|---|---|
| payload | No | ||
| model_id | No | ||
| project_id | No | ||
| artifact_id | No | ||
| resource_id | Yes | ||
| resource_type | Yes | ||
| component_type | No |
| Name | Required | Description |
|---|---|---|
No output parameters | ||
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Annotations already declare destructiveHint=true, but the description adds meaningful behavioral context: the operation is limited to one exact UUID desu, and there is an archive alternative. It also conveys that destructive options are bounded, which is valuable beyond the raw annotation.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single sentence with no filler. It front-loads the core action and scope ('Delete or archive one exact UUID') and wastes no words.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Despite having an output schema and annotations, the tool has 7 parameters, 0% schema coverage, and no enums. The description does not explain how to select resource_type, which parameters apply to each resource type, or when deletion versus archiving is appropriate. For a destructive operation, this is incomplete.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate for the 7 parameters. The only hint is 'one exact UUID', which loosely maps to resource_id, but resource_type, payload, model_id, project_id, artifact_id, and component_type are left entirely unexplained. This is a severe gap for a destructive tool.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states a specific action ('Delete or archive') applied to 'one exact UUID', which identifies the resource by ID. It conveys destructive scope and separates this tool from read/list/create tools, though it does not explicitly name sibling alternatives.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No explicit guidance is given for when to use this tool versus zenml_update_resource or zenml_action_resource. The phrase 'using bounded destructive options' implies a destructive context, but there is no when-to-use, when-not-to-use, or alternative routing.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Discover supported generic ZenML resources or one operation schema.
With no arguments this returns a short catalog. Pass a canonical singular resource type to inspect its operations, and add an operation name for its bounded input schema and a small example.
| Name | Required | Description | Default |
|---|---|---|---|
| operation | No | ||
| resource_type | No |
| Name | Required | Description |
|---|---|---|
No output parameters | ||
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations, the description carries the full burden of behavioral disclosure. It transparently describes what each invocation returns: a short catalog, operations for a resource type, and a bounded input schema with a small example. It does not discuss side effects or error behavior, but this is a read-only discovery tool and those gaps are minor.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is two sentences with no filler. The lead sentence states the core purpose immediately, and the second sentence delivers the usage pattern in a compact, ordered way.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
The output schema exists, so return values do not need deeper explanation. The description covers all invocation modes and parameter combinations sufficiently for an agent to call the tool. It could mention what happens with invalid inputs or explicitly point to the sibling CRUD tools for actual operations, but those are not essential.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The input schema has zero parameter descriptions, so the description must compensate. It explains both optional parameters and how they combine: resource_type selects a resource and operation narrows to a specific schema. It does not enumerate canonical resource type values, but the no-argument catalog is the intended way to discover them.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description states a specific purpose: discover supported generic ZenML resources or one operation schema. It clearly distinguishes itself from sibling CRUD/list tools by being an introspective metadata tool rather than an action tool.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description gives explicit usage modes: no arguments for a catalog, resource type for operations, and operation name for the schema. It does not explicitly name alternatives or say when not to use it, but the usage context is clear and separate from the sibling tools.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get one allowlisted ZenML resource by its identifier.
Artifact versions, model versions, and run steps require their parent identifier. Stack components require their fixed component type.
| Name | Required | Description | Default |
|---|---|---|---|
| hydrate | No | ||
| model_id | No | ||
| project_id | No | ||
| artifact_id | No | ||
| resource_id | Yes | ||
| resource_type | Yes | ||
| component_type | No | ||
| pipeline_run_id | No |
| Name | Required | Description |
|---|---|---|
No output parameters | ||
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full burden. It doesn't mention any side effects, access requirements, or rate limits. It doesn't state whether the tool is read-only, but 'Get' implies read-only; however, without annotations, this is implicit and not explicitly disclosed. Could mention that it only retrieves allowlisted resources.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is concise, with two sentences. It front-loads the core purpose and then adds necessary context about parent identifiers and component type. No fluff, each sentence earns its place.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity of 8 parameters with 0% schema coverage and no annotations, the description is insufficient. It doesn't specify which parameters are required for each resource type, nor does it explain the output format (though output schema exists, so that's covered). It leaves ambiguity for agents on how to fill parameters for different resource types.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate. The description explains that parent identifiers are needed for certain resource types and component type for stack components, which adds meaning to those parameters. However, it doesn't explain hydrate, project_id, model_id, artifact_id, pipeline_run_id in detail, leaving uncertainty about which to use for which resource type.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description states the tool gets a single allowlisted ZenML resource by identifier, which is clear. It distinguishes from siblings like list and describe by emphasizing 'one' resource. However, it doesn't explicitly name siblings like zenml_describe_resources to differentiate, but the purpose is clear enough.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides some usage context by noting that artifact versions, model versions, and run steps require parent identifiers, and stack components require component type. This implies when to use those parameters but doesn't explicitly say when to use this tool over zenml_describe_resources or list. No exclusions or alternatives mentioned.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List one allowlisted ZenML resource type with validated filters.
Use ``zenml_describe_resources(resource_type, "list")`` to discover the
accepted filters. Page sizes are capped at 200. Project-scoped reads use
``project_id`` when supplied and otherwise report the active project used.
| Name | Required | Description | Default |
|---|---|---|---|
| page | No | ||
| size | No | ||
| filters | No | ||
| project_id | No | ||
| resource_type | Yes |
| Name | Required | Description |
|---|---|---|
No output parameters | ||
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations, the description carries the behavioral burden and discloses concrete traits: page size cap of 200 and project_id fallback to the active project. It doesn't mention auth or error behavior, but for a list operation these are secondary.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Four sentences, each adding distinct information; purpose is front-loaded, and no filler. The reference to describe is compact but actionable.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given an output schema, return values need no explanation. The description covers the non-obvious runtime constraints (page cap, project fallback, filter discovery) and leaves only minor parameter details (page behavior, size null) unexplained.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema coverage is 0%, so the description must compensate. It adds meaning for size (cap 200), project_id (fallback behavior), and filters (via pointer to describe), but leaves resource_type values and page semantics undocumented. This is partial compensation, not full.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
States the operation ('List') and scope ('one allowlisted ZenML resource type') and mentions validated filters. It doesn't explicitly contrast with sibling get/create/update/delete tools, but the verb and resource scoping make the purpose clear.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Explicitly routes filter discovery to zenml_describe_resources(resource_type, 'list'), giving the agent a clear precondition. It does not state exclusions for sibling tools, but the list-specific guidance is sufficient context.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Update one exact UUID through an allowlisted operation-specific payload.
| Name | Required | Description | Default |
|---|---|---|---|
| payload | No | ||
| model_id | No | ||
| project_id | No | ||
| artifact_id | No | ||
| resource_id | Yes | ||
| resource_type | Yes | ||
| component_type | No |
| Name | Required | Description |
|---|---|---|
No output parameters | ||
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Annotations already declare readOnlyHint=false, idempotentHint=false, and destructiveHint=false, so the mutation profile is known. The description adds context by emphasizing 'one exact UUID' and an 'allowlisted operation-specific payload,' which suggests constrained, targeted updates. It does not explain permissions, side effects, or failure behavior, but the annotation coverage lowers the burden.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single front-loaded sentence with no filler. Every word adds some meaning, and it is appropriately sized for a tool definition that relies on structured schema/annotations for the rest.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
This is a 7-parameter mutation tool with no parameter descriptions, no enums, and no sibling routing. The description only captures the core update intent but omits the resource_type semantics, payload constraints, and selection guidance needed for reliable invocation. The existence of an output schema reduces the need for return-value explanation, but the input-side gaps remain significant.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate, but it only vaguely maps to resource_id ('one exact UUID') and payload ('operation-specific payload'). Required resource_type and optional model_id, project_id, artifact_id, and component_type are left unexplained, making correct parameter selection difficult.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description identifies a clear verb and object: 'Update one exact UUID through an allowlisted operation-specific payload.' This distinguishes the tool from create, delete, get, and list siblings. It does not explicitly name sibling alternatives, but the update resource scope is reasonably clear.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is given about when to use this tool versus zenml_create_resource, zenml_delete_resource, zenml_action_resource, or other siblings. The verb 'Update' implies it is for modifying an existing resource, but no exclusions, prerequisites, or alternative-selection cues are provided.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
v2.0.0diagnose_zenml_setupeaster_eggget_active_project5 fields changedInput schema / additionalPropertiesAdded value: +falseOutput schema / additionalPropertiesAdded value: +trueOutput schema / propertiesRemoved value: -{
- "result": {
- "title": "Result",
- "type": "string"
- }
-}Output schema / requiredRemoved value: -[
- "result"
-]Output schema / titlePrevious value: -"get_active_projectOutput"New value: +"get_active_projectDictOutput"get_active_user5 fields changedInput schema / additionalPropertiesAdded value: +falseOutput schema / additionalPropertiesAdded value: +trueOutput schema / propertiesRemoved value: -{
- "result": {
- "title": "Result",
- "type": "string"
- }
-}Output schema / requiredRemoved value: -[
- "result"
-]Output schema / titlePrevious value: -"get_active_userOutput"New value: +"get_active_userDictOutput"get_buildget_deploymentget_deployment_logs5 fields changedInput schema / additionalPropertiesAdded value: +falseOutput schema / additionalPropertiesAdded value: +trueOutput schema / propertiesRemoved value: -{
- "result": {
- "title": "Result",
- "type": "string"
- }
-}Output schema / requiredRemoved value: -[
- "result"
-]Output schema / titlePrevious value: -"get_deployment_logsOutput"New value: +"get_deployment_logsDictOutput"get_flavorget_modelget_model_versionget_pipeline_detailsget_pipeline_runget_projectget_run_stepget_run_templateget_scheduleget_serviceget_service_connectorget_snapshotget_stackget_stack_componentget_step_code1 field changedInput schema / additionalPropertiesAdded value: +falseget_step_logs7 fields changedInput schema / additionalPropertiesAdded value: +falseInput schema / properties / logs_idAdded value: +{
+ "anyOf": [
+ {
+ "type": "string"
+ },
+ {
+ "type": "null"
+ }
+ ],
+ "default": null,
+ "title": "Logs Id"
+}Input schema / properties / sourceAdded value: +{
+ "anyOf": [
+ {
+ "type": "string"
+ },
+ {
+ "type": "null"
+ }
+ ],
+ "default": null,
+ "title": "Source"
+}Output schema / additionalPropertiesAdded value: +trueOutput schema / propertiesRemoved value: -{
- "result": {
- "title": "Result",
- "type": "string"
- }
-}Output schema / requiredRemoved value: -[
- "result"
-]Output schema / titlePrevious value: -"get_step_logsOutput"New value: +"get_step_logsDictOutput"get_tagget_userlist_artifactslist_buildslist_deploymentslist_flavorslist_model_versionslist_modelslist_pipeline_runslist_pipelineslist_projectslist_run_stepslist_run_templateslist_scheduleslist_secretslist_service_connectorslist_serviceslist_snapshotslist_stack_componentslist_stackslist_tagslist_usersopen_pipeline_run_dashboardopen_run_activity_charttrigger_pipeline9 fields changedInput schema / additionalPropertiesAdded value: +falseInput schema / properties / pipeline_name_or_id / anyOfAdded value: +[
+ {
+ "type": "string"
+ },
+ {
+ "type": "null"
+ }
+]Input schema / properties / pipeline_name_or_id / defaultAdded value: +nullInput schema / properties / pipeline_name_or_id / typeRemoved value: -"string"Input schema / requiredRemoved value: -[
- "pipeline_name_or_id"
-]Output schema / additionalPropertiesAdded value: +trueOutput schema / propertiesRemoved value: -{
- "result": {
- "title": "Result",
- "type": "string"
- }
-}Output schema / requiredRemoved value: -[
- "result"
-]Output schema / titlePrevious value: -"trigger_pipelineOutput"New value: +"trigger_pipelineDictOutput"zenml_action_resourcezenml_create_resourcezenml_delete_resourcezenml_describe_resourceszenml_get_resourcezenml_list_resourceszenml_update_resourcev1.2.0easter_eggget_active_projectget_active_userget_buildget_deploymentget_deployment_logsget_flavorget_modelget_model_versionget_pipeline_detailsget_pipeline_runget_projectget_run_stepget_run_templateget_scheduleget_serviceget_service_connectorget_snapshotget_stackget_stack_componentget_step_codeget_step_logsget_tagget_userlist_artifactslist_buildslist_deploymentslist_flavorslist_model_versionslist_modelslist_pipeline_runslist_pipelineslist_projectslist_run_stepslist_run_templateslist_scheduleslist_secretslist_service_connectorslist_serviceslist_snapshotslist_stack_componentslist_stackslist_tagslist_userstrigger_pipelineScored across 16 tools
Each tool has a distinct purpose: resource CRUD operations are clearly separated by verb (list, get, create, update, delete, action), and specific tools for logs, code, diagnostics, and dashboards are differentiated by target entity (step, deployment, pipeline, user, project). No two tools appear to perform the same function.
The tool names follow a predictable pattern: generic resource operations all use the 'zenml_<verb>_resource' convention, while specific operations use descriptive verbs like 'get_', 'open_', 'trigger_', and 'diagnose_'. This creates two consistent sub-patterns, but the mix is still readable and distinguishable.
With 16 tools, the server is slightly above the typical 3-15 range but still well-scoped for a comprehensive ZenML MCP server. Each tool serves a clear purpose, covering resource management, pipeline execution, logging, diagnostics, and visualization without redundancy.
The tool set provides full CRUD and lifecycle coverage through the generic resource tools, supplemented by specific operations for pipeline triggering, log retrieval, step code, and user/project context. The dashboard and chart tools offer monitoring capabilities, leaving no obvious gaps for common ZenML workflows.
A Model Context Protocol server for Wix AI tools
Enable secure connectivity between Sentry issues and debugging data, and LLM clients, using a Model Context Protocol (MCP) server.
A comprehensive Model Context Protocol (MCP) server that enables AI assistants to interact with yo…
Model Context Protocol server for the Apideck Unified API. Connect any MCP-compatible agent framework to 100+ accounting systems, HRIS platforms, file storage providers, and more through one integration. More information https://www.apideck.com/mcp-server