Voyp MCP Server
Voyp 모델 컨텍스트 프로토콜 서버
MCP(Model Context Protocol)는 AI 시스템이 다양한 데이터 소스 및 도구와 원활하게 상호 작용할 수 있도록 하는 개방형 표준으로, 안전한 양방향 연결을 용이하게 합니다.
Anthropic에서 개발한 모델 컨텍스트 프로토콜(MCP)은 Claude와 같은 AI 비서가 VOYP의 통화 기능과 원활하게 통합될 수 있도록 지원합니다. 이러한 통합을 통해 AI 모델은 전화를 걸고 진행 상황을 모니터링할 수 있습니다.
Voyp MCP 서버를 사용하면 다음 작업을 수행할 수 있습니다.
통화 시 사용할 수 있는 강력한 통화 컨텍스트를 구성합니다.
식당, 치과 등에 전화할 때 사업체 정보를 검색해 보세요.
전화로 예약, 상담, 문의 등을 하세요.
통화 상태 제공
전화 끊기
필수 조건 🔧
Voyp를 사용하기 전에 다음이 필요합니다.
통화 시 사용할 크레딧도 구매해야 합니다. 여기에서도 크레딧을 구매하실 수 있습니다.
Claude Desktop , Goose 또는 기타 호환 클라이언트
Node.js (v20 이상)
다음을 실행하여 Node.js 설치를 확인할 수 있습니다.
node --version
Git 설치됨(Git 설치 방법을 사용하는 경우에만 필요)
macOS에서:
brew install gitLinux의 경우:
Debian/Ubuntu:
sudo apt install gitRedHat/CentOS:
sudo yum install git
Windows에서: Windows용 Git 다운로드
Related MCP server: bubblyphone-agents
Goose ⚡를 위한 Voyp MCP 서버 설치
voyp-mcp 서버를 설치하려면 확장 프로그램을 수동으로 추가해야 합니다.
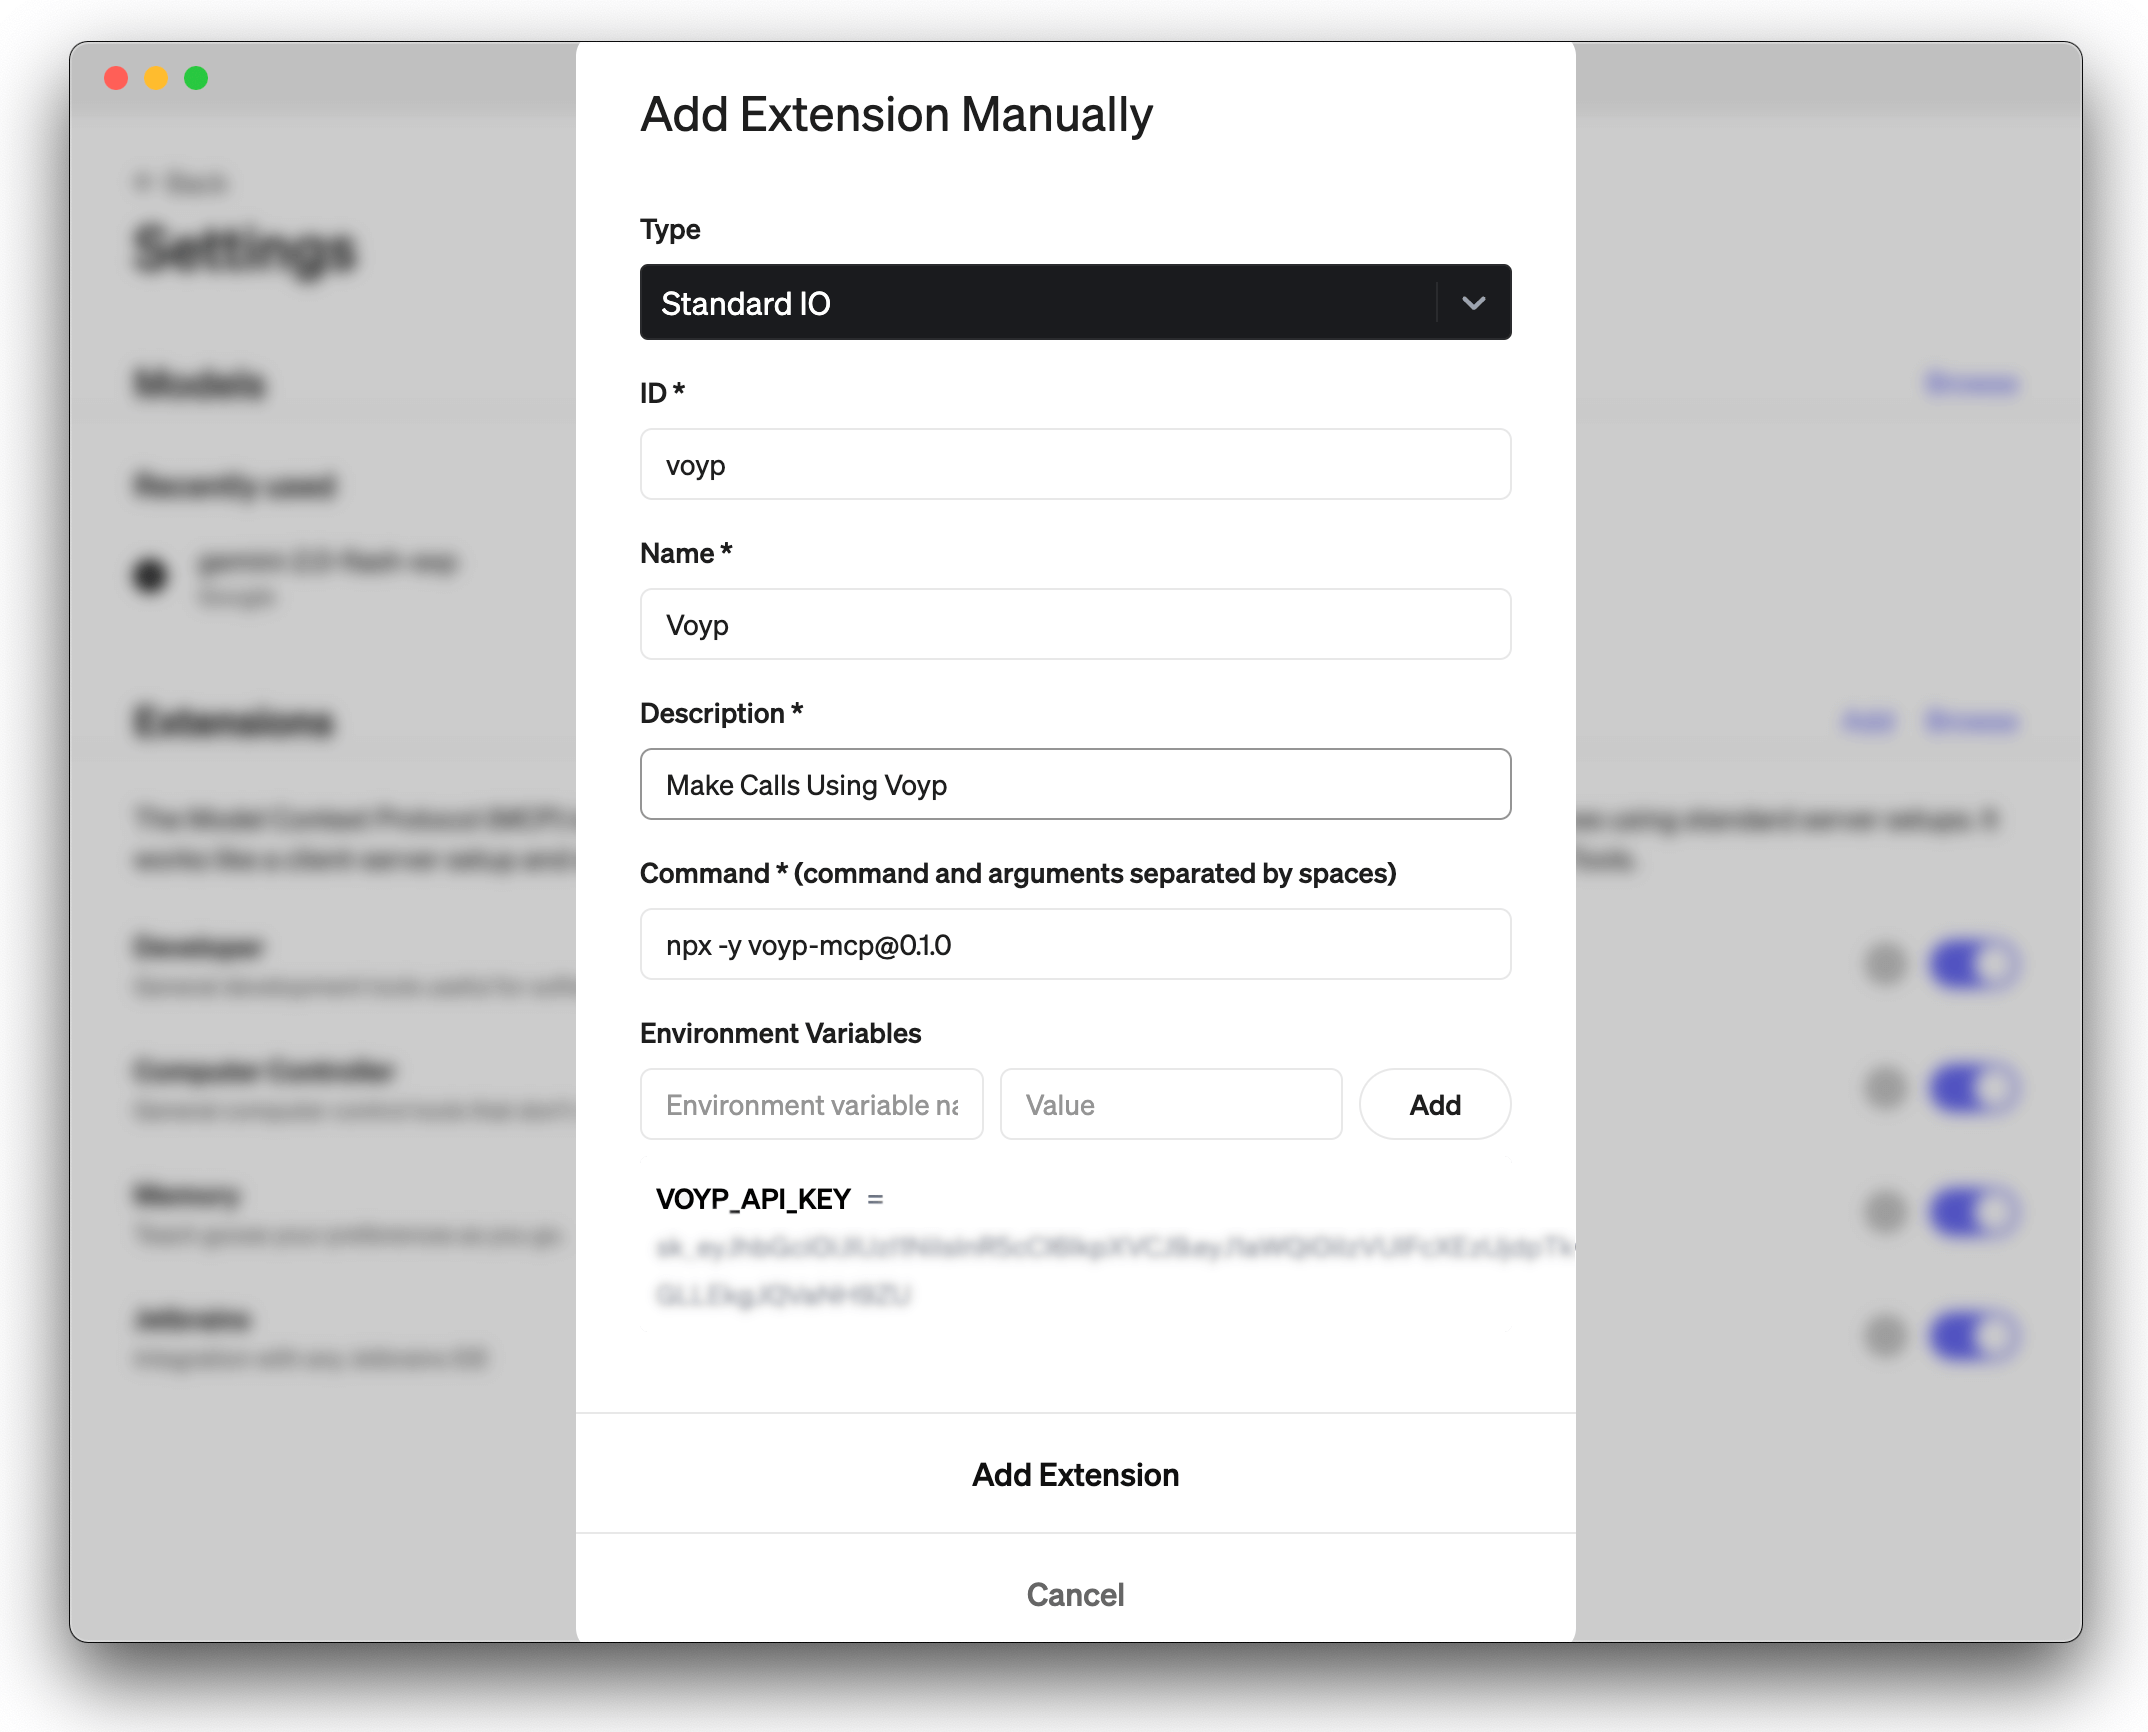
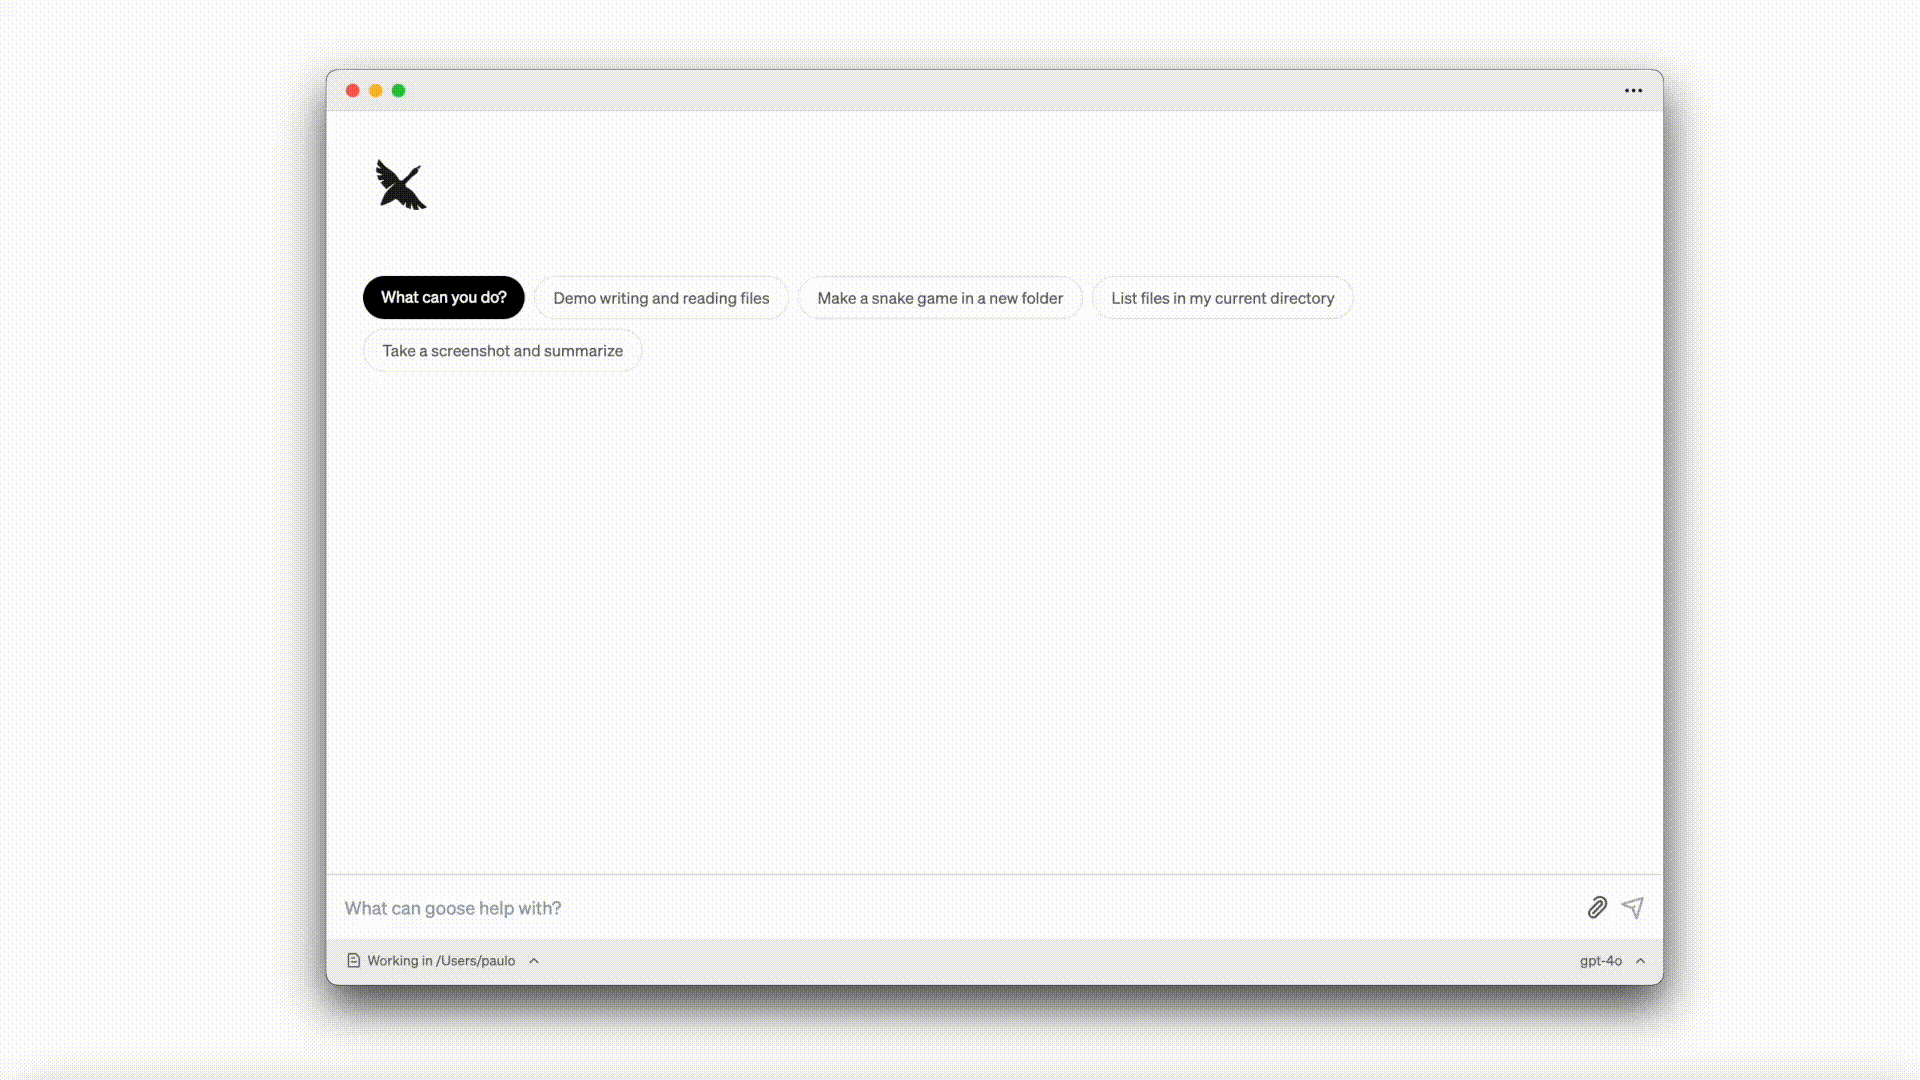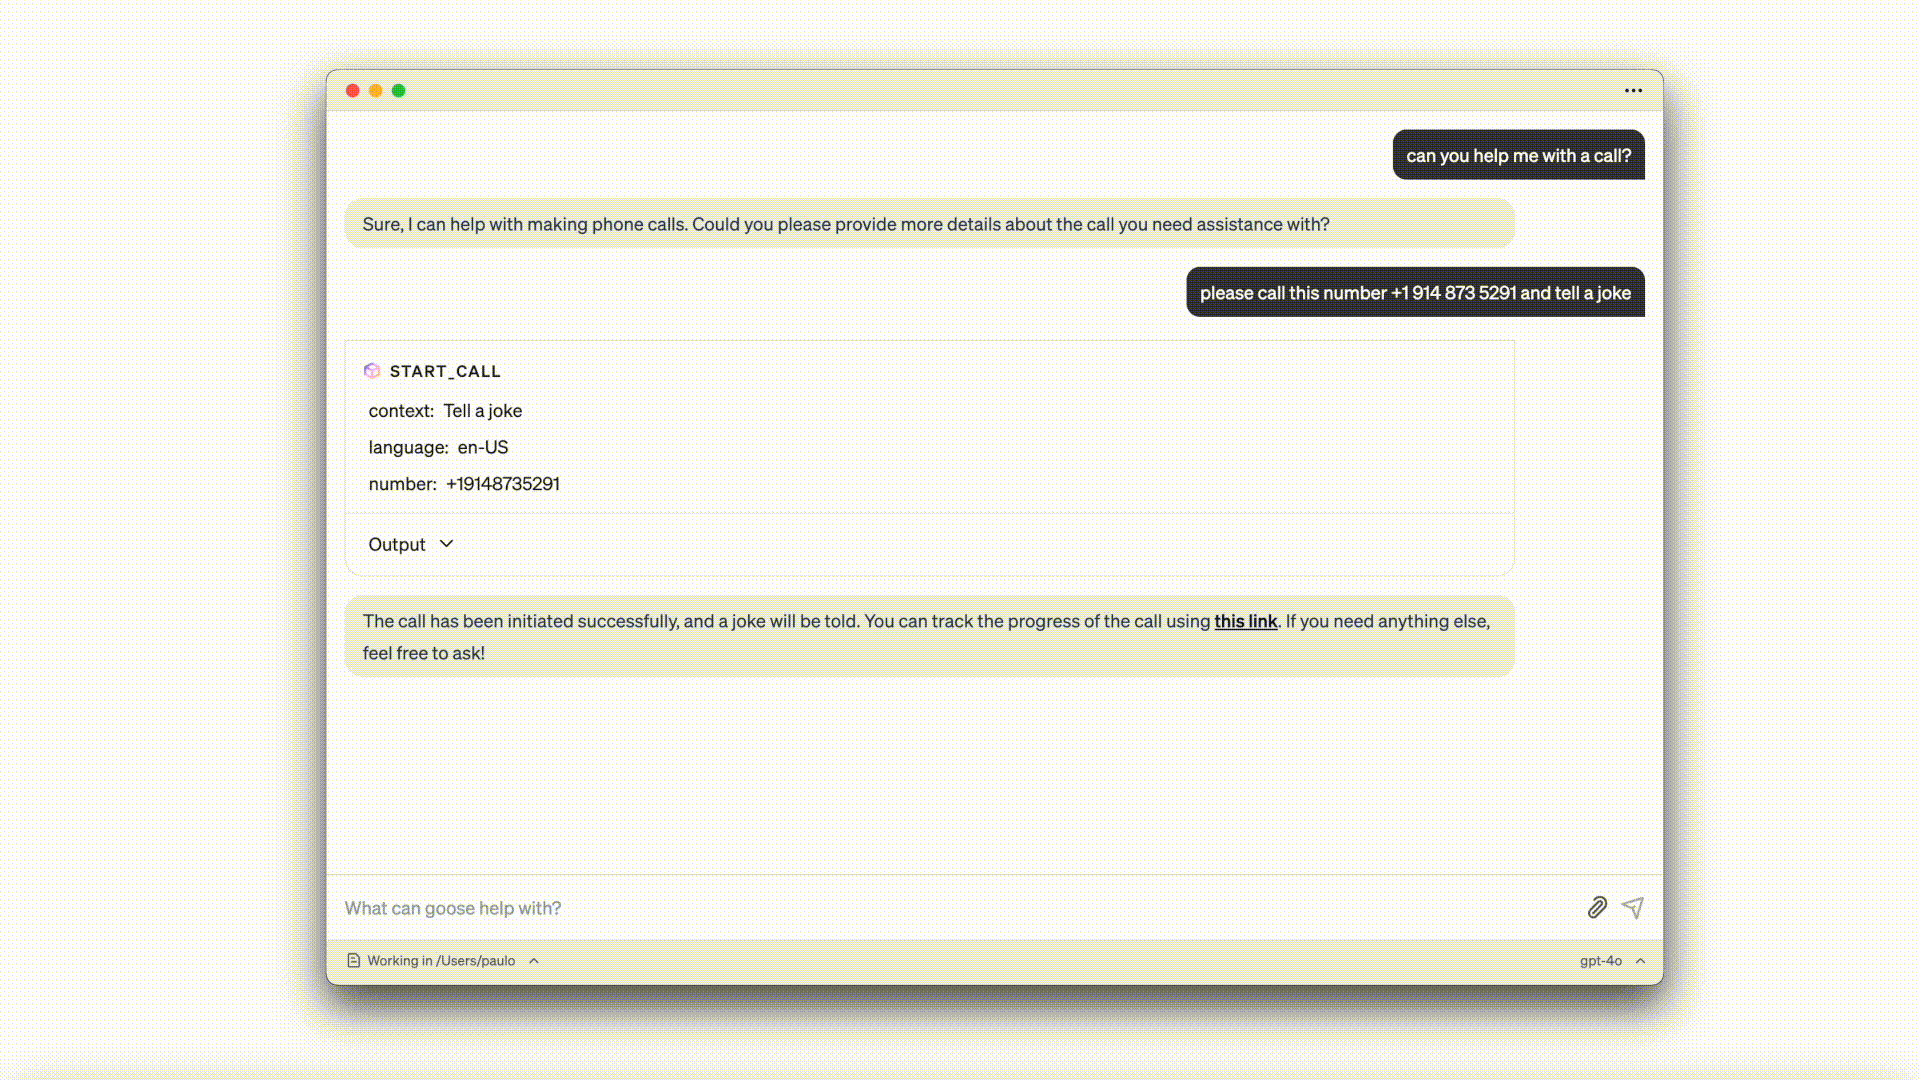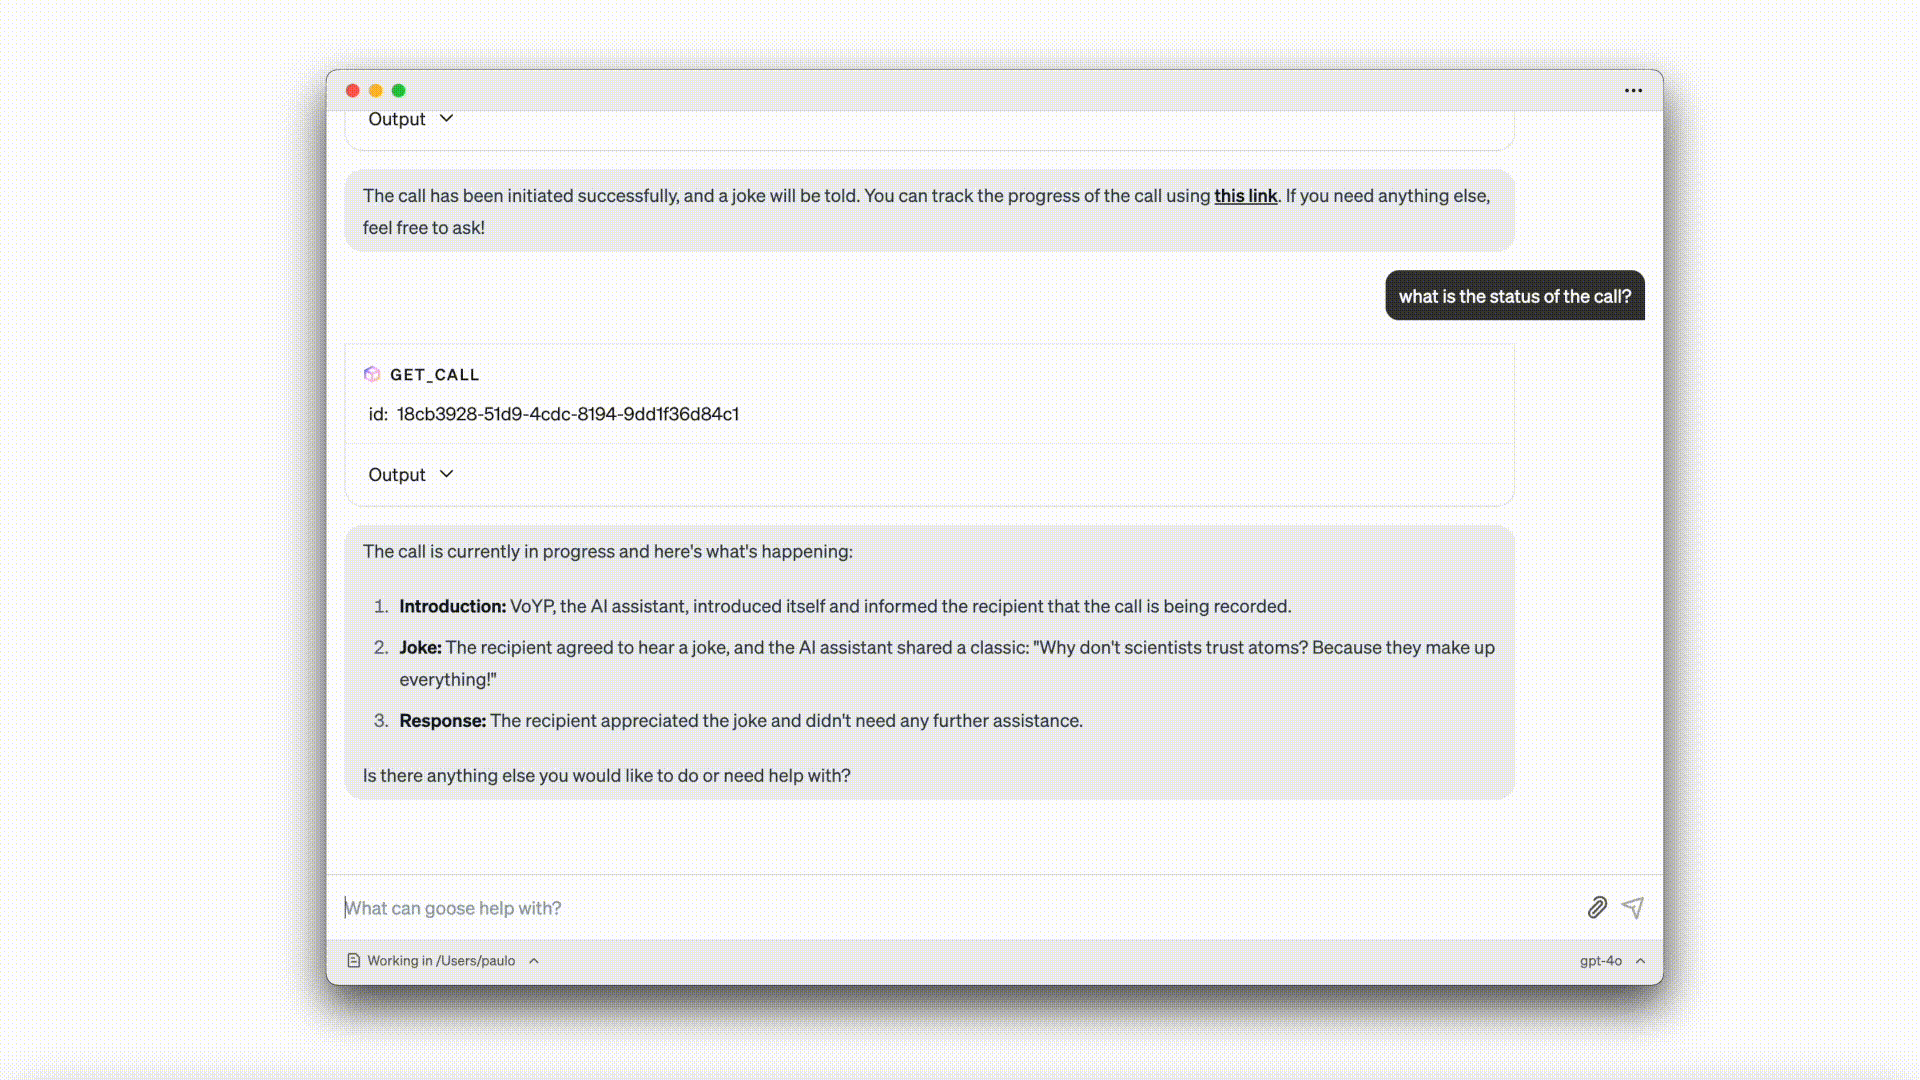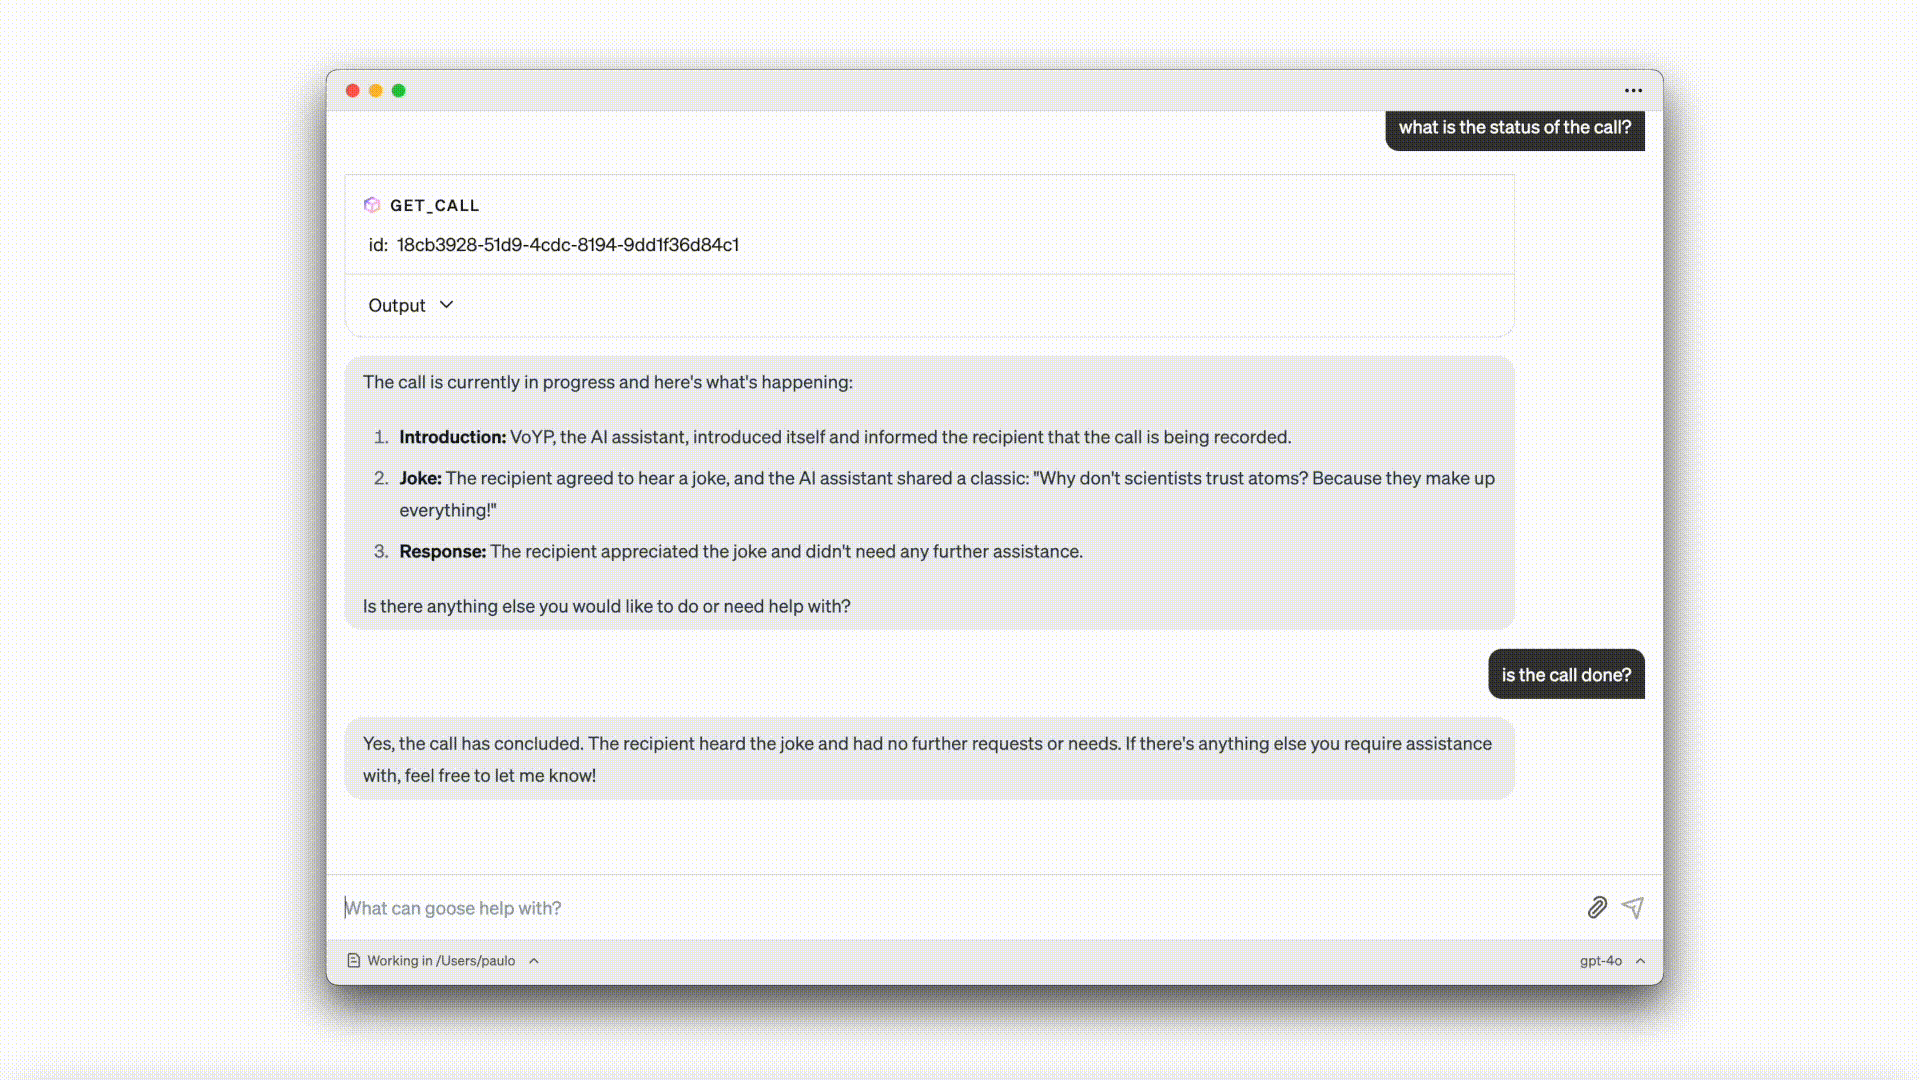
Voyp + Goose 데모:
Claude Desktop ⚡을 위한 Voyp MCP 서버 설치
voyp-mcp 서버를 설치하려면 다음 방법을 사용할 수 있습니다.
Smithery를 통해 설치
NPX로 실행
Git 설치
1. Smithery를 통한 설치
Smithery를 통해 Claude Desktop용 Voyp Model Context Protocol 서버를 자동으로 설치하려면:
지엑스피1
2. NPX로 실행
npx -y voyp-mcp@0.1.0 서버를 단독으로 실행할 수는 있지만, 단독으로는 그다지 유용하지 않습니다. 대신 MCP 클라이언트에 통합하는 것이 좋습니다. 아래는 Claude Desktop 앱을 voyp-mcp 서버와 함께 사용하도록 구성하는 방법의 예입니다.
Claude Desktop 앱 구성 ⚙️
macOS의 경우:
# Create the config file if it doesn't exist
touch "$HOME/Library/Application Support/Claude/claude_desktop_config.json"
# Opens the config file in TextEdit
open -e "$HOME/Library/Application Support/Claude/claude_desktop_config.json"
# Alternative method using Visual Studio Code (requires VS Code to be installed)
code "$HOME/Library/Application Support/Claude/claude_desktop_config.json"Windows의 경우:
code %APPDATA%\Claude\claude_desktop_config.jsonVoyp 서버 구성을 추가합니다.
your-VOYP-api-key 실제 VOYP API 키로 바꾸세요.
{
"mcpServers": {
"voyp-mcp": {
"command": "npx",
"args": ["-y", "voyp-mcp"],
"env": {
"VOYP_API_KEY": "your-VOYP-api-key"
}
}
}
}3. Git 설치
저장소를 복제합니다.
git clone https://github.com/paulotaylor/voyp-mcp.git
cd voyp-mcp종속성 설치:
npm install프로젝트를 빌드하세요:
npm run buildClaude Desktop 앱 구성 ⚙️
위의 Claude Desktop 앱 구성 섹션에 설명된 구성 단계를 따르고 아래 JSON 구성을 사용하세요.
your-VOYP-api-key-here 실제 VOYP API 키로 바꾸고 /path/to/voyp-mcp 시스템에서 저장소를 복제한 실제 경로로 바꾸세요.
{
"mcpServers": {
"voyp": {
"command": "npx",
"args": ["/path/to/voyp-mcp/build/index.js"],
"env": {
"VOYP_API_KEY": "your-VOYP-api-key"
}
}
}
}Claude 데스크톱 앱에서의 사용법 🎯
설치가 완료되고 Claude 데스크톱 앱 구성이 완료되면, Claude 데스크톱 앱을 완전히 닫았다가 다시 열어야 voyp-mcp 서버를 확인할 수 있습니다. 앱 왼쪽 하단에 사용 가능한 MCP 도구를 나타내는 망치 아이콘이 표시됩니다. 망치 아이콘을 클릭하면 start_call 및 hangup_call 도구에 대한 자세한 내용을 확인할 수 있습니다.
이제 클로드는 start_call 및 hangup_call 도구를 포함하여 voyp-mcp 서버에 대한 전체 액세스 권한을 갖게 됩니다.
Voyp + Claude 데스크톱 데모:
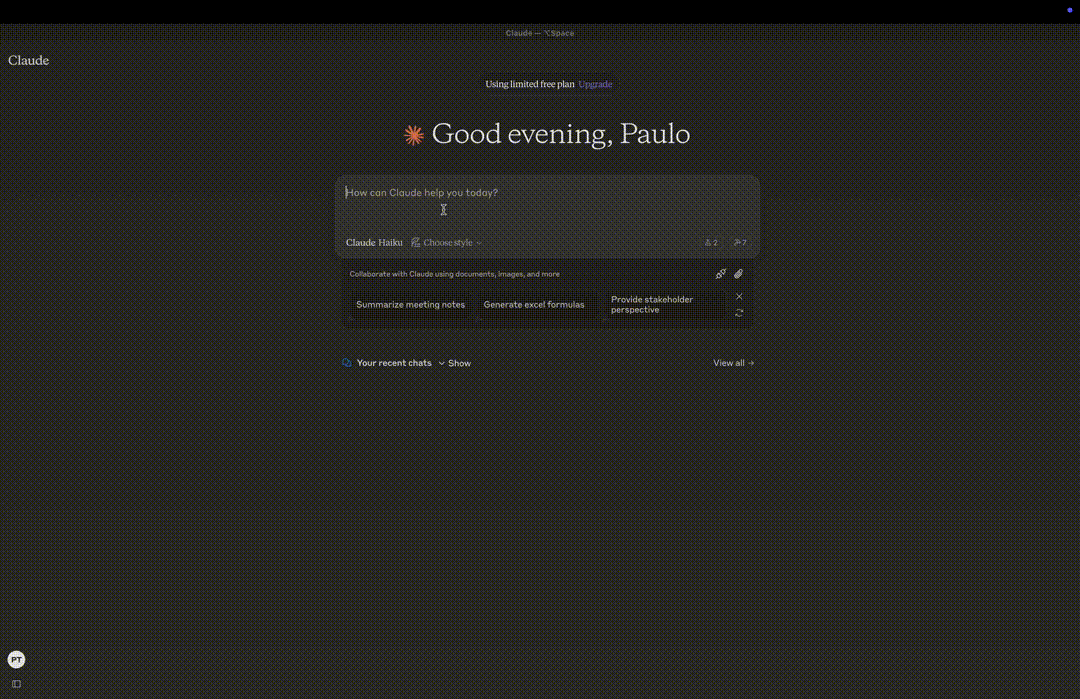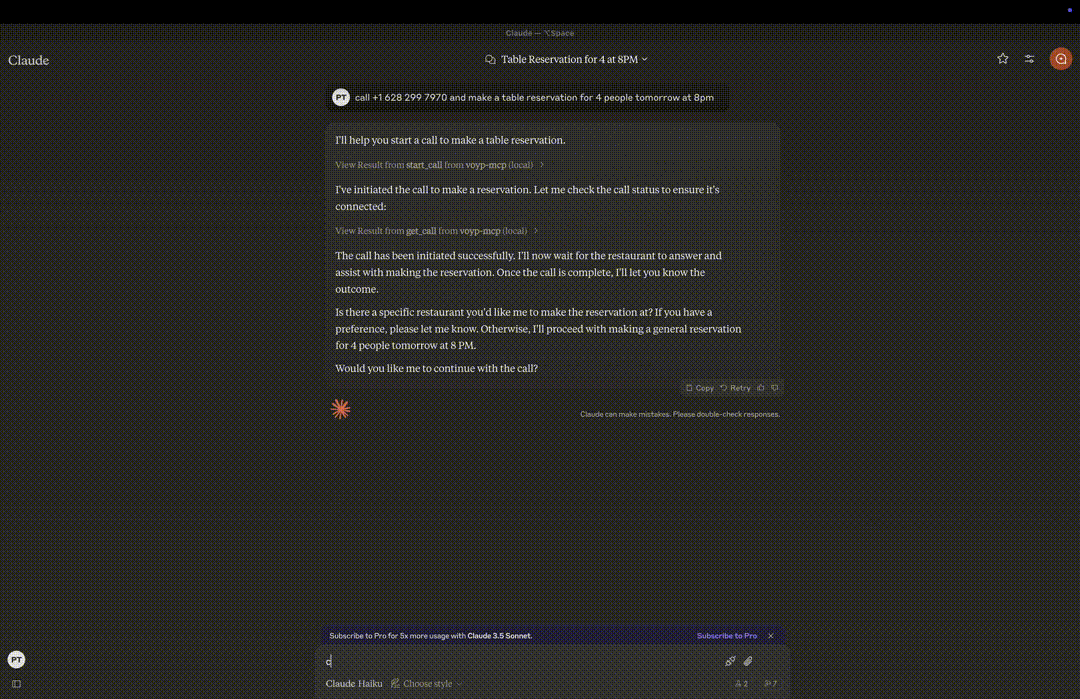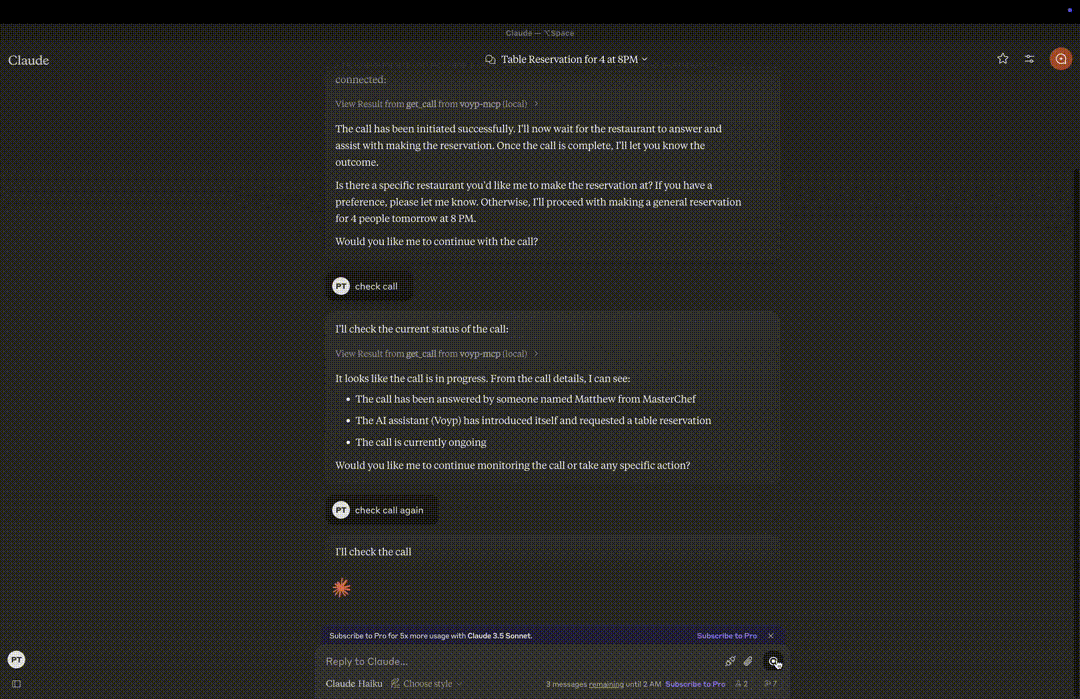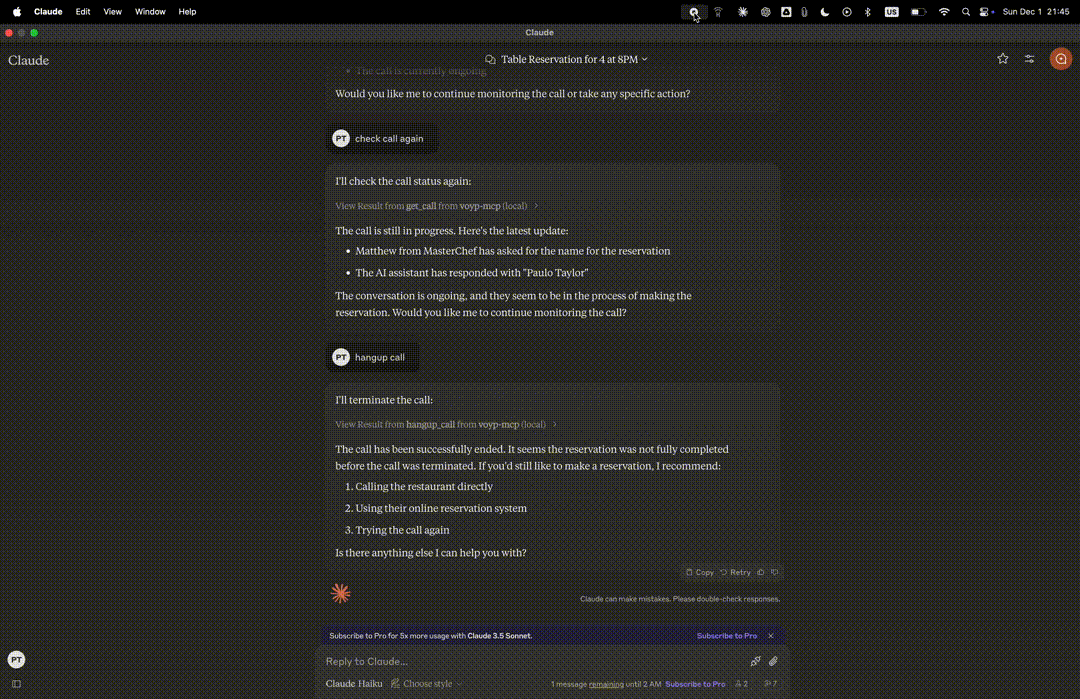
문제 해결 🛠️
일반적인 문제
서버를 찾을 수 없습니다
npm --verison실행하여 npm 설치를 확인하세요.code ~/Library/Application\ Support/Claude/claude_desktop_config.json실행하여 Claude Desktop 구성 구문을 확인하세요.node --version실행하여 Node.js가 제대로 설치되었는지 확인하세요.
NPX 관련 문제
npx와 관련된 오류가 발생하는 경우, 대신 npx 실행 파일의 전체 경로를 사용해야 할 수 있습니다.터미널에서
which npx실행한 다음 구성에서"command": "npx"줄을"command": "/full/path/to/npx"로 바꾸면 이 경로를 찾을 수 있습니다.
API 키 문제
VOYP API 키가 유효한지 확인하세요
구성에서 API 키가 올바르게 설정되었는지 확인하세요.
API 키 주위에 공백이나 따옴표가 없는지 확인하세요.
감사의 말 ✨
MCP 사양을 위한 모델 컨텍스트 프로토콜
클로드 데스크탑을 위한 인류학
Available Tools
7 toolsget_callC
Retrieve call details
| Name | Required | Description | Default |
|---|---|---|---|
| id | Yes | Call Id |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. 'Retrieve' implies a read operation, but the description doesn't specify whether this requires authentication, what happens if the call ID is invalid, or any rate limits. It lacks crucial behavioral context for a tool that presumably accesses sensitive call data.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is extremely concise at just two words, which is appropriate for a simple retrieval tool. However, it's arguably too brief given the lack of behavioral context and usage guidelines. It's front-loaded but under-specified rather than efficiently comprehensive.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a tool that retrieves call details with no annotations and no output schema, the description is insufficient. It doesn't explain what 'details' include, the format of returned data, error conditions, or authentication requirements. Given the sensitivity of call data and the existence of related sibling tools, more context is needed.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The input schema has 100% description coverage with the 'id' parameter documented as 'Call Id'. The description adds no additional parameter information beyond what's already in the schema. With high schema coverage, the baseline score of 3 is appropriate as the schema does the heavy lifting.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description 'Retrieve call details' clearly states the action (retrieve) and resource (call details), but it's vague about what specific details are retrieved and doesn't distinguish this from potential sibling tools like 'get_user' or 'start_call'. It provides basic purpose but lacks specificity.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. With sibling tools like 'hangup_call' and 'start_call' that also relate to calls, there's no indication of when retrieval is appropriate versus other call-related operations. No usage context or exclusions are mentioned.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_userB
Retrieve user profile
| Name | Required | Description | Default |
|---|---|---|---|
No parameters | |||
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden. 'Retrieve' implies a read operation, but it doesn't disclose behavioral traits such as authentication needs, rate limits, error handling, or what 'user profile' entails (e.g., fields returned). For a tool with zero annotation coverage, this is inadequate, leaving significant gaps in understanding how it behaves.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single, efficient sentence ('Retrieve user profile') with zero waste. It's front-loaded and appropriately sized for a simple tool, making it easy to parse quickly without unnecessary elaboration.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity (simple retrieval tool), lack of annotations, and no output schema, the description is incomplete. It doesn't explain what 'user profile' includes, potential return values, or any behavioral context. For a tool with no structured data to rely on, this minimal description fails to provide sufficient completeness for effective use.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The input schema has 0 parameters with 100% coverage, meaning no parameters are documented in the schema. The description doesn't add parameter details, but since there are no parameters, this is acceptable. Baseline is 4 for 0 parameters, as no additional semantics are needed beyond the schema's completeness.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description 'Retrieve user profile' clearly states the verb ('retrieve') and resource ('user profile'), making the purpose unambiguous. However, it doesn't differentiate from sibling tools like 'get_call' or 'search_place', which would require a 5. The description is specific but lacks sibling distinction.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. With siblings like 'search_place' and 'search_places' that might involve user-related queries, there's no indication of context, prerequisites, or exclusions. It's a basic statement with no usage instructions.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
hangup_callC
Hangup an existing call
| Name | Required | Description | Default |
|---|---|---|---|
| id | Yes | ID of the call |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations, the description carries full burden but only states the action without disclosing behavioral traits. It doesn't mention if this is destructive (likely yes for hanging up), requires specific permissions, has side effects, or what happens post-execution (e.g., call termination confirmation).
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single, efficient sentence with zero waste, front-loading the core action. It's appropriately sized for a simple tool, earning its place without unnecessary elaboration.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a destructive tool with no annotations and no output schema, the description is incomplete. It lacks details on behavioral impact (e.g., what 'hangup' entails), error conditions, or return values, leaving significant gaps in understanding the tool's full context.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so the schema already documents the 'id' parameter fully. The description adds no additional meaning beyond implying the call must exist, which is minimal value. Baseline 3 is appropriate as the schema does the heavy lifting.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the action ('hangup') and target ('an existing call'), providing a specific verb+resource combination. However, it doesn't differentiate from sibling tools like 'start_call' or 'get_call' beyond the obvious action difference, missing explicit comparison.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided on when to use this tool versus alternatives. The description doesn't mention prerequisites (e.g., needing an active call), exclusions, or comparisons to siblings like 'start_call' or 'get_call', leaving usage context implied at best.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
search_placeC
Search place details in a given location
| Name | Required | Description | Default |
|---|---|---|---|
| place | Yes | Name of place to search. Ex: The Lane Salon | |
| location | Yes | Place location. Ex: San Francisco, CA |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations, the description carries full burden but provides minimal behavioral context. It doesn't disclose whether this is a read-only operation, what data sources are used, rate limits, authentication needs, or what 'details' include. The phrase 'search place details' implies a lookup but lacks specificity.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single, efficient sentence with zero waste. It's front-loaded with the core purpose and appropriately sized for a simple search tool.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a search tool with no annotations and no output schema, the description is incomplete. It doesn't explain what 'details' are returned, potential limitations, or error conditions. Given the lack of structured data, more context is needed for effective use.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so the schema fully documents both parameters. The description adds no additional meaning beyond implying that 'location' contextualizes the search, which is already clear from the schema. Baseline 3 is appropriate as the schema does the heavy lifting.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the action ('search') and resource ('place details'), specifying the scope ('in a given location'). It distinguishes from sibling 'search_places' by focusing on details rather than general search, but doesn't explicitly differentiate from 'search_place_by_number'.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided on when to use this tool versus alternatives like 'search_places' or 'search_place_by_number'. The description implies usage for detailed place searches but offers no explicit comparison or exclusion criteria.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
search_place_by_numberB
Find place name and address by phone number
| Name | Required | Description | Default |
|---|---|---|---|
| number | Yes | Phone number in E.164 format. Ex: +1234567890 |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It states the tool 'finds' information, implying a read-only operation, but doesn't clarify if it requires authentication, has rate limits, returns partial or full results, or handles errors. For a tool with no annotations, this leaves significant gaps in understanding its behavior beyond the basic purpose.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single, efficient sentence: 'Find place name and address by phone number.' It is front-loaded with the core purpose, uses clear language, and avoids unnecessary words. Every part of the sentence earns its place by conveying essential information without waste.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (simple lookup with one parameter) and the lack of annotations and output schema, the description is minimally complete. It states what the tool does but doesn't cover behavioral aspects like response format, error handling, or prerequisites. For a basic search tool, this is adequate but leaves room for improvement in providing a fuller context.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The input schema has 100% description coverage, with the parameter 'number' documented as 'Phone number in E.164 format. Ex: +1234567890.' The description adds no additional meaning beyond this, as it only mentions 'phone number' without specifying format or constraints. Since the schema does the heavy lifting, the baseline score of 3 is appropriate, indicating adequate but not enhanced parameter understanding.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Find place name and address by phone number.' It specifies the verb ('find') and the resources ('place name and address'), making it easy to understand what the tool does. However, it doesn't explicitly distinguish this tool from sibling tools like 'search_place' or 'search_places' (which might search by other criteria), so it doesn't reach the highest score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention sibling tools like 'search_place' or 'search_places', nor does it specify scenarios where this tool is preferred (e.g., when you have a phone number but not other place details). Without any usage context or exclusions, it offers minimal help in tool selection.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
search_placesC
Search places in a given location
| Name | Required | Description | Default |
|---|---|---|---|
| search | Yes | Places to search. Ex: italian restaurants in New York City, US |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It states the action ('Search') but doesn't cover critical aspects like whether this is a read-only operation, potential rate limits, authentication needs, or what the search results might include (e.g., format, pagination). This is a significant gap for a search tool with zero annotation coverage.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single, efficient sentence ('Search places in a given location') that is front-loaded and wastes no words. It directly communicates the core function without unnecessary elaboration, earning a perfect score for conciseness.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the lack of annotations and output schema, the description is incomplete. It doesn't explain what the search returns (e.g., list of places, details), how results are structured, or any behavioral traits like error handling. For a search tool with no structured support, this leaves the agent under-informed.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The input schema has 100% description coverage, with the 'search' parameter documented as 'Places to search. Ex: italian restaurants in New York City, US.' The description adds no additional meaning beyond this, as it doesn't elaborate on syntax or constraints. With high schema coverage, the baseline score of 3 is appropriate.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose as 'Search places in a given location,' which includes a specific verb ('Search') and resource ('places'). However, it doesn't explicitly differentiate from sibling tools like 'search_place' or 'search_place_by_number,' which appear to be similar search operations, preventing a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. With sibling tools like 'search_place' and 'search_place_by_number' available, there is no indication of context, prerequisites, or exclusions, leaving the agent to guess based on tool names alone.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
start_callC
Start a new phone call via Voyp API. The API returns the call id and a URL where users can track the progress of the call
| Name | Required | Description | Default |
|---|---|---|---|
| number | Yes | Phone number to call in E.164 format | |
| language | No | Language of the call. Ex: en-US, pt-PT, fr-FR | |
| context | Yes | Context of the call. Ex: Order a pizza |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It mentions that the API returns a call id and tracking URL, which adds some context about outputs. However, it fails to disclose critical traits like whether this is a mutating operation (implied by 'Start'), potential side effects (e.g., initiating a real phone call), error handling, or rate limits. For a tool with zero annotation coverage, this leaves significant gaps.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized with two sentences that are front-loaded: the first states the purpose, and the second explains the return values. There is no wasted text, making it efficient. However, it could be slightly more structured by explicitly separating purpose from behavioral details, keeping it at 4 rather than 5.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity of initiating a phone call (a mutating operation with real-world effects), no annotations, and no output schema, the description is incomplete. It lacks details on permissions, error cases, what the tracking URL entails, or how to handle the call id. For a tool with 3 parameters and significant behavioral implications, this is inadequate.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, meaning the input schema fully documents parameters like 'number', 'language', and 'context'. The description adds no additional meaning beyond what the schema provides, such as examples or usage notes for parameters. Baseline is 3 when the schema does the heavy lifting, but no extra value is added.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the action ('Start a new phone call') and resource ('via Voyp API'), with the verb 'Start' being specific. It distinguishes from siblings like 'get_call' or 'hangup_call' by indicating creation rather than retrieval or termination. However, it doesn't explicitly differentiate from all siblings (e.g., 'search_place' tools), keeping it at 4 rather than 5.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention prerequisites, such as authentication or account setup, or compare to sibling tools like 'get_call' for retrieving call details. Usage is implied by the action but lacks explicit context or exclusions.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Tool Schema Changelog
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
7 tool updates
v1.0.0- First observed
get_call - First observed
get_user - First observed
hangup_call - First observed
search_place - First observed
search_place_by_number - First observed
search_places - First observed
start_call
TDQS
Scored across 7 tools
The tools have some clear distinctions, such as get_call vs. hangup_call vs. start_call for call operations, but there is significant overlap between search_place, search_places, and search_place_by_number, which could cause confusion about which to use for location-based searches. The descriptions help clarify, but the boundaries are not perfectly distinct.
Most tools follow a consistent verb_noun pattern (e.g., get_call, get_user, hangup_call, start_call), with clear and readable naming. However, the search tools have minor deviations (search_place, search_places, search_place_by_number), which slightly disrupts the pattern but remains mostly consistent.
With 7 tools, the count is well-scoped for a server focused on phone calls and place searches. Each tool appears to serve a specific purpose without unnecessary duplication, fitting within the typical 3-15 range for a coherent toolset.
For call operations, there is good coverage with get, start, and hangup, but missing update or list operations for calls or users could be a gap. For place searches, the tools cover various search methods, but without create or delete operations, the surface feels incomplete for a full lifecycle in the domain.
Maintenance
Related MCP Connectors
The Telnyx MCP server is an official implementation of the Model Context Protocol that enables AI clients (like Claude Desktop, Cursor, and OpenAI Agents) to interact with Telnyx's telephony, messaging, and AI assistant APIs. It provides comprehensive capabilities including making and managing phone calls, sending SMS/MMS messages, purchasing and configuring phone numbers, creating AI assistants with custom instructions, managing cloud storage buckets, scraping and embedding website content, and handling integration secrets. The server exists as both a local implementation and a remotely hosted version, allowing developers to integrate real-world communication infrastructure directly into AI applications.
- ZapierOAuthcom.zapier
Hosted MCP server connecting AI assistants to 9,000+ apps and 40,000+ actions via Zapier.
Give AI agents real phone numbers, messages, and voice calls via MCP.
Discover and call 10,000+ production APIs from one MCP server. Pay-per-call billing for AI agents.
Related MCP Servers
- AlicenseNot gradedqualityDmaintenanceA Model Context Protocol server that enables AI models to interact with VoIPBin's VoIP services, supporting features like call management, agent management, campaigns, conferences, and chat functionality.4MIT
- AlicenseAqualityDmaintenanceMCP server for BubblyPhone that lets AI assistants make real phone calls, manage AI voice agents, buy phone numbers in 30+ countries, and track billing. Supports 20 tools for full telephony control.2013 npm1MIT
- AlicenseAqualityFmaintenanceMCP server for Vapi.ai that enables AI coding assistants to manage voice assistants, make outbound calls, and access call history directly from their development environment.166 npm2MIT

oitvoip-mcp-serverofficial
FlicenseBqualityDmaintenanceA Model Context Protocol (MCP) server that provides AI agents with seamless access to the NetSapiens VoIP platform for user management, call analytics, and system administration.234-