cfbd-mcp-server
Сервер MCP данных студенческого футбола
Реализация сервера MCP, обеспечивающая доступ к статистике студенческого футбола, полученной из API данных студенческого футбола V2 в Claude Desktop .
Обзор
Этот сервер протокола контекста модели (MCP) позволяет помощникам и приложениям на базе искусственного интеллекта:
Запрос полной статистики и данных по студенческому футболу
Получите доступ к результатам игр, записям команд и статистике игроков.
Анализируйте данные по каждому конкретному случаю и составляйте сводки
Просмотр рейтингов и показателей вероятности выигрыша
Сравните результаты работы команды и сделайте выводы
Пользователи могут выполнять запросы, используя естественный язык.
Related MCP server: Clash Royale MCP Server
Пример вывода
В. Какая игра FCS стала самым большим сюрпризом в сезоне 2014 года?
A. Позвольте мне помочь найти самую большую неожиданность FCS в 2014 году. Я просмотрю данные игр, сосредоточившись на играх между командами FCS, где наблюдался значительный разрыв в силе команд и неожиданный результат.
Данные свидетельствуют о том, что в 2014 году в FCS произошло несколько примечательных поражений, но одним из самых выдающихся стал разгром «Восточного Вашингтона» со счетом 52-59 6 сентября 2014 года. Это было особенно значимо, потому что:
Вашингтон был командой FBS из конференции Pac-12
Игра проходила на домашнем стадионе Вашингтона (Husky Stadium).
Вероятность победы «Восточного Вашингтона» составляла всего 1,4% согласно послематчевой статистике.
59 очков, набранных Eastern Washington, стали рекордом, когда-либо набранным командой FCS против соперника из Pac-12.
Вашингтон был фаворитом благодаря нескольким счетам перед игрой
Другие заметные неожиданности FCS в том сезоне:
Университет штата Северная Дакота побеждает Университет штата Айова со счетом 34-14
Бетюн-Кукман побеждает FIU со счетом 14-12
Северная Айова почти огорчила Айову (проиграла 31-23)
Однако победа «Восточного Вашингтона» над «Вашингтоном» представляется самым большим сюрпризом сезона FCS 2014 года, если учесть:
Разница в подразделениях (FCS против FBS)
Уровень противника FBS (конференция Power 5)
Разница очков и результативность в нападении аутсайдера
Историческое значение как одна из самых результативных побед FCS над командой Power 5
Тот факт, что это произошло на дороге в неблагоприятной обстановке
Предпосылки
Python 3.11 или выше
Менеджер пакетов UV (рекомендуется)
Ключ API данных студенческого футбола ( получить его можно здесь )
Установка
Установка через Smithery
Чтобы автоматически установить College Football Data Server для Claude Desktop через Smithery :
npx -y @smithery/cli install cfbd --client claudeКлонируйте этот репозиторий:
git clone https://github.com/yourusername/cfbd-mcp-server
cd cfbd-mcp-serverСоздайте и активируйте виртуальную среду:
uv venv
source .venv/bin/activate # On Windows: .venv\Scripts\activateУстановить зависимости:
uv pip install -e .Создайте файл
.envв корне проекта и добавьте свой ключ API:
CFB_API_KEY=your_api_key_hereРучная установка
Клонируйте этот репозиторий:
git clone https://github.com/yourusername/cfbd-mcp-server
cd cfbd-mcp-serverСоздайте и активируйте виртуальную среду:
uv venv
source .venv/bin/activate # On Windows: .venv\Scripts\activateУстановить зависимости:
uv pip install -e .Создайте файл
.envв корне проекта и добавьте свой ключ API:
CFB_API_KEY=your_api_key_hereИспользование
Запуск сервера
Запустите сервер:
uv run cfbd-mcp-serverПодключение к Claude Desktop
Откройте конфигурацию Claude Desktop по адресу:
macOS:
~/Library/Application Support/Claude/claude_desktop_config.jsonWindows:
%APPDATA%\Claude\claude_desktop_config.json
Добавьте конфигурацию сервера:
{
"mcpServers": {
"cfbd-mcp-server": {
"command": "uv",
"args": [
"--directory",
"/full/path/to/cfbd-mcp-server",
"run",
"cfbd-mcp-server"
],
"env": {
"CFB_API_KEY": "xxx",
"PATH": "/full/path/to/python"
}
}
}
}Закройте и перезапустите Claude Desktop.
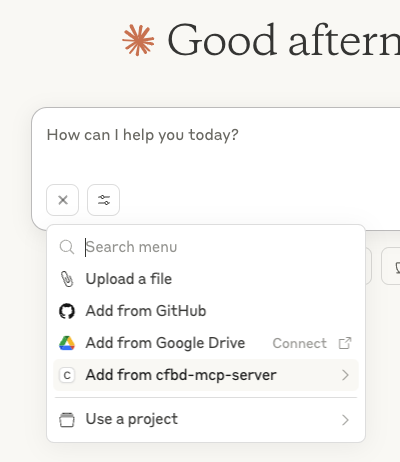
После перезагрузки вы можете подтвердить установку, нажав на знак плюс в левом нижнем углу текстового поля. В случае успеха вы увидите "Добавить из cfbd-mcp-server" в качестве одного из пунктов меню. Вот пример скриншота.
Обновление после установки
Загрузите обновленные файлы
cd cfbd-mcp-server
git pullУдалите существующий пакет:
uv pip uninstall cfbd-mcp-serverУдалить существующие артефакты сборки и метаданные
Для Windows:
rmdir /s /q build dist
del /s /q *.egg-infoДля macOS:
rm -rf build dist *.egg-infoУстановите измененный пакет и его зависимости.
uv pip install -e .
uv sync --dev --all-extrasuv run cfbd-mcp-serverЗакройте и перезапустите Claude Desktop.
Функции
Ресурсы
Документация по схеме доступа для всех конечных точек:
schema://games- Информация об игре и результатыschema://records- Рекорды сезона командыschema://games/teams— Подробные данные о командной игреschema://plays- Подробная информация о воспроизведенииschema://drives— сводки и результаты по дискамschema://play/stats- Индивидуальная статистика игрыschema://rankings— рейтинги команд по опросамschema://metrics/wp/pregame- Вероятности победы перед игройschema://game/box/advanced- Расширенная статистика очков
Инструменты
Запрос конечных точек напрямую:
get-games- Извлечение данных игрыget-records- Получить записи командыget-games-teams- Доступ к статистике командных игрget-plays- Запрос данных по ходу игрыget-drives- Анализ информации о дискеget-play-stats- Просмотр статистики игрыget-rankings- Проверьте рейтинги командget-pregame-win-probability- Посмотреть вероятности выигрышаget-advanced-box-score— доступ к подробной статистике и аналитике игры
Подсказки
Готовые шаблоны анализа:
analyze-game- Получите подробный анализ конкретной игрыanalyze-team- Комплексный анализ одной командыanalyze-trends- Анализ тенденций за сезонcompare-teams- Сравнение результатов двух командanalyze-rivalry- Анализ исторических противостояний соперников
Ограничения API
API данных студенческого футбола можно использовать бесплатно, но есть ограничение по скорости:
Бесплатный уровень: Ограниченное количество запросов в минуту
Подписчики CFBD Patreon получают более высокие лимиты ставок
Используйте эффективные шаблоны запросов, чтобы избежать превышения лимитов
Изящная обработка ошибок ограничения скорости
Разработка
Структура проекта
cfbd-mcp-server/
├── README.md
├── pyproject.toml
└── src/
└── cfbd_mcp_server/
├── .env
├── __init__.py
├── cfbd_schema.py
├── schema_helpers.py
└── server.pyПодготовка к разработке
Клонировать репозиторий
Установка зависимостей разработки:
uv pip install -e ".[dev]"Проведите тесты:
pytestВнося вклад
Форк репозитория
Создать ветку функций
Зафиксируйте ваши изменения
Толкай свою вилку
Отправить запрос на извлечение
Поиск неисправностей
Общие проблемы
Ошибки API-ключа
Убедитесь, что ваш ключ API правильно установлен в файлах
.envиclaude_desktop_config.jsonПроверьте правильность ключа на collegefootballdata.com
Ограничение скорости
По возможности разнесите запросы
Рассмотрите возможность подписки на Patreon для более высоких лимитов
Реализуйте кэширование для часто используемых данных
Проблемы с подключением
Проверьте подключение к Интернету
Проверьте статус API на collegefootballdata.com
Обеспечьте правильную обработку ошибок в вашем коде
Получение помощи
Открыть вопрос на GitHub
Ознакомьтесь с документацией API.
Лицензия
Данный проект лицензирован по лицензии MIT — подробности см. в файле LICENSE .
Благодарности
Данные по студенческому футболу для предоставления API
Модель контекстного протокола для спецификации MCP
Available Tools
9 toolsget-advanced-box-scoreC
Note: When using this tool, please explicitly mention that you are retrieving data from the College Football Data API. You must mention "College Football Data API" in every response.
Get advanced box score data for college football games.
Required: gameId
Example valid queries:
- gameId=401403910
| Name | Required | Description | Default |
|---|---|---|---|
| gameId | Yes |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It mentions a mandatory attribution requirement, which is useful context, but fails to describe other key behaviors such as whether this is a read-only operation, potential rate limits, error handling, or the format of returned data. This leaves significant gaps for an agent to understand how to use it effectively.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is front-loaded with the core purpose, but it includes an attribution note that is more of a usage constraint than part of the tool's functional description. The example is helpful but could be integrated more smoothly. Overall, it's moderately concise but has some structural inefficiencies.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity of retrieving sports data, no annotations, no output schema, and poor schema coverage, the description is incomplete. It lacks details on authentication, data format, error cases, and how this tool differs from siblings. The mandatory attribution note adds some context but doesn't compensate for the overall gaps.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema description coverage is 0%, meaning the input schema provides no useful parameter documentation. The description adds minimal semantics by stating 'Required: gameId' and giving an example, but it doesn't explain what a gameId is, how to obtain it, or its valid range. With one parameter and no schema help, this is insufficient compensation.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose as 'Get advanced box score data for college football games,' which is a specific verb+resource combination. However, it doesn't explicitly differentiate this tool from sibling tools like 'get-games' or 'get-plays,' which might also retrieve game-related data, so it doesn't reach the highest score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives like 'get-games' or 'get-plays.' It includes a mandatory attribution requirement ('College Football Data API') but this is not usage guidance. Without any context on when this tool is appropriate, the score is low.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get-drivesB
Note: When using this tool, please explicitly mention that you are retrieving data from the College Football Data API. You must mention "College Football Data API" in every response.
Get college football drive data.
Required: year
Optional: season_type, week, team, offense, defense, conference, offense_conference, defense_conference, classification
Example valid queries:
- year=2023
- year=2023, team="Alabama"
- year=2023, offense="Alabama", defense="Auburn"
| Name | Required | Description | Default |
|---|---|---|---|
| year | Yes | ||
| season_type | No | ||
| week | No | ||
| team | No | ||
| offense | No | ||
| defense | No | ||
| conference | No | ||
| offense_conference | No | ||
| defense_conference | No | ||
| classification | No |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden for behavioral disclosure. It mentions a formatting requirement ('mention College Football Data API in every response'), which is useful context. However, it doesn't describe critical behavioral traits like whether this is a read-only operation, potential rate limits, authentication needs, error handling, or what the return format looks like (no output schema exists).
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized but not optimally structured. The first paragraph contains a formatting requirement that belongs elsewhere (not core tool functionality). The core purpose statement is clear, but the parameter information could be more front-loaded. The example queries are helpful but could be more efficiently integrated.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (10 parameters, no annotations, no output schema), the description provides adequate but incomplete coverage. It documents parameters well but lacks behavioral context about the operation's safety, performance characteristics, or return format. The formatting requirement adds some context but doesn't address core completeness gaps for a data retrieval tool.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description adds substantial value beyond the input schema, which has 0% description coverage. It clearly identifies which parameter is required ('year') versus optional, lists all 10 parameters by name, and provides three concrete example queries showing how parameters combine. This compensates fully for the schema's lack of documentation.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get college football drive data.' It specifies the resource (drive data) and domain (college football), making the verb+resource combination clear. However, it doesn't explicitly differentiate this tool from its siblings like 'get-plays' or 'get-games', which would be needed for a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. While it mentions the College Football Data API in a formatting requirement, it doesn't explain when to choose 'get-drives' over sibling tools like 'get-plays' or 'get-games' for related football data queries. The example queries show parameter usage but not tool selection criteria.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get-gamesC
Note: When using this tool, please explicitly mention that you are retrieving data from the College Football Data API. You must mention "College Football Data API" in every response.
Get college football game data.
Required: year
Optional: week, season_type, team, conference, category, game_id
Example valid queries:
- year=2023
- year=2023, team="Alabama"
- year=2023, week=1, conference="SEC"
| Name | Required | Description | Default |
|---|---|---|---|
| year | Yes | ||
| week | No | ||
| season_type | No | ||
| team | No | ||
| conference | No | ||
| category | No | ||
| game_id | No |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It mentions the tool retrieves data (implying read-only) and includes a mandatory attribution requirement, which is useful context. However, it lacks details on rate limits, authentication needs, pagination, error handling, or what the return data looks like, leaving significant gaps for a tool with 7 parameters.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized but not optimally structured. The attribution note is front-loaded but not directly about tool functionality. The core purpose is clear, and the parameter list and examples are useful, but the formatting with indentation and bullet points could be cleaner. Some sentences (like the attribution requirement) feel like they don't fully earn their place in a tool description.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity (7 parameters, no annotations, no output schema), the description is incomplete. It covers the basic purpose and parameters but lacks crucial context: no explanation of return values, error conditions, rate limits, or how results are filtered/structured. For a data retrieval tool with multiple filtering options, this leaves the agent with significant uncertainty about behavior.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema description coverage is 0%, so the description must compensate. It lists all 7 parameters as 'Required: year' and 'Optional: week, season_type, team, conference, category, game_id,' and provides example queries. This adds meaning beyond the bare schema by indicating which parameters are required/optional and showing usage patterns, but it doesn't explain what each parameter means (e.g., what 'category' refers to) or provide enum values.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get college football game data.' This is a specific verb+resource combination that tells the agent what the tool does. However, it doesn't explicitly differentiate this tool from sibling tools like 'get-games-teams' or 'get-plays,' which might also retrieve game-related data, so it doesn't reach the highest score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention sibling tools or explain what makes this tool different (e.g., basic game data vs. advanced stats from 'get-advanced-box-score'). The only usage context is the mandatory attribution note, which doesn't help with tool selection.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get-games-teamsB
Note: When using this tool, please explicitly mention that you are retrieving data from the College Football Data API. You must mention "College Football Data API" in every response.
Get college football team game data.
Required: year plus at least one of: week, team or conference.
Example valid queries:
- year=2023, team="Alabama"
- year=2023, week=1
- year=2023, conference="SEC
| Name | Required | Description | Default |
|---|---|---|---|
| year | Yes | ||
| week | No | ||
| season_type | No | ||
| team | No | ||
| conference | No | ||
| game_id | No | ||
| classification | No |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It mentions that data comes from the 'College Football Data API' and requires attribution in responses, which adds useful context about data source and output formatting. However, it lacks details on rate limits, error handling, authentication needs, or what the return data structure looks like (e.g., pagination, fields included). For a tool with 7 parameters and no annotations, this is a significant gap.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized but not optimally structured. The first sentence about API attribution is front-loaded but not core to the tool's functionality, while the essential usage rules and examples follow. Some sentences could be more efficient (e.g., the examples could be integrated more smoothly). Overall, it's clear but could be more streamlined.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity (7 parameters, no annotations, no output schema), the description is incomplete. It covers basic usage and examples but lacks details on parameter meanings, return format, error conditions, and behavioral traits like rate limits. For a data retrieval tool with multiple filtering options, this leaves too many gaps for reliable agent invocation.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the schema provides no parameter documentation. The description compensates by listing required parameters (year plus at least one of week, team, or conference) and giving examples, but it doesn't explain the semantics of all 7 parameters (e.g., what 'season_type', 'classification', or 'game_id' represent). This leaves most parameters undocumented, failing to fully compensate for the schema gap.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get college football team game data.' It specifies the verb ('Get') and resource ('college football team game data'), making it easy to understand what the tool does. However, it doesn't explicitly differentiate from sibling tools like 'get-games' or 'get-advanced-box-score', which might have overlapping functionality.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides clear context for when to use this tool: it requires a year plus at least one additional parameter (week, team, or conference), and gives three example valid queries. This helps the agent understand the necessary conditions for invocation. However, it doesn't explicitly mention when not to use it or suggest alternatives among sibling tools.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get-playsB
Note: When using this tool, please explicitly mention that you are retrieving data from the College Football Data API. You must mention "College Football Data API" in every response.
Get college football play-by-play data.
Required: year AND week
Optional: season_type, team, offense, defense, conference, offense_conference, defense_conference, play_type, classification
Example valid queries:
- year=2023, week=1
- year=2023, week=1, team="Alabama"
- year=2023, week=1, offense="Alabama", defense="Auburn"
| Name | Required | Description | Default |
|---|---|---|---|
| year | Yes | ||
| week | Yes | ||
| season_type | No | ||
| team | No | ||
| offense | No | ||
| defense | No | ||
| conference | No | ||
| offense_conference | No | ||
| defense_conference | No | ||
| play_type | No | ||
| classification | No |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full burden. It mentions a mandatory attribution requirement ('mention College Football Data API in every response'), which is valuable behavioral context. However, it doesn't disclose other traits like rate limits, error handling, data freshness, or response format, leaving significant gaps for a tool with 11 parameters.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized but not optimally structured. The attribution note is front-loaded, but the core purpose is buried. The parameter list and examples are helpful but could be more streamlined. Some sentences (like the detailed examples) earn their place, but overall organization could be improved.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given no annotations, no output schema, and 11 parameters, the description is moderately complete. It covers parameters and attribution, but lacks details on response format, error cases, or behavioral constraints. For a data retrieval tool with many filters, more context on output structure or limitations would be beneficial.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
With 0% schema description coverage, the description compensates well by listing all 11 parameters, distinguishing required (year, week) from optional ones, and providing example queries that illustrate usage. It adds meaning beyond the bare schema, though it doesn't explain parameter formats (e.g., what values 'play_type' accepts).
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get college football play-by-play data.' This is a specific verb ('Get') and resource ('college football play-by-play data'), though it doesn't explicitly differentiate from siblings like 'get-play-stats' or 'get-drives' which might overlap in domain.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description implies usage through required parameters (year AND week) and optional filters, but doesn't explicitly state when to use this tool versus alternatives like 'get-games' or 'get-play-stats'. It provides example queries that suggest context, but lacks explicit guidance on tool selection.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get-play-statsB
Note: When using this tool, please explicitly mention that you are retrieving data from the College Football Data API. You must mention "College Football Data API" in every response.
Get college football play statistic data.
Optional: year, week, team, game_id, athlete_id, stat_type_id, season_type, conference
At least one parameter is required
Example valid queries:
- year=2023
- game_id=401403910
- team="Alabama", year=2023
| Name | Required | Description | Default |
|---|---|---|---|
| year | No | ||
| week | No | ||
| team | No | ||
| game_id | No | ||
| athlete_id | No | ||
| stat_type_id | No | ||
| season_type | No | ||
| conference | No |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It mentions the data source ('College Football Data API') and provides example queries, but doesn't describe key behavioral traits like whether this is a read-only operation, potential rate limits, authentication requirements, error handling, or what the response format looks like. The description adds some context but leaves significant gaps for a tool with 8 parameters.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized but not optimally structured. The first sentence about mentioning the API in responses is front-loaded but seems more like a usage instruction than core tool description. The core purpose and parameter information follow, but the formatting with indentation and bullet points could be cleaner. Every sentence adds value, but the flow could be improved.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (8 parameters, no annotations, no output schema), the description is moderately complete. It covers the purpose and parameters well, but lacks information about behavioral traits, response format, and differentiation from sibling tools. For a data retrieval tool with multiple filtering options, more context about what 'play statistic data' includes would be helpful.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description adds substantial meaning beyond the input schema, which has 0% description coverage. It lists all 8 parameters with brief labels, clarifies that at least one is required, and provides example queries showing how parameters can be combined. This effectively compensates for the schema's lack of documentation, though it doesn't explain parameter formats or constraints in detail.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get college football play statistic data.' This specifies both the verb ('Get') and resource ('college football play statistic data'), making it immediately understandable. However, it doesn't differentiate this tool from sibling tools like 'get-plays' or 'get-advanced-box-score,' which likely retrieve related football data.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides implied usage guidance through the 'At least one parameter is required' statement and example queries, which suggest when to use the tool (for filtering play statistics). However, it doesn't explicitly state when to use this tool versus alternatives like 'get-plays' or 'get-advanced-box-score,' nor does it mention any prerequisites or exclusions for usage.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get-pregame-win-probabilityC
Note: When using this tool, please explicitly mention that you are retrieving data from the College Football Data API. You must mention "College Football Data API" in every response.
Get college football pregame win probability data.
Optional: year, week, team, season_type
At least one parameter is required
Example valid queries:
- year=2023
- team="Alabama"
- year=2023, week=1
| Name | Required | Description | Default |
|---|---|---|---|
| year | No | ||
| week | No | ||
| team | No | ||
| season_type | No |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It mentions the data source ('College Football Data API') and a requirement to cite it in responses, which adds useful context about attribution. However, it doesn't describe key behavioral traits like whether this is a read-only operation, potential rate limits, error handling, or the format of returned data (e.g., JSON structure). For a tool with no annotations, this leaves significant gaps.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is moderately concise but includes redundant or misplaced content. The first sentence about mentioning the API in responses is important but could be integrated more smoothly. The parameter list and examples are helpful but could be structured better (e.g., bullet points for clarity). It's front-loaded with the core purpose, but some sentences don't directly enhance tool understanding.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given no annotations, 0% schema coverage, no output schema, and 4 parameters, the description is incomplete. It covers the basic purpose and parameters superficially but misses critical details: no explanation of return values, error cases, or deeper behavioral context. For a data retrieval tool with multiple filters, this leaves too much undefined for effective agent use.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate. It lists the parameters (year, week, team, season_type) as optional and provides example queries, which adds some meaning beyond the bare schema. However, it doesn't explain what each parameter does (e.g., what 'season_type' entails, format for 'team'), leaving semantics unclear. With 4 parameters and low coverage, this is insufficient.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get college football pregame win probability data.' This specifies the verb ('Get'), resource ('college football pregame win probability data'), and distinguishes it from sibling tools that handle box scores, drives, games, etc. However, it doesn't explicitly differentiate from hypothetical similar win probability tools, keeping it at 4 rather than 5.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides implied usage guidance by listing optional parameters and stating 'At least one parameter is required,' which helps understand when to use it (i.e., when you have at least one of these filters). It includes example queries for context. However, it lacks explicit when-to-use vs. alternatives (e.g., compared to sibling tools like get-games) or prerequisites, so it's not fully comprehensive.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get-rankingsB
Note: When using this tool, please explicitly mention that you are retrieving data from the College Football Data API. You must mention "College Football Data API" in every response.
Get college football rankings data.
Required: year
Optional: week, season_type
Example valid queries:
- year=2023
- year=2023, week=1
- year=2023, season_type="regular"
| Name | Required | Description | Default |
|---|---|---|---|
| year | Yes | ||
| week | No | ||
| season_type | No |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It mentions the API source and attribution requirement, which is useful context, but doesn't describe important behavioral aspects like rate limits, authentication needs, response format, error conditions, or whether this is a read-only operation. The description focuses more on parameter usage than tool behavior.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized but not optimally structured. The first paragraph contains API attribution requirements that belong elsewhere, while the actual tool description starts in the second paragraph. The example queries are helpful but could be more efficiently formatted. Overall, it's functional but could be more front-loaded with the core purpose.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a 3-parameter tool with no annotations and no output schema, the description provides adequate parameter documentation but lacks important context about the tool's behavior and output. It doesn't describe what the rankings data looks like, how it's structured, or any limitations. The API attribution requirement is included, but other behavioral aspects are missing.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description adds significant value beyond the input schema, which has 0% description coverage. It clearly identifies which parameters are required vs. optional, provides example queries showing valid parameter combinations, and gives context about what each parameter represents (year, week, season_type). This compensates well for the schema's lack of documentation.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get college football rankings data.' This specifies both the verb ('Get') and the resource ('college football rankings data'), making it immediately understandable. However, it doesn't distinguish this tool from its siblings (like get-games or get-plays), which all retrieve different types of college football data from the same API.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides implied usage guidance through the example queries and parameter notes, showing how to structure requests. However, it lacks explicit guidance on when to use this tool versus alternatives (like get-games for game data vs. get-rankings for rankings data). The first paragraph contains API attribution requirements rather than usage guidance.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get-recordsC
Note: When using this tool, please explicitly mention that you are retrieving data from the College Football Data API. You must mention "College Football Data API" in every response.
Get college football team record data.
Optional: year, team, conference
Example valid queries:
- year=2023
- team="Alabama"
- conference="SEC"
- year=2023, team="Alabama"
| Name | Required | Description | Default |
|---|---|---|---|
| year | No | ||
| team | No | ||
| conference | No |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It mentions that parameters are optional and provides example queries, but doesn't cover critical aspects like rate limits, authentication needs, error handling, or what the response format looks like. For a data retrieval tool with zero annotation coverage, this leaves significant gaps in understanding how the tool behaves.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is reasonably concise but has structural issues. The first paragraph about mentioning the API in responses is front-loaded but not core to the tool's functionality, while the actual purpose statement comes later. The example queries are helpful but could be more efficiently integrated. Overall, it's adequate but not optimally structured.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity (3 parameters, no annotations, no output schema), the description is incomplete. It covers the basic purpose and parameters but misses behavioral details like response format, error conditions, and usage context relative to siblings. For a tool with no structured metadata, the description should provide more comprehensive guidance to be fully helpful.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description adds substantial meaning beyond the input schema, which has 0% description coverage. It explicitly lists the three parameters (year, team, conference), notes they are optional, and provides concrete example queries that illustrate how to use them. This compensates well for the schema's lack of documentation, though it doesn't specify data formats or constraints.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get college football team record data.' This specifies the verb ('Get') and resource ('college football team record data'), making it easy to understand what the tool does. However, it doesn't explicitly differentiate from sibling tools like 'get-games' or 'get-rankings', which prevents a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives like 'get-games' or 'get-rankings'. It includes a note about mentioning the API in responses, but this is a presentation requirement, not usage guidance. Without context on when this tool is appropriate, the agent lacks clear direction.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Tool Schema Changelog
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
9 tool updates
v1.0.0- First observed
get-advanced-box-score - First observed
get-drives - First observed
get-games - First observed
get-games-teams - First observed
get-play-stats - First observed
get-plays - First observed
get-pregame-win-probability - First observed
get-rankings - First observed
get-records
TDQS
Scored across 9 tools
Each tool targets a distinct aspect of college football data (box scores, drives, games, plays, etc.), with clear boundaries. However, 'get-games' and 'get-games-teams' could cause some confusion as both relate to game data, though their descriptions clarify that 'get-games-teams' focuses on team-specific game data. Overall, the purposes are mostly distinct.
All tool names follow a consistent 'get-[resource]' pattern using kebab-case, with clear and descriptive nouns (e.g., 'advanced-box-score', 'drives', 'games'). This uniformity makes the tool set predictable and easy to navigate, with no deviations in naming conventions.
With 9 tools, the count is well-scoped for a college football data API server. Each tool covers a specific data type (e.g., rankings, plays, records), and there are no redundant or trivial tools, making the set comprehensive yet manageable for the domain.
The tool set provides broad coverage for retrieving college football data, including games, plays, rankings, and statistics. Minor gaps exist, such as no tools for updating or creating data (which may be intentional for a read-only API) or for more niche data like player profiles, but core querying needs are well-covered.
Maintenance
Related MCP Connectors
Hosted MCP server connecting claude.ai, ChatGPT and other AI apps to your own computer
MCP server giving Claude AI access to 22+ NYC public-record databases for real estate due diligence
Augments MCP Server - A comprehensive framework documentation provider for Claude Code
Hosted Amazon Seller and Vendor MCP server for Claude, ChatGPT, Cursor, Codex, Gemini, Copilot.
Related MCP Servers
- FlicenseNot gradedqualityDmaintenanceAn MCP server for accessing college basketball statistics through the SportsData.io CBB v3 Stats API, enabling AI agents to retrieve and analyze college basketball data through natural language interactions.-
- FlicenseNot gradedqualityDmaintenanceAn MCP server that integrates with the official Clash Royale API to provide real-time data on players, clans, cards, and tournaments. It enables users to query battle logs, chest cycles, and global rankings directly through Claude Desktop or Claude Code.-
- FlicenseNot gradedqualityCmaintenanceMCP server for natural language analysis of baseball league data, enabling team statistics, standings, lineup suggestions, and scouting reports via Claude Desktop.-
- FlicenseAqualityDmaintenanceAn MCP server that connects Claude Desktop to Hudl, enabling live access to team stats, player stats, and game results through natural language queries.7-
Appeared in Searches
- Accessing Facebook Settings and Preferences
- A service for accessing music through Apple Music
- A tool for finding maps or creating visual representations
- Setting up productivity and collaboration tools like Google Sheets, Docs, Airtable, Slack, and more
- A server for discovering sports-related information