Tavily MCP Serverofficial
A
licenseA
qualityC
maintenanceThis server enables AI systems to integrate with Tavily's search and data extraction tools, providing real-time web information access and domain-specific searches.
4
15,370 npm
2,386
MIT

Tutorials on Medium show how to integrate Tavily MCP with Neo4j and with Cline in VS Code
Mentioned in a tutorial about combining Tavily MCP with Neo4j MCP server to build a knowledge graph assistant
Server is built on Node.js and provides web search, data extraction, web mapping, and web crawling functionality
Click on "Deploy Server".
Wait a few minutes for the server to deploy. Once ready, it will show a "Started" state.
In the chat, type @ followed by the MCP server name and your instructions, e.g., "@tavily-mcp search for the latest AI research papers on large language models"
That's it! The server will respond to your query, and you can continue using it as needed.
Here is a step-by-step guide with screenshots.
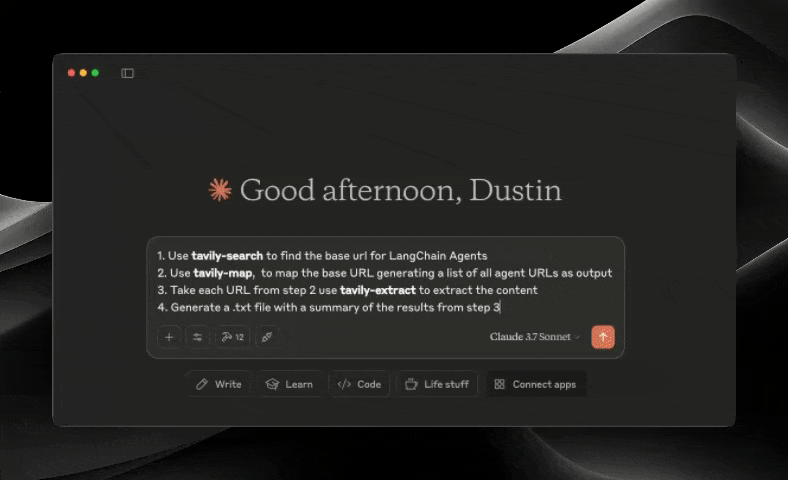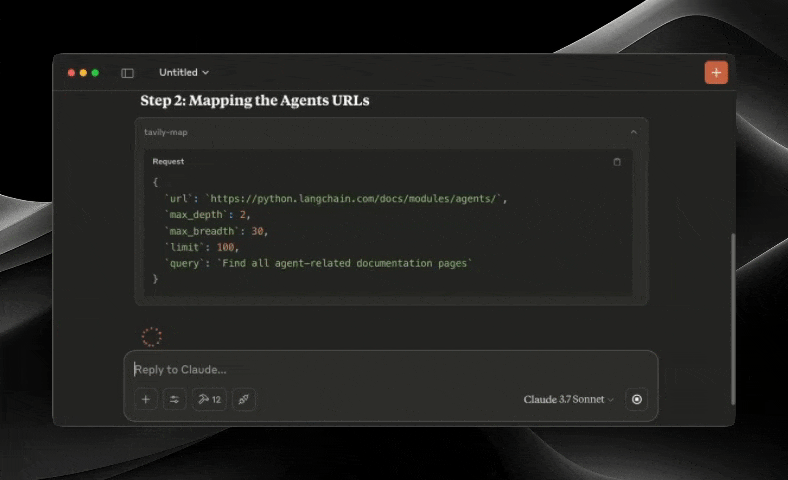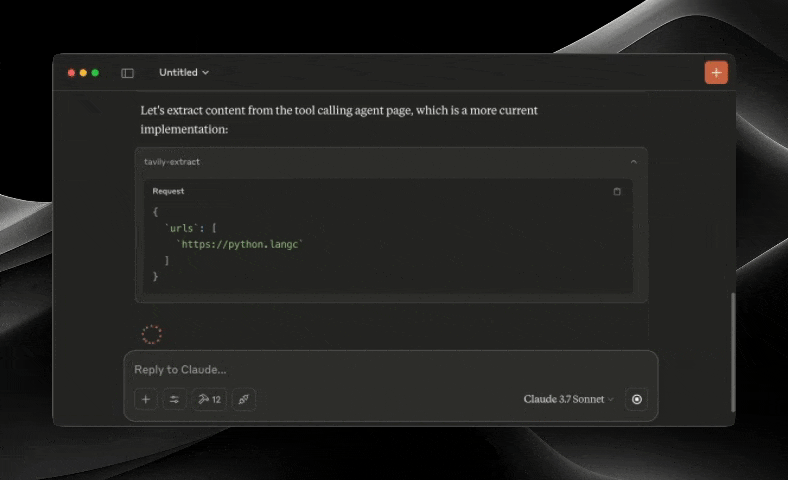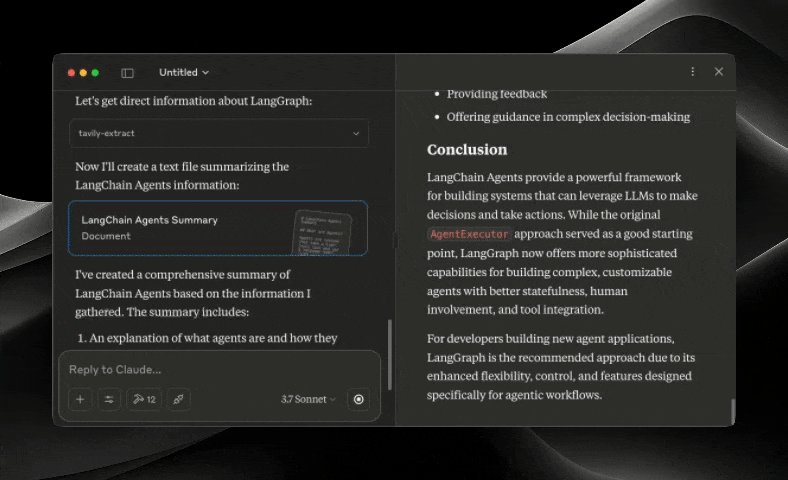
The Model Context Protocol (MCP) is an open standard that enables AI systems to interact seamlessly with various data sources and tools, facilitating secure, two-way connections.
Developed by Anthropic, the Model Context Protocol (MCP) enables AI assistants like Claude to seamlessly integrate with Tavily's advanced search and data extraction capabilities. This integration provides AI models with real-time access to web information, complete with sophisticated filtering options and domain-specific search features.
The Tavily MCP server provides:
search, extract, map, crawl tools
Real-time web search capabilities through the tavily-search tool
Intelligent data extraction from web pages via the tavily-extract tool
Powerful web mapping tool that creates a structured map of website
Web crawler that systematically explores websites
Tutorial on combining Tavily MCP with Neo4j MCP server
Tutorial on integrating Tavily MCP with Cline in VS Code
Related MCP server: tavily-mcp
Before you begin, ensure you have:
If you don't have a Tavily API key, you can sign up for a free account here
Node.js (v20 or higher)
You can verify your Node.js installation by running:
node --version
Git installed (only needed if using Git installation method)
On macOS: brew install git
On Linux:
Debian/Ubuntu: sudo apt install git
RedHat/CentOS: sudo yum install git
On Windows: Download Git for Windows
npx -y tavily-mcp@0.2.1 To install Tavily MCP Server for Claude Desktop automatically via Smithery:
npx -y @smithery/cli install @tavily-ai/tavily-mcp --client claudeAlthough you can launch a server on its own, it's not particularly helpful in isolation. Instead, you should integrate it into an MCP client. Below is an example of how to configure the Claude Desktop app to work with the tavily-mcp server.
This repository will explain how to configure VS Code, Cursor and Claude Desktop to work with the tavily-mcp server.
For one-click installation, click one of the install buttons below:
First check if there are install buttons at the top of this section that match your needs. If you prefer manual installation, follow these steps:
Add the following JSON block to your User Settings (JSON) file in VS Code. You can do this by pressing Ctrl + Shift + P (or Cmd + Shift + P on macOS) and typing Preferences: Open User Settings (JSON).
{
  "mcp": {
    "inputs": [
      {
        "type": "promptString",
        "id": "tavily_api_key",
        "description": "Tavily API Key",
        "password": true
      }
    ],
    "servers": {
      "tavily": {
        "command": "npx",
        "args": ["-y", "tavily-mcp@0.2.1"],
        "env": {
          "TAVILY_API_KEY": "${input:tavily_api_key}"
        }
      }
    }
  }
}
Optionally, you can add it to a file called .vscode/mcp.json in your workspace:
{
  "inputs": [
    {
      "type": "promptString",
      "id": "tavily_api_key",
      "description": "Tavily API Key",
      "password": true
    }
  ],
  "servers": {
    "tavily": {
      "command": "npx",
      "args": ["-y", "tavily-mcp@0.2.1"],
      "env": {
        "TAVILY_API_KEY": "${input:tavily_api_key}"
      }
    }
  }
}The easiest way to set up the Tavily MCP server in Cline is through the marketplace with a single click:
Open Cline in VS Code
Click on the Cline icon in the sidebar
Navigate to the "MCP Servers" tab ( 4 squares )
Search "Tavily" and click "install"
When prompted, enter your Tavily API key
Alternatively, you can manually set up the Tavily MCP server in Cline:
Open the Cline MCP settings file:
# Using Visual Studio Code
code ~/Library/Application\ Support/Code/User/globalStorage/saoudrizwan.claude-dev/settings/cline_mcp_settings.json

# Or using TextEdit
open -e ~/Library/Application\ Support/Code/User/globalStorage/saoudrizwan.claude-dev/settings/cline_mcp_settings.jsoncode %APPDATA%\Code\User\globalStorage\saoudrizwan.claude-dev\settings\cline_mcp_settings.jsonAdd the Tavily server configuration to the file:
Replace your-api-key-here with your actual Tavily API key.
{
  "mcpServers": {
    "tavily-mcp": {
      "command": "npx",
      "args": ["-y", "tavily-mcp@0.2.1"],
      "env": {
        "TAVILY_API_KEY": "your-api-key-here"
      },
      "disabled": false,
      "autoApprove": []
    }
  }
}
Save the file and restart Cline if it's already running.
When using Cline, you'll now have access to the Tavily MCP tools. You can ask Cline to use the tavily-search and tavily-extract tools directly in your conversations.
Note: Requires Cursor version 0.45.6 or higher
To set up the Tavily MCP server in Cursor:
Open Cursor Settings
Navigate to Features > MCP Servers
Click on the "+ Add New MCP Server" button
Fill out the following information:
Name: Enter a nickname for the server (e.g., "tavily-mcp")
Type: Select "command" as the type
Command: Enter the command to run the server:
env TAVILY_API_KEY=your-api-key npx -y tavily-mcp@0.2.1Important: Replace
your-api-keywith your Tavily API key. You can get one at app.tavily.com/home
After adding the server, it should appear in the list of MCP servers. You may need to manually press the refresh button in the top right corner of the MCP server to populate the tool list.
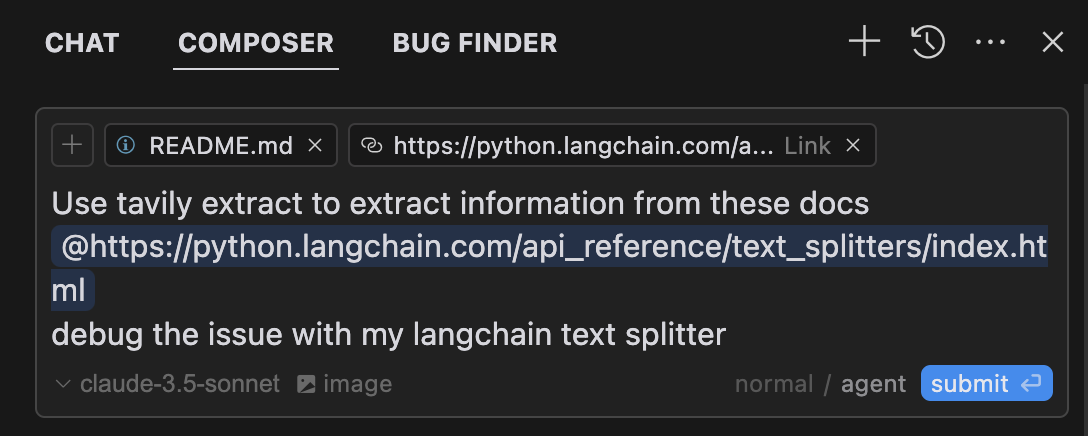
The Composer Agent will automatically use the Tavily MCP tools when relevant to your queries. It is better to explicitly request to use the tools by describing what you want to do (e.g., "User tavily-search to search the web for the latest news on AI"). On mac press command + L to open the chat, select the composer option at the top of the screen, beside the submit button select agent and submit the query when ready.
# Create the config file if it doesn't exist
touch "$HOME/Library/Application Support/Claude/claude_desktop_config.json"

# Opens the config file in TextEdit
open -e "$HOME/Library/Application Support/Claude/claude_desktop_config.json"

# Alternative method using Visual Studio Code (requires VS Code to be installed)
code "$HOME/Library/Application Support/Claude/claude_desktop_config.json"code %APPDATA%\Claude\claude_desktop_config.jsonReplace your-api-key-here with your actual Tavily API key.
{
  "mcpServers": {
    "tavily-mcp": {
      "command": "npx",
      "args": ["-y", "tavily-mcp@0.2.1"],
      "env": {
        "TAVILY_API_KEY": "your-api-key-here"
      }
    }
  }
}Clone the repository:
git clone https://github.com/tavily-ai/tavily-mcp.git
cd tavily-mcp
Install dependencies:
npm installBuild the project:
npm run buildFollow the configuration steps outlined in the Configuring the Claude Desktop app section above, using the below JSON configuration.
Replace your-api-key-here with your actual Tavily API key and /path/to/tavily-mcp with the actual path where you cloned the repository on your system.
{
  "mcpServers": {
    "tavily": {
      "command": "npx",
      "args": ["/path/to/tavily-mcp/build/index.js"],
      "env": {
        "TAVILY_API_KEY": "your-api-key-here"
      }
    }
  }
}Once the installation is complete, and the Claude desktop app is configured, you must completely close and re-open the Claude desktop app to see the tavily-mcp server. You should see a hammer icon in the bottom left of the app, indicating available MCP tools, you can click on the hammer icon to see more detial on the tavily-search and tavily-extract tools.
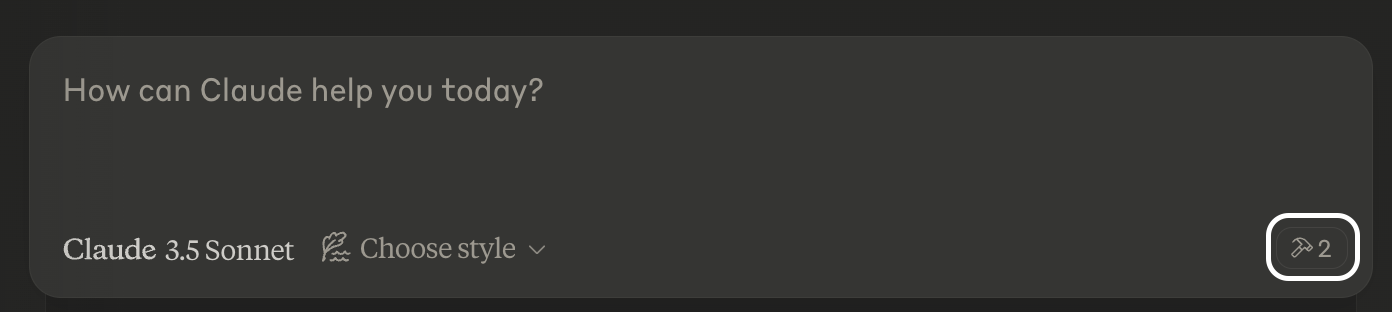
Now claude will have complete access to the tavily-mcp server, including the tavily-search and tavily-extract tools. If you insert the below examples into the Claude desktop app, you should see the tavily-mcp server tools in action.
General Web Search:
Can you search for recent developments in quantum computing?News Search:
Search for news articles about AI startups from the last 7 days.Domain-Specific Search:
Search for climate change research on nature.com and sciencedirect.comExtract Article Content:
Extract the main content from this article: https://example.com/articleYou can also combine the tavily-search and tavily-extract tools to perform more complex tasks.
Search for news articles about AI startups from the last 7 days and extract the main content from each article to generate a detailed report.Server Not Found
Verify the npm installation by running npm --verison
Check Claude Desktop configuration syntax by running code ~/Library/Application\ Support/Claude/claude_desktop_config.json
Ensure Node.js is properly installed by running node --version
NPX related issues
If you encounter errors related to npx, you may need to use the full path to the npx executable instead.
You can find this path by running which npx in your terminal, then replace the "command": "npx" line with "command": "/full/path/to/npx" in your configuration.
API Key Issues
Confirm your Tavily API key is valid
Check the API key is correctly set in the config
Verify no spaces or quotes around the API key
Model Context Protocol for the MCP specification
Anthropic for Claude Desktop
A powerful web crawler that initiates a structured web crawl starting from a specified base URL. The crawler expands from that point like a tree, following internal links across pages. You can control how deep and wide it goes, and guide it to focus on specific sections of the site.
| Name | Required | Description | Default |
|---|---|---|---|
| url | Yes | The root URL to begin the crawl | |
| max_depth | No | Max depth of the crawl. Defines how far from the base URL the crawler can explore. | |
| max_breadth | No | Max number of links to follow per level of the tree (i.e., per page) | |
| limit | No | Total number of links the crawler will process before stopping | |
| instructions | No | Natural language instructions for the crawler | |
| select_paths | No | Regex patterns to select only URLs with specific path patterns (e.g., /docs/.*, /api/v1.*) | |
| select_domains | No | Regex patterns to select crawling to specific domains or subdomains (e.g., ^docs\.example\.com$) | |
| allow_external | No | Whether to allow following links that go to external domains | |
| categories | No | Filter URLs using predefined categories like documentation, blog, api, etc | |
| extract_depth | No | Advanced extraction retrieves more data, including tables and embedded content, with higher success but may increase latency | basic |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It effectively describes the crawling behavior ('expands like a tree', 'following internal links'), scope control ('how deep and wide it goes'), and focus guidance. However, it doesn't mention important behavioral aspects like rate limits, authentication requirements, error handling, or what the output format looks like.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is perfectly sized at three sentences, each earning its place. It's front-loaded with the core purpose, followed by expansion behavior, and ending with control capabilities. Zero wasted words or redundant information.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity of a 10-parameter web crawling tool with no annotations and no output schema, the description provides adequate high-level context but lacks details about output format, error conditions, performance characteristics, or specific use cases. For a tool this complex, more behavioral and output information would be helpful despite the excellent schema coverage.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so the schema already documents all 10 parameters thoroughly. The description adds some high-level context about controlling depth, breadth, and focusing on specific sections, which aligns with parameters like max_depth, max_breadth, and categories/select_paths. However, it doesn't provide additional semantic meaning beyond what's already in the comprehensive schema descriptions.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose with specific verbs ('initiates a structured web crawl', 'expands like a tree', 'following internal links') and identifies the resource ('starting from a specified base URL'). It distinguishes this crawl tool from sibling tools like 'search' or 'extract' by emphasizing its tree-based expansion approach.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides clear context about when to use this tool: for structured crawling starting from a base URL with tree-like expansion. It mentions controlling depth, breadth, and focusing on specific site sections. However, it doesn't explicitly state when NOT to use it or name specific alternatives among the sibling tools.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
A powerful web content extraction tool that retrieves and processes raw content from specified URLs, ideal for data collection, content analysis, and research tasks.
| Name | Required | Description | Default |
|---|---|---|---|
| urls | Yes | List of URLs to extract content from | |
| extract_depth | No | Depth of extraction - 'basic' or 'advanced', if usrls are linkedin use 'advanced' or if explicitly told to use advanced | basic |
| include_images | No | Include a list of images extracted from the urls in the response |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It mentions 'retrieves and processes raw content' but lacks details on rate limits, authentication needs, error handling, or what 'processes' entails (e.g., formatting, cleaning). For a web extraction tool with potential complexities, this leaves significant gaps in understanding its behavior beyond basic functionality.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single, efficient sentence that front-loads the core purpose ('retrieves and processes raw content from specified URLs') and adds value with ideal use cases. There's no wasted wording, though it could be slightly more structured by separating functional description from usage contexts.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (web content extraction with processing), lack of annotations, and no output schema, the description is incomplete. It doesn't explain what 'processes' means, the format or structure of returned content, potential limitations (e.g., site restrictions), or how it differs from siblings. For a tool with three parameters and no structured behavioral hints, more context is needed.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The input schema has 100% description coverage, clearly documenting all three parameters. The description adds no parameter-specific information beyond what the schema provides, such as examples or contextual usage tips. However, since the schema is comprehensive, a baseline score of 3 is appropriate as the description doesn't need to compensate for gaps.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose as 'retrieves and processes raw content from specified URLs' with specific verbs and resources. It distinguishes itself from potential siblings by focusing on extraction rather than crawling, mapping, or searching, though it doesn't explicitly name alternatives. The description is specific but could be more precise about what 'processes' entails.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides minimal guidance with 'ideal for data collection, content analysis, and research tasks,' but offers no explicit when-to-use rules, exclusions, or comparisons to sibling tools like tavily-crawl, tavily-map, or tavily-search. There's no mention of prerequisites, limitations, or scenarios where this tool is preferred over alternatives.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
A powerful web mapping tool that creates a structured map of website URLs, allowing you to discover and analyze site structure, content organization, and navigation paths. Perfect for site audits, content discovery, and understanding website architecture.
| Name | Required | Description | Default |
|---|---|---|---|
| url | Yes | The root URL to begin the mapping | |
| max_depth | No | Max depth of the mapping. Defines how far from the base URL the crawler can explore | |
| max_breadth | No | Max number of links to follow per level of the tree (i.e., per page) | |
| limit | No | Total number of links the crawler will process before stopping | |
| instructions | No | Natural language instructions for the crawler | |
| select_paths | No | Regex patterns to select only URLs with specific path patterns (e.g., /docs/.*, /api/v1.*) | |
| select_domains | No | Regex patterns to select crawling to specific domains or subdomains (e.g., ^docs\.example\.com$) | |
| allow_external | No | Whether to allow following links that go to external domains | |
| categories | No | Filter URLs using predefined categories like documentation, blog, api, etc |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden. It describes the tool as 'powerful' and for 'discovering and analyzing,' which implies it performs read-only operations, but doesn't specify behavioral traits like rate limits, authentication needs, or potential impacts on target websites. The description adds value by explaining the mapping purpose but lacks detailed behavioral disclosure.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized and front-loaded: it starts with the core purpose, then elaborates on use cases. Every sentence earns its place by adding value without redundancy, making it efficient and well-structured.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity (9 parameters, no annotations, no output schema), the description is somewhat complete but has gaps. It explains the tool's purpose and use cases well, but without annotations or output schema, it doesn't cover behavioral aspects or return values, leaving the agent to infer details from the schema alone.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema description coverage is 100%, so the schema already documents all 9 parameters thoroughly. The description doesn't add specific parameter semantics beyond what the schema provides, such as explaining how 'categories' interact with mapping or the implications of 'max_depth.' Baseline 3 is appropriate since the schema does the heavy lifting.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'creates a structured map of website URLs' with specific verbs like 'discover and analyze site structure, content organization, and navigation paths.' It distinguishes from siblings like 'search' or 'extract' by focusing on mapping and structural analysis rather than general search or content extraction.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides clear context for when to use this tool: 'Perfect for site audits, content discovery, and understanding website architecture.' It doesn't explicitly mention when not to use it or name alternatives among siblings, but the context strongly implies it's for structural mapping rather than other tasks like searching or crawling without mapping.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
A powerful web search tool that provides comprehensive, real-time results using Tavily's AI search engine. Returns relevant web content with customizable parameters for result count, content type, and domain filtering. Ideal for gathering current information, news, and detailed web content analysis.
| Name | Required | Description | Default |
|---|---|---|---|
| query | Yes | Search query | |
| search_depth | No | The depth of the search. It can be 'basic' or 'advanced' | basic |
| topic | No | The category of the search. This will determine which of our agents will be used for the search | general |
| days | No | The number of days back from the current date to include in the search results. This specifies the time frame of data to be retrieved. Please note that this feature is only available when using the 'news' search topic | |
| time_range | No | The time range back from the current date to include in the search results. This feature is available for both 'general' and 'news' search topics | |
| max_results | No | The maximum number of search results to return | |
| include_images | No | Include a list of query-related images in the response | |
| include_image_descriptions | No | Include a list of query-related images and their descriptions in the response | |
| include_raw_content | No | Include the cleaned and parsed HTML content of each search result | |
| include_domains | No | A list of domains to specifically include in the search results, if the user asks to search on specific sites set this to the domain of the site | |
| exclude_domains | No | List of domains to specifically exclude, if the user asks to exclude a domain set this to the domain of the site |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It mentions 'real-time results' and 'customizable parameters' which are useful, but doesn't cover important aspects like rate limits, authentication requirements, error conditions, or what the response structure looks like. The description provides basic behavioral context but leaves significant gaps.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is efficiently structured in two sentences that each earn their place. The first sentence establishes the core functionality and key features, while the second sentence provides usage context. There's zero wasted language or redundancy.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a complex tool with 11 parameters and no output schema, the description provides adequate but incomplete context. It covers the purpose and high-level capabilities well, but given the parameter complexity and absence of annotations, it should do more to explain behavioral aspects like response format, error handling, or performance characteristics.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
With 100% schema description coverage, the schema already documents all 11 parameters thoroughly. The description mentions 'customizable parameters for result count, content type, and domain filtering' which aligns with some parameters but doesn't add meaningful semantic context beyond what the schema provides. The baseline score of 3 is appropriate when the schema does the heavy lifting.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool performs 'web search' using 'Tavily's AI search engine' and returns 'relevant web content', which is a specific verb+resource combination. It distinguishes from sibling tools by focusing on search rather than crawling, extraction, or mapping operations mentioned in the sibling list.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides clear context for when to use this tool ('gathering current information, news, and detailed web content analysis'), but doesn't explicitly state when not to use it or mention alternatives like the sibling tools (tavily-crawl, tavily-extract, tavily-map). The guidance is helpful but lacks explicit exclusion criteria.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
tavily-crawltavily-extracttavily-maptavily-searchScored across 4 tools
The tools have mostly distinct purposes: crawling (tavily-crawl), extraction (tavily-extract), mapping (tavily-map), and searching (tavily-search). However, there is some potential overlap between tavily-crawl and tavily-map, as both involve exploring website structure, which could cause minor confusion for an agent.
All tool names follow a consistent 'tavily-' prefix with a descriptive action suffix (crawl, extract, map, search). This pattern is clear and predictable, making it easy for agents to understand and use the toolset.
With 4 tools, this server is well-scoped for web-related tasks. Each tool serves a specific function in the domain of web data retrieval and analysis, and none appear redundant or unnecessary given the server's purpose.
The toolset covers key web operations: crawling, extracting, mapping, and searching. Minor gaps might include advanced filtering or processing options, but the core workflows for web content analysis and research are well-covered, allowing agents to perform most common tasks effectively.