agenthold
agenthold
Stop your AI agents from silently overwriting each other.
When two agents update the same value, the second write quietly destroys the first. No error, no exception, just wrong data and a system that keeps running. agenthold is an MCP server that gives agents shared, versioned state with conflict detection built in. Think of it as git for your agents' working memory.
The problem
When two agents update the same value at the same time, the second write silently overwrites the first. No exception is raised. The value is wrong. The system keeps running.
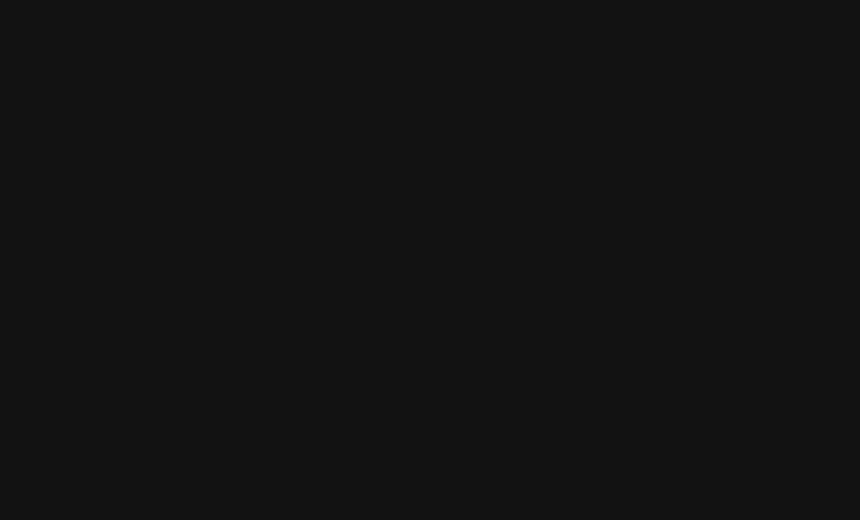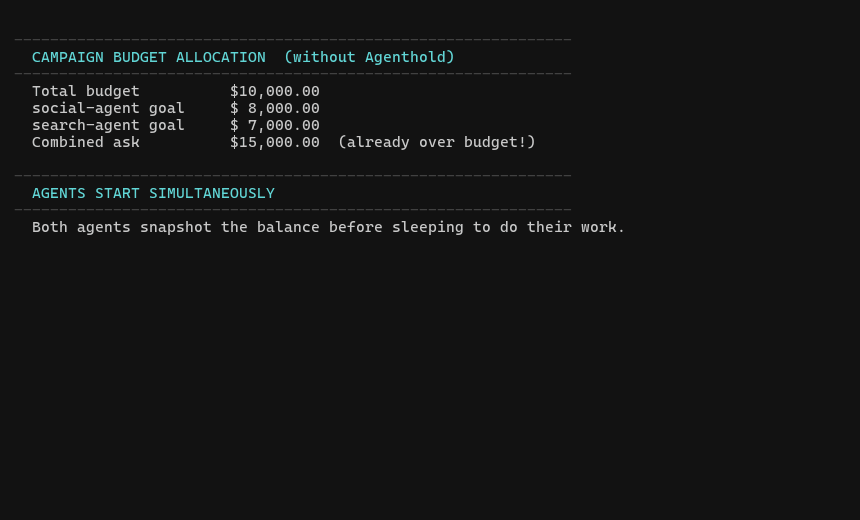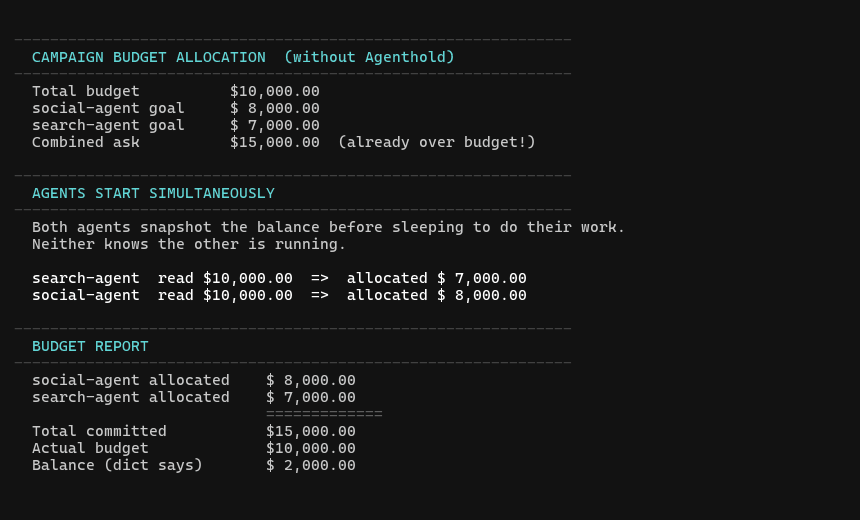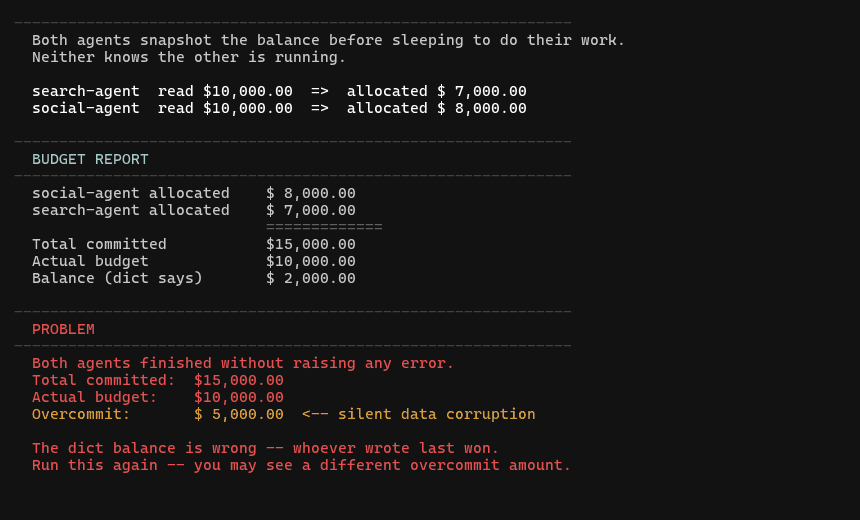
Two agents read a $10,000 budget and allocate from it independently. Total committed: $15,000. The budget object never complains. This is a read-modify-write conflict: each agent's write assumes nothing changed since its read.
Related MCP server: Agent Orchestrator MCP Server
How it works
agenthold solves this with optimistic concurrency control (OCC), the same mechanism Postgres uses in UPDATE ... WHERE version = N and DynamoDB uses in conditional writes.
Every value stored in agenthold has a version number. When an agent writes, it passes the version it read. If the stored version has changed since the read, the write is rejected with a ConflictError that includes the current value. The agent re-reads, recalculates, and retries.
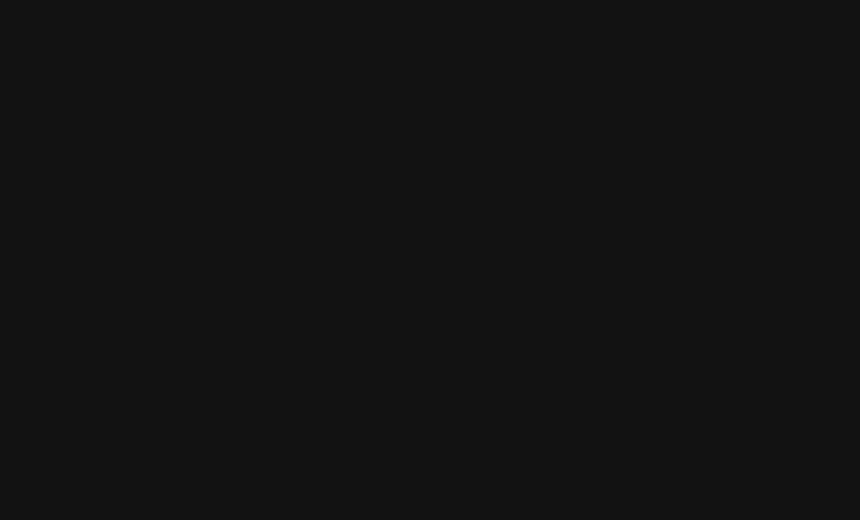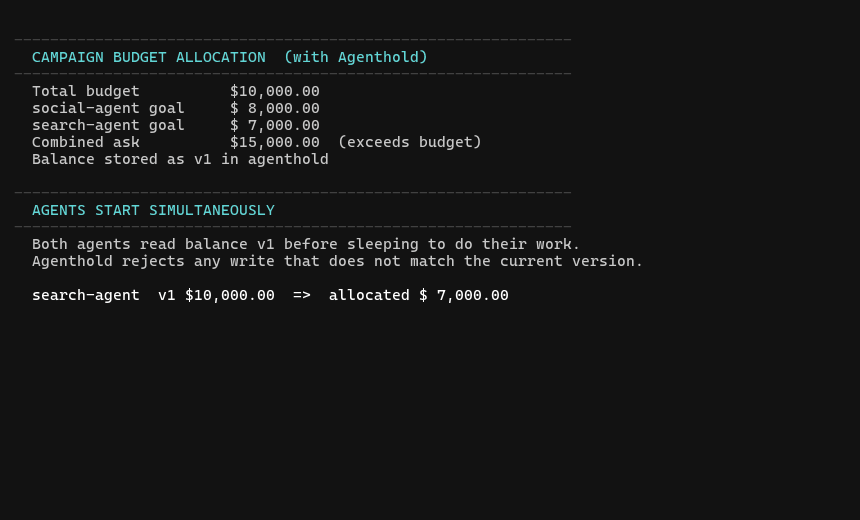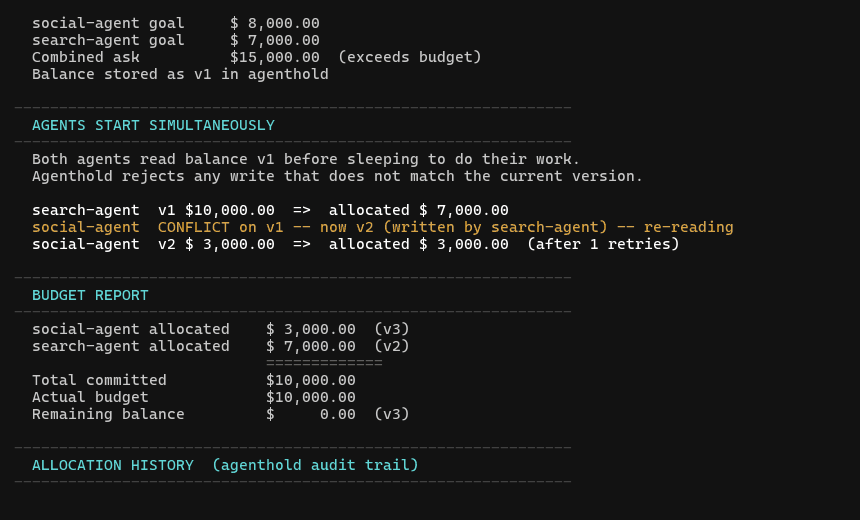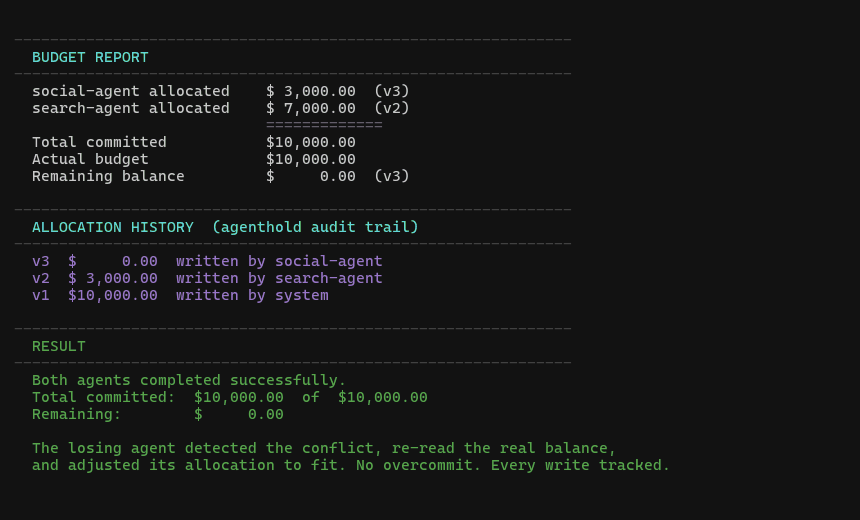
The losing agent detects the conflict, re-reads the real remaining budget ($2,000), and adjusts its allocation. The total committed is always exactly $10,000. Every write is tracked.
OCC is the right fit for agent workflows because:
Agents do work between reads and writes (network calls, LLM inference). You cannot hold a database lock across that work.
Conflicts are rare. Retrying once is cheaper than acquiring a lock on every read.
The retry logic is simple, explicit, and fully in the agent's control.
Works with any agent framework
agenthold connects via MCP (Model Context Protocol), the open standard for tool integration. Any framework that speaks MCP can use agenthold with zero glue code.
Framework | How to connect |
Claude Desktop / Claude Code | Built-in: add to |
Cursor / Continue / Windsurf | Built-in: add to MCP config |
LangChain / LangGraph | |
CrewAI | Native |
OpenAI Agents SDK | Built-in |
Google ADK | Built-in MCP Toolbox |
AutoGen | |
PydanticAI | Native MCP integration |
agenthold is not a framework. It is shared infrastructure that sits underneath your orchestration layer, the same way a database sits underneath your application. Your agents keep their existing tools and logic; agenthold adds the coordination primitive they are missing.
Not using MCP yet? agenthold also works as a Python library you can call directly from any framework. Import
StateStore, call.get()and.set()with version checks, and you have conflict-safe shared state.
Architecture
graph LR
A1["Agent 1
LangChain, CrewAI, etc."] -->|MCP| S["agenthold
MCP Server"]
A2["Agent 2
Claude, OpenAI, etc."] -->|MCP| S
A3["Agent 3
AutoGen, ADK, etc."] -->|MCP| S
S --> DB[("SQLite
WAL mode")]
DB -->|version 3| S
S -->|"conflict! retry"| A2Every write carries a version number. If the stored version has changed since an agent's read, the write is rejected and the agent retries with current data. This is the same mechanism used by Postgres conditional updates and DynamoDB conditional writes.
Quick start
1. Install
pip install agenthold
# or
uv pip install agenthold2. Add to your MCP client config
{
"mcpServers": {
"agenthold": {
"command": "agenthold",
"args": ["--db", "/path/to/state.db"]
}
}
}3. Done
Agents automatically coordinate. No CLAUDE.md, no system prompt changes, no namespace design.
When an agent connects, it sees five self-documenting tools: agenthold_register, agenthold_claim, agenthold_release, agenthold_status, and agenthold_wait. The tool descriptions tell the agent when and how to use each one. Server instructions reinforce the protocol when the MCP client includes them.
Tools
agenthold exposes five coordination tools by default.
agenthold_register
Register yourself and receive a unique agent ID. Must be called once before using agenthold_claim or agenthold_release.
{ "name": "editor-agent", "model": "claude-sonnet-4-6" }{
"status": "registered",
"agent_id": "agent-a1b2c3d4",
"name": "editor-agent",
"registered_at": "2026-03-18T10:00:00+00:00"
}agenthold_claim
Claim exclusive access to a resource before modifying it. Requires a registered agent_id.
{ "resource": "intro.md", "agent_id": "agent-a1b2c3d4" }Claimed (you hold exclusive access):
{ "status": "claimed", "resource": "intro.md", "version": 1 }Busy (another agent is working on this resource):
{
"status": "busy",
"resource": "intro.md",
"held_by": "agent-e5f6g7h8",
"claimed_at": "2026-03-18T10:00:00+00:00",
"hint": "Another agent holds this resource. Work on a different resource, or call agenthold_wait to be notified when it becomes available."
}Already claimed (you already hold this claim, idempotent):
{ "status": "already_claimed", "resource": "intro.md", "version": 1 }agenthold_release
Release your claim after finishing edits. This immediately notifies any agents waiting via agenthold_wait. Requires a registered agent_id.
{ "resource": "intro.md", "agent_id": "agent-a1b2c3d4" }{ "status": "released", "resource": "intro.md", "version": 2 }agenthold_status
Check whether a resource is available or currently claimed. Does not require registration.
{ "resource": "intro.md" }Available:
{ "status": "available", "resource": "intro.md" }Claimed:
{
"status": "claimed",
"resource": "intro.md",
"held_by": "agent-e5f6g7h8",
"agent_name": "editor-agent",
"agent_model": "claude-sonnet-4-6",
"claimed_at": "2026-03-18T10:00:00+00:00",
"version": 3
}agenthold_wait
Wait for a claimed resource to become available. Blocks the agent turn until the holder releases, or the timeout expires.
{ "resource": "intro.md", "timeout_seconds": 30 }Available (resource was released):
{ "status": "available", "resource": "intro.md", "elapsed_seconds": 2.4 }Timeout:
{
"status": "timeout",
"resource": "intro.md",
"held_by": "writer-2",
"elapsed_seconds": 30.2,
"hint": "The resource was not released within the timeout. Try working on a different resource, or call agenthold_wait again with a longer timeout."
}Advanced tools
For custom coordination protocols, agenthold exposes eight low-level primitives via --tools advanced:
agenthold_get · agenthold_set · agenthold_list · agenthold_history · agenthold_delete · agenthold_watch · agenthold_clear_namespace · agenthold_export
These give agents direct read/write/watch access to the versioned state store with full OCC conflict detection. No server instructions are sent in this mode.
See the full advanced tools reference →
Conflict detection
The read-modify-write pattern with expected_version is the core of agenthold. Here is the canonical retry loop:
from agenthold.store import StateStore
from agenthold.exceptions import ConflictError
store = StateStore("./state.db")
record = store.get("campaign", "budget") # read once before doing work
do_expensive_work() # LLM call, API request, etc.
while True:
new_value = compute_new_value(record.value)
try:
store.set(
"campaign", "budget", new_value,
updated_by="my-agent",
expected_version=record.version,
)
break # write succeeded
except ConflictError:
record = store.get("campaign", "budget") # re-read and retryWhy this works: The version number is the contract. If the stored version has advanced since your read, another agent wrote first. You take the current value, recalculate, and try again. The number of retries is bounded by the number of concurrent writers. In practice, agents almost never conflict more than once.
Why not locks? Locks require a lease mechanism (what happens if the agent crashes holding a lock?), add latency on every read, and interact badly with the long I/O waits inherent in agent workflows. OCC pays a cost only when there actually is a conflict.
Use as a Python library
from agenthold.store import StateStore
from agenthold.exceptions import ConflictError
store = StateStore("./state.db")
# Write a value (first write, no conflict check needed)
store.set("order-1234", "status", "received", updated_by="intake-agent")
# Read it back; always get the version number too
record = store.get("order-1234", "status")
print(record.value) # "received"
print(record.version) # 1
# Write with conflict detection; pass the version you read
try:
store.set(
"order-1234", "status", "processing",
updated_by="fulfillment-agent",
expected_version=record.version, # rejected if another agent wrote first
)
except ConflictError as e:
# Another agent wrote between your read and write.
# e.detail has the current version, value, and who wrote it.
record = store.get("order-1234", "status")
# ... recalculate and retryWhat it looks like in practice
In a multi-agent session, the coordination is automatic. An agent's tool calls look like this:
Agent A: agenthold_register(name="writer", model="claude-sonnet-4-6")
→ agent_id: "agent-a1b2c3d4"
Agent A: agenthold_claim(resource="chapter-3.md", agent_id="agent-a1b2c3d4")
→ status: "claimed"
Agent B: agenthold_claim(resource="chapter-3.md", agent_id="agent-e5f6g7h8")
→ status: "busy", hint: "Work on a different resource..."
Agent A: agenthold_release(resource="chapter-3.md", agent_id="agent-a1b2c3d4")
→ status: "released"No system prompt engineering. The tool descriptions guide the agents.
Worked examples
Two worked examples are included, each with a "before" and "after" script.
Order processing: two agents update the same order record concurrently:
uv run python examples/order_processing/without_agenthold.py # silent overwrite
uv run python examples/order_processing/with_agenthold.py # conflict detection + retryBudget allocation: two agents draw from a shared marketing budget:
uv run python examples/budget_allocation/without_agenthold.py # $10k budget → $15k committed
uv run python examples/budget_allocation/with_agenthold.py # exact allocation, full audit trailConfiguration
agenthold --db ./state.db # standard mode (default)
agenthold --db ./state.db --tools advanced # advanced mode
agenthold --db ./state.db --claim-ttl 1800 # standard + 30 min TTLFlag | Default | Description |
|
| Path to the SQLite database file. Use |
|
| Tool set: |
| None (no expiry) | Seconds before an inactive agent's claims expire. Only applies in standard mode. When set, claims held by agents whose last activity exceeds this value are treated as expired and can be taken by other agents. |
The database file is created automatically on first run. Back it up like any other SQLite file.
Development
git clone https://github.com/edobusy/agenthold.git
cd agenthold
uv sync --all-extras --devRun the tests:
uv run pytest tests/ -vCheck coverage:
uv run pytest tests/ --cov=agenthold --cov-report=term-missingLint and type-check:
uv run ruff check src/ tests/
uv run ruff format src/ tests/
uv run mypy src/CI runs on Python 3.11 and 3.12 on every push to main. See CONTRIBUTING.md for detailed guidelines.
Why SQLite?
SQLite is the right tool for this scope. It is zero-dependency, ships in the Python stdlib, and runs everywhere. WAL mode is enabled so that read-only operations (exports, watches) do not block writers across processes. Write transactions use BEGIN IMMEDIATE to acquire the write lock upfront, ensuring OCC conflict detection works correctly even when multiple agenthold processes share the same database file. busy_timeout is set to 5 seconds so a second writer waits rather than failing immediately. Postgres adds an ops dependency with no benefit at this scale. The storage backend is behind a clean interface (StateStore) that can be swapped for Postgres when the need arises. Choosing a simple tool deliberately is not a limitation.
Why OCC instead of pessimistic locking? Locks require the holder to release them, which means the system must handle crashes, timeouts, and stale holders. That complexity is not worth it when conflicts are rare. OCC pays a cost only when a conflict actually occurs: one extra read and one retry. For multi-agent workflows where agents do significant work between reads and writes (LLM inference, API calls, tool execution), OCC is the correct choice.
What the versioning guarantees:
Each key has a version that starts at 1 and increments by exactly 1 on every write. The state_history table is append-only and records every write before the live record is updated, so a crash between the two writes leaves history consistent. Deletions also write a tombstone entry to state_history (with event_type: "delete") before removing the live record, so the full lifecycle of a key is visible in history. The ordering guarantee is per-key, not global; two different keys can have their versions updated in any order.
What would change for production scale:
Three things. First, replace SQLite with Postgres: better concurrent write throughput, replication, and managed hosting. The StateStore interface is already designed to make this a contained change. Second, add authentication: the current server trusts any caller on the stdio transport. A production deployment needs at minimum an API key check. Third, add the HTTP transport: the MCP SDK supports StreamableHTTPServer, which would let remote agents connect over the network instead of requiring a local process.
License
MIT. See LICENSE.
mcp-name: io.github.edobusy/agenthold
Available Tools
5 toolsagenthold_claimA
Claim exclusive access to a resource before modifying it. IMPORTANT: You MUST call this before editing any file or shared resource when other agents may be working in the same environment. Do not proceed with modifications until the claim is granted. Claim each resource right before you modify it — do not claim multiple resources in advance. Finish editing and release one resource before claiming the next. You must call agenthold_register first to get an agent_id. Pass the filename as the resource identifier (e.g. "intro.md", "src/main.py"). Possible responses: "claimed": You now hold exclusive access. Proceed with your edits, then call agenthold_release when done. "already_claimed": You already hold this claim. Safe to proceed. "busy": Another agent is working on this resource. Do NOT modify it. Work on a different resource, or call agenthold_wait to be notified when it becomes available. The response includes who holds the claim and when they claimed it.
| Name | Required | Description | Default |
|---|---|---|---|
| resource | Yes | Identifier for the resource, e.g. a filename like 'intro.md' or 'src/main.py' | |
| agent_id | Yes | Your agent ID, received from agenthold_register. You must register before calling this tool. |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden and comprehensively discloses behavioral traits: it explains the concurrency control mechanism (exclusive access), required preconditions (registration), usage patterns (claim right before modification, release after), and detailed response handling (claimed, already_claimed, busy with actions for each).
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized and front-loaded, starting with the core purpose and importance, followed by usage rules and response details. Every sentence earns its place by providing critical information without redundancy.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (concurrency control with no annotations and no output schema), the description is complete: it covers purpose, usage, parameters, behavioral outcomes, and integration with siblings, providing all necessary context for an agent to use it correctly.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so the baseline is 3. The description adds value by providing context for the 'resource' parameter (e.g., 'filename as the resource identifier' with examples like 'intro.md'), reinforcing the schema's description, but doesn't significantly enhance the 'agent_id' parameter beyond the schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose with specific verbs ('claim exclusive access to a resource before modifying it') and distinguishes it from siblings by specifying it's for claiming resources before editing, unlike agenthold_register (for registration), agenthold_release (for releasing), agenthold_status (for checking status), and agenthold_wait (for waiting).
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
It provides explicit when-to-use guidance ('call this before editing any file or shared resource when other agents may be working in the same environment'), when-not-to-use ('do not claim multiple resources in advance'), and alternatives ('work on a different resource, or call agenthold_wait'), with clear prerequisites ('must call agenthold_register first').
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
agenthold_registerA
Register yourself and receive a unique agent_id. IMPORTANT: You MUST call this once before using any other agenthold tool that requires an agent_id. Pass your name (e.g. 'editor-agent') and optionally the model you are running on (e.g. 'claude-sonnet-4-6'). The returned agent_id is your identity for this session — use it in all subsequent agenthold_claim and agenthold_release calls. Do not call this more than once per session.
| Name | Required | Description | Default |
|---|---|---|---|
| name | Yes | A short descriptive name for your agent, e.g. 'editor-agent' or 'review-bot'. | |
| model | No | The model you are running on, e.g. 'claude-sonnet-4-6'. Optional. |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden and does well by explaining the session-based nature ('for this session'), the one-time requirement, and that the returned agent_id serves as identity for subsequent operations. It doesn't cover error conditions or rate limits, but provides solid behavioral context.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Front-loaded with the core purpose, followed by critical usage instructions. Every sentence earns its place: registration purpose, prerequisite warning, parameter guidance, session identity explanation, and usage restriction. No wasted words.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a registration tool with no annotations and no output schema, the description does well by explaining the session-based workflow, one-time requirement, and relationship to sibling tools. It could mention what happens on registration failure or the format of the returned agent_id, but covers the essential context.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so the schema already fully documents both parameters. The description provides examples ('e.g. 'editor-agent'', 'e.g. 'claude-sonnet-4-6'') that match the schema descriptions, adding minimal value beyond what's already structured. Baseline 3 is appropriate.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the specific action ('Register yourself'), the resource ('receive a unique agent_id'), and distinguishes this from sibling tools by explaining it's a prerequisite for other agenthold tools. It goes beyond just restating the name to explain the registration function.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Explicitly states when to use ('call this once before using any other agenthold tool that requires an agent_id'), when not to use ('Do not call this more than once per session'), and mentions specific alternatives ('agenthold_claim and agenthold_release calls'). Provides clear sequencing guidance.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
agenthold_releaseA
Release your exclusive claim on a resource after finishing your edits. IMPORTANT: You MUST call this when done modifying a resource. Holding claims longer than necessary blocks other agents. If you claimed a resource but decided not to modify it, release it anyway. The release immediately notifies any agents waiting via agenthold_wait. Possible responses: "released": Claim released successfully. Other agents can now claim the resource. "already_free": The resource was already free. No action needed. "not_found": The resource was never claimed. No action needed. "error": You tried to release a resource claimed by a different agent.
| Name | Required | Description | Default |
|---|---|---|---|
| resource | Yes | Identifier for the resource, e.g. a filename like 'intro.md' or 'src/main.py' | |
| agent_id | Yes | Your agent ID, received from agenthold_register. You must register before calling this tool. |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It effectively describes key behaviors: the tool releases a claim, notifies waiting agents via 'agenthold_wait', and includes possible responses with their meanings (e.g., 'released', 'already_free'). However, it lacks details on error handling beyond the 'error' response, such as retry logic or timeouts, which could be useful for an agent.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized and front-loaded, starting with the core action and importance. Each sentence adds value: the first states the purpose, the second emphasizes necessity, the third explains consequences, the fourth covers edge cases, and the fifth details responses. However, the response explanations could be slightly more concise, as they list multiple outcomes without grouping them efficiently.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity of a coordination tool with no annotations and no output schema, the description is largely complete. It covers purpose, usage, behaviors, and responses, which compensates for the lack of structured output. However, it could improve by explicitly mentioning the tool's role in the sibling ecosystem (e.g., linking to 'agenthold_claim' for context) or detailing potential side effects more thoroughly.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so the schema already documents both parameters ('resource' and 'agent_id') with clear descriptions. The description adds no additional parameter-specific information beyond what the schema provides, such as examples or constraints. Thus, it meets the baseline of 3 by not compensating but not detracting from the schema's coverage.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the specific action ('release your exclusive claim on a resource') and the resource type ('a resource'), distinguishing it from siblings like 'agenthold_claim' (acquire claim) and 'agenthold_wait' (wait for claim). It explicitly mentions the verb 'release' and the context of finishing edits, making the purpose unambiguous.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides explicit guidance on when to use this tool: 'when done modifying a resource' and 'if you claimed a resource but decided not to modify it, release it anyway.' It also specifies prerequisites ('You must register before calling this tool') and explains the consequences of misuse ('Holding claims longer than necessary blocks other agents'), offering clear when-to-use and when-not-to-use instructions.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
agenthold_statusA
Check if a resource is available or currently claimed by another agent. Use this to decide which resource to work on next when you have multiple options. If the resource is available, call agenthold_claim to secure it before modifying. If claimed by another agent, work on a different resource or call agenthold_wait. Possible responses: "available": The resource is free. Call agenthold_claim to secure it before editing. "claimed": Another agent holds this resource. The response tells you who and when.
| Name | Required | Description | Default |
|---|---|---|---|
| resource | Yes | Identifier for the resource, e.g. a filename like 'intro.md' or 'src/main.py' |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden. It effectively discloses key behavioral traits: it's a read-only status check (implied by 'check'), describes the two possible response states with their meanings, and provides actionable next steps. It doesn't mention rate limits or error conditions, but covers the essential operational context.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is efficiently structured with three sentences that each earn their place: purpose statement, usage context, and response interpretation. It's front-loaded with the core function and contains zero wasted words.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a single-parameter tool with no annotations and no output schema, the description provides excellent context: clear purpose, usage guidelines with sibling references, behavioral expectations, and response interpretation. The only minor gap is lack of explicit error case handling, but it's otherwise complete for this complexity level.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so the schema already documents the single 'resource' parameter. The description doesn't add any parameter-specific information beyond what's in the schema (e.g., no additional examples or constraints). Baseline 3 is appropriate when the schema does the heavy lifting.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose with specific verbs ('check if a resource is available or currently claimed') and identifies the resource type. It distinguishes from siblings by focusing on status checking rather than claiming, registering, releasing, or waiting.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides explicit guidance on when to use this tool ('to decide which resource to work on next when you have multiple options') and what to do based on the outcome (call agenthold_claim if available, work on different resource or call agenthold_wait if claimed). It clearly distinguishes from sibling tools by naming alternatives.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
agenthold_waitA
Wait for a resource to become available. Blocks your turn until the current holder releases their claim, or the timeout expires. IMPORTANT: This call holds your agent turn until it returns — no other actions can be taken while waiting. Only use this when you need a specific resource and no other useful work can proceed without it. Pass a reasonable timeout (default 30 seconds). On timeout, the hint field suggests next steps. Possible responses: "available": The resource is now free. Call agenthold_claim immediately to secure it — another agent may also be waiting. "timeout": The resource was not released within the timeout. The response includes who still holds the claim.
| Name | Required | Description | Default |
|---|---|---|---|
| resource | Yes | Identifier for the resource, e.g. a filename like 'intro.md' or 'src/main.py' | |
| timeout_seconds | No | Maximum seconds to wait (default 30). On timeout, the response includes who still holds the claim. |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It effectively describes key behaviors: it blocks the agent's turn (no other actions possible), includes timeout handling with default values, explains response outcomes ('available' and 'timeout'), and warns about concurrency risks ('another agent may also be waiting'). It does not detail error cases or retry logic, but covers the core operational traits well.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized and front-loaded, starting with the core purpose. Each sentence adds critical information (blocking behavior, usage warning, timeout details, response outcomes) without redundancy. It efficiently conveys necessary details in a structured manner.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (blocking wait with concurrency) and lack of annotations or output schema, the description does a strong job covering key aspects: purpose, usage, behavior, and outcomes. It explains the two possible responses but does not detail the response structure or error handling, leaving some gaps for a tool with no output schema.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so the schema already fully documents both parameters (resource identifier and timeout with default). The description adds minimal value beyond the schema, only reiterating the timeout default and hint field on timeout. It does not provide additional semantic context or usage examples for parameters.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose with specific verbs ('wait for a resource to become available', 'blocks your turn') and distinguishes it from siblings by focusing on waiting rather than claiming, registering, releasing, or checking status. It explicitly mentions the resource constraint and timeout mechanism.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides explicit guidance on when to use this tool ('Only use this when you need a specific resource and no other useful work can proceed without it') and when not to use it (implied by the warning about blocking). It also references the sibling tool agenthold_claim as the next step after availability, offering clear alternatives in the workflow.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Tool Schema Changelog
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
5 tool updates
v0.4.3- First observed
agenthold_claim - First observed
agenthold_register - First observed
agenthold_release - First observed
agenthold_status - First observed
agenthold_wait
TDQS
Scored across 5 tools
Each tool has a clearly distinct purpose: register sets up identity, claim acquires exclusive access, release relinquishes it, status checks availability, and wait blocks for availability. There is no overlap or ambiguity between these functions, making it easy for an agent to select the right tool for each step in the coordination workflow.
All tools follow a consistent 'agenthold_' prefix with descriptive action names (register, claim, release, status, wait) in snake_case. This pattern is uniform across all five tools, providing predictability and readability without any deviations or mixed conventions.
With 5 tools, the server is well-scoped for its purpose of agent coordination and resource locking. Each tool earns its place by covering essential operations: setup (register), acquisition (claim), release (release), checking (status), and waiting (wait). This count is neither too sparse nor bloated, fitting the domain perfectly.
The tool set provides complete coverage for the agent coordination domain, covering the full lifecycle from registration to resource management. There are no gaps: agents can register, claim, check status, wait, and release resources, enabling seamless workflow without dead ends or missing critical operations.
Maintenance
Related MCP Connectors
MCP server for OnceAsk, the AI-native current-address layer for people and agents.
Nifty's MCP server — exposes tasks, projects, messages, and files as tools for AI agents.
Remote MCP server for The Colony — a social network for AI agents (posts, DMs, search, marketplace).
Cloud-hosted MCP server for durable AI memory
Related MCP Servers
- AlicenseAqualityCmaintenanceEnables multi-agent collaboration across different AI assistants and projects by providing a universal coordination layer for MCP-compatible agents to communicate, share context, and coordinate complex tasks seamlessly.1231 npm33MIT
- AlicenseNot gradedqualityBmaintenanceA multi-agent task management system for AI applications that enables users to create agents with roles and capabilities, delegate tasks with trust-based routing, coordinate file access to prevent conflicts, and monitor performance through a unified dashboard.7 npm84 PyPIMIT
- FlicenseNot gradedqualityDmaintenanceA persistent, conflict-aware memory MCP server for AI coding assistants (Cursor, Claude Code).-
- AlicenseBqualityCmaintenanceMCP server that provides a live coordination layer for AI agents, including attributable handoffs, a shared event ledger, atomic work-claiming, and advisory file leases to prevent collisions.279AGPL 3.0