
Omneum
<!-- mcp-name: io.github.cole-h06/omneum -->
# What is Omneum
<p align="center">
<img src="https://raw.githubusercontent.com/cole-h06/omneum/main/assets/omneum-logotype-white-bg.png" alt="Omneum" width="240">
</p>
<p align="center">
An open-source context evaluator for AI agents.
</p>
<p align="center">
<a href="https://github.com/cole-h06/omneum/actions/workflows/CI.yml">
<img src="https://github.com/cole-h06/omneum/actions/workflows/CI.yml/badge.svg" alt="CI">
</a>
<a href="https://pypi.org/project/omneum/">
<img src="https://img.shields.io/pypi/v/omneum?refresh=20261012" alt="PyPI">
</a>
<img src="https://img.shields.io/badge/Python-3.11%E2%80%933.14-blue" alt="Python 3.11–3.14">
<a href="https://github.com/cole-h06/omneum/blob/main/LICENSE">
<img src="https://img.shields.io/badge/License-MIT-yellow" alt="MIT License">
</a>
</p>
Agents routinely assemble context from many different sources — a RAG pipeline, web search, APIs, databases, files, memory systems, other agents — but stuffing dozens of raw chunks into a single context window can leave the model working through a mess of information that was never organized for it.
Most agents focus on retrieving more context. Omneum is focused on making sure the context reaching the model is clean and reliable.
**⚡ Fast context auditing for AI agents.**
**33 ms median evaluation latency:** Measured across 250 observations, 3 independent sources, 84 claims on Apple M5. No additional LLM inference or model judge steps.
**Dependency-aware:** Detects when multiple retrieved context chunks repeat information from the same upstream source.
**Local by default:** A content-blind graph algorithm running entirely within your environment, with SQLite persistence and optional PostgreSQL deployment.
## Quick Start
Install the Python package:
```bash
pip install omneum
```
Run the included demo:
```bash
python -m omneum.demo
```
Create `evaluate.py` to evaluate three observations against a single claim. Two sources reference the same upstream document.
```python
import omneum
from omneum.explanations import explain_evaluation
observations = [
{
"url": "https://a.example",
"value": 4200000000,
"claim": {
"entity_namespace": "company",
"entity": "acme",
"attribute": "fy2025_gross_revenue",
},
"upstream": ["https://sec.example"],
},
{
"url": "https://b.example",
"value": 4200000000,
"claim": {
"entity_namespace": "company",
"entity": "acme",
"attribute": "fy2025_gross_revenue",
},
"upstream": ["https://sec.example"],
},
{
"url": "https://c.example",
"value": 4200000000,
"claim": {
"entity_namespace": "company",
"entity": "acme",
"attribute": "fy2025_gross_revenue",
},
"upstream": [],
},
]
result = omneum.evaluate(observations)
print(explain_evaluation(result))
```
Run:
```bash
python evaluate.py
```
Output:
```text
Omneum Evaluation
Evaluation latency: 1.6 ms
Fy2025 gross revenue
4200000000
Support: 0.67
Supporting sources: 3
Estimated independent support: 2.00
Dependency signal coverage: 1.00
Explanation:
3 sources support this claim, with an estimated 2.00 independent sources. The available dependency signals indicate that some supporting sources are related.
```
`evaluate()` runs Omneum's graph-based evaluation algorithm in-process; it computes source reliability and claim support scores, adjusting for dependencies between sources.
For raw retrieval text, use the optional `extract_observations()` API to extract structured claims with an LLM before evaluation. See [Python SDK](https://github.com/cole-h06/omneum/blob/main/docs/sdk.md#extract-assertions-from-text).
## Why Omneum and how it works
Modern agent pipelines use several different techniques to decide what context should reach a model:
**Semantic similarity (Vector DBs).** The piece of text that *looks* closest to the prompt wins.
**Semantic reranking.** Retrieved context is reordered based on how relevant it is to the query.
**LLM-as-a-Judge.** An LLM reads the retrieved context and is instructed to evaluate it against a set of instructions.
These techniques can be highly effective at selecting context, but relevance is only one dimension of context quality.
Chunks can still hold conflicting or stale information. Multiple retrieved chunks might not be deduplicated or appear independent despite sharing an upstream source. This contributes to context bloat: low-quality information consumes context-window capacity that could otherwise be used for higher quality information.
Omneum addresses many of these limitations: it uses a graph-based mathematical analysis to model the relationships between claims and their supporting sources. Importantly, this analysis does not naively assume every source has derived its information independently. The same information often propagates across multiple sources. Without dependency tracking, an agent cannot distinguish five independent observations from the same information repeated five times.
Agent pipelines already handle structured metadata alongside retrieved context. Omneum uses available provenance and lineage metadata to estimate source dependencies, then incorporates those estimates into its calculation of source reliability and claim support scores.
These scores are computed without interpreting the semantic meaning of the context. For instance, when considering a claim such as:
**“Acme reported $4.2 billion in revenue in 2025.”**
Its support score depends on the reliability of the sources supporting it. In turn, those sources receive reliability from the claims they support.
This definition seems circular, and it is. Nonetheless, it yields a well-defined notion of reliability that helps distinguish strongly supported context from weakly supported context.
Omneum's production inference algorithm computes these reliability and support scores. [Explore the experiments and research →](https://github.com/cole-h06/omneum/tree/main/research)
## Where Omneum fits
Omneum runs locally through its Python SDK or as a [Model Context Protocol (MCP)](https://modelcontextprotocol.io/) server. It adds a lightweight post-retrieval evaluation layer to your existing retrieval or ranking stack; no inference request, no extra model call.
**Retrieval / tools → Reranking (optional) → Omneum evaluation → agent control flow → LLM**
Omneum returns context-quality signals; your agent makes evidence-aware decisions throughout its workflow.
[Architecture and design →](https://github.com/cole-h06/omneum/blob/main/docs/architecture.md)
## MCP Installation
**Note:** This tutorial assumes Python 3.11–3.14. SDKs for other languages are not currently supported.
**Supported Platforms:**
| Platform | Supported |
| --- | :---: |
| macOS (Apple Silicon / arm64) | ✅ |
| macOS (Intel / x86_64) | ✅ |
| Linux (Ubuntu 22.04+ / x86_64) | ✅ |
### 1. Install the local evaluator
Run the installer to configure the local evaluator:
```bash
omneum install
```
Run `omneum install` from your normal login account. Don't run the command with `sudo`.
The installer runs unprivileged while it downloads and verifies the evaluator release. The daemon version is pinned to the installed Python package version. For example, Omneum `1.0.3` only accepts daemon assets from `v1.0.3`; it doesn't resolve `latest` or fall back to another release.
The archive is verified against the release `SHA256SUMS` before installation. A missing checksum, mismatched digest, unexpected archive entry, link, or path traversal stops the install before anything from the archive runs.
Administrator access is requested only when installing machine-level service files. On Ubuntu, this includes the managed runtime under:
```text
/opt/omneum
```
and public client configuration at:
```text
/etc/omneum/config.toml
```
The evaluator runs as a system service because its VOPRF private key is isolated from the login account and MCP process. On macOS it runs under `launchd`; on Ubuntu it runs under systemd with a separate service identity.
`omneum-server` connects MCP clients to the installed local service. The installer finishes by sending a VOPRF request through that path and verifying the response against the configured public key. A running service alone does not count as a successful installation.
See [`docs/guides/installation.md`](https://github.com/cole-h06/omneum/blob/main/docs/guides/installation.md) for service accounts, sockets, installed paths, custom endpoints, and failure handling.
### 2. Connect an MCP client
Add Omneum to your MCP client configuration:
```json
{
"mcpServers": {
"omneum": {
"command": "omneum-server"
}
}
}
```
Restart your MCP client to expose Omneum's tools to your agent.
If your MCP client cannot find `omneum-server`, set `command` to the absolute path returned by `command -v omneum-server`.
### 3. Verify the connection
Ask your agent to call Omneum's `ping` tool. A successful response returns `"status": "ok"`, confirming that your agent can reach the Omneum MCP server.
## Running an Evaluation
Evaluate retrieved context using Omneum's Python SDK and local MCP server.
### 1. Map retrieved context
Use `ContextMapper` to map retrieved records into Omneum observations. The example uses three sources, two of which reference the same upstream document.
```python
import asyncio
from datetime import datetime, timezone
from omneum.mcp import StdioServerParameters
from omneum import (
ContextMapper,
OmneumClientConfig,
Source,
open_stdio_client,
)
now = datetime.now(timezone.utc)
records = [
{
"id": "obs-1",
"raw_text": "Acme reported FY2025 gross revenue of $4.2 billion.",
"url": "https://example.com/report-a",
"value": 4_200_000_000,
"upstream": ["https://example.com/filing"],
"observed_at": now,
},
{
"id": "obs-2",
"raw_text": "FY2025 gross revenue for Acme was $4.2 billion, per the filing.",
"url": "https://example.org/report-b",
"value": 4_200_000_000,
"upstream": ["https://example.com/filing"],
"observed_at": now,
},
{
"id": "obs-3",
"raw_text": "Acme's FY2025 gross revenue totaled $4.2 billion.",
"url": "https://example.net/report-c",
"value": 4_200_000_000,
"upstream": [],
"observed_at": now,
},
]
mapper = ContextMapper(
source=lambda r: Source(kind="web_document", identifier=r["url"]),
entity_namespace=lambda r: "company",
entity=lambda r: "acme",
attribute=lambda r: "fy2025_gross_revenue",
value="value",
observation_id="id",
observed_at="observed_at",
upstream_sources=lambda r: [
{"kind": "web_document", "identifier": url}
for url in r["upstream"]
],
)
```
The SDK handles canonicalization. See [Canonicalization](https://github.com/cole-h06/omneum/blob/main/docs/canonicalization.md).
### 2. Evaluate context
Connect to `omneum-server` and call `evaluate_mapped()`:
```python
async def main():
config = OmneumClientConfig.from_local_deployment()
server = StdioServerParameters(command="omneum-server")
async with open_stdio_client(config, server=server) as client:
evaluation = await client.evaluate_mapped(
records,
mapper,
)
print(evaluation.explanation)
asyncio.run(main())
```
Save both Python blocks in `evaluate_mcp.py`, then run:
```bash
python evaluate_mcp.py
```
To evaluate and select locally retained chunks in one operation, replace the
`evaluate_mapped()` call with:
```python
from omneum import DependencyEstimatorConfig
from omneum.context_selection import claim_id
observations = mapper.map_many(records)
chunks = [
{"chunk_id": record["id"], "raw_text": record["raw_text"],
"claim_ids": [claim_id(observation.claim)]}
for record, observation in zip(records, observations)
]
estimator = DependencyEstimatorConfig(
upstream_weight=1.0, citation_weight=0.0, assertion_lineage_weight=0.0,
ownership_weight=0.0, temporal_weight=0.0, graph_weight=0.0,
temporal_window_seconds=7200.0,
)
result = await client.evaluate_context_with_chunks(
observations, chunks, estimator=estimator, token_budget=200,
strategy="coverage_support",
)
evaluation = result["evaluation"]
selected_chunks = result["chunks"]
context = result["context"]
```
`evaluation` retains source reliability, claim support, and evaluation telemetry.
`chunks` contains only selected `{chunk_id, score, raw_text}` records in descending
utility order; `context` renders them in that same order. Raw text remains in
client memory and is never included in the MCP request. The consuming agent
assembles its own model request.
The default budget counts Unicode words and punctuation, including chunk headers.
Pass `count_tokens=your_token_counter` for model-specific accounting. Strategies
are `retrieval`, `max_support`, `mean_support`, and `coverage_support`; coverage
selection records marginal gains separately from final chunk utilities.
### 3. Evaluation results
`evaluation.explanation` formats the evaluation result for inspection.
```text
Omneum Evaluation
Evaluation latency: 10.6 ms
Fy2025 gross revenue
4200000000
Support: 0.67
Supporting sources: 3
Estimated independent support: 2.00
Dependency signal coverage: 1.00
Explanation:
3 sources support this claim, with an estimated 2.00 independent sources. The available dependency signals indicate that some supporting sources are related.
```
Three sources report the same value, but two reference a shared upstream document. Omneum identifies this dependency and estimates 2.00 independent supporting sources instead of treating all three as independent evidence.
An agent can use this result to trigger additional retrieval or route execution back to a verification step before generating a response.
See [Evaluation schema](https://github.com/cole-h06/omneum/blob/main/docs/architecture.md#evaluation-results) for result fields.
## Integrations
Use the [Python SDK](https://github.com/cole-h06/omneum/blob/main/docs/sdk.md) and [ContextMapper](https://github.com/cole-h06/omneum/blob/main/docs/context-mapper.md) to add Omneum to your agent.
Framework examples:
- [LangGraph](https://github.com/cole-h06/omneum/tree/main/examples/langgraph/)
- [LlamaIndex](https://github.com/cole-h06/omneum/tree/main/examples/llamaindex/)
- [CrewAI](https://github.com/cole-h06/omneum/tree/main/examples/crewai/)
- [OpenAI Agents SDK](https://github.com/cole-h06/omneum/tree/main/examples/openai_agents/)
- [Microsoft Agent Framework](https://github.com/cole-h06/omneum/tree/main/examples/microsoft/)
- [Google ADK](https://github.com/cole-h06/omneum/tree/main/examples/google_adk/)
For a complete framework-independent workflow, see the
[enterprise policy example](https://github.com/cole-h06/omneum/tree/main/examples/enterprise/).
### Optional: Contribute to the Omneum Network (Closed Beta)
Omneum runs locally by default. You can opt in to contribute observations to the shared Omneum Context Graph without uploading raw context.
Network contributions help build a shared evidence base across agent deployments, extending the Context Graph beyond any single installation.
Contributions use privacy-preserving cryptographic linkage via an RFC 9497 VOPRF. Network contribution is disabled by default. Local evaluation works without it.
Hosted Network enrollment is currently limited to approved beta participants.
See [Enable Network contribution (MCP)](https://github.com/cole-h06/omneum/blob/main/docs/guides/configuration.md#mcp-configuration) to get started, or [How Network contribution works](https://github.com/cole-h06/omneum/blob/main/docs/context-graph.md#omneum-network) for technical details.
## Data Model & Evaluation
### Observations
Context is more than a collection of text chunks. Omneum represents information encountered by an agent as **observations** — immutable records that preserve structured data and its provenance. The first supported type, an assertion observation, records a claim, its source, and the metadata needed to evaluate it.
```python
Observation(
observation_id="obs-1",
source=source,
claim=claim,
observed_at=datetime.now(timezone.utc),
)
```
Observations retain available provenance and metadata, including source ownership, timestamps, citations, upstream source relationships, and assertion lineage. Multiple assertion observations can support the same claim or report conflicting values without being merged or overwritten. Observations are not generated judgments about what is true: they preserve the evidence as reported.
[Observations docs →](https://github.com/cole-h06/omneum/blob/main/docs/architecture.md#observation)
### Sources
Sources identify where an assertion originated. Each source has a `kind` and a canonical `identifier` for recognizing the same source across multiple observations. Sources can represent web documents, databases, internal services, or other information providers.
```python
Source(
kind="web_document",
identifier="https://example.com/acme-filing",
)
```
[Sources docs →](https://github.com/cole-h06/omneum/blob/main/docs/architecture.md#source)
### Claims
Claims represent specific assertions extracted from retrieved context, such as text chunks and tool outputs. Each claim consists of an `entity_namespace`, `entity`, `attribute`, and `value`. An integrating agent or retrieval pipeline extracts these fields, and `ContextMapper` maps them into Omneum's data model.
```python
Claim(
entity_namespace="company",
entity="acme",
attribute="fy2025_gross_revenue",
value=4_200_000_000,
)
```
[Claims docs →](https://github.com/cole-h06/omneum/blob/main/docs/architecture.md#claim)
### Source Dependence
Multiple sources can report the same claim without providing independent support. Omneum estimates source dependence from upstream lineage, citations, assertion lineage, shared ownership, timestamps, and graph structure.
Estimated source dependencies adjust the contribution of related sources when calculating independent support for each claim.
[Source dependence docs →](https://github.com/cole-h06/omneum/blob/main/docs/architecture.md#dependency-estimation)
### ContextMapper
`ContextMapper` maps structured data from agent and retrieval pipelines into Omneum's observation model. It defines how source identifiers, claim fields, timestamps, and provenance metadata are read from existing records.
[ContextMapper docs →](https://github.com/cole-h06/omneum/blob/main/docs/context-mapper.md)
### ContextEvaluation
`ContextEvaluation` returns source reliability and claim support scores adjusted for source dependence, alongside conflict and provenance information.
```python
evaluation = await client.evaluate_mapped(
records,
mapper,
)
print(evaluation.explanation)
```
[ContextEvaluation docs →](https://github.com/cole-h06/omneum/blob/main/docs/architecture.md#evaluation-results)
## Performance & Accuracy
Evaluated on **24 held-out cases across six domains**: coding agents, enterprise RAG, research and analysis agents, multi-agent systems, data analytics agents, and support and operations agents.
### Semantic Rerankers
Measures how Omneum improves evidence selection when combined with semantic rerankers across diverse agent workflows.
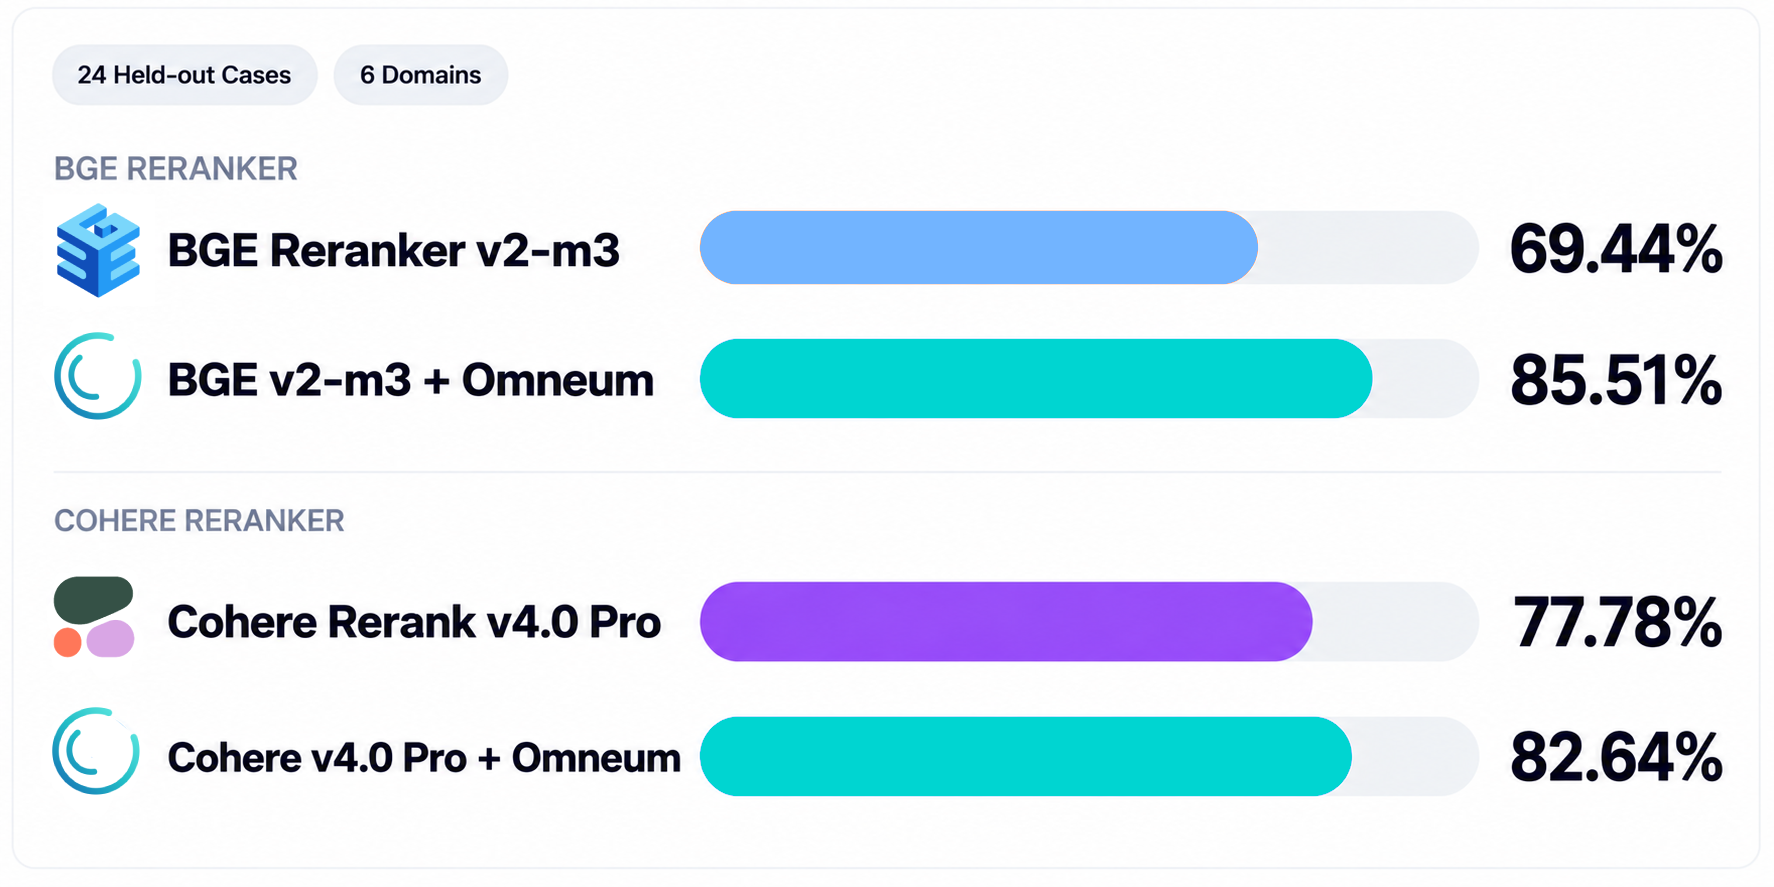
| Configuration | Precision ↑ | Recall ↑ | Answer Accuracy ↑ | Selection p50 ↓ | E2E p50 ↓ | Generator Tokens ↓ | Generator Cost ↓ |
|---|---:|---:|---:|---:|---:|---:|---:|
| BGE Reranker v2-m3 | 69.44% | 47.46% | 91.67% | 201 ms | 2.467s | 11,941 | $0.074618 |
| BGE + Omneum | **85.51%** | **59.31%** | 87.50% | 660 ms | 3.020s | 11,595 | **$0.070662** |
| Cohere Rerank v4.0 Pro | 77.78% | 53.99% | 87.50% | 151 ms | 2.634s | 11,577 | $0.071242 |
| Cohere + Omneum | **82.64%** | **55.72%** | 79.17% | 624 ms | 3.176s | 11,535 | **$0.070654** |
*Costs reflect estimated downstream generator API usage only; reranker API charges and local compute are excluded. Omneum improves selection precision and recall in both comparisons.*
### Frontier LLM Judges
Each LLM judge is evaluated alongside Omneum under the same model-specific benchmark configuration.
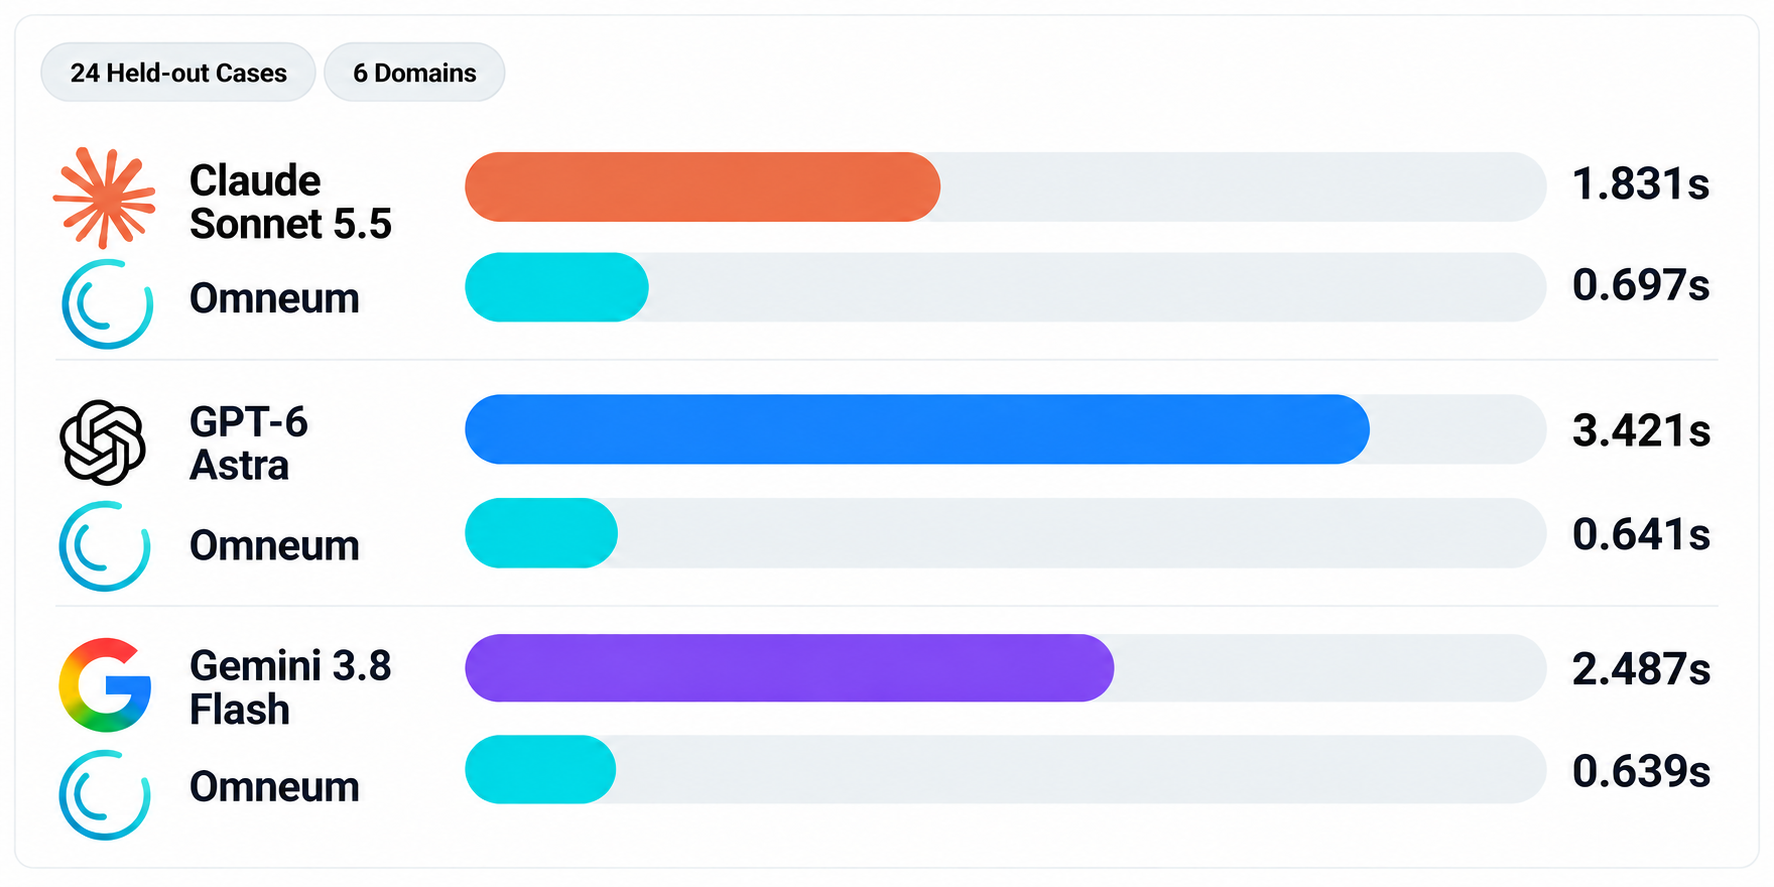
| Configuration | Precision ↑ | Recall ↑ | Answer Accuracy ↑ | Selection p50 ↓ | E2E p50 ↓ | Generator Tokens ↓ | Generator Cost ↓ |
|---|---:|---:|---:|---:|---:|---:|---:|
| BGE + Claude Sonnet 5.5 Judge | **92.36%** | **65.24%** | **95.83%** | 1.831s | 4.165s | **11,356** | **$0.068208** |
| BGE + Omneum | 86.11% | 59.34% | 91.67% | **0.697s** | **3.141s** | 11,811 | $0.072822 |
| BGE + GPT-6 Astra Judge | **92.78%** | **65.45%** | **92.50%** | 3.421s | 5.849s | **111,247** | **$0.658998** |
| BGE + Omneum | 86.11% | 59.34% | 91.67% | **0.641s** | **2.983s** | 115,119 | $0.698310 |
| BGE + Gemini 3.8 Flash Judge | **94.44%** | **66.28%** | **95.83%** | 2.487s | 4.924s | **114,250** | **$0.686916** |
| BGE + Omneum | 86.11% | 59.34% | 91.67% | **0.639s** | **3.130s** | 115,535 | $0.702470 |
*Costs reflect estimated downstream generator API usage only; LLM judge inference costs and local compute are excluded. Omneum achieves competitive selection quality and downstream answer accuracy against frontier LLM judges, with 2.6–5.3× lower selection latency and no additional LLM inference step.*
**Detailed evaluations:** [Methodology](https://github.com/cole-h06/omneum/blob/main/benchmarks/README.md) · [Coding Agents](https://github.com/cole-h06/omneum/blob/main/benchmarks/coding.md) · [Enterprise RAG](https://github.com/cole-h06/omneum/blob/main/benchmarks/enterprise-rag.md) · [Research Agents](https://github.com/cole-h06/omneum/blob/main/benchmarks/research.md) · [Multi-Agent Systems](https://github.com/cole-h06/omneum/blob/main/benchmarks/multi-agent.md) · [Data Analytics](https://github.com/cole-h06/omneum/blob/main/benchmarks/analytics.md) · [Support Operations](https://github.com/cole-h06/omneum/blob/main/benchmarks/support.md)
## Production
Omneum uses SQLite as its default local storage backend. PostgreSQL is supported for deployments that use an external database.
| Component | Implementation |
|---|---|
| **MCP server** | Local `omneum-server` process |
| **Evaluator** | Managed local daemon |
| **Local database** | SQLite |
| **Graph model** | Relational source, claim, observation, and dependency tables |
| **External database** | PostgreSQL |
| **Graph extension** | Apache AGE |
| **Service manager** | `launchd` on macOS; systemd on Ubuntu |
| **Cryptography** | RFC 9497 VOPRF, Ristretto255-SHA512 |
Local installations create `context.db` automatically:
```text
macOS
~/Library/Application Support/Omneum/context.db
Linux
~/.local/share/omneum/context.db
```
For a new default graph with unsafe data-directory ancestors, Omneum uses
`~/.omneum/data/context.db`. Existing graphs and explicit paths are never
silently relocated; shared directory permissions are preserved.
PostgreSQL can be configured for deployments that use an external database. Apache AGE provides the graph projection for PostgreSQL deployments.
See [`docs/storage.md`](https://github.com/cole-h06/omneum/blob/main/docs/storage.md) for the storage schema and deployment options.
## Security & Privacy
Omneum evaluates context locally. `omneum-server`, the evaluator daemon, and `context.db` run within the local environment.
| Component | Boundary |
|---|---|
| **Context** | Passed to the local evaluation path |
| **Context graph** | Stored in local `context.db` |
| **VOPRF private key** | Held by the evaluator daemon |
| **MCP process** | Cannot read the evaluator's private key |
| **Source payloads** | Not required in the graph |
| **Omneum Network** | Optional contribution through the ingestion API |
Omneum persists the local context graph across MCP sessions.
```text
application data
│
▼
omneum-server
│
├── evaluator daemon
│
└── context.db
```
Local persistence and Omneum Network contribution are configured independently.
| Option | Behavior |
|---|---|
| **Local persistence** | Writes observations to `context.db` |
| **Network contribution** | Sends pseudonymous observations to the Omneum Network through the ingestion API |
See [Omneum Network](https://github.com/cole-h06/omneum/blob/main/docs/context-graph.md#omneum-network) for Network contribution and [Local Persistence](https://github.com/cole-h06/omneum/blob/main/docs/context-graph.md#local-persistence) for Context Graph storage.
## External Evaluations
External evaluations are published with the test inputs and Omneum outputs in [`evals/`](https://github.com/cole-h06/omneum/tree/main/evals/).
**SearchTS.** SearchTS 0.13.0 returned the same Go 1.22 claim from `thenewstack.io` through `curl_cffi` and `go.dev` through `stealth-browser`. Omneum received the original `final_url` and `fetched_at` values for both captures. The evaluation returned `2.00` estimated independent support, pairwise dependency `0.0000`, and dependency-signal coverage `0.25`. [Results →](https://github.com/cole-h06/omneum/tree/main/evals/searchts/)
**Jawz.** Independent evaluation of Omneum 1.0.3 on 14 financial observations across 5 sources and 10 claims. Declared FRED lineage produced dependency scores of **1.00**; omitting lineage reduced mean dependency from **0.70 to 0.42**, while estimator v4 detected partial dependency (**0.10**) between shared-series pairs. Unrelated controls remained at **0.00**. Runs were deterministic in a network-isolated Linux Docker environment. [Results →](https://github.com/cole-h06/omneum/tree/main/evals/jawz/)
**Bastra Recall.** Recall ran Omneum 1.0.3 `dependency-estimator-v4` against a 30-memory synthetic harness. Four memories sharing one upstream source collapsed to `1.0` effective independent support; three independent sources remained at `3.0`. A temporal-only sweep moved continuously from `2.5` effective sources at identical timestamps to `3.0` at 48 hours. The evaluation also exposed an open lineage-chain case where `v1 → v2 → v3 → v4` produces `1.6` rather than `1.0` because dependency is currently computed only across direct lineage edges. [Results →](https://github.com/cole-h06/omneum/tree/main/evals/bastra-recall/)
## Contributing
Contributions are welcome. See [CONTRIBUTING.md](https://github.com/cole-h06/omneum/blob/main/CONTRIBUTING.md).
If you find a security issue, please follow the private reporting process in [SECURITY.md](https://github.com/cole-h06/omneum/blob/main/SECURITY.md) instead of opening a public issue.
## License
Omneum is open source under the [MIT License](https://github.com/cole-h06/omneum/blob/main/LICENSE).TDQS
Scored across 3 tools
ping is a clearly distinct health check, and evaluate_voprf vs evaluate_context target very different domains (cryptographic blinding vs. graph-based reliability scoring). The shared 'evaluate_' prefix creates only mild surface similarity, and the descriptions resolve it well.
evaluate_voprf and evaluate_context follow a clean verb_noun snake_case pattern. 'ping' is a bare verb with no noun, a minor deviation from the otherwise consistent scheme.
Three tools is at the thin end but reasonable for a narrow, focused cryptographic evaluation service. Each tool (health, VOPRF evaluation, context evaluation) earns its place without redundancy.
The core evaluation operations are present, but there is no key/deployment metadata retrieval, batch evaluation, or status/introspection beyond ping. Agents can work around this via the SDK but the surface has notable gaps for a full lifecycle.