Glama

Paper Pilot

Paper Pilot

您 AI 的研究副驾驶。

当您说“研究”时,您的 AI 只是在谷歌搜索。而 Paper Pilot 实际上会搜索真实的学术数据库,下载 PDF,从头到尾阅读,并为您提供带有引用的证据。

CI PyPI License: MIT Python 3.11+ GitHub stars


Demo

快速开始

uvx paper-pilot

就是这样。或者安装它:

pip install paper-pilot

Related MCP server: Research MCP

工作原理

graph LR
    A[Prompt] --> B[Search 6 databases]
    B --> C[Resolve OA PDFs]
    C --> D[Download & read]
    D --> E[Extract evidence]
    E --> F[Render figures]
    F --> G[Markdown report]
    G --> H[Zotero sync]

一个提示词。六个学术数据库。真实的 PDF。真实的引用。

Research retrieval-augmented generation, deep-read the top papers, and compare the methods.

您的 AI 将会:

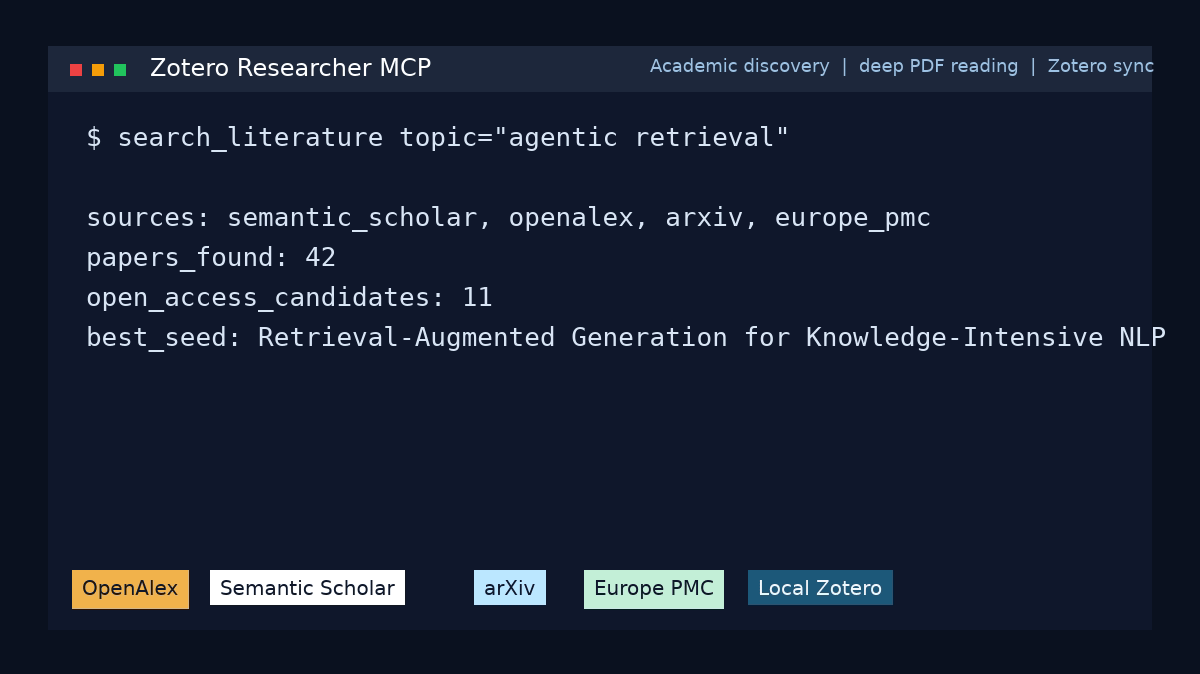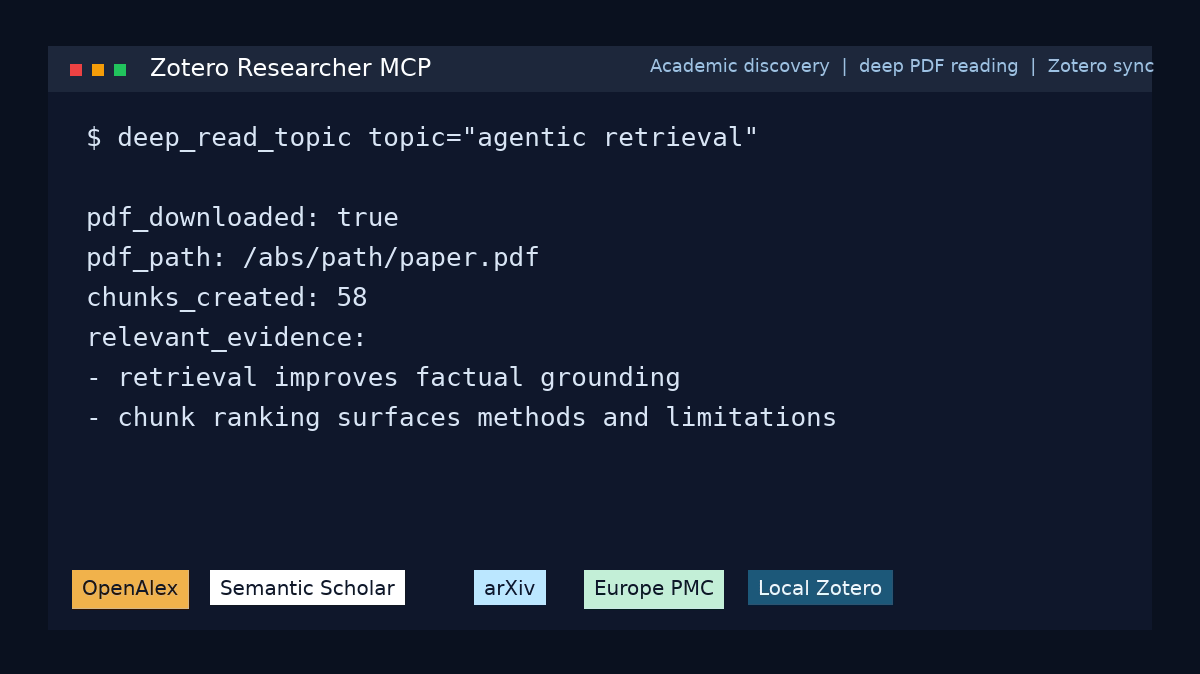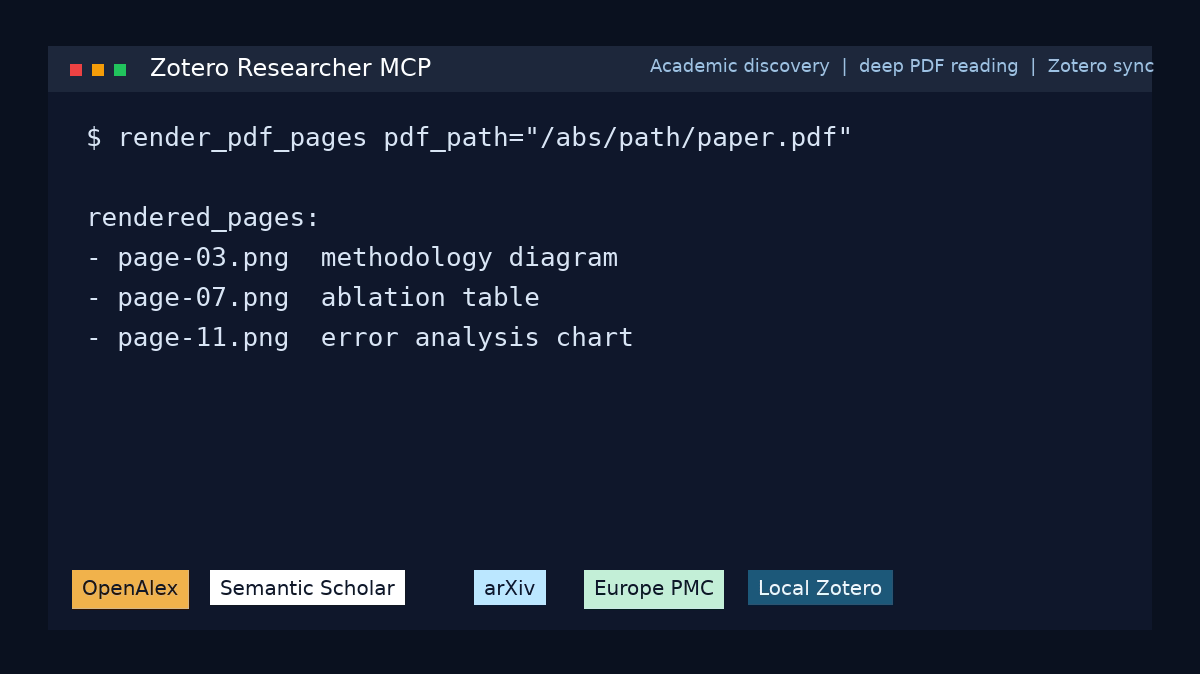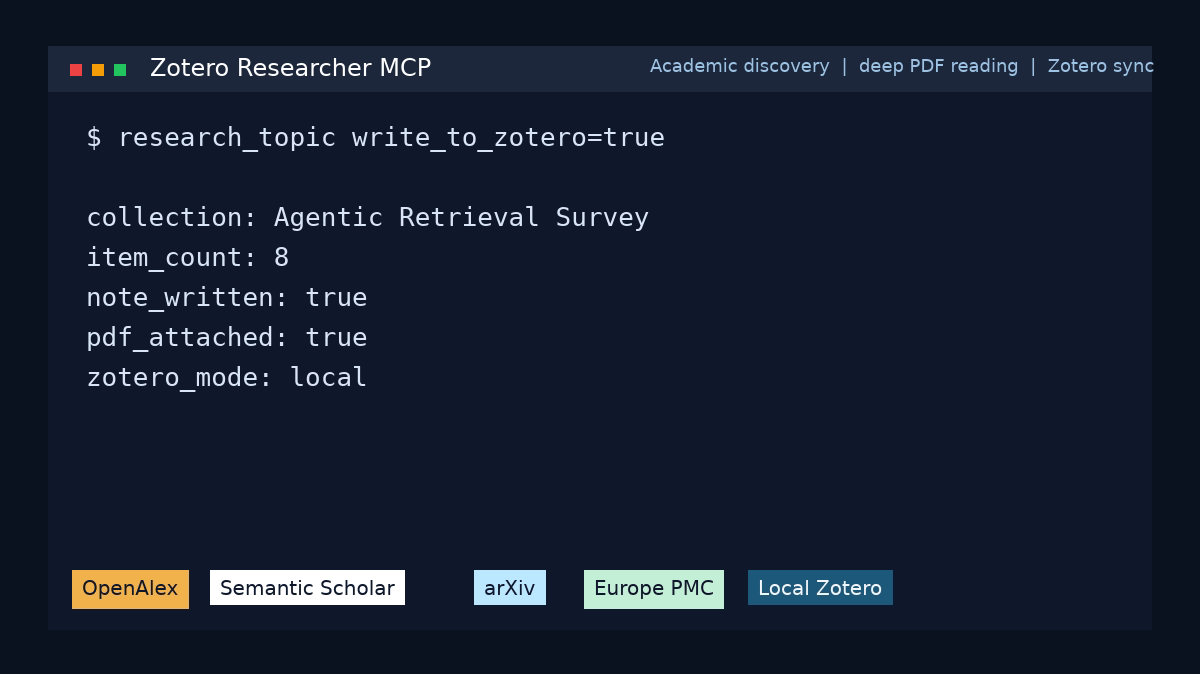
  1. 搜索 Semantic Scholar、OpenAlex、arXiv、Crossref 和 Europe PMC

  2. 查找开放获取的 PDF,而不仅仅是摘要

  3. 下载并从头到尾阅读它们

  4. 提取带有来源归属的证据片段

  5. 渲染特定页面,以便它能够“看到”图表

  6. 编写结构化的 Markdown 报告

  7. 将所有内容保存到您的 Zotero 库中


与替代方案对比

ChatGPT Deep Research

Gemini Deep Research

Perplexity Pro

Paper Pilot

阅读实际 PDF

网络摘要

网络摘要

网络摘要

全文提取

图表

仅文本

仅文本

仅文本

页面渲染为 PNG

您的库

锁定在他们的 UI 中

锁定在 Google 中

锁定在 Perplexity 中

同步到 Zotero

来源

通用网络搜索

通用网络搜索

网络搜索

6 个学术数据库

成本

$200/月

$20/月

$20/月

免费,MIT 许可

您的数据

他们的云端

他们的云端

他们的云端

您的机器

开源

否

否

否

是


MCP 客户端设置

Claude Desktop

添加到您的 claude_desktop_config.json:

{
  "mcpServers": {
    "paper-pilot": {
      "command": "uv",
      "args": ["--directory", "/path/to/paper-pilot", "run", "paper-pilot"],
      "env": {
        "OPENALEX_EMAIL": "you@example.com",
        "UNPAYWALL_EMAIL": "you@example.com",
        "ZOTERO_LOCAL": "true",
        "SCIHUB_ENABLED": "false"
      }
    }
  }
}

Claude Code

claude mcp add --scope user paper-pilot -- uv --directory /path/to/paper-pilot run paper-pilot

Codex

添加到 ~/.codex/config.toml:

[mcp_servers.paper_pilot]
command = "uv"
args = ["--directory", "/path/to/paper-pilot", "run", "paper-pilot"]

[mcp_servers.paper_pilot.env]
OPENALEX_EMAIL = "you@example.com"
ZOTERO_LOCAL = "true"

可流式传输的 HTTP 模式

paper-pilot --transport streamable-http --host 127.0.0.1 --port 8000

工具

工具

功能

research_topic

完整流程:搜索、下载、报告、Zotero 同步

deep_read_topic

上述所有功能 + 带证据片段的全文提取

render_pdf_pages

将 PDF 页面转换为 PNG 以检查图表

search_literature

精细的多源学术搜索

find_similar_papers

基于种子论文的相关工作扩展

inspect_open_access_pdf

OA 可用性检查和 PDF 预览

extract_local_pdf_text

从任何本地 PDF 提取文本

search_scihub

通过 DOI、标题或关键词搜索 Sci-Hub(需选择加入)

download_scihub_paper

通过 DOI 下载 Sci-Hub 论文(需选择加入)

search_libgen

补充影子图书馆搜索

healthcheck

验证所有连接是否正常


Sci-Hub 集成(需选择加入)

Sci-Hub 访问权限默认禁用。要选择加入:

SCIHUB_ENABLED=true

启用后,直接使用 search_scihub 和 download_scihub_paper,或者在 research_topic / deep_read_topic 中传递 include_scihub=True 以进行自动回退。

免责声明: Sci-Hub 集成仅用于教育和研究目的。用户需自行负责遵守适用法律和机构政策。


谁在使用它

博士生:不想花一周时间做文献综述。将其指向您的论文主题,即可获得带有真实引用且已存入 Zotero 的结构化对比报告。

研究实验室:想要每周扫描预印本并自动归档。按计划运行 research_topic,让您的团队库保持最新。

AI 构建者:需要他们的智能体使用真实的学术论文,而不是网络抓取的片段。


配置

OPENALEX_EMAIL=you@example.com        # Required for polite API access
UNPAYWALL_EMAIL=you@example.com       # Required for OA resolution
SEMANTIC_SCHOLAR_API_KEY=             # Optional, higher rate limits

# Local Zotero
ZOTERO_LOCAL=true
ZOTERO_LIBRARY_TYPE=user

# Web Zotero API (alternative)
ZOTERO_LIBRARY_ID=
ZOTERO_API_KEY=

# Sci-Hub (disabled by default)
SCIHUB_ENABLED=false

# Storage
PAPER_PILOT_DATA_DIR=./data

# Institutional networks
HTTP_PROXY=
HTTPS_PROXY=
SSL_CERT_FILE=

项目结构

src/paper_pilot/
  server.py              MCP tools and pipeline orchestration
  config.py              Environment and settings
  services/
    academic.py          Multi-source scholarly search
    open_access.py       OA resolution and PDF downloads
    scihub.py            Sci-Hub paper resolution (opt-in)
    deep_read.py         Full-text extraction and page rendering
    zotero.py            Local and web Zotero integration
    reporting.py         Markdown report generation
    libgen.py            Supplementary LibGen support

架构详情:docs/ARCHITECTURE.md


针对 AI 智能体


贡献

欢迎提交 PR。最有影响力的领域:

  • 新的学术来源适配器

  • 更好的 OA 解析逻辑

  • PDF 解析改进

  • 更多的 MCP 客户端配置

请参阅 CONTRIBUTING.md。


免责声明

此工具仅供学术研究和教育目的使用。开放获取功能仅使用合法的、公开可用的来源。Sci-Hub 和 LibGen 集成默认禁用,并作为可选功能提供。


许可

MIT。随心所欲地使用它。

如果这对您的研究有帮助,请给仓库加星并告诉您的同事。

Available Tools

16 tools
deep_read_topicA

Search, download, extract full text, and return evidence chunks plus local PDF paths for direct inspection.

By default the result is just [result_dict]: it carries every downloaded PDF's local path in pdf_paths (and in deep_reads[].pdf_path / downloads[].pdf_path), so a client can open the files when needed without any base64 in the payload. Opt in to inline content when your client benefits: render_top_pages=True appends the top paper's relevant pages as images (vision models); attach_top_pdf=True embeds its PDF as an application/pdf resource (Claude API style). include_scihub=True adds a Sci-Hub fallback; write_graph=True also renders a citation graph (path in graph_path).

Inputs: topic (required), research_question, limit_per_source, related_limit, +21 more.

download_scihub_paperA

Download a paper PDF via Sci-Hub using its DOI. Returns local path and text preview. Requires SCIHUB_ENABLED=true.

Inputs: doi (required), topic_hint.

extract_local_pdf_textC

Extract full text from a local PDF, save a text sidecar, and return top matching chunks.

Inputs: pdf_path (required), title_hint, research_question, chunk_size_chars, +2 more.

find_similar_papersC

Find similar papers starting from a seed paper title or DOI.

Inputs: seed_title (required), seed_doi, limit, open_access_only.

get_pdf_page_textA

Return the exact extracted text of specific PDF pages (1-based) as plain JSON.

For fine-grained lookups over the wire (a single reference entry, a table, a footnote) without base64 and without filesystem/shell access. Use deep_read_topic first to get the pdf_path and the page mapping (deep_reads[*].chunk_manifest_path), then fetch the exact pages you need here.

Inputs: pdf_path (required), page_numbers (required).

graph_topicB

Search a topic and render an interactive citation/relatedness graph as a self-contained HTML file.

Nodes are papers (size scales with citation count, color by year); edges connect papers that share keywords or a venue, plus similarity links radiating from the top result. Returns the local HTML path. Open it in a browser to explore or screenshot the landscape.

Inputs: topic (required), limit_per_source, related_limit, from_year, +2 more.

healthcheckA

Return current configuration summary and enabled integrations.

Inputs: no named parameters.

inspect_libgen_itemC

Resolve LibGen mirror links, download a PDF when possible, and return a preview.

Inputs: mirror_1 (required), title (required), author, year, +3 more.

inspect_open_access_pdfC

Download an open-access PDF and return a local preview.

Inputs: pdf_url (required), filename_hint.

list_zotero_collectionsC

List Zotero collections visible to the configured web or local Zotero integration.

Inputs: query.

read_pdf_documentA

Return a downloaded PDF's local path so a client can open the file when it needs it.

By default nothing is base64-inlined: the result is [metadata, resource_link] where metadata carries pdf_path / doc_id / page_count / size_bytes. The PDF stays on disk; clients that read local files (e.g. Claude Code) or fetch the paperpilot://pdf/{doc_id} resource use it without payload bloat. Set embed_base64=True to inline the PDF as an application/pdf resource for clients that read PDFs that way (Claude API integrations), bounded by max_mb / max_pages.

Inputs: pdf_path (required), embed_base64, max_pages, max_mb.

render_pdf_pagesA

Render selected PDF pages to PNG and return them as images the model can see.

The result is [metadata_dict, image, image, ...]: the dict keeps pdf_path and images (local PNG paths) for path-based clients, and the trailing image blocks let a vision-capable model inspect figures, tables, and layout directly. Set include_images=False to return only the paths.

Inputs: pdf_path (required), page_numbers (required), scale, include_images.

research_topicC

Run the end-to-end research workflow and optionally sync the result into Zotero. Set include_scihub=True to use Sci-Hub as a fallback for papers without open-access PDFs. Set write_graph=True to also render an interactive citation graph HTML (path returned as graph_path).

Inputs: topic (required), limit_per_source, related_limit, download_top_n, +14 more.

search_libgenC

Search LibGen mirrors for supplemental research material.

Inputs: query (required), search_type, limit, allowed_extensions.

search_literatureC

Search Semantic Scholar, OpenAlex, Europe PMC, arXiv, Crossref, and DOAJ for a topic.

Inputs: topic (required), limit_per_source, from_year, to_year, +1 more.

search_scihubB

Search Sci-Hub for papers by DOI, title, or keyword. Use search_type='doi', 'title', or 'keyword'. Requires SCIHUB_ENABLED=true.

Inputs: query (required), search_type, limit, check_availability.

Tool Schema Changelog

Recent tool additions, removals, and schema changes observed during successful MCP inspections.

Loading tool schema changelog…

    TDQS

    B3.4/5.0

    Scored across 16 tools

    Disambiguation4/5

    Most tools have distinct purposes, but there is some overlap between deep_read_topic and research_topic, and between various search/download tools. Descriptions help differentiate them.

    Naming Consistency5/5

    All tool names follow a consistent verb_noun pattern in snake_case, except for 'healthcheck' which is a single word but still clear. Overall very consistent.

    Tool Count5/5

    16 tools is well-scoped for a research assistant server covering search, download, extraction, visualization, and Zotero integration. No extraneous tools.

    Completeness4/5

    Covers major workflows (search, download, extraction, graphing, Zotero) but lacks tools for managing Zotero items beyond collections or batch operations. Minor gaps.

    Maintenance

    ActivityMaintained
    ResponsivenessNo recent community issues

    Related MCP Connectors

    Related MCP Servers

    • F
      license
      Not graded
      quality
      D
      maintenance
      Enables AI assistants to search across multiple academic databases (PubMed, arXiv, bioRxiv, medRxiv, Semantic Scholar) through a unified interface. Supports advanced filtering, metadata retrieval, PDF downloads, and comprehensive research workflows with citation analysis.
      5
      -
    • A
      license
      Not graded
      quality
      D
      maintenance
      Enables LLMs to search, analyze, and summarize academic research papers in real-time from arXiv, Semantic Scholar, and PubMed. Provides automatic deduplication, citation analysis, and BibTeX generation across multiple research databases.
      22 npm
      MIT
    • A
      license
      B
      quality
      B
      maintenance
      AI-operable research workspace integrating Zotero, Obsidian, and NotebookLM. Search papers (arXiv/Semantic Scholar/PubMed/CrossRef), ingest into Zotero, sync per-paper notes to Obsidian, verify NotebookLM briefs. All three external tools optional.
      76
      117 PyPI
      70
      MIT