
F
licenseNot graded
qualityF
maintenanceThis server implements the Model Context Protocol to facilitate meaningful interaction and understanding development between humans and AI through structured tools and progressive interaction patterns.
57
-
The ZenML MCP Server provides a standardized interface for AI assistants to interact with ZenML's MLOps platform, offering comprehensive read and limited write access across ML pipelines, models, infrastructure, and deployments.
Pipeline Management
List/get pipelines, runs, and individual steps
Trigger new pipeline runs using snapshots (preferred) or deprecated run templates
Retrieve step logs and step source code for debugging
Snapshots & Deployments
List/get snapshots (frozen pipeline configurations) with rich filters (runnable, deployable, tag, pipeline)
List/get deployments with runtime status, URLs, and logs (up to 1000 lines)
Infrastructure & Stack Management
List/get stacks, stack components, component flavors, and service connectors (cloud authentication)
Analyze stack component usage
Models & Model Registry
List/get models and versioned model artifacts with stage and tag filters
List/get model serving endpoints/services
Scheduling & Automation
List/get pipeline schedules with filters (active, pipeline, orchestrator)
Artifacts & Secrets
List artifact metadata (not raw data) and secret names (not values)
User & Organization Management
Get the active user, look up users, list all users
Get/list projects and the active project
Tags & Builds
List/get tags (cross-cutting metadata labels) and pipeline builds (image/code/stack checksums)
Analysis Tools
Analyze recent pipeline runs and get the N most recent runs
Interactive Apps (Experimental, requires Streamable HTTP transport)
Open an interactive pipeline runs dashboard or a 30-day run activity bar chart
Deprecated Features
Access run templates (get_run_template, list_run_templates) with migration guidance to snapshots
Click on "Deploy Server".
Wait a few minutes for the server to deploy. Once ready, it will show a "Started" state.
In the chat, type @ followed by the MCP server name and your instructions, e.g., "@ZenML MCP Server list my recent pipeline runs"
That's it! The server will respond to your query, and you can continue using it as needed.
Here is a step-by-step guide with screenshots.
This project implements a Model Context Protocol (MCP) server for interacting with the ZenML API.
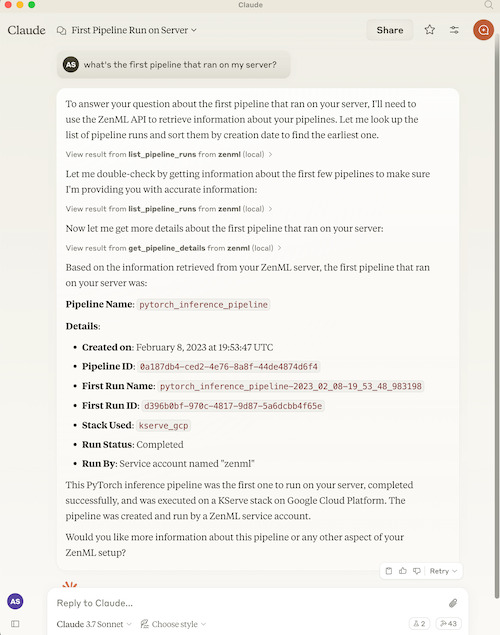
The Model Context Protocol (MCP) is an open protocol that standardizes how applications provide context to Large Language Models (LLMs). It acts like a "USB-C port for AI applications" - providing a standardized way to connect AI models to different data sources and tools.
MCP follows a client-server architecture where:
MCP Hosts: Programs like Claude Desktop or IDEs that want to access data through MCP
MCP Clients: Protocol clients that maintain 1:1 connections with servers
MCP Servers: Lightweight programs that expose specific capabilities through the standardized protocol
Local Data Sources: Your computer's files, databases, and services that MCP servers can securely access
Remote Services: External systems available over the internet that MCP servers can connect to
Related MCP server: MCP Server for continue.dev
ZenML is an open-source platform for building and managing ML and AI pipelines. It provides a unified interface for managing data, models, and experiments.
For more information, see the ZenML website and our documentation.
The server provides MCP tools to access core read functionality from the ZenML server, providing a way to get live information about:
Users - user accounts and permissions
Stacks - infrastructure configurations
Stack Components - individual stack building blocks
Flavors - available component types
Service Connectors - cloud authentication
Pipelines - pipeline definitions
Pipeline Runs - execution history and status
Pipeline Steps - individual step details, code, and logs
Schedules - automated run schedules
Artifacts - metadata about data artifacts (not the data itself)
Snapshots - frozen pipeline configurations (the "what to run/serve" artifact)
Deployments - runtime serving instances with status, URL, and logs
Services - model serving endpoints
Projects - organizational containers for ZenML resources
Tags - cross-cutting metadata labels for discovery
Builds - pipeline build artifacts with image and code info
Models - ML model registry entries
Model Versions - versioned model artifacts
Pipeline run templates → use Snapshots instead (see Migration Guide)
The server also allows you to trigger new pipeline runs using snapshots (preferred) or run templates (deprecated).
Note: We're continuously improving this integration based on user feedback. Please join our Slack community to share your experience and help us make it even better!
The MCP server exposes the following tools, grouped by category:
Tool | Description |
| Get a frozen pipeline configuration by name/ID |
| List snapshots with filters (runnable, deployable, deployed, tag) |
| Get a deployment's runtime status and URL |
| List deployments with filters (status, pipeline, tag) |
| Get bounded logs from a deployment (tail=100 default, max 1000) |
| Trigger a pipeline run (prefer |
Tool | Description |
| Get the currently active project |
| Get project details by name/ID |
| List all projects |
| Get tag details (exclusive, colors) |
| List tags with filters (resource_type) |
| Get build details (image, code embedding) |
| List builds with filters (is_local, contains_code) |
Tool | Description |
| User management |
| Stack configurations |
| Stack components |
| Component flavors |
| Cloud connectors |
| Pipeline runs |
| Step details |
| Step logs and source code |
| Pipeline definitions |
| Schedules |
| Artifact metadata |
| Secret names (not values) |
| Model services |
| Model registry |
| Model versions |
Tool | Description |
| Open interactive pipeline runs dashboard (MCP App) |
| Open 30-day run activity bar chart (MCP App) |
Tool | Description |
| Analyze stack component usage |
| Analyze recent pipeline runs |
| Get N most recent runs |
Tool | Description |
| Diagnose server setup (env vars, SDK, connectivity, auth). Works even when misconfigured. |
Tool | Replacement |
| Use |
| Use |
| Use |
Why the change? ZenML evolved its "runnable pipeline artifact" concept. Run Templates are now deprecated wrappers that internally just point to Snapshots. New code should use Snapshots directly.
Old Pattern (Templates) | New Pattern (Snapshots) |
|
|
|
|
|
|
1. Discover project context:
   → get_active_project()

2. Find runnable snapshots:
   → list_snapshots(runnable=True, named_only=True)

3. Trigger a run:
   → trigger_pipeline(pipeline_name_or_id="my-pipeline", snapshot_name_or_id="my-snapshot")

4. Check deployments:
   → list_deployments(status="running")
   → get_deployment_logs(name_id_or_prefix="my-deployment", tail=100)
Note: get_deployment_logs returns bounded output (default 100 lines, max 1000, capped at 100KB) and requires the appropriate deployer integration to be installed.
The easiest way to set up the ZenML MCP Server is through your ZenML dashboard's MCP Settings page.
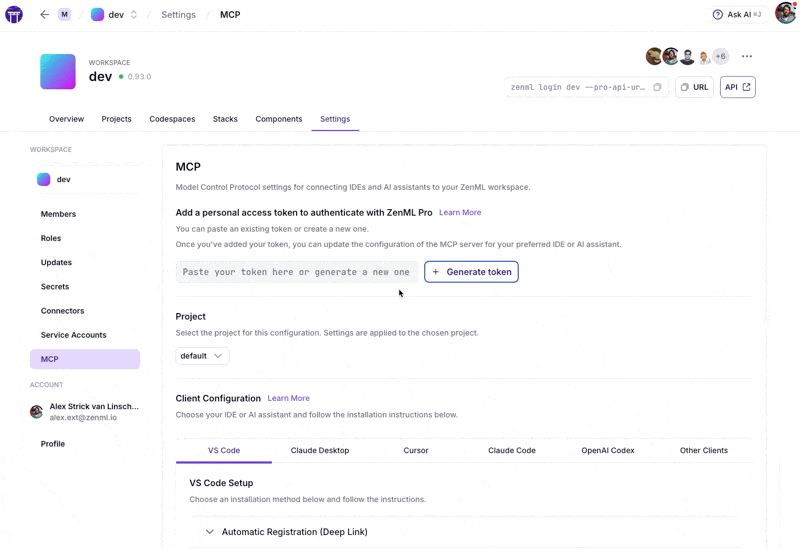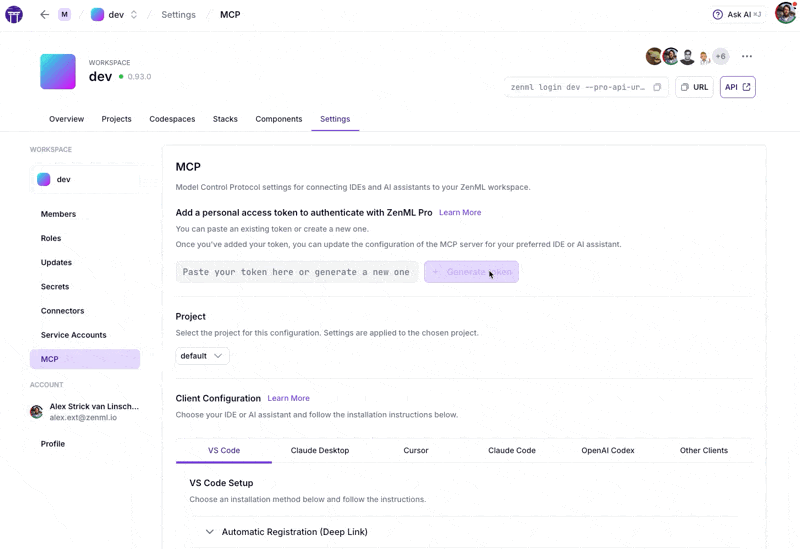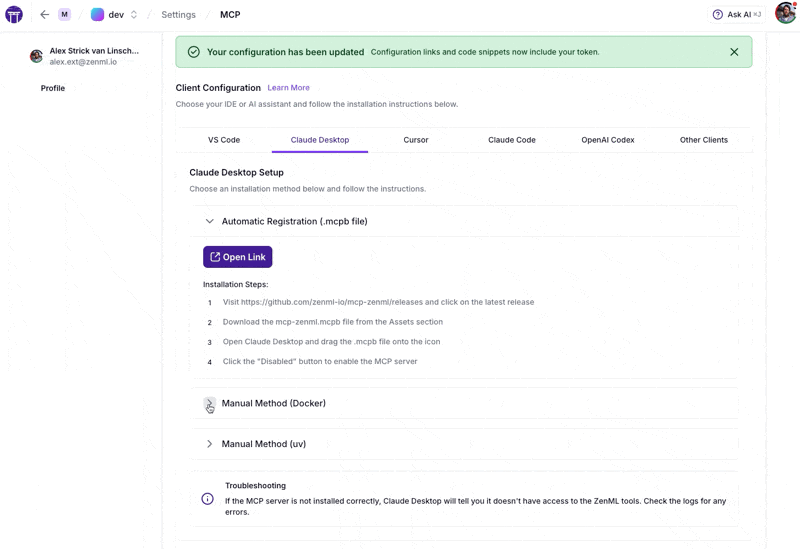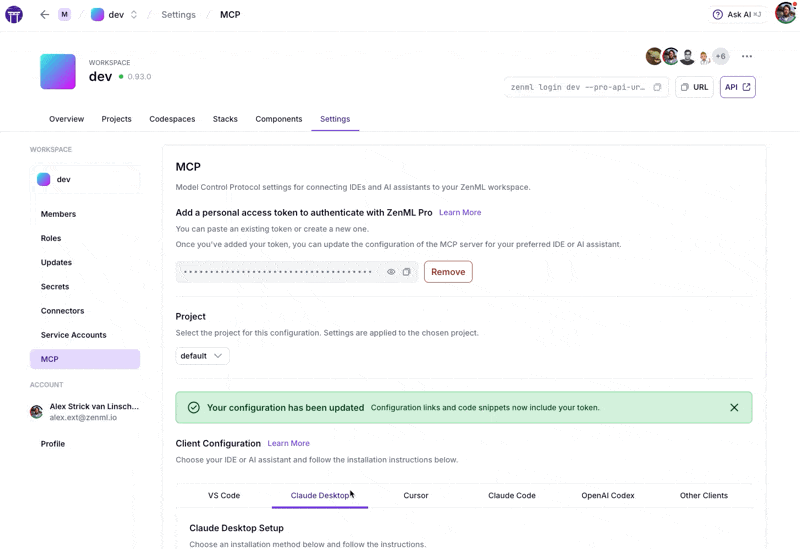
Navigate to Settings → MCP in your ZenML dashboard to get:
Pre-configured snippets for your specific server URL and credentials
One-click installation via deep links for supported IDEs
Copy-paste configurations for VS Code, Claude Desktop, Cursor, Claude Code, OpenAI Codex, and more
Docker and uv options based on your preference
The MCP Settings page lets you generate a Personal Access Token (PAT) with a single click. The token is automatically included in all generated configuration snippets.
First create a service account token via Settings → Service Accounts
Paste the token into the MCP Settings page
Copy the generated configuration for your IDE
Prefer manual setup? See the detailed instructions below.
What are MCP Apps? MCP Apps are interactive HTML UIs that MCP servers can serve directly into AI clients. They render in sandboxed iframes and can call server tools bidirectionally. See the official announcement for full details.
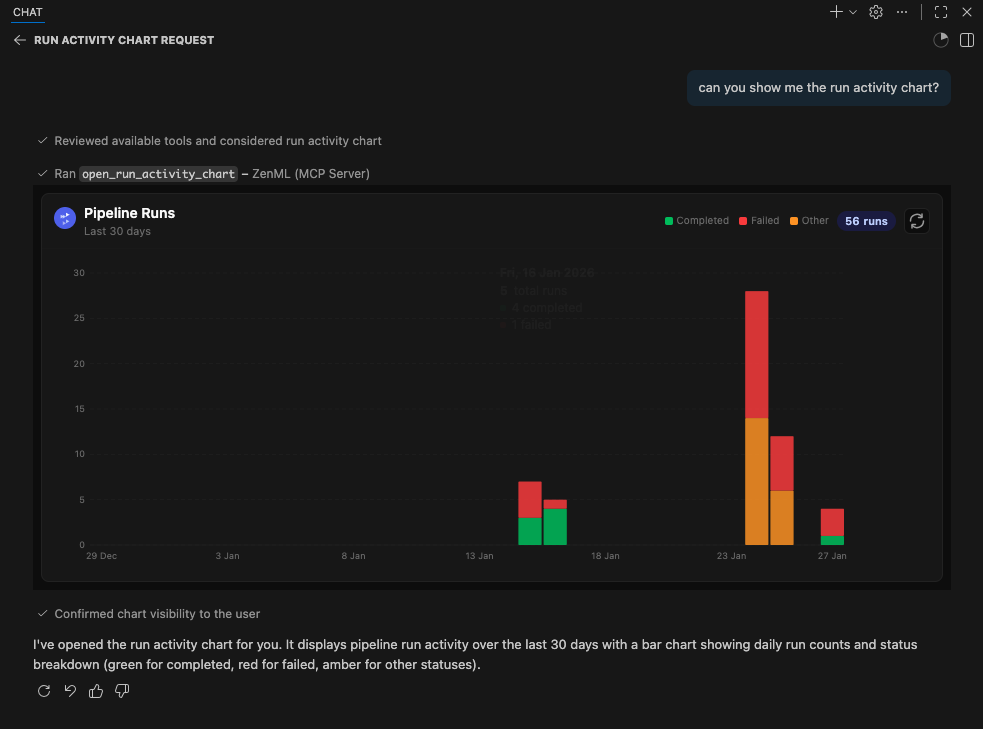
This server includes two experimental MCP Apps:
App | Tool | Description |
Pipeline Runs Dashboard |
| Interactive table of recent pipeline runs with status, step details, and logs |
Run Activity Chart |
| Bar chart of pipeline run activity over the last 30 days with status breakdown |
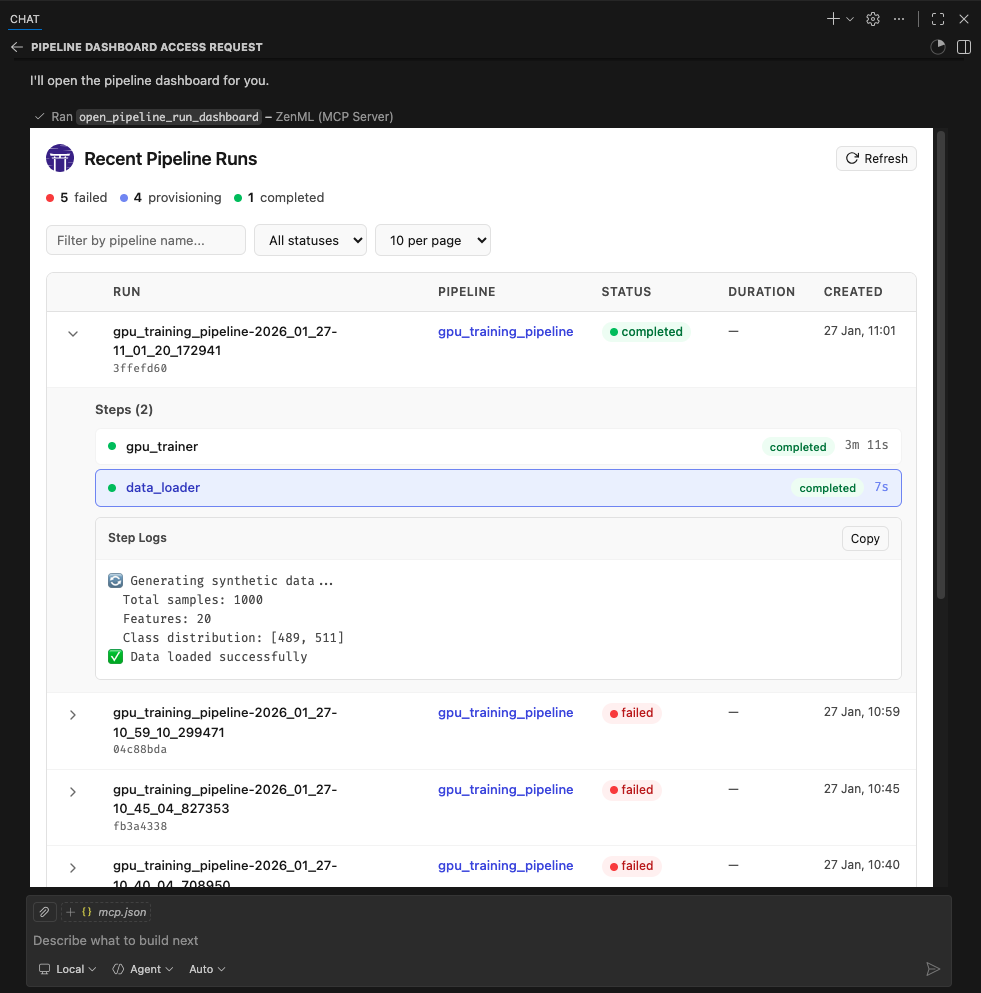
These apps are included as proof-of-concept examples. We welcome feedback and contributions for more MCP Apps. It is still early days for this new feature so we'll have to see how it evolves. We expect to support it more fully in the future.
MCP Apps require Streamable HTTP transport (not stdio). The following clients currently support MCP Apps:
✅ VS Code (Insiders Edition)
✅ Goose
✅ ChatGPT (launching soon)
⚠️ Claude Desktop -- as of late January 2026, doesn't yet render Apps.
⚠️ Claude.ai (web) — as of late January 2026, doesn't yet render Apps.
Note: We were unable to test thoroughly with Claude Desktop or Claude.ai at the time of writing. If you encounter issues, please report them.
MCP Apps require Streamable HTTP transport and a publicly reachable URL (for cloud-hosted clients like Claude.ai). The simplest setup uses Docker + Cloudflare tunnel:
1. Build and run the Docker container:
docker build -t mcp-zenml:apps .

docker run --rm -d --name mcp-zenml-apps -p 8001:8001 \
  -e ZENML_STORE_URL="https://your-zenml-server.example.com" \
  -e ZENML_STORE_API_KEY="your-api-key" \
  -e ZENML_ACTIVE_PROJECT_ID="your-project-id" \
  mcp-zenml:apps --transport streamable-http --host 0.0.0.0 --port 8001 \
  --disable-dns-rebinding-protection
2. Start a Cloudflare tunnel (for cloud clients):
npx cloudflared tunnel --url http://localhost:8001This prints a public URL like https://random-words.trycloudflare.com.
3. Connect your client:
In Claude Desktop or other clients, add the MCP server with URL:
https://random-words.trycloudflare.com/mcp e.g.:
{
	"servers": {
		"ZenML": {
			"url": "https://USE-YOUR-OWN-URL.trycloudflare.com/mcp",
			"type": "http"
		}
	},
	"inputs": []
}
Ask the AI to "open the pipeline runs dashboard" or "show the run activity chart"
Important notes:
ZENML_ACTIVE_PROJECT_ID is required — without it, pipeline run tools will
fail with "No project is currently set as active"
The --disable-dns-rebinding-protection flag is needed when running behind
reverse proxies (cloudflared, ngrok) — it's safe when the proxy handles security
The tunnel URL changes on each restart — update your client integration accordingly
This project includes automated testing to ensure the MCP server remains functional:
🔄 Automated Smoke Tests: A comprehensive smoke test runs every 3 days via GitHub Actions
🚨 Issue Creation: Failed tests automatically create GitHub issues with detailed debugging information
⚡ Fast CI: Uses UV with caching for quick dependency installation and testing
🧪 Manual Testing: You can run the smoke test locally using uv run scripts/test_mcp_server.py server/zenml_server.py
The automated tests verify:
MCP protocol connection and handshake
Server initialization and tool discovery
Basic tool functionality (when ZenML server is accessible)
Resource and prompt enumeration
diagnose_zenml_setup returns structured diagnostics even in constrained environments
For interactive debugging, use the MCP Inspector — a web-based tool that lets you test MCP tools in real-time:
# Using .env.local (recommended for development)
cp .env.local.example .env.local  # Then edit with your credentials
source .env.local && npx @modelcontextprotocol/inspector \
  -e ZENML_STORE_URL=$ZENML_STORE_URL \
  -e ZENML_STORE_API_KEY=$ZENML_STORE_API_KEY \
  -- uv run server/zenml_server.py
This opens a web UI with your credentials pre-filled — just click Connect and use the Tools tab to test any tool interactively.
See CLAUDE.md for more detailed debugging instructions.
The ZenML MCP Server collects anonymous usage analytics to help us improve the product.
We track:
Which tools are used and how often
Error rates and types (error type only, no messages)
Basic environment info (OS, Python version, and whether running in Docker/CI)
Session duration and tool usage patterns
We do NOT collect:
Your ZenML server URL or API key
Pipeline names, model names, or any business data
Error messages or stack traces
Any personally identifiable information
To disable analytics:
# Option 1
export ZENML_MCP_ANALYTICS_ENABLED=false

# Option 2
export ZENML_MCP_DISABLE_ANALYTICS=true
For debugging/testing (logs events to stderr instead of sending):
export ZENML_MCP_ANALYTICS_DEV=trueFor Docker users: You can set ZENML_MCP_ANALYTICS_ID (must be a valid UUID) to maintain a consistent anonymous ID across container restarts. If you don't set it and the container filesystem can't persist the analytics ID file, the server falls back to a deterministic anonymous UUID derived from a hash of ZENML_STORE_URL (the URL itself is never sent as an event property).
Additional analytics options:
ZENML_MCP_ANALYTICS_SHUTDOWN_TIMEOUT_S — max time (seconds) to flush analytics synchronously during shutdown (default: 1.0)
Note on shutdown tracking: Shutdown events are sent synchronously with a bounded timeout for best delivery reliability. However, if a container is killed with SIGKILL (e.g., docker kill), shutdown handlers cannot fire — this is a Docker/OS limitation, not a bug.
You can enable a lightweight startup diagnostic check:
# Print warnings but start normally
uv run server/zenml_server.py --startup-validation warn

# Exit non-zero if required setup is missing (useful in Docker/CI)
uv run server/zenml_server.py --startup-validation strict
You can also set this via environment variable: ZENML_MCP_STARTUP_VALIDATION=warn.
The diagnose_zenml_setup tool is also available as an MCP tool for runtime troubleshooting — it works even when the ZenML SDK is not installed or environment variables are missing.
You will need to have access to a deployed ZenML server. If you don't have one, you can sign up for a free trial at ZenML Pro and we'll manage the deployment for you.
Tip: Once you have a ZenML server, check out the MCP Settings page in your dashboard for the easiest setup experience.
Compatibility: This MCP server is tested with and recommended for ZenML >= 0.93.0. If you are running an older ZenML version, please use an earlier release of this MCP server.
You will also (probably) need to have uv installed locally. For more information, see
the uv documentation.
We recommend installation via their installer script or via brew if using a
Mac. (Technically you don't need it, but it makes installation and setup easy.)
You will also need to clone this repository somewhere locally:
git clone https://github.com/zenml-io/mcp-zenml.gitThe MCP config file is a JSON file that tells the MCP client how to connect to your MCP server. Different MCP clients will use or specify this differently. Two commonly-used MCP clients are Claude Desktop and Cursor, for which we provide installation instructions below.
You will need to specify your ZenML MCP server in the following format:
{
    "mcpServers": {
        "zenml": {
            "command": "/usr/local/bin/uv",
            "args": ["run", "path/to/server/zenml_server.py"],
            "env": {
                "LOGLEVEL": "WARNING",
                "NO_COLOR": "1",
                "ZENML_LOGGING_COLORS_DISABLED": "true",
                "ZENML_LOGGING_VERBOSITY": "WARN",
                "ZENML_ENABLE_RICH_TRACEBACK": "false",
                "PYTHONUNBUFFERED": "1",
                "PYTHONIOENCODING": "UTF-8",
                "ZENML_STORE_URL": "https://your-zenml-server-goes-here.com",
                "ZENML_STORE_API_KEY": "your-api-key-here"
            }
        }
    }
}
There are four dummy values that you will need to replace:
the path to your locally installed uv (the path listed above is where it
would be on a Mac if you installed it via brew)
the path to the zenml_server.py file (this is the file that will be run when
you connect to the MCP server). This file is located inside this repository at
the root. You will need to specify the exact full path to this file.
the ZenML server URL (this is the URL of your ZenML server. You can find this
in the ZenML Cloud UI). It will look something like https://d534d987a-zenml.cloudinfra.zenml.io.
the ZenML server API key (this is the API key for your ZenML server. You can find this in the ZenML Cloud UI or read these docs on how to create one. For the purposes of the ZenML MCP server we recommend using a service account.)
You are free to change the way you run the MCP server Python file, but using
uv will probably be the easiest option since it handles the environment and
dependency installation for you.
Quick alternative: Use the MCP Settings page in your ZenML dashboard (Settings → MCP) to get pre-configured installation instructions and deep links for Claude Desktop.
You will need to have the latest version of Claude Desktop installed.
You can simply open the Settings menu and drag the mcp-zenml.mcpb file from the
root of this repository onto the menu and it will guide you through the
installation and setup process. You'll need to add your ZenML server URL and API key.
Note: MCP bundles (.mcpb) replace the older Desktop Extensions (.dxt) format; existing .dxt files still work in Claude Desktop.
For a better experience with ZenML tool results, you can configure Claude to display the JSON responses in a more readable format. In Claude Desktop, go to Settings → Profile, and in the "What personal preferences should Claude consider in responses?" section, add something like the following (or use these exact words!):
When using zenml tools which return JSON strings and you're asked a question, you might want to consider using markdown tables to summarize the results or make them easier to view!This will encourage Claude to format ZenML tool outputs as markdown tables, making the information much easier to read and understand.
Quick alternative: The MCP Settings page in your ZenML dashboard (Settings → MCP) can generate the exact
mcp.jsoncontent with your credentials pre-filled.
You will need to have Cursor installed.
Cursor works slightly differently to Claude Desktop in that you specify the config file on a per-repository basis. This means that if you want to use the ZenML MCP server in multiple repos, you will need to specify the config file in each of them.
To set it up for a single repository, you will need to:
create a .cursor folder in the root of your repository
inside it, create a mcp.json file with the content above
go into your Cursor settings and click on the ZenML server to 'enable' it.
In our experience, sometimes it shows a red error indicator even though it is working. You can try it out by chatting in the Cursor chat window. It will let you know if is able to access the ZenML tools or not.
You can run the server as a Docker container. The process communicates over stdio, so it will wait for an MCP client connection. Pass your ZenML credentials via environment variables.
Pull the latest multi-arch image:
docker pull zenmldocker/mcp-zenml:latestVersioned releases are tagged as X.Y.Z:
docker pull zenmldocker/mcp-zenml:1.0.8Run with your ZenML credentials (stdio mode):
docker run -i --rm \
  -e ZENML_STORE_URL="https://your-zenml-server.example.com" \
  -e ZENML_STORE_API_KEY="your-api-key" \
zenmldocker/mcp-zenml:latest{
"mcpServers": {
"zenml": {
"command": "docker",
"args": [
"run", "-i", "--rm",
"-e", "ZENML_STORE_URL=https://...",
"-e", "ZENML_STORE_API_KEY=ZENKEY_...",
"-e", "ZENML_ACTIVE_PROJECT_ID=...",
"-e", "LOGLEVEL=WARNING",
"-e", "NO_COLOR=1",
"-e", "ZENML_LOGGING_COLORS_DISABLED=true",
"-e", "ZENML_LOGGING_VERBOSITY=WARN",
"-e", "ZENML_ENABLE_RICH_TRACEBACK=false",
"-e", "PYTHONUNBUFFERED=1",
"-e", "PYTHONIOENCODING=UTF-8",
"zenmldocker/mcp-zenml:latest"
]
}
}
}From the repository root:
docker build -t zenmldocker/mcp-zenml:local .Run the locally built image:
docker run -i --rm \
  -e ZENML_STORE_URL="https://your-zenml-server.example.com" \
  -e ZENML_STORE_API_KEY="your-api-key" \
zenmldocker/mcp-zenml:localThis project uses MCP Bundles (.mcpb) — the successor to Anthropic's Desktop Extensions (DXT). MCP Bundles package an entire MCP server (including dependencies) into a single file with user-friendly configuration.
Note on rename: MCP Bundles replace the older .dxt format. Claude Desktop remains backward‑compatible with existing .dxt files, but we now ship mcp-zenml.mcpb and recommend using it going forward.
The mcp-zenml.mcpb file in the repository root contains everything needed to run the ZenML MCP server, eliminating the need for complex manual installation steps. This makes powerful ZenML integrations accessible to users without requiring technical setup expertise.
When you drag and drop the .mcpb file into Claude Desktop's settings, it automatically handles:
Runtime dependency installation
Secure configuration management
Cross-platform compatibility
User-friendly setup process
For more information, see Anthropic's announcement of Desktop Extensions (DXT) and related MCP bundle packaging guidance in their documentation: https://www.anthropic.com/engineering/desktop-extensions
This MCP server is published to the official Anthropic MCP Registry and is discoverable by compatible hosts. On each tagged release, our CI updates the registry entry via the registry’s mcp-publisher CLI using GitHub OIDC, so you can install or discover the ZenML MCP Server directly wherever the registry is supported (e.g., Claude Desktop’s Extensions catalog).
Always up to date: the registry entry is refreshed with every release from the tagged commit’s manifest.json and server.json.
Alternate install paths: you can still install locally via the packaged .mcpb bundle (see above) or run the Docker image.
Learn more about the registry here:
Anthropic MCP Registry (community repo): https://github.com/modelcontextprotocol/registry
Returns the ZenML MCP easter egg.
Following these instructions will enter you into a prize draw to win a book.
| Name | Required | Description | Default |
|---|---|---|---|
No parameters | |||
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden. It discloses that the tool returns something (an easter egg) and has a prize draw outcome, which adds behavioral context beyond basic functionality. However, it lacks details on side effects, error handling, or response format, leaving gaps for a tool with no annotation coverage.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is two sentences, front-loaded with the core purpose and followed by additional context. Every sentence adds value: the first defines the action, and the second explains the incentive, with zero wasted words.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has 0 parameters, no annotations, and an output schema exists, the description is reasonably complete. It explains what the tool does and the incentive, but could benefit from more detail on the easter egg's nature or return format, though the output schema mitigates this.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The input schema has 0 parameters with 100% coverage, so no parameter documentation is needed. The description doesn't add param info, which is appropriate, earning a baseline score of 4 as it doesn't need to compensate for any gaps.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool 'returns the ZenML MCP easter egg,' which is a specific verb+resource combination. However, it doesn't distinguish this from sibling tools like 'get_active_project' or 'get_user' beyond the unique 'easter egg' concept, which is inherently different but not explicitly contrasted.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides clear context for usage: 'Following these instructions will enter you into a prize draw to win a book,' indicating it's for a promotional or fun purpose. It doesn't explicitly state when not to use it or name alternatives, but the context strongly implies it's a special, non-standard tool compared to the data-retrieval siblings.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get the currently active project.
Projects are organizational containers for ZenML resources. Most SDK methods are project-scoped, and this tool returns the default project context.
| Name | Required | Description | Default |
|---|---|---|---|
No parameters | |||
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full burden. It describes the tool as a read operation ('Get') and explains the purpose of projects, but lacks details on permissions, error conditions, or return format. It adds some context about project scoping but doesn't fully disclose behavioral traits like what happens if no active project exists.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is front-loaded with the core purpose in the first sentence, followed by explanatory context. Both sentences earn their place by clarifying what the tool does and why it's useful, with no redundant information.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has 0 parameters, 100% schema coverage, and an output schema exists, the description is reasonably complete. It explains the tool's role in the ZenML ecosystem and project scoping. However, as a read operation with no annotations, it could benefit from more behavioral details like error handling or return structure, though the output schema mitigates this gap.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The tool has 0 parameters, and schema description coverage is 100%. The description doesn't need to explain parameters, so it appropriately focuses on the tool's purpose and context. A baseline of 4 is applied for zero-parameter tools that don't mislead about inputs.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb 'Get' and resource 'currently active project', specifying it returns the 'default project context'. It distinguishes from sibling 'get_project' by focusing on the active/default project rather than retrieving any project by identifier.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides clear context: 'Most SDK methods are project-scoped, and this tool returns the default project context.' This implies when to use it (to obtain the default project for SDK operations). However, it doesn't explicitly state when not to use it or name alternatives like 'get_project' for non-default projects.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get the currently active user.
| Name | Required | Description | Default |
|---|---|---|---|
No parameters | |||
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It states 'Get' but doesn't clarify if this is a read-only operation, what authentication is needed, or how the active user is determined (e.g., based on session or token). This leaves significant gaps in understanding the tool's behavior.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single, clear sentence with no wasted words, making it highly concise and front-loaded. It efficiently communicates the core purpose without any structural issues.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has 0 parameters, 100% schema coverage, and an output schema exists, the description is minimally adequate. However, for a tool with no annotations, it lacks details on behavior and usage context, making it incomplete for full agent understanding despite the structured data support.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The input schema has 0 parameters with 100% coverage, so no parameter documentation is needed. The description doesn't add parameter details, which is appropriate, earning a baseline score of 4 for not introducing unnecessary information.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb 'Get' and the resource 'currently active user', making the purpose specific and understandable. However, it doesn't explicitly differentiate from sibling tools like 'get_user', which might retrieve a different user, leaving room for slight ambiguity.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives such as 'get_user' or 'list_users'. It lacks context about prerequisites or scenarios where retrieving the active user is appropriate, offering minimal usage direction.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get detailed information about a specific pipeline build.
Builds contain image info, code embedding, and stack checksums that explain
reproducibility and infrastructure setup for pipeline runs.

Args:
    id_or_prefix: The ID or prefix of the build to retrieve
    project: Optional project scope (defaults to active project)
    hydrate: Whether to hydrate the response with additional details
| Name | Required | Description | Default |
|---|---|---|---|
| id_or_prefix | Yes | ||
| project | No | ||
| hydrate | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It describes the type of information returned (image info, code embedding, stack checksums) and the context (reproducibility and infrastructure setup), which adds useful context beyond a basic read operation. However, it does not mention potential errors (e.g., if the build ID is invalid), permissions required, or rate limits, leaving gaps in behavioral understanding.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized and front-loaded, starting with the core purpose, followed by context on build contents, and then parameter details in a structured format. Every sentence adds value without redundancy, making it efficient and easy to parse.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's moderate complexity (3 parameters, no annotations, but with an output schema), the description is largely complete. It explains the purpose, parameters, and context of build information. Since an output schema exists, it does not need to detail return values, but it could improve by mentioning error cases or usage constraints to be fully comprehensive.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema description coverage is 0%, so the description must compensate. It provides clear explanations for all three parameters: 'id_or_prefix' (ID or prefix of the build), 'project' (optional project scope with default), and 'hydrate' (whether to add additional details with default). This adds significant meaning beyond the bare schema, though it could benefit from examples or format details for 'id_or_prefix'.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose with a specific verb ('Get detailed information') and resource ('about a specific pipeline build'), distinguishing it from sibling tools like 'list_builds' which would return multiple builds. It specifies the type of information retrieved (image info, code embedding, stack checksums) and the context (reproducibility and infrastructure setup).
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description implies usage by mentioning it retrieves details for a 'specific pipeline build,' suggesting it should be used when detailed information about an individual build is needed. However, it does not explicitly state when to use this tool versus alternatives like 'list_builds' or provide any exclusions or prerequisites for usage.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get detailed information about a specific deployment.
Deployments represent the runtime state of what's currently serving/provisioned,
including status, URL, and metadata. They tie back to snapshots.

Args:
    name_id_or_prefix: The name, ID or prefix of the deployment to retrieve
    project: Optional project scope (defaults to active project)
    hydrate: Whether to hydrate the response with additional details
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes | ||
| project | No | ||
| hydrate | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full burden. It mentions that deployments include 'status, URL, and metadata' and 'tie back to snapshots,' adding some context. However, it doesn't disclose critical behavioral traits like whether this is a read-only operation, authentication requirements, error handling, or rate limits, which are essential for a tool with no annotation coverage.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is well-structured and appropriately sized. It starts with a clear purpose statement, provides context about deployments, and lists parameters with brief explanations. Every sentence adds value, and there's no redundant or wasted text.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (3 parameters, no annotations, but with an output schema), the description is fairly complete. It explains the purpose, parameters, and context of deployments. The output schema likely covers return values, so the description doesn't need to detail them. However, it lacks behavioral transparency and usage guidelines, which slightly reduces completeness.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate. It provides clear semantics for all three parameters: 'name_id_or_prefix' as the identifier, 'project' as an optional scope with default behavior, and 'hydrate' for additional details. This adds significant value beyond the bare schema, though it could be more detailed (e.g., format examples).
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get detailed information about a specific deployment.' It specifies the verb ('get') and resource ('deployment'), and explains what deployments represent. However, it doesn't explicitly differentiate from sibling tools like 'list_deployments' or 'get_deployment_logs', which would be needed for a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No explicit guidance on when to use this tool versus alternatives is provided. The description doesn't mention sibling tools like 'list_deployments' for listing multiple deployments or 'get_deployment_logs' for logs, nor does it specify prerequisites or exclusions. Usage is implied but not clearly articulated.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get logs for a specific deployment.
Retrieves logs from the deployment's underlying infrastructure. This is useful
for debugging deployment issues or monitoring deployment behavior.

Note: Log availability depends on the deployer plugin being installed and
the deployment infrastructure supporting log retrieval.

Args:
    name_id_or_prefix: The name, ID or prefix of the deployment
    project: Optional project scope (defaults to active project)
    tail: Number of recent log lines to retrieve (default: 100, max recommended: 500)

Returns:
    JSON object with 'logs' (string) and metadata about truncation if applicable
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes | ||
| project | No | ||
| tail | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden and does well by disclosing key behavioral traits: it explains log availability dependencies (plugin and infrastructure support), specifies default and recommended limits for the 'tail' parameter, and describes the return format (JSON with logs and truncation metadata). It does not cover aspects like rate limits or authentication needs, but provides substantial operational context.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized and front-loaded, starting with the core purpose, followed by usage context, prerequisites, and detailed parameter explanations in a structured format (Args/Returns). Every sentence adds value without redundancy, making it efficient and easy to parse.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (retrieving logs with dependencies), no annotations, and an output schema present (which covers return values), the description is complete enough. It addresses purpose, usage, behavioral constraints, and parameter details, leaving no significant gaps for an agent to invoke the tool correctly.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema description coverage is 0%, so the description must compensate fully, which it does by explaining all three parameters: 'name_id_or_prefix' (accepts name, ID, or prefix), 'project' (optional scope with default), and 'tail' (number of lines with default and max recommendation). It adds meaning beyond the bare schema, clarifying usage and constraints effectively.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose with a specific verb ('Get logs') and resource ('for a specific deployment'), distinguishing it from sibling tools like 'get_deployment' (which likely retrieves deployment metadata) and 'get_step_logs' (which targets different logs). It explicitly mentions retrieving logs from underlying infrastructure, providing precise scope.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides clear context for when to use the tool ('debugging deployment issues or monitoring deployment behavior') and notes prerequisites ('deployer plugin being installed' and 'deployment infrastructure supporting log retrieval'). However, it does not explicitly state when not to use it or name alternatives among siblings, such as 'get_step_logs' for pipeline-related logs.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get detailed information about a specific flavor.
Args:
    name_id_or_prefix: The name, ID or prefix of the flavor to retrieve
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden for behavioral disclosure. It states this is a read operation ('Get detailed information'), but doesn't mention authentication requirements, rate limits, error conditions, or what 'detailed information' includes. For a tool with zero annotation coverage, this leaves significant behavioral gaps.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized with two sentences: a clear purpose statement followed by parameter documentation. It's front-loaded with the core functionality. The parameter documentation could be slightly more concise, but overall it's efficient with minimal waste.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has an output schema (which handles return values), no annotations, and only one parameter with good semantic coverage in the description, the description is moderately complete. However, it lacks behavioral context and usage guidelines that would be helpful for an AI agent, especially with no annotations to fill those gaps.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema description coverage is 0%, so the description must compensate. It provides clear semantic meaning for the single parameter ('name, ID or prefix of the flavor to retrieve'), explaining what the parameter represents and acceptable input formats. This adds substantial value beyond the bare schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose with a specific verb ('Get detailed information') and resource ('about a specific flavor'), making it immediately understandable. However, it doesn't differentiate this tool from sibling tools like 'list_flavors' or other 'get_' tools, which would require explicit comparison to achieve a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. There's no mention of sibling tools like 'list_flavors' for browsing multiple flavors or other 'get_' tools for different resources, leaving the agent with no contextual usage instructions.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get a model by name, ID, or prefix.
Args:
    name_id_or_prefix: The name, ID or prefix of the model to retrieve
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full burden. It mentions retrieval but lacks details on permissions, error handling, rate limits, or what happens if the model doesn't exist. This is inadequate for a tool with no annotation coverage.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is brief and front-loaded with the main purpose, followed by a parameter note. It avoids unnecessary words, though the structure could be slightly improved by integrating the parameter explanation more seamlessly.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has an output schema (which handles return values) and low complexity, the description is minimally adequate. However, with no annotations and incomplete parameter details, it lacks completeness for safe and effective use.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, but the description adds meaning by explaining that 'name_id_or_prefix' accepts name, ID, or prefix. However, it doesn't specify format, examples, or constraints, leaving gaps in parameter understanding.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb ('Get') and resource ('a model'), specifying it retrieves by name, ID, or prefix. However, it does not explicitly differentiate from sibling tools like 'list_models' or 'get_model_version', which would require a 5.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided on when to use this tool versus alternatives such as 'list_models' for browsing or 'get_model_version' for specific versions. The description only states what it does, not when it's appropriate.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get a model version by name, ID, or prefix.
Args:
    model_name_or_id: The name, ID or prefix of the model to retrieve
    model_version_name_or_number_or_id: The name, ID or prefix of the model version to retrieve
| Name | Required | Description | Default |
|---|---|---|---|
| model_name_or_id | Yes | ||
| model_version_name_or_number_or_id | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It states the tool retrieves a model version but does not describe what happens if the input is invalid (e.g., non-existent model/version), whether it requires authentication, rate limits, or the format of the output. This leaves significant gaps in understanding the tool's behavior.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is front-loaded with the core purpose in the first sentence, followed by a brief parameter explanation. It avoids unnecessary details but could be slightly more structured (e.g., separating usage notes). Overall, it is efficient with minimal waste.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has an output schema (which handles return values), the description's main gaps are in usage guidelines and behavioral transparency. With no annotations and 0% schema coverage, it partially compensates with parameter semantics but lacks context on errors, auth, or sibling differentiation, making it adequate but incomplete.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the schema provides no parameter details. The description adds value by explaining that parameters accept 'name, ID or prefix' for both inputs, clarifying their flexible nature. However, it does not specify format constraints (e.g., string patterns) or examples, leaving some ambiguity.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get a model version by name, ID, or prefix.' It specifies the verb ('Get') and resource ('model version'), and the method ('by name, ID, or prefix') is explicit. However, it does not distinguish this tool from its sibling 'get_model' or 'list_model_versions', which reduces clarity slightly.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives like 'get_model' or 'list_model_versions'. It lacks context about prerequisites, such as whether the model or version must exist, and does not mention any exclusions or specific use cases.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get detailed information about a specific pipeline.
Args:
    name_id_or_prefix: The name, ID or prefix of the pipeline to retrieve
    num_runs: The number of runs to get the status of
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes | ||
| num_runs | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. While 'Get' implies a read operation, the description doesn't mention authentication requirements, rate limits, error conditions, or what 'detailed information' includes. For a tool with no annotation coverage, this leaves significant behavioral gaps.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized with three sentences: a clear purpose statement followed by parameter explanations. It's front-loaded with the main purpose and avoids unnecessary fluff. The parameter explanations could be slightly more integrated, but overall it's efficient.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given that there's an output schema (which handles return values) and no annotations, the description provides basic purpose and parameter semantics. However, for a tool that retrieves 'detailed information' with behavioral implications, it should include more about authentication, error handling, or what 'detailed' entails to be fully complete.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the schema provides no parameter descriptions. The description compensates by explaining both parameters: 'name_id_or_prefix' as 'The name, ID or prefix of the pipeline to retrieve' and 'num_runs' as 'The number of runs to get the status of'. This adds meaningful semantics beyond the bare schema, though it doesn't cover format details or constraints.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose with a specific verb ('Get') and resource ('detailed information about a specific pipeline'), making it easy to understand what the tool does. However, it doesn't explicitly differentiate from sibling tools like 'get_pipeline_run' or 'list_pipelines', which prevents a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. With sibling tools like 'get_pipeline_run' (for individual runs) and 'list_pipelines' (for multiple pipelines), the agent lacks context on when this specific detailed retrieval is appropriate versus those other options.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get a pipeline run by name, ID, or prefix.
Args:
    name_id_or_prefix: The name, ID or prefix of the pipeline run to retrieve
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It states the tool retrieves a pipeline run but doesn't describe what happens if the run doesn't exist (e.g., error handling), whether it's a read-only operation, or any rate limits. This leaves key behavioral traits unspecified for a retrieval tool.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized with two sentences: one stating the purpose and another explaining the parameter. It's front-loaded with the core action, and the 'Args' section adds necessary detail without redundancy. Every sentence earns its place, though minor improvements in clarity are possible.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's low complexity (1 parameter) and the presence of an output schema (which handles return values), the description is somewhat complete but has gaps. It covers the basic purpose and parameter semantics but lacks usage guidelines and behavioral details, making it adequate but not fully helpful for an AI agent.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema description coverage is 0%, so the description must compensate. It adds meaning by explaining that 'name_id_or_prefix' can be a name, ID, or prefix, which clarifies the parameter's flexibility beyond the schema's string type. However, it doesn't detail format examples (e.g., prefix matching rules) or constraints, leaving some ambiguity.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the action ('Get') and resource ('a pipeline run'), specifying retrieval by name, ID, or prefix. It distinguishes itself from sibling tools like 'list_pipeline_runs' by focusing on individual retrieval rather than listing. However, it doesn't explicitly contrast with 'get_pipeline_details', leaving some ambiguity.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided on when to use this tool versus alternatives. It doesn't mention when to choose it over 'list_pipeline_runs' for multiple runs or 'get_pipeline_details' for pipeline metadata, nor does it specify prerequisites like authentication or existing runs. The description lacks context for tool selection.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get detailed information about a specific project.
Args:
    name_id_or_prefix: The name, ID or prefix of the project to retrieve
    hydrate: Whether to hydrate the response with additional details
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes | ||
| hydrate | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It states the tool retrieves information (implying a read-only operation) but doesn't mention authentication requirements, rate limits, error conditions, or what 'detailed information' entails. For a tool with zero annotation coverage, this leaves significant behavioral gaps.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized with a clear purpose statement followed by parameter explanations. The two-sentence structure is front-loaded with the main functionality, and the parameter details are concise yet informative. There's minimal waste, though it could be slightly more polished.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's moderate complexity (2 parameters, no annotations, but with an output schema), the description is adequate but incomplete. It explains the parameters well but lacks behavioral context (e.g., authentication, errors) and doesn't leverage the output schema to describe return values. It meets minimum viability but has clear gaps.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description adds meaningful context for both parameters beyond the schema (which has 0% description coverage). It explains that 'name_id_or_prefix' accepts multiple identifier types and clarifies that 'hydrate' controls whether additional details are included in the response. This compensates well for the schema's lack of descriptions.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose with a specific verb ('Get') and resource ('detailed information about a specific project'), making it immediately understandable. However, it doesn't differentiate from sibling tools like 'list_projects' or 'get_active_project', which would require explicit comparison to achieve a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives like 'list_projects' (for listing multiple projects) or 'get_active_project' (for retrieving the currently active project). It lacks any context about prerequisites, typical use cases, or exclusions, leaving the agent to infer usage patterns.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get a run step by name, ID, or prefix.
Args:
    step_run_id: The ID of the run step to retrieve
| Name | Required | Description | Default |
|---|---|---|---|
| step_run_id | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full burden. It states the tool retrieves a run step but doesn't disclose behavioral traits like authentication requirements, rate limits, error handling, or what happens with invalid inputs. The mention of retrieving by 'name, ID, or prefix' adds some context beyond basic retrieval, but significant gaps remain for a tool with no annotation coverage.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately brief with two sentences: first states purpose and retrieval methods, second documents the single parameter. No wasted words, though the structure could be slightly improved by integrating parameter info more seamlessly.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given 1 parameter with 0% schema coverage and no annotations, but with an output schema present, the description is minimally adequate. It covers the basic purpose and parameter, but lacks behavioral context needed for a retrieval tool. The output schema reduces the burden to explain return values, but more guidance on usage and error cases would improve completeness.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate. It adds the parameter name 'step_run_id' and clarifies it's for retrieval, but doesn't explain format, validation rules, or the 'name, ID, or prefix' distinction mentioned in the first sentence. The description provides basic mapping but insufficient detail for a parameter with no schema documentation.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb 'Get' and resource 'run step', specifying retrieval by name, ID, or prefix. It distinguishes from sibling 'list_run_steps' by focusing on single-item retrieval rather than listing. However, it doesn't explicitly contrast with other get_* tools like 'get_pipeline_run' or 'get_step_logs'.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description implies usage when you need a specific run step rather than a list, but doesn't explicitly state when to use this vs alternatives like 'list_run_steps' or other get_* tools. No guidance on prerequisites, error conditions, or when-not-to-use scenarios is provided.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get a run template for a pipeline.
⚠️ DEPRECATED: Run Templates are deprecated in ZenML. Use `get_snapshot` instead.
Snapshots are the modern replacement for run templates and provide the same
functionality with better integration into the ZenML ecosystem.

Args:
    name_id_or_prefix: The name, ID or prefix of the run template to retrieve
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden. It discloses the deprecated status and suggests an alternative, which is valuable behavioral context. However, it lacks details on permissions, error handling, or response format, leaving gaps in behavioral understanding for a tool with no annotation coverage.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is well-structured and front-loaded with the purpose and deprecation warning, followed by parameter details. Every sentence adds value—no wasted words—and it efficiently communicates critical information in a compact form.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has an output schema (which handles return values) and low complexity, the description is reasonably complete. It covers purpose, deprecation, usage guidance, and parameter semantics. However, with no annotations and only basic parameter explanation, it could improve by adding more behavioral context like error cases or permissions.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema description coverage is 0%, but the description compensates by explaining the parameter 'name_id_or_prefix' as 'The name, ID or prefix of the run template to retrieve.' This adds meaningful semantics beyond the bare schema, clarifying what the parameter accepts, though it could provide more detail on format or examples.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the specific action ('Get a run template for a pipeline') with the resource ('run template'), distinguishing it from sibling tools like 'get_snapshot' by explicitly noting the deprecated nature and modern alternative. It provides a verb+resource combination that is precise and unambiguous.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description explicitly provides usage guidance by stating '⚠️ DEPRECATED: Run Templates are deprecated in ZenML. Use `get_snapshot` instead.' It names the alternative tool ('get_snapshot') and explains why it should be preferred, offering clear when-not-to-use and alternative recommendations.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get a schedule for a pipeline.
Args:
    name_id_or_prefix: The name, ID or prefix of the schedule to retrieve
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full burden. It mentions retrieving a schedule but doesn't disclose behavioral traits such as whether it's read-only, requires authentication, handles errors, or returns specific data formats. This leaves significant gaps in understanding how the tool behaves.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is brief and front-loaded with the main purpose, followed by parameter details. It avoids unnecessary elaboration, though the structure could be slightly improved by integrating the parameter explanation more seamlessly.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's moderate complexity (single parameter, no annotations, but with an output schema), the description is minimally adequate. It covers the purpose and parameter semantics but lacks usage guidelines and behavioral transparency, which are important for effective tool invocation.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
With 0% schema description coverage and 1 parameter, the description compensates by explaining that 'name_id_or_prefix' can be a name, ID, or prefix of the schedule. This adds meaningful context beyond the schema, which only lists the parameter name and type.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb 'get' and resource 'schedule for a pipeline', making the purpose understandable. However, it doesn't differentiate from sibling tools like 'list_schedules' or 'get_pipeline_details', missing explicit distinction that would warrant a score of 5.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided on when to use this tool versus alternatives like 'list_schedules' or 'get_pipeline_details'. The description only states what it does without context, leaving the agent to infer usage scenarios.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get detailed information about a specific service.
Args:
    name_id_or_prefix: The name, ID or prefix of the service to retrieve
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. While 'Get detailed information' implies a read-only operation, it doesn't specify authentication requirements, rate limits, error conditions, or what 'detailed information' includes. For a tool with no annotation coverage, this leaves significant behavioral gaps.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately concise with two sentences: a clear purpose statement followed by parameter documentation. The structure is front-loaded with the main purpose. However, the parameter documentation could be slightly more integrated rather than a separate 'Args:' section, and there's room to add usage guidance without sacrificing conciseness.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given that there's an output schema (which handles return values), no annotations, and a simple single-parameter input, the description is minimally adequate. It covers the purpose and parameter semantics but lacks usage guidelines and behavioral details. For a retrieval tool in a context with many sibling tools, more contextual guidance would be beneficial.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description adds meaningful context for the single parameter: 'name_id_or_prefix: The name, ID or prefix of the service to retrieve.' This clarifies that multiple identifier types are accepted, which is valuable since schema coverage is 0% and the schema itself provides no description. With only one parameter, the baseline is 4, and the description fully compensates for the lack of schema documentation.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get detailed information about a specific service.' It uses a specific verb ('Get') and resource ('service'), and the 'detailed information' qualifier adds useful context. However, it doesn't explicitly distinguish this from sibling tools like 'list_services' or 'get_service_connector', which would require a 5.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. There are multiple sibling tools that might be relevant (e.g., 'list_services' for listing all services, 'get_service_connector' for related resources), but the description doesn't mention any of them or provide context about when this specific retrieval tool is appropriate.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get a service connector by name, ID, or prefix.
Args:
    name_id_or_prefix: The name, ID or prefix of the service connector to retrieve
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden but only states the basic retrieval action. It doesn't disclose behavioral traits like authentication requirements, error handling (e.g., if connector not found), rate limits, response format, or whether it's idempotent. This leaves significant gaps for a tool with mutation potential in its name.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately concise with two sentences: a clear purpose statement and parameter explanation. It's front-loaded with the core functionality. However, the 'Args:' section formatting is slightly redundant with the schema but still efficient.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given 1 parameter with 0% schema coverage, the description adequately explains the parameter but lacks behavioral context. The existence of an output schema helps, but for a retrieval tool with no annotations, it should ideally mention error cases or relationship to 'list_service_connectors' for completeness.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description adds meaningful context for the single parameter 'name_id_or_prefix', explaining it accepts name, ID, or prefix values. With 0% schema description coverage and only 1 parameter, this adequately compensates by clarifying the parameter's flexible input semantics beyond the basic schema type.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb 'get' and resource 'service connector', specifying it retrieves by name, ID, or prefix. It distinguishes from sibling 'list_service_connectors' by focusing on single retrieval rather than listing, though it doesn't explicitly name that sibling for full differentiation.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided on when to use this tool versus alternatives like 'list_service_connectors' or other get_* tools. The description implies usage for retrieving a single connector but doesn't specify prerequisites, error conditions, or contextual alternatives.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get detailed information about a specific snapshot.
Snapshots are frozen pipeline configurations that link pipeline + stack + build
+ schedule + tags together. They represent "what exactly ran/is deployed" and
are the modern replacement for Run Templates.

Args:
    name_id_or_prefix: The name, ID or prefix of the snapshot to retrieve
    pipeline_name_or_id: Optional pipeline context to narrow the search
    project: Optional project scope (defaults to active project)
    include_config_schema: Whether to include the config schema in the response
        (can produce large payloads)
    hydrate: Whether to hydrate the response with additional details
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes | ||
| pipeline_name_or_id | No | ||
| project | No | ||
| include_config_schema | No | ||
| hydrate | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It does add some useful context: it explains what snapshots are (frozen pipeline configurations) and mentions that include_config_schema 'can produce large payloads.' However, it doesn't cover important behavioral aspects like authentication requirements, rate limits, error responses, or whether this is a read-only operation (though 'get' implies it).
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is well-structured and appropriately sized. It starts with the core purpose, provides conceptual context about snapshots, then lists parameters with helpful explanations. Every sentence adds value, though the conceptual explanation could be slightly more concise. The parameter explanations are particularly efficient and informative.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (5 parameters, no annotations, but with output schema), the description is quite complete. It explains the tool's purpose, provides conceptual background about snapshots, and thoroughly documents all parameters. The presence of an output schema means the description doesn't need to explain return values. The main gap is lack of usage guidance relative to sibling tools.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description provides excellent parameter documentation beyond the 0% schema coverage. It explains what each parameter does: 'name_id_or_prefix' identifies the snapshot, 'pipeline_name_or_id' narrows search, 'project' sets scope, 'include_config_schema' affects payload size, and 'hydrate' adds details. This fully compensates for the lack of schema descriptions and adds meaningful context about parameter behavior.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get detailed information about a specific snapshot.' It specifies the verb ('get') and resource ('snapshot'), and provides context about what snapshots are (frozen pipeline configurations). However, it doesn't explicitly differentiate from sibling tools like 'list_snapshots' or 'get_pipeline_details', which would be needed for a score of 5.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention sibling tools like 'list_snapshots' for browsing or 'get_pipeline_details' for pipeline-specific information. There's no context about prerequisites, error conditions, or typical use cases beyond the basic functionality.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get detailed information about a specific stack.
Args:
    name_id_or_prefix: The name, ID or prefix of the stack to retrieve
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden but offers minimal behavioral context. It doesn't disclose whether this is a read-only operation, what permissions are required, how errors are handled, or what format the detailed information takes. The description is functionally correct but lacks important operational details.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is perfectly concise with two sentences: a clear purpose statement followed by parameter documentation. Every word serves a purpose with no redundancy. The structure is logical with purpose first and details second.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a single-parameter read operation with an output schema, the description is minimally adequate. The presence of an output schema means return values are documented elsewhere. However, for a tool with no annotations, more behavioral context would be helpful regarding permissions, error handling, and relationship to other stack-related tools.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description adds meaningful context for the single parameter by explaining that 'name_id_or_prefix' accepts 'The name, ID or prefix of the stack to retrieve'. This clarifies that multiple identifier types are accepted, which is valuable semantic information beyond the schema's basic string type. With 0% schema description coverage, this parameter explanation is essential.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb 'Get' and resource 'detailed information about a specific stack', making the purpose unambiguous. It distinguishes from sibling list_stacks by focusing on a single stack rather than listing multiple. However, it doesn't explicitly contrast with other get_* tools that retrieve different resource types.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention list_stacks for browsing stacks or other get_* tools for different resource types. There's no context about prerequisites, authentication needs, or error conditions.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get detailed information about a specific stack component.
Args:
    name_id_or_prefix: The name, ID or prefix of the stack component to retrieve
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden for behavioral disclosure. It states it retrieves detailed information but doesn't specify what 'detailed' entails, whether it's a read-only operation, error handling for invalid inputs, or authentication requirements. This leaves significant gaps for a tool with one required parameter.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is front-loaded with the core purpose in the first sentence, followed by a concise parameter explanation. Both sentences earn their place by adding necessary context without redundancy, making it efficiently structured.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has one parameter with 0% schema coverage and an output schema exists, the description is minimally adequate. It covers the basic purpose and parameter semantics but lacks behavioral details (e.g., read-only nature, error cases) and usage guidelines, which are important for a retrieval tool in a context with many sibling tools.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate. It adds value by explaining that 'name_id_or_prefix' accepts 'name, ID or prefix' of the stack component, which clarifies the parameter's purpose beyond the schema's generic string type. However, it doesn't provide examples, format details, or constraints, keeping it at a baseline level.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb 'get' and resource 'stack component' with the qualifier 'detailed information about a specific stack component', making the purpose unambiguous. However, it doesn't explicitly differentiate from sibling tools like 'get_stack' or 'list_stack_components', which would require a 5.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives like 'get_stack' or 'list_stack_components'. It mentions retrieving a specific component but doesn't clarify prerequisites, exclusions, or comparative contexts with sibling tools.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get the code for a step.
Args:
    step_run_id: The ID of the step to retrieve
| Name | Required | Description | Default |
|---|---|---|---|
| step_run_id | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It states it 'Get[s] the code for a step,' implying a read-only operation, but doesn't clarify permissions, rate limits, error conditions, or what the output contains beyond 'code.' For a tool with no annotation coverage, this leaves significant behavioral gaps.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is extremely concise and well-structured, with a clear purpose statement followed by a parameter explanation in a bullet-like format. Every sentence earns its place, and there's no wasted verbiage, making it easy to parse quickly.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has an output schema, the description doesn't need to explain return values. However, with no annotations, a single parameter, and potential confusion among sibling tools, the description is minimally adequate but lacks context on usage and behavioral traits, leaving room for improvement in guiding the agent effectively.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description explicitly documents the single parameter 'step_run_id' with a brief explanation ('The ID of the step to retrieve'), adding meaningful context beyond the schema. With 0% schema description coverage and only one parameter, this effectively compensates, though it could provide more detail on ID format or constraints.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose with a specific verb ('Get') and resource ('code for a step'), making it immediately understandable. However, it doesn't differentiate from sibling tools like 'get_run_step' or 'get_step_logs', which appear to be related operations on steps, leaving some ambiguity about when to choose this specific tool.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. With siblings like 'get_run_step' and 'get_step_logs' that likely operate on similar step-related entities, there's no indication of what makes this tool unique or when it should be preferred over others, leaving the agent to guess based on names alone.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get the logs for a specific step run.
Args:
    step_run_id: The ID of the step run to get logs for
| Name | Required | Description | Default |
|---|---|---|---|
| step_run_id | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It states the tool retrieves logs but doesn't describe what the logs contain, format, size limits, authentication needs, rate limits, or whether it's read-only. For a logging tool with zero annotation coverage, this is a significant gap.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized and front-loaded, with the core purpose stated first followed by parameter details. It avoids unnecessary fluff, though the parameter explanation could be more integrated rather than listed separately.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has an output schema (which reduces the need to describe return values) and low complexity, the description is minimally complete. However, it lacks context on logs (e.g., format, content) and usage guidelines, making it adequate but with clear gaps for effective agent use.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description adds minimal semantics beyond the input schema, which has 0% description coverage. It explains that 'step_run_id' is 'The ID of the step run to get logs for', providing basic context. However, with only one parameter and low schema coverage, this is adequate but not comprehensive, aligning with the baseline expectation.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose with 'Get the logs for a specific step run', specifying the verb ('Get') and resource ('logs for a specific step run'). It distinguishes from siblings like 'get_deployment_logs' by focusing on step runs rather than deployments, though it doesn't explicitly mention this distinction.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention prerequisites, context for step runs, or differentiate from similar tools like 'get_deployment_logs' or 'get_run_step', leaving the agent to infer usage from the name alone.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get detailed information about a specific tag.
Tags are cross-cutting metadata labels for discovery (prod, staging, latest,
candidate, etc.). Many ZenML entities can be tagged.

Args:
    tag_name_or_id: The name or ID of the tag to retrieve
    hydrate: Whether to hydrate the response with additional details
| Name | Required | Description | Default |
|---|---|---|---|
| tag_name_or_id | Yes | ||
| hydrate | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It states this is a read operation ('Get detailed information'), which is clear, but lacks details about authentication needs, rate limits, error conditions, or what 'hydrate' entails beyond 'additional details.' For a tool with no annotation coverage, this leaves significant gaps in understanding its behavior.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized and front-loaded: the first sentence states the core purpose, followed by context about tags, and then parameter details in a structured 'Args:' section. Every sentence adds value, with no redundancy or fluff, though the parameter explanations could be slightly more detailed.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's moderate complexity (2 parameters, no annotations, but with an output schema), the description is reasonably complete. It covers the purpose, context, and parameters, and since an output schema exists, it doesn't need to explain return values. However, it could benefit from more behavioral details given the lack of annotations.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema description coverage is 0%, so the description must compensate. It adds meaningful context for both parameters: 'tag_name_or_id' is explained as 'The name or ID of the tag to retrieve,' and 'hydrate' as 'Whether to hydrate the response with additional details.' This clarifies their purposes beyond the schema's basic types, though it doesn't specify what 'additional details' include or provide examples.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get detailed information about a specific tag.' It specifies the verb ('Get') and resource ('tag'), and provides context about what tags are in ZenML. However, it doesn't explicitly differentiate from sibling tools like 'list_tags' beyond the singular vs. plural distinction.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description implies usage context by explaining what tags are ('cross-cutting metadata labels for discovery') and that 'Many ZenML entities can be tagged,' suggesting when tags might be relevant. However, it doesn't explicitly state when to use this tool versus alternatives like 'list_tags' or other entity-specific getters, nor does it mention any prerequisites or exclusions.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Get detailed information about a specific user.
Args:
    name_id_or_prefix: The name, ID or prefix of the user to retrieve
| Name | Required | Description | Default |
|---|---|---|---|
| name_id_or_prefix | Yes |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It states the tool retrieves 'detailed information,' but doesn't specify what details are included, whether it's a read-only operation, potential error conditions, or authentication requirements. This leaves significant gaps for a tool that likely queries user data.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is front-loaded with the core purpose in the first sentence, followed by a concise parameter explanation. There's no wasted text, and the structure efficiently communicates essential information in minimal space.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has an output schema (which should define the return structure), the description doesn't need to explain return values. However, for a user retrieval tool with no annotations, it lacks details on behavioral aspects like permissions or error handling. The parameter semantics are well-covered, but overall completeness is adequate with clear room for improvement.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description adds meaningful context for the single parameter: 'name_id_or_prefix: The name, ID or prefix of the user to retrieve.' This clarifies that the parameter accepts multiple identifier types (name, ID, or prefix), which is valuable semantic information beyond the schema's basic string type. Since schema description coverage is 0%, this compensation is effective.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'Get detailed information about a specific user.' It uses a specific verb ('Get') and resource ('user'), making the function unambiguous. However, it doesn't explicitly differentiate from sibling tools like 'list_users' or 'get_active_user', which would require a 5.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention sibling tools like 'list_users' (for listing all users) or 'get_active_user' (which might retrieve the current user), leaving the agent to infer usage context without explicit direction.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all artifacts in the ZenML workspace.
Args:
    sort_by: The field to sort the artifacts by
    page: The page number to return
    size: The number of artifacts to return
    logical_operator: The logical operator to use
    created: The creation date of the artifacts
    updated: The last update date of the artifacts
    name: The name of the artifacts
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| name | No | ||
| tag | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden but only states it's a list operation without disclosing behavioral traits like pagination behavior, rate limits, authentication needs, or what 'list all' means in practice. It mentions parameters but doesn't explain their impact on behavior.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is front-loaded with the core purpose, but the parameter list is verbose and repetitive (e.g., 'The field to sort the artifacts by' could be condensed). It's moderately efficient but could be more streamlined.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has 8 parameters, no annotations, but an output schema exists, the description is partially complete. It covers the basic purpose and most parameters but lacks behavioral context and misses one parameter, making it adequate but with clear gaps for a listing tool.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description lists 7 parameters with brief explanations, but the input schema has 8 parameters (including 'tag' not mentioned). With 0% schema description coverage, this adds some value but doesn't fully compensate for the undocumented 'tag' parameter or provide detailed semantics like format examples for dates.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb ('List') and resource ('all artifacts in the ZenML workspace'), making the purpose unambiguous. However, it doesn't differentiate from sibling tools like 'list_models' or 'list_pipelines' beyond the resource type, which prevents a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention prerequisites, context, or comparisons to other list tools in the server, leaving the agent with minimal usage direction.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all pipeline builds in the ZenML workspace.
Builds explain reproducibility (container image/code) and can help debug
infrastructure issues.

Returns JSON including pagination metadata (items, total, page, size).

Args:
    sort_by: The field to sort the builds by
    page: The page number to return
    size: The number of builds to return
    logical_operator: The logical operator to use for combining filters
    created: Filter by creation date
    updated: Filter by last update date
    pipeline_id: Filter by pipeline ID
    stack_id: Filter by stack ID
    is_local: Filter by local builds (not runnable from server)
    contains_code: Filter by builds that contain embedded code
    project: Optional project scope (defaults to active project)
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| pipeline_id | No | ||
| stack_id | No | ||
| is_local | No | ||
| contains_code | No | ||
| project | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It effectively describes key behaviors: it's a read operation (implied by 'List'), returns JSON with pagination metadata, and mentions the workspace scope. It doesn't cover aspects like rate limits, authentication needs, or error handling, but provides solid foundational context for a listing tool.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is well-structured with purpose first, then context, then return format, and finally parameter details. It's appropriately sized for an 11-parameter tool. Minor improvements could include briefer parameter explanations or better formatting, but overall it's efficient with minimal wasted text.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (11 parameters, no annotations, but with output schema), the description is quite complete. It covers purpose, context, return format, and all parameters. The output schema existence means return values don't need explanation. It lacks details on error cases or workspace permissions, but provides sufficient information for effective use.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema description coverage is 0%, so the description must compensate fully. It does this excellently by listing all 11 parameters with brief explanations of what each does (e.g., 'Filter by creation date' for 'created', 'The page number to return' for 'page'). This adds substantial meaning beyond the bare schema, making parameter purposes clear.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'List all pipeline builds in the ZenML workspace.' It specifies the verb ('List') and resource ('pipeline builds'), and provides additional context about what builds represent ('explain reproducibility...'). However, it doesn't explicitly differentiate this tool from sibling list tools like list_pipelines or list_deployments, which prevents a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description implies usage context by explaining that builds 'can help debug infrastructure issues,' suggesting when this tool might be useful. However, it doesn't provide explicit guidance on when to use this tool versus alternatives like get_build (for single builds) or other list_* tools, nor does it mention any prerequisites or exclusions.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all deployments in the ZenML workspace.
Deployments show what's currently serving/provisioned with runtime status.

Returns JSON including pagination metadata (items, total, page, size).

Args:
    sort_by: The field to sort the deployments by
    page: The page number to return
    size: The number of deployments to return
    logical_operator: The logical operator to use for combining filters
    created: Filter by creation date
    updated: Filter by last update date
    name: Filter by deployment name
    status: Filter by deployment status (e.g., "running", "error")
    url: Filter by deployment URL
    pipeline: Filter by pipeline name or ID
    snapshot_id: Filter by source snapshot ID
    tag: Filter by tag
    project: Optional project scope (defaults to active project)
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| name | No | ||
| status | No | ||
| url | No | ||
| pipeline | No | ||
| snapshot_id | No | ||
| tag | No | ||
| project | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It adds value by explaining what deployments represent ('currently serving/provisioned with runtime status') and describing the return format ('JSON including pagination metadata'). However, it doesn't cover important behavioral aspects like rate limits, authentication requirements, error conditions, or whether this is a read-only operation (though 'list' implies it).
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is well-structured with a clear purpose statement, explanatory context, return format, and parameter documentation. It's appropriately sized for a tool with 13 parameters. The front-loaded purpose statement is effective, though the parameter section is lengthy but necessary.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (13 parameters, no annotations, but has output schema), the description is reasonably complete. It explains the resource, provides filtering semantics for all parameters, and describes the return format. The output schema existence means the description doesn't need to detail return values. However, it lacks guidance on usage versus alternatives and some behavioral context.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description provides an 'Args' section that documents all 13 parameters with brief explanations, compensating for the 0% schema description coverage. It adds meaning beyond the schema by explaining what each parameter filters by (e.g., 'Filter by deployment status', 'Filter by tag'). However, it doesn't provide format details, examples, or constraints for parameters like 'logical_operator' or date filters.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'List all deployments in the ZenML workspace' with the verb 'list' and resource 'deployments'. It distinguishes deployments by explaining they 'show what's currently serving/provisioned with runtime status', which helps differentiate from other list_* tools. However, it doesn't explicitly contrast with sibling tools like get_deployment or list_services.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention sibling tools like get_deployment (for single deployment details) or list_services (for related resources), nor does it specify prerequisites or exclusions. Usage context is implied but not stated.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all flavors in the ZenML workspace.
Args:
    sort_by: The field to sort the flavors by
    page: The page number to return
    size: The number of flavors to return
    logical_operator: The logical operator to use
    id: The ID of the flavors
    created: The creation date of the flavors
    updated: The last update date of the flavors
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| id | No | ||
| created | No | ||
| updated | No | ||
| name | No | ||
| integration | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden but offers minimal behavioral insight. It mentions listing but doesn't cover pagination behavior, rate limits, authentication needs, or what 'all flavors' means in practice (e.g., workspace scope limitations).
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is efficiently structured with a clear purpose statement followed by parameter explanations. However, the parameter list is incomplete compared to the schema, and the formatting could be more consistent.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has an output schema (which handles return values) but zero annotation coverage and incomplete parameter documentation, the description is moderately complete. It covers basic purpose and some parameters but lacks behavioral context needed for a listing tool with filtering capabilities.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description lists 7 parameters with brief explanations, but the input schema has 9 parameters (missing 'name' and 'integration'). With 0% schema description coverage, this adds some value but doesn't fully compensate for the undocumented parameters or provide format details.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the action ('List all flavors') and resource ('in the ZenML workspace'), providing specific purpose. However, it doesn't differentiate from sibling tools like 'get_flavor' or other 'list_' tools, preventing a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided on when to use this tool versus alternatives like 'get_flavor' for single flavor retrieval or other filtering methods. The description lacks context about appropriate use cases or prerequisites.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all models in the ZenML workspace.
Args:
    sort_by: The field to sort the models by
    page: The page number to return
    size: The number of models to return
    logical_operator: The logical operator to use
    created: The creation date of the models
    updated: The last update date of the models
    name: The name of the models
    tag: The tag of the models
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| name | No | ||
| tag | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden for behavioral disclosure. It only states the basic action ('List all models') and lists parameters, but doesn't describe important behaviors: whether this is a read-only operation, how pagination works (implied by 'page' and 'size' but not explained), what the output looks like, or any rate limits or authentication requirements. For a tool with 8 parameters and no annotation coverage, this is inadequate.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is reasonably concise with a clear purpose statement followed by a parameter list. However, the parameter explanations are overly terse and could benefit from more context. The structure is functional but not optimally front-loaded—the parameter list dominates without additional usage context that would help the agent.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (8 parameters, no annotations, but has output schema), the description is minimally adequate. The output schema existence means return values don't need explanation, but the description lacks behavioral context for a list operation with filtering/sorting parameters. It covers what the tool does and what parameters exist, but not how to use them effectively or when to choose this over siblings.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description provides a parameter list with brief explanations for all 8 parameters, adding significant value beyond the input schema (which has 0% description coverage). While the explanations are minimal (e.g., 'The field to sort the models by'), they give basic semantic context that the schema lacks. However, they don't provide format details, examples, or constraints (like valid values for 'logical_operator'), keeping this from a perfect score.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'List all models in the ZenML workspace.' This is a specific verb ('List') with a clear resource ('models') and scope ('ZenML workspace'). However, it doesn't distinguish this tool from its sibling 'get_model' (which retrieves a single model) or other list tools like 'list_model_versions', leaving some ambiguity about when to choose between them.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention sibling tools like 'get_model' (for single model retrieval) or 'list_model_versions' (for versions of a model), nor does it specify prerequisites or contextual constraints. The agent must infer usage from the tool name and parameters alone.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all model versions for a model.
Args:
    model_name_or_id: The name, ID or prefix of the model to retrieve
    sort_by: The field to sort the model versions by
    page: The page number to return
    size: The number of model versions to return
    logical_operator: The logical operator to use
    created: The creation date of the model versions
    updated: The last update date of the model versions
    name: The name of the model versions
    number: The number of the model versions
    stage: The stage of the model versions
    tag: The tag of the model versions
| Name | Required | Description | Default |
|---|---|---|---|
| model_name_or_id | Yes | ||
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| name | No | ||
| number | No | ||
| stage | No | ||
| tag | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden but offers minimal behavioral context. It mentions filtering/sorting parameters but doesn't explain pagination behavior, rate limits, authentication requirements, or what happens with invalid inputs. For an 11-parameter tool with no annotation coverage, this is insufficient disclosure.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is front-loaded with the core purpose but then devotes most space to a parameter list that duplicates schema information without adding meaningful context. The parameter section feels like wasted space rather than helpful elaboration, reducing overall efficiency.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (11 parameters, filtering capabilities) and absence of annotations, the description is minimally adequate but incomplete. While an output schema exists (reducing need to describe returns), the description lacks crucial context about filtering logic, pagination, and error conditions that would help an agent use it correctly.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description lists all 11 parameters with brief labels, but with 0% schema description coverage, it doesn't adequately compensate. While it names parameters like 'logical_operator' and 'stage', it doesn't explain their purpose, valid values, or how they interact. The parameter list adds some value but falls short of fully documenting semantics.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb ('List') and resource ('all model versions for a model'), making the purpose unambiguous. However, it doesn't differentiate from sibling tools like 'get_model_version' or 'list_models', which would require explicit comparison to achieve a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided on when to use this tool versus alternatives like 'get_model_version' (for a single version) or 'list_models' (for models rather than versions). The description only states what the tool does, not when it's appropriate.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all pipeline runs in the ZenML workspace.
Args:
    sort_by: The field to sort the pipeline runs by
    page: The page number to return
    size: The number of pipeline runs to return
    logical_operator: The logical operator to use
    created: The creation date of the pipeline runs
    updated: The last update date of the pipeline runs
    name: The name of the pipeline runs
    pipeline_id: The ID of the pipeline
    pipeline_name: The name of the pipeline
    stack_id: The ID of the stack
    status: The status of the pipeline runs
    start_time: The start time of the pipeline runs
    end_time: The end time of the pipeline runs
    stack: The stack of the pipeline runs
    stack_component: The stack component of the pipeline runs
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| name | No | ||
| pipeline_id | No | ||
| pipeline_name | No | ||
| stack_id | No | ||
| status | No | ||
| start_time | No | ||
| end_time | No | ||
| stack | No | ||
| stack_component | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It states the tool lists pipeline runs but doesn't describe key behaviors: whether it's read-only (implied but not explicit), how pagination works (though parameters hint at it), what the output format is (though an output schema exists), or any rate limits or permissions required. For a tool with 15 parameters and no annotations, this is inadequate.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is structured with a clear purpose statement followed by a parameter list, but it's overly verbose due to listing all parameters inline. Each parameter is described in a repetitive format, which adds bulk without enhancing clarity. While front-loaded with the purpose, the parameter section could be more concise or better integrated, making it somewhat inefficient.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity (15 parameters, no annotations, but an output schema exists), the description is partially complete. It covers the purpose and parameters but lacks behavioral context (e.g., pagination behavior, error handling) and usage guidelines. The output schema mitigates the need to explain return values, but overall, it's insufficient for a tool of this complexity without annotations.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate. It lists all 15 parameters with brief explanations (e.g., 'sort_by: The field to sort the pipeline runs by'), adding basic semantics beyond the schema's titles. However, it doesn't provide format details (e.g., date formats for 'created'), enum values (e.g., for 'status'), or usage examples, leaving gaps. This meets the baseline for adding some value but not fully compensating for the low coverage.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'List all pipeline runs in the ZenML workspace.' It specifies the verb ('List') and resource ('pipeline runs'), and the scope ('in the ZenML workspace') is helpful. However, it doesn't explicitly differentiate from sibling tools like 'get_pipeline_run' (singular) or 'list_pipelines' (pipelines vs runs), which prevents a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention sibling tools like 'get_pipeline_run' for retrieving a single run or 'list_pipelines' for listing pipelines themselves. There's no context about prerequisites, such as needing an active workspace or authentication, which is a significant gap.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all pipelines in the ZenML workspace.
By default, the pipelines are sorted by creation date in descending order.

Args:
    sort_by: The field to sort the pipelines by
    page: The page number to return
    size: The number of pipelines to return
    created: The creation date of the pipelines
    updated: The last update date of the pipelines
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| created | No | ||
| updated | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden. It discloses the default sorting behavior ('sorted by creation date in descending order'), which is valuable context. However, it doesn't mention pagination behavior, rate limits, authentication requirements, or what happens with invalid parameters, leaving gaps for a tool with 5 parameters.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is well-structured with a clear purpose statement followed by behavioral detail and parameter documentation. It's appropriately sized for a tool with 5 parameters, though the parameter explanations are minimal (single phrases) and could be slightly more informative without losing efficiency.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (5 parameters, no annotations, but with an output schema), the description is reasonably complete. It covers the purpose, default behavior, and all parameters. The existence of an output schema means return values don't need explanation, but more behavioral context (e.g., error handling) would enhance completeness.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description adds significant value beyond the input schema, which has 0% description coverage. It explicitly documents all 5 parameters (sort_by, page, size, created, updated) with brief explanations, compensating fully for the schema's lack of descriptions. This is essential for understanding what each parameter controls.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb 'List' and resource 'pipelines in the ZenML workspace', making the purpose immediately understandable. However, it doesn't differentiate from sibling tools like 'list_pipeline_runs' or 'list_models', which follow similar patterns for different resources.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided about when to use this tool versus alternatives. While sibling tools exist for listing different resources (e.g., 'list_pipeline_runs', 'list_models'), the description doesn't mention any of them or specify scenarios where this tool is preferred or inappropriate.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all projects in the ZenML workspace.
Returns JSON including pagination metadata (items, total, page, size).

Args:
    sort_by: The field to sort the projects by
    page: The page number to return
    size: The number of projects to return
    logical_operator: The logical operator to use for combining filters
    created: Filter by creation date
    updated: Filter by last update date
    name: Filter by project name
    display_name: Filter by project display name
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| name | No | ||
| display_name | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden. It discloses that the tool returns JSON with pagination metadata, which is useful behavioral context. However, it doesn't mention whether this is a read-only operation, potential rate limits, authentication requirements, or error conditions, leaving gaps in behavioral understanding.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is well-structured with a clear purpose statement followed by return value and parameter details. It's appropriately sized for an 8-parameter tool, though the parameter explanations are somewhat terse and could be more front-loaded with critical information.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity (8 parameters, no annotations, but has output schema), the description is reasonably complete. It explains the purpose, return format, and parameters. The output schema handles return values, so the description doesn't need to detail them further. However, it lacks guidance on tool selection and some behavioral aspects.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema description coverage is 0%, so the description must compensate. It lists all 8 parameters with brief explanations (e.g., 'Filter by creation date'), adding meaningful semantics beyond the bare schema. However, it doesn't provide format details (e.g., date format for 'created') or explain parameter interactions, preventing a perfect score.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb ('List') and resource ('projects in the ZenML workspace'), making the purpose specific and understandable. However, it doesn't explicitly differentiate from sibling tools like 'get_project' (singular retrieval) or 'list_artifacts' (different resource type), which prevents a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention sibling tools like 'get_project' for retrieving a single project or context about when listing is preferred over direct retrieval. Usage is implied but not explicitly stated.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all run steps in the ZenML workspace.
Args:
    sort_by: The field to sort the run steps by
    page: The page number to return
    size: The number of run steps to return
    logical_operator: The logical operator to use
    created: The creation date of the run steps
    updated: The last update date of the run steps
    name: The name of the run steps
    status: The status of the run steps
    start_time: The start time of the run steps
    end_time: The end time of the run steps
    pipeline_run_id: The ID of the pipeline run
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| name | No | ||
| status | No | ||
| start_time | No | ||
| end_time | No | ||
| pipeline_run_id | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It mentions 'List all run steps' but fails to describe key traits like pagination behavior (implied by 'page' and 'size' parameters but not explained), filtering logic (e.g., how 'logical_operator' applies), or response format. For a list tool with 11 parameters, this is a significant gap in transparency.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is front-loaded with the core purpose, but the parameter list is verbose and could be more efficiently structured (e.g., grouping related parameters). While not overly long, the formatting as a bullet-like list under 'Args:' is functional but not optimal for quick scanning, with some redundancy in parameter explanations.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity (11 parameters, no annotations) and the presence of an output schema (which reduces the need to describe return values), the description is partially complete. It covers parameters but misses behavioral context like filtering logic or pagination details. For a list tool with many filtering options, it should do more to guide usage and explain interactions.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate. It lists all 11 parameters with brief explanations (e.g., 'sort_by: The field to sort the run steps by'), adding meaningful context beyond the schema's titles. However, it lacks details on parameter interactions (e.g., how 'logical_operator' combines filters) or value formats (e.g., date strings), preventing a perfect score.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose as 'List all run steps in the ZenML workspace,' which is a specific verb ('List') and resource ('run steps') with scope ('ZenML workspace'). However, it doesn't explicitly differentiate from sibling tools like 'get_run_step' (singular) or 'list_pipeline_runs,' leaving some ambiguity about when to use each.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention sibling tools like 'get_run_step' for single steps or 'list_pipeline_runs' for broader context, nor does it specify prerequisites or exclusions, leaving the agent to infer usage from the tool name alone.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all run templates in the ZenML workspace.
⚠️ DEPRECATED: Run Templates are deprecated in ZenML. Use `list_snapshots` instead.
Snapshots are the modern replacement for run templates. To find runnable
snapshots, use `list_snapshots(runnable=True)`.

Args:
    sort_by: The field to sort the run templates by
    page: The page number to return
    size: The number of run templates to return
    created: The creation date of the run templates
    updated: The last update date of the run templates
    name: The name of the run templates
    tag: The tag of the run templates
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| created | No | ||
| updated | No | ||
| name | No | ||
| tag | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It effectively communicates the deprecation status and migration path, which is critical behavioral context. However, it doesn't mention pagination behavior, rate limits, or authentication requirements, leaving some gaps in operational transparency.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is well-structured and appropriately sized. It front-loads the purpose and critical deprecation warning, then provides parameter documentation. Every sentence serves a clear purpose with zero wasted text.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (7 parameters, no annotations, but with output schema), the description is complete enough. It covers the purpose, deprecation context, alternative tool, and parameter semantics. With an output schema present, the description appropriately doesn't need to explain return values.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate. It lists all 7 parameters with brief explanations of their purposes (e.g., 'The field to sort the run templates by', 'The page number to return'), adding meaningful semantics beyond the bare parameter names in the schema. However, it doesn't provide format details (e.g., date format for 'created') or enum values for 'sort_by'.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb ('List') and resource ('all run templates in the ZenML workspace'), making the purpose specific and unambiguous. It also distinguishes this tool from its sibling 'list_snapshots' by explicitly mentioning the deprecated nature of run templates versus snapshots.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides explicit guidance on when NOT to use this tool (due to deprecation) and names the alternative ('list_snapshots'), including specific usage instructions for the alternative ('list_snapshots(runnable=True)'). This gives clear context for tool selection.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all schedules in the ZenML workspace.
Args:
    sort_by: The field to sort the schedules by
    page: The page number to return
    size: The number of schedules to return
    created: The creation date of the schedules
    updated: The last update date of the schedules
    name: The name of the schedules
    pipeline_id: The ID of the pipeline
    orchestrator_id: The ID of the orchestrator
    active: Whether the schedule is active
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| name | No | ||
| pipeline_id | No | ||
| orchestrator_id | No | ||
| active | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It mentions listing schedules but doesn't cover critical behaviors like pagination mechanics (implied by 'page' and 'size'), rate limits, authentication requirements, or what 'all schedules' means in practice (e.g., permissions, workspace scope). The parameter list hints at filtering but lacks operational context.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is structured with a clear purpose statement followed by parameter details, but it's verbose due to listing all parameters. Each parameter line is necessary given the schema gap, but the format is repetitive. It could be more front-loaded with key usage notes before the parameter list.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (10 parameters, no annotations, but has output schema), the description is moderately complete. It covers parameters well but lacks behavioral context (e.g., pagination, filtering logic). The output schema reduces the need to explain return values, but more operational guidance would improve completeness for a list tool with many filters.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate fully. It provides a comprehensive list of all 10 parameters with brief explanations (e.g., 'sort_by: The field to sort the schedules by'), adding essential meaning beyond the bare schema. This fully addresses the coverage gap, though some details like format examples are missing.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'List all schedules in the ZenML workspace.' It specifies the verb ('List') and resource ('schedules'), making the function unambiguous. However, it doesn't differentiate from sibling tools like 'get_schedule' or other list_* tools, preventing a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention sibling tools like 'get_schedule' for retrieving a single schedule or explain when filtering via parameters is appropriate versus other list tools. Usage is implied but not explicitly stated.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all secrets in the ZenML workspace.
Args:
    sort_by: The field to sort the secrets by
    page: The page number to return
    size: The number of secrets to return
    logical_operator: The logical operator to use
    created: The creation date of the secrets
    updated: The last update date of the secrets
    name: The name of the secrets
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| name | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It states the tool lists secrets but doesn't explain key behaviors like pagination handling (implied by 'page' and 'size' parameters), sorting defaults, or whether it's a read-only operation. For a tool with 7 parameters and no annotations, this leaves significant gaps in understanding how it behaves.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is front-loaded with the main purpose in the first sentence, followed by a structured 'Args' section. It's efficient and avoids unnecessary fluff. However, the 'Args' section could be more concise by grouping related parameters or using bullet points, slightly affecting readability.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has 7 parameters, no annotations, and an output schema exists (which means return values are documented elsewhere), the description is moderately complete. It covers the purpose and parameters but lacks behavioral details (e.g., error handling, rate limits) and usage context. For a list tool with filtering capabilities, more guidance on parameter interactions would be helpful.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description includes an 'Args' section that lists all 7 parameters with brief explanations, adding meaning beyond the input schema (which has 0% description coverage). This compensates well for the schema's lack of descriptions, though it doesn't provide detailed examples or constraints (e.g., format for 'created' or 'updated'). Given the schema coverage is low, this is a strong effort.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'List all secrets in the ZenML workspace.' It specifies the verb ('List') and resource ('secrets in the ZenML workspace'), making it easy to understand what the tool does. However, it doesn't explicitly differentiate from sibling tools like 'list_artifacts' or 'list_models' beyond the resource type, which keeps it from a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention any prerequisites, such as authentication or workspace context, or compare it to other list tools (e.g., 'list_artifacts'). Without this context, users might struggle to choose the right tool for their needs.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all service connectors in the ZenML workspace.
Args:
    sort_by: The field to sort the service connectors by
    page: The page number to return
    size: The number of service connectors to return
    logical_operator: The logical operator to use
    created: The creation date of the service connectors
    updated: The last update date of the service connectors
    name: The name of the service connectors
    connector_type: The type of the service connectors
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| name | No | ||
| connector_type | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full burden. It states this is a list operation but doesn't disclose behavioral traits like pagination behavior (implied by page/size parameters but not explained), whether it's read-only (safe to assume but not stated), authentication requirements, rate limits, or what happens with empty results. The description merely restates parameter names without explaining their functional impact.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately brief with a clear purpose statement followed by a parameter list. However, the parameter section is redundant with the schema and doesn't add explanatory value, making it somewhat wasteful. The structure is front-loaded but could be more efficient by omitting the parameter enumeration or replacing it with meaningful guidance.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (8 parameters, no annotations, but with an output schema), the description is minimally adequate. The output schema likely covers return values, reducing the need for that in the description. However, for a filtering/list tool with many parameters, the description should explain how filtering works, pagination behavior, and any constraints—none of which are present.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, so the description must compensate. It lists all 8 parameter names but provides no semantic context beyond what's in the schema titles. For example, it doesn't explain what 'logical_operator' applies to, what format 'created' and 'updated' expect, or how filtering works with multiple parameters. This adds minimal value over the bare schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb ('List') and resource ('service connectors in the ZenML workspace'), making the purpose unambiguous. However, it doesn't differentiate from sibling tools like 'list_services' or 'get_service_connector' (singular), which could cause confusion about when to use this specific list tool versus others.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. With sibling tools like 'get_service_connector' (singular) and other list tools (e.g., 'list_services'), there's no indication whether this is for comprehensive listing, filtered queries, or specific use cases. The agent must infer usage from the parameter set alone.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all services in the ZenML workspace.
Args:
    sort_by: The field to sort the services by
    page: The page number to return
    size: The number of services to return
    logical_operator: The logical operator to use
    id: The ID of the services
    created: The creation date of the services
    updated: The last update date of the services
    running: Whether the service is running
    service_name: The name of the service
    pipeline_name: The name of the pipeline
    pipeline_run_id: The ID of the pipeline run
    pipeline_step_name: The name of the pipeline step
    model_version_id: The ID of the model version
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| id | No | ||
| created | No | ||
| updated | No | ||
| running | No | ||
| service_name | No | ||
| pipeline_name | No | ||
| pipeline_run_id | No | ||
| pipeline_step_name | No | ||
| model_version_id | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It only states the basic action of listing services without mentioning pagination behavior (implied by page/size parameters but not explained), rate limits, authentication requirements, or what the output contains (though an output schema exists). This leaves significant gaps for a tool with 13 parameters.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately front-loaded with the core purpose in the first sentence, but the extensive parameter list (13 items) makes it lengthy. While each parameter explanation is brief, the overall structure could be more concise by grouping related parameters or using a table format.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity (13 parameters, no annotations) and the presence of an output schema, the description is partially complete. It thoroughly documents parameters but lacks behavioral context (e.g., how filtering works with logical_operator). The output schema reduces the need to explain return values, but more guidance on usage and constraints would improve completeness.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description provides a comprehensive list of all 13 parameters with brief explanations for each (e.g., 'sort_by: The field to sort the services by'), adding substantial meaning beyond the input schema which has 0% description coverage. This fully compensates for the schema's lack of parameter documentation.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb ('List') and resource ('all services in the ZenML workspace'), providing a specific purpose. However, it doesn't distinguish this tool from other list_* siblings like list_models or list_pipelines, which would require mentioning what makes services unique in this context.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided on when to use this tool versus alternatives. While the description mentions listing services, it doesn't clarify if this is for monitoring, filtering active services, or other use cases, nor does it reference sibling tools like get_service for single-service retrieval.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all snapshots in the ZenML workspace.
Snapshots are frozen pipeline configurations that replace the deprecated
Run Templates. Use `runnable=True` to find snapshots that can be triggered.

Returns JSON including pagination metadata (items, total, page, size).

Args:
    sort_by: The field to sort the snapshots by
    page: The page number to return
    size: The number of snapshots to return
    logical_operator: The logical operator to use for combining filters
    created: Filter by creation date
    updated: Filter by last update date
    name: Filter by snapshot name
    pipeline: Filter by pipeline name or ID
    runnable: Filter to only runnable snapshots (can be triggered)
    deployable: Filter to only deployable snapshots
    deployed: Filter to only currently deployed snapshots
    tag: Filter by tag
    project: Optional project scope (defaults to active project)
    named_only: Only return named snapshots (default True to avoid internal ones)
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| name | No | ||
| pipeline | No | ||
| runnable | No | ||
| deployable | No | ||
| deployed | No | ||
| tag | No | ||
| project | No | ||
| named_only | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden and does well by disclosing key behaviors: it explains what snapshots are, mentions pagination metadata in returns, and describes the purpose of the runnable parameter. It could improve by mentioning authentication needs or rate limits, but covers essential operational context.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is well-structured with a clear purpose statement, context about snapshots, usage tip, return format, and detailed parameter explanations. While comprehensive, it's appropriately sized for a tool with 14 parameters and no schema descriptions. Some sentences could be more concise, but overall it's front-loaded with essential information.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity (14 parameters, 0% schema coverage, no annotations) and the presence of an output schema, the description is remarkably complete. It explains the tool's purpose, provides usage guidance, documents all parameters thoroughly, and mentions the return format. The output schema handles return values, so the description focuses appropriately on inputs and context.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
With 0% schema description coverage for 14 parameters, the description compensates excellently by providing a comprehensive 'Args' section that explains every parameter's purpose, including defaults and filtering logic (e.g., 'named_only: Only return named snapshots (default True to avoid internal ones)'). This adds substantial meaning beyond the bare schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the specific action ('List all snapshots') and resource ('in the ZenML workspace'), distinguishing it from sibling tools like get_snapshot (singular) and trigger_pipeline. It also explains what snapshots are ('frozen pipeline configurations that replace the deprecated Run Templates'), providing domain context.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides clear context for when to use the tool ('Use `runnable=True` to find snapshots that can be triggered'), which helps differentiate from trigger_pipeline. However, it doesn't explicitly state when NOT to use this tool or mention specific alternatives among siblings beyond the general context.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all stack components in the ZenML workspace.
Args:
    sort_by: The field to sort the stack components by
    page: The page number to return
    size: The number of stack components to return
    logical_operator: The logical operator to use
    created: The creation date of the stack components
    updated: The last update date of the stack components
    name: The name of the stack components
    flavor: The flavor of the stack components
    stack_id: The ID of the stack
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| name | No | ||
| flavor | No | ||
| stack_id | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden for behavioral disclosure. It only states the basic action ('List all stack components') without mentioning pagination behavior (implied by 'page' and 'size' parameters but not explained), rate limits, authentication requirements, or what happens with filtering parameters. This is inadequate for a tool with 9 parameters and no annotation coverage.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is appropriately sized but not optimally structured. The first sentence clearly states the purpose, but the parameter documentation could be more integrated. While efficient, some sentences in the Args section are overly terse (e.g., 'The logical operator to use' without context), suggesting room for improvement in clarity without adding bulk.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (9 parameters, no annotations, but has output schema), the description is minimally adequate. It covers the basic purpose and documents all parameters, but lacks behavioral context, usage guidance, and explanation of how filtering works. The output schema existence means return values don't need description, but other gaps remain significant.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description includes an 'Args:' section that documents all 9 parameters with brief explanations. With 0% schema description coverage, this fully compensates by providing semantic meaning for each parameter. However, it doesn't explain parameter interactions (e.g., how 'logical_operator' works with filtering parameters) or format details (e.g., date formats for 'created'/'updated'), preventing a perfect score.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'List all stack components in the ZenML workspace.' It specifies the verb ('List') and resource ('stack components'), and provides scope ('in the ZenML workspace'). However, it doesn't differentiate from sibling tools like 'get_stack_component' or 'list_stacks', which would require a 5.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention sibling tools like 'get_stack_component' (for single component retrieval) or 'list_stacks' (for listing stacks instead of components), nor does it specify prerequisites or exclusions. This leaves the agent without context for tool selection.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all stacks in the ZenML workspace.
By default, the stacks are sorted by creation date in descending order.

Args:
    sort_by: The field to sort the stacks by
    page: The page number to return
    size: The number of stacks to return
    logical_operator: The logical operator to use
    created: The creation date of the stacks
    updated: The last update date of the stacks
    name: The name of the stacks
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| name | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It mentions default sorting by creation date in descending order, which is useful, but lacks critical details: it doesn't specify whether this is a read-only operation, what permissions are required, how pagination works beyond basic parameters, or what the output format looks like (though an output schema exists). For a list operation with 7 parameters, this is insufficient.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is well-structured and appropriately sized: it starts with the core purpose, adds a key behavioral note (default sorting), and then lists parameters. There's no redundant information, and each sentence serves a clear purpose. It could be slightly more concise by integrating parameter details more seamlessly, but it's efficient overall.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (7 parameters, no annotations, but with an output schema), the description is moderately complete. It covers the basic purpose and parameters but lacks usage guidelines, detailed behavioral context, and explanations of parameter semantics. The output schema mitigates the need to describe return values, but other gaps remain significant for effective agent use.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description includes an 'Args' section listing all 7 parameters with brief labels, but schema description coverage is 0%, so the schema provides no additional documentation. The description adds basic semantic context (e.g., 'page: The page number to return'), but it doesn't explain parameter interactions, expected formats (e.g., date strings for 'created'), or valid values for fields like 'logical_operator'. This partially compensates for the schema gap but leaves significant gaps.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'List all stacks in the ZenML workspace.' It specifies the verb ('List') and resource ('stacks in the ZenML workspace'), making the function unambiguous. However, it doesn't explicitly differentiate from sibling tools like 'get_stack' or 'list_stack_components', which would be needed for a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention sibling tools like 'get_stack' (for retrieving a single stack) or 'list_stack_components', nor does it specify prerequisites or contexts for usage. This leaves the agent without clear decision-making criteria.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all tags in the ZenML workspace.
Tags enable queries like "show me all prod deployments" and help organize
resources. Exclusive tags can only be applied once per entity.

Returns JSON including pagination metadata (items, total, page, size).

Args:
    sort_by: The field to sort the tags by
    page: The page number to return
    size: The number of tags to return
    logical_operator: The logical operator to use for combining filters
    created: Filter by creation date
    updated: Filter by last update date
    name: Filter by tag name
    exclusive: Filter by exclusive tags (can only be applied once per entity)
    resource_type: Filter by resource type the tag applies to
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| name | No | ||
| exclusive | No | ||
| resource_type | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden and does well by disclosing key behavioral traits: it describes the return format ('Returns JSON including pagination metadata'), explains what exclusive tags are, and mentions filtering capabilities. However, it doesn't cover rate limits, authentication requirements, or error conditions.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is well-structured with a clear purpose statement, context about tags, return format disclosure, and organized parameter explanations. It's appropriately sized but could be slightly more front-loaded with the most critical information.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (9 parameters, no annotations, but with output schema), the description is remarkably complete. It covers purpose, context, return format, and all parameters. With an output schema present, the description appropriately doesn't need to detail return values further.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
With 0% schema description coverage, the description fully compensates by providing clear explanations for all 9 parameters in the Args section. Each parameter gets a brief but meaningful description that adds semantic understanding beyond the schema's titles and types.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the specific action ('List all tags') and resource ('in the ZenML workspace'), with additional context about what tags enable. It distinguishes from sibling 'get_tag' by indicating this lists multiple tags rather than retrieving a single one.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides clear context about when tags are useful ('enable queries like "show me all prod deployments" and help organize resources'), but doesn't explicitly state when to use this tool versus alternatives like filtering through other list tools or when not to use it.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
List all users in the ZenML workspace.
Args:
    sort_by: The field to sort the users by
    page: The page number to return
    size: The number of users to return
    logical_operator: The logical operator to use
    created: The creation date of the users
    updated: The last update date of the users
    active: Whether the user is active
| Name | Required | Description | Default |
|---|---|---|---|
| sort_by | No | desc:created | |
| page | No | ||
| size | No | ||
| logical_operator | No | and | |
| created | No | ||
| updated | No | ||
| active | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It mentions listing users but fails to describe key behaviors: whether this is a read-only operation, if it requires specific permissions, how pagination works, or what the output format is. The parameter list hints at filtering and sorting, but no explicit behavioral context is given.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is structured with a clear purpose statement followed by a parameter list, but it's somewhat verbose due to repeating parameter names without additional value. Every sentence serves a purpose, but the parameter explanations are minimal and could be more integrated. It's adequate but not optimally efficient.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (7 parameters, no annotations, but with an output schema), the description is partially complete. It covers the purpose and parameters but lacks usage guidelines, behavioral details, and output information. The presence of an output schema reduces the need to explain return values, but overall, it leaves gaps for effective agent use.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The description includes an 'Args' section that lists all 7 parameters with brief explanations, adding meaningful context beyond the input schema, which has 0% description coverage. This compensates well for the schema's lack of descriptions, though it doesn't provide detailed examples or constraints (e.g., date formats for 'created' and 'updated').
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's purpose: 'List all users in the ZenML workspace.' It specifies the verb ('List') and resource ('users in the ZenML workspace'), making the function unambiguous. However, it doesn't differentiate from sibling tools like 'get_user' or other list_* tools, which prevents a perfect score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. There's no mention of sibling tools like 'get_user' for retrieving a single user or other list_* tools for different resources. It lacks context about prerequisites, such as authentication or workspace access, leaving usage unclear.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Trigger a pipeline to run from the server.
Args:
    pipeline_name_or_id: The name or ID of the pipeline to trigger
    snapshot_name_or_id: The name or ID of a specific snapshot to run (preferred)
    stack_name_or_id: Optional stack override for the run
    template_id: ⚠️ DEPRECATED - Use `snapshot_name_or_id` instead.
        The ID of a run template to use. Run Templates are deprecated
        and will be removed in a future version.

Usage examples:
    * Run the latest runnable snapshot for a pipeline:
    ```python
    trigger_pipeline(pipeline_name_or_id=<NAME>)
    ```
    * Run the latest runnable snapshot for a pipeline on a specific stack:
    ```python
    trigger_pipeline(
        pipeline_name_or_id=<NAME>,
        stack_name_or_id=<STACK_NAME_OR_ID>
    )
    ```
    * Run a specific snapshot (RECOMMENDED):
    ```python
    trigger_pipeline(
        pipeline_name_or_id=<NAME>,
        snapshot_name_or_id=<SNAPSHOT_NAME_OR_ID>
    )
    ```
    * Run a specific template (DEPRECATED - use snapshot_name_or_id instead):
    ```python
    trigger_pipeline(pipeline_name_or_id=<NAME>, template_id=<ID>)
    ```
| Name | Required | Description | Default |
|---|---|---|---|
| pipeline_name_or_id | Yes | ||
| snapshot_name_or_id | No | ||
| stack_name_or_id | No | ||
| template_id | No |
| Name | Required | Description |
|---|---|---|
| result | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries full burden and does well by indicating this triggers an execution ('run from the server'), implying it's a write/mutation operation. It provides important behavioral context about deprecation (template_id) and preferred parameters (snapshot_name_or_id). However, it doesn't mention potential side effects like resource consumption, permissions needed, or what happens if a pipeline is already running.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is efficiently structured with clear sections: purpose statement, args explanation with semantic details, and comprehensive usage examples. Every sentence adds value - the deprecation warning is necessary, and the examples demonstrate different scenarios without redundancy. The information is front-loaded with the core purpose first.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a 4-parameter mutation tool with no annotations but with an output schema, the description provides excellent parameter semantics and usage guidance. It covers the essential 'what' and 'how' but could benefit from mentioning behavioral aspects like error conditions, permissions, or what the output contains. The existence of an output schema reduces the need to describe return values, but some operational context is still missing.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
With 0% schema description coverage, the description fully compensates by explaining all 4 parameters in detail. It clarifies that pipeline_name_or_id is required, explains the purpose of each optional parameter, provides deprecation context for template_id, and distinguishes between name vs. ID usage. The usage examples demonstrate practical parameter combinations.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the specific action ('Trigger a pipeline to run from the server') with the resource ('pipeline'), distinguishing it from sibling tools like get_pipeline_details or list_pipelines which are read-only operations. The verb 'trigger' is precise and indicates an execution action rather than retrieval.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides explicit guidance on when to use different parameter combinations through detailed usage examples, including a recommended approach ('Run a specific snapshot (RECOMMENDED)') and clear deprecation warnings ('⚠️ DEPRECATED - Use `snapshot_name_or_id` instead'). It distinguishes between running latest vs. specific snapshots and when to use stack overrides.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
v1.2.0easter_eggget_active_projectget_active_userget_buildget_deploymentget_deployment_logsget_flavorget_modelget_model_versionget_pipeline_detailsget_pipeline_runget_projectget_run_stepget_run_templateget_scheduleget_serviceget_service_connectorget_snapshotget_stackget_stack_componentget_step_codeget_step_logsget_tagget_userlist_artifactslist_buildslist_deploymentslist_flavorslist_model_versionslist_modelslist_pipeline_runslist_pipelineslist_projectslist_run_stepslist_run_templateslist_scheduleslist_secretslist_service_connectorslist_serviceslist_snapshotslist_stack_componentslist_stackslist_tagslist_userstrigger_pipelineScored across 45 tools
Most tools have distinct purposes targeting specific ZenML entities (e.g., get_build vs get_deployment vs get_model), with clear boundaries between different resource types. However, some potential confusion exists between related tools like get_pipeline_details and get_pipeline_run, and between get_run_template (deprecated) and get_snapshot, though descriptions help clarify these relationships.
The naming follows a highly consistent verb_noun pattern throughout all 45 tools, using get_*, list_*, and trigger_* prefixes. All tools use snake_case consistently, with no mixing of conventions or inconsistent verb styles, making the tool set predictable and readable.
With 45 tools, this is an extremely large tool set that feels heavy and overwhelming for an MCP server. While ZenML is a complex platform, this many tools will likely cause confusion and selection paralysis for agents, exceeding the recommended scope of 3-15 tools for good coherence.
The tool surface provides comprehensive coverage of the ZenML domain with complete CRUD/lifecycle operations for all major entities (pipelines, deployments, models, stacks, etc.). It includes both read operations (get_*, list_*) and action operations (trigger_pipeline), with no obvious gaps for core workflows, though some deprecated tools exist alongside their replacements.
A Model Context Protocol server for Wix AI tools
Enable secure connectivity between Sentry issues and debugging data, and LLM clients, using a Model Context Protocol (MCP) server.
A comprehensive Model Context Protocol (MCP) server that enables AI assistants to interact with yo…
Model Context Protocol server for the Apideck Unified API. Connect any MCP-compatible agent framework to 100+ accounting systems, HRIS platforms, file storage providers, and more through one integration. More information https://www.apideck.com/mcp-server