Longhand
Longhand is a persistent local memory server for Claude Code that indexes all past sessions into a searchable SQLite + ChromaDB store, enabling semantic recall, file replay, and git history queries — all with zero API calls and full local privacy.
Semantic Search — Search across all session events using natural language, with filters for event type, session, project, tool name, or file path.
Contextual Search — Find specific discussions within a session and retrieve them with surrounding conversation context.
Session Listing & Timeline — List recent sessions and browse chronological event timelines with pagination, tail support, and summary-only mode.
Latest Events — Retrieve the most recent events in reverse chronological order, optionally filtered by type.
File History & Replay — View every edit made to a file across all sessions and deterministically reconstruct its exact state at any past point.
Fuzzy Recall — Answer "do you remember..." questions with fuzzy time references and project matching, returning episodes, diffs, thinking blocks, and a prebuilt narrative in one call.
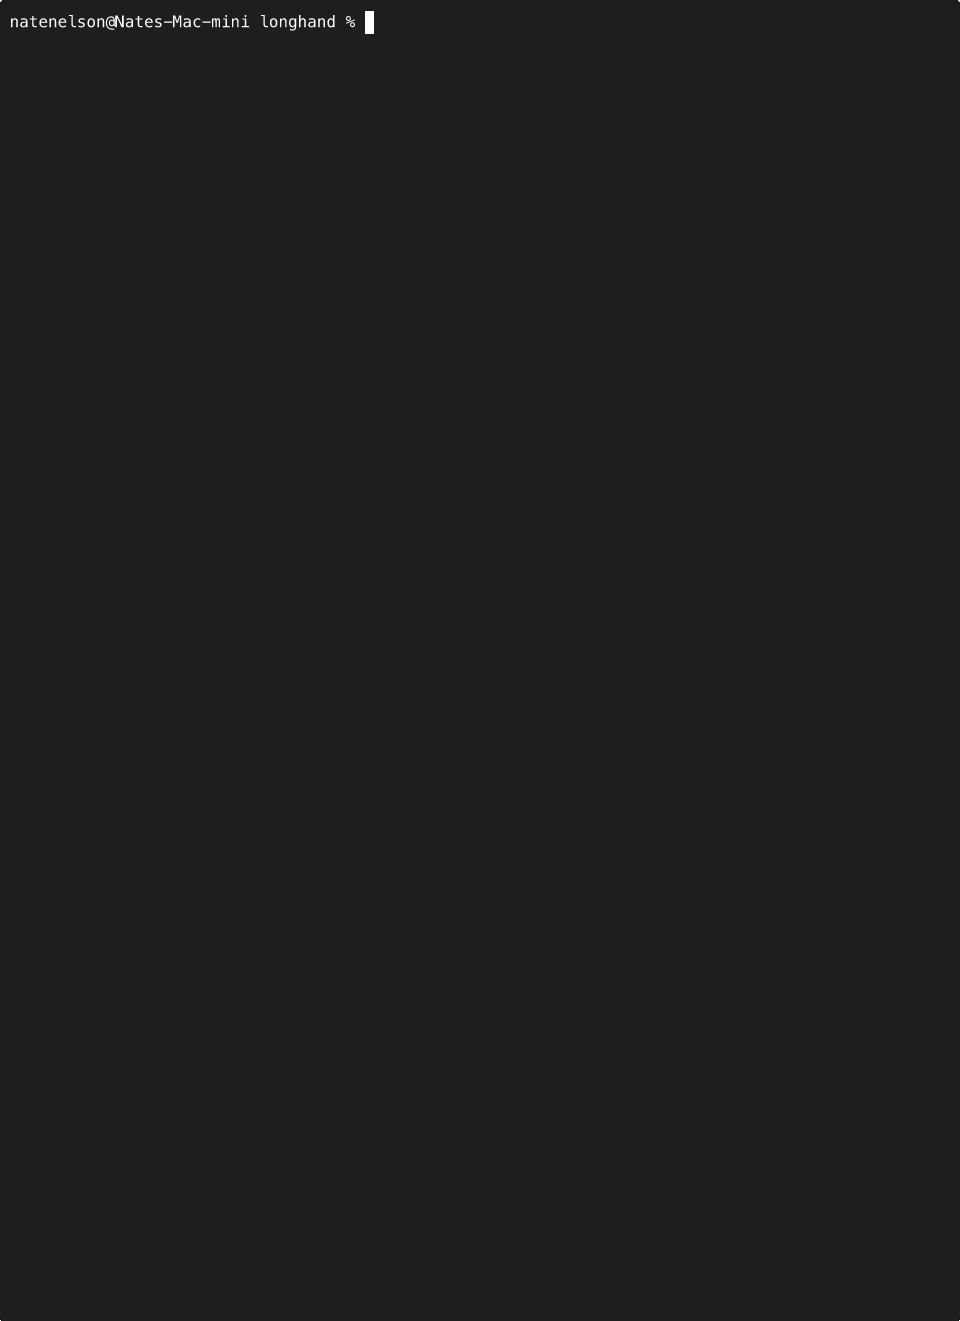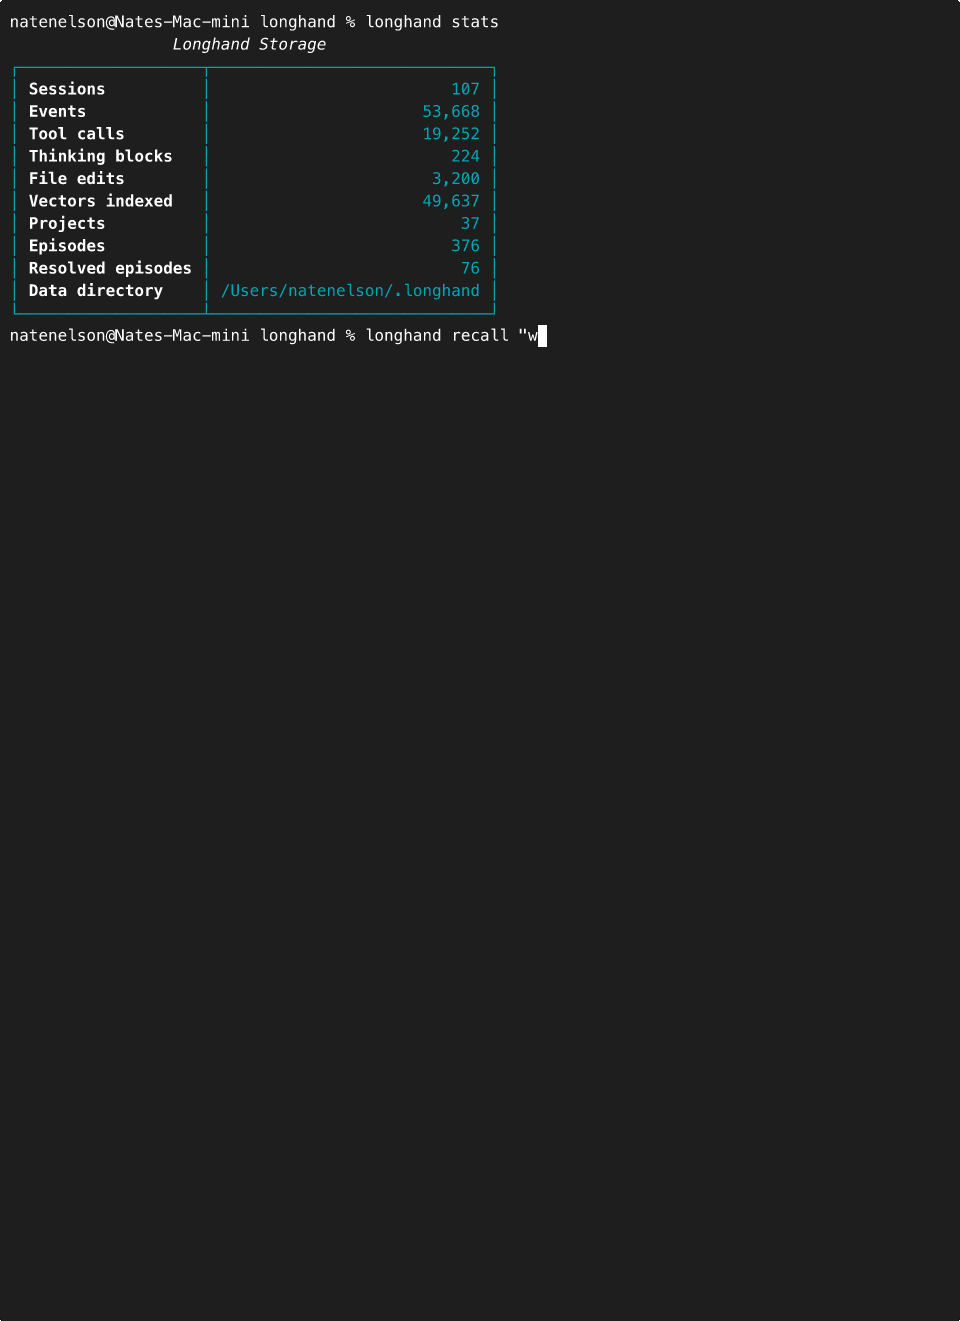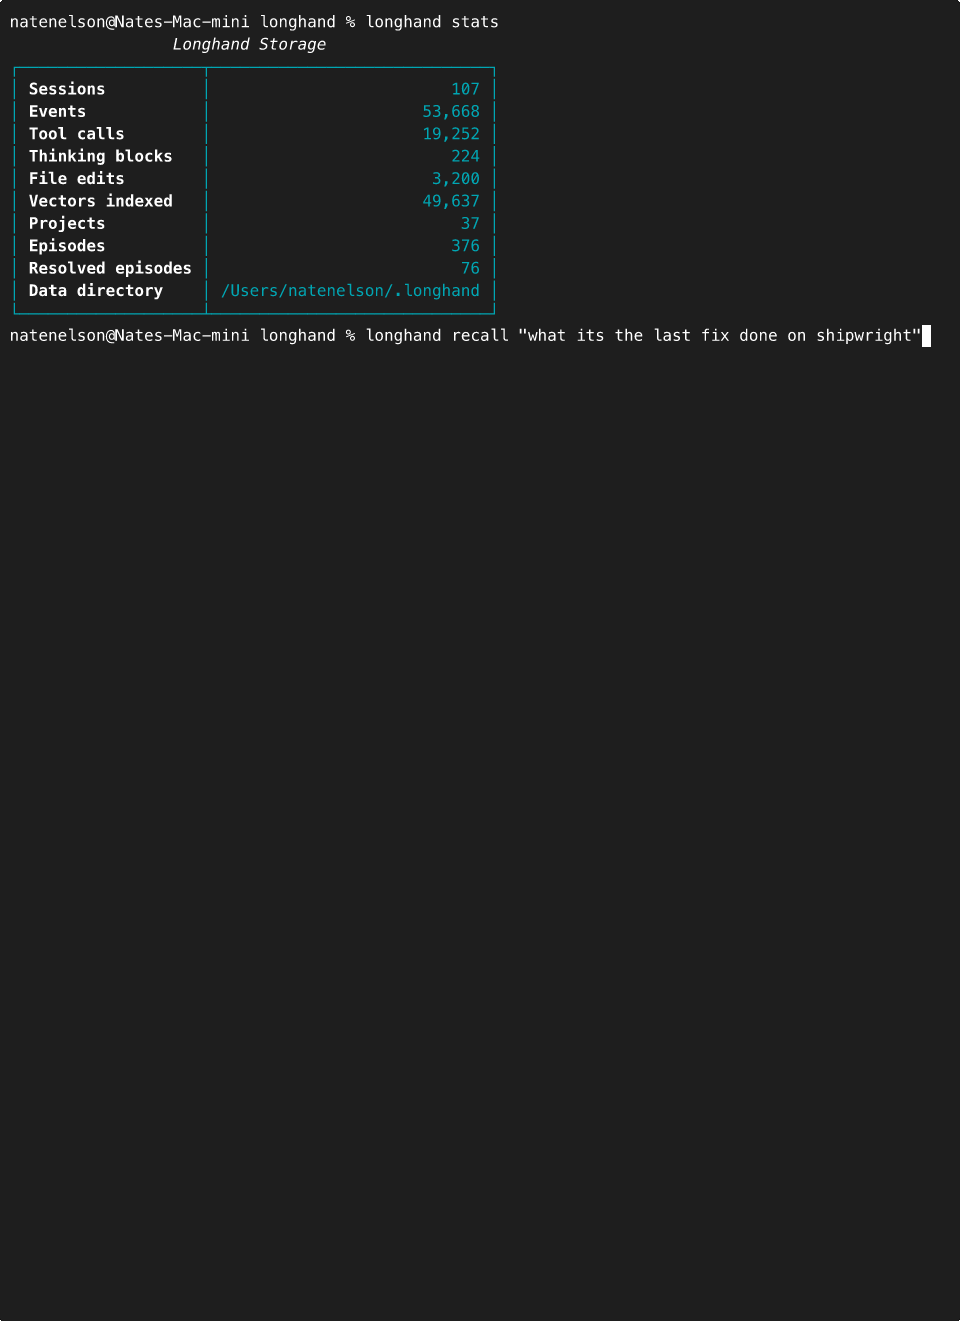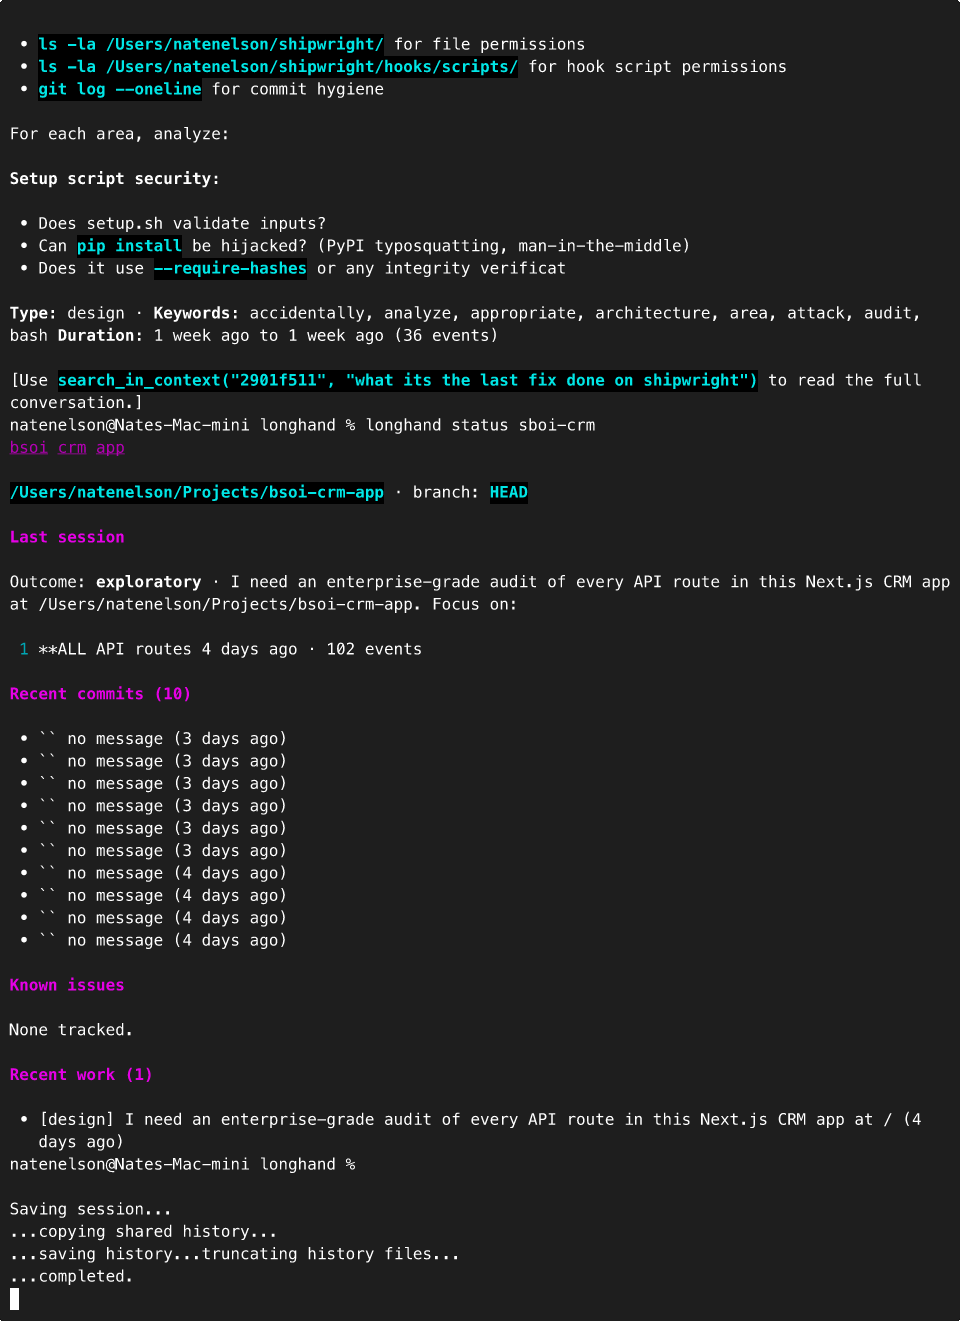
Project Status — Get a structured "where we left off" summary including recent commits, unresolved issues, episodes, and conversation context.
Project Management — Browse inferred projects by keyword/category/recency, fuzzy-match partial project names, and view session-level project timelines with outcomes (shipped/fixed/stuck/exploratory).
Episode Search & Detail — Find structured problem→fix episodes with filters, and retrieve full episode details including diagnosis thinking blocks, fix diffs, and reconstructed file states.
Git Integration — Search git operations (commits, pushes, merges, checkouts) across sessions by message, hash, or branch, or retrieve all git ops from a specific session.
Thinking Block Retrieval — Access Claude's verbatim thinking blocks as first-class events.
Storage Statistics — Get overall archive metrics (sessions, events, vectors, etc.).
Automatic Ingestion & Context Injection — Automatically ingest sessions when they end and optionally inject relevant past context into new prompts.
Tracks and searches git operations (commits, pushes, merges) performed during Claude Code sessions, linking session work to git history for finding specific fixes or changes.
References GitHub as the platform hosting the Longhand project and related tools like claude-mem, though the MCP server itself operates locally on Claude Code session data.
Mentioned as an example use case for recalling past work (e.g., 'that stripe webhook bug from last week'), demonstrating the server's ability to find specific fixes or discussions related to Stripe integrations.
Longhand
Using Codex too? Share one memory archive between Claude Code and Codex.
Persistent local memory for Claude Code. Every tool call, every file edit, every thinking block from every Claude Code session — stored verbatim on your machine. Searchable, replayable, and recallable by fuzzy natural-language questions. Zero API calls. Zero summaries. Zero decisions made by an AI about what's worth remembering.
Claude Code quietly rotates your session files after a few weeks. Longhand captures them into SQLite before they're gone. Once ingested, your history stays forever — even after the source JSONL files are deleted. Install early; the past you don't capture is unrecoverable.
If you have 20+ Claude Code sessions in
~/.claude/projects/, Longhand can search across every fix, decision, and conversation you've had in ~56ms — without a single API call.
Does it use a lot of tokens? No — every tool is capped by design. A full
recallacross 100+ sessions returns ~4K tokens. Reading one raw session JSONL costs 10–50× more. See Token budget.
pip install longhand
longhand setup # ingest history + install hooks + configure MCP
longhand recall "that stripe webhook bug from last week"Want to kick the tires first? Run longhand demo for a 60-second walkthrough on a fake 3-session sample corpus — your real ~/.claude and ~/.longhand are not touched. The demo seeds a sandboxed store with a Stripe-webhook bug + Supabase auth migration + downstream 401 fix, then runs cross-session recall and project-status so you can see what the output looks like before committing.
pip install longhand
longhand demo # sandboxed; cleans up afterwards (pass --keep to explore)Upgrading to 1.0.0? This is the release that closes the deprecation window 0.13 opened. Everything removed here has been warning since 0.13.0:
Four CLI aliases are gone:
patterns→recall "<topic>",recap→status --days N,continue→status --session <prefix>,reanalyze→analyze --all.The
reconcileMCP tool now defaults to a dry run. If you have an agent loop that relied on the implicit heal, passfix=trueexplicitly. Dry runs tell you so in the payload.Six retired MCP tools left the listing (19 → 13) but still answer forever with a migration note — retired names live in users' own
CLAUDE.mdfiles and must never hard-fail.New: COMPATIBILITY.md states what 1.x guarantees and what it doesn't.
Your database needs nothing. Migrations are automatic and a 0.11+ store opens on any later 1.x — that's Promise 2, and there's a real 0.11-schema fixture in the test suite proving it.
Upgrading to 0.13.0? Nothing breaks — that release opened the v1.0 deprecation window, so every old name kept working while pointing at its replacement:
statusis now the single resume command: barestatus= recent digest (wasrecap),status <project>unchanged,status --session <prefix>= session tail (wascontinue). The old commands still run and print a pointer; they're removed at v1.0.Six MCP tools folded into six survivors with identical parameters (
search_in_context→search+context_events,get_episode→find_episodes+episode_id, etc. — full table in the CHANGELOG). The retired names still answer, prefixed with a migration note.Hooks can no longer exit nonzero — failures become breadcrumbs in
~/.longhand/logs/and two newdoctorrows (Hook errors,Transcript format) keep them visible."Today"/"yesterday" recall windows now follow your local calendar day instead of UTC's; rankings may shift once if you're not in UTC.
Windows users: this release fixes a serious bug where the ingest-lock liveness check could terminate other longhand processes.
New:
LONGHAND_DATA_DIRrelocates the store for the CLI, hooks, and MCP server in one move;status --json/doctor --jsonfor scripting.
Upgrading to 0.9.0? Live ingestion captures sessions in flight, plan history is preserved as first-class data, and an optional reconciler job keeps the index honest in the background:
New
longhand ingest-livecommand runs from Claude Code'sStophook to tail the active transcript between assistant turns. Sessions show up inrecallwhile you're still working, not after they end.New
longhand plans listcommand andlist_plansMCP tool surface every Write/Edit to~/.claude/plans/*.mdacross your entire history. Plans are now extracted as their own entity alongside episodes.New
longhand schedule install-reconcilerinstalls an optional launchd job that runsreconcile --fixperiodically — catches anything the live and post-session hooks missed without you ever thinking about it.The Stop hook coexists with the existing SessionEnd hook: live tails the transcript as it grows; SessionEnd does the full analysis pass when the session closes.
Upgrading to 0.8.1? Staleness signals now propagate everywhere they belong, and reconcile is an MCP tool — Claude can self-heal the index from inside a session:
searchandlist_sessionsnow wrap the response withstale: true+stale_reasonwhen the project they're scoped to has on-disk transcripts not yet ingested. Pre-v0.8.1 these returned clean-looking empty results (same silent-failure shaperecall_project_statuswas built to catch — just one layer up).New
reconcileMCP tool wrapslonghand reconcile --fix. After a staleness banner fires, Claude callsreconciledirectly instead of asking the user to run a CLI command.list_sessionsdefaultlimitraised from 20 to 50 — active days routinely cross 5+ projects across 5+ sessions; the old default truncated reviews silently.
Upgrading from 0.7.x or earlier? Cleaner recall narratives, plus a real bug-finding test layer underneath (from 0.8.0):
Pre-v0.8
_compose_fix_summaryprepended a literal"Intent:"label to half of all extracted episodes (49% of the reference corpus). The label leaked into every recall narrative for those episodes. Migration v4 strips it from existing rows on first store open — no command needed.Diff content in
fix_summarynow truncates at whitespace boundaries with a visible…, instead of landing mid-token (phoneNum',family?:',strin'). Forward-only.Narrative footer "Other matches" lines now include the session id so you can drill in.
New canary harness (
tests/fixtures/corpus/) anchors regression tests to real shipped bugs. New recall validator (scripts/recall_diff.py) snapshots and diffs ranking results against your live corpus — catches regressions pytest can't see.
pip install --upgrade longhand
longhand recall "..." # migration runs transparently on first openIf you're also coming from 0.5.x, run longhand reconcile --fix once to re-attribute multi-project sessions per the v0.6 inference improvements (cd-into-project sessions now attribute to the project where most work happened, not the first-event cwd). If you're on 0.5.8 or earlier, chain them: longhand reconcile --fix && longhand analyze --all. Both are idempotent.
Large history? (>1 GB of ~/.claude/projects) Expect the first-time backfill to take 10–30 minutes on an M-class Mac — most of that wall time is the embedding model running on all your cores (which is why you'll see triple-digit CPU%; that's ONNX doing its job, not a hang). To get a working store faster, use the fast-path:
longhand setup --skip-analysis # SQLite only; works in ~1 min for multi-GB corpora
longhand analyze --all # fill in episodes + vectors whenever, safe to backgroundExact-text search, timelines, file history, and commit lookup all work after --skip-analysis. Semantic recall needs the analyze --all pass to complete. Typical throughput on an M-class Mac is ~1–2 sessions/sec for full analysis.
Status: v1.2.0 — stable, daily-driver tested, security-audited (zero critical findings), on PyPI, available as a Claude Code plugin. Validated against 433 real Claude Code sessions across 37 inferred projects (measured 2026-08-12). 588 unit tests passing.
Full docs: Longhand Wiki — getting started, CLI reference, MCP tools reference, architecture, and troubleshooting.
The Inversion
Everyone is solving AI memory by making the context window bigger. 1M tokens. 2M tokens. Context-infinite. The whole industry is racing in the same direction: make the model carry more state.
Longhand goes the other direction. The model doesn't need to carry the memory. The disk does.
Bigger context windows | Longhand | |
Where it lives | Rented from a model provider | A SQLite file + ChromaDB on your laptop |
Cost per query | Tokens × dollars | Zero |
Privacy | Goes through someone else's servers | Never leaves your machine |
Speed | Seconds to minutes for large contexts | ~56ms search · ~1.4s full recall |
Loss | Attention degrades in the middle of long contexts | Every event from the source file, nothing dropped |
Persistence | Dies when the window closes | Lives until you delete the file |
Across model versions | Doesn't transfer | Same data, any model |
Offline | No | Yes |
Scales with | Provider's pricing | Your hard drive |
The "memory crisis" in AI was an artificial constraint. Storage is solved. SQLite is from 2000. ChromaDB is two years old. Both run on a laptop. Longhand bypasses the crisis by ignoring it — your past sessions are already on disk, written by Claude Code itself, in JSONL files that contain every single event verbatim. Longhand reads those files, indexes them locally, and gives you semantic recall over your entire history without ever sending a token through someone else's API.
Local. Complete. Yours.
Storage footprint: ~5GB for a heavy power user (430+ sessions, 195k+ events, months of daily Opus usage across 37 inferred projects). Typical users: 200–400MB. Once Claude Code rotates the source files off disk, Longhand isn't a duplicate — it's the only copy.
Related MCP server: ClaudeX
Platform support
Python 3.10 – 3.14 are all fully supported and gated in CI — every release must pass the full suite on all five before it can merge.
Longhand pins chromadb<1.0 for every Python version, not just 3.14. The pin originated with chromadb's newer Rust bindings segfaulting on 3.14 (#4, now closed), and it stays until a 1.x chromadb is verified across the whole matrix.
Windows: CI-tested, best-effort. A windows-latest × py3.12 leg runs on every PR and has gone green on every run since v0.13.0, but it is non-blocking and covers one Python version on GitHub's runners. That is honest evidence, not a support tier — Linux and macOS are the tested platforms. Windows bugs are welcome as issues; they just aren't release-blocking.
Codex Desktop and Codex CLI threads are captured into the same archive from 1.1.0 — see Works with Codex.
Compatibility
Longhand 1.0 makes five promises, each backed by an enforcement artifact in the repo. The full text is in COMPATIBILITY.md; the short version:
Stable surface — CLI and MCP frozen through 1.x. Removals only at a major version, and only after warning for one full minor.
Forward data compat — a database written by 0.11+ opens on any later 1.x. Migrations are automatic, one-time, never renumbered. Older code refuses a newer database loudly rather than operating blind.
Hook guarantees — hooks never raise, never touch the network, never block your prompt.
Upstream drift is never silent — unknown transcript entries are preserved, surfaced in
doctor, and regression-gated.Honest metrics — counts reflect real signals, and
doctornever recommends a remedy that cannot work.
Deprecation policy: anything slated for removal warns for at least one full minor release first, and the warning names its replacement. Retired MCP tool names are the one thing that never goes away — they leave the tool listing but keep answering forever with a migration note, because those names live in users' own CLAUDE.md files.
Longhand vs claude-mem
thedotmack/claude-mem is the most popular Claude Code memory tool on GitHub (55k+ stars). It's a good tool. It is also solving the memory problem in the opposite direction from Longhand, and the difference is worth understanding before you pick one.
claude-mem | Longhand | |
What's stored | AI-generated summaries / "observations" | Verbatim events from the raw JSONL |
Who decides what's kept | An LLM, at write time | Nobody — everything is kept |
Compression | Semantic (lossy, by design) | None (lossless) |
API calls per session | One or more (calls Claude to summarize) | Zero |
Thinking blocks | Typically folded into summaries | First-class, stored verbatim |
Deterministic replay | No — summaries can't reconstruct file state | Yes — every diff kept and replayable |
Model portability | Tied to the summarizer's output | Same data works across any model, forever |
Runtime | TypeScript, Bun, HTTP worker on :37777 | Python, no server |
License | AGPL-3.0 | MIT |
The philosophical split: claude-mem asks an AI what was important and keeps that. Longhand keeps the actual bytes and lets you decide later. If you trust a model's judgment about its own past, claude-mem's approach is cheaper at query time (pre-summarized) and easier on storage. If you've ever been burned by a summary that dropped the thing that turned out to matter, Longhand is the tool that never throws anything away.
Both can coexist on the same machine — they operate on the same JSONL files without interfering.
The Principles
Longhand is built on a handful of principles. If you disagree with them, you probably want a different tool.
1. Information doesn't disappear — it moves.
When data goes "missing" it's almost never actually gone. It got compressed, summarized, filed somewhere else, or renamed. Find the raw source and the truth is still there waiting. Claude Code already writes every session to disk as JSONL. That file is the raw source. Longhand just reads it.
2. Summarization is a lossy decision disguised as a convenience.
Most AI memory systems read a conversation and ask the AI to write down "what mattered." The AI is now the gatekeeper of its own memory, and the AI has incentives — brevity, confidence, coherence — that aren't the same as truth. You end up with a story about what happened instead of what happened.
Longhand never summarizes. It stores the complete record and lets you query it.
3. The raw record is cheap. Acting like it isn't wastes it.
A full Claude Code JSONL file is kilobytes to low megabytes. A year of daily sessions is hundreds of megabytes. That is nothing on modern hardware. There is no engineering reason to throw the data away. Summary-based memory isn't saving space — it's giving away information that was free.
4. The thinking is the most valuable part.
When Claude produces a thinking block, that's the reasoning behind the decision — usually invisible to the user, almost always more useful than the final answer. Summary-based memory throws thinking blocks away because they're "internal." Longhand treats them as first-class events. "What was I thinking when I chose to use a conditional update?" pulls the verbatim thinking block that contains the answer.
5. A fix you can't reproduce is a fix you didn't keep.
If you fixed a bug in March, the state of that file when the bug was fixed is a fact. Longhand reconstructs it deterministically by applying every edit in sequence from the session JSONL. No guessing, no AI inference, just literal application of the diffs. You can see the exact state of any file at any point in any past session.
6. Memory should be proactive, not just searchable.
A searchable archive is useful but passive. Real memory answers fuzzy questions. "A couple months ago I was building a game that kept breaking, then you fixed it — bring that fix forward." Longhand parses the time phrase, matches the project, finds the problem→fix episode, and returns the diff. You don't have to know the session ID. You just have to remember that it happened.
7. Deterministic beats clever.
Everything in Longhand's analysis is rules-based. Regex error detection. Hash-based project IDs. Forward-walking episode extraction. No LLMs in the core pipeline. That means fast (< 200ms recall queries), reproducible (same input → same output), and fully local (no API keys, no cloud). An LLM layer could go on top later, but the foundation runs on laws, not on a model's opinion.
8. Local or nothing.
Your Claude Code history is yours. It goes into a SQLite file and a ChromaDB directory in ~/.longhand/. No telemetry. No sync. No account. If your laptop is offline, Longhand works. If Anthropic goes down, Longhand works. If you delete the directory, it's gone.
One boring exception, disclosed in full: the interactive CLI checks pypi.org for a newer Longhand version at most once a day. That request carries nothing but itself — no telemetry, no identifiers, nothing about your corpus — and a newer version just shows up as a dim one-line hint and a doctor row. It never runs from hooks or the MCP server, never blocks a command, and LONGHAND_NO_UPDATE_CHECK=1 turns it off entirely. "Zero API calls" means what it always meant: no LLM or cloud service ever touches your data.
What It Actually Does
When you use Claude Code, every session writes a JSONL file to ~/.claude/projects/<project>/<session-id>.jsonl. That file contains every message, every tool call, every thinking block, every file edit with full before/after content, and a millisecond-precise timestamp for each event.
Longhand reads those files. Then it gives you:
Semantic search across every event you've ever generated
Filterable search — by tool, file, session, project, time range, event type — all filters combinable
Tool call archaeology — "show me every Bash command I ran in March that touched Supabase"
File history across sessions — every edit to a specific file, chronologically, across all your sessions
Session replay — reconstruct any file's state at any point in any past session
Reasoning retrieval — query Claude's verbatim thinking blocks
Timeline view — chronological playback with pagination (offset, tail, summary-only scan mode)
Fuzzy recall — natural-language questions about past work ("that race condition fix from last week")
Project inference — automatic detection of which projects you've worked on, with categories and aliases
Episode extraction — automatic detection of problem→fix sequences in your sessions
Conversation segments — topic-level clustering (stories, design discussions, debugging, planning) so recall finds the why, not just the what
Git-aware project recall — ask "where did we leave off on X" and get recent commits, unresolved issues, last session outcome in one call
Git commit extraction — structured extraction of every git commit, push, merge, checkout from sessions, linked to episodes
MCP server — 13 tools that let Claude query Longhand directly during live conversations
Auto-ingest hook — drops into Claude Code's
SessionEndhook so new sessions are indexed automaticallyLive ingestion — optional
Stophook tails the active transcript between turns so in-flight sessions show up inrecallimmediatelyPlan history — every Write/Edit to
~/.claude/plans/*.mdis captured as a first-class entity, queryable vialonghand plans listand thelist_plansMCP toolSecret redaction (opt-in) —
longhand config --set redact.enabled=truemasks secret-shaped strings (API keys, tokens, JWTs, DB passwords) at ingest before they reach the index;longhand redact --applyretroactively masks data ingested earlierBackground reconciler — optional launchd job (
longhand schedule install-reconciler) keeps the index honest without manualreconcile --fixrunsContext injection —
UserPromptSubmithook auto-injects relevant past context before Claude sees your message (configurable threshold and size cap)Configurable —
longhand configto tune injection relevance, token budget, and behavior without editing code
Install
pip install longhand
longhand setupThat's it. longhand setup backfills your existing Claude Code history, installs the hooks that keep it updated automatically, registers Longhand as an MCP server for Claude Code, and verifies everything works. About two minutes the first time, zero maintenance after that.
To upgrade later: pip install -U longhand.
Developer install (from source)
git clone https://github.com/Wynelson94/longhand.git
cd longhand
pip install -e .
longhand setuplonghand ingest # ingest all your existing Claude Code history
longhand analyze --all # run analysis (projects, outcomes, episodes, segments)
longhand hook install # wires both SessionEnd and Stop hooks
longhand ingest-live # live-tail the active transcript (Stop hook calls this)
longhand prompt-hook install # (optional) auto-inject past context into new prompts
longhand mcp install # let Claude Code call Longhand as MCP tools
longhand schedule install-reconciler # (optional) launchd job to run reconcile --fix periodically
longhand config # view/tune hook behavior (relevance threshold, injection size)
longhand doctor # verify everything is wired upQuick Start
# What's in the archive?
longhand stats
longhand sessions
longhand projects
# Daily-use commands — status is the single resume command (git-status shape)
longhand status # what have I been up to (recent digest)
longhand status --days 30 -p bsoi # filtered digest
longhand status <project-name> # where did we leave off on a project (git-aware)
longhand status --session <session-id> # pick up where a session left off
longhand history src/app/route.ts # every edit ever to a file
# (recap / continue / patterns / reanalyze were deprecated aliases through
# 0.13 and were removed at 1.0 — use status, recall, and analyze --all)
# Semantic search
longhand search "race condition"
longhand search "stripe webhook" --tool Edit
longhand search "why did we" --type assistant_thinking
# Proactive recall (the fun one)
longhand recall "that clerk type error I fixed a couple weeks ago"
longhand recall "the python missing module bug last month"
# Session inspection
longhand timeline <session-id-prefix>
longhand replay <session-id> /path/to/file.ts
longhand diff <event-id>
# Git history
longhand git-log # recent git operations across all sessions
longhand git-log <session-id> # git ops in a specific session
longhand git-log --type commit # only commits
longhand git-log --query "fix parser" # search commit messages
# Export
longhand export latest-fix # most recent resolved episode
longhand export ep_<id> --out fix.md # specific episode to file
longhand export <session-id-prefix> # full session timeline
# Configuration
longhand config # show current hook settings
longhand config --set hook.min_relevance=3.0 # tune injection threshold
longhand config --set hook.max_inject_chars=1000 # cap token usage
# Plans + background maintenance
longhand plans list # every plan-mode plan you've written
longhand plans list --limit 100 # raise the row cap (default 50)
longhand schedule install-reconciler # background launchd job; runs reconcile --fixSession IDs accept prefix matches — longhand timeline cf86 is enough if only one session starts with that.
Recall Example
$ longhand recall "that stripe webhook I was fixing"
╭─ Project matches ───────────────────────────────────────╮
│ new-product (nextjs web app) · alias: 'stripe' · 1.52 │
╰─────────────────────────────────────────────────────────╯
Found it: new-product · 2 weeks ago · session a4ba29d1
### What went wrong
Type error: Property 'current_period_end' does not exist on type 'Subscription'.
### How it was diagnosedIn Stripe's type definitions, current_period_end moved off the Subscription interface. It's still on the actual API payload but the types don't expose it. We need to cast through Record<string, unknown> to access it.
### The fix
Edit on route.ts: 'const periodEnd = sub.current_period_end' → 'const periodEnd
= (sub as Stripe.Subscription & Record<string, any>).current_period_end as number'
Diff:
- const periodEnd = sub.current_period_end
+ const periodEnd = (sub as Stripe.Subscription & Record<string, any>).current_period_end as number
✓ Verified — a test passed after the fix.
Other candidates (4)
• 2 weeks ago: Type error: Module '"@/lib/utils"' has no exported member 'getInitials'.
• 2 weeks ago: Type error: Property 'role' does not exist on type 'User'.That's one local command. No API call. The fix came from a session file Claude Code wrote to your disk weeks ago and Longhand had been waiting with the answer the whole time.
MCP Integration (Claude Desktop)
Run longhand mcp install to wire Longhand into Claude Desktop's config. After you restart Claude Desktop, it has thirteen tools:
Core (searchable archive):
search— semantic search with session, project, tool, file, and event_type filters (all combinable); passcontext_eventswith asession_idto get each match wrapped in its surrounding conversationlist_sessions— recent sessions with project/time filters; passproject_id(plus optionalsince/until) for a project's outcome-enriched session timelineget_session_timeline— chronological view with offset/tail pagination and summary-only scan mode (tail: Ncovers "the latest events / how did it end")replay_file— reconstruct file state at a point in timeget_file_history— every edit to a file across all sessionsget_stats— storage statistics
Proactive memory:
recall— fuzzy natural-language recall (use this first): a narrative built from conversation segments and session timelines, with high-precision problem→fix episodes when the work left clean evidencerecall_project_status— "where did we leave off on X?" — git-aware project summary with commits, issues, last outcomefind_episodes— structured search for problem→fix pairs; passepisode_idfor full detail on one episode (referenced events, diff, post-fix file state)list_projects— browse inferred projects; passmatchfor fuzzy candidates with scored reasonslist_plans— every Write/Edit to~/.claude/plans/*.mdacross your entire history
Git history:
find_commits— search across all sessions by commit message, hash prefix, or branch name; or pass asession_idwithout a query for one session's chronological git story
Self-healing:
reconcile— wrapslonghand reconcileso Claude can re-attribute and re-ingest from inside a session after a staleness banner; passfixexplicitly (the implicit default flips to dry-run at v1.0)
Deprecated (still answer through 0.x, with a migration preamble; leave the listing at v1.0): search_in_context → search(context_events) · get_latest_events → get_session_timeline(tail) · get_project_timeline → list_sessions(project_id) · get_session_commits → find_commits(session_id) · get_episode → find_episodes(episode_id) · match_project → list_projects(match)
All tools support max_chars output capping with pagination hints. No more 96k dumps crashing your context.
Once installed, you can ask Claude things like "what did we decide about the auth middleware in last week's session?" and it will actually search its own past work.
Auto-Ingest
longhand hook install adds two hooks to ~/.claude/settings.json — Stop for live tailing between turns, SessionEnd for the full analysis pass at session close:
{
"hooks": {
"Stop": [
{"command": "longhand ingest-live"}
],
"SessionEnd": [
{"command": "longhand ingest-session"}
]
}
}Both commands read transcript_path from the hook's stdin JSON, so no flags are needed in the hook entry itself.
Stop hook (
ingest-live) runs after every assistant turn. Tails the transcript file and ingests new events incrementally so an in-flight session is queryable inrecallwhile you're still working in it.SessionEnd hook (
ingest-session) runs once when a session closes. Does the full analysis pass: project inference, outcomes, episodes, segments, embeddings.
Both are non-blocking and run in one to two seconds. You don't have to think about either of them again.
Optional background reconciler: longhand schedule install-reconciler adds a launchd plist that runs reconcile --fix on a schedule. Catches any sessions the hooks missed (e.g., when a hook silently failed) without you ever needing to remember it exists.
Works with Codex
Use Codex Desktop or the Codex CLI too? Longhand captures those threads into the same archive, so a question asked in Claude Code can be answered from work done in Codex, and the other way round.
pip install -U longhand
longhand codex-sync # capture every Codex thread on this machine
claude mcp add --scope user longhand-shared -- longhand shared-mcp # keyword search across both clients, from Claude
codex mcp add longhand -- longhand shared-mcp # the same server from Codex (Desktop: config.toml, see the docs)From then on reconcile --fix captures new Codex threads too, so the scheduled reconciler keeps both clients current. A thread is stored exact-record-only while it is being written — verbatim and searchable, no model loaded — and gets the full pipeline 30 minutes after it goes quiet, so recall sees it with no manual step (codex-sync --semantic does it immediately). Threads Codex spawns for itself are skipped, UI mirrors are never stored twice, and unknown record shapes surface in doctor like any other drift. Setup, bounds, and the macOS launchd template: docs/codex.md.
Architecture
longhand/
├── parser.py — JSONL → typed Events, nothing lost
├── replay.py — deterministic file state reconstruction
├── types.py — Pydantic models
├── storage/
│ ├── migrations.py — version-aware schema evolution
│ ├── sqlite_store.py — structured data + full raw JSON preserved
│ ├── vector_store.py — ChromaDB (events + sessions + projects collections)
│ └── store.py — unified ingest pipeline
├── extractors/ — per-event (errors, file refs, topics, git ops)
├── analysis/ — per-session (project, outcomes, episodes, embeddings)
├── recall/ — per-query (time parsing, project match, narrative)
├── cli.py — Typer CLI with Rich output
├── mcp_server.py — Model Context Protocol server (13 tools)
└── setup_commands.py — hook install, mcp install, config, doctorSource of truth: SQLite. Every event's raw JSON is preserved as a blob. ChromaDB is the search index — it only holds what's needed for semantic retrieval.
Analysis layer: Runs at ingest time, not query time. Pre-computes projects, session outcomes, and episodes so recall queries are fast. Fully deterministic, no LLM.
Recall pipeline: query → time parse → project match → episode search → rank → load artifacts → narrative. A single vector search is ~56ms; full recall runs ~7 of them (events, projects, episodes, segments, plus relaxation retries) and then loads artifacts and composes the narrative — landing around ~1.4s on a warm 246-session corpus.
Comparison
Longhand | Summary-based (Mem0, MemPalace, LangMem) | |
Source | Raw Claude Code JSONL | AI-generated summaries |
Tool calls captured | Every one, verbatim | Whatever the summarizer kept |
File edits | Full before/after diffs | Usually not captured |
Thinking blocks | First-class events | Usually discarded |
File state replay | Deterministic | Not possible |
Problem→fix extraction | Rules-based, at ingest | Depends on summarizer |
Fuzzy recall | Yes, with artifacts | Text search over summaries |
What gets "decided" | Nothing — store everything | The AI decides what matters |
Local-first | Yes | Most |
Completeness | Every event from the session file | Whatever the summarizer kept |
LLM calls to function | Zero | Varies |
Summary memory and Longhand solve different problems. Summary memory is good for long-term personal assistants that need compressed context across many conversations. Longhand is good for developers who need forensic access to their past Claude Code work — the kind of access where you need the exact diff, not a paraphrase.
Stats
Corpus measured 2026-08-12 against the author's live store on v0.13.0:
433 unique sessions
197,978 events
64,364 tool calls
15,202 file edits
224 thinking blocks
37 projects inferred automatically
1,119 problem→fix episodes extracted — 618 are low-confidence (fixless) and excluded from the rate, leaving 423 of 501 resolved (84%)
4,286 conversation segments (design, story, debugging, discussion, planning)
2,661 git operations extracted (107 commits linked)
142,897 vectors indexed
Storage footprint: 5.0 GB total (3.9 GB SQLite + 1.0 GB ChromaDB) across 433 sessions — ~12 MB per session
Latency, benchmarked on the earlier 246-session corpus (M-class Mac) and not re-measured since:
Vector search: ~56ms median (p90 ~62ms)
SQL queries (
get_events): ~2ms median (p90 ~13ms)Full recall pipeline: ~1.4s median, warm (~7 vector queries + artifact load + narrative)
Token budget
The single most common question: does Longhand consume a lot of tokens when Claude uses it?
No. Every MCP tool has a hard output cap enforced in longhand/mcp_server.py. The response truncates and appends a pagination hint before Claude ever sees it, so the token cost per tool call is bounded — not by your history size, but by the cap itself.
Tool | Default output cap | Rough token equivalent |
| 12,000 chars | ~3,000 tokens |
| 12,000–16,000 chars | ~3,000–4,000 tokens |
| 20,000 chars | ~5,000 tokens |
Absolute ceiling ( | 200,000 chars | ~50,000 tokens |
Why this matters — the comparison:
Reading one raw session JSONL directly: 50K–200K tokens per session (Claude Code sessions are typically 1–5MB each).
Bigger-context-window approaches: every prompt pays the full history, every time.
Summarizer-based memory tools: cheap per-query but they already threw away the thinking blocks.
Longhand is flat-cost: the cap is per-call, not per-corpus. Recalling across 10 sessions and recalling across 1,000 sessions both come back in the same token envelope. And Longhand itself makes zero API calls — the only tokens consumed are the MCP payload Claude reads back. No model sits between you and your data.
Tuning: every tool accepts a max_chars parameter that can be lowered per-call. summary_only: true on timeline tools drops the content field and shrinks payloads ~10×.
588 unit tests passing. All 13 MCP tools stress-tested. Full security audit: zero critical findings, zero high findings. ~/.longhand/ created with 0700 permissions, all SQL parameterized, all inputs bounded. Dependencies: chromadb, typer, rich, pydantic, mcp.
Author
Nate Nelson. Idaho Falls. No computer science degree. Fourteen industries of building software by describing what I see and letting the translation happen.
GitHub: Wynelson94
License
MIT. Do whatever you want with it.
Available Tools
17 toolsfind_commitsA
Search across all sessions for git commits matching a query — by commit message, hash prefix, or branch name. Great for 'find that commit where we fixed the parser' queries.
| Name | Required | Description | Default |
|---|---|---|---|
| query | Yes | Commit message substring, hash prefix, or branch name | |
| session_id | No | Optional: scope to a single session (prefix match) | |
| operation_type | No | Filter by operation type (default: all) | |
| limit | No | Max results | |
| max_chars | No | Max output characters |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations present, so description must cover behavioral traits. It states it searches read-only, but omits details like result order, pagination behavior, or performance implications. The description adds limited behavioral context beyond the search intent.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Two sentences with front-loaded purpose. Efficient but not overly terse; the example adds clarity without wasted words.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
No output schema, but description does not mention what the tool returns (e.g., list of commits, formatting). Also lacks details on defaults like limit and max_chars. Given 5 parameters and no output schema, the description should provide more context on results and constraints.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema coverage is 100%, baseline 3. The description adds value by explaining the query parameter can be message substring, hash, or branch name, and hints that session_id is optional for scoping. This clarifies usage beyond the schema definitions.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool searches for git commits across sessions by message, hash prefix, or branch name. The verb 'search' and resource 'commits' are specific, and the scope 'across all sessions' distinguishes it from sibling tools like get_session_commits.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Provides a concrete example of when to use ('find that commit where we fixed the parser'), but lacks explicit guidance on when not to use or mention of alternative sibling tools like get_session_commits or search.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
find_episodesA
Structured search for problem→fix episodes. Filters: project_ids, time range, keyword, has_fix. Returns raw episode rows. Use this when you already know the project or want data instead of narrative.
| Name | Required | Description | Default |
|---|---|---|---|
| project_ids | No | ||
| since | No | ISO timestamp | |
| until | No | ISO timestamp | |
| keyword | No | ||
| has_fix | No | ||
| limit | No | Max results (default 20) |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations provided. Description indicates a read-like search operation ('Structured search', 'Returns raw episode rows') but lacks details on performance, rate limits, or side effects.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Two concise sentences: first states purpose and lists filters, second provides usage guidance and output type. No redundant information.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Covers primary usage and output type. Lacks details on default behavior without filters and pagination beyond 'limit' parameter, but sufficient for basic understanding.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema coverage is 50% (only 'since', 'until', 'limit' described). The description lists additional filters ('project_ids', 'keyword', 'has_fix') but does not explain their semantics, e.g., what fields 'keyword' searches.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states 'Structured search for problem→fix episodes' with specific filters, distinguishing it from siblings like 'get_episode' and 'search'.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Explicit guidance: 'Use this when you already know the project or want data instead of narrative.' This context helps the agent choose among siblings.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_episodeA
Full detail for one episode by episode_id. Includes all referenced events (problem, diagnosis thinking block, fix edit, verification), the diff, and the reconstructed file state after the fix.
| Name | Required | Description | Default |
|---|---|---|---|
| episode_id | Yes |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
The description discloses what data is returned (events, diff, reconstructed state), providing some transparency. However, without annotations, it does not mention read-only nature, permissions, or side effects, leaving some behavioral traits unspecified.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single, information-dense sentence that efficiently communicates core functionality and output contents. Every word adds value.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a single-parameter retrieval tool without output schema, the description adequately conveys what the agent will receive. It covers the main data points but omits potential edge cases (e.g., error handling, empty results).
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 0%, and the description only mentions 'episode_id' without additional details about its format, source, or constraints. It adds minimal meaning beyond the schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool retrieves full detail for a single episode by ID, specifically listing included components (events, diff, reconstructed file state). This differentiates it from sibling tools like find_episodes which likely list episodes or summaries.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description gives no explicit guidance on when to use this tool versus alternatives. It does not mention prerequisites, context, or exclusions. The agent must infer usage from the description alone.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_file_historyB
Get every edit ever made to a file across all sessions, chronologically.
| Name | Required | Description | Default |
|---|---|---|---|
| file_path | Yes | ||
| session_id | No | Optional: limit to a single session |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Description implies read-only, chronological retrieval. No annotations, so description carries burden. It does not mention potential size limits, error behavior, or authorization needs.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Single sentence, front-loaded with action and scope. No redundant words.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Indicates output is a chronological list of edits, but lacks details on output structure (fields like timestamp, user, change type). No output schema to compensate.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema covers session_id with description, but file_path lacks description. The description does not add meaning for file_path beyond its name, and session_id context is already in schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
Clearly states 'get every edit ever made to a file', specifying verb and resource with scope (all sessions, chronological). Distinguishes from siblings like get_session_timeline or replay_file.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance on when to use this tool vs alternatives. Siblings include get_session_timeline and get_episode, but no context for choosing between them.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_latest_eventsA
Get the N most recent events in a session, in reverse chronological order (sequence DESC). Use this when you need 'what was the latest X' — e.g., the last user message, the last tool call, the last assistant response. Semantic search is the wrong tool for recency; this one is. Supports session id prefix match.
| Name | Required | Description | Default |
|---|---|---|---|
| session_id | Yes | ||
| limit | No | Max events to return (default 10) | |
| event_type | No | Optional: filter to a single event type (user_message, assistant_text, tool_call, etc.) | |
| max_chars | No | Max total output characters |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Describes ordering, filtering by event_type, and max_chars. No annotations provided; could mention it's read-only but implied.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Three concise sentences, front-loaded with primary purpose, followed by usage guidance. No fluff.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Good coverage given no output schema or annotations. Could mention return format or pagination, but sufficient for a list retrieval tool.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema covers 75% of parameters with descriptions. Description adds context for event_type with examples (user_message, etc.). session_id lacks description but is self-explanatory.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
Clearly states it gets the N most recent events in reverse chronological order. Distinguishes from semantic search by emphasizing recency.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Explicitly tells when to use ('what was the latest X') and warns against using semantic search. Also mentions session id prefix match.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_project_timelineA
Session-level timeline for a project. Returns recent sessions with their outcomes (shipped / fixed / stuck / exploratory) for a bird's-eye view of what's been happening in a project lately.
| Name | Required | Description | Default |
|---|---|---|---|
| project_id | Yes | ||
| since | No | ||
| until | No | ||
| limit | No | Max results (default 50) |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full burden. It states it returns sessions with outcomes but doesn't disclose read-only nature, ordering, or side effects.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Two efficient sentences, front-loaded with purpose, no wasted words.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given 4 parameters, no output schema, and many siblings, the description is too brief. It omits parameter details, ordering, and structure of the timeline.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema coverage is 25% (only limit described). Description adds meaning to since/until as date filters and project_id as identifier, but lacks format details.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states it returns a session-level timeline with specific outcomes (shipped/fixed/stuck/exploratory), distinguishing it from siblings like list_sessions or get_session_timeline.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
It implies use for a bird's-eye view of recent project activity, providing context but lacking explicit when-not-to-use or alternative comparisons.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_session_commitsA
Get all git operations (commits, pushes, merges, checkouts, etc.) from a session, chronologically. Links session work to git history — the in-between that git log doesn't capture.
| Name | Required | Description | Default |
|---|---|---|---|
| session_id | Yes | Session ID (prefix match) | |
| operation_type | No | Filter: commit, push, pull, checkout, merge, etc. | |
| limit | No | Max results | |
| max_chars | No | Max output characters |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description must convey behavioral context. It mentions chronologically ordered results and the value of capturing intermediate git operations, but does not disclose pagination, error conditions, or any side effects. Adequate but not comprehensive.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Two concise sentences with no fluff. The main action is front-loaded in the first sentence, and the second sentence provides context. Every phrase adds value.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
The description is fairly complete for a list operation: it explains the purpose, scope (session), and ordering (chronological). However, without an output schema, the agent lacks information about return format (e.g., fields available). Still, it adequately informs selection and invocation.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so each parameter's purpose is already clear from the schema. The tool's description adds no additional semantic meaning beyond what is in the schema, so baseline score of 3 is appropriate.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the specific verb and resource ('Get all git operations from a session, chronologically') and distinguishes itself from siblings like 'find_commits' by noting it captures 'the in-between that git log doesn't capture.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description implies usage for linking session work to git history, but does not explicitly state when to use this tool versus alternatives like 'find_commits' or 'get_session_timeline'. No when-not-to-use guidance is provided.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_session_timelineA
Get a chronological timeline of events in a session. Supports session id prefix match. Use 'tail' to get only the last N events (great for checking how a session ended). Use 'offset' to paginate through long sessions. NOT for searching — if you're looking for something specific in a session, use search_in_context instead of paginating this tool in a loop.
| Name | Required | Description | Default |
|---|---|---|---|
| session_id | Yes | ||
| limit | No | Max events to return (default 100) | |
| offset | No | Skip first N events (for pagination) | |
| tail | No | Return only the last N events of the session | |
| include_thinking | No | ||
| event_type | No | Filter to a single event type | |
| summary_only | No | Return only event_type, timestamp, tool_name, file_path — no content. Great for scanning long sessions. | |
| max_chars | No | Max total output characters |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Without annotations, the description carries full burden. It discloses support for session ID prefix match, tail, and offset for pagination. However, it does not explicitly state that the operation is read-only or describe ordering details beyond 'chronological', which are minor omissions.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is concise with five sentences. The first sentence front-loads the main purpose, followed by key usage patterns and a clear warning. Every sentence adds value without redundancy.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given 8 parameters and no output schema, the description covers essential usage patterns (prefix match, tail, offset, not for searching) but could elaborate on return format or ordering beyond 'chronological'. However, schema covers parameter details, making it fairly complete.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
With 75% schema coverage, the description adds significant meaning beyond the schema. It explains the purpose of tail and offset, and notes that session_id supports prefix matching, which is not in the schema. It also warns against using the tool for searching.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool retrieves a chronological timeline of events in a session. It distinguishes itself from sibling tools like search_in_context by explicitly stating it is not for searching.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides explicit guidance on when to use this tool (chronological timeline) and when not (searching). It also explains specific use cases for tail and offset, and names the alternative tool for searching.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_statsA
Get overall Longhand storage statistics.
| Name | Required | Description | Default |
|---|---|---|---|
No parameters | |||
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations provided, so the description must disclose behavior. It implies a non-destructive read operation, but no details on what 'statistics' include or any side effects. This is minimally adequate.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
One sentence with no unnecessary words. Perfectly concise.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a parameterless retrieval tool with no output schema, the description is minimal but likely sufficient to inform the agent of its purpose. However, it lacks details about the nature of the statistics.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
There are no parameters, and schema description coverage is 100% trivial. The description adds no parameter info, but none is needed.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states it retrieves overall Longhand storage statistics, which is specific. However, it does not differentiate from siblings like 'get_session_timeline' or 'list_projects', but the name and 'overall' imply a summary.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance on when to use this tool versus alternatives. While it may be obvious for overall stats, explicit instructions are missing.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
list_projectsB
Browse inferred projects by keyword, category, or recency. Returns compact summaries by default. Set verbose=true for full detail.
| Name | Required | Description | Default |
|---|---|---|---|
| keyword | No | ||
| category | No | ||
| limit | No | Max results (default 20) | |
| verbose | No | Return full project rows including aliases, keywords, languages JSON |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Discloses default output format (compact summaries) and the option for full detail (verbose=true). Does not mention ordering, pagination, or error handling. With no annotations, the description provides basic but incomplete behavioral context.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Two concise sentences, no extraneous information. Front-loads key information. Every sentence adds value.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a straightforward list tool with no output schema and moderate param count, the description covers basic functionality and output options. Lacks details on ordering, result set limits, and behavior when no results are found.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 50%, partially compensated by description mentioning keyword, category, and recency. However, keyword and category lack format or constraints. The description adds 'recency' which is not a schema parameter, implying default ordering, which is helpful but vague.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description uses specific verb 'Browse' and resource 'inferred projects', and lists filter criteria (keyword, category, recency). It clearly indicates the tool is for listing projects, distinguishing it from siblings like get_project_timeline or match_project.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance on when to use this tool versus alternatives. Does not specify when not to use or mention sibling tools. The agent receives no help in deciding between list_projects and related tools like search or find_commits.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
list_sessionsB
List recent Claude Code sessions that Longhand has indexed.
| Name | Required | Description | Default |
|---|---|---|---|
| project | No | Filter by project path substring | |
| limit | No | Max results (default 20) |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, and the description offers only the vague term 'recent' without defining it. It does not disclose whether the tool is read-only, what ordering is used, or any other behavioral traits, putting the full burden on the description.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single concise sentence with no wasted words. It front-loads the key action and resource, making it efficient for quick scanning.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a simple listing tool with two optional parameters and no output schema, the description is adequate but lacking. It does not explain what a session is, what fields are returned, or any default time range, leaving important gaps for the agent.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The input schema has 100% coverage for both parameters, so the description does not need to add much. However, 'recent' provides minimal extra context that is not parameter-specific, but the description adds no meaningful semantics beyond the schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool lists 'recent Claude Code sessions that Longhand has indexed,' with a specific verb and resource. However, it does not differentiate from sibling tools like get_session_timeline or get_latest_events, which also relate to sessions.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance on when to use this tool versus alternatives such as search or find_commits. The description does not mention context, prerequisites, or exclusions, leaving the agent without decision criteria.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
match_projectA
Fuzzy project matching. Given a partial project name, category, or description, returns candidate projects with match reasons. Useful for confirming 'which game did you mean?' before drilling into episodes.
| Name | Required | Description | Default |
|---|---|---|---|
| query | Yes | ||
| top_k | No | Max project matches to return |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations provided, so description bears full burden. It describes a read-like operation (returns candidates) but does not explicitly state it is non-destructive or safe. Could be more transparent about side effects.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Two sentences with no unnecessary words. First sentence immediately states the primary function, making it easy for an agent to parse.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
No output schema exists, but description mentions 'match reasons' as part of output, giving a clue. For a simple fuzzy match tool, this is sufficient; however, more detail on return structure could be helpful.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 50% (top_k described, query not). Description adds value by explaining 'query' can be a partial name, category, or description, which enriches the schema's bare parameter definition.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
Clearly states it performs fuzzy matching on partial project name, category, or description, returning candidates with match reasons. Distinguishes from siblings like list_projects (exact listing) and search (broader search).
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Provides the use case of disambiguation before drilling into episodes, which gives clear context. Does not explicitly state when not to use or name alternatives, but the intended scenario is well-defined.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
recallA
PROACTIVE MEMORY — START HERE for any 'do you remember...' question. Handles fuzzy time references ('a couple months ago'), project matching ('that game project'), and episode retrieval in ONE call. Returns: matched projects, relevant episodes (problem→fix pairs), diffs, verbatim thinking blocks, reconstructed file states, and a prebuilt markdown narrative. Do NOT manually search and paginate — use this tool first.
| Name | Required | Description | Default |
|---|---|---|---|
| query | Yes | Natural language question | |
| max_episodes | No | Max episodes to return | |
| max_chars | No | Max total output characters |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations, the description details the return types: matched projects, episodes, diffs, thinking blocks, reconstructed files, and a narrative. It mentions 'in ONE call' but does not disclose authorization needs or rate limits, though the comprehensive output description covers most behavioral aspects.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is concise, with four sentences each adding unique value: attention-getter, capabilities, specific returns, and usage instruction. It is well-structured and front-loaded with the most important information.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
The tool is complex with no output schema, but the description fully explains its purpose, input, output, and usage context. It covers why to use it over alternatives and what to expect, making it complete for an agent to select and invoke correctly.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema coverage is 100%, baseline 3. The description adds meaning by explaining that the query parameter handles natural language with fuzzy time references and project matching, enhancing understanding beyond the schema's 'Natural language question' description.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool is for memory recall, handling fuzzy time references, project matching, and episode retrieval in one call. It distinguishes from siblings by explicitly advising not to manually search or paginate, making it the first tool for recall questions.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description explicitly says 'START HERE for any 'do you remember...' question' and instructs 'Do NOT manually search and paginate — use this tool first,' providing clear when-to-use and when-not-to-use guidance.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
recall_project_statusA
Get the current status of a project — where you left off, recent commits, unresolved issues, and latest conversation context. Takes a project name (fuzzy match) and returns a structured summary with git history, linked episodes, and conversation segments. Use this when someone says 'pick up where we left off on X', 'what's the status of X', or 'where did we end on X'.
| Name | Required | Description | Default |
|---|---|---|---|
| project | Yes | Project name, alias, or ID (fuzzy match) | |
| max_commits | No | Max recent commits to show | |
| max_episodes | No | Max recent episodes | |
| max_chars | No | Max output characters |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations provided, so description carries burden. Mentions return of structured summary but does not disclose read-only nature, potential performance impact, or any side effects. Adequate but could be more explicit.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Two sentences: first front-loads purpose and return content, second gives concrete usage examples. No redundant words.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Covers what it returns, when to use, and has well-documented parameters. Could mention output limits or that it is a read operation, but overall sufficient for a retrieval tool with no output schema.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, and description adds 'fuzzy match' for project but schema already includes that. Little added meaning beyond schema, so baseline 3 is appropriate.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
Clearly states it retrieves the status of a project, listing specific components like commits, issues, and conversation context. Distinguishes from sibling tools like find_commits or find_episodes by providing a summary.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Explicitly provides example user queries ('pick up where we left off', 'what's the status') to guide invocation. No direct exclusion of sibling tools, but the context is sufficiently clear.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
replay_fileB
Reconstruct the state of a file at a point in a past Claude Code session. Applies every edit verbatim from the session JSONL — no summarization.
| Name | Required | Description | Default |
|---|---|---|---|
| session_id | Yes | ||
| file_path | Yes | ||
| at_event_id | No | Optional: reconstruct up to this event |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations provided, so description must carry full burden. It mentions 'no summarization' but fails to disclose whether reconstruction is destructive, idempotent, or requires permissions. Ambiguous if it modifies state or just returns data.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Two concise sentences with no filler. Front-loaded with clear purpose and unique behavior (verbatim edits).
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given no output schema and 3 parameters, description lacks details on return format, side effects, or error conditions. Incomplete for an agent to confidently invoke without additional context.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema coverage is only 33% (only at_event_id described). Description does not explain session_id or file_path beyond their existence, missing opportunity to clarify usage or format.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
Clearly states the tool reconstructs a file state at a past session point, with specific verb 'reconstruct' and resource 'file state'. The addition of 'Applies every edit verbatim' distinguishes it from summarization tools like get_file_history.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance on when to use this tool versus siblings like get_file_history or search. Lacks context for when reconstruction is appropriate or alternative approaches.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
searchA
Semantic search across all stored Claude Code session events. Returns events matching a natural language query, with optional filters by event type, session, project, tool, or file path. IMPORTANT: Always pass session_id when you know which session to search — unscoped search returns noisy results. For finding a discussion WITH surrounding conversation context, use search_in_context instead.
| Name | Required | Description | Default |
|---|---|---|---|
| query | Yes | Natural language query | |
| limit | No | Max results (default 10) | |
| session_id | No | Scope search to a single session (prefix match) | |
| project_id | No | Scope search to a project by project_id | |
| project_name | No | Scope search to a project by name substring (e.g. 'gonzo') | |
| event_type | No | Filter: user_message, assistant_text, assistant_thinking, tool_call, tool_result | |
| tool_name | No | Filter by tool name (Edit, Bash, Read, etc.) | |
| file_path_contains | No | Filter to events with an explicit file_path containing this string (tool_call/tool_result events only — user messages won't have file_path metadata) | |
| max_chars | No | Max total output characters (default 12000). Set higher if you need full content. |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Without annotations, description implies read-only by stating 'Returns events'. No contradictions, but could be more explicit about side effects.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Four sentences, front-loaded purpose, every sentence adds value with guidance and alternatives.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Covers purpose, filters, and usage guidance for a tool with many parameters and no output schema; could clarify filter combination logic.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema already describes all 9 parameters with 100% coverage; description adds usage advice ('Always pass session_id') but no additional semantic meaning beyond schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
Description clearly states 'Semantic search across all stored Claude Code session events' and distinguishes from sibling 'search_in_context' for conversation context retrieval.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Explicitly advises always passing session_id to avoid noisy results, and directs to search_in_context when surrounding context is needed.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
search_in_contextA
Search within a specific session and return matches WITH surrounding conversation context. This is the tool you want when you know WHICH session to look in but need to FIND a specific discussion or event. Returns each semantic match plus N events before/after it from the timeline, so you can read the full conversation flow. Much more efficient than paginating get_session_timeline manually.
| Name | Required | Description | Default |
|---|---|---|---|
| session_id | Yes | Session ID (prefix match) | |
| query | Yes | Natural language query to find within the session | |
| context_events | No | Number of events to include before AND after each match (default 5) | |
| limit | No | Max number of matches to return with context (default 3) | |
| event_type | No | Optional: filter matches to a single event type | |
| max_chars | No | Max total output characters (default 20000) |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations provided, but description details return structure—each match plus N events before/after—and default parameter values, adding behavioral context beyond the schema.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Concise paragraph where each sentence adds value: purpose, usage context, return detail, efficiency comparison.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a search tool with 6 parameters and no output schema, description adequately explains what it returns and how to use it, including defaults and optional filters.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Description explains the meaning of key parameters like context_events (before AND after each match), limit (max matches), and max_chars (total output), enhancing the schema descriptions.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool searches within a specific session and returns matches with surrounding context, distinguishing it from siblings like 'search' and 'get_session_timeline'.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Explicitly says when to use: when you know which session to look in but need to find a specific discussion, and it's more efficient than paginating get_session_timeline.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Tool Schema Changelog
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
17 tool updates
- First observed
find_commits - First observed
find_episodes - First observed
get_episode - First observed
get_file_history - First observed
get_latest_events - First observed
get_project_timeline - First observed
get_session_commits - First observed
get_session_timeline - First observed
get_stats - First observed
list_projects - First observed
list_sessions - First observed
match_project - First observed
recall - First observed
recall_project_status - First observed
replay_file - First observed
search - First observed
search_in_context
TDQS
Scored across 17 tools
Most tools have distinct purposes: 'recall' is the primary proactive memory, 'find_episodes' returns raw data, and 'search' is for semantic queries. However, 'search' and 'search_in_context' could be confused if descriptions are skimmed, and 'find_episodes' vs 'get_episode' might overlap for some users.
Tools use a mix of verbs: 'find_', 'get_', 'list_', 'search', 'match_project', 'replay_file'. While all are lowercase with underscores, the verb choice is inconsistent. For example, 'find_commits' and 'get_session_commits' both retrieve commits but use different prefixes.
17 tools is on the higher side but reasonable for a comprehensive memory server covering episodes, sessions, commits, and project status. Each tool has a specific retrieval niche, though some consolidation could reduce count slightly.
The tool set covers core retrieval needs: searching, getting details, timelines, and project status. It includes proactive recall and context-aware search. Minor gaps like a tool for counting or aggregating data, but overall it's well-rounded for read-only memory access.
Maintenance
Related MCP Connectors
- mcpOAuthai.butlerbrain
Persistent memory for AI assistants. Save once; recall from Claude, ChatGPT, or any MCP client.
Persistent memory for AI agents across Claude, ChatGPT and any MCP client.
Private persistent memory for Claude, ChatGPT & Gemini via MCP - semantic search, zero-code setup.
Persistent AI memory shared across Claude, ChatGPT, coding agents, and compatible MCP clients.
Related MCP Servers
- AlicenseAqualityBmaintenancePersistent memory for Claude Code. Automatically indexes every conversation and provides production-grade hybrid search (BM25 + vectors + reranker) via MCP tools. 100% local, zero config, zero API keys, zero invoice.1633 npm7MIT
- AlicenseAqualityBmaintenancePersistent memory + FTS5 full-text search for Claude Code conversation history. Indexes ~/.claude/projects/ JSONL into SQLite, exposes 10 MCP tools (store/recall/search memories, browse sessions, get summaries) plus prompts. Includes a web UI for visual exploration1042 npm93MIT
- AlicenseNot gradedqualityDmaintenanceProvides persistent, searchable memory for Claude Code using local SQLite, semantic embeddings, and full-text search, enabling Claude to recall and retrieve context across sessions and projects without external services.6 npm4MIT
- FlicenseNot gradedqualityDmaintenanceProvides persistent semantic memory for Claude Code via local embeddings and six MCP tools, enabling context storage and retrieval across sessions without cloud dependencies.-