


A
licenseNot graded
qualityD
maintenanceEnables AI assistants to search, read, summarize, and analyze sentiment of Notion pages and databases, turning your Notion workspace into an intelligent, queryable knowledge system.
MIT

Este proyecto implementa un servidor MCP de solo lectura optimizado para la API de Notion, centrándose en el rendimiento y la eficiencia de los asistentes de IA para consultar y recuperar contenido de Notion.
Diseño de solo lectura : centrado exclusivamente en las operaciones de recuperación de datos, lo que garantiza un acceso seguro al contenido de Notion.
Conjunto de herramientas minimizado : se redujo la cantidad de herramientas API de Notion expuestas de más de 15 a solo 6 esenciales para el análisis de documentos.
Procesamiento paralelo : rendimiento mejorado al implementar solicitudes de API asincrónicas y paralelas para recuperar contenido de bloques, lo que reduce significativamente los tiempos de respuesta.
Acceso extendido a la base de datos : se agregó soporte para operaciones de recuperación de bases de datos, propiedades de página y comentarios.
Optimizado para asistentes de IA : la cantidad de herramientas significativamente reducida soluciona el problema de "Demasiadas herramientas pueden degradar el rendimiento" en asistentes de IA como Cursor, que limita los modelos a aproximadamente 40 herramientas.
Related MCP server: notion-slim
Esta implementación de solo lectura expone muchas menos herramientas en comparación con la integración de API estándar de Notion, lo que mejora el rendimiento y la compatibilidad con los asistentes de IA:
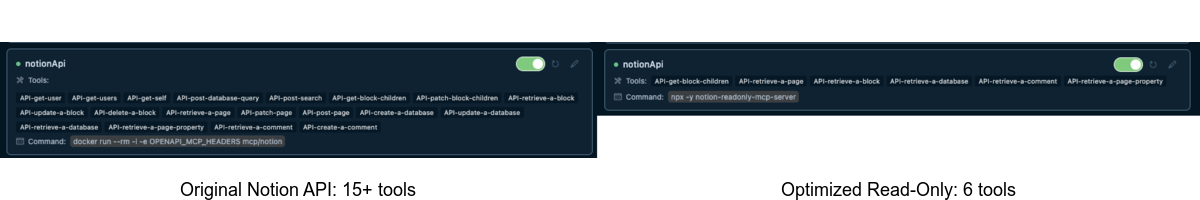
El conjunto de herramientas reducido ayuda a mantenerse dentro de los límites de herramientas recomendados para un rendimiento óptimo del asistente de IA y, al mismo tiempo, proporciona todas las funciones esenciales.
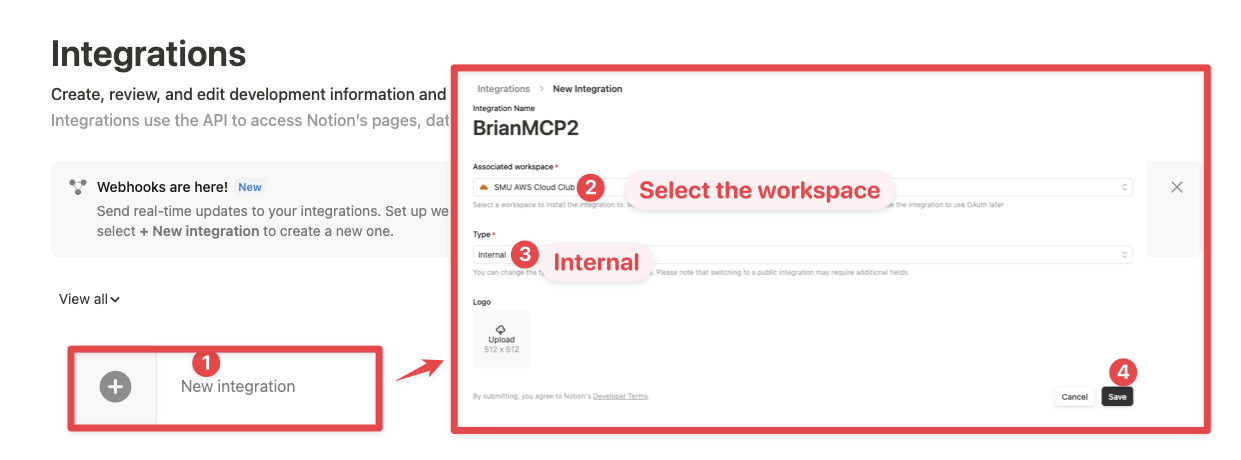
Vaya a https://www.notion.so/profile/integrations y cree una nueva integración interna o seleccione una existente.
Si bien limitamos el alcance de las API de Notion expuestas a operaciones de solo lectura, existe un riesgo considerable para los datos del espacio de trabajo al exponerlos a LLM. Los usuarios preocupados por la seguridad deberían configurar mejor las capacidades de la integración.
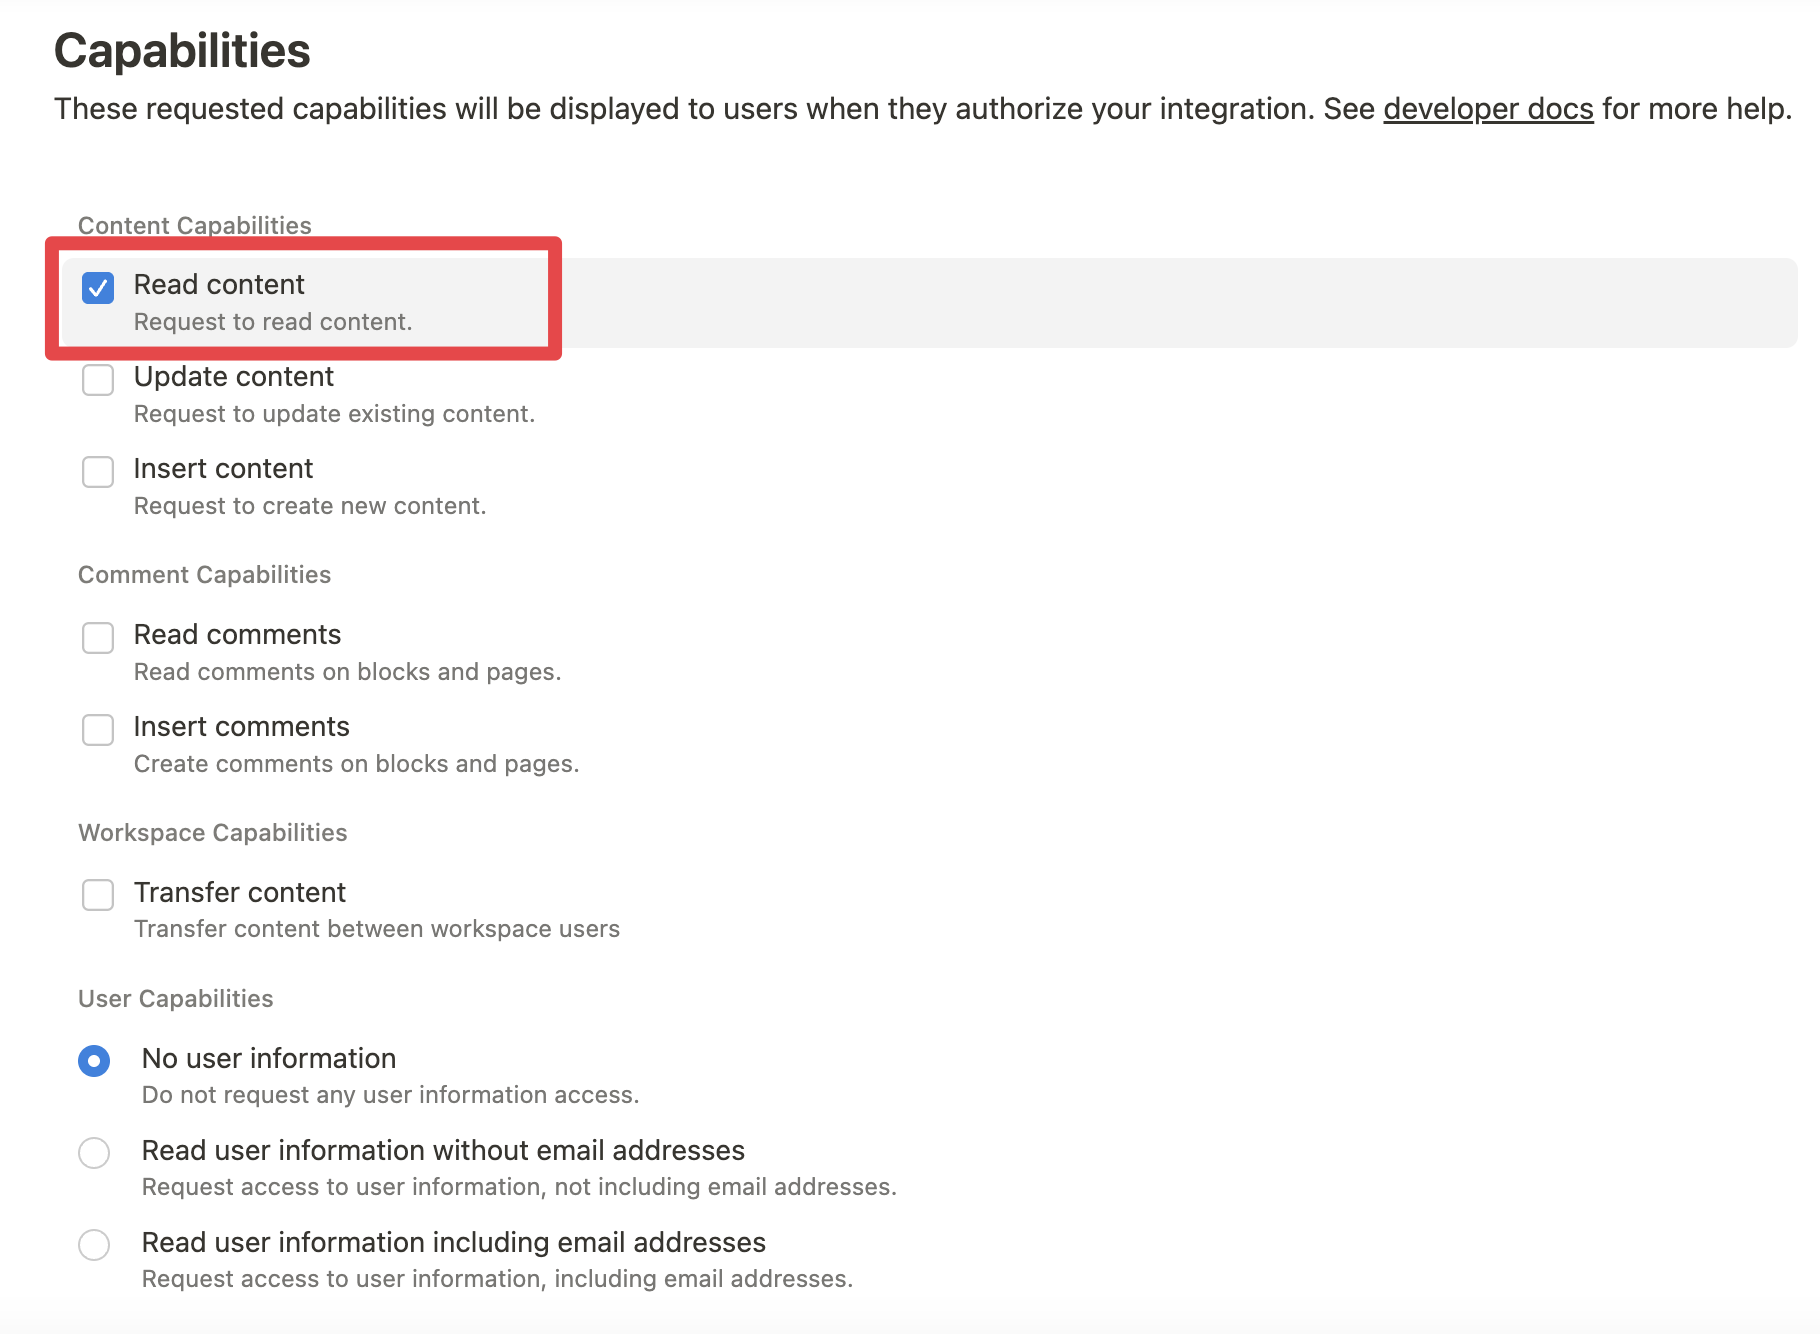
Por ejemplo, puede crear un token de integración de solo lectura otorgando únicamente acceso a "Leer contenido" desde la pestaña "Configuración":
Agregue lo siguiente a su .cursor/mcp.json o claude_desktop_config.json (MacOS: ~/Library/Application\ Support/Claude/claude_desktop_config.json )
{
  "mcpServers": {
    "notionApi": {
      "command": "npx",
      "args": ["-y", "notion-readonly-mcp-server"],
      "env": {
        "OPENAPI_MCP_HEADERS": "{\"Authorization\": \"Bearer ntn_****\", \"Notion-Version\": \"2022-06-28\" }"
      }
    }
  }
}Agregue lo siguiente a su .cursor/mcp.json o claude_desktop_config.json :
{
  "mcpServers": {
    "notionApi": {
      "command": "docker",
      "args": [
        "run",
        "--rm",
        "-i",
        "-e", "OPENAPI_MCP_HEADERS",
        "taewoong1378/notion-readonly-mcp-server"
      ],
      "env": {
        "OPENAPI_MCP_HEADERS": "{\"Authorization\":\"Bearer ntn_****\",\"Notion-Version\":\"2022-06-28\"}"
      }
    }
  }
}
No olvides reemplazar ntn_**** con tu secreto de integración. Puedes encontrarlo en la pestaña de configuración de la integración.
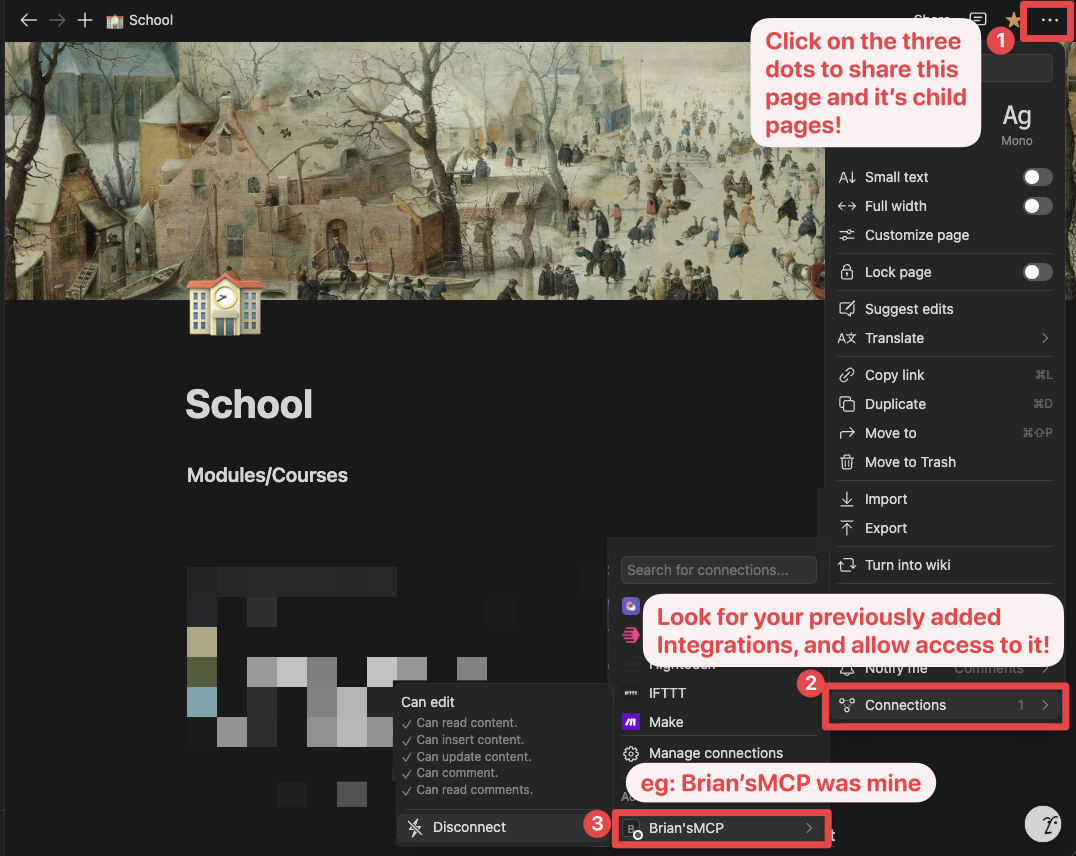
Asegúrese de que las páginas y bases de datos relevantes estén conectadas a su integración.
Para ello, visite la página, haga clic en los 3 puntos y seleccione “Conectar a integración”.
Este servidor optimizado expone únicamente herramientas esenciales de la API de Notion de solo lectura:
API-retrieve-a-page : Obtener información de la página
API-get-block-children : Obtener bloques de contenido de página (con procesamiento paralelo)
API-retrieve-a-block : obtener detalles sobre un bloque específico
API-retrieve-a-database : Obtener información de la base de datos
API-retrieve-a-comment : Obtener comentarios en una página o bloque
API-retrieve-a-page-property : Obtener información específica de la propiedad de una página
API-get-one-pager : ¡NUEVO! Recupera recursivamente una página completa de Notion con todos sus bloques, bases de datos y contenido relacionado en una sola llamada.
Al limitarnos a estas 7 herramientas esenciales (en comparación con las más de 15 de la implementación estándar), garantizamos:
Mejor rendimiento en asistentes de IA como Cursor y Claude que tienen limitaciones en el número de herramientas
Reducción de la carga cognitiva para los modelos de IA al elegir las herramientas adecuadas
Tiempos de respuesta más rápidos con menos opciones de API a considerar
Seguridad mejorada mediante una superficie API minimizada
La nueva herramienta API-get-one-pager proporciona una forma poderosa de explorar páginas de Notion sin necesidad de múltiples llamadas API:
Recuperación recursiva : recorre automáticamente toda la estructura de la página, incluidos los bloques anidados.
Procesamiento paralelo : obtiene varios bloques y sus elementos secundarios simultáneamente para obtener el máximo rendimiento
Almacenamiento en caché inteligente : almacena los datos recuperados para minimizar las llamadas API redundantes
Contenido completo : incluye páginas, bloques, bases de datos, comentarios e información detallada de la propiedad.
Profundidad personalizable : controle el nivel de recursión para equilibrar entre detalle y rendimiento.
{
  "page_id": "YOUR_PAGE_ID",
  "maxDepth": 5,               // Optional: Maximum recursion depth (default: 5)
  "includeDatabases": true,    // Optional: Include linked databases (default: true)
  "includeComments": true,     // Optional: Include comments (default: true)
  "includeProperties": true    // Optional: Include detailed page properties (default: true)
}
Esta capacidad de exploración automática es especialmente útil para los asistentes de IA que necesitan comprender todo el contenido de una página de Notion sin realizar docenas de llamadas API independientes, lo que da como resultado respuestas mucho más rápidas y eficientes.
El servidor implementa técnicas avanzadas de procesamiento paralelo para manejar documentos Notion de gran tamaño:
Se agrupan y procesan varias solicitudes simultáneamente
La paginación se gestiona automáticamente para los elementos secundarios del bloque.
Los resultados se agregan de manera eficiente antes de ser devueltos.
El registro de la consola proporciona visibilidad del proceso sin afectar el formato de respuesta.
Utilizando la siguiente instrucción:
Get the content of page 1a6b35e6e67f802fa7e1d27686f017f2La IA recuperará los detalles de la página de manera eficiente con el procesamiento paralelo del contenido del bloque.
Usando la información de la base de datos:
Get the structure of database 8a6b35e6e67f802fa7e1d27686f017f2Construir:
pnpm buildEjecutar:
pnpm devInstituto Tecnológico de Massachusetts (MIT)
Los asistentes de IA modernos como Cursor y Claude tienen limitaciones en la cantidad de herramientas que pueden manejar de manera efectiva:
La mayoría de los modelos pueden no respetar más de 40 herramientas en total
Demasiadas herramientas pueden degradar el rendimiento general y las capacidades de razonamiento.
Los conjuntos de herramientas complejos aumentan la latencia de respuesta y la dificultad de toma de decisiones
Esta implementación de solo lectura reduce deliberadamente la superficie de la API de Notion para abordar estas limitaciones, conservando al mismo tiempo toda la funcionalidad esencial. El resultado es:
Respuestas más rápidas y fiables de los asistentes de IA
Precisión mejorada al interactuar con el contenido de Notion
Mejor rendimiento general mediante un diseño de API enfocado
Retrieve the result of a background processing request
| Name | Required | Description | Default |
|---|---|---|---|
| page_id | Yes | Identifier for the Notion page that was processed in background |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It states this is a retrieval operation, implying it's likely read-only, but doesn't clarify authentication needs, rate limits, error conditions, or what happens if the background processing isn't complete. For a tool with zero annotation coverage, this leaves significant gaps in understanding its behavior.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single, clear sentence with zero waste. It's appropriately sized and front-loaded, efficiently conveying the core purpose without unnecessary elaboration.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the lack of annotations and output schema, the description is incomplete. It doesn't explain what the result contains (e.g., status, data, errors), how to handle pending processing, or any dependencies. For a tool that retrieves background processing results, this leaves critical context gaps for an agent.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The input schema has 100% description coverage, with the single parameter 'page_id' documented as 'Identifier for the Notion page that was processed in background'. The description adds no additional meaning beyond this, such as format examples or constraints, so it meets the baseline of 3 where the schema does the heavy lifting.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb ('Retrieve') and resource ('result of a background processing request'), making the purpose understandable. However, it doesn't differentiate this tool from its siblings (like API-retrieve-a-page or API-retrieve-a-database), which also retrieve data but for different resources.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It doesn't mention prerequisites (e.g., that a background processing request must have been initiated first) or compare it to sibling tools that retrieve other types of data, leaving the agent to infer usage context.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Retrieve block children
| Name | Required | Description | Default |
|---|---|---|---|
| block_id | Yes | Identifier for a [block](ref:block) | |
| start_cursor | No | If supplied, this endpoint will return a page of results starting after the cursor provided. If not supplied, this endpoint will return the first page of results. | |
| page_size | No | The number of items from the full list desired in the response. Maximum: 100 |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. 'Retrieve' implies a read-only operation, but it does not specify critical traits like pagination behavior (implied by 'start_cursor' and 'page_size' in the schema), rate limits, authentication needs, or error handling. The description adds minimal context beyond the basic action, leaving gaps in understanding how the tool behaves in practice.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description 'Retrieve block children' is extremely concise—just three words—and front-loaded with the core action. There is no wasted language or unnecessary elaboration, making it efficient for quick comprehension. Every word earns its place by directly stating the tool's function.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity of a paginated retrieval tool with no annotations and no output schema, the description is incomplete. It does not explain what 'block children' are, the return format, pagination details, or error conditions. While the schema covers inputs, the lack of behavioral and output information makes it inadequate for an agent to use the tool effectively without additional context.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, meaning the input schema fully documents all parameters ('block_id', 'start_cursor', 'page_size') with clear descriptions. The description does not add any meaning beyond this, such as explaining relationships between parameters or usage examples. According to the rules, with high schema coverage, the baseline score is 3, as the description does not compensate but also does not detract.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description 'Retrieve block children' states the verb ('Retrieve') and resource ('block children'), making the purpose clear. However, it lacks specificity about what 'block children' are (e.g., nested content in a Notion-like system) and does not differentiate from sibling tools like 'API-retrieve-a-block', which might retrieve a single block rather than its children. This vagueness prevents a higher score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It does not mention sibling tools such as 'API-retrieve-a-block' or 'API-retrieve-a-page', nor does it specify contexts like fetching hierarchical content. Without any usage context or exclusions, the agent must infer when to apply it, leading to potential misuse.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Recursively retrieve a full Notion page with all its blocks, databases, and related content
| Name | Required | Description | Default |
|---|---|---|---|
| page_id | Yes | Identifier for a Notion page | |
| maxDepth | No | Maximum recursion depth (default: 5) | |
| includeDatabases | No | Whether to include linked databases (default: true) | |
| includeComments | No | Whether to include comments (default: true) | |
| includeProperties | No | Whether to include detailed page properties (default: true) | |
| maxParallelRequests | No | Maximum number of parallel requests (default: 15) | |
| batchSize | No | Batch size for parallel processing (default: 10) | |
| timeoutMs | No | Timeout in milliseconds (default: 300000) | |
| runInBackground | No | Process request in background without timeout (default: true) |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure. It mentions recursion and content inclusion but lacks details on performance implications, error handling, rate limits, authentication needs, or what the output looks like. For a complex tool with 9 parameters, this is a significant gap in transparency.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single, efficient sentence that front-loads the core purpose without unnecessary words. It directly communicates the tool's function, making it highly concise and well-structured for quick understanding.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (9 parameters, no annotations, no output schema), the description is insufficient. It lacks information on output format, error conditions, performance trade-offs, and when to use alternatives, leaving the agent with incomplete context for effective tool invocation.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so the schema fully documents all parameters. The description adds no additional parameter semantics beyond implying recursion and content scope, which is already covered by parameter names like 'maxDepth' and 'includeDatabases'. Baseline 3 is appropriate as the schema does the heavy lifting.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the action ('recursively retrieve') and the resource ('full Notion page with all its blocks, databases, and related content'), making the purpose specific and unambiguous. It distinguishes from siblings like 'API-retrieve-a-page' by emphasizing the comprehensive, recursive nature of the retrieval.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. It does not mention any prerequisites, exclusions, or compare it to sibling tools like 'API-retrieve-a-page' for simpler needs or 'API-get-background-result' for background processing, leaving the agent without usage context.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Retrieve a block
| Name | Required | Description | Default |
|---|---|---|---|
| block_id | Yes | Identifier for a Notion block |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations provided, the description carries the full burden of behavioral disclosure but fails to add any meaningful context. It doesn't specify whether this is a read-only operation, what permissions are required, potential rate limits, error conditions, or the format of returned data. The description is too minimal to provide useful behavioral insights beyond the basic action implied by 'retrieve'.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is extremely concise at just two words ('Retrieve a block'), with zero wasted language. It's front-loaded with the core action, though this brevity comes at the cost of completeness. Every word serves a purpose in stating the basic function, making it structurally efficient despite its limitations.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's simplicity (1 parameter, 100% schema coverage) but lack of annotations and output schema, the description is incomplete. It doesn't explain what 'retrieve' entails (e.g., returns block content, metadata, or both), how it differs from sibling tools, or any behavioral aspects. For a retrieval tool in a family of similar tools, more context is needed to guide proper usage.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema description coverage is 100%, with the single parameter 'block_id' clearly documented as 'Identifier for a Notion block' in the schema. The description adds no additional parameter information beyond what the schema provides, so it meets the baseline score of 3 for adequate coverage when the schema handles parameter documentation effectively.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description 'Retrieve a block' is a tautology that essentially restates the tool name 'API-retrieve-a-block', providing no additional specificity. It mentions the verb 'retrieve' and resource 'block', but doesn't distinguish what kind of block (Notion block is only implied by the parameter description in the schema) or what information is retrieved, making it vague compared to more specific alternatives.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus sibling tools like 'API-retrieve-a-page', 'API-retrieve-a-database', or 'API-get-block-children'. There's no mention of prerequisites, alternatives, or contextual constraints, leaving the agent with no usage direction beyond the tool name.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Retrieve comments
| Name | Required | Description | Default |
|---|---|---|---|
| block_id | Yes | Identifier for a Notion block or page | |
| start_cursor | No | If supplied, this endpoint will return a page of results starting after the cursor provided. If not supplied, this endpoint will return the first page of results. | |
| page_size | No | The number of items from the full list desired in the response. Maximum: 100 |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. 'Retrieve comments' implies a read-only operation, but it doesn't specify authentication needs, rate limits, error handling, or pagination behavior. The description lacks details on what 'retrieve' entails, such as whether it returns all comments or supports filtering, leaving behavioral traits unclear.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is extremely concise with 'Retrieve comments', which is front-loaded and wastes no words. However, it may be overly brief, risking under-specification. For a tool with three parameters and no annotations, more detail could be beneficial, but the current form is structurally efficient.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has 3 parameters, no annotations, and no output schema, the description is incomplete. It doesn't explain the return values, error cases, or operational context. For a retrieval tool in a Notion API context, more information on what 'comments' are and how they relate to 'block_id' would enhance completeness.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, with clear documentation for 'block_id', 'start_cursor', and 'page_size'. The description adds no parameter-specific information beyond the schema. Since the schema is comprehensive, a baseline score of 3 is appropriate, as the description doesn't compensate but also doesn't detract from the schema's clarity.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description 'Retrieve comments' restates the tool name with minimal elaboration. It specifies the action ('retrieve') and resource ('comments'), but lacks detail about scope or context, making it vague. Compared to siblings like 'API-retrieve-a-block' or 'API-retrieve-a-page', it doesn't clearly differentiate what makes retrieving comments unique, beyond the resource type.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided on when to use this tool versus alternatives. The description doesn't mention prerequisites, context, or exclusions. Given siblings like 'API-get-block-children' that might overlap in functionality, the absence of usage guidelines leaves the agent without direction on tool selection.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Retrieve a database
| Name | Required | Description | Default |
|---|---|---|---|
| database_id | Yes | An identifier for the Notion database. |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It only states the action ('Retrieve') without detailing aspects like authentication requirements, rate limits, error handling, or what the retrieval entails (e.g., read-only operation, data format returned). This leaves significant gaps in understanding the tool's behavior.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is extremely concise with just two words, making it front-loaded and free of unnecessary information. Every word earns its place, though this brevity contributes to gaps in other dimensions like purpose clarity and guidelines.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the lack of annotations and output schema, the description is incomplete for a retrieval tool. It fails to explain what is retrieved (e.g., database properties, schema, content), potential side effects, or response format, leaving the agent with insufficient context to use the tool effectively.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The input schema has 100% description coverage, with the single parameter 'database_id' clearly documented as 'An identifier for the Notion database.' The description adds no additional semantic context beyond this, so it meets the baseline score of 3 where the schema does the heavy lifting.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description 'Retrieve a database' is a tautology that essentially restates the tool name 'API-retrieve-a-database' without adding meaningful specificity. While it indicates a retrieval action on a database resource, it lacks details about what exactly is retrieved (structure, content, metadata) and doesn't differentiate from sibling tools like 'API-retrieve-a-page' or 'API-retrieve-a-block' beyond the resource type.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus alternatives. There are no explicit instructions, prerequisites, or comparisons to sibling tools (e.g., when to retrieve a database vs. a page or block), leaving the agent with no contextual cues for selection.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Retrieve a page
| Name | Required | Description | Default |
|---|---|---|---|
| page_id | Yes | Identifier for a Notion page | |
| filter_properties | No | A list of page property value IDs associated with the page. Use this param to limit the response to a specific page property value or values. To retrieve multiple properties, specify each page property ID. For example: `?filter_properties=iAk8&filter_properties=b7dh`. |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. 'Retrieve a page' implies a read-only operation but doesn't specify authentication requirements, rate limits, error handling, or what the response contains. For a tool with no annotation coverage, this is a significant gap in behavioral transparency.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is extremely concise with just two words, 'Retrieve a page', which is front-loaded and wastes no space. While under-specified in content, it earns full marks for brevity and structure as every word contributes directly to the core purpose without redundancy.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the complexity of a retrieval tool with 2 parameters, no annotations, and no output schema, the description is incomplete. It doesn't explain what a 'page' is in context (Notion), how results are returned, or any behavioral aspects. The agent lacks sufficient context to use this tool effectively beyond basic parameter passing.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The schema description coverage is 100%, with both parameters ('page_id' and 'filter_properties') fully documented in the input schema. The description adds no additional parameter information beyond what the schema provides, so it meets the baseline score of 3 for adequate coverage when the schema handles the heavy lifting.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description 'Retrieve a page' is a tautology that essentially restates the tool name 'API-retrieve-a-page'. It doesn't specify what kind of page (Notion page) or provide any distinguishing context from sibling tools like 'API-retrieve-a-database' or 'API-retrieve-a-block'. The purpose is minimally stated but lacks specificity and differentiation.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided on when to use this tool versus alternatives. With sibling tools like 'API-retrieve-a-database' and 'API-retrieve-a-block', the description offers no context about when this tool is appropriate, what prerequisites exist, or when other tools might be better suited. This leaves the agent without usage direction.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Retrieve a page property item
| Name | Required | Description | Default |
|---|---|---|---|
| page_id | Yes | Identifier for a Notion page | |
| property_id | Yes | Identifier for a page [property](https://developers.notion.com/reference/page#all-property-values) | |
| page_size | No | For paginated properties. The max number of property item objects on a page. The default size is 100 | |
| start_cursor | No | For paginated properties. |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries full burden. It only states the action ('retrieve') without disclosing behavioral traits such as authentication needs, rate limits, error handling, or what 'retrieve' entails operationally (e.g., read-only, data format). This leaves significant gaps for a tool with 4 parameters.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single, efficient sentence with zero waste. It's appropriately sized and front-loaded, making it easy to parse without unnecessary elaboration.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given no annotations, no output schema, and a tool with 4 parameters, the description is incomplete. It fails to address key aspects like return values, error cases, or operational context, making it inadequate for effective tool selection and invocation.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100%, so parameters are well-documented in the schema. The description adds no meaning beyond the schema, as it doesn't explain parameter relationships or usage context. Baseline 3 is appropriate since the schema does the heavy lifting.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description 'Retrieve a page property item' states the action (retrieve) and target (page property item), which is clear but vague. It doesn't specify what a 'property item' entails or differentiate from siblings like 'API-retrieve-a-page' or 'API-retrieve-a-database', leaving ambiguity about scope.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided on when to use this tool versus alternatives. With siblings like 'API-retrieve-a-page' and 'API-retrieve-a-database', the description lacks context for choosing this specific retrieval tool, offering no explicit or implied usage scenarios.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
API-get-background-resultAPI-get-block-childrenAPI-get-one-pagerAPI-retrieve-a-blockAPI-retrieve-a-commentAPI-retrieve-a-databaseAPI-retrieve-a-pageAPI-retrieve-a-page-propertyScored across 8 tools
Most tools have distinct purposes targeting specific Notion resources (blocks, pages, databases, comments, properties), but 'API-retrieve-a-block' and 'API-get-block-children' could cause confusion as both relate to blocks with overlapping retrieval functions. The descriptions help clarify, but the boundary isn't perfectly clear.
The naming follows a mostly consistent 'API-[verb]-a-[noun]' pattern for seven tools, but 'API-get-background-result' and 'API-get-one-pager' deviate with different verb structures ('get' vs 'retrieve') and compound nouns. This mixed convention reduces predictability, though the names remain readable.
With 8 tools, the count is well-scoped for a read-only Notion server, covering key retrieval operations without bloat. Each tool serves a clear purpose, making the set manageable and focused on the server's stated functionality.
For a read-only server, the tool set provides comprehensive coverage of Notion's core resources (pages, blocks, databases, comments, properties) and includes useful utilities like background result retrieval. A minor gap exists in lacking a tool for listing/searching across multiple resources, but agents can work around this with the available retrieval tools.
Read-only MCP server: let AI agents read your ORANO saved-video library, tasks, and memory.
The HubSpot MCP Server acts as a bridge that enables AI assistants and Large Language Models to securely interact with HubSpot CRM data through natural conversation, without requiring users to understand complex API structures. It provides read-only access to standard CRM objects (contacts, companies, deals, tickets, products, invoices, and more) and their associations, secured via OAuth 2.0, allowing AI agents to perform tasks like summarizing deals, fetching company updates, and looking up record changes.
Read-only MCP server for Muovi, Argentina's trust-first local services marketplace (6 tools).
Read-only AI access to HAVN properties, leads, tasks, files, media, and analytics.