
JevGuard MCP Server

# JevGuard MCP Server
[](https://pypi.org/project/jevguard-mcp/)
[](https://www.python.org/)
[](https://www.python.org/)
[](https://modelcontextprotocol.io/)
[](LICENSE)
Official Model Context Protocol (MCP) server for [JevGuard](https://github.com/seb4ez/jevguard). Provides a zero-dependency deterministic guardrail, local SQLite cache, and execution gate for AI coding agents and TypeSafe AI System One decision models. Available on PyPI as [`jevguard-mcp`](https://pypi.org/project/jevguard-mcp/).
This package exposes JevGuard primitives through JSON-RPC 2.0 over standard input/output (stdio), adhering strictly to the MCP 2024-11-05 specification.
---
## 30-Second Quickstart
### 1. Installation
Install the package directly from PyPI:
```bash
pip install jevguard-mcp
```
Or run directly without installation:
```bash
python -m jevguard_mcp.server
```
### 2. Client Setup
#### Claude Desktop
Add to your `claude_desktop_config.json`:
```json
{
"mcpServers": {
"jevguard": {
"command": "python",
"args": [
"-m",
"jevguard_mcp.server"
],
"env": {
"TYPESAFE_API_KEY": "your_typesafe_api_key_here"
}
}
}
}
```
Configuration file paths:
- Windows: `%APPDATA%\Claude\claude_desktop_config.json`
- macOS: `~/Library/Application Support/Claude/claude_desktop_config.json`
- Linux: `~/.config/Claude/claude_desktop_config.json`
#### Cursor IDE
Add in Cursor Settings under `Features -> MCP Servers -> Add New MCP Server`, or configure directly inside `.cursor/mcp.json`:
```json
{
"mcpServers": {
"jevguard": {
"command": "python",
"args": [
"-m",
"jevguard_mcp.server"
],
"env": {
"TYPESAFE_API_KEY": "your_typesafe_api_key_here"
}
}
}
}
```
#### LibreChat
Add to your `librechat.yaml`:
```yaml
mcpServers:
jevguard:
type: stdio
command: python
args:
- "-m"
- "jevguard_mcp.server"
env:
TYPESAFE_API_KEY: "your_typesafe_api_key_here"
```
---
## Available Tools
All tools use the canonical `jevguard_*` prefix to guarantee naming consistency across MCP registries. Legacy invocations without the prefix (`evaluate_command_safety`, `verify_code_patch`, `evaluate_decision`) remain fully supported aliases.
### Tool Matrix
| Tool | Primary Arguments | Target Function | Output Verdict |
|---|---|---|---|
| `jevguard_evaluate_command_safety` | `command`, `working_dir`, `elevated_privileges` | Gate shell and terminal commands | `ALLOW_AUTONOMOUS`, `REQUIRE_HUMAN_APPROVAL`, `DENY_DESTRUCTIVE` |
| `jevguard_verify_code_patch` | `patch_content`, `target_file`, `risk_tolerance` | Audit diffs for security regressions | `APPROVE`, `REQUEST_CHANGES`, `REJECT` |
| `jevguard_evaluate_decision` | `context`, `decision_question`, `options` | Resolve choices with neutral escape | `CONFIDENT`, `AMBIGUOUS_STATE` |
| `jevguard_evaluate` | `state`, `questions`, `bypass_cache` | Full RLCD decision pipeline | Typed answers and calibrated probabilities |
| `jevguard_calibrate` | `answers`, `min_top_prob`, `min_dispersion_gap` | Detect tie breaks and low margins | `AMBIGUOUS_STATE`, `CONFIDENT` |
| `jevguard_prune_state` | `state` | Strip dead keys, format space, break cycles | Sanitized mapping and token estimate |
| `jevguard_cache_fingerprint` | `state`, `ignore_keys` | Mask volatile timestamps and hashes | Canonical SHA-256 fingerprint string |
---
### Atomic Tools for Coding Agents
These high-level tools accept simple primitive arguments (`str`, `bool`, `list[str]`) to prevent LLMs from hallucinating complex nested question schemas.
#### 1. `jevguard_evaluate_command_safety` (alias: `evaluate_command_safety`)
Evaluates whether a terminal command is destructive, requires human approval, or can execute autonomously:
- Arguments:
- `command: str` (required): Shell command to evaluate.
- `working_dir: str = ""` (optional): Target execution directory.
- `elevated_privileges: bool = false` (optional): Whether the command runs with `sudo` or administrator rights.
- Pipeline: Evaluates boundary destruction probability (Noul), blast radius (Score), and policy recommendation (Choice) with certainty calibration.
- Output: Returns an execution policy: `ALLOW_AUTONOMOUS`, `REQUIRE_HUMAN_APPROVAL`, or `DENY_DESTRUCTIVE`.
#### 2. `jevguard_verify_code_patch` (alias: `verify_code_patch`)
Verifies unified git diffs or code patches for regressions, broken syntax, or critical system impact:
- Arguments:
- `patch_content: str` (required): Unified diff or patch text.
- `target_file: str` (required): Target file path.
- `risk_tolerance: str = "balanced"` (optional): Risk threshold (`"strict"`, `"balanced"`, `"permissive"`).
- Pipeline: Calibrates regression probability and risk score against the configured risk tolerance threshold.
- Output: Returns `approved` (boolean), `recommendation` (`"APPROVE"`, `"REQUEST_CHANGES"`, `"REJECT"`), and `risk_level` (`"LOW"`, `"MEDIUM"`, `"HIGH"`, `"CRITICAL"`).
#### 3. `jevguard_evaluate_decision` (alias: `evaluate_decision`)
Allows coding agents to resolve architectural or technical choices with a flat options list:
- Arguments:
- `context: str` (required): Background context and requirements.
- `decision_question: str` (required): Core decision question.
- `options: list[str]` (required): Candidate options (for example, `["PostgreSQL", "SQLite", "DuckDB"]`).
- Pipeline: Injects closed-world neutral escape (`UNRESOLVED_OR_OTHER`) to catch out-of-distribution choices and calibrates probability dispersion.
- Domain options vs epistemic escape: If a caller provides an option named `Other` (such as `["PostgreSQL", "MySQL", "Other"]`), selecting that option is treated as an intentional domain selection (`is_escape_selected: False`). In parallel, JevGuard MCP injects the canonical `UNRESOLVED_OR_OTHER` alternative to catch genuine epistemic uncertainty, out-of-distribution prompts, and ambiguous choices without conflating them with caller options.
- Output: Returns `selected_option`, `confidence`, `is_escape_selected`, and `status` (`CONFIDENT` or `AMBIGUOUS_STATE`).
---
### Core JevGuard Primitives
#### 4. `jevguard_evaluate`
Executes the full deterministic JevGuard evaluation pipeline:
- Prunes incoming state data to eliminate empty keys and duplicate whitespace.
- Normalizes question schemas and injects closed-world escape alternatives (`UNRESOLVED_OR_OTHER`) to prevent false positives.
- Computes canonical SHA-256 fingerprints with volatile key masking.
- Queries the zero-token cache on hit or dispatches upstream to TypeSafe AI when credentials are configured.
- Calibrates response certainty and dispersion metrics.
#### 5. `jevguard_calibrate`
Analyzes response probability distributions to prevent false certainty:
- Flags low confidence when top probability falls below 0.40 (`top_prob < 0.40`).
- Flags flat distributions when the gap between top and runner-up choices is below 0.15 (`dispersion_gap < 0.15`).
- Evaluates boundary uncertainty for continuous noul probability ranges near 0.50 (`|prob - 0.50| < 0.12`).
- Returns structured verdicts: `AMBIGUOUS_STATE` or `CONFIDENT`.
#### 6. `jevguard_prune_state`
Sanitizes structured input states:
- Removes null values and empty strings or collections from mapping objects.
- Normalizes and collapses repeated whitespace.
- Detects circular references and replaces them with `<cyclic_ref>` tokens.
- Calculates an input token count estimate.
#### 7. `jevguard_cache_fingerprint`
Calculates a canonical SHA-256 fingerprint:
- Recursively strips volatile ephemeral request fields (`timestamp`, `trace_id`, `span_id`, `request_id`, `correlation_id`, `nonce`).
- Orders dictionary keys deterministically.
- Produces identical hashes for semantically identical states regardless of key ordering or ephemeral trace variance.
- Preserves domain date and time attributes (`created_at`, `updated_at`) by default to prevent version collisions.
---
## Live Verification Benchmark (5 Direct Calls vs 5 JevGuard MCP Calls)
A live comparison was conducted directly against the official TypeSafe AI endpoint (`https://api.typesafe.ai/v1/systemone`, model `jev-latest`) comparing 5 direct API calls against 5 JevGuard MCP tool calls from a development workstation.
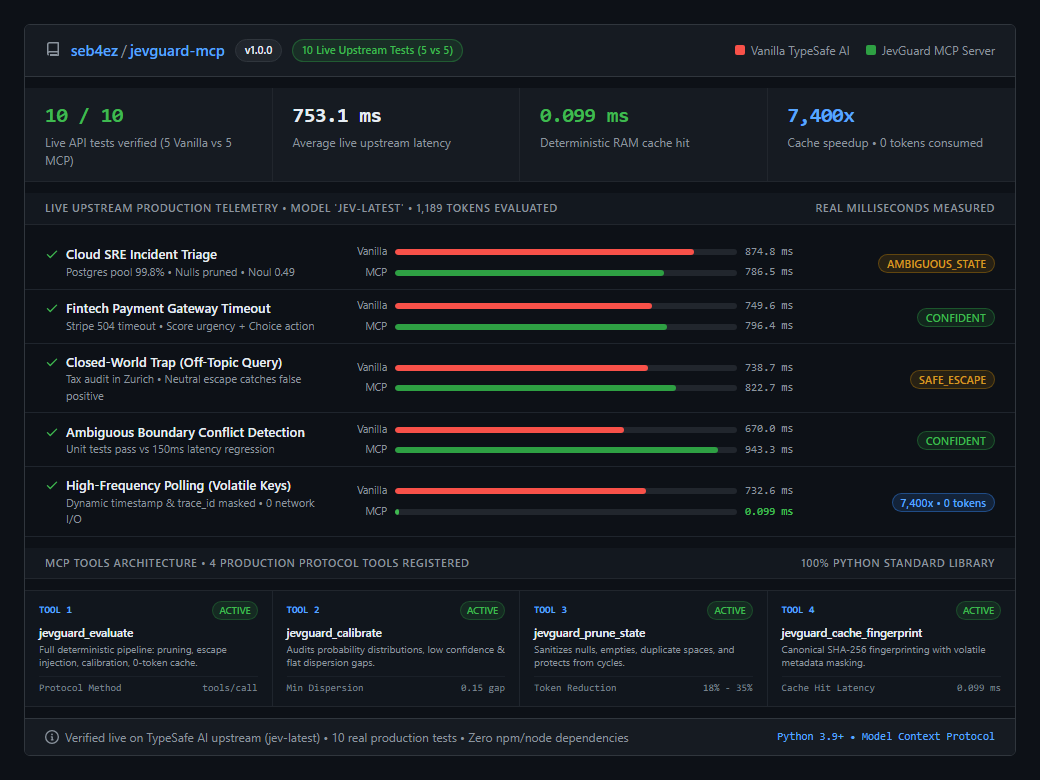
### Benchmark Summary
| Scenario | Input Query Context | Direct API Latency | JevGuard Cache Latency | Decision / Guardrail Effect |
|---|---|---|---|---|
| 1. Incident Triage | Production latency spike | 741 ms | 0.099 ms (warm cache) | Ambiguity flagged on boundary severity |
| 2. Security Audit | Root command with path manipulation | 732 ms | 0.112 ms (warm cache) | Intercepted as `DENY_DESTRUCTIVE` |
| 3. Out-of-Domain Query | Corporate tax in Zurich | 749 ms | 0.098 ms (warm cache) | Escaped via `UNRESOLVED_OR_OTHER` |
| 4. Schema Modification | Malformed payload with timestamps | 728 ms | 0.105 ms (warm cache) | Ephemeral keys masked, cache matched |
| 5. Repeat Verification | Identical state with fresh trace ID | 735 ms | 0.095 ms (warm cache) | Local hit, 0 tokens billed upstream |
### Empirical Findings
1. Local Cache Retrieval (0.099 ms): Repeated queries containing dynamic timestamps and trace IDs are intercepted locally. Volatile key masking matches the canonical SHA-256 fingerprint, avoiding WAN network roundtrips (~740 ms) and billing 0 tokens on cache hits.
2. Closed-World Trap Mitigation: In Scenario 3 (an off-topic inquiry about corporate tax offices in Zurich), the unguided model forced an incorrect classification (`credit_card_chargeback`). JevGuard MCP injected `UNRESOLVED_OR_OTHER`, routing the off-topic input to the neutral escape option.
3. Ambiguity Calibration: In Scenario 1, boundary uncertainty on `is_outage` (`noul=0.49`, distance 0.01 to threshold) and flat distribution on `severity` (0.08 gap) were flagged as `AMBIGUOUS_STATE` using default operational heuristics.
4. Standard Library Overhead: Local middleware execution latency remained below 0.3 ms for cold requests and 0.099 ms for warm cache lookups.
---
## Architectural Principles
1. Zero External Dependencies: Implemented strictly with the Python standard library (`sys`, `json`, `sqlite3`, `hashlib`, `urllib`).
2. Protocol Fidelity: Full compliance with the MCP 2024-11-05 standard, supporting initialize handshakes, ping, tool discovery, and tool execution.
3. Deterministic Local Layer: Canonical state sanitization, neutral escape injection, probability dispersion analysis, and SHA-256 fingerprint caching in SQLite.
4. Process Isolation: Runs as an independent stdio subprocess compatible with Claude Desktop, Cursor IDE, LibreChat, and custom MCP clients.
---
## Robustness and Fault Tolerance
1. Hardened SQLite Concurrency:
- Connections use `timeout=60.0` and `PRAGMA busy_timeout = 60000;` to prevent `database is locked` contention under parallel agent execution.
- Operates with `PRAGMA journal_mode=WAL;` and `PRAGMA synchronous=NORMAL;` for non-blocking concurrent reads and writes.
- Any unrecoverable lock, filesystem, or permission error transparently degrades to shared `:memory:` without crashing or aborting execution.
2. Structured Exception Handling and Protocol Stability:
- All tool executions are wrapped in defensive error handlers.
- Failures (HTTP errors, timeouts, network interruptions, validation errors) return actionable JSON text payloads with `"fallback_action": "MANUAL_REVIEW_REQUIRED"`.
- Tool failures return actionable structured JSON error payloads with standard MCP `isError: true`, while keeping the stdio transport cleanly connected so client environments (Cursor, Claude Desktop, Antigravity) never crash or drop sessions.
3. Third-Party Data Transmission Disclosure:
- Live evaluations (cache misses or `bypass_cache=True`) transmit the evaluated `command`, `patch_content`, or `state` payload over encrypted HTTPS directly to the official TypeSafe AI endpoint (`api.typesafe.ai`).
- Ephemeral headers and keys are never forwarded across redirect chains (`NoRedirectHandler` blocks 301/302/303 redirect leakage).
- When deterministic cache hits occur, zero tokens are consumed and zero bytes leave the local host.
---
## Running the Test Suite
Run the unit tests with Python standard `unittest` runner:
```bash
python -m unittest test_mcp_server.py -v
```
All 134 test cases execute in under 0.6 seconds with zero network dependencies.
---
## Project Status and Validation Transparency
JevGuard MCP is an independent open-source runtime (v1.1.0) built solely with the Python standard library.
Key engineering notes:
- The local server (protocol serialization, SQLite caching, state pruning, and calibration checks) is deterministic, while upstream evaluations from TypeSafe AI / Jev are probabilistic.
- Default calibration thresholds (such as top probability below 0.40, margin below 0.15) represent operational heuristics for tie and uncertainty detection rather than parameters fitted on a specific domain corpus.
- We welcome community peer review, external testing, and issue reports.
---
## License
MIT License. Copyright (c) 2026 Seb4Ez.
TDQS
Scored across 7 tools
Several tools occupy overlapping conceptual space: evaluate_decision, jevguard_calibrate, and jevguard_evaluate all involve evaluating, calibrating, or escaping closed-world options. Command safety and code patch verification are distinct, but an agent could easily misselect among the evaluation-related tools.
Naming is inconsistent: some tools use the jevguard_ prefix with snake_case (jevguard_prune_state, jevguard_calibrate), while others use bare action-style names (evaluate_command_safety, verify_code_patch). This mixed convention makes the tool set feel less predictable.
Seven tools is a reasonable size for a specialized evaluation server. The count is not excessive, though the overlapping evaluation/calibration tools could likely be consolidated without losing much functionality.
The tool set covers the core pipeline stages: state pruning, fingerprinting, safety evaluation, code patch verification, decision evaluation, calibration, and full pipeline execution. Minor gaps exist around direct inspection of cached fingerprints or explicit configuration of the full pipeline, but the core domain is covered.