mcp-server-scraper


Extract clean, readable content from any URL. Returns markdown text, links, and metadata. No API keys, no config. A free alternative to Firecrawl for scraping docs, blogs, and articles.
Works with Claude Desktop, Cursor, VS Code Copilot, and any MCP client. No accounts or API keys needed.
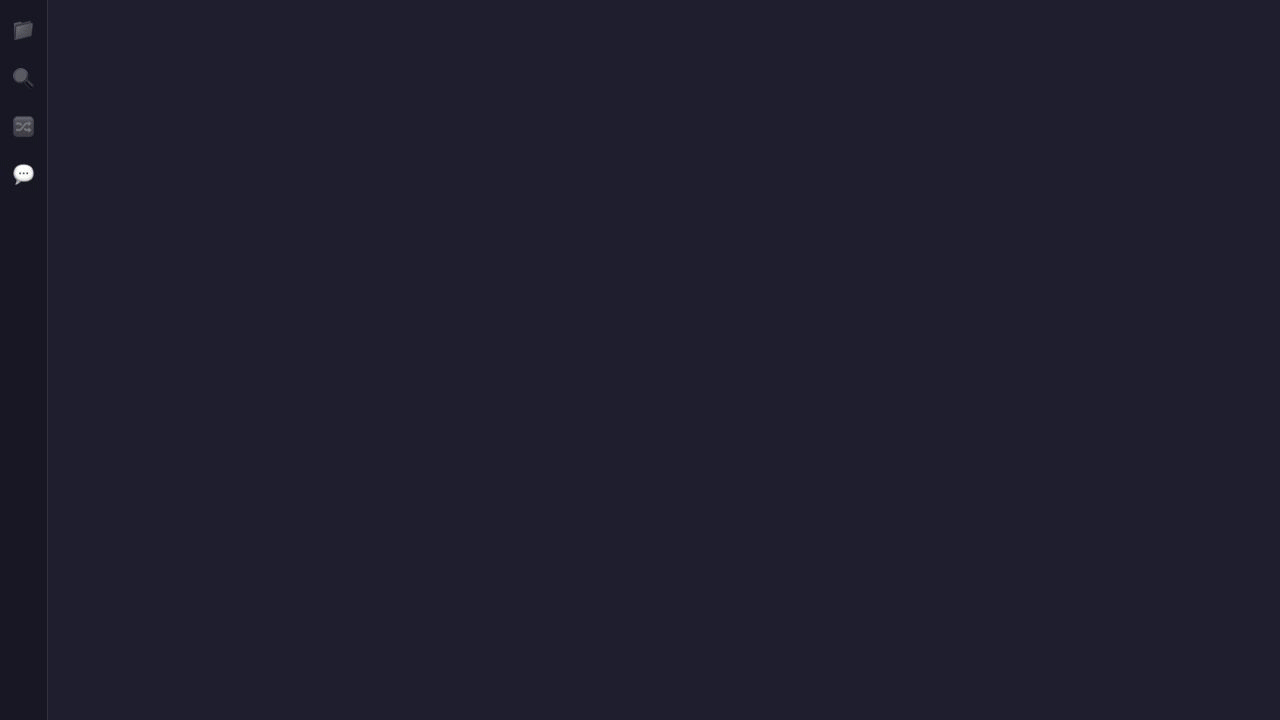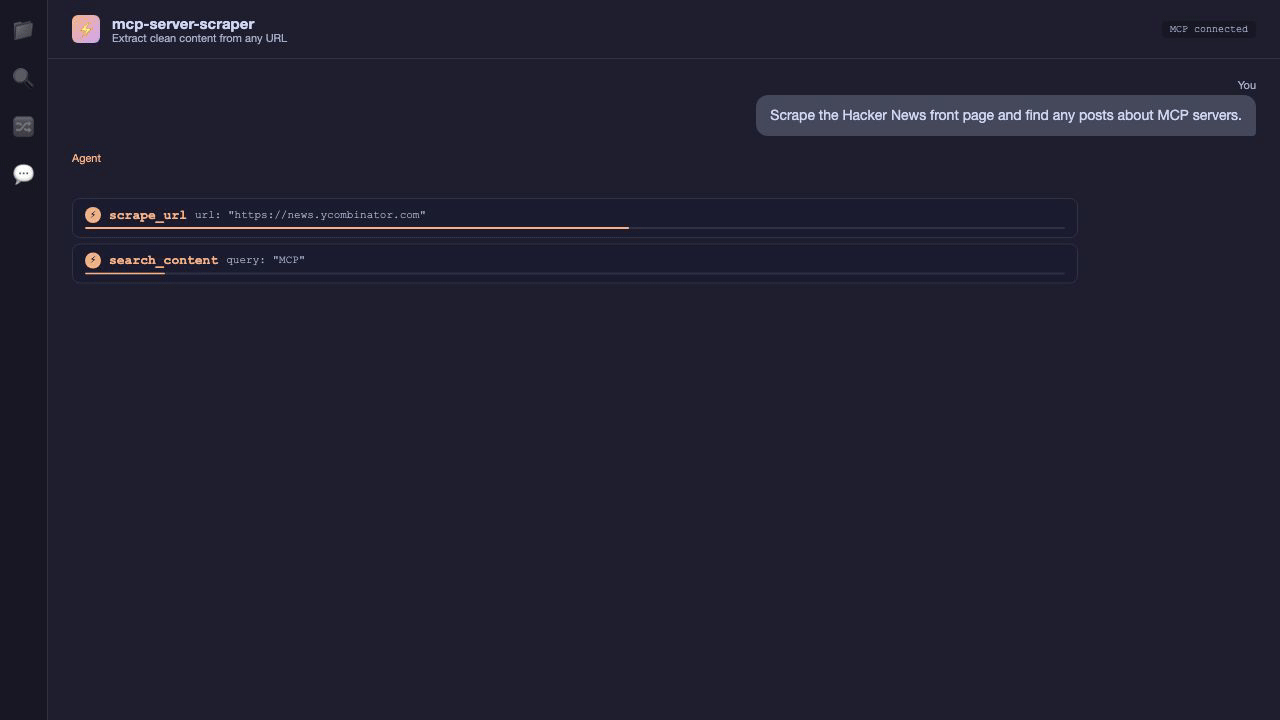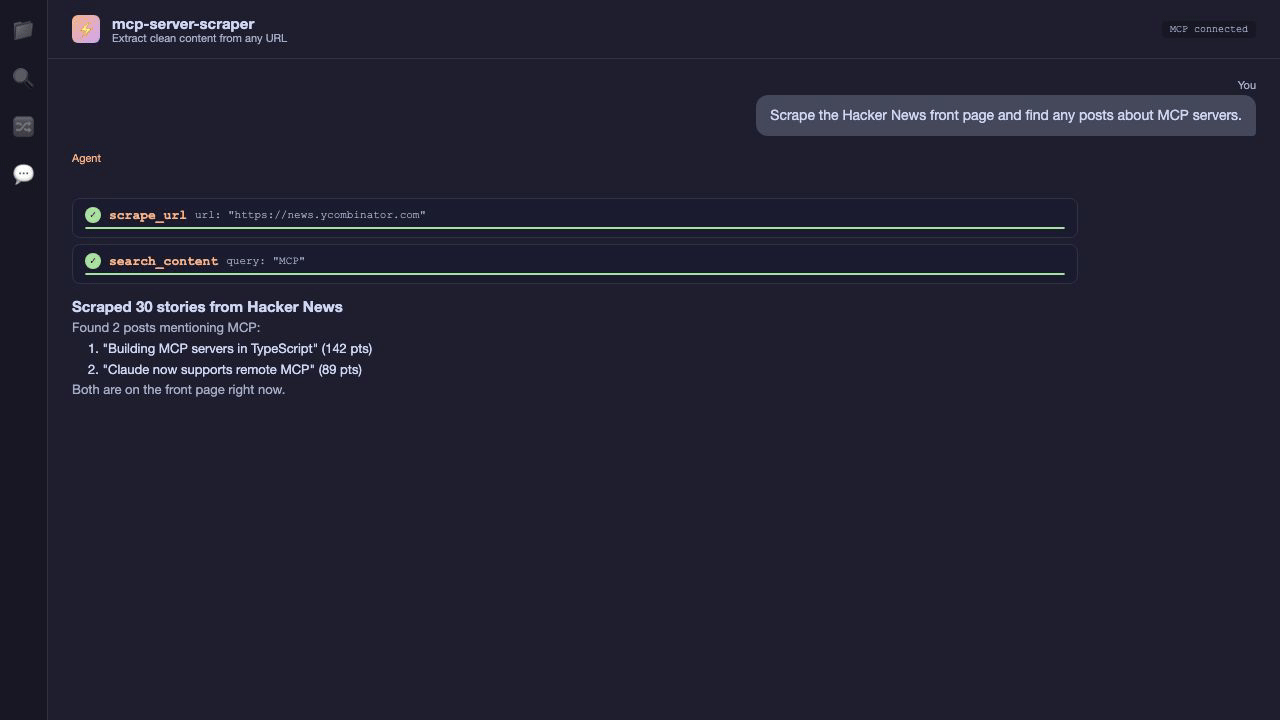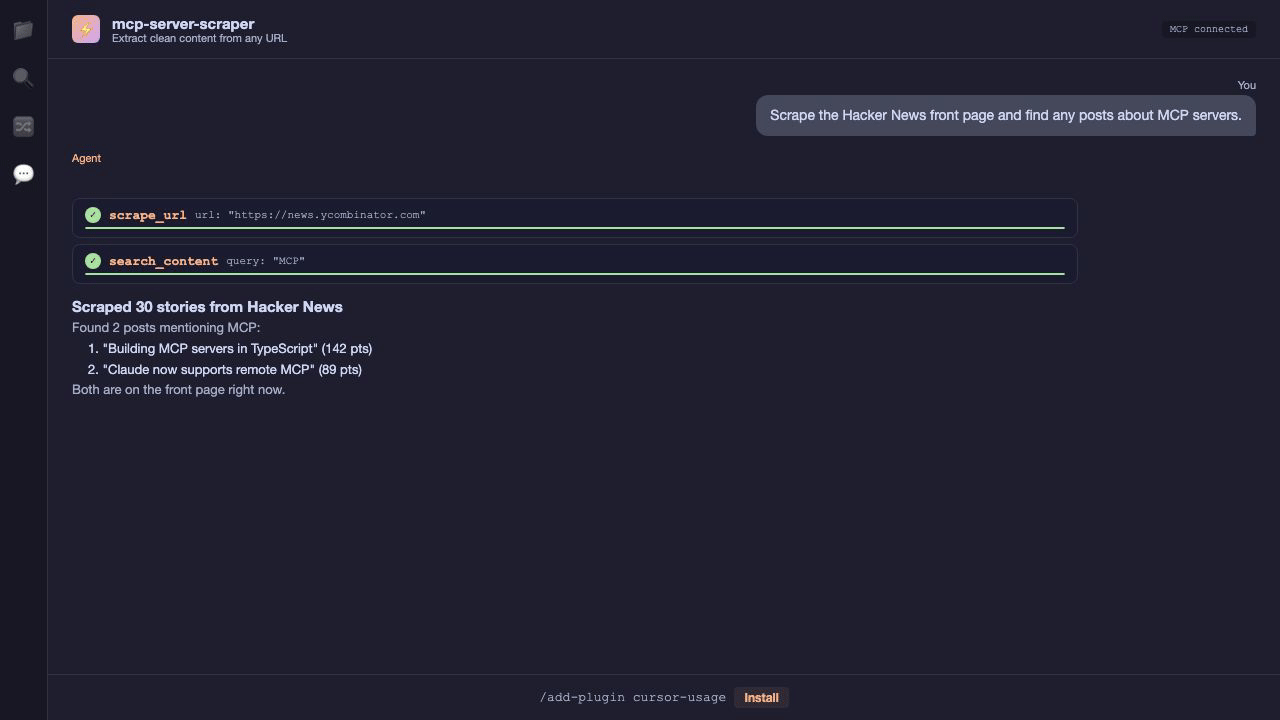
Demo built with remotion-readme-kit
Why
When you're working with an AI assistant and need to reference a docs page, a blog post, or an API reference, you usually end up copy-pasting content manually. Tools like Firecrawl solve this but require a paid API key. This server does the same thing for free. It fetches a URL, runs it through Mozilla Readability (the same engine behind Firefox Reader View), and returns clean markdown. It works well for server-rendered content like documentation sites, blog posts, and articles. It won't handle JavaScript-heavy SPAs, but for the most common use case of "read this docs page and summarize it," it does the job.
Related MCP server: @hauntapi/mcp-server
Tools
Tool | What it does |
scrape_url
| Extract clean text content from a URL (Readability-powered) |
extract_links
| Get all links with href and anchor text |
extract_metadata
| Get title, description, OG tags, canonical, favicon |
search_page
| Search for a query string within the page, return matching lines |
scrape_multiple
| Batch scrape multiple URLs, get title + excerpt per URL |
Quick Start
Cursor
Add to .cursor/mcp.json:
{
  "mcpServers": {
    "scraper": {
      "command": "npx",
      "args": ["-y", "mcp-server-scraper"]
    }
  }
}
Claude Desktop
Add to claude_desktop_config.json:
{
  "mcpServers": {
    "scraper": {
      "command": "npx",
      "args": ["-y", "mcp-server-scraper"]
    }
  }
}
VS Code
Add to your MCP settings (e.g. .vscode/mcp.json):
{
  "mcp": {
    "servers": {
      "scraper": {
        "command": "npx",
        "args": ["-y", "mcp-server-scraper"]
      }
    }
  }
}
Examples
"Scrape the API docs from https://docs.example.com and summarize them"
"Extract all links from this page"
"What's the OG image and description for this URL?"
"Search this page for mentions of 'authentication'"
"Scrape these 5 URLs and give me a summary of each"
How it works
Uses Mozilla Readability (the engine behind Firefox Reader View) plus linkedom for fast HTML parsing in Node. No headless browser needed. Works best with server-rendered pages: docs, blogs, articles, news sites.
Agent Plugins
This repo is an Agent Plugins 1.0.0 package: plugin.json, portable mcp.json, and skills/ ship together with the MCP server.
For Cursor, clone the repo and copy or symlink it to ~/.cursor/plugins/local/mcp-server-scraper, then reload the window. Skills and MCP show up under Customize > Plugins.
The Cursor and VS Code install buttons above still work: they add the same npx -y mcp-server-scraper stdio server as manual JSON.
FAQ
What is mcp-server-scraper?
A free MCP server that turns public web pages into clean markdown using Mozilla Readability. No Firecrawl or other scrape API key.
Does it run JavaScript or SPAs?
No. It fetches HTML and parses it in Node. Use a browser MCP for React dashboards and other client-rendered sites.
How is this different from Firecrawl?
Firecrawl is a hosted scrape API with billing. This server runs locally via npx, costs nothing, and fits doc/blog/article URLs.
Can I install it as an Agent Plugin in Cursor?
Yes. Use the local plugin path under ~/.cursor/plugins/local/mcp-server-scraper so the bundled web-scraping skill loads with the MCP config.
Do I need API keys or env vars?
No. Point your MCP client at npx -y mcp-server-scraper only.
Development
npm install
npm run typecheck
npm run build
npm test
See also
More MCP servers and developer tools on my portfolio.
Author


README built with README Builder
License
MIT © Ofer Shapira
