neurarch-mcp
Officialby neurarch-ai

README.md
# neurarch-mcp
**Know what a GPU job needs before it takes a reservation, from inside your agent. An MCP server for Claude Code, Cursor, Claude Desktop, VS Code, Windsurf and Codex.**
- **Small jobs:** pack them or move them to a smaller card.
- **Large jobs:** the right card count and sharding the first time.
- **Agent-launched jobs:** a gate before the GPU, because an agent cannot size its own job.
[](https://github.com/neurarch-ai/neurarch-mcp/actions/workflows/ci.yml)
[](https://www.npmjs.com/package/neurarch-mcp)
[](https://www.npmjs.com/package/neurarch-mcp)
[](https://pypi.org/project/neurarch-trace/)
[](./LICENSE)
[](https://modelcontextprotocol.io)
[](https://smithery.ai/servers/neurarch-ai/neurarch-mcp)
[](https://github.com/neurarch-ai/neurarch-mcp/stargazers)
Call `size_training_job` before a job launches and the agent learns, for the model, batch and card in front of it: **the peak memory** (weights and optimizer state, activations, stored attention scores, each shown), **the smallest card that holds it**, **the largest batch each card holds**, a two-card split when one card does not, **what one run costs**, and a one-line verdict such as `will not fit a T4: needs ~30 GB with headroom (peak 26 GB) at batch 32, seq 2048, use L40S or batch <= 12`. `history` adds **what that structure measured the last time it ran** in your organisation. After a CUDA out-of-memory error, `diagnose_oom` reads the message against the same estimate and names the cause (too big for the card, fragmentation, another process, logits over a large vocabulary, growth during the run) with the least invasive fix first. Then whether it forward-passes: the structural checks the CI bot runs (`lint_model`, `check_design`), offline too. It answers the same whether a person or an agent wrote the job, which is the question the person who owns the GPU bill is asking.
## See it
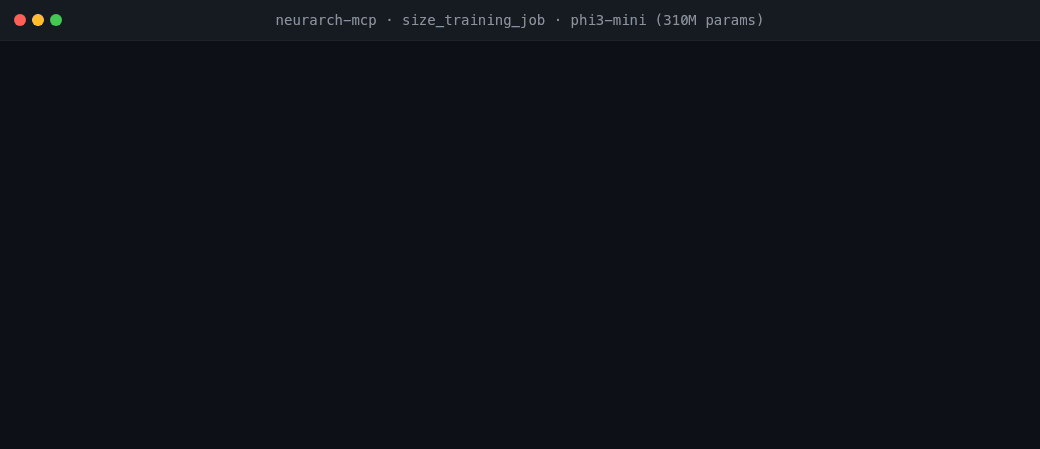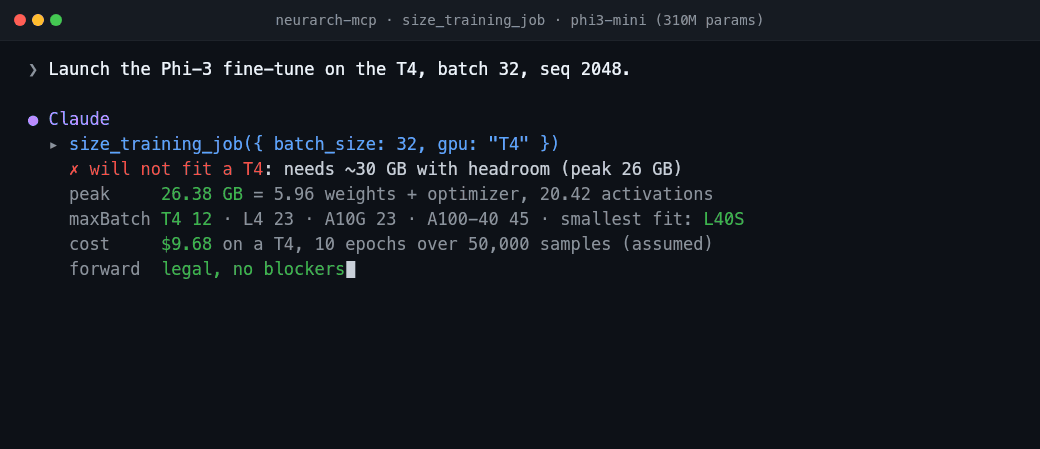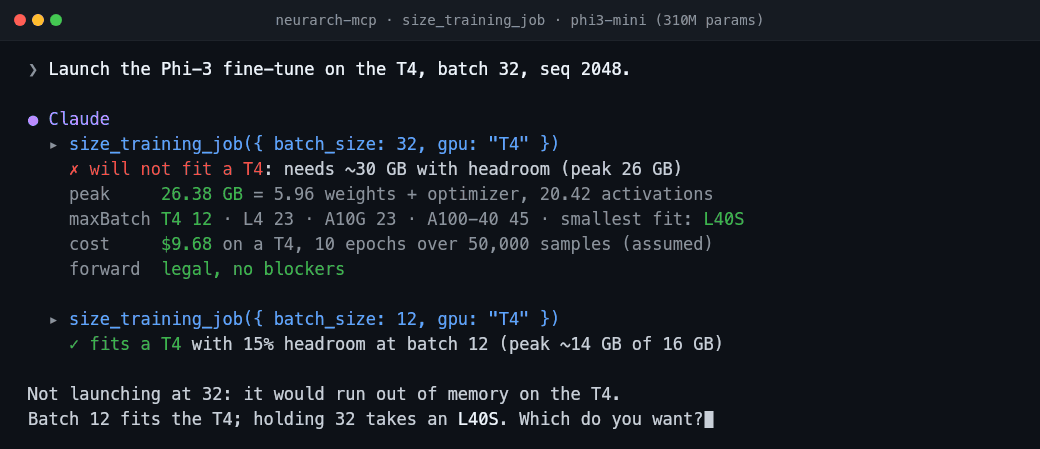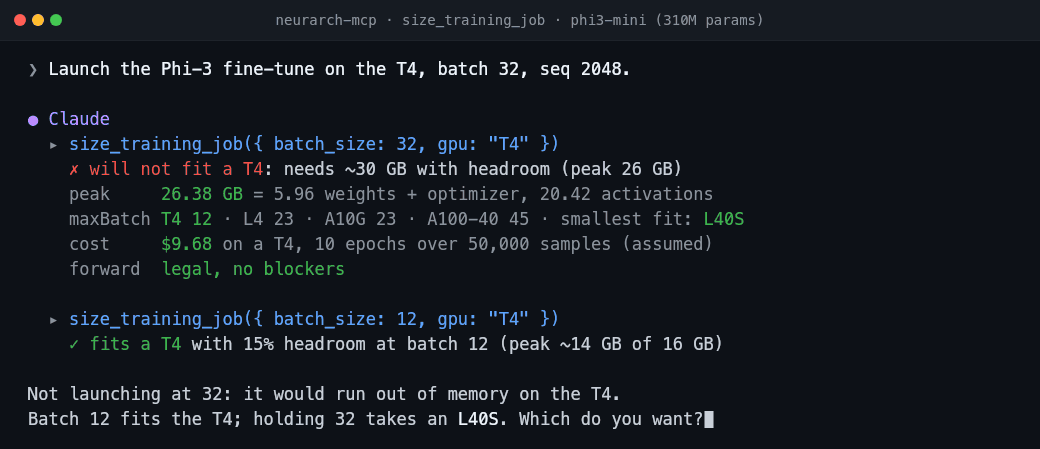
**Before launch.** The job does not fit the card it was about to take, so the agent sizes it again at the batch the tool named:
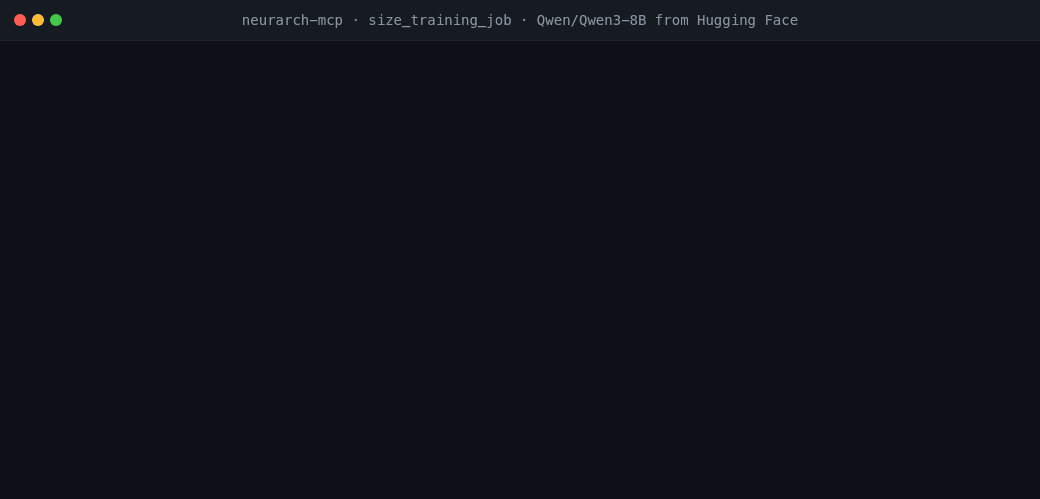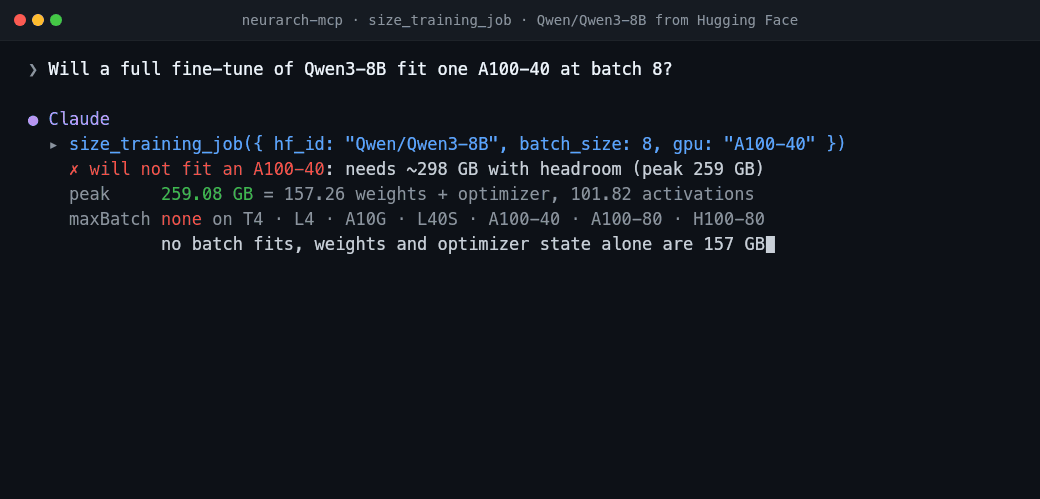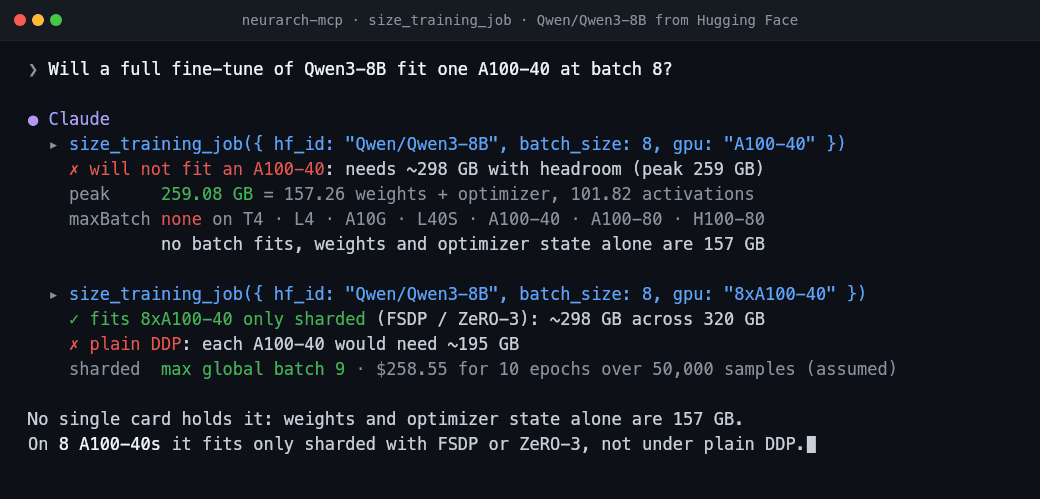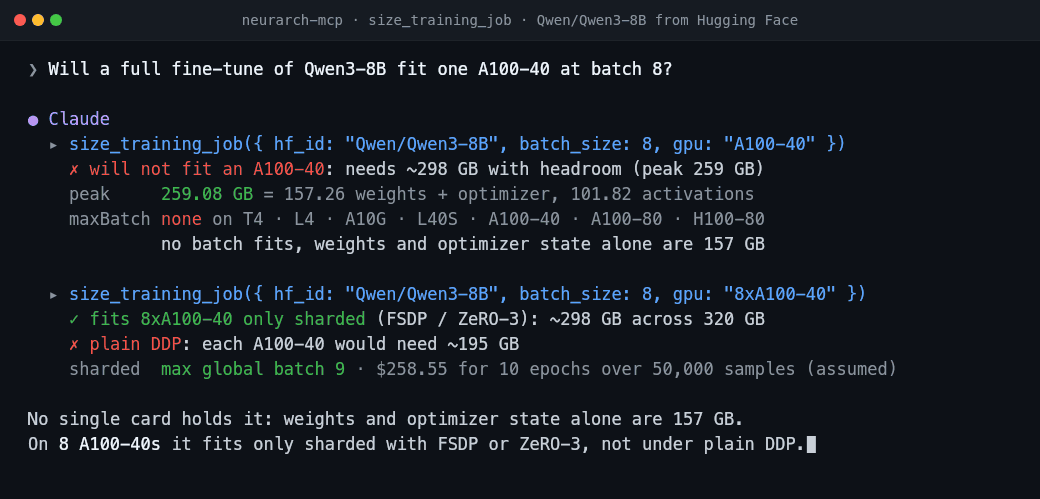
**A model straight from Hugging Face.** Qwen3-8B fits no single card at batch 8, and on eight A100-40s only sharded:
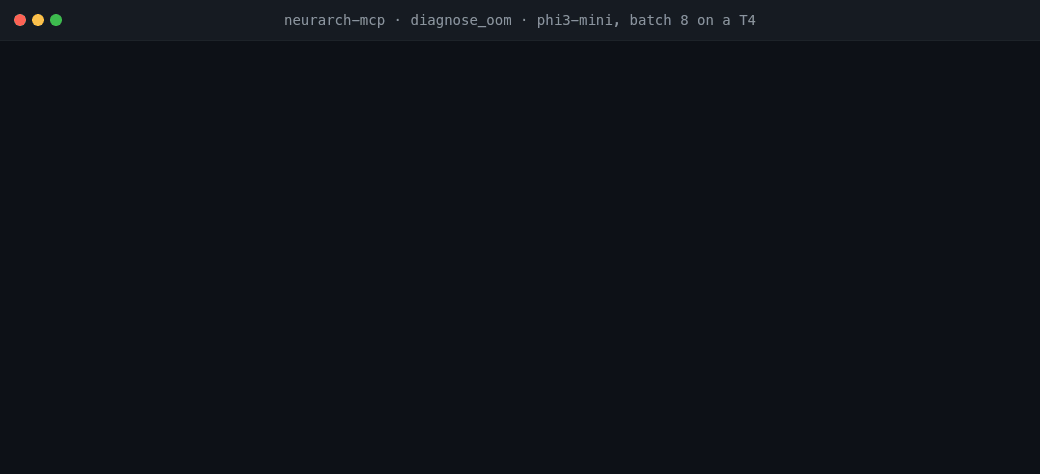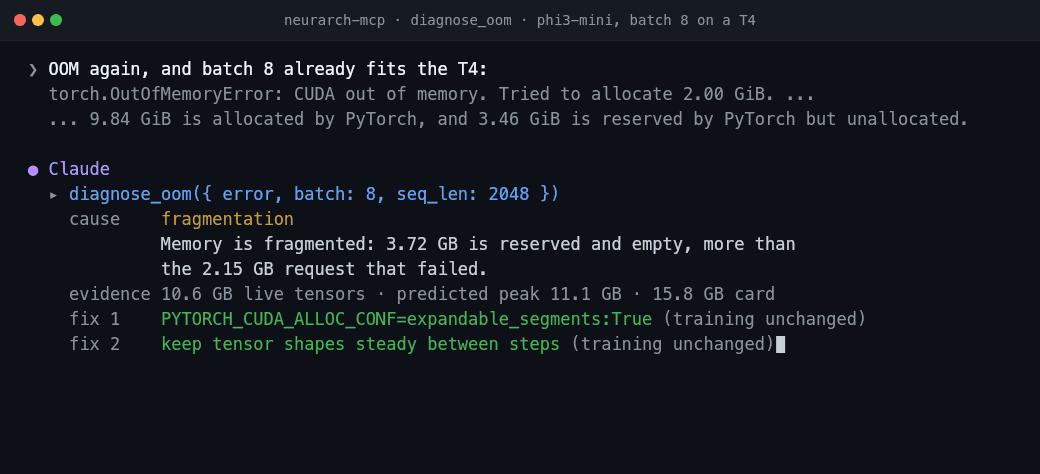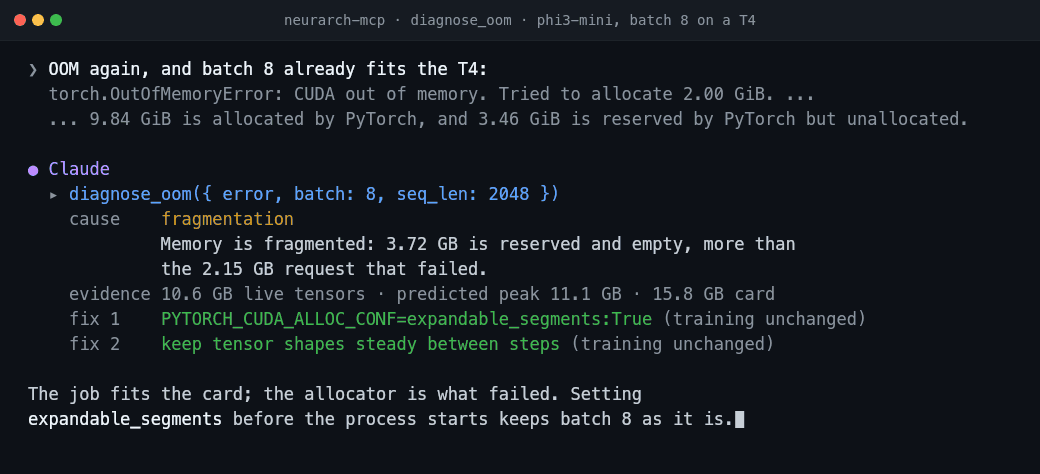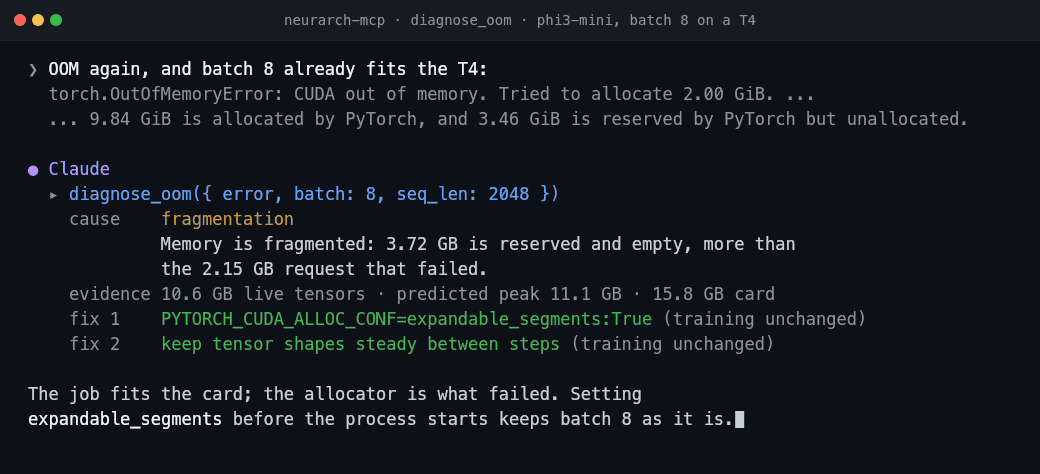
**After a CUDA out-of-memory error.** The message is read against the same estimate, and the cause comes back with the fix that leaves training unchanged listed first:
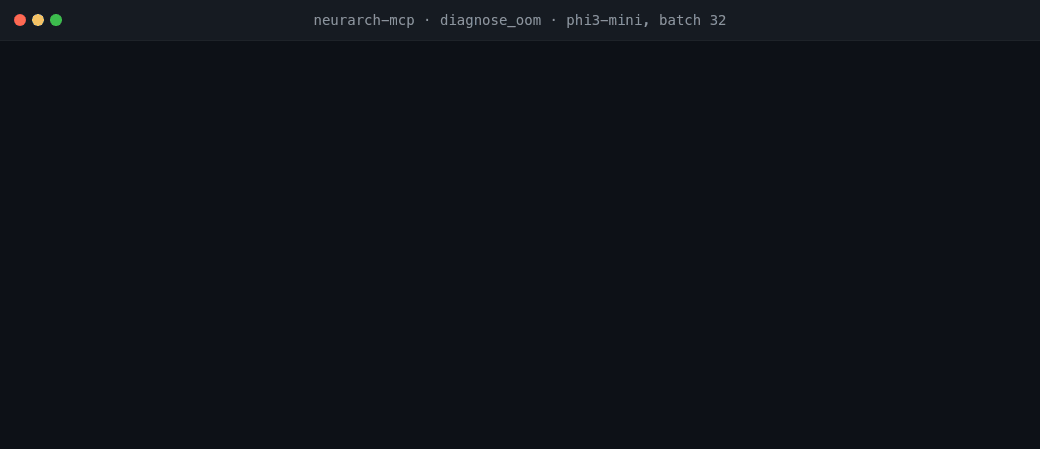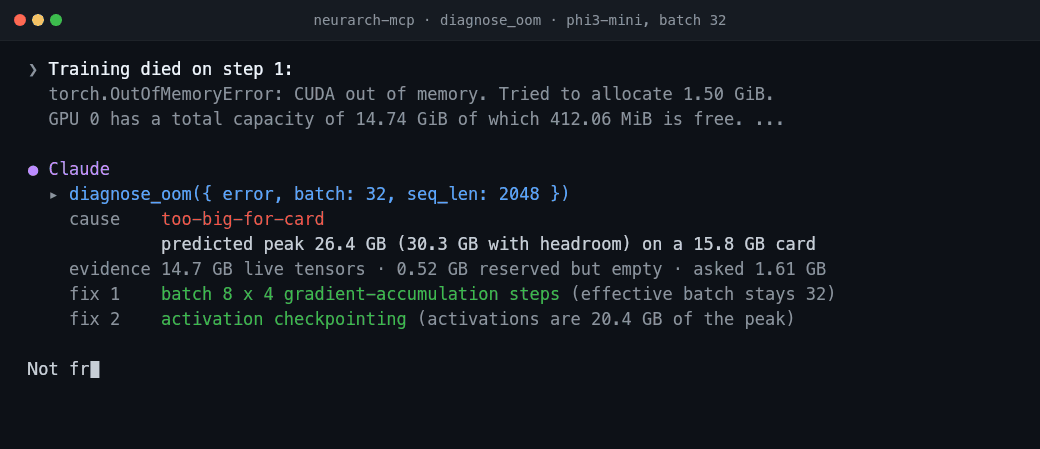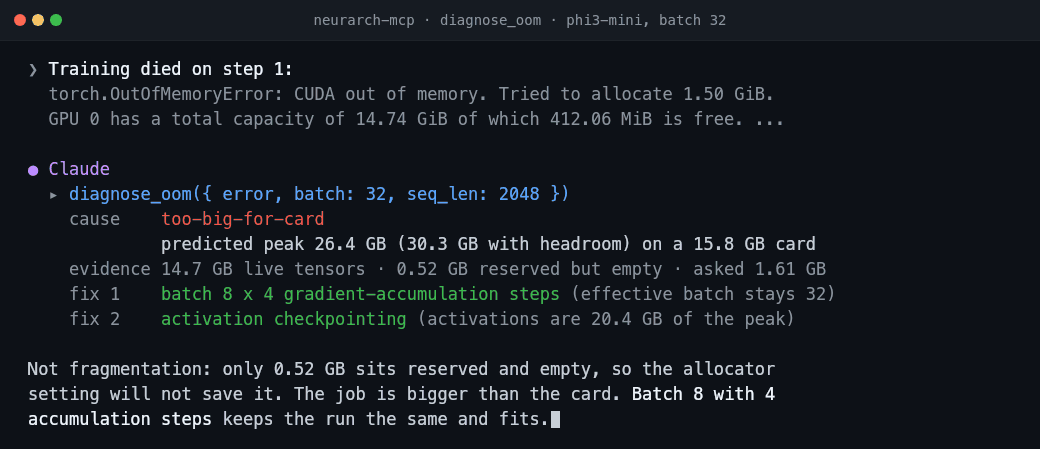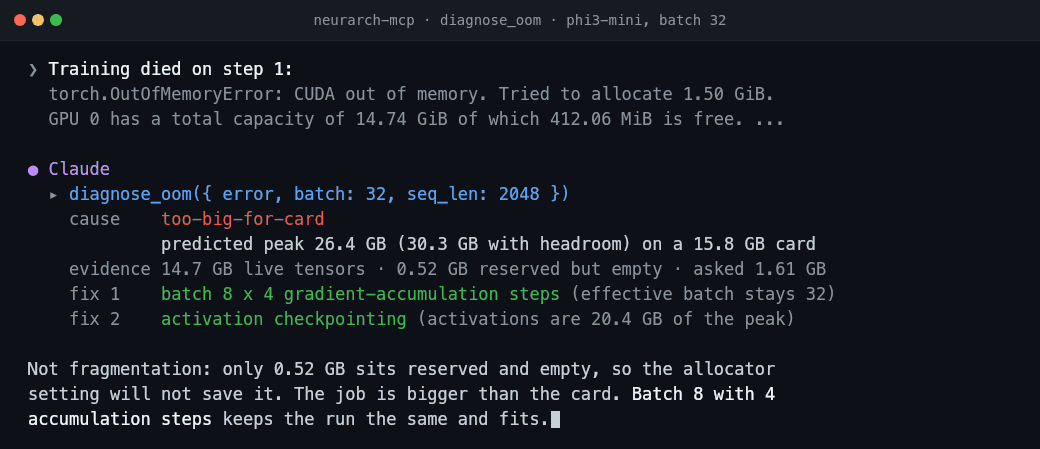
**Not every OOM means a smaller batch.** When the job fits and the allocator does not, the fix leaves training as it is:
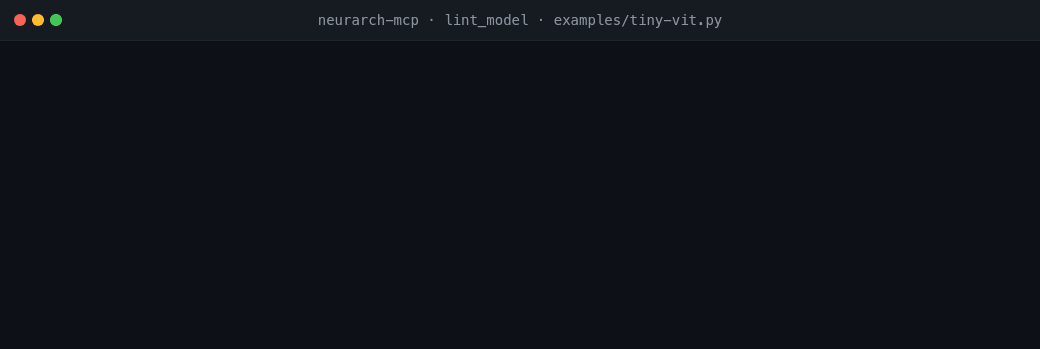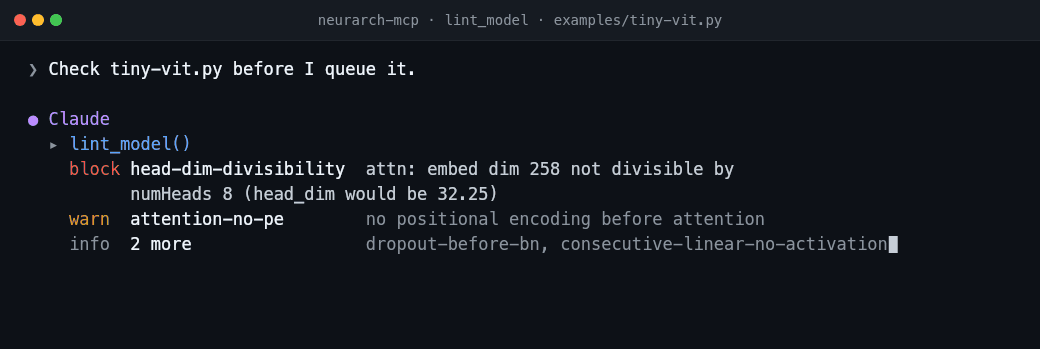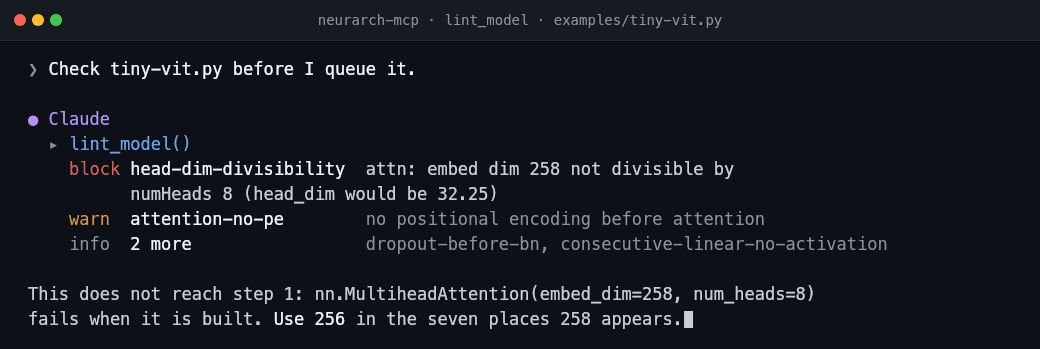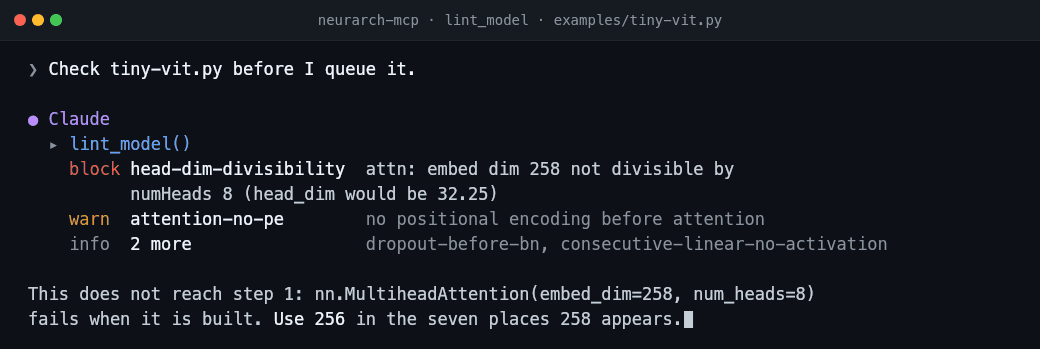
**Whether it forward-passes.** The shipped [`examples/tiny-vit.py`](./examples/tiny-vit.py) builds an attention layer its head count does not divide:
**Without the agent asking.** [`neurarch-mcp hook`](#a-claude-code-hook-refuse-the-launch-that-will-not-fit) sizes a `python train.py` launch before the Bash call runs and blocks the one that will not fit:
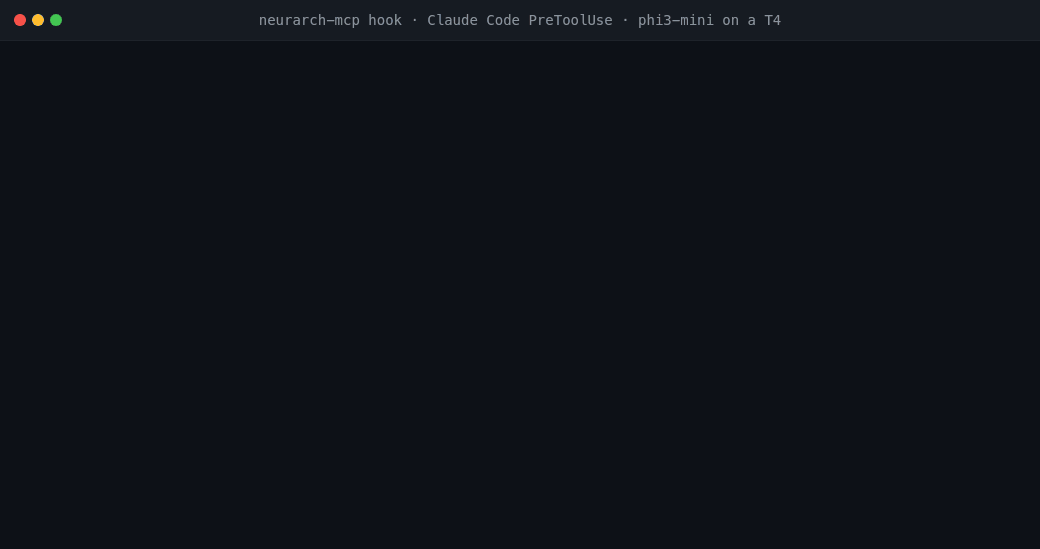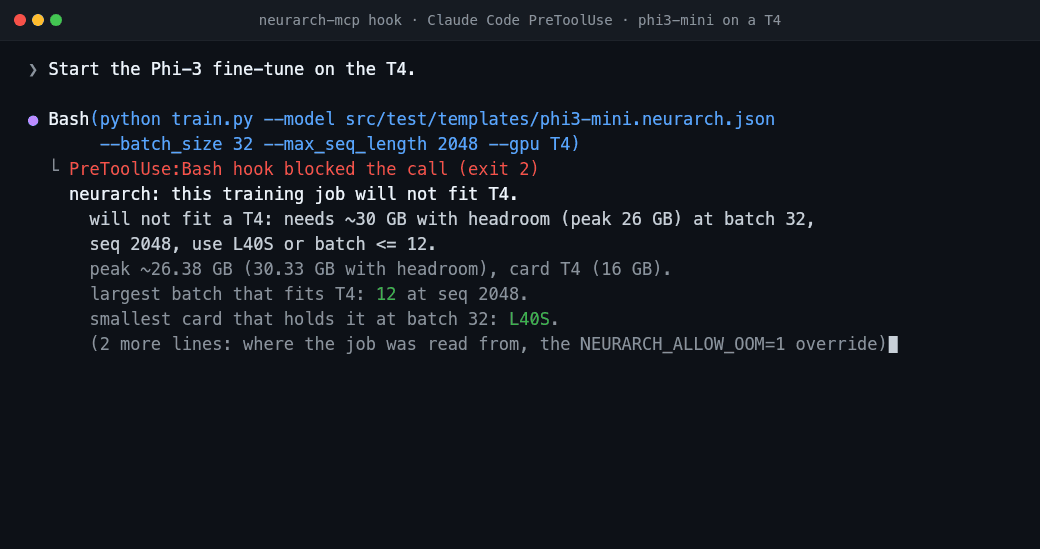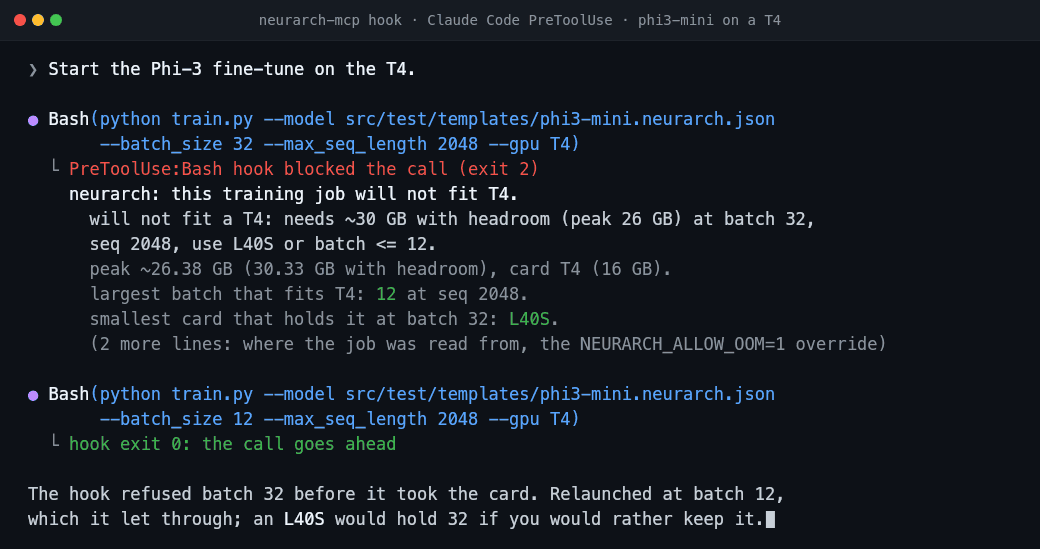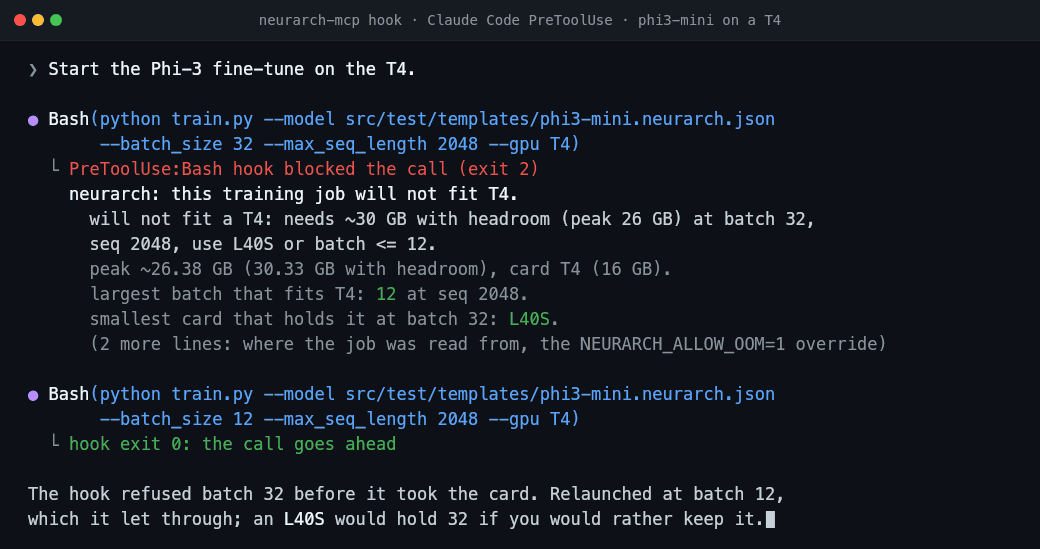
<sub>Every number in these recordings is copied from the tools' real output (0.17.1 and 0.17.2) on [`phi3-mini`](./src/test/templates/phi3-mini.neurarch.json), [`tiny-vit.py`](./examples/tiny-vit.py) and `hf:Qwen/Qwen3-8B`; the error texts are examples and the model's closing sentences are scripted. [`scripts/demo-anim/`](./scripts/demo-anim/) has the calls.</sub>
The memory number is a calibrated estimate of the training peak under AdamW with bf16 autocast, not a measurement: 1.2 x 16 bytes per parameter, plus, per sample in bf16, 0.88 x every layer output, 3.64 x stored attention scores (eager attention only; SDPA and flash keep none), 1.34 x each layer's weight-matrix intermediates, 5.2 x recurrent gate states and 2.02 x the largest single tensor. Fitted on 178 measured runs across 41 architectures, out-of-memory runs included. Held out one architecture at a time, the median error is 7% above 1 GB and it flagged 113 of the 131 times a run did not fit a 16, 24, 40 or 80 GB card, where `accelerate estimate-memory` flagged at most 8. On 25 runs measured after the fit, at the edge of a 24 GB card, the median miss is 14%, so read it as a fit check before a precise number. Every run is public: [neurarch.com/memory-calibration](https://www.neurarch.com/memory-calibration.html).
Get the graph by tracing the model for real shapes, or point the server at a saved graph, a PyTorch `.py`, or a Hugging Face repo. Every tool but three runs on your machine, offline, with no API key and no account. Two of the three, `plan` and `history`, read what a frontier model structurally cannot know: what happened the last time this exact structure trained here. That is not in the weights and not in the repository. The third, `model_changes`, reads the public record of what changed in a Hugging Face model between revisions. They are the only tools in this package that open a socket.
## Install
```bash
claude mcp add neurarch -- npx -y neurarch-mcp /abs/path/to/model.py # Claude Code
```
Or, in Claude Code, the server, the launch hook and the skill in one [plugin](#claude-code-plugin): `/plugin marketplace add neurarch-ai/neurarch-mcp`, then `/plugin install neurarch@neurarch-ai`.
[<img src="https://img.shields.io/badge/Add%20to-Cursor-000000?logo=cursor&logoColor=white" alt="Add to Cursor" height="28">](cursor://anysphere.cursor-deeplink/mcp/install?name=neurarch&config=eyJjb21tYW5kIjoibnB4IiwiYXJncyI6WyIteSIsIm5ldXJhcmNoLW1jcCIsIi4vbW9kZWwucHkiXX0=)
[<img src="https://img.shields.io/badge/Install%20in-VS%20Code-0098FF?logo=visualstudiocode&logoColor=white" alt="Install in VS Code" height="28">](https://vscode.dev/redirect/mcp/install?name=neurarch&config=%7B%22name%22%3A%20%22neurarch%22%2C%20%22command%22%3A%20%22npx%22%2C%20%22args%22%3A%20%5B%22-y%22%2C%20%22neurarch-mcp%22%2C%20%22%24%7BworkspaceFolder%7D%2Fmodel.py%22%5D%7D)
[<img src="https://img.shields.io/badge/Claude%20Desktop-.mcpb-D97757?logo=anthropic&logoColor=white" alt="Claude Desktop bundle" height="28">](https://github.com/neurarch-ai/neurarch-mcp/releases/latest)
Per-client config for Claude Desktop, Cursor, VS Code, Windsurf and Codex is [below](#client-setup). Node 20+ is the only requirement; there is no install step beyond `npx`.
## What it looks like
An agent about to launch a fine-tune on a T4, against [`src/test/templates/phi3-mini.neurarch.json`](./src/test/templates/phi3-mini.neurarch.json) (a 310M-parameter Phi-3 block, one of the Neurarch app's templates). The output is the tool's, trimmed:
```
Agent ▸ (calls size_training_job { batch_size: 32, gpu: "T4" })
verdict will not fit a T4: needs ~30 GB with headroom (peak 26 GB) at batch 32,
seq 2048, use L40S or batch <= 12
memory peak 26.38 GB = 5.96 weights + optimizer state, 20.42 activations
(SDPA: the 40.13 GB of attention scores eager would keep are not counted)
maxBatch T4 12, L4 23, A10G 23, A100-40 45, L40S 56, A100-80 99, H100-80 99
cost $9.68 on a T4, 10 epochs over 50,000 samples (assumed; pass samples)
forwardPasses legal, no blockers
lastRun fingerprint 4e0b97b4: call history for what it measured last time
(same job, attention: "eager", gpu: "A100-40")
verdict will not fit an A100-40: needs ~76 GB with headroom (peak 67 GB) at batch 32,
seq 2048, use A100-80 or batch <= 15
memory peak 66.51 GB = 5.96 weights + optimizer state, 60.55 activations
(40.13 GB of them the attention scores eager keeps)
```
A real exchange against [`examples/tiny-gpt.neurarch.json`](./examples/tiny-gpt.neurarch.json), about where the budget lives:
```
You ▸ Where does the parameter budget live, and is it safe to drop block_1?
Claude ▸ (calls describe_architecture)
tiny-gpt: 8 layers, depth 7, 57.8M params, 8.27 GMACs.
Heaviest by params: token_embedding (25.7M, 44%), lm_head (25.7M), block_0/1 (3.1M each).
Heaviest by compute: lm_head, then the two decoder blocks. Validation: clean.
(calls layer_impact { names: ["block_1"] })
Downstream of block_1: final_norm and lm_head (shape-sensitive, weight-carrying), then output.
The budget is dominated by the embedding + LM head (~89%), not the decoder blocks,
so dropping block_1 frees only ~3.1M params (~5%) while removing one of just two
decoder layers. It is structurally safe (final_norm just re-reads block_0's output),
but it is the wrong lever if your goal is shrinking the model. Quantizing the
embedding/head would do far more.
```
And whether it forward-passes, shown on [`examples/tiny-vit.py`](./examples/tiny-vit.py) in the [recording above](#see-it). That is a runtime crash sitting in source that reads fine, found offline in milliseconds, with no key and no account. The same rule set the [Neurarch CI action](https://github.com/neurarch-ai/neurarch-lint) reports, so a clean result here is a clean CI run. The rules are measured (the crash rules: 96 of 96 blocked graphs crashed PyTorch forward, 80 of 80 passes ran); the static parser in front of them is the weaker half, and [we measured that too](#what-the-static-parser-can-read).
## Three ways in, in order of how well they work
| Input | What the agent gets | How |
|---|---|---|
| **A traced graph** (`neurarch-trace`). **Start here.** | Everything, with real shapes, because they are read at runtime rather than inferred from text. Handles what static parsing cannot: `from_pretrained`, timm, models spread across files, anything built dynamically. The `trace_model` tool runs this for the agent. | `pip install neurarch-trace`<br>`NEURARCH_TRACE=1 python train.py` (no target, no shapes, no edit: it records the first forward pass the script runs)<br>or `neurarch-trace my_pkg.model:build --input 1,3,224,224` |
| **A Hugging Face repo** | The architecture from `config.json`, with the published parameter count next to the graph's so you can see how close it is (Qwen2.5-0.5B: 494.00M against 494,032,768). | `npx -y neurarch-mcp hf:Qwen/Qwen2.5-0.5B --hf` |
| **A self-contained PyTorch `.py` file**. The fallback. | Layers, types, hyperparameters and wiring, when the file builds its own layers with literal sizes. Shapes and FLOPs are unknown, because the source never says what goes in, and are reported as unknown rather than as zero. On real repositories this is the weak path, and we measured how weak: a graph a person would recognise for **41% of 116 real model files**, and of the block and warn findings raised on them, **zero were real defects** when hand-judged. Good enough to orient with, not to act on. [The study](#what-the-static-parser-can-read). | `npx -y neurarch-mcp model.py` |
A `.neurarch.json` saved from the [Neurarch app](https://neurarch.com) (**File → Save**) is the fourth, and carries shapes, groups and design notes. Add `--watch` so the agent sees app-side saves without a restart.
**The flow this server is built around**, in one line each: `size_training_job` before any job launches, `history` for what that structure measured last time, `trace_model` for a graph with real shapes, `plan` for the card the CI bot posts, `lint_model` / `check_design` for whether it forward-passes, `suggest_fix` for the edit. Everything else answers a question one of those raised.
### What the static parser can read
We measured it rather than describe it: [`docs/REAL_REPOS_STUDY.md`](./docs/REAL_REPOS_STUDY.md) runs the parser and linter over 116 model files from 59 popular repositories (nanoGPT, HF `modeling_*.py`, timm, torchvision, DiT, MAE, CLIP, Mamba, SAM, diffusers and more). The parser returns a graph for 86% of files and a graph a person would recognise as the model for 41% (Llama, Qwen2, Mistral and Gemma come back as 58-node graphs; nanoGPT as 72), up from 63% and 8% in August. Re-measured 2026-09-09 with per-edge provenance: every edge the importer chained from statement order rather than read out of `forward()` is marked, the rules that are about adjacency hold back on those, and block+warn findings fell from 92 to 37 with two thirds of the parser artefacts gone. Real defects found on either engine: still zero. The graph is good enough to orient with and not yet good enough to lint from; run `trace_model` before acting on a finding from a `.py`.
Three consequences are in this release. A graph from source carries a `parseQuality` grade (`full`, `partial`, `thin`) on `describe_architecture` and `lint_model`, with the fix named. Dimension rules are held back on layers whose dimension is still source text, and the count is reported as `suppressed` rather than dropped. And `find_models` marks thin parses `partial` so an agent does not build a plan on two layers. For real repositories, use `neurarch-trace`: it reads the numbers at runtime, which is the only place they exist.
Every read tool also takes an optional `model_path`, so **one server covers a whole repository**: ask about `baseline.py`, then `variant_b.neurarch.json`, then `zoo:llama-3-8b`, without restarting anything. `find_models` tells the agent what is there.
## Tools
### Start here: size the job before it launches
| Tool | Answers |
|---|---|
| `size_training_job` | **What a training job needs before it takes a GPU reservation.** Inputs: the model (the server's, `model_path` to a `.py`, a traced `.neurarch.json`, `zoo:<id>` or `hf:<org/name>`, or `hf_id`), `batch_size`, and optionally `gpu` (`"A100-40"`, `"H100"`, `"8xH100"`), `seq_len`, `attention` (`sdpa` default, `flash`, `eager`), `epochs` and `samples` for the price, and `data` (`seq_len`, `tokenizer_size`, `num_classes`, `image_size`, `channels`). Returns the training peak at that batch with its weights-and-optimizer, activation and attention-score parts; the smallest card that holds it with 1.15x headroom; per card a `gpuVerdict` of `fits`, `borderline` or `does_not_fit` against an `upperBound` (the estimate x 1.43, at or above the measured peak on 95% of 91 held-out runs), with `smallestSafeGpu` (the cheapest card that holds the upper bound) and `maxBatchSafe`, and a borderline verdict says to measure one step before reserving; with `data` or `seq_len`, a `dataFit` report on whether the data fits what the model accepts (a sequence past a learned position table, a tokenizer larger than the embedding, labels past the classifier head, an image size or channel count the first layer was not built for, each a first-batch crash), the label count read from an `hf:` model's own `config.json`; the largest batch on each of T4, L4, A10G, L40S, A100-40, A100-80 and H100-80; a two-card split when one card does not hold it; one run's cost on the requested card or the cheapest that fits; a verdict line; whether the graph forward-passes; the structural fingerprint for `history`; and the held-out accuracy sentence. An N-card request is read both as plain DDP (a full copy per card at the per-device batch) and as sharded FSDP / ZeRO-3. Computed by the same `buildPlan` the Neurarch app, the CI bot and `POST /api/v1/plan` run, vendored, offline. A graph that feeds a hidden-state or image tensor into a token embedding is refused rather than sized, because the number would be wrong by the hidden width. |
| `diagnose_oom` | **Why a job ran out of GPU memory, and the smallest change that fixes it.** Call it after a CUDA out-of-memory error, before changing batch size. Inputs: `error` (the text as printed, either PyTorch wording), and optionally the model (as above, or `hf_id`, read from the local config cache with no network when it is there), `batch`, `seq_len`, `step`, `attention`, and `inference: true` with `gen_tokens` for a generation job. It reads the allocated, reserved-but-empty, other-process and failing-request numbers out of the message, compares them with the same predicted peak `size_training_job` uses, and returns one `cause` (`too-big-for-card`, `fragmentation`, `other-process`, `large-logits`, `undeclared-memory`, `grows-during-run`, `unknown`), a `summary`, the `evidence` lines it was read from, `fixes` ordered least invasive first with a `changesTraining` flag on each, and the `job` facts used. A smaller batch is offered only when the job is too big for the card, and then with the gradient accumulation that keeps the effective batch. The diagnosis is the app's own (`npx neurarch oom`), vendored in the plan bundle. |
| `check_edit` | **Whether an edit to a model's config or architecture is one that runs and is wrong, and what it did to memory.** Call it after editing and before training. Inputs: the base (`base_model_path`: a `.py`, a `.neurarch.json`, `zoo:<id>` or `hf:<org/name>`; or `base_config`) and the changed model (the server's, `model_path`, `model_source`, or `config`); `base_config` and `config` take a Hugging Face `config.json` as an object, JSON text or a path. Optionally `lora_target_modules`, `batch` (default 32), `seq_len`, `gpu`, `attention`. Returns `findings`, each with a stable `rule`, a severity, the tensors or keys it is about, and `seenIn` (the public upstream reports of that failure): `vocab-resize-incomplete` (a resize that left a token-indexed tensor at the old vocabulary), `weight-tying-lost`, `attention-config-drift` (heads, `head_dim`, `hidden_size` and kv heads that have to move together), `rope-context-drift` (a longer context with no RoPE scaling), and, against `lora_target_modules` matched the way PEFT matches it, `lora-target-no-match`, `lora-target-partial` and `lora-target-wrapper`; config divisibility comes back under the lint ids `head-dim-divisibility` and `gqa-head-divisibility`. Then `memory`: the training peak before and after at that batch and sequence length, the delta, and whether the job still fits `gpu` (or the smallest card that holds it, before and after), from the same estimate `size_training_job` uses. The checks are the app's own (`src/utils/editChecks.ts`), vendored in the plan bundle. |
### Before a multi-GPU or serving launch
`check_parallel_layout` says whether a TP / PP / DP / CP / EP split is legal, which pipeline stage is the straggler, the predicted step slowdown against a balanced split and the split that removes it, every time labelled predicted (per-card matmul efficiency fitted on public GEMM measurements, the 1F1B schedule simulated op by op, never timed):
```text
check_parallel_layout { model_path: "hf:Qwen/Qwen3-8B", tp: 4, pp: 4, micro_batch: 1, global_batch: 32, seq_len: 4096, gpu: "h100" }
-> legal on 16 x h100-sxm; predicted 15.5% slower per step than a balanced split (slowest stage 3);
split 10,10,9,7 is predicted 11.4% faster; bubble 8.6%; 1 warning
```
`check_serving_config` reads a vLLM, SGLang or llama.cpp launch line against the model's `config.json`, `tokenizer_config.json`, `chat_template.jinja` and `generation_config.json` and the card, and returns findings on TP against the heads, served length against the context, KV memory and concurrency, quantization against the card, and the chat template and sampler defaults (with `against`, what changed from the model it replaces):
```text
check_serving_config { command: "vllm serve Qwen/Qwen3-8B -tp 4 --max-model-len 131072 --max-num-seqs 64", gpu: "l4", gpus: 4 }
-> blocked: Served length 131072 is past the model's 40960-token context
(+ warn: --max-num-seqs 64, but at most 3 requests fit at the full 131072 tokens; info: no --reasoning-parser)
```
Both are the app's own checks (`npx neurarch layout`, `npx neurarch serve-check`), vendored in the plan bundle and offline; an `hf:` model needs `--hf` the first time.
### Before a Hugging Face download moves under you
`check_pins` finds downloads that load whatever `main` points at on the day the job runs (`from_pretrained`, `load_dataset`, `hf_hub_download`, `snapshot_download`, `pipeline`, `vllm serve`, the SGLang server, `hf download`, YAML model keys), with the fix spelled for each file. It is the scanner behind `npx neurarch pin-check`, aligned with Bandit B615, and offline. `model_changes` says what a tracked model changed between revisions (config, tokenizer, chat template, generation defaults, weights), whether each change is breaking under the published rule, and with `since_revision` only what landed after your pin. It reads two public files from [the change record](https://www.neurarch.com/changes-feeds/); a change record says what a revision does mechanically, not that anything broke, and an untracked model has no record rather than no changes.
```text
check_pins { paths: ["."] }
-> 4 downloads not pinned to a commit in 3 files
train.py:2 AutoModel.from_pretrained("Qwen/Qwen3-8B") has no revision: it loads whatever main is when the job runs
fix: Pin a full 40-character commit: revision="<sha>", from https://huggingface.co/Qwen/Qwen3-8B/commits/main (`neurarch pin-check --resolve` looks it up).
model_changes { hf_id: "Qwen/Qwen3-8B" }
-> 1 recorded change, 0 breaking; main is b968826d9c46 (2025-07-26)
```
### The plan card, and the memory behind it
These two are the only two tools in this package that reach the network. `plan` is the artifact: the same card the [Neurarch CI bot](https://github.com/neurarch-ai/neurarch-bot) posts on a pull request and the `neurarch-trace` CLI prints, so the agent and the reviewer read the same words about the same graph.
| Tool | Answers | Sends |
|---|---|---|
| `plan` | **Will it run, what will it cost, which GPUs does it fit, which of your repository's own rules does it break, what changed against a base design, and what happened last time this structure trained here.** `text` comes back verbatim. Policy lines are read from the repository's `.neurarch.yml` (the same file the CI bot reads, merged the same way) unless you pass `policy`; `base_path` adds a diff. `NEURARCH_API_KEY` is optional and adds the history line. `share` is pinned to false: an agent cannot publish your design. | The graph, to `POST /api/v1/plan`. This is the one tool that sends the model. |
| `history` | **What this exact structure measured the last time it trained inside your organisation**: metric, epochs, wall time, cost, newest first, at most 20. Keyed by the graph's 8-character structural fingerprint, so it answers about the shape rather than the file and two people who arrived at the same architecture see the same runs. Pass `model_path`, or a `fingerprint` straight from a plan result. | The fingerprint and your key. **Never the graph.** |
Why these exist: a frontier model reading your code can reason about the architecture, and cannot know that this shape trained here three days ago and reached 98.65% in 34 seconds for under a cent. That fact is not in the weights, not in the repository, and not derivable from the graph.
**Without `NEURARCH_API_KEY`, `history` makes no request and says so.** It does not return an empty list: an unread ledger and an empty one are different answers, and only one of them means nobody has trained this. Keys come from [neurarch.com/developer](https://www.neurarch.com/developer).
### Then whether it forward-passes: the offline ladder
Across three datasets we found agents rarely write a structurally illegal model, and the one failure a structure-focused agent hit in our experiment was an out-of-memory, which is why sizing comes first. When the structure is in question, these grade it, and they are a ladder worth climbing in order. Each is free, offline and instant; `check_design` runs five pipeline stages, so an agent that starts at the top still pays for an answer two thirds of which a cheaper tool had.
| | Tool | Answers |
|---|---|---|
| 1 | `validate_model` | Is this a well-formed graph at all: cycles, dangling refs, duplicate names, orphans. |
| 2 | `lint_model` | Does it break a design rule: attention head-dim and GQA divisibility, norm/activation ordering, dropout and feature ranges, missing residuals in deep stacks, the shape rules decidable statically. Returns `provenance`: for every rule that fired and has a published measurement behind it, the measurement. A rule with no number is absent rather than dressed up. |
| 3 | `check_design` | Will it train, what will it cost, where can it run: readiness, parameter and cost estimates, the best deployment target and its latency, and the decisions still left to the human. Same code path as the app and `POST /api/v1/check`. |
| 4 | `rank_designs` | Orders k candidate designs. Candidates are paths, `zoo:`/`hf:` refs or inline graphs. Blocked ones (a pre-flight finding that means the graph will not forward-pass) rank last and come back as reclaimable budget; that part is measured, 96 of 96 blocked graphs crashed PyTorch forward and 80 of 80 passes ran. Legal candidates are ordered only by rules with a trained outcome behind them, and **a tie stays a tie**: `recommended` is null when nothing measured separates the top, which is the common answer. Params, cost and GPU fit are returned per candidate for you to break ties on your own budget; they never order on their own, but `tie_break: "cost"` or `"params"` will break a measured tie on them, echoed and labelled as your rule with `measuredRank` kept. `calibration` ships inside every result (pairwise accuracy 51.4% at 8.3% coverage, in-sample, not quotable; out of sample the score abstained on 11 of 15 pairs while Claude Opus 5 reading the code got 12 of 15 and always picking the larger design got 11 of 15), so the ordering cannot be read as a quality prediction. |
| 5 | `suggest_fix` | **The finding as a change to the file.** A unified diff per finding: `exact` where the rule pins a number or an order (the head-dim crash above becomes a 7-line diff that changes every `258` to `256`), `proposal` where a layer is missing. Apply, then lint again. |
### Inspect
| Tool | What it does |
|---|---|
| `describe_architecture` | One-call orientation: topo-ordered pipeline, depth, IO shapes, total params and MACs, top-5 param **and** compute hotspots, validation rollup. Start here. |
| `get_model_summary` | Layer count, total params, dominant types, input/output shape. |
| `get_layer` | One layer by name: params, shapes, notes, upstream/downstream. |
| `find_layers` | Search by type, name regex, scope prefix or augmentation; rank by parameter count. |
| `compare_layers` | Structural diff of two layers. |
| `layer_impact` | **Blast radius** of changing a layer or matched set: shape-sensitive and weight-carrying downstream layers. Call it before recommending an edit. |
| `find_path`, `list_connections` | Directed path between two layers; the edge list. |
| `param_count_by_block`, `flops_by_block` | Params and MACs grouped by block, scope or type. |
| `list_blocks`, `get_block` | Collapsed groups and what crosses their boundary. |
| `diff_models` | Structural diff against another `.neurarch.json`. |
| `mermaid_diagram` | The model as Mermaid `flowchart TD`. |
| `list_hyperparams`, `get_design_notes` | What the user set and wrote in the app. |
### Reference library and other models
| Tool | What it does |
|---|---|
| `list_architectures` | Search the **81 reference architectures bundled with this server** (DeepSeek-V3, Qwen2.5, Llama, Mixtral, Gemma, Whisper, CLIP, BERT, ViT, ResNet and more), each with real dimensions from the model's config and a parameter count checked against the published one. Offline. |
| `load_architecture` | Open one and describe it. Then `model_path: "zoo:<id>"` on any tool. |
| `load_hf_model` | A Hugging Face repo as a graph. Listed only under `--hf`, because it is the one tool that opens a socket. |
| `find_models` | Walk a directory for nn.Module definitions and saved graphs, try the parser on each, and say which need `neurarch-trace` instead. |
| `trace_model` | Run `neurarch-trace` in your Python with the input dims and get a graph with real shapes back as a `model_path`. **The primary way in for a real repository**, not a fallback: the static parser returns a recognisable graph for 41% of real model files and no finding it raised on one has yet been a real defect. |
| `export_pytorch` | The graph as a runnable `nn.Module`, the app's own generator. `save_to` needs `--write` and never targets the file the server was started from. |
### Write (opt in with `--write`)
`add_layer`, `modify_layer`, `add_connection`, `delete_layer`, `delete_connection`, `save_model`. Mutations always target the file passed on the command line; write tools refuse `model_path`, so an agent cannot edit, and then save over, a path it invented. Refused on a `.py` (the graph was derived from it; use `export_pytorch` to emit new source).
Every tool declares what it does to your files (MCP annotations): read tools are read-only and closed-world, `load_hf_model` is open-world, the three that can destroy something say so. Results carry `structuredContent` alongside the JSON text.
## Prompts and resources
In Claude Desktop, Cursor and VS Code these show up as slash commands. Each is the tool ladder written out in order, with one rule on top: every number in the answer comes from a tool result, never from memory of similar models.
| Prompt | Argument | What it does |
|---|---|---|
| `/review_design` | `focus?` | Structured review: readiness, risks, where the budget lives, the edits worth making with their blast radius. |
| `/pre_train_checklist` | | Pass / fail / unknown per line, each backed by the tool that decided it, before you spend GPU time. |
| `/shrink_for_target` | `target` | Fit "under 100M params" or "a T4 with batch 32": find where the budget lives, propose variants, rank them. |
| `/compare_with_reference` | `architecture?` | The model next to a published one from the library, with the differences that would change training. |
| `/explain_finding` | `rule` | What a finding means for this model, the evidence behind it, the smallest edit that clears it. |
Resources a client can pin as context: `neurarch://model` (the graph), `neurarch://model/mermaid`, `neurarch://model/pytorch`, `neurarch://zoo`, `neurarch://zoo/{id}`, `neurarch://rules` (the provenance table), `neurarch://docs` and `neurarch://docs/{tool}` (every tool's full contract).
`check_design` can also **ask the person** when the verdict ends in a decision only they can make (which data, whether to spend the money): pass `ask_user: true` and, in a client that supports MCP elicitation, the question is put to them and their answer comes back with the verdict.
Whether an agent reaches for the right tool is measured, not assumed: `npm run eval:tools` runs six fixed asks through Claude Code against the built server and grades the tool calls (lint before proposing an edit, `rank_designs` for a which-of-k question). The latest result is in [`docs/tool-selection-eval.json`](./docs/tool-selection-eval.json).
## Also a CLI
```bash
npx -y neurarch-mcp lint model.py # findings, exit 1 on a block
npx -y neurarch-mcp lint a.py b.py --json # for CI
npx -y neurarch-mcp check model.py # the full verdict
npx -y neurarch-mcp check zoo:qwen2.5-7b # on a reference architecture
```
### The same estimate in a shell: `npx neurarch`
The [`neurarch`](https://www.npmjs.com/package/neurarch) CLI runs the estimate this server vendors on a Hugging Face id, with no agent in the loop.
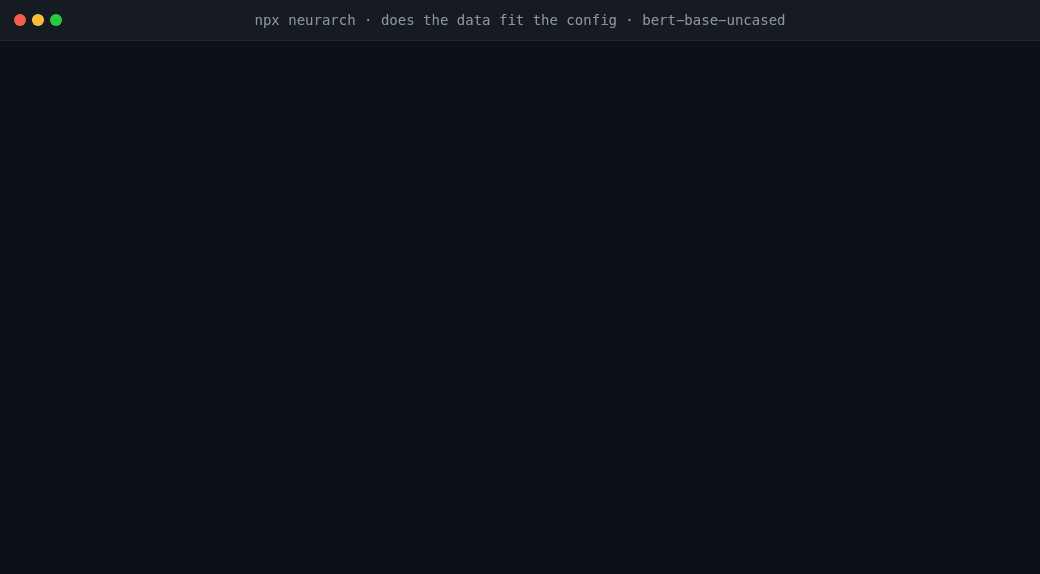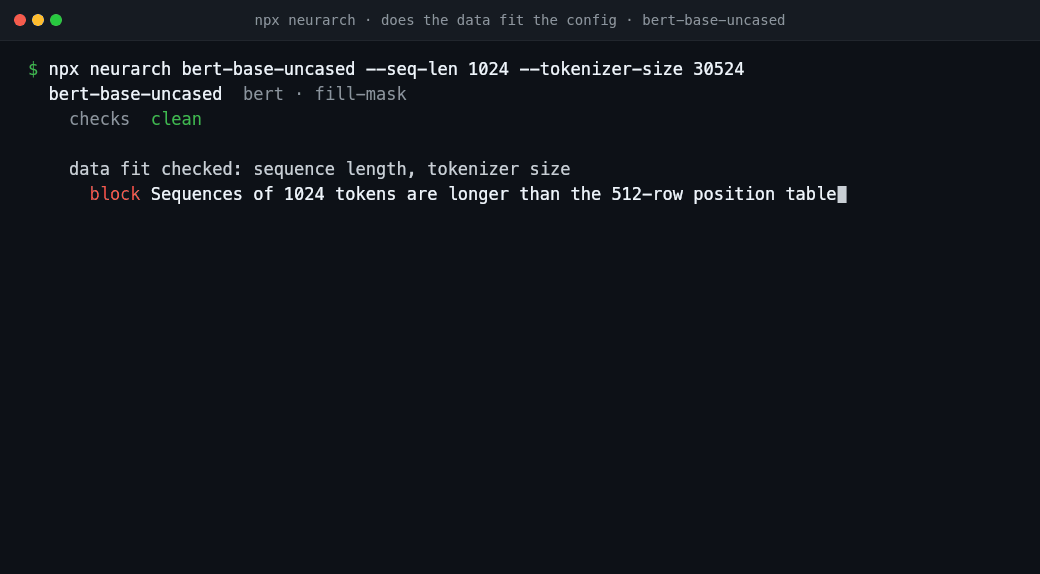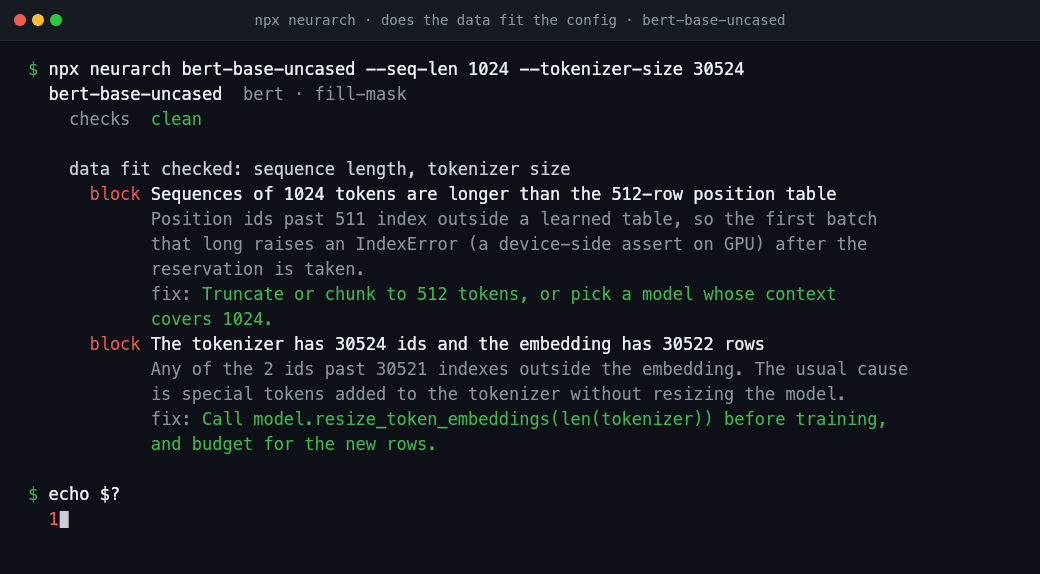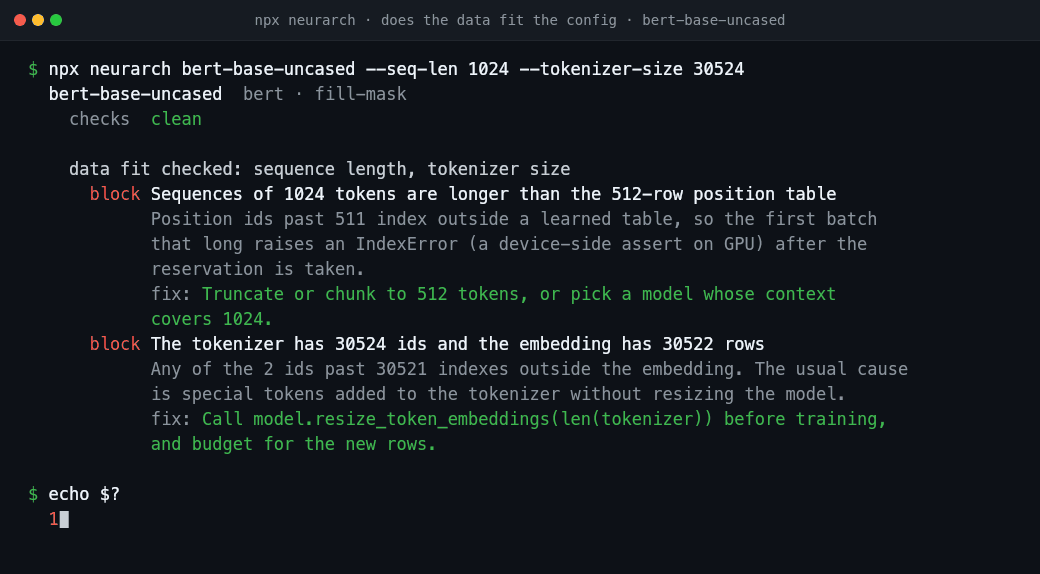
**Data the config cannot take.** Both of these pass the architecture checks and crash on the first batch, after the GPU is reserved:
**Past jobs, requested against needed**, from a CSV of what your team already ran:
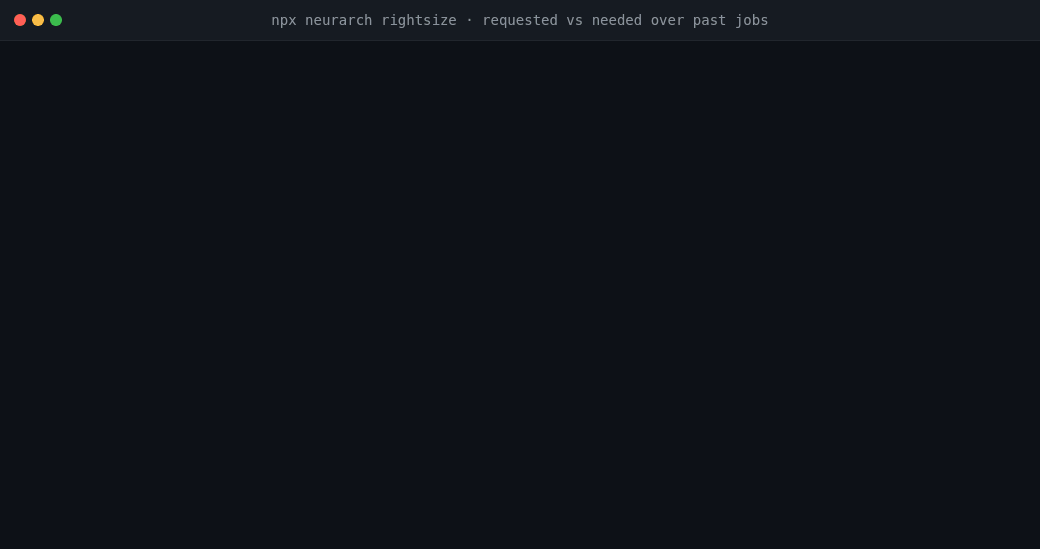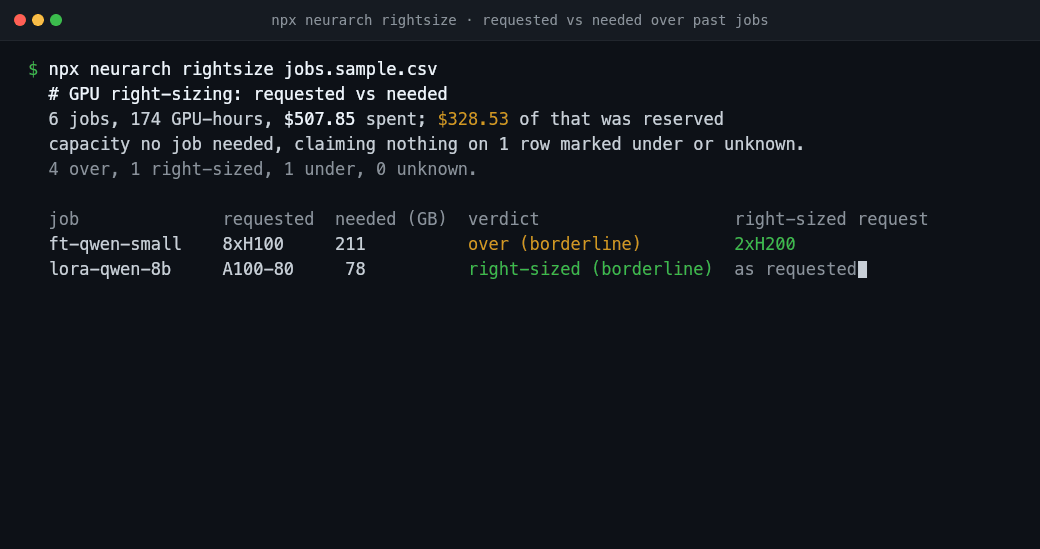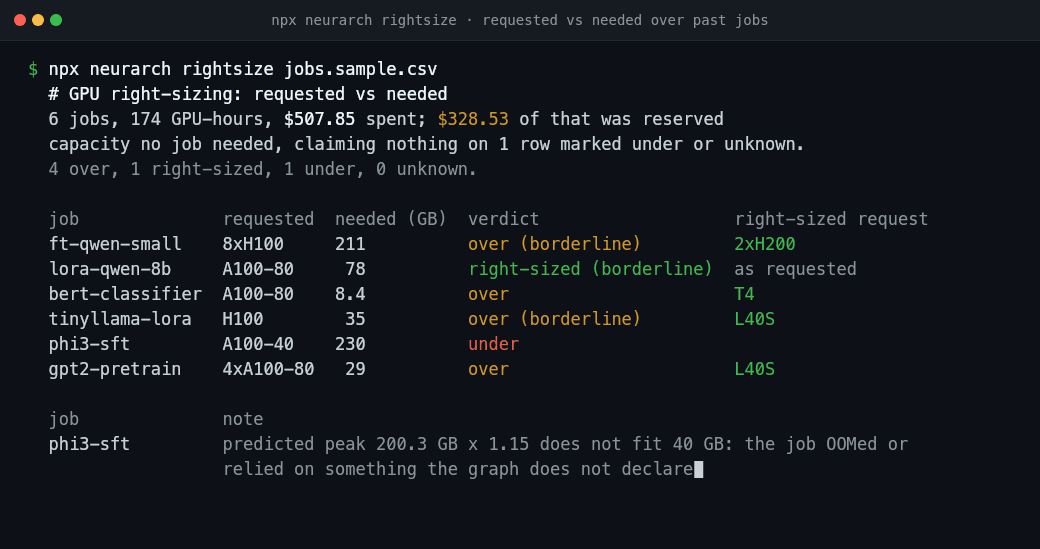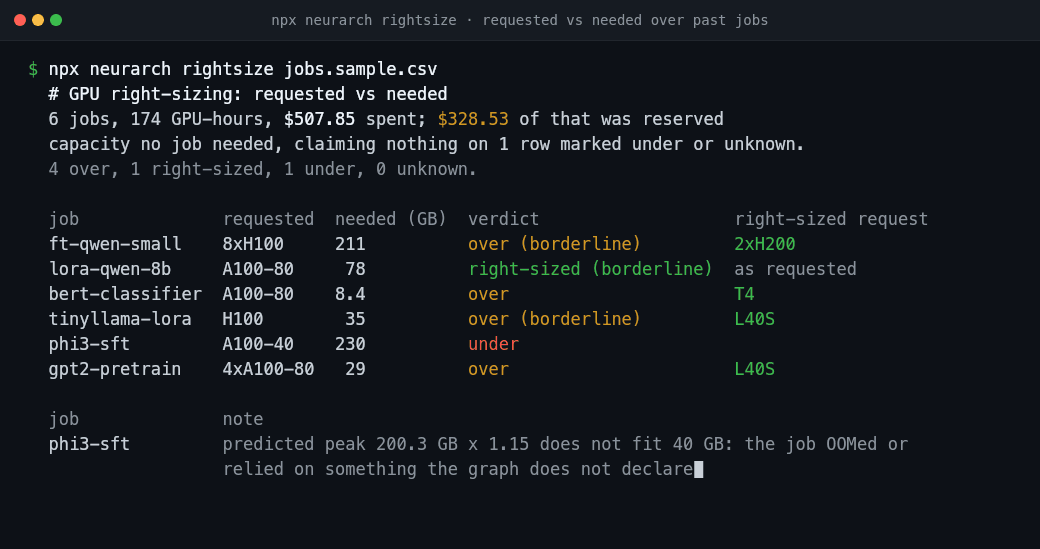
<sub>Real output, every string verbatim: `rightsize` from `neurarch` 0.1.1 on the `examples/jobs.sample.csv` it ships, with columns cut; the data-fit run cut to its data-fit block, long sentences wrapped and none reworded.</sub>
### A Claude Code hook: refuse the launch that will not fit
`neurarch-mcp hook` is a [PreToolUse hook](https://docs.claude.com/en/docs/claude-code/hooks) for Claude Code. Before each Bash call it reads the pending command from stdin; when the command launches training (`python train.py`, `accelerate launch`, `torchrun`, `deepspeed`, `sky launch`) it sizes the job exactly as `size_training_job` does, and when the job will not fit the card it declares it exits 2, which blocks the call and hands the agent the reason: the peak, the card, the largest batch that fits it, and the smallest card that holds the job. Every other command runs untouched, and the hook prints nothing.
Add it to `.claude/settings.json` in the repository (or `~/.claude/settings.json`):
```json
{
"hooks": {
"PreToolUse": [
{
"matcher": "Bash",
"hooks": [
{ "type": "command", "command": "npx -y neurarch-mcp hook --hf" }
]
}
]
}
}
```
`--hf` lets it read `config.json` from huggingface.co for a model named as `org/name` (cached for a day); drop it to stay offline, and then only local models (a `.py`, a `.neurarch.json`, a checkpoint directory with a `config.json`, `zoo:<id>`, or an `hf:` id already in the cache) are sized. For a hook that runs on every Bash call, `npm i -g neurarch-mcp` and `"command": "neurarch-mcp hook --hf"` skip npx's startup.
The model, batch, sequence length and card come from the command line (`--model` / `--model_name_or_path`, `--batch_size` / `--per_device_train_batch_size` times `--nproc_per_node` / `--num_processes`, `--gradient_accumulation_steps`, `--max_seq_length` / `--seq_len`, `--gpu`, `sky launch --gpus A100-80GB:8`, `--attn_implementation`), and anything the command leaves out from the `job:` block in the nearest `.neurarch.yml`.
That block is the one [neurarch-bot](https://github.com/neurarch-ai/neurarch-bot) reads for the memory line on its pull request comment, with the same semantics, so one file drives both: the agent is refused before the launch for the same reason the pull request would turn red. A top-level `job:` applies to every model and a model entry's own `job:` merges over it key by key. The keys are `gpu`, `batch` (the per-step batch the memory is sized at), `seq_len`, `grad_accum` (only sets the effective batch the reason quotes), `attention`, `epochs` and `samples`; each is a value or a `file:key` pointer into your own YAML or JSON training config, read relative to the repository root, dotted keys allowed. Unknown keys are ignored. One key is the hook's own: `model`, because the bot takes the model from its traced file list and the hook has no trace to read it from.
```yaml
job:
model: meta-llama/Llama-3.2-1B # hook only: a path, zoo:<id>, hf:<org/name> or org/name
gpu: A10G # T4, L4, A10G, L40S, A100 40GB, A100 80GB, H100, 8xH100
batch: configs/pretrain.yaml:batch_size # a number, or file:key into your training config
seq_len: configs/pretrain.yaml:seq_len
grad_accum: configs/pretrain.yaml:grad_accum
attention: sdpa # sdpa (default), flash or eager
```
A per-model `job:` applies when its entry's `path` (or its own `model`) names the model being launched, or when it is the only entry with one. The command line wins over the block, key by key. A pointer that does not resolve leaves its key unset rather than guessed.
It fails open. A command it does not recognise, a job with no declared card or batch (including a `file:key` pointer that does not resolve), a model it cannot load, a card it cannot parse (a bare `A100` is ambiguous), or any error at all lets the call run. So does a job the estimate does not model: `--gradient_checkpointing`, LoRA or PEFT flags, 4- or 8-bit loading and CPU offload, since the number is a full fine-tune's peak. The estimate is a fit check, not a measurement, so `NEURARCH_ALLOW_OOM=1` in front of a command lets a refused launch through.
The same hook pre-checks a vLLM or SGLang launch (`vllm serve`, `python -m vllm.entrypoints...`, `python -m sglang.launch_server`) with `check_serving_config`, and blocks only on a finding read from the model's own `config.json` and the flags, such as a TP that does not divide the heads or a served length past the context; `NEURARCH_ALLOW_SERVE=1` lets it through:
```text
$ vllm serve Qwen/Qwen3-8B --tensor-parallel-size 3
neurarch: this vLLM launch has 2 blocking findings for Qwen/Qwen3-8B.
TP 3 does not divide 32 attention heads.
```
### Claude Code plugin
The server, the hook above and the [skill](./skills/neurarch-skill/SKILL.md) install together as one Claude Code plugin. This repository is its marketplace:
```text
/plugin marketplace add neurarch-ai/neurarch-mcp
/plugin install neurarch@neurarch-ai
```
On Claude Code 2.1.275 or later, `/plugin install neurarch --marketplace neurarch-ai/neurarch-mcp` does both in one step. From a shell, the same two steps are `claude plugin marketplace add neurarch-ai/neurarch-mcp` and `claude plugin install neurarch@neurarch-ai`.
What it adds, all from [`.claude-plugin/plugin.json`](./.claude-plugin/plugin.json) and [`hooks/hooks.json`](./hooks/hooks.json):
- **The MCP server**, as `npx -y neurarch-mcp --hosted --hf`: no model of its own, so every tool takes `model_path` (a `.py`, a `.neurarch.json`, `zoo:<id>` or `hf:<org/name>`) or `hf_id`. `--hf` lets an `hf:` model read `config.json` from huggingface.co.
- **The hook**, `npx -y neurarch-mcp hook --hf` before every Bash call, exactly as configured by hand above: training launches are sized, vLLM and SGLang launches are pre-checked.
- **The skill**, `/neurarch:neurarch-skill`: size the job before it launches, then the evidence-gated edit loop.
Both commands contact huggingface.co only for a model named by its Hugging Face id. To stay offline, or to point the server at one model, configure the server and the hook by hand as above instead of installing the plugin.
## Client setup
Use an **absolute** path in any global config: `npx` does not run from your project directory. Relative paths work in project-scoped configs (`.mcp.json`, `.cursor/mcp.json`, `.vscode/mcp.json`).
<details open><summary><b>Claude Code</b></summary>
```bash
claude mcp add neurarch -- npx -y neurarch-mcp /abs/path/to/model.py
```
Or commit a project-scoped `.mcp.json` so every collaborator gets the server:
```json
{ "mcpServers": { "neurarch": { "command": "npx", "args": ["-y", "neurarch-mcp", "./model.py"] } } }
```
</details>
<details><summary><b>Claude Desktop</b></summary>
Download the `.mcpb` from [Releases](https://github.com/neurarch-ai/neurarch-mcp/releases/latest) and open it, or edit the config (**Settings → Developer → Edit Config**; macOS `~/Library/Application Support/Claude/claude_desktop_config.json`, Windows `%APPDATA%\Claude\claude_desktop_config.json`):
```json
{ "mcpServers": { "neurarch": { "command": "npx", "args": ["-y", "neurarch-mcp", "/abs/path/to/model.py"] } } }
```
Fully quit and reopen Claude Desktop; the config is read at startup.
</details>
<details><summary><b>Cursor</b></summary>
Click **Add to Cursor** above, or create `.cursor/mcp.json` (project) or `~/.cursor/mcp.json` (global):
```json
{ "mcpServers": { "neurarch": { "command": "npx", "args": ["-y", "neurarch-mcp", "./model.py"] } } }
```
</details>
<details><summary><b>VS Code (Copilot agent mode)</b></summary>
Click **Install in VS Code** above, or create `.vscode/mcp.json` (note the `servers` key):
```json
{ "servers": { "neurarch": { "command": "npx", "args": ["-y", "neurarch-mcp", "${workspaceFolder}/model.py"] } } }
```
</details>
<details><summary><b>Windsurf, Codex, and anything speaking Streamable HTTP</b></summary>
Same `command` + `args` shape; only the file location differs. For HTTP clients, run `npx neurarch-mcp model.py --http` and point the client at:
```json
{ "mcpServers": { "neurarch": { "type": "http", "url": "http://127.0.0.1:8787/mcp" } } }
```
</details>
**Verify:** ask the agent *"List the Neurarch tools you can see."* From a shell, `npx -y neurarch-mcp --help` prints usage and the full tool list.
### Flags
- `--write`: expose the six mutation tools. Off by default.
- `--watch`: reload the model file on change. Pair with the app.
- `--hf`: allow `hf:<org/name>` refs and list `load_hf_model`. The one network switch. `HF_TOKEN` is sent for gated repos; results are cached for a day under `~/.cache/neurarch-mcp`.
- `--tools=full`: advertise every read tool. The default is the core nineteen, listed in the order they are meant to be reached for (`size_training_job`, `trace_model`, `plan`, `history`, `diagnose_oom`, `check_edit`, `check_parallel_layout`, `check_serving_config`, `check_pins`, `model_changes`, then the offline ladder); every tool stays callable by name either way, and `neurarch://docs/<tool>` has the full contract. The default listing costs the agent about 5.5k tokens per turn, the full one 7.8k, output schemas included.
- `--toolsets=sizing,serving,...`: advertise only these groups (`sizing`, `parallel`, `serving`, `changes`, `design`, `models`, `write`). A team that only sizes training jobs loads six tools (about 1.6k tokens a turn). `write` is the same as `--write`, with the same startup refusals; an unknown group name stops the server at startup. Overrides `--tools`.
- `--read-only`: never expose write tools, even with `--write` or `--toolsets=write`.
- `response_format: "concise" | "detailed"` on `lint_model`, `find_layers`, `layer_impact`, `describe_architecture` and `check_design`. Concise is the default and says what it left out (`omitted.count`, or `fields` for find_layers); on qwen2.5-7b it cuts `lint_model` from 10.6 KB to 1.4 KB by counting info findings per rule instead of listing them.
- `--http[=PORT]`, `--host=ADDR`: serve over Streamable HTTP. See [Remote access](#remote-access).
- `--version`, `--help`.
## Network: three tools, two switches, and nothing else
| What | What it sends | When |
|---|---|---|
| `plan` | Your graph (and the base graph, and the policy lines) to `POST /api/v1/plan`. `share` is pinned to false. | Only when the agent calls `plan`. |
| `history` | An 8-character structural fingerprint and your `NEURARCH_API_KEY`, to `GET /api/v1/history`. **Never the graph.** | Only when the agent calls `history` **and** a key is set. With no key it makes no request. |
| `model_changes` | Two GETs of public static files on www.neurarch.com: the advisory index and the one model's revision list (its path is the model id). No key, no graph, nothing from your repository. | Only when the agent calls `model_changes`; the index is cached for an hour. |
| `--hf` | A request to huggingface.co for a repo's `config.json`, plus `tokenizer_config.json`, `chat_template.jinja` and `generation_config.json` for `check_serving_config` (and `HF_TOKEN`, if set). Never your model. | Only on `load_hf_model` or an `hf:` ref, each file cached for a day. |
| `NEURARCH_REPORT=1` | One anonymous structure+verdict row: structural fingerprint, layer-type histogram, edge count, (rule id, severity) pairs. **Structurally incapable of carrying the graph.** | After each `validate_model`, `lint_model`, `check_design` or `plan` call, fire and forget, 5s cap. |
Both switches are off by default and `NEURARCH_REPORT` has not changed: `plan` joins the three tools that already send a row so that opting in means one thing across every tool that grades, and `history` grades nothing and sends none. Nothing here is new default-on behaviour; the three tools reach out when they are called, which their descriptions and their `openWorldHint` annotation say out loud. Under `--hf` every read tool is annotated open-world too, because any of them can be handed an `hf:` model.
With `--hf` off, `NEURARCH_REPORT` unset and neither `plan` nor `history` called, this server makes **no network calls at all**, and no other tool is an exception: the parser, the rule engine, the verifier, the ranker and the reference library are vendored into the package, so your model never leaves the machine. `NEURARCH_API` (the same variable `neurarch-trace` uses) points the two ledger tools somewhere else. Corpus policy: [neurarch.com/rules.html#data](https://neurarch.com/rules.html#data).
## Remote access
By default the server talks stdio, so the agent and the model file live on the same machine. `--http` serves the same tools over Streamable HTTP, so a hosted or phone-based agent can drive a model running on your machine, for example behind a Cloudflare or Tailscale tunnel.
```bash
npx neurarch-mcp model.py --http # loopback, no auth needed
NEURARCH_MCP_TOKEN=$(openssl rand -hex 16) \
npx neurarch-mcp model.neurarch.json --write --http --host=0.0.0.0
```
Binds to `127.0.0.1` by default with DNS-rebinding protection; `NEURARCH_MCP_TOKEN` requires `Authorization: Bearer <token>` on every request and is **required** before `--write` may bind to a non-loopback host.
**Hosted, with no model on disk:** `npx neurarch-mcp --http --hf` serves a server that answers about whatever each call names (`model_path: "zoo:..."` / `"hf:..."`, or `model_source` with the model text inline). `Dockerfile`, `fly.toml` and [docs/HOSTED.md](./docs/HOSTED.md) carry the deploy. A hosted server sees the model text a client sends it, which the local one never does; say so wherever a URL is published.
## Real shapes from real code: `neurarch-trace`
Static parsing stops at the source. [`python/neurarch-trace`](./python/neurarch-trace) instantiates the model, runs one forward pass with hooks, and writes a `.neurarch.json` with every shape filled in, functional residual adds and concats included:
```bash
pip install neurarch-trace
neurarch-trace models/resnet.py:ResNet18 --input 1,3,224,224 -o resnet18.neurarch.json
neurarch-trace hf:bert-base-uncased --input 1,128 --dtype long # needs transformers
npx -y neurarch-mcp resnet18.neurarch.json
```
Shapes come out batchless (`[3,224,224]`, never `[1,3,224,224]`), the convention every tool here expects.
## Development
```bash
git clone https://github.com/neurarch-ai/neurarch-mcp && cd neurarch-mcp
npm install
npm run typecheck && npm run build && npm test # vitest, 290+ tests
node dist/index.js --help
npm run build:mcpb # the Claude Desktop bundle
```
CI runs typecheck, build and test on Node 20 and 22. The package vendors from the main Neurarch repo so that it works with no network, no key and no second install: `src/vendor/engine.bundle.mjs` (registry, PyTorch parser, rule set, code generator, HF config converter) and `src/vendor/verifier.bundle.mjs` (five pipeline stages, provenance table, ranker). Both are generated, contract-tested, and asserted to contain no `import` (and, for the verifier, no `fetch`). The MCP SDK (`@modelcontextprotocol/server`, with `@modelcontextprotocol/node` for the HTTP adapter) is the only runtime dependency. `zoo/` is synced from [awesome-llm-model-zoo](https://github.com/neurarch-ai/awesome-llm-model-zoo) with `npm run sync:zoo`.
A new tool is a small, self-contained PR: see [CONTRIBUTING.md](./CONTRIBUTING.md). The agent skill that teaches an evidence-gated edit loop over these tools lives in [`skills/`](./skills/neurarch-skill) (`npx skills add neurarch-ai/neurarch-mcp`).
## Troubleshooting
- **The server never appears in the client.** The model path must be absolute in any global config; `npx` does not run from your project directory. Relative paths only work in project-scoped configs (`.mcp.json`, `.cursor/mcp.json`, `.vscode/mcp.json`).
- **Read tools work but write tools are missing.** You did not pass `--write`. It is off by default so accidental writes can't clobber a file you're editing in the app.
- **`npx` fails on first run.** Node >= 20 is required (`node --version`).
- **Claude Desktop shows nothing after editing the config.** Fully quit and reopen the app; the config is only read at startup.
- **The agent sees a stale graph after you edit in the app.** Add `--watch`, or restart the server.
## What this is not
- **Not a generic codebase indexer.** It reads model definitions (`.py`, `.neurarch.json`, `zoo:`, `hf:`), not your whole tree. For codebase structure, use [GitNexus](https://github.com/abhigyanpatwari/GitNexus) or similar.
- **Not a trainer.** It tells you what a run needs, whether it would start, what it would cost and where the result could be served; it never spends your GPU time.
- **Not a measurement.** `size_training_job` is a calibrated estimate (fitted on 178 measured runs across 41 architectures; held out, 7% median error and 113 of the 131 runs that did not fit a card flagged; 14% median miss on 25 runs measured after the fit); it is not a profiler, and a job using an optimizer other than AdamW, or no bf16 autocast, will differ. `check_design` says when a decision is yours.
- **Not connected to your Neurarch workspace.** It reads files. Live editing happens in the [Neurarch app](https://neurarch.com); `--watch` follows its saves.
## Issues & Feedback
This repo is the public home for both:
- **neurarch-mcp** (this MCP server): bugs, protocol changes, integration questions.
- **[Neurarch](https://neurarch.com)** (the app): canvas bugs, agent issues, linter rules, feature requests.
| | |
|---|---|
| 🐛 **[Report a bug](https://github.com/neurarch-ai/neurarch-mcp/issues/new?template=bug_report.yml)** | Something is broken or behaving unexpectedly. |
| 💡 **[Request a feature](https://github.com/neurarch-ai/neurarch-mcp/issues/new?template=feature_request.yml)** | An idea that would make Neurarch or the MCP server better. |
| ❓ **[Ask a question](https://github.com/neurarch-ai/neurarch-mcp/issues/new?template=question.yml)** | Something specific you can't figure out. |
| 💬 **[Start a discussion](https://github.com/neurarch-ai/neurarch-mcp/discussions)** | Open-ended ideas, design feedback, "how would you…". |
Please tag issues with `mcp`, `app`, `linter`, or `feature-request` so we can triage faster.
## Star this repo
If `neurarch-mcp` saved you from pasting an `nn.Module` into chat, a ⭐ helps other ML engineers find it. It is the lowest-effort way to support the project.
## Contributing
A new tool is a small, self-contained PR. See [CONTRIBUTING.md](./CONTRIBUTING.md) for the 3-step "add a tool" guide.
## Development
```bash
git clone https://github.com/neurarch-ai/neurarch-mcp
cd neurarch-mcp
npm install
npm run typecheck # tsc --noEmit
npm run build # tsup → dist/index.js
npm test # vitest (≈190 unit + end-to-end tests)
node dist/index.js --help # confirm bin works
```
CI runs `typecheck` + `build` + `test` on Node 20 and 22 for every push and PR.
The package vendors from the main Neurarch repo, and everything is vendored for the same reason: this server has to work with no network, no API key and no second install step.
- `src/lib/`: pure-TypeScript utilities (model types, parameter and FLOP estimators, impact analyzer), maintained as source here.
- `src/vendor/engine.bundle.mjs`: the compiled Neurarch engine: the component registry, the PyTorch parser behind `.py` support, and the rule set behind `lint_model`. Generated, never hand-edited; the header says how to regenerate it, and `src/vendor/engine.contract.test.ts` fails if its exports drift or it ever acquires an import.
- `src/vendor/verifier.bundle.mjs`: the compiled Neurarch verifier behind `check_design`: the five pipeline stages, plus the rule-provenance table. Same code path as the app and the hosted endpoint, so an agent here and a person in the app get the same answer. Same rules: generated, contract-tested (`verifier.contract.test.ts`), and asserted to contain no import and no `fetch`.
Neither adds a runtime dependency: the MCP SDK is still the only one.
## Privacy Policy
This server runs on your machine and is built not to phone home:
- **Data collection**: none by default. Your model files, graphs and source code are read from your disk and are transmitted by exactly one tool, `plan`, and only when it is called.
- **`plan` (on request)**: sends the graph you are planning (plus the base graph if you passed `base_path`, and the policy lines from your `.neurarch.yml`) to `POST /api/v1/plan` on `neurarch.com`, which renders the card and returns it. `share` is pinned to false, so nothing is published; the graph is processed to answer that call. Your `NEURARCH_API_KEY` is sent if you set one. No other tool sends your model anywhere.
- **`history` (on request, needs a key)**: sends an 8-character structural fingerprint of the graph and your `NEURARCH_API_KEY` to `GET /api/v1/history`. The graph itself is never sent, and with no key set the tool makes no request at all.
- **`NEURARCH_API` (optional)**: points those two tools at a different host; nothing else reads it.
- **`--hf` (optional)**: fetches a model's public `config.json` from huggingface.co. What is sent: the repo id you asked for, and your `HF_TOKEN` if you set one (to huggingface.co only). Responses are cached locally under `~/.cache/neurarch-mcp` and can be deleted at any time.
- **`NEURARCH_REPORT=1` (optional, off by default)**: sends one anonymous structure row per graded graph (`validate_model`, `lint_model`, `check_design`, `plan`) to the Neurarch corpus: a structural fingerprint (8-char hash), a layer-type histogram, an edge count, and (rule id, severity) pairs. The payload format cannot carry your graph, parameter values, layer names, file paths, or any identity. Policy and examples: [neurarch.com/rules.html#data](https://www.neurarch.com/rules.html#data).
- **The hosted instance** (`neurarch-mcp.fly.dev`) is different by nature: it processes the model text or references a client sends it, in memory, to answer that call. Nothing is stored server-side beyond a one-day `hf:` config cache; there are no accounts and no request logs of graph content. It runs with `NEURARCH_REPORT=1`, so each graded call also sends the anonymous structure row described above; use the local server if you do not want that.
- **Retention**: the local server stores nothing beyond its local caches. Corpus rows (opt-in) are retained indefinitely as anonymous aggregates.
- **Third parties**: no data is shared with anyone. The only third-party endpoint ever contacted is huggingface.co, and only under `--hf`; `neurarch.com` is contacted only by `plan`, `history`, and opt-in corpus reporting.
- **Contact**: neurarch.ai@gmail.com, or [open an issue](https://github.com/neurarch-ai/neurarch-mcp/issues).
The app-wide policy at [neurarch.com/privacy](https://www.neurarch.com/privacy) covers the Neurarch web app; this section covers this server.
## License
MIT. See [LICENSE](./LICENSE).
## Links
- [Neurarch](https://neurarch.com): the visual neural-network editor that produces the model files this server reads.
- [Model Context Protocol](https://modelcontextprotocol.io): the spec this server implements.
- [npm](https://www.npmjs.com/package/neurarch-mcp): package page.
This server cannot be deployed
Maintenance
ActivityActive
ResponsivenessNo issues