
mcp-retriever
# mcp-retriever
One MCP server for web search, page extraction, and cited research.
Use your own providers, combine their results, and keep API keys out
of client configs.
- **Search together:** query two or three providers, deduplicate URLs,
and merge rankings with `web_search_fused`.
- **Read more:** extract pages, crawl sites, and recover 404/410 pages
from Wayback Machine snapshots when archive fallback is enabled.
- **Control usage:** optional spending caps for provider-reported
usage, cooldowns, and paged access to large results.
Supports Tavily, Brave, Exa, You.com, SearXNG, GitHub, Linkup,
Firecrawl, and Context.dev. Configure only what you use.
Context.dev covers web search, researched answers through `ai_search`,
news search with `context_news`, scraping, and brand tools. Its
highlights are available in the search and read tools. Exa search adds
a `lite` type, and Firecrawl search categories are `developer`, `gov`,
`research`, and `pdf`. See
[Configuration](https://github.com/keiranhaax/mcp-retriever/blob/main/docs/configuration.md#provider-notes)
for details verified on 2026-10-19.
## Quickstart
Requires **Node.js 22+** and a provider key, or your own SearXNG
instance.
```bash
npx -y mcp-retriever setup
```
Choose providers, save keys privately, and connect your MCP client.
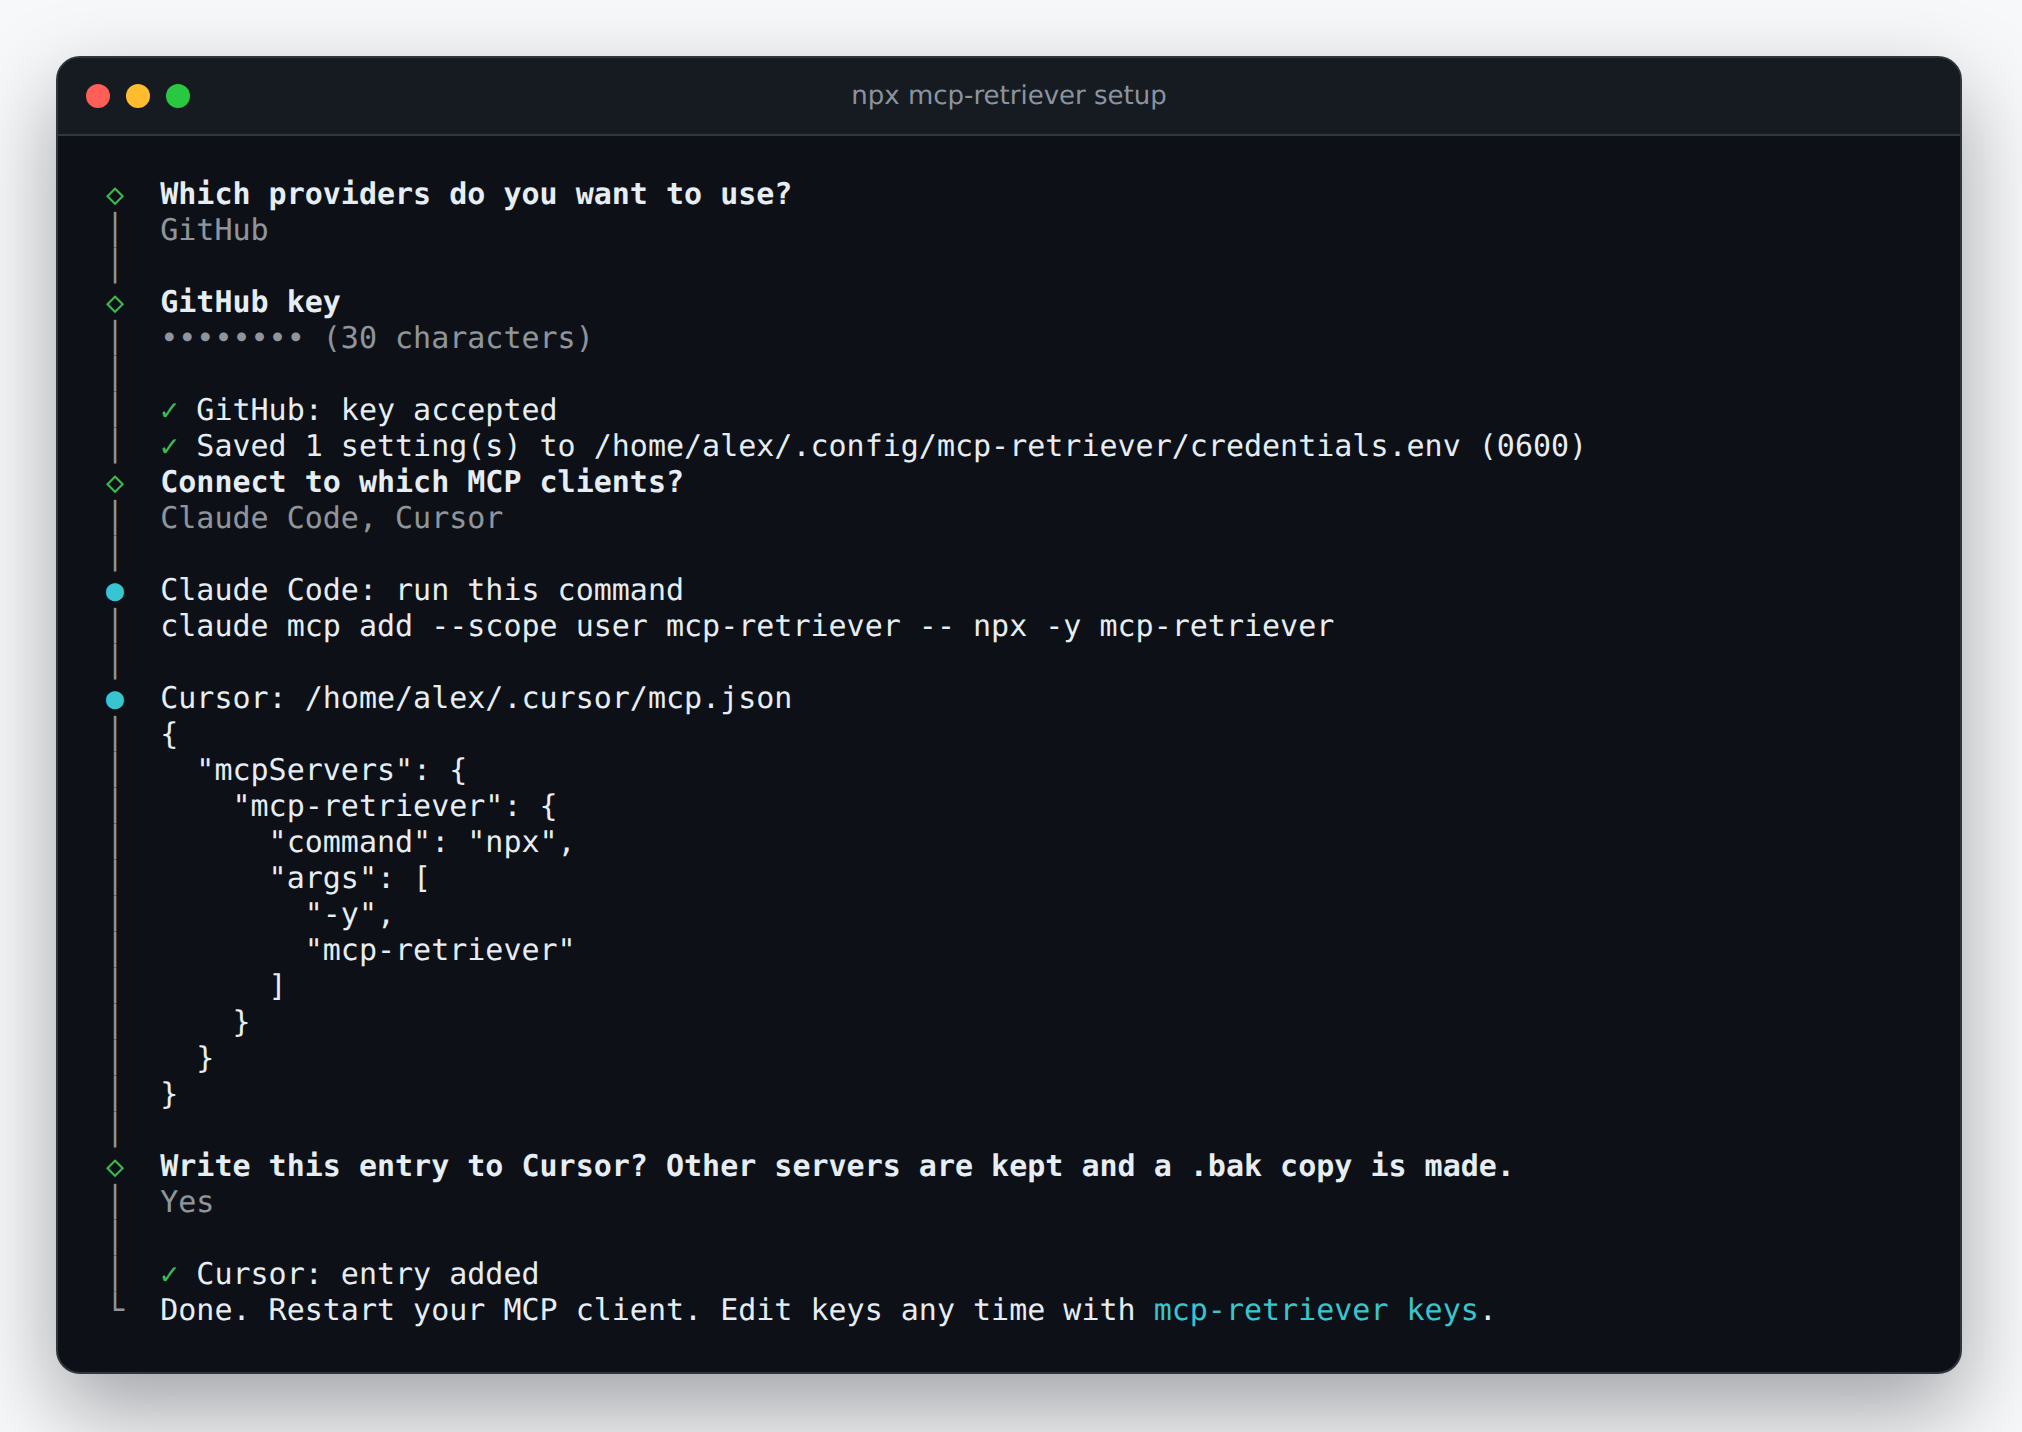
The wizard writes Claude Desktop and Cursor entries, or shows the
command/configuration for Claude Code and Codex. Billable key checks
require consent.
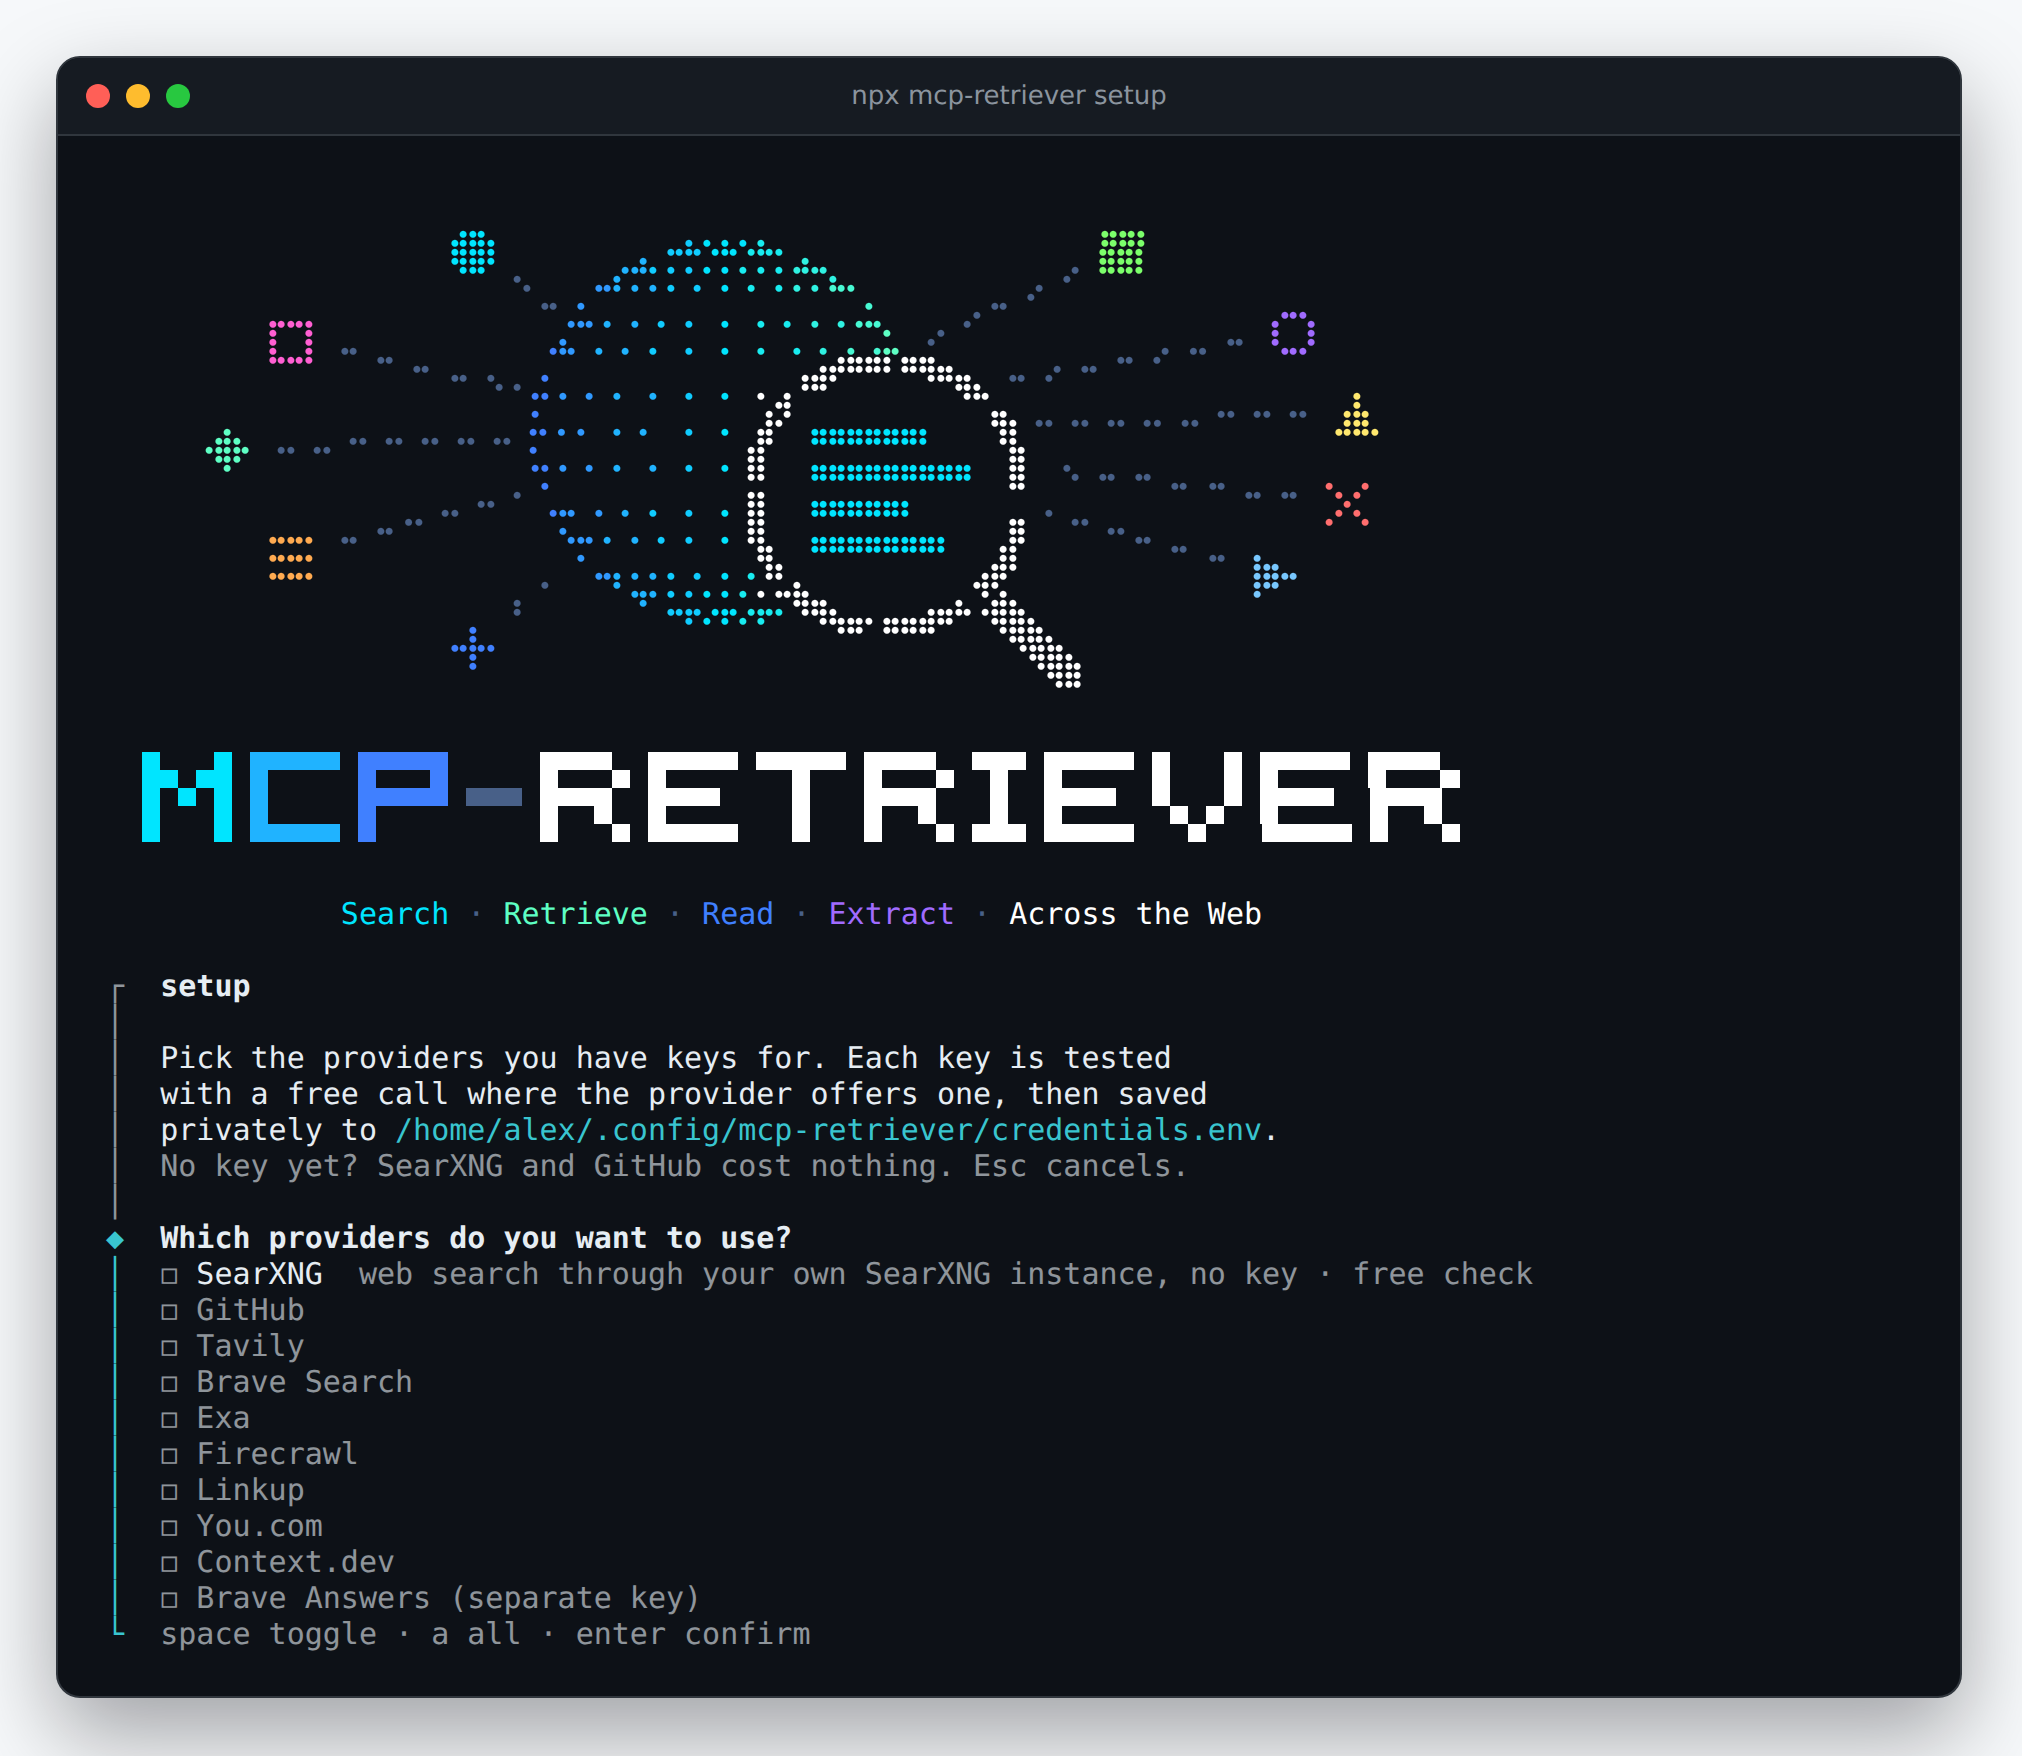
Keys are stored in `~/.config/mcp-retriever/credentials.env`, not in
client configs. Restart your client after setup.
<details>
<summary>Client connection and key management</summary>
Add, test, or remove keys:
```bash
npx mcp-retriever keys
```
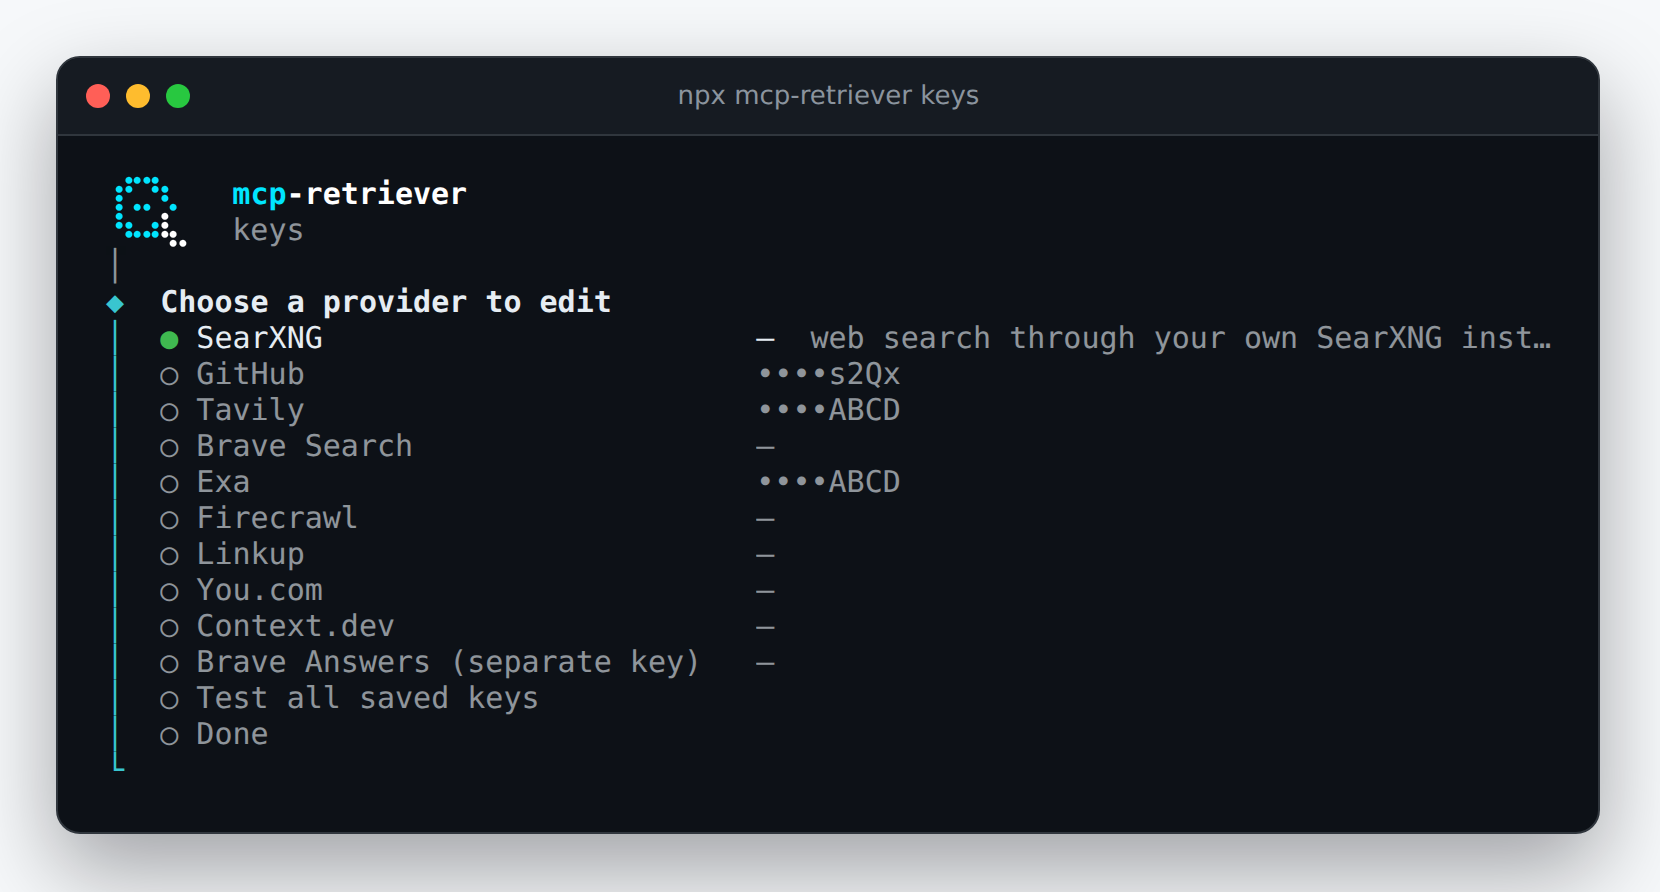
Screenshots show a demo session with fixture credentials and a mocked
key-check response, not a live provider validation.
</details>
## Example
Call `web_search_fused` with two configured search providers:
```json
{
"query": "reciprocal rank fusion hybrid search",
"providers": ["brave", "exa"],
"limit": 3
}
```
Results include source providers and merged rankings. If a provider
fails, available results are returned with per-provider status.
## Documentation
- [Configuration](https://github.com/keiranhaax/mcp-retriever/blob/main/docs/configuration.md):
keys, manual client setup, providers, and spending controls.
- [Search and read](https://github.com/keiranhaax/mcp-retriever/blob/main/docs/structured-search-workflow.md):
retrieving pages and handling large results.
- [Tool groups](https://github.com/keiranhaax/mcp-retriever/blob/main/docs/focused-tools-and-groups.md):
choose which capabilities to expose.
- [Deployment](https://github.com/keiranhaax/mcp-retriever/blob/main/docs/deployment.md):
remote HTTP access and operations.
- [Contributing](https://github.com/keiranhaax/mcp-retriever/blob/main/CONTRIBUTING.md):
build from source and run checks.
Each server instance shares one trust boundary. Do not use its result
store for mutually untrusted clients. Spending caps depend on
provider-reported usage, not estimated costs.
## License and origins
[MIT](https://github.com/keiranhaax/mcp-retriever/blob/main/LICENSE).
Formerly named `mcp-omnisearch`; a maintained fork of Scott Spence's
[mcp-omnisearch](https://github.com/spences10/mcp-omnisearch). When
upgrading this fork, rename `OMNISEARCH_*` settings to `RETRIEVER_*`,
`omnisearch://` resources to `retriever://`, and `_meta.omnisearch` to
`_meta.retriever`. Preserve the old result store and spending ledger
when moving to `~/.cache/mcp-retriever/results`; Docker/MCPO clients
must also change `/omnisearch` to `/retriever`.
TDQS
Scored across 1 tool
There is only one tool, so there is no risk of confusing it with another operation. Its purpose—reading stored result content by an opaque result_id—is clear.
With a single tool, there is no internal inconsistency across names. The name result_read is readable but uses a noun-first form rather than the more typical verb_noun convention.
A single tool is borderline thin for a server surface, though this may be acceptable for a narrowly scoped result-retrieval utility. It does not feel excessive, but it lacks enough breadth to feel fully well-scoped.
The tool covers paginated reading of result content, including byte-offset continuation. However, there are no operations for discovering result IDs, inspecting metadata/status, or managing expired/evicted results, which are notable gaps for a retrieval surface.