
AgentSQL
Officialby grishahq
README.md
# AgentSQL
**Persistent state for AI agents.** Files, JSON, and tool history in SQLite.
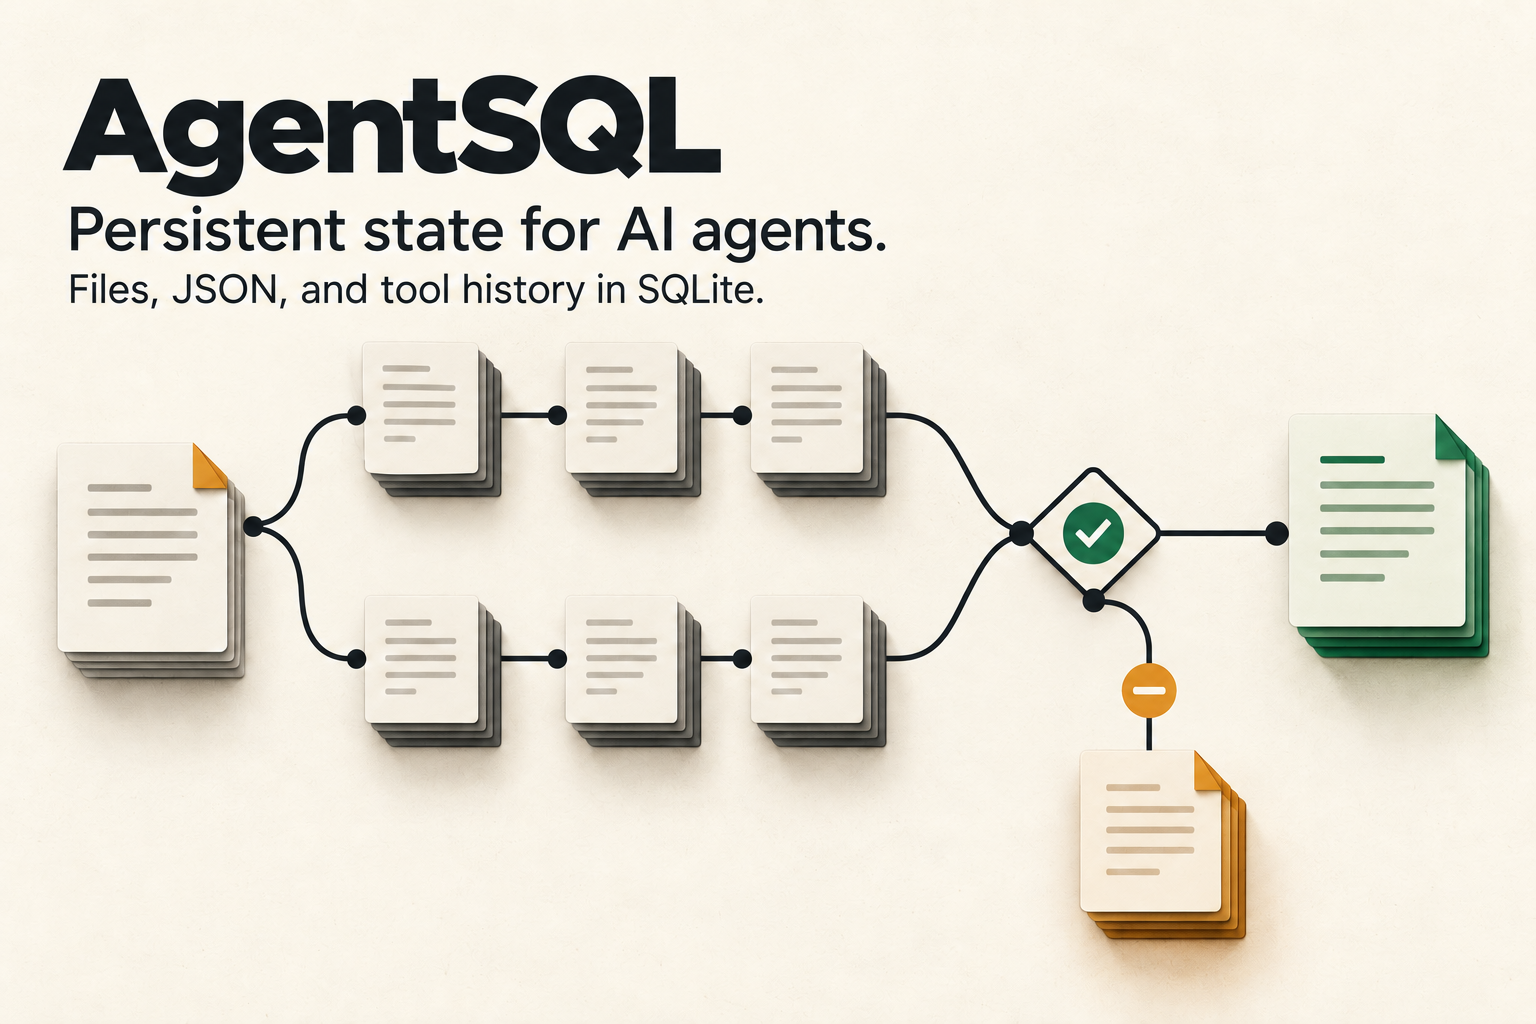
Agent A reads `prices.csv` at version 1 and writes `proposal.md`. Agent B updates
`prices.csv` and publishes it first. A's proposal now depends on an old input,
even though the agents wrote different files.
**AgentSQL rejects A's publication with `requires_recheck` evidence.**
Create a fresh branch, read the current prices, recompute the proposal, and
publish it successfully. An input change means the result needs rechecking; it
does not prove that the result is wrong.
This local-first Python SDK, CLI, and MCP server provides **versioned workspaces
for agent teams**: files and directories, JSON key-value state, explicit tool-call
history, persistent sessions, forks, and command execution with checked import.
Files and state publish together after dependency validation. One worker can
also compare alternative approaches.
**Public alpha: 0.3.0a1.** Python 3.10+, macOS and Linux, MIT licensed, with no
third-party runtime dependencies. Start with a small cooperative workload and
review the [operational limits](docs/operations.md).
## Install and run
With Python 3.10 or later on macOS or Linux:
```sh
python3 -m venv .venv
. .venv/bin/activate
python -m pip install agentsql==0.3.0a1
agentsql demo
```
For a source checkout, replace the install command with `python -m pip install .`.
The explicit version selects the alpha release without enabling other
prerelease dependencies.
The deterministic demo uses **simulated agent workers**, runs locally, and needs
no model, network service, or API key. It shows the different-output-path stale
input rejection, recomputes A's proposal on a new branch, and verifies the final
accepted contents. Run [`examples/demo.py`](examples/demo.py) after installation,
or inspect the [worker implementation](src/agentsql/demo.py). Use
`agentsql demo --directory ./demo-output` to keep its database in a new
or empty directory. The runtime uses only Python's standard library.
To use it in another project, follow the [integration guide](docs/integration.md)
and run [the application example](examples/project_integration.py). It covers
installation from this checkout or a shared wheel, adapting a model callable,
CLI use from another language, bounded retries, and exporting accepted results.
For a broader walkthrough, run `python examples/scenarios.py` to exercise
[11 deterministic scenarios](examples/scenarios.py). The [operations guide](docs/operations.md)
covers sealed review, backups, recovery, lock contention, and schema upgrades.
The [platform guide](docs/platform.md) shows the expanded `fs`, `kv`, and `tools`
interfaces, MCP connection, command runner, and an explicit capability comparison
with AgentFS. Run `python examples/platform_demo.py` after installation.
## SDK quickstart
```python
from pathlib import Path
from tempfile import TemporaryDirectory
from agentsql import ConflictError, Workspace
with TemporaryDirectory() as directory:
root = Path(directory)
source = root / "inputs"
source.mkdir()
(source / "prices.csv").write_text("item,price\nwidget,10\n", encoding="utf-8")
workspace = Workspace.create(root / "workspace.db", source)
worker = workspace.branch("researcher")
prices = worker.read_text("prices.csv") # Records this input's base version.
worker.write_text("proposal.md", "# Proposal\n\nPrices used:\n" + prices)
proposal_id = worker.seal() # Freeze this complete proposal.
print(worker.inspect()) # Inputs, versions, proposed writes.
print(worker.diff())
try:
print(worker.accept(message="Prepare a proposal", expected_proposal=proposal_id))
except ConflictError as error:
print(error.as_dict()) # Structured requires_recheck evidence.
raise # Recompute on a new branch before retrying.
reopened = Workspace.open(root / "workspace.db")
print(reopened.snapshot().read_text("proposal.md"))
print(reopened.history())
```
The database is the authoritative workspace. Creation imports source files;
acceptance updates the database and **does not rewrite the source directory**.
Use one branch for each independent worker or computation. A branch starts from
the current accepted revision and keeps that base while other workers publish.
| Object | Operations |
| --- | --- |
| `Workspace` | `create`, `open`, `branch`, `session`, `fork`, `get_branch`, `snapshot`, `history`, `branches`, `tools`, `backup`, `check_integrity` |
| Branch | `read_bytes`, `read_text`, `exists`, `list_files`, `write_bytes`, `write_text`, `delete`, `seal`, `inspect`, `diff`, `accept` |
| Snapshot | `read_bytes`, `read_text`, `exists`, `list_files`, `version` |
| Branch/Snapshot `fs` | `read_file`, `write_file`, `readdir`, `stat`, `exists`, `mkdir`, `remove`, `rename`; snapshot edits are rejected |
| Branch/Snapshot `kv` | `get`, `exists`, `version`, `list`, `set`, `delete`; snapshot edits are rejected |
| Workspace/Branch `tools` | `start`, `success`, `error`, `record`, `track`, `get`, `list`, `events`, `stats` |
`Workspace.create("workspace.sqlite3")` creates an empty workspace. `session(name)`
creates or reopens a named branch; `fork(source, name)` copies pending state and
its dependencies, or starts from an accepted source's published revision. Named
sessions remain cooperative: workers sharing a branch share staged state. Whole
branch acceptance closes that branch; create a new task branch after acceptance.
`workspace.snapshot(revision=1)` opens an immutable historical view. Snapshot
reads are for inspection; they do not register inputs on a branch. Use branch
reads for inputs that a worker uses to compute a proposal.
## CLI quickstart
With an existing `./inputs` directory, keep the database outside that directory:
```sh
agentsql -w workspace.db create ./inputs
agentsql -w workspace.db branch researcher
agentsql -w workspace.db read researcher prices.csv
agentsql -w workspace.db write researcher proposal.md --text 'Draft proposal'
proposal_id=$(agentsql -w workspace.db seal researcher | python -c 'import json,sys; print(json.load(sys.stdin)["proposal_id"])')
agentsql -w workspace.db inspect researcher
agentsql -w workspace.db diff researcher
agentsql -w workspace.db accept researcher --proposal "$proposal_id" -m 'Publish proposal'
agentsql -w workspace.db history
agentsql -w workspace.db show proposal.md
agentsql -w workspace.db check
agentsql -w workspace.db backup ./workspace-backup.db
```
The commands save the ID returned by `seal` and pass it to `accept`. Place `-w` and optional
`--timeout SECONDS` before the command. `write` also accepts `--from-file FILE` or
stdin. `show` reads an untracked snapshot; `read` tracks a branch input. Metadata
is JSON; conflicts emit JSON on stderr and exit 2. Operation errors exit 1;
invalid arguments exit 2, and interruption exits 130. A failed `check` returns its
JSON integrity report on stdout and exits 1. `--help` lists all commands.
## Publication contract
Both file bytes and metadata live in one SQLite database. Acceptance starts a
SQLite write transaction, checks the branch's dependencies against the current
accepted revision, and publishes the entire proposed change set in that same
transaction. This also serializes competing publishers in separate processes
using the same local database. A failed validation publishes nothing.
- **Read dependencies:** every base file read through a branch must still have
the recorded version. Reading or testing a missing path also records its
absence. Reading the branch's own staged output does not invent a base read.
- **Write conflicts:** every written or deleted path must still match its base
version, even when the worker never read it. File/directory prefix collisions
are rejected too.
- **File listings:** `branch.list_files()` tracks the base list of live paths.
A changed set of paths requires rechecking. Listing names does not imply that
their contents were read; read each file used in the computation.
Branches and snapshots read from a pinned immutable revision, so a multi-file
read cannot mix accepted revisions. Each accepted write creates a new path
version, including writes of identical bytes; empty change sets are rejected.
Deletion history is retained so a removed and recreated path is not silently
treated as an untouched path. Accepted revisions, branch provenance, tracked
inputs, and proposed outputs remain inspectable after reopening the database.
**Acceptance is always a whole branch change set.** There is no file selection,
cherry-pick, or automatic rebase. The SDK tracks inputs for the computation as a
whole, not a proven dependency graph for each output. Publishing only some
outputs could omit another required output. To accept independent work
separately, compute it in separate branches; after a conflict, create a fresh
branch and recompute. Copying old output into a fresh branch alone is not
evidence that its inputs were rechecked.
`branch.seal()` permanently freezes a complete proposal and returns its
`proposal_id`. Seal **before** `inspect`/`diff`, then call
`accept(expected_proposal=proposal_id)` so publication checks the reviewed token
in the same transaction as dependency validation. Sealed branches cannot add
tracked reads, listings, writes, or deletions. They remain inspectable after a
conflict; recompute on a fresh branch. The ID is a content token, not a signature
or approval policy.
`inspect` and `diff` alone do not freeze an open branch. Legacy `accept()` without
a token remains available and publishes the current whole change set. Use one
worker per branch; the caller owns consistency between outputs and intermediate
files produced within that branch. Sealing prevents later edits from changing a
reviewed proposal, but does not prove its generated content is correct.
## Capture and consistency limits
- Keep the source directory quiescent during `Workspace.create`, or import an
externally created filesystem snapshot. Import rejects symlinks and special
files and checks for metadata changes, but ordinary filesystem traversal
cannot guarantee an instantaneous source snapshot under concurrent writers.
Once captured, the committed database revision is immutable and coherent.
The database must be outside the source tree. Import requires macOS/Linux
filesystem APIs and fails clearly where those APIs are unavailable.
- Only operations through the SDK, CLI, or MCP tools are tracked. The command
runner conservatively tracks every exported input; raw host reads, external
APIs, and direct database edits are outside the contract.
This is a cooperative workspace API, not an OS filesystem mount or sandbox.
- Paths are relative workspace paths. Absolute paths, parent traversal, and
noncanonical paths are rejected. Files contain bytes; text helpers use UTF-8.
Empty directories are preserved. Source file permissions, ownership, links,
and devices are not represented by this file-tree API.
- Consistency is local to one database and SQLite's locking guarantees. Use a
local filesystem, not a shared network drive or asynchronously synced database.
This MVP does not provide distributed consistency or remote collaboration.
- There is no automatic semantic merge, claim of universal agent compatibility,
deterministic LLM replay, or proof that generated content is correct. An old
workspace snapshot cannot undo external API effects or restore an OS process.
- Capture loads all file bytes into memory; use small workspaces for this MVP.
Content is deduplicated, but every revision stores a full path/version index.
Retained history grows with the workspace. There is no
garbage collection, access control, or support for untrusted database writers.
- Capture imports every file; it does not apply `.gitignore` or exclusion patterns.
Use a dedicated input directory and manage access to database and backup files.
Check the [operational scope and upgrade procedure](docs/operations.md) before
deploying the SDK in a long-running application.
## Relationship to existing tools
[Git worktrees](https://git-scm.com/docs/git-worktree) provide separate working
directories for repository branches and integrate with Git's review and merge
workflow. This project's extra contract is explicit input-version tracking:
publishing an output can fail because a different file it read changed.
Git does not infer that relationship from arbitrary program reads.
[AgentFS](https://github.com/tursodatabase/agentfs) provides files, key-value state,
tool history, SDKs, and filesystem integration. Its
[shared-session guide](https://docs.turso.tech/agentfs/guides/sessions) describes
shared copy-on-write sessions and review with `diff`, with applying results back
done manually or by script. We cover the common files/state/tool-history SDK
workflow and add branch → tracked inputs → sealed review → atomic acceptance.
This is an independent schema and API, not AgentFS database compatibility. Native
FUSE/NFS mounting, OS isolation, cloud sync, and at-rest encryption are not
implemented; the [capability matrix](docs/platform.md) distinguishes these from
the SDK/MCP and materialized-command features that are implemented.
[Redis AFS](https://github.com/redis/agent-filesystem) already offers Redis-backed
workspaces, checkpoints, forks, and local sync or mounts.
[agent-coherence](https://github.com/cohexa-ai/agent-coherence) is especially
close adjacent work: it addresses tracked reads, stale state, coordinated writes,
pinned sessions, and atomic multi-file publication. This is not the first or only
project solving stale agent state. Our hypothesis is that a small local SDK,
explicit guarantees, and a runnable example make the workflow easy to adopt.
These are independent projects; no source code from them is included here.
## Development and roadmap
Run the correctness tests after installation:
```sh
python -m unittest discover -s tests -v
```
**Current release:** versioned files and directories, JSON state, tool history,
named sessions and forks, MCP stdio tools, materialized command execution,
tracked inputs, diffs, sealed review, atomic checked publication, conflict
evidence, consistent backup, integrity checking, and deterministic demos.
Operational tests cover multiple processes and interrupted transactions. This
remains an early local SDK: qualify it against your workload and storage before
deploying it; passing tests do not establish every production environment.
**Possible follow-ups:** use workload feedback to prioritize additional
language/framework adapters, storage compaction, and integration improvements.
Native filesystem mounting, OS isolation, encryption, and remote sync are
separate, optional integrations rather than prerequisites for this SDK's release.
Their scope should follow concrete user needs; AgentFS feature parity is not a
release requirement.
Contributions should keep the publication contract small and add regression
tests for meaningful consistency changes. Licensed under [MIT](LICENSE).
This server cannot be deployed
Maintenance
ActivityMaintained
ResponsivenessNo issues