
sprinty
# Sprinty
[Website](https://ebursztein.github.io/sprinty/) · [45-second demo](https://ebursztein.github.io/sprinty/demo.html) · [Try a project](docs/examples/README.md)
[](https://skills.sh/ebursztein/sprinty)
[](https://www.npmjs.com/package/sprinty-mcp)
**Agentic sprints done right.** Plan, coordinate, and scale high-quality agent work.
Sprinty turns ideas into organized tasks, coordinates agents on one shared plan, and keeps progress across sessions. Use it for websites, research, design, software, and other Git-backed projects. The local dashboard shows the work; resolving commits, check evidence, and artifacts make the results inspectable.
Start with a [website launch](docs/examples/website-launch.md), a [research brief](docs/examples/research-brief.md), or a [small agent team](docs/examples/parallel-agents.md). Each walkthrough includes a copyable starting prompt.
## What's new in 0.2.2
- **Direct claim recovery.** Use `item_claim({ id, force: "Previous agent terminated" })` to reassign work immediately. `force` is the explanation string (1–500 characters); no inactivity or stall threshold is required. `item_takeover` accepts the same option.
- **Clearer claim rejections.** Errors explain the unmet ownership or stall condition and show the explicit override option. Handover history and stale-owner protection remain intact.
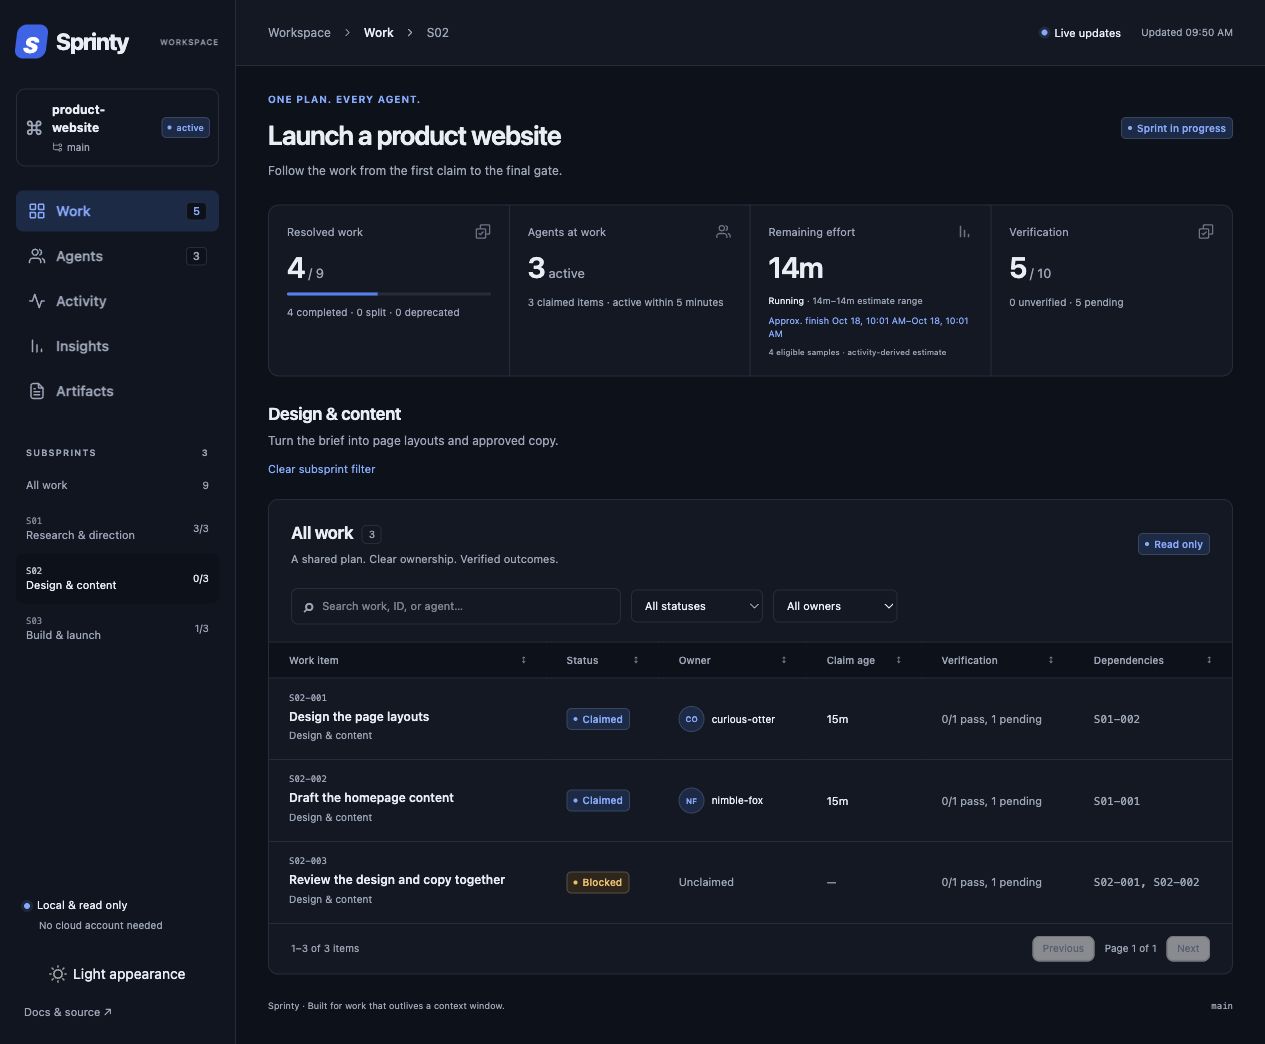
- **Updated dashboard.** The packaged dashboard now uses React, Untitled UI, and TanStack Table, with a refreshed work table and item detail views.
Upgrade to `npx -y sprinty-mcp@0.2.2` and restart your MCP connection.
## What's new in 0.2.1
- **Automatic caller identity.** Normal MCP connections remember the agent; the Claude plugin now supplies session/subagent IDs automatically through a bundled hook. Stable native IDs recover identities across MCP restarts without model-managed tokens.
- **Agent and claim discovery.** `agent_list()` shows agents and their activity; `items_claimed({ mine:true })` shows your work, claim age, progress, and potential stalls. Both support pagination.
Use `npx -y sprinty-mcp@0.2.1` and restart your MCP connection. Update the Claude plugin as well to install its automatic-identity hook. Existing MCP-only Claude installs retain connection identity; shared subagents need the plugin hook or explicit tokens.
## What's new in 0.2.0
- **Multiple agents, one sprint.** Each agent gets an adjective–animal name and its own token. Exclusive item claims and claim generations prevent agents from overwriting each other's work.
- **Visible stalls and handovers.** Track claim age and ownership history. Sprinty flags potential stalls after an hour without owner activity or three other item completions without progress; reassignment always requires an explicit handover.
- **ETA that handles laptop sleep.** Tools and dashboard share an activity-aware estimate that separates queue time from observed work, accounts for parallel agents and dependencies, and shows when work is paused or awaiting its owner.
- **Safer concurrent writes.** Cross-process locking, journaled recovery, pinned sprint bindings, and asynchronous gates protect shared local sprint data.
- **Updated agent skills.** Claude, Codex, and Gemini bundles explain tokens, claims, heartbeats, progress, and takeovers.
To upgrade, use `npx -y sprinty-mcp@0.2.0` as your MCP server command and restart the connection. Resume your existing sprint, retain the returned agent token, and call `item_claim` before editing or completing work. Concurrent agents must share the same canonical repository and data directory, with a separate token per agent. Existing ledgers remain readable; the new ETA shows “learning” until it has three eligible completed items.
See the [0.2.0 release notes](https://github.com/ebursztein/sprinty/releases/tag/v0.2.0) and [concurrent-agent workflow](#concurrent-agents-and-timing).
## Quick setup
Run from your project to install the MCP connection and skills for Codex or Claude Code:
```sh
curl -fsSL https://ebursztein.github.io/sprinty/install.sh | sh
```
Requires Node.js 20+, Git, and a client CLI. If both clients are installed, choose one when prompted, or append `-s -- --client codex` (or `claude`) after `sh`. The [installer](https://ebursztein.github.io/sprinty/install.sh) preserves existing MCP entries and installs skills in the repository. Restart your client afterward. Claude shared-subagent hooks still require the plugin below. Other clients can use the [agent setup prompt](https://ebursztein.github.io/sprinty/agent-start.txt) or manual instructions.
## Agent skills via `npx skills`
Discover and install the workflow and tool-reference skills for Codex, Claude Code, and other supported agents:
```bash
npx skills add ebursztein/sprinty
```
List first with `npx skills add ebursztein/sprinty --list`, or choose both explicitly with `--skill how-to-run-a-sprint --skill using-sprinty`. This installs agent guidance; connect the MCP server using the client instructions below to get Sprinty's tools. Claude's automatic shared-subagent identity hook comes with the Claude plugin, not with a skills-only install.
Prefer to have your agent handle setup? Copy the [setup prompt](https://ebursztein.github.io/sprinty/agent-start.txt) into your coding agent. The [website](https://ebursztein.github.io/sprinty/) includes the same prompt and install commands; [llms.txt](https://ebursztein.github.io/sprinty/llms.txt) provides a compact agent reference.
## Install
Sprinty is published to npm as `sprinty-mcp`. The npm package is the MCP server. Claude and Codex
plugin installs are distributed from this Git repository through each client's marketplace system.
### Claude Code
MCP-only install:
```bash
claude mcp add sprinty -- npx -y sprinty-mcp
```
Plugin install, with Sprinty skills plus the MCP server:
```bash
claude plugin marketplace add ebursztein/sprinty
claude plugin install sprinty@sprinty
```
The Claude marketplace manifest is `.claude-plugin/marketplace.json`; the plugin bundle is
`clients/claude/`.
### Codex
MCP-only install:
```bash
codex mcp add sprinty -- npx -y sprinty-mcp
```
Plugin install, with Sprinty skills plus the MCP server:
```bash
codex plugin marketplace add ebursztein/sprinty
codex plugin add sprinty@sprinty
```
The Codex marketplace manifest is `.agents/plugins/marketplace.json`; the plugin bundle is
`plugins/sprinty/`. Codex does not currently use an OpenAI npm plugin package for this flow.
### Gemini CLI
Use the MCP server directly from npm:
```bash
npx -y sprinty-mcp
```
The repository also includes a Gemini extension in `clients/gemini/` for clients that install local
Gemini extensions.
### Cursor, VS Code, Kiro, GitHub Copilot, ChatGPT & Codex
Sprinty ships a portable [Agent Plugins](https://agent-plugins.org) package at the repository root
(`plugin.json`, `mcp.json`, `skills/`), so any conformant client can load the skills and the MCP
server without a client-specific bundle. Follow your client's plugin install instructions and point
it at this repository.
Claude Code and Gemini CLI are not Agent Plugins clients today; they use the bundles above.
### Any MCP Client
Configure a stdio MCP server with:
```json
{
"command": "npx",
"args": ["-y", "sprinty-mcp"]
}
```
## Use
Sprinty never guesses the repository from the MCP server process cwd. Start or resume with explicit
paths:
```text
sprint_new({ goal, git_dir, data_dir, context_notes? })
sprint_resume({ git_dir, data_dir })
```
Use a worktree-local, gitignored `data_dir`, usually `<git_dir>/.sprinty`. When `data_dir` is
omitted and `git_dir` is provided, Sprinty uses `<git_dir>/.sprinty`. `sprint_new` and
`sprint_resume` return the dashboard URL. Call `info({ git_dir })` first for startup orientation and
compact sprint rows. Use `info({ workspace_dirs: [...] })` when you need to inspect multiple Sprinty
data dirs together, then `sprint_resume({ git_dir, data_dir })`.
## Concurrent agents and timing
`sprint_new` and `sprint_resume` return `agent: { id, name, token }`; `info` reports your generated adjective–animal identity. The connection remembers your identity automatically; ordinary calls need no name or token. Tokens are an advanced fallback for clients without automatic caller integration. Codex stdio agents normally have separate connections. The Claude plugin bundles a `PreToolUse` hook that supplies native session/subagent IDs, so shared-connection callers are also identified automatically. Update the installed plugin to get this hook; an MCP-only install does not include it. Other shared clients can use `agent_attach({})` and explicit `agent_token`. Without native caller integration, omitting it is allowed only with one attached agent. Never share tokens between agents or put them in notes/artifacts. `agent_detach` releases only your claims; it keeps the shared dashboard and other agents attached. Use `sprint_detach` only when you are the connection's sole agent.
Before editing an item, call `item_claim({ id, agent_token? })`. Then use the returned claim generation when appropriate: item mutation tools accept `claim_generation` as an explicit stale-write fence. Repeating your own claim is idempotent. `item_release({ id })` hands work back. Item edits, completion, splitting and deprecation require ownership; collaborative notes and artifacts remain available to other agents. A completed item's last owner may correct its recorded metadata and gates. Native caller mappings recover identity and claim generations after an MCP restart. Codex can supply `CODEX_THREAD_ID`, or a launcher can set `SPRINTY_SESSION_ID`; without a stable native ID, a new MCP process gets a new identity. For manual recovery, resume with your existing `agent_token`. Never invent native caller IDs in tool arguments.
For long tasks, call `agent_heartbeat({})` at least every five minutes and `item_progress({ id, message })` when meaningful progress occurs. Progress messages are trimmed and limited to 500 characters. Generic server uptime and dashboard polling do not count as agent activity. Repeated calls within one second coalesce their durable heartbeat, while mutations retain their own attributed timestamps.
Sprinty tracks claim age, historical ownership, estimated active work and owner inactivity separately. It flags a **potential stall** after either three other distinct items complete without item progress, or one hour without owner activity. Reads/heartbeats do not reset the three-item counter. Notes, item edits and related artifact updates do. No work is automatically reassigned: use `item_takeover({ id, explanation })` on a potentially stalled claim, with a nonempty explanation capped at 500 characters. History preserves both owners and the handover; old owners cannot continue writing. For an interrupted session or any explicit reassignment, use `item_claim({ id, force: "Previous session terminated; continuing its work" })`. `force` is the explanation (trimmed, 1–500 characters), not a boolean. It overrides ownership immediately without an inactivity or stall requirement; Sprinty does not infer that an owner is defunct. `item_takeover({ id, force: "Reason for reassignment" })` supports the same override. Both record the explanation and fence the previous owner. Ordinary claims retain exclusive ownership, and ordinary takeovers still require a potential stall. Rejections explain the unmet conditions and show the force option.
ETA is one shared activity-aware estimate. It excludes queue age, counts at most five minutes after each observed activity event within claim intervals, and uses the latest 20 eligible completed items (minimum three). Legacy, split and deprecated items do not train it. The median estimates item effort; the 25th–75th percentile range is an estimate range, not a statistical confidence interval. Remaining working time is aggregate estimated effort; the finish range separately accounts for active agents, existing owners and dependencies. With no agents active in five minutes it shows `paused`; work owned by an inactive agent shows `awaiting_handover`. Both suppress calendar finish forecasts. Before sufficient samples it shows `learning`; resolved work shows `complete`.
A shared data directory supports concurrent local processes on one canonical worktree. Separate worktrees retain separate sprint bindings. Gate execution is asynchronous and runs outside the write lock; if state changes during verification, retry the tool rather than treating stale evidence as valid.
## Tools
| Tool | Purpose |
| --- | --- |
| `agent_attach` / `agent_detach` | Create or recover a named agent session / detach it and release its claims. |
| `agent_heartbeat` | Report agent activity without resetting item progress. |
| `item_claim` / `item_release` | Exclusively claim an item / release your ownership. |
| `item_takeover` | Take over stalled work with `explanation`, or override ownership immediately with `force: "reason"` (1–500 characters). |
| `item_progress` | Record meaningful progress (1–500 characters). |
| `info` | Startup orientation before binding, including sprint rows, resume/create help, and dashboard state. |
| `sprint_new` | Start a sprint with explicit `git_dir` and `data_dir`; returns orientation and dashboard info. |
| `sprint_resume` | Reattach this MCP session to an existing sprint. |
| `sprint_detach` | Clear this MCP process binding and stop the dashboard. |
| `sprint_close` | Recheck gates, write the canonical changelog, and close after work and coverage are complete; `force:true` bypasses only final executable-gate failures. |
| `sprint_archive` | Archive an active sprint with a recovery reason. |
| `overview` | Compact sprint summary for orientation. |
| `next` | Compact active work window with current, next, blocked, relations, notes, and artifacts. |
| `search` | Regex search over the immutable sprint ledger. |
| `changelog` | Preview or export SemVer Markdown; canonical output is automatic at close. |
| `subsprint_new` | Create a feature-sized unit of work. |
| `subsprint_list` | List subsprints with compact item counts. |
| `subsprint_get` | Read one subsprint and its item rows. |
| `item_add` | Create one atomic, gated item with an optional gate timeout. |
| `item_get` | Read full item detail. |
| `item_update` | Update item metadata, execution settings, recorded commit, or dependency edges; completed items may revise executable gates/timeouts before close. |
| `item_done` | Complete an item with a real commit, gate evidence, and changelog entry. |
| `item_split` | Resolve an oversized item by creating a seeded subsprint. |
| `item_deprecate` | Drop an item with an explicit reason, or pass a subsprint id to drop it and its open items. |
| `note_add` | Attach a note to an item. |
| `note_list` | List notes for an item. |
| `note_get` | Read one note. |
| `note_update` | Update one note. |
| `artifact_add` | Attach a durable file path to the sprint. |
| `artifact_list` | List active artifacts. |
| `artifact_get` | Read one artifact record. |
| `artifact_update` | Update artifact metadata. |
| `dashboard_info` | Report the current dashboard URL and port. |
| `dashboard_restart` | Restart the dashboard and return the new URL and port. |
## Release
Publishing is gated by tests. The GitHub Release workflow runs `npm ci`, `npm test`, and only then
`npm publish --access public`.
Local checks:
```bash
npm test
npm run typecheck
```
## License
Apache-2.0
## Dashboard development
The next dashboard uses React, MIT Untitled UI components, Tailwind CSS 4, and TanStack Table 9. Its read-only `/state` contract and shared domain ETA remain unchanged.
```bash
npm run dev:dashboard -- --mode demo
```
Demo mode uses deterministic synthetic data for screenshots and UI checks. To develop against a real local sprint, set `SPRINTY_DASHBOARD_URL` to the URL returned by Sprinty and run `npm run dev:dashboard`. `npm run build` produces the self-contained MCP dashboard; `npm run typecheck` checks server and UI types.
The static marketing site lives in `website/`. Run `npm run dev:site` for a preview and `npm run build:site` to check local links and build `.site-dist/`. GitHub Pages publishes it through `.github/workflows/site.yml`; it is kept out of the npm server package. Dashboard screenshots use illustrative data and are labelled as the next-dashboard preview until that UI ships to npm.
TDQS
Scored across 38 tools
The domain prefixes (item_/subsprint_/note_/artifact_/agent_/sprint_/dashboard_) make most tools separable, but item_claim and item_takeover genuinely overlap since item_claim's `force` argument already overrides ownership immediately, duplicating takeover's force behavior. sprint_close vs sprint_archive and the family of compact readers (info, overview, next, subsprint_get, items_claimed) also require reading descriptions carefully to choose correctly.
Strong, mostly consistent snake_case with resource prefixes and a predictable verb set (add/get/list/update/done/split/deprecate/new/resume). Minor deviations only: a handful of bare names (info, next, overview, search, changelog) and one plural outlier (items_claimed) break the verb_noun pattern.
38 tools is heavy for a single sprint-tracking server, well past the comfortable 3-15 range. Several clusters could be consolidated (claim/release/takeover/progress as one item lifecycle tool; dashboard_info/dashboard_restart; sprint_close/sprint_archive), so the surface feels padded rather than scoped.
Sprint lifecycle, subsprints, items, claims, notes, artifacts, agents, and changelog are broadly covered, but there are real gaps: no delete for notes or artifacts (only add/get/list/update), and no generic item_list — items are only reachable via subsprint_get or `next`. Agents will hit dead ends when they need to remove a stale note/artifact or enumerate items directly.