
F
licenseNot graded
qualityD
maintenanceConverts web-based documentation into markdown format using jina.ai's conversion service, allowing users to scrape documentation from any URL and save it as markdown files.
10
-
Click on "Deploy Server".
Wait a few minutes for the server to deploy. Once ready, it will show a "Started" state.
In the chat, type @ followed by the MCP server name and your instructions, e.g., "@Deepwiki MCP Server fetch the Tailwind CSS documentation on theme configuration"
That's it! The server will respond to your query, and you can continue using it as needed.
Here is a step-by-step guide with screenshots.
⚠️ IMPORTANT NOTICE: This server is currently not working since DeepWiki has cut off the possibility to scrape it. We recommend using the official DeepWiki MCP server at https://docs.devin.ai/work-with-devin/deepwiki-mcp for the time being.
This is an unofficial Deepwiki MCP Server
It takes a Deepwiki URL via MCP, crawls all relevant pages, converts them to Markdown, and returns either one document or a list by page.
基于原项目: 此项目基于 deepwiki-mcp 修改而来
🔒 Domain Safety: Only processes URLs from deepwiki.com
🧹 HTML Sanitization: Strips headers, footers, navigation, scripts, and ads
🔗 Link Rewriting: Adjusts links to work in Markdown
📄 Multiple Output Formats: Get one document or structured pages
🚀 Performance: Fast crawling with adjustable concurrency and depth
NLP: It's to search just for the library name
Related MCP server: Deepwiki MCP Server
Prompts you can use:
deepwiki fetch how can i use gpt-image-1 with "vercel ai" sdkdeepwiki fetch how can i create new blocks in shadcn?deepwiki fetch i want to understand how X worksFetch complete Documentation (Default)
use deepwiki https://deepwiki.com/shadcn-ui/ui
use deepwiki multiple pages https://deepwiki.com/shadcn-ui/ui
Single Page
use deepwiki fetch single page https://deepwiki.com/tailwindlabs/tailwindcss/2.2-theme-systemGet by shortform
use deepwiki fetch tailwindlabs/tailwindcssdeepwiki fetch library
deepwiki fetch url
deepwiki fetch <name>/<repo>
deepwiki multiple pages ...
deepwiki single page url ...Add this to .cursor/mcp.json file.
{
  "mcpServers": {
    "mcp-deepwiki": {
      "command": "npx",
      "args": ["-y", "@bachstudio/mcp-deepwiki@latest"]
    }
  }
}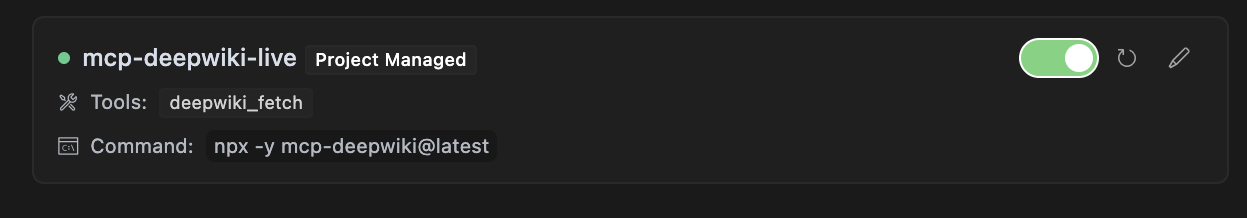
The package registers a tool named deepwiki_fetch that you can use with any MCP-compatible client:
{
  "action": "deepwiki_fetch",
  "params": {
    "url": "https://deepwiki.com/user/repo",
    "mode": "aggregate",
    "maxDepth": "1"
  }
}url (required): The starting URL of the Deepwiki repository
mode (optional): Output mode, either "aggregate" for a single Markdown document (default) or "pages" for structured page data
maxDepth (optional): Maximum depth of pages to crawl (default: 10)
{
  "status": "ok",
  "data": "# Page Title\n\nPage content...\n\n---\n\n# Another Page\n\nMore content...",
  "totalPages": 5,
  "totalBytes": 25000,
  "elapsedMs": 1200
}{
"status": "ok",
"data": [
{
"path": "index",
"markdown": "# Home Page\n\nWelcome to the repository."
},
{
"path": "section/page1",
"markdown": "# First Page\n\nThis is the first page content."
}
],
"totalPages": 2,
"totalBytes": 12000,
"elapsedMs": 800
}{
"status": "error",
"code": "DOMAIN_NOT_ALLOWED",
"message": "Only deepwiki.com domains are allowed"
}{
"status": "partial",
"data": "# Page Title\n\nPage content...",
"errors": [
{
"url": "https://deepwiki.com/user/repo/page2",
"reason": "HTTP error: 404"
}
],
"totalPages": 1,
"totalBytes": 5000,
"elapsedMs": 950
}When using the tool, you'll receive progress events during crawling:
Fetched https://deepwiki.com/user/repo: 12500 bytes in 450ms (status: 200)
Fetched https://deepwiki.com/user/repo/page1: 8750 bytes in 320ms (status: 200)
Fetched https://deepwiki.com/user/repo/page2: 6200 bytes in 280ms (status: 200){
"mcpServers": {
"mcp-deepwiki": {
"command": "node",
"args": ["./bin/cli.mjs"]
}
}
}# Clone the repository
git clone https://github.com/BACH-AI-Tools/deepwiki-mcp.git
cd deepwiki-mcp
# Install dependencies
npm install
# Build the package
npm run buildFor HTTP transport, you can make direct API calls:
curl -X POST http://localhost:3000/mcp \
  -H "Content-Type: application/json" \
  -d '{
    "id": "req-1",
    "action": "deepwiki_fetch",
    "params": {
      "url": "https://deepwiki.com/user/repo",
      "mode": "aggregate"
    }
}'DEEPWIKI_MAX_CONCURRENCY: Maximum concurrent requests (default: 5)
DEEPWIKI_REQUEST_TIMEOUT: Request timeout in milliseconds (default: 30000)
DEEPWIKI_MAX_RETRIES: Maximum retry attempts for failed requests (default: 3)
DEEPWIKI_RETRY_DELAY: Base delay for retry backoff in milliseconds (default: 250)
To configure these, create a .env file in the project root:
DEEPWIKI_MAX_CONCURRENCY=10
DEEPWIKI_REQUEST_TIMEOUT=60000
DEEPWIKI_MAX_RETRIES=5
DEEPWIKI_RETRY_DELAY=500Build and run the Docker image:
# Build the image
docker build -t mcp-deepwiki .

# Run with stdio transport (for development)
docker run -it --rm mcp-deepwiki

# Run with HTTP transport (for production)
docker run -d -p 3000:3000 mcp-deepwiki --http --port 3000

# Run with environment variables
docker run -d -p 3000:3000 \
  -e DEEPWIKI_MAX_CONCURRENCY=10 \
  -e DEEPWIKI_REQUEST_TIMEOUT=60000 \
mcp-deepwiki --http --port 3000# Install dependencies
pnpm install
# Run in development mode with stdio
pnpm run dev-stdio
# Run tests
pnpm test
# Run linter
pnpm run lint
# Build the package
pnpm run buildPermission Denied: If you get EACCES errors when running the CLI, make sure to make the binary executable:
chmod +x ./node_modules/.bin/mcp-deepwikiConnection Refused: Make sure the port is available and not blocked by a firewall:
# Check if port is in use
lsof -i :3000
Timeout Errors: For large repositories, consider increasing the timeout and concurrency:
DEEPWIKI_REQUEST_TIMEOUT=60000 DEEPWIKI_MAX_CONCURRENCY=10 npx mcp-deepwikiWe welcome contributions! Please see CONTRIBUTING.md for details.
MIT
X/Twitter: @kregenrek
Bluesky: @kevinkern.dev
Learn Cursor AI: Ultimate Cursor Course
Learn to build software with AI: instructa.ai
AI Prompts - Curated AI Prompts for Cursor AI, Cline, Windsurf and Github Copilot
codefetch - Turn code into Markdown for LLMs with one simple terminal command
aidex A CLI tool that provides detailed information about AI language models, helping developers choose the right model for their needs.# tool-starter
Fetch a deepwiki.com repo and return Markdown
| Name | Required | Description | Default |
|---|---|---|---|
| url | Yes | should be a URL, owner/repo name (e.g. "vercel/ai"), a two-word "owner repo" form (e.g. "vercel ai"), or a single library keyword | |
| maxDepth | No | Can fetch a single site => maxDepth 0 or multiple/all sites => maxDepth 1 | |
| mode | No | aggregate | |
| verbose | No |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description carries the full burden of behavioral disclosure. It mentions fetching and returning Markdown but omits critical details like authentication requirements, rate limits, error handling, or whether this is a read-only operation. For a tool with no annotation coverage, this is insufficient.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is extremely concise—a single sentence that directly states the tool's purpose. Every word earns its place, with no unnecessary elaboration. It's front-loaded and efficiently communicates the core functionality.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (4 parameters, 50% schema coverage, no output schema, no annotations), the description is inadequate. It doesn't explain what 'fetching' entails, how the Markdown is structured, error conditions, or usage constraints. For a tool with significant undocumented aspects, more context is needed.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 50%, with only the 'url' parameter well-documented in the schema. The description adds no parameter-specific information beyond what the schema provides. It doesn't explain the meaning of 'maxDepth', 'mode', or 'verbose' parameters, leaving gaps in understanding.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the action ('fetch') and resource ('deepwiki.com repo'), and specifies the output format ('return Markdown'). It distinguishes the tool by mentioning the specific domain (deepwiki.com) and output type. However, without sibling tools, there's no explicit differentiation from alternatives.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides no guidance on when to use this tool versus other methods or tools. It lacks context about prerequisites, typical use cases, or limitations. With no sibling tools mentioned, it doesn't address alternatives within the server.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
v1.0.0deepwiki_fetchScored across 1 tool
With only one tool, there is no possibility of ambiguity or overlap with other tools. The tool's purpose is clearly distinct by default.
The single tool name follows a consistent verb_noun pattern (deepwiki_fetch), and with no other tools to compare, there is no inconsistency in naming conventions.
One tool is too few for a server with the apparent purpose of fetching and processing DeepWiki repos, as it lacks operations like search, list, or update, making the scope feel thin and incomplete.
The tool surface is severely incomplete for a DeepWiki server; it only provides a fetch operation without any CRUD lifecycle coverage, search capabilities, or other essential functions for repo management.
Web search, URL content extraction to Markdown, site mapping, and recursive web crawler.
Web scraping for AI agents. Converts URLs to clean, LLM-ready Markdown with anti-bot bypass.
Read any web page as clean Markdown for AI agents: fetch, search, metadata, links. SSRF-safe.
Converts any URL to clean, LLM-ready Markdown using real Chrome browsers