PhpCodeArcheology
OfficialThe PhpCodeArcheology MCP server gives AI assistants direct access to PHP static analysis results, enabling deep code quality, architecture, and technical debt insights.
Overall Health Assessment – Retrieve the project's health score (0–100, graded A–F), technical debt score, problem counts, and general statistics.
Code Problem Inspection – List quality issues filterable by severity (
error,warning,info), type keyword, and count — covering God Classes, SOLID violations, security smells, dead code, deep inheritance, and more.Hotspot Detection – Identify the riskiest files ranked by git churn × cyclomatic complexity (files that change often and are hard to understand).
Refactoring Prioritization – Get classes ranked by refactoring urgency, with specific recommendations and driving factors (complexity, coupling, lack of tests, etc.).
Class Listing & Filtering – Browse all classes with key metrics (CC, LLOC, maintainability index, coupling, refactoring priority), with sorting and filtering support.
Detailed Metrics Lookup – Fetch full metrics for a specific class, file, or function, including cognitive complexity, LCOM, Halstead metrics, type coverage, and instability.
Dependency Analysis – Explore a class's outgoing dependencies and incoming usages along with coupling metrics.
Knowledge Graph Export – Access the full project knowledge graph (nodes, edges, clusters, dependency cycles) as structured JSON for architectural analysis or visualization.
Code Search – Find classes, files, or functions by name and view their key metrics.
Impact Analysis – Understand what is affected if a specific method or class changes, showing direct and transitive callers and full call chains.
Test Coverage Analysis – Review test ratio, tested vs. untested classes, coverage gaps, and untested complex code hotspots.
PhpCodeArcheology
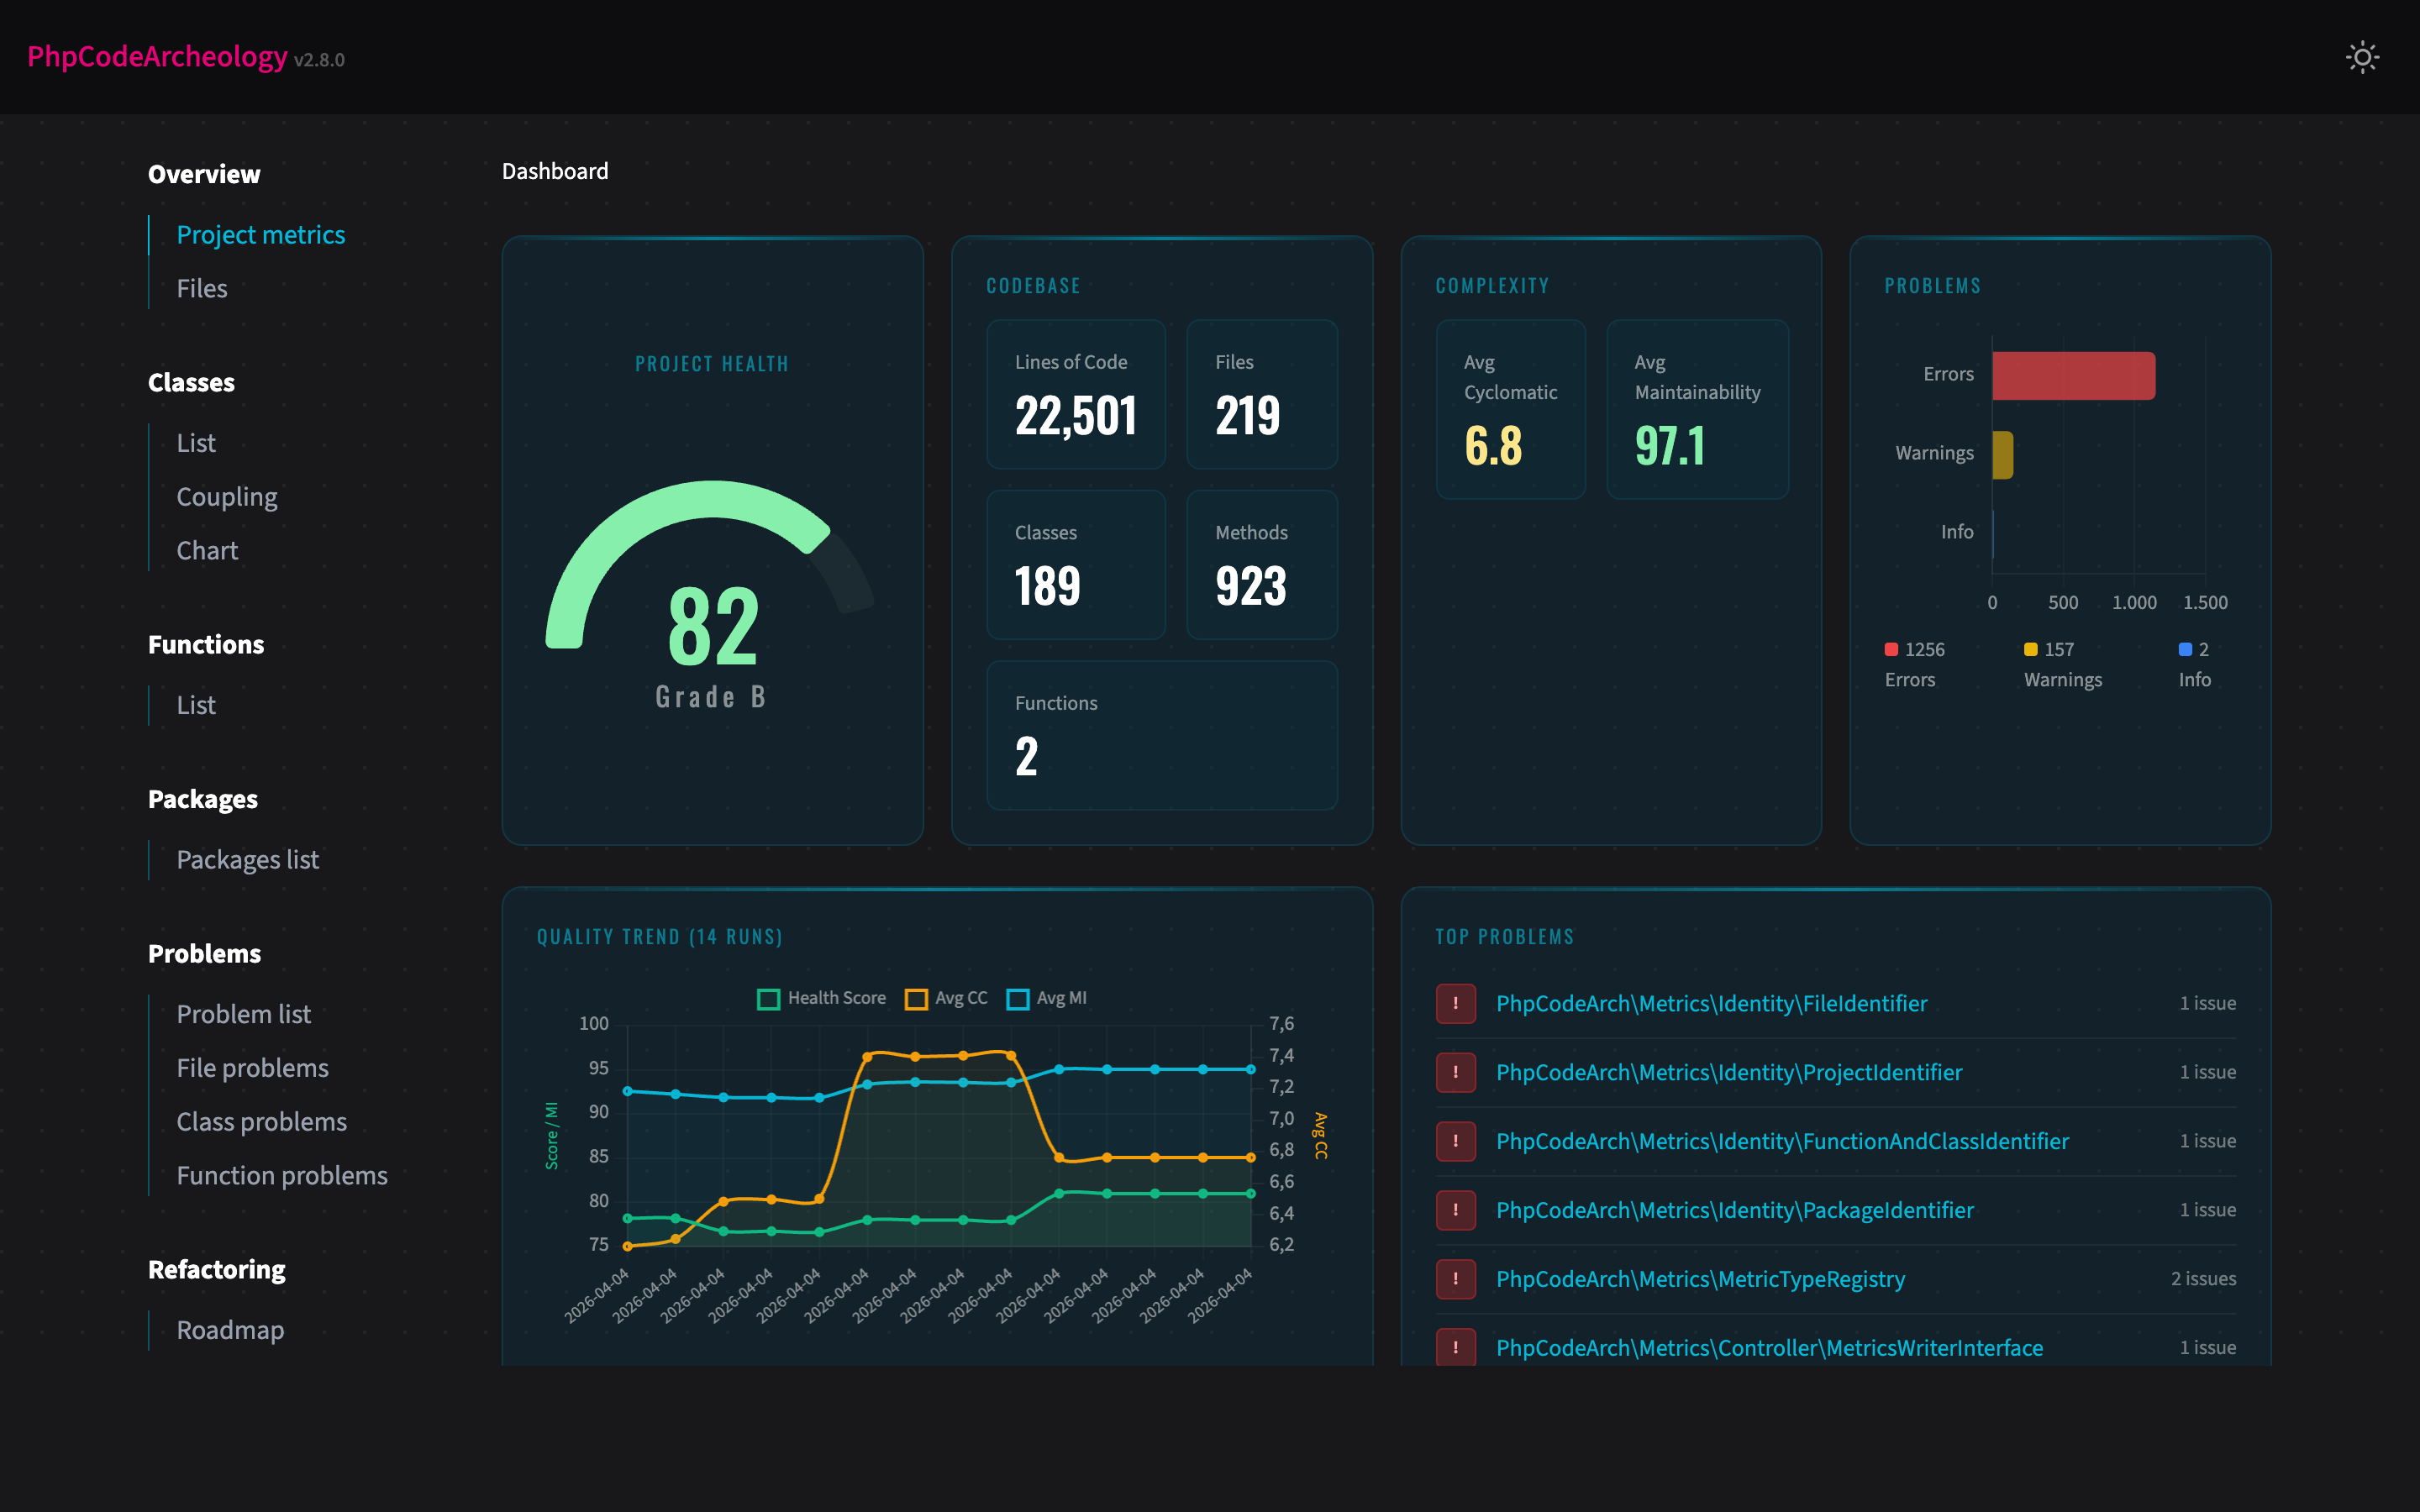
PhpCodeArcheology is a PHP static analysis tool that measures code quality through 60+ metrics including cyclomatic complexity, maintainability index, coupling, and cohesion. It generates comprehensive reports for files, classes, methods, and functions — detecting code smells, identifying hotspots via git churn analysis, and tracking quality trends over time.
Unlike PHPStan or Psalm (which focus on type safety and bug detection), PhpCodeArcheology focuses on architecture and maintainability — giving you the insights you need to understand and improve your codebase structure. Think of it as an alternative to PHPMetrics with deeper git integration, baseline management, and AI-ready output.
Features
60+ code quality metrics per file, class, and function — cyclomatic complexity, cognitive complexity, maintainability index, LCOM, Halstead metrics, coupling, instability, and more
Problem detection with 14 built-in rules — God Class, too complex, dead code, security smells, SOLID violations, deep inheritance, low type coverage, untested complex code
Test analysis — auto-detects PHPUnit/Pest/Codeception, maps test files to production classes, integrates Clover XML for line-level coverage, highlights untested hotspots
Git integration — churn analysis, hotspot detection (high churn + high complexity), author tracking
Source code display — view method source code directly in the HTML report with PHP syntax highlighting and a nesting-depth heatmap that reveals complexity hotspots at a glance (details below)
Multiple report formats — interactive HTML, Markdown, JSON, SARIF (GitHub Code Scanning), AI summary, Knowledge Graph (JSON)
Health Score — single 0-100 score with A-F grading for your entire project
Technical Debt Score — weighted problem score normalised per 100 logical lines of code
History tracking — trend charts across multiple analysis runs
Baseline management — track only new problems, ignore existing ones (ideal for legacy projects)
CI/CD ready — configurable exit codes, SARIF for GitHub Code Scanning, JSON for custom tooling
Quick mode — fast terminal-only output without report generation
CLAUDE.md generation — auto-generated project overview for AI coding assistants
AI integration — native MCP server for AI assistants like Claude Code (details below)
Related MCP server: trace-mcp
Quick Start
composer require --dev php-code-archeology/php-code-archeology
./vendor/bin/phpcodearcheologyNo config file needed — the tool works out of the box. It scans your src directory and creates an HTML report in tmp/report. Open tmp/report/index.html in your browser.
Tip: Add
tmp/reportto your.gitignoreto keep generated reports out of version control.
Table of Contents
Prerequisites
PHP 8.2 or higher (works on 8.2, 8.3, 8.4, 8.5)
Composer
Installation
composer require --dev php-code-archeology/php-code-archeologyGlobal Installation
composer global require php-code-archeology/php-code-archeologyMake sure ~/.composer/vendor/bin (or ~/.config/composer/vendor/bin) is in your $PATH. Then run from any directory:
phpcodearcheology /path/to/your/projectDocker
docker build -t phpcodearcheology https://github.com/PhpCodeArcheology/PhpCodeArcheology.gitRun against a local project:
docker run --rm -v "$(pwd)":/project -v "$(pwd)/report":/output phpcodearcheology /projectThis mounts your project into the container and writes the HTML report to ./report/.
PHAR (for legacy codebases)
If your project has dependency conflicts with PhpCodeArcheology's requirements (e.g. an older nikic/php-parser version), download the standalone PHAR from the Releases page. The PHAR ships all dependencies bundled, so it works without touching your project's composer.json.
# Download the PHAR and checksum from the latest release
curl -LO https://github.com/PhpCodeArcheology/PhpCodeArcheology/releases/latest/download/phpcodearcheology.phar
curl -LO https://github.com/PhpCodeArcheology/PhpCodeArcheology/releases/latest/download/phpcodearcheology.phar.sha256
# Verify checksum
shasum -a 256 -c phpcodearcheology.phar.sha256 # macOS
sha256sum -c phpcodearcheology.phar.sha256 # Linux
# Run it (PHP 8.2+)
php phpcodearcheology.phar --quick src/Use the PHAR when: your project's dependencies collide with PhpCodeArcheology's, you want a CI step without a composer require --dev, or you analyse a legacy codebase where adding dev-deps is risky.
Using the Composer Plugin
PhpCodeArcheology registers itself as a Composer plugin, so you can run the analysis directly via Composer:
composer codearch:analyzeWhen no path is given and no config file exists, it automatically detects your PSR-4 source directories from composer.json. All CLI options are supported:
composer codearch:analyze -- --quick
composer codearch:analyze -- --report-type=json --coverage-file=clover.xml
composer codearch:analyze -- src/ lib/To create a config file interactively:
./vendor/bin/phpcodearcheology initCLI Options
./vendor/bin/phpcodearcheology [options] [path...]Option | Description |
| Report format: |
| Output directory (default: |
| Fast analysis with terminal output only, no report generation |
| Disable coloured terminal output (also respects |
| Exit 1 on |
| Generate a |
| Git repository root (default: current directory) |
| File extensions to analyse (comma-separated, default: |
| Directories to exclude (comma-separated) |
| Clover XML coverage file from PHPUnit/Pest for line-level coverage data |
| Include source code with syntax highlighting and nesting heatmap in the HTML report (details below) |
| Show version |
Subcommands
init — Create Config File
./vendor/bin/phpcodearcheology initInteractively creates a php-codearch-config.yaml with sensible defaults. Detects common source directories (src, app, lib) automatically.
compare — Compare Two Reports
./vendor/bin/phpcodearcheology compare report-before.json report-after.jsonShows a delta view of metrics, problem counts, and lists new/resolved problems. Useful for answering: "Did my refactoring actually help?"
baseline — Track New Problems Only
./vendor/bin/phpcodearcheology baseline create src
./vendor/bin/phpcodearcheology baseline check srccreate saves the current problem set as a baseline. check runs a fresh analysis and reports only problems that are new compared to the baseline. Returns exit code 1 if new errors are found — ideal for CI pipelines on legacy projects.
Configuration
Create a php-codearch-config.yaml in your project root (or use init):
include:
- "src"
exclude:
- "vendor"
extensions:
- "php"
packageSize: 2
reportDir: "tmp/report"
reportType: "html"
git:
enable: true
since: "6 months ago"
root: "." # Git repository root (useful for monorepos or subdirectory analysis)
graph:
methodCalls: true # Track cross-class method calls in the knowledge graph (default: true)
php:
version: "8.2" # Target PHP version for parsing (default: host PHP version)
shortOpenTags: false # Treat <? as PHP open tag (default: false)
framework:
detect: true # Auto-detect Symfony/Laravel/Doctrine from composer.json (default: true)
adjustments:
doctrineCycles: true # Downgrade Entity↔Repository cycles to info (default: true)
entityCycles: true # Downgrade Entity↔Entity ORM cycles to info (default: true)
controllerThresholds: true # Raise dependency thresholds for controllers (default: true)
qualityGate:
maxErrors: 0
maxWarnings: 10
thresholds:
tooLong:
file: 400
class: 300
function: 40
method: 30
tooComplex:
cc: 10
ccLargeCode: 20
difficulty: 20
cognitiveComplexity: 15
avgMethodCc: 10
tooManyParameters:
warning: 4
error: 7
tooDependent:
function: 10
class: 20
lowTypeCoverage:
warning: 60
error: 40
deepInheritance:
warning: 4
error: 6
tooMuchHtml:
filePercent: 25
classPercent: 10
fileOutput: 10
classOutput: 4
hotspot:
minChurn: 10
minCc: 15
lcomExclude:
patterns: # Class name patterns to skip LCOM warnings (fnmatch)
- "*Exception"
- "*Error"
interfaces: # Implemented interfaces that justify low cohesion
- "EventSubscriberInterface"
- "EventListenerInterface"Note: Enums, interfaces, traits, and classes with 0-1 methods are always excluded from LCOM warnings regardless of configuration.
All threshold values shown above are the defaults. You only need to specify values you want to override.
Test Analysis
PhpCodeArcheology automatically detects your test infrastructure from composer.json (PHPUnit, Pest, or Codeception) and maps test files to production classes using PSR-4 namespaces, naming conventions, and directory structure.
What you get out of the box:
Per-class
hasTestflag and test file count in the HTML/Markdown/JSON reportsUntestedComplexCodewarnings for classes with cyclomatic complexity ≥ 8 and no tests (only when test infrastructure is detected)untestedas a refactoring priority driverA Tests page in the HTML and Markdown reports with a coverage gaps table and dashboard tiles
Important note on Pest: Pest's function-based tests (it(...), test(...)) contain no class declaration and cannot be mapped to production classes by name alone. To get accurate coverage for Pest projects, generate a Clover XML report — this tracks actual line execution regardless of test style.
With Clover XML coverage data (optional, recommended for Pest), you get line-level coverage per class:
# Generate coverage first (requires Xdebug or PCOV PHP extension)
XDEBUG_MODE=coverage vendor/bin/pest --coverage-clover clover.xml
# or: XDEBUG_MODE=coverage vendor/bin/phpunit --coverage-clover clover.xml
# PhpCodeArcheology auto-detects clover.xml in common locations:
# clover.xml, coverage/clover.xml,
# build/logs/clover.xml, build/coverage/clover.xml,
# var/reports/clover.xml, var/coverage/clover.xml (Symfony layout)
./vendor/bin/phpcodearcheology src/
# Or specify explicitly via CLI:
./vendor/bin/phpcodearcheology --coverage-file clover.xml src/To make the path persistent across runs, set it in your config file:
# php-codearch-config.yaml
coverageFile: var/reports/clover.xmlThe CLI flag still takes precedence over the config file value.
Coverage data is factored into the Health Score as a 10th factor (10% weight). The get_test_coverage MCP tool exposes all coverage data to AI assistants.
Report Types
Type | Subdirectory | Output | Use Case |
|
| Interactive HTML report with charts | Browser-based review |
|
| Markdown files | Text-based review, Git-friendly |
|
|
| Machine processing, custom tooling |
|
|
| GitHub Code Scanning, VS Code SARIF Viewer |
|
|
| Token-efficient summary for LLM consumption |
|
|
| Knowledge Graph (nodes + edges) for AI tools and visualisations |
Since v1.6.0, each report type writes into its own subdirectory. history.jsonl remains in the report root.
tmp/report/
├── html/
│ └── index.html
├── json/
│ └── report.json
├── sarif/
│ └── report.sarif.json
├── markdown/
│ └── ...
├── ai-summary/
│ └── ai-summary.md
├── graph/
│ └── graph.json
└── history.jsonlGenerate multiple report types in one run:
./vendor/bin/phpcodearcheology --report-type=html,jsonUpgrading from v1.5.x? Old report files in the report root (e.g.
index.html,report.json) are no longer overwritten. They can be safely deleted.
Source Code Display
The HTML report can embed the actual source code of methods and functions — with PHP syntax highlighting and a nesting-depth heatmap that makes complexity visible at a glance.
./vendor/bin/phpcodearcheology --source-code src/What you see:
Full PHP source code with syntax highlighting (powered by highlight.js)
Nesting heatmap — lines inside deeper control structures (if/for/while/switch/catch) progressively light up from yellow to red, so the complexity drivers are immediately obvious
Problem badges above the code showing all detected issues (e.g. "Complexity is too high")
Severity border — the code block gets a colored left border matching the worst problem level
Configuration:
sourceCode:
enable: true
display: "problems-only" # or "all" for every method/functionproblems-only(default with--source-code) — only shows source for methods with detected problems, keeping the report size manageableall— shows source for every method and function
The highlight.js assets are only included in the report when the feature is enabled.
Knowledge Graph Export
The graph report type exports your codebase structure as a machine-readable Knowledge Graph — designed for AI tools, graph databases, and custom visualisations.
./vendor/bin/phpcodearcheology --report-type=graph --report-dir=output src/
# Writes: output/graph/graph.jsonThe JSON output contains four top-level arrays:
nodes — five types of nodes, each with an id, type, name, metrics, and flags:
Node type | Metrics |
|
|
|
|
|
|
|
|
|
|
edges — relationships between nodes:
Edge type | Meaning |
| Class → Method |
| Class → Parent class |
| Class → Interface |
| Class → Trait |
| Class → Class (via |
| Method → Method (cross-class calls via |
| Class → Package |
| Class → Author |
| Class ↔ Class (dependency cycle, bidirectional) |
clusters — classes grouped by package.
cycles — detected dependency cycles with the involved class node IDs.
{
"version": "1.0",
"generatedAt": "2026-03-24T12:00:00+00:00",
"nodes": [
{ "id": "class:x1a2b3c4", "type": "class", "name": "App\\UserService",
"path": "/src/UserService.php",
"metrics": { "cc": 12, "lcom": 3, "mi": 65.2, "instability": 0.8,
"afferentCoupling": 5, "efferentCoupling": 20,
"gitChurnCount": 15, "gitCodeAgeDays": 42 },
"flags": { "interface": false, "trait": false, "abstract": false,
"final": false, "enum": false },
"problems": [] }
],
"edges": [
{ "source": "class:x1a2b3c4", "target": "class:x9c0d1e2f",
"type": "depends_on", "weight": 1 }
],
"clusters": [
{ "id": "package:App\\Services", "name": "App\\Services",
"nodeIds": ["class:x1a2b3c4"] }
],
"cycles": [
{ "nodes": ["class:xabc123", "class:xdef456"], "length": 2 }
]
}Key Metrics
Metric | Description |
Cyclomatic Complexity (CC) | Number of independent paths through code. Below 5 is good, above 10 needs attention. |
Cognitive Complexity | How difficult code is to understand (considers nesting depth). |
Maintainability Index (MI) | Composite score from CC, Halstead volume, and LOC. Above 85 is good, below 65 is concerning. |
LCOM | Lack of Cohesion of Methods — how well a class's methods relate to each other. Lower is better. |
Halstead Metrics | Difficulty, effort, volume, and vocabulary based on operators/operands. |
Type Coverage | Percentage of parameters and return values with type declarations. |
Instability | Ratio of efferent to total coupling (0 = stable, 1 = unstable). |
Technical Debt Score | Weighted problem points per 100 logical lines of code. |
Health Score | Overall project quality grade from A (excellent) to F (critical). |
For detailed descriptions, formulas, thresholds, and interpretation guidelines, see the Metric Reference.
The HTML report also includes a full Metric Glossary with descriptions, thresholds, and severity levels.
AI Integration (MCP Server)
PhpCodeArcheology includes a native MCP (Model Context Protocol) server — AI assistants like Claude can query your codebase analysis results directly, without reading files or parsing JSON manually.
Setup with Claude Code
The setup depends on how you installed PhpCodeArcheology:
Global installation (composer global require php-code-archeology/php-code-archeology):
claude mcp add phpcodearcheology -- phpcodearcheology mcpProject dependency (composer require --dev php-code-archeology/php-code-archeology):
claude mcp add phpcodearcheology -- vendor/bin/phpcodearcheology mcpOr drop a .mcp.json into your project root for team sharing:
{
"mcpServers": {
"phpcodearcheology": {
"command": "vendor/bin/phpcodearcheology",
"args": ["mcp"]
}
}
}Once connected, Claude can answer questions like "Which classes have the highest technical debt?", "Show me all God Classes", or "What are the top refactoring priorities in this project?" — using live analysis data.
Available MCP Tools
Tool | Description |
| Overall code health score, grade, and project statistics |
| Code quality problems, filterable by severity and type |
| Detailed metrics for a specific class, file, or function |
| Git hotspots ranked by churn × complexity |
| Ranked refactoring candidates with recommendations |
| Class dependency analysis (incoming/outgoing) |
| All classes with key metrics, sortable and filterable |
| Knowledge graph as JSON (nodes, edges, cycles) |
| Impact analysis: what breaks if you change a method? Shows callers and call chains |
| Test coverage summary — tested/untested classes, coverage gaps, test mapping |
| Search entities by name with metric overview |
Understanding the Health Score
The Health Score (0–100) is a guideline for tracking trends, not an absolute judgment of code quality. Some things to keep in mind:
Complex domains produce complex code. A financial calculation engine, a protocol parser, or a compiler will naturally have higher Halstead Difficulty and Cyclomatic Complexity than a REST API. That's expected, not a defect.
Scores are most useful over time. A project that moves from 65 to 72 over six months is improving — even if it never reaches 90.
Focus on outliers, not the average. The most actionable insight is which classes deviate significantly from your project's baseline. Those are your refactoring candidates.
Don't compare across projects. A score of 80 in a Symfony application is not the same as 80 in a CLI tool. Different architectures and domains have different natural complexity floors.
The score is weighted across 10 factors (Maintainability Index, Problem Density, Complexity, Coupling, Code Structure, HTML Ratio, Encapsulation, Dependencies, Abstractness, and Test Coverage). See docs/metrics-formulas.md for the exact formulas and weights.
Further reading: How I Use PhpCodeArcheology in Practice — a real-world walkthrough covering legacy assessment, hotspot discovery, and measuring refactoring success.
Memory and Performance
The directories vendor/, node_modules/, and .git/ are excluded automatically — you don't need to configure this. If you point the tool at your project root, only your own code is analysed.
For large codebases (50k+ files), analysis may require more memory than the default 1G. The tool respects your php.ini memory_limit — if you've set it to -1 (unlimited), it stays unlimited. To adjust the limit per project, add memoryLimit to your config file:
# php-codearch-config.yaml
memoryLimit: "2G" # or "-1" for unlimitedA Note on Metric Accuracy (v2.7.0)
I use PhpCodeArcheology extensively on my own projects to track code quality over time. While doing so, I noticed that some metric values didn't quite add up — method-level Halstead difficulty seemed too high, certain classes were flagged as God Classes when they shouldn't have been, and error counts felt inflated.
After a thorough review, I found and fixed several calculation bugs that had been present since earlier versions. The most impactful was a Halstead operand tracking bug at the method level, along with double-counting in complexity predictions, false positives in God Class detection, and a few other issues.
I sincerely apologize for the inaccuracy. A code analysis tool must be trustworthy above all else, and these bugs undermined that. Version 2.7.0 corrects all known calculation issues, and I've added hand-calculated test fixtures to ensure the formulas stay correct going forward.
What this means for you: If you're upgrading from an earlier version, your analysis results will change — most notably, error counts will decrease significantly and Health Scores will improve. The tool will show a one-time notice on first run. See docs/metrics-formulas.md for a detailed breakdown of every change and its expected impact.
Development
The HTML report templates use Tailwind CSS. The compiled output.css is committed to the repository, so you do not need Node.js to use or contribute to this project.
If you modify HTML templates or CSS, rebuild with:
npm install
npm run build:cssFor live rebuilding during development:
npm run watch:cssRoadmap
See ROADMAP.md for planned features. The next major version (3.0) is in development on the 3.0.x branch — it reworks how relative problem thresholds are calculated, replacing the current "percentage above/below project average" rule with robust statistical outlier detection. Track progress in the 3.0.0 milestone.
Contributing
Contributions are welcome! Check the open issues for bugs and feature requests, or see the Roadmap for planned features. For larger changes, open an issue first to discuss the approach.
Author
Marcus Kober — GitHub
License
MIT
Available Tools
11 toolsget_class_listB
Returns a sorted and filtered list of classes with key metrics (CC, LLOC, MI, refactoring priority, coupling).
| Name | Required | Description | Default |
|---|---|---|---|
| limit | No | Parameter: limit | |
| filter | No | Parameter: filter | |
| sort_by | No | Parameter: sort_by |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations provided; description mentions sorting and filtering but does not disclose pagination, permissions, or read-only nature. Minimal behavioral context beyond stated features.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Single sentence, front-loaded with action, no unnecessary words.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Covers main purpose but omits details about output format, pagination, or sorting/filtering behavior. Adequate for a simple list tool but could be more informative.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema coverage 100% but parameter descriptions are generic. Description adds context that parameters enable sorting and filtering, but lacks allowed values or formatting details.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
Clearly states verb 'returns', resource 'list of classes', and included key metrics. Distinguishes from siblings like get_metrics which focus on metrics without list.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance on when to use this tool versus alternatives like get_hotspots or get_metrics. Implicit usage from name but no explicit context.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_dependenciesB
Returns dependency information for a specific class — outgoing dependencies, incoming usage, and coupling metrics.
| Name | Required | Description | Default |
|---|---|---|---|
| direction | No | Parameter: direction | |
| class_name | Yes | Parameter: class_name |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations, the description must disclose behavioral traits. It mentions returning 'dependency information' and 'coupling metrics' but does not explain error conditions, performance, or whether it requires specific permissions. The description is minimal.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single, concise sentence that front-loads the main purpose. Every part is necessary and adds value.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given no output schema, the description should explain the return format. It mentions 'coupling metrics' but not their structure. The direction parameter is undocumented in the description. Overall, the description is too brief to fully inform usage.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Although schema coverage is 100%, the parameter descriptions are merely 'Parameter: direction' and 'Parameter: class_name', adding no meaning. The tool description does not explain the direction parameter or its values, and class_name is only implied to identify the class.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
Description clearly states the tool returns dependency information for a specific class, including outgoing dependencies, incoming usage, and coupling metrics. This distinguishes it from sibling tools like get_class_list and get_metrics.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance on when to use this tool versus alternatives such as get_impact_analysis or get_problems. The description only states what it does, leaving the agent to infer usage context.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_graphC
Returns the knowledge graph of the project as JSON with nodes, edges, clusters, and dependency cycles.
| Name | Required | Description | Default |
|---|---|---|---|
| summary_only | No | Parameter: summary_only |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations provided. Description implies read-only behavior but does not disclose performance implications, authentication needs, or edge cases. Lacks detail beyond return format.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Single sentence, concise, but misses critical information about parameters and usage. Could be restructured to front-load key behavioral details.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
No output schema, and description only partially describes return format. Does not cover parameter behavior or edge cases. Inadequate for an agent to use correctly without additional inference.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The input schema has one parameter with a tautological description. The tool description does not explain how 'summary_only' affects the output, leaving the agent to guess.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool returns the knowledge graph with specific elements (nodes, edges, clusters, dependency cycles). It distinguishes from sibling tools like get_dependencies which focus on a subset, but does not explicitly differentiate.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance on when to use this tool versus siblings or alternatives. No context on prerequisites or typical use cases.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_health_scoreA
Returns the overall code health score, grade, technical debt score, problem counts, and project statistics.
| Name | Required | Description | Default |
|---|---|---|---|
No parameters | |||
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations provided, so the description carries full burden. It only lists return fields without disclosing behavioral traits such as data freshness, side effects, or cost implications.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Single sentence of 15 words, front-loading purpose and returns, with no wasted phrases.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's simplicity (no params, no output schema), the description covers the main return items adequately, though a mention of read-only nature would enhance completeness.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
No parameters exist (schema coverage 100%), baseline 4 applies. Description adds value by itemizing return data, fulfilling the need for zero-parameter tools.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool returns overall code health score, grade, technical debt, problem counts, and project statistics, specifying the resource and actions distinctly from sibling tools.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Implied usage for retrieving overall health summary, but no explicit guidance on when to use this tool versus specific siblings like get_metrics or get_problems, nor any when-not-to-use conditions.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_hotspotsB
Returns the top N code hotspots ranked by churn × cyclomatic complexity. Files that change often and are complex.
| Name | Required | Description | Default |
|---|---|---|---|
| limit | No | Parameter: limit |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations exist, so description must carry full burden. It only states the output ranking but omits behavioral traits like read-only nature, data freshness, caching, or any side effects. This is a significant safety gap.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Two sentences with no wasted words. The action and ranking criteria are front-loaded, making it easy to scan.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
No output schema exists, yet description fails to specify what data each hotspot contains (e.g., filename, churn, complexity). Also missing default behavior when limit is omitted or pagination. For a simple tool, this is insufficient.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The sole parameter 'limit' has a tautological schema description ('Parameter: limit'), and the tool description does not clarify what it controls (e.g., max count, default). Schema coverage is 100% in terms of existence but adds zero value.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
Description clearly states it returns top N code hotspots ranked by churn × cyclomatic complexity, with a succinct definition. This distinguishes it from sibling tools like get_metrics or get_health_score.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance on when to use this tool vs alternatives like get_metrics or get_refactoring_priorities. Does not mention when not to use or provide contextual cues for selection.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_impact_analysisA
Analyzes the impact of changing a method. Shows direct and transitive callers across classes, affected class count, and call chains. Provide class_name (required) and optionally method_name and depth (default 2).
| Name | Required | Description | Default |
|---|---|---|---|
| depth | No | Parameter: depth | |
| class_name | Yes | Parameter: class_name | |
| method_name | No | Parameter: method_name |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided. The description implies a read-only analysis but does not explicitly state that the tool has no side effects or destructive behavior. The behavioral transparency is adequate but could be improved.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Three sentences, with the first sentence front-loading the purpose, the second adding output details, and the third specifying parameter usage. No wasted words.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
The description covers what the tool does and what it shows (callers, call chains, count). Though no output schema is provided, the description is sufficient for an agent to understand the tool's functionality. Minor gap: could mention that it is read-only.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema coverage is 100%, but the description adds context beyond the schema: notes that class_name is required, method_name is optional, and depth defaults to 2. This helps an agent understand how to use the parameters.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states it analyzes the impact of changing a method, showing direct and transitive callers, affected class count, and call chains. This distinguishes it from sibling tools like get_dependencies or get_graph.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description says to provide class_name (required) and optionally method_name and depth, but does not explicitly state when to use this tool versus alternatives like search_code or get_dependencies.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_metricsB
Returns all available metrics for a specific class, file, or function. Provide the entity name (e.g. 'UserService').
| Name | Required | Description | Default |
|---|---|---|---|
| type | No | Parameter: type | |
| entity | Yes | Parameter: entity |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations provided. The description only states what it returns and the input needed, but does not disclose behavioral traits like whether it is a read-only operation, potential side effects, or error conditions.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Two sentences with no superfluous information. Front-loaded with the core functionality.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
No output schema, so description should describe return values. It says 'all available metrics' but does not specify format or what metrics are included. Adequate but incomplete for an agent to fully understand the response.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema description coverage is 100% but parameter descriptions are minimal ('Parameter: type', 'Parameter: entity'). The description adds an example for the entity parameter, but no guidance for the type parameter. Meets baseline but does not excel.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb 'Returns', resource 'metrics', and scope 'for a specific class, file, or function'. It distinguishes from siblings like get_class_list or get_dependencies which have different purposes.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No explicit guidance on when to use this tool vs alternatives. It only implies usage through the entity types mentioned, but lacks exclusions or context for selection.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_problemsA
Returns a filtered list of code problems. Filter by severity (error/warning/info), type keyword, and limit.
| Name | Required | Description | Default |
|---|---|---|---|
| type | No | Parameter: type | |
| limit | No | Parameter: limit | |
| severity | No | Parameter: severity |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Annotations are absent, so the description carries full burden. It only states the tool returns a filtered list, missing traits like read-only nature, pagination, or performance implications. Minimal disclosure.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Single sentence, no unnecessary words. Efficiently communicates the tool's purpose and filter options.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
For a tool with 3 optional parameters and no output schema, the description is adequate but lacks details on return structure, default behavior, or constraints. Could be more informative.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema descriptions are minimal ('Parameter: type'), so the description adds value by clarifying that severity values are error/warning/info and that type is a keyword. It explains the filter capabilities beyond the schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool returns a filtered list of code problems, specifying the resource and action. It lists the filter options (severity, type keyword, limit), distinguishing it from sibling tools like search_code or get_metrics.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description implies usage for filtering problems but does not explicitly state when to use this tool over alternatives like search_code or provide any exclusions. No guidance on default behavior when no filters are applied.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_refactoring_prioritiesB
Returns classes ranked by refactoring priority score. Includes recommendation and driving factors.
| Name | Required | Description | Default |
|---|---|---|---|
| limit | No | Parameter: limit | |
| min_score | No | Parameter: min_score |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations provided; description carries full burden. It mentions output content but lacks details on safety (read-only), side effects, or authorization needs.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Two sentences, no redundancy. Front-loaded with key purpose, then details. Efficient.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
No output schema, no explanations for optional parameters, no behavioral context. An agent cannot infer valid inputs or output structure.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema coverage is 100% but parameter descriptions are trivial ('Parameter: limit'). Description does not explain limit or min_score beyond schema, failing to add meaning.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
Description clearly states the tool returns classes ranked by refactoring priority score, including recommendation and driving factors. It distinguishes from siblings like get_class_list (plain list) and get_problems (issues).
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance on when to use this tool vs alternatives. Among siblings like get_health_score, get_hotspots, no context for selection.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
get_test_coverageC
Get test coverage analysis: test ratio, tested classes, and untested complex code gaps
| Name | Required | Description | Default |
|---|---|---|---|
| limit | No | Parameter: limit |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
No annotations are provided, so the description must fully disclose behavior. It identifies the type of analysis but omits whether the tool is read-only, requires authentication, or has computational cost. It also does not explain the response format or pagination behavior.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is a single, concise sentence that conveys the core functionality without unnecessary words. It is structured well but could benefit from a clearer breakdown of what each element means.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool has one parameter, no output schema, and no annotations, the description lacks sufficient detail for correct invocation. It does not specify the format of the output, how 'limit' affects results, or how coverage metrics are defined.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The only parameter 'limit' has a tautological description in the schema. The tool description does not mention or clarify the parameter's purpose, leaving the agent without context on how to use it effectively.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool retrieves test coverage analysis, listing three specific aspects (test ratio, tested classes, untested complex code gaps). This gives a good sense of its purpose, though it doesn't differentiate from sibling tools that also analyze code health.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance on when to use this tool versus siblings like get_health_score, get_hotspots, or search_code. The description does not mention prerequisites, limitations, or alternative tools.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
search_codeA
Search for classes, files, or functions by name. Returns matching entities with key metrics.
| Name | Required | Description | Default |
|---|---|---|---|
| limit | No | Parameter: limit | |
| query | Yes | Parameter: query | |
| entity_type | No | Parameter: entity_type |
TDQS
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
With no annotations, the description must cover behavior. It indicates a search and return of metrics, but does not disclose ordering, pagination, or whether the operation is read-only. It is somewhat transparent but lacks detail.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Two sentences, front-loaded with the action and resource. No unnecessary words; every sentence adds value. Extremely concise.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
While the description covers the basic purpose, it omits details about the return format, pagination, or what 'key metrics' means. Given the complexity (3 parameters, no output schema, many siblings), more information is needed for full completeness.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
The input schema has generic parameter descriptions (e.g., 'Parameter: query'), adding no value. The tool description fills the gap by implying query is a name search and entity_type filters entity types, providing meaningful context beyond the schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool searches for classes, files, or functions by name and returns matching entities with key metrics. It uses a specific verb and resource, and the name 'search_code' plus the sibling list differentiate it from more specific tools like get_class_list.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No explicit guidance is provided on when to use this tool versus its siblings. It does not mention alternatives or conditions for use, leaving the agent without decision criteria.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Tool Schema Changelog
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
11 tool updates
v1.1.0- Added
get_class_list - Added
get_dependencies - Added
get_graph - Added
get_health_score - Added
get_hotspots - Added
get_impact_analysis - Added
get_metrics - Added
get_problems - Added
get_refactoring_priorities - Added
get_test_coverage - Added
search_code
TDQS
Scored across 11 tools
Most tools target a clear, distinct slice of project analysis—health, problems, dependencies, impact, coverage, hotspots—so an agent can usually pick correctly. A few pairs overlap somewhat (get_class_list vs get_refactoring_priorities, get_metrics vs get_class_list), but the descriptions provide enough differentiation.
All tools follow the `get_` or `search_` prefix with lowercase snake_case nouns, creating a highly predictable pattern. The naming clearly communicates read-only analysis operations consistent with the server's purpose.
Eleven tools is well within the ideal range for a code-analysis server. Each tool covers a meaningful analysis concern without redundancy or bloat.
The surface covers the full archeology workflow: overall health, problems, refactoring priorities, class metrics, dependencies, graph navigation, search, impact analysis, test coverage, and hotspots. For a read-only analysis tool, there are no obvious dead ends or missing core capabilities.
Maintenance
Related MCP Connectors
AI-powered codebase analysis — call graphs, security, dead code, complexity. 150+ tools.
MCP server for static security analysis of Android source code
Hosted MCP server for PostgreSQL diagnostics: slow queries, missing indexes, connection pressure.
- AgentCatOAuthcom.agentcat
Analytics and debugging for your MCP server — explore usage and sessions, then root-cause errors.
Related MCP Servers
- FlicenseAqualityDmaintenanceAn MCP server that transforms repositories into queryable knowledge by combining static code analysis with git history tracking. It allows users to investigate codebase structure, identify fragile files based on churn, and receive risk assessments through natural language queries.7-
- AlicenseAqualityAmaintenanceFramework-aware code intelligence MCP server that builds a cross-language dependency graph from source code. 53 integrations (Laravel, Django, Rails, Spring, NestJS, Next.js, and more) across 68 languages. 100+ tools for navigation, impact analysis, refactoring, security scanning, session memory, and CI/PR reports — up to 97% token reduction.291,663 npm176MIT
- AlicenseAqualityDmaintenanceMCP server for comprehensive code analysis, navigation, and quality assessment across 25+ programming languages.988MIT
- FlicenseNot gradedqualityDmaintenanceMCP server for automated architectural mapping, security vulnerability detection, ML asset tracking, and code metrics in local repositories.-