
A
licenseA
qualityC
maintenanceFetch URLs and return clean, LLM-ready markdown with metadata and layered prompt injection defense. Configurable timeouts, word limits, JS rendering, and link extraction. All-in-one MCP server + CLI.
1
1
MIT

nab is a local, token-optimized HTTP client server that fetches web content as clean markdown for LLM pipelines, with browser authentication, anti-bot evasion, and structured output.
fetch — Fetch any URL and convert to clean markdown (HTML, PDF, JSON, plain text, SPA data), with:
Browser cookie injection (Brave, Chrome, Firefox, Safari, Edge, Dia)
Focus mode (BM25 scoring) to extract only relevant sections
Token budget with structure-aware truncation
Diff mode to return only changed content vs. a previous snapshot
Named sessions for persistent cookie state across requests
HTTP/2, HTTP/3 (QUIC), TLS 1.3, and realistic browser fingerprinting
fetch_batch — Fetch multiple URLs concurrently with HTTP/2 multiplexing and connection pooling, returning per-URL timing results
submit — Submit web forms by auto-extracting hidden fields and CSRF tokens, merging user-provided fields, and POSTing; supports session-based cookie persistence
login — Auto-login to websites using 1Password credentials, with MFA/TOTP handling and session cookie storage for subsequent authenticated requests
auth_lookup — Look up 1Password credentials for a URL/domain, returning username and TOTP availability without exposing the password
fingerprint — Generate realistic browser fingerprint profiles (Chrome, Firefox, Safari) including User-Agent, Sec-CH-UA, and Accept-Language headers
validate — Run a validation suite against real websites to verify HTTP/2, HTTP/3, compression, fingerprinting, TLS 1.3, and 1Password integrations
benchmark — Benchmark URL fetching over multiple iterations, returning min/avg/max response times and error counts
Enables credential lookup, auto-login with CSRF handling, and TOTP support for accessing authenticated websites.
Used as the underlying protocol for extracting structured data from Mastodon instances.
Enables authenticated web fetching by injecting session cookies from the Brave browser.
Allows defining custom extraction rules for specific web elements using CSS selectors in plugins.
Utilized to retrieve structured discussion data from Hacker News via its Firebase-backed API.
Facilitates authenticated access and bot evasion through cookie injection and browser fingerprinting.
Extracts structured data from issues and pull requests via the GitHub REST API.
Provides specialized extraction for Google Workspace services including Docs, Sheets, and Slides.
Converts documents into clean markdown while preserving comments and suggested edits.
Renders spreadsheet data as markdown tables for easy processing by LLMs.
Extracts text content and comments from presentations into clean markdown.
Retrieves structured content from posts and reels using the oEmbed API.
Enables data extraction from Single Page Applications (SPAs) and lightweight rendering of dynamic content.
The primary output format, converting complex HTML into token-efficient markdown optimized for LLM context windows.
Fetches structured social media content from Mastodon users and statuses via ActivityPub.
Retrieves subreddit discussions and comments using the Reddit JSON API.
Supports authenticated fetching and anti-fingerprinting using Safari's browser profiles and cookies.
Used for configuring custom site extractors and plugins via plugins.toml.
Provides native passkey authentication support for secure website logins.
Extracts structured article content using the Wikipedia REST API.
Retrieves video metadata and information via the YouTube oEmbed API.


Token-optimized web fetcher + multilingual ASR + URL watcher. MCP 2025-11-25 compliant. Rust. macOS arm64 first, cross-platform.
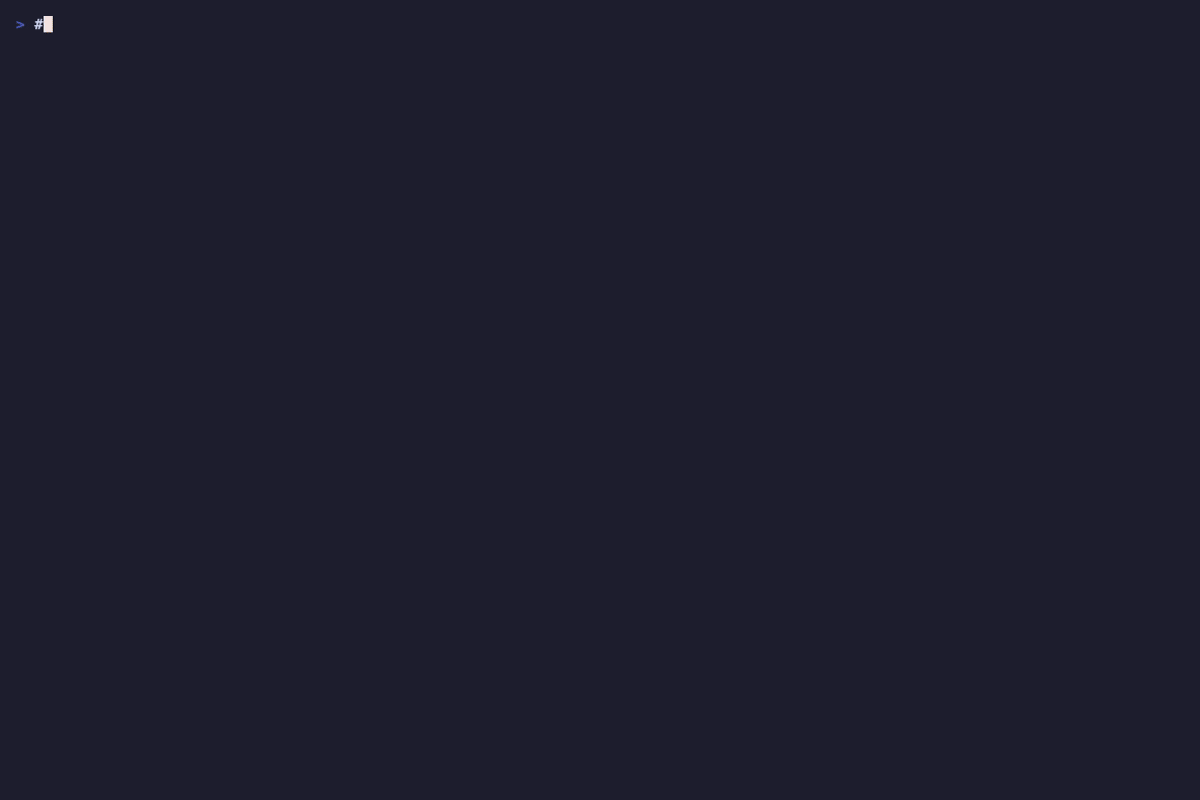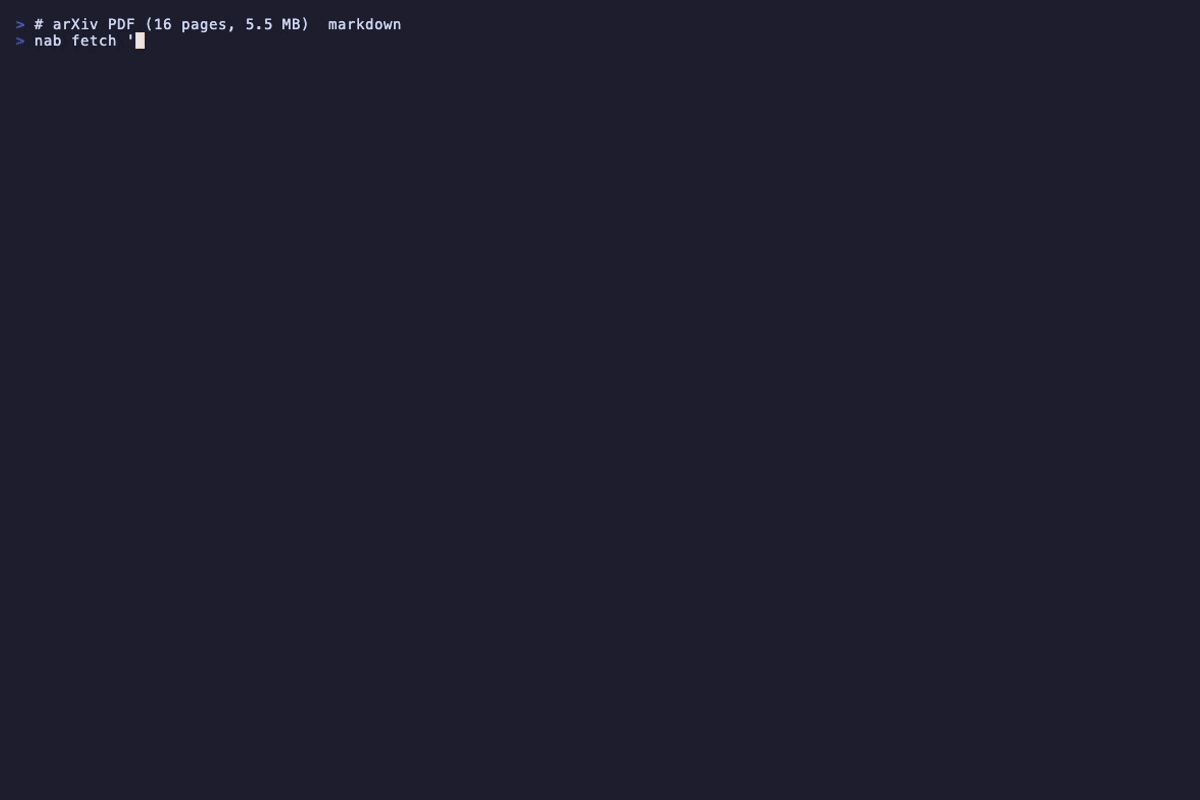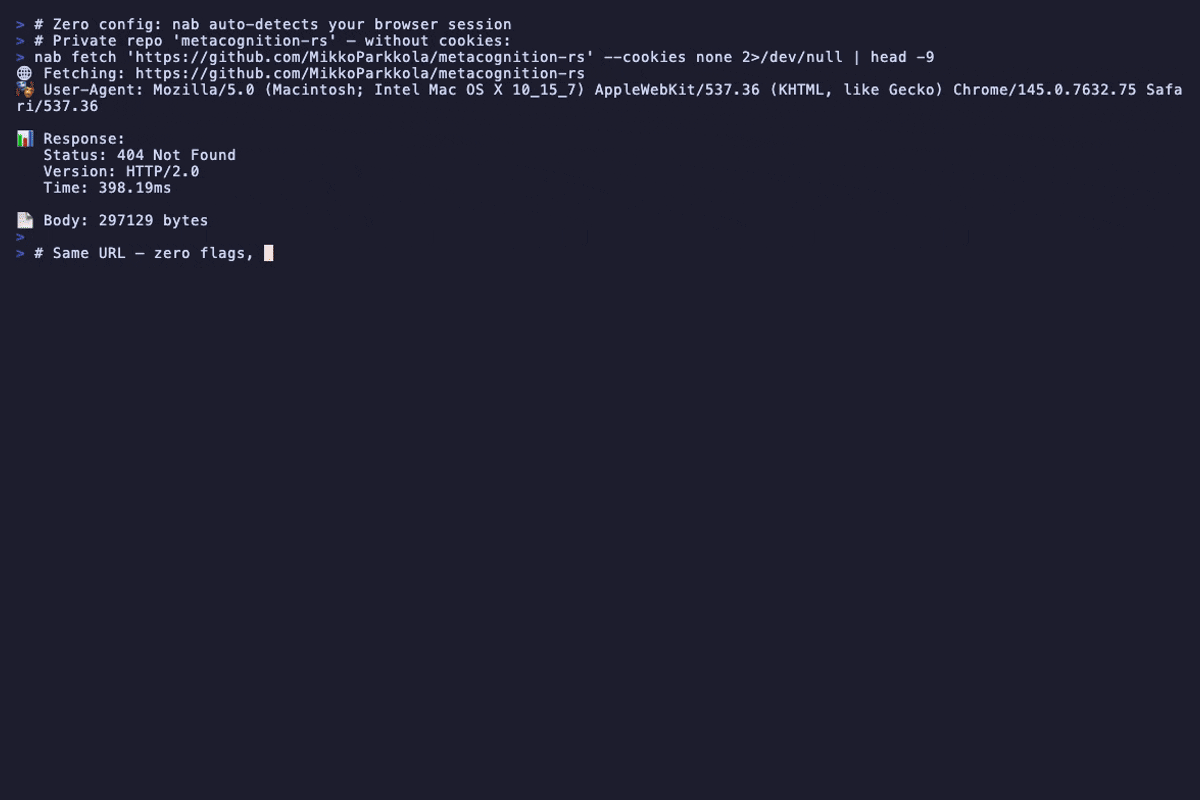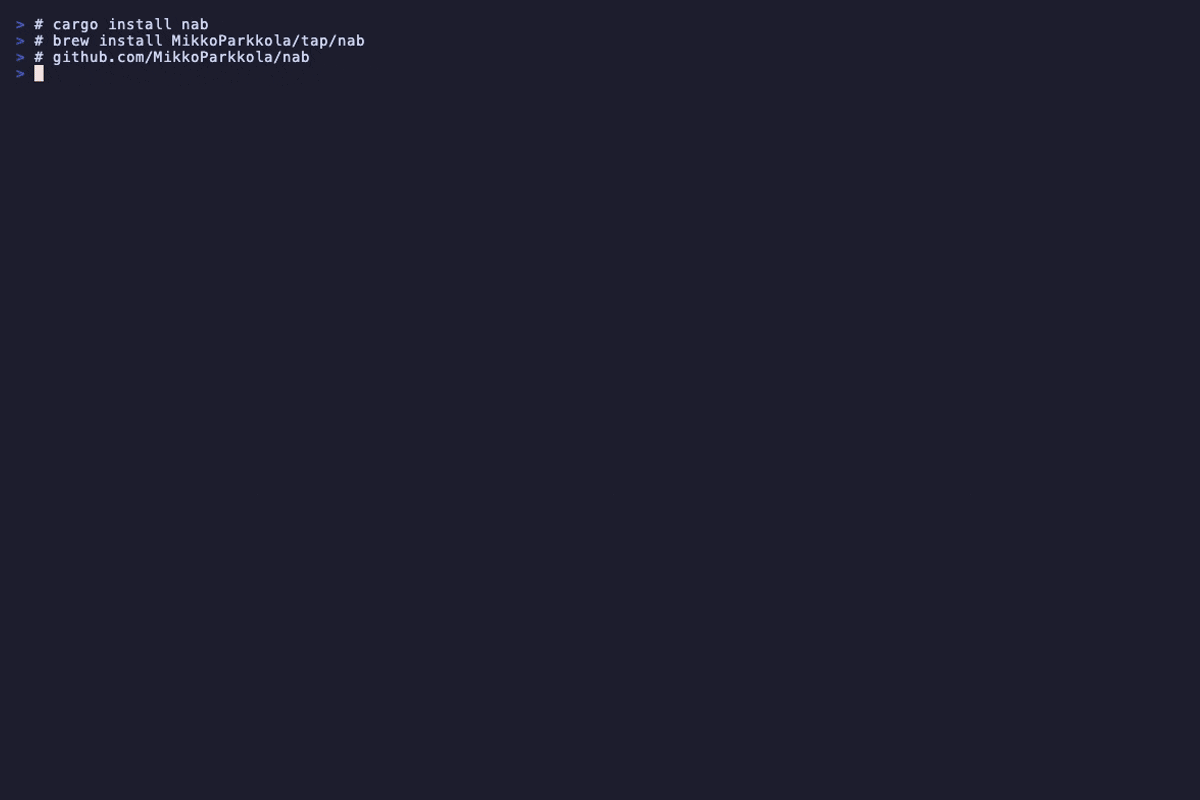
nab is a single Rust binary that does three things very well: it fetches any URL as clean markdown (with your real browser cookies and anti-bot evasion), it analyzes any audio or video file with on-device multilingual ASR and speaker diarization, and it watches any URL for changes and pushes notifications when content moves. Everything runs locally. There are no API keys to set up by default. The output is shaped for LLM context windows.
Token-lean by design. nab returns only what an LLM actually needs — clean markdown, BM25-lite query-focused extraction, and structure-aware token budgets — cutting the token cost of web research instead of dumping raw HTML into your context window.
Multimodal, fully on-device. Transcribe and diarize any audio or video (FluidAudio / Parakeet TDT v3 on the Apple Neural Engine — 131× realtime on a 2-hour clip, 25 EU languages, word-level timestamps, optional Qwen3-ASR for zh/ja/ko/vi) and OCR images via Apple Vision (15 languages, ~10–50 ms). No cloud, no API keys.
Authenticated reach. Real browser cookies, 1Password auto-login with TOTP/MFA, WebAuthn passkeys, fingerprint spoofing and WAF evasion — reach internal dashboards, SaaS apps, and paywalled research with the same command as a public URL.
Watch the web. Subscribe to any URL via MCP resources — conditional GETs, semantic diff, adaptive backoff. RSS for the entire web.
Prompt-injection defense, on by default. Hidden instructions addressed to your AI are surfaced to you, not silently executed by your model — see Security.
Everything is a single local Rust binary. No cloud backend, no API keys by default, output shaped for LLM context windows.
Related MCP server: markdown-for-agents-mcp
Tell your AI assistant (recommended):
Read https://github.com/MikkoParkkola/nab and install nab as my web fetching and audio analysis MCP server
Your agent will install the binary, wire itself up, and start fetching. Works in Claude Code, Cursor, Windsurf, and any AI with terminal access.
Or install and try manually:
brew trust --tap MikkoParkkola/tap   # Homebrew 6.0+
brew install MikkoParkkola/tap/nab                            # install
nab fetch https://news.ycombinator.com                        # fetch as markdown
nab models fetch fluidaudio                                   # download ASR model
nab analyze interview.mp4 --diarize                           # transcribe + identify speakers
nab watch add https://status.openai.com --interval 5m # subscribe to changesCommand | What it does |
| Fetch any URL as clean markdown. HTTP/3, browser cookie injection (Brave / Chrome / Firefox / Safari / Edge / Dia), 1Password auto-login, fingerprint spoofing, fetch-time YARA-X redaction for prompt-injection/exfil signatures, 12 site providers. MCP fetch also supports query-focused extraction, readability, and token budgets. |
| Explicit opt-in browser rendering for JS-heavy pages through a configured Chrome DevTools Protocol WebSocket endpoint. No Chromium is bundled and default |
| Transcribe and diarize. FluidAudio (Parakeet TDT v3) on Apple Neural Engine, 131x realtime on a 2-hour clip, word-level timestamps, 25 EU languages, optional Qwen3-ASR for zh/ja/ko/vi, optional active reading via MCP sampling. |
| Monitor a URL and push notifications via subscribable MCP resources. RSS for the entire web. Conditional GETs, semantic diff, adaptive backoff. |
| Persistent install of inference model binaries. Supports |
| MCP 2025-11-25 server. stdio + Streamable HTTP. 12 tools, 4 prompts, 2+N resources, structured logging, sampling, roots, elicitation. |
| Apple Vision OCR engine. 15 languages. Apple Neural Engine accelerated. ~10-50 ms per image. macOS only. |
Web pages increasingly carry instructions written for the AI, not for you — concealed in HTML comments, display:none / aria-hidden text, data-ai / data-mcp / data-agent attribute payloads, or WebMCP manifests. Fetch such a page with a naive tool and those hidden instructions land straight in your model's context, where they can be acted on. This is the prompt-injection-as-phishing class of attack.
nab treats every fetched page as hostile input and runs two local, non-networked guards before any content reaches your agent — on by default, no flag, no setup:
Secure Ingestion guard — detects and strips machine-targeted markup that is invisible to humans (AI-addressed comments, hidden display:none / aria-hidden text, agent-only data-* payloads, WebMCP advertisements) and reports each detection at Info / Warn / Block severity, so you see what a page tried to tell your agent instead of it being silently executed.
YARA-X signature guard — scans every returned body for prompt-injection, exfiltration, secret-leak, and obfuscation signatures, redacting matched sections by default. Set NAB_YARA_ACTION=refuse to block the fetch outright (or NAB_YARA_BYPASS=1 as an audited emergency opt-out).
The net effect: hidden instructions become visible to you, not executed by your model — a strong reason to point your agent at nab fetch instead of a built-in web-fetch tool.
Licensing: both guards are Enterprise Edition modules — free for personal and non-commercial use under PolyForm Noncommercial 1.0.0; commercial / business use requires a commercial license (see COMMERCIAL.md and the License section).
brew tap MikkoParkkola/tap
brew install nabMost users want this path — these are ready-to-run binaries; nothing is compiled on your machine.
If you have cargo-binstall, it fetches the right pre-built binary automatically:
cargo binstall nabOtherwise download directly from GitHub Releases. Both the nab CLI and the nab-mcp server ship for every platform below, alongside checksums-sha256.txt:
Platform | CLI binary | MCP server binary |
macOS Apple Silicon |
|
|
macOS Intel |
|
|
Linux x86_64 (glibc) |
|
|
Linux x86_64 (static musl) |
|
|
Linux ARM64 (glibc) |
|
|
Linux ARM64 (static musl) |
|
|
Windows x64 |
|
|
Example install for macOS Apple Silicon (substitute the filename for your platform):
shasum -a 256 -c checksums-sha256.txt --ignore-missing
chmod +x nab-aarch64-apple-darwin
mv nab-aarch64-apple-darwin /usr/local/bin/nab
xattr -d com.apple.quarantine /usr/local/bin/nab 2>/dev/null || trueBuilds nab locally — requires the Rust toolchain (1.95 or newer) and takes a few minutes:
cargo install nabgit clone https://github.com/MikkoParkkola/nab.git
cd nab
cargo install --path .If you install nab through more than one channel (for example a Homebrew tap
and cargo install), the copy that wins depends on PATH order. On many
setups /opt/homebrew/bin comes before ~/.cargo/bin, so a Homebrew binary can
shadow a newer cargo-installed one — and nab --version then reports the older
version.
Run the built-in diagnostic to see every nab on your PATH, which one wins,
and their versions:
nab doctorIf the binary on your PATH is the stale one, its doctor may predate this
command; invoke the newer install by full path to diagnose, e.g.
~/.cargo/bin/nab doctor. To resolve, keep a single install channel
(brew uninstall nab or cargo uninstall nab), or reorder PATH so the
directory of the install you want comes first.
Add to your MCP client config (Claude Desktop, Cursor, Windsurf, etc.):
{
  "mcpServers": {
    "nab": {
      "command": "nab-mcp"
    }
  }
}
Or use the auto-installer:
nab mcp install                        # Claude Desktop (default)
nab mcp install --client claude-code   # Claude Code
nab mcp install --client cursor        # Cursor
nab mcp install --client windsurf      # Windsurf
nab mcp install --client codex         # OpenAI Codex CLI
nab mcp install --client vscode        # VS Code Copilot
nab mcp install --client zed           # Zed
nab mcp install --dry-run              # preview without writing
Also supported: gemini, amazon-q, lm-studio.
See MCP integration below for the full list of tools, capabilities, and HTTP transport.
This repository includes a local Claude Code plugin in plugin/. It bundles nab MCP auto-registration with the Claude Elite research, url-insight, wayback, ia, and oreilly skills.
claude --plugin-dir ./pluginThe plugin exposes the /nab workflow shape for fetch, authenticated Brave-cookie fetches, archive retrieval, and multi-source research. It keeps nab's auth-aware path front and center: nab fetch --cookies brave <url> for existing browser sessions and nab fetch --1password <url> for 1Password/TOTP flows.
# Basic fetch — auto-detects browser, returns markdown
nab fetch https://example.com

# Use cookies from a specific browser
nab fetch https://github.com/notifications --cookies brave

# 1Password auto-login (TOTP/MFA supported)
nab fetch https://internal.company.com --1password

# Google Workspace (Docs, Sheets, Slides) with comments
nab fetch --cookies brave "https://docs.google.com/document/d/DOCID/edit"

# Output JSON with confidence scores
nab fetch https://example.com --format json

# Batch fetch with parallelism
nab fetch --batch urls.txt --parallel 8

# Explicit browser rendering for JS-heavy pages
NAB_BROWSER_CDP_WS=wss://... nab browser https://example.com
nab fetch https://example.com --render --browser-cdp-url wss://...
Common flags for fetch:
Flag | Description |
|
|
| 1Password credential lookup + auto-login |
| HTTP or SOCKS5 proxy |
|
|
| Skip markdown conversion |
| Force readability extraction for generic HTML pages |
| Apply an output token envelope; returned markdown uses 80% for headroom |
| Opt in to remote thin-content recovery via |
| Opt in to configured CDP browser rendering for JS-heavy pages; requires |
| Show what changed since the last fetch |
| HTTP method + body |
| Write body to file |
MCP fetch additionally supports focus, readability, max_tokens, and session parameters for query-focused extraction, readability extraction, structure-aware token budgets, and persistent encrypted cookie sessions.
nab analyze transcribes audio and video files locally. The default backend on macOS arm64 is FluidAudio, which runs Parakeet TDT v3 on the Apple Neural Engine.
# Download the ASR model (~600 MB, one-time)
nab models fetch fluidaudio

# Transcribe a video
nab analyze interview.mp4

# Add speaker diarization (PyAnnote community-1)
nab analyze interview.mp4 --diarize

# Force a language hint (BCP-47)
nab analyze podcast.mp3 --language fi

# Word-level timestamps
nab analyze talk.mp4 --word-timestamps

# Active reading: nab uses MCP sampling to look up references mentioned in the audio
nab analyze interview.mp4 --active-reading

# Expose speaker embeddings for matching against hebb's voiceprint database
nab analyze interview.mp4 --diarize --include-embeddings

# Output JSON
nab analyze podcast.mp3 --format json
Real numbers from a 2 h 09 m English audio file (Karen Hao interview, MacBook Pro M-series):
Metric | Value |
Wall time | 59.6 s |
Realtime factor | 131x |
FluidAudio mean confidence | 97.18 % |
Audio extraction (ffmpeg) | ~650x realtime |
Backend | Platform | Languages | Diarization |
| macOS arm64 | 25 EU languages, +zh/ja/ko/vi via Qwen3-ASR (opt-in) | PyAnnote community-1 |
| Linux/x86, macOS, Windows | Parakeet ONNX, 25+ langs | sherpa-onnx pyannote-seg-3.0 |
| Universal fallback | whisper-large-v3-turbo, 99 langs | none |
nab watch turns any URL into a subscribable resource. MCP clients receive notifications/resources/updated when the content changes.
nab watch add https://news.ycombinator.com --interval 10m
nab watch add https://example.com/pricing --interval 1h --selector "table.pricing"
nab watch add https://api.openai.com/status --interval 5m --notify-on regression
nab watch list
nab watch logs <id>
nab watch remove <id>
Per-watch options:
Flag | Default | Description |
| 1h | Polling interval ( |
| none | CSS selector to scope diff to one element |
|
|
|
|
|
|
The poller uses conditional GETs (If-None-Match, If-Modified-Since), so 304 responses cost effectively nothing. Watches with five consecutive failures auto-mute. Adaptive backoff applies on 429 and 503.
nab models list                           # show installed model versions
nab models fetch fluidaudio               # download FluidAudio binary + Parakeet weights
nab models update fluidaudio              # check for upstream updates
nab models verify fluidaudio              # checksum + smoke test
Both whisper and sherpa-onnx ship as cross-platform fallbacks alongside the macOS-default fluidaudio backend.
nab-mcp is a native Rust MCP server. It runs over stdio (default) or Streamable HTTP. It is fully compliant with MCP protocol version 2025-11-25.
nab mcp install                        # Claude Desktop (default)
nab mcp install --client claude-code   # Claude Code
nab mcp install --client cursor        # Cursor
nab mcp install --client windsurf      # Windsurf
nab mcp install --client codex         # OpenAI Codex CLI
nab mcp install --client vscode        # VS Code Copilot
nab mcp install --client zed           # Zed
nab mcp install --dry-run              # preview what would change
Also supported: gemini, amazon-q, lm-studio. This auto-detects the nab-mcp binary path, backs up your existing config, and adds the nab entry. Restart your client after installing.
Add to your MCP client configuration (~/.config/claude/mcp.json or equivalent):
{
  "mcpServers": {
    "nab": {
      "command": "nab-mcp"
    }
  }
}nab mcp serve --http 127.0.0.1:8765
# or directly:
nab-mcp --http 127.0.0.1:8765Bind to localhost by default. Origin checks and MCP-Protocol-Version header validation are enforced per spec.
Capability | Status |
Tools | 12 tools with structured output schemas, annotations, validation errors |
Prompts | 4 prompts ( |
Resources | 2 static + N dynamic watch resources, all subscribable |
Logging |
|
Sampling | nab calls back to the host LLM for active reading, focus extraction, form auto-fill |
Roots |
|
Elicitation | Form mode + URL mode for OAuth/SSO |
Argument completion |
|
Server icons | Light + dark SVG |
Transports | stdio + Streamable HTTP (resumable, session-scoped) |
The 12 MCP tools:
Tool | Description |
| Fetch URL → markdown, with cookies, focus, token budget, session |
| Parallel multi-URL fetch with task-augmented async execution |
| Submit a form with CSRF + smart field extraction |
| 1Password auto-login with TOTP support |
| Look up 1Password credentials for a URL |
| Generate browser fingerprint profiles |
| Run the validation test suite |
| Time URL fetches with stats |
| Transcribe and diarize audio/video |
| Create a URL watch and subscribe |
| Manage watches |
nab detects URLs for 12 platforms and uses APIs or stable structured page data instead of broad HTML scraping.
Provider | URL pattern | Method |
Twitter / X |
| FxTwitter API |
| JSON API | |
Hacker News |
| Firebase API |
GitHub |
| REST API |
Google Workspace | Docs, Sheets, Slides | Export API + OOXML |
YouTube |
| oEmbed |
Wikipedia |
| REST API |
StackOverflow |
| API |
Mastodon |
| ActivityPub |
| oEmbed | |
| oEmbed | |
Substack |
| Article DOM ( |
If no provider matches, nab falls back to standard HTML fetch + markdown conversion.
nab is built around a small set of orthogonal subsystems: cmd/ (CLI), bin/mcp_server/ (MCP server), content/ (HTML / PDF / OCR pipeline), analyze/ (ASR + diarization + vision), watch/ (URL monitoring + subscriptions), auth/ (cookies + 1Password + WebAuthn), site/ (per-site providers), and the shared AcceleratedClient (HTTP/3 + connection pool + fingerprint store).
See:
docs/ARCHITECTURE.md — full module map and data flow
docs/sovereign-stack.md — how nab composes with hebb to form a local-first multimodal stack
docs/getting-started.md — new user onboarding
The docs/design/ directory tracks recent design proposals:
analyze-v2.md — multilingual ASR + diarization + vision pipeline
url-watch-resources.md — URL watch as MCP subscribable resources
active-reading.md — active reading via MCP sampling
mcp-spec-closure.md — closing the last MCP 2025-11-25 spec gaps
nab is half of a sovereign multimodal stack. The other half is hebb, a neuroscience-inspired memory MCP server. Composition examples:
nab analyze --diarize --include-embeddings → hebb voice_match → speakers labeled with names
nab fetch URL → hebb kv_set → personal sovereign web memory
nab watch add URL → hebb kv_set (on update) → time-series of changes to any web page
See docs/sovereign-stack.md for the full composition story.
nab requires no configuration files. It uses smart defaults: auto-detected browser cookies, randomized fingerprints, and markdown output.
Persistent state lives in ~/.nab/:
Path | Purpose |
| Content snapshots for |
| AES-256-GCM encrypted named-session jars (non-Windows) |
| Locally generated master key for session encryption (non-Windows) |
| Cached browser versions (auto-updates every 14 days) |
| URL watch state |
| Installed inference model binaries |
Optional plugin configuration at ~/.config/nab/plugins.toml. See docs/getting-started.md for plugin examples.
Variable | Purpose |
| HTTPS proxy URL |
| HTTP proxy URL |
| Proxy for all protocols |
| Logging level (e.g., |
| Set to |
| Comma-separated CIDR/IP allowlist exempting only those private ranges (e.g. |
| Set to |
| Pushover notifications for MFA |
| Telegram notifications for MFA |
use nab::AcceleratedClient;

#[tokio::main]
async fn main() -> anyhow::Result<()> {
    let client = AcceleratedClient::new()?;
    let html = client.fetch_text("https://example.com").await?;
    println!("Fetched {} bytes", html.len());
    Ok(())
}Rust 1.95+ for building from source
ffmpeg for analyze and stream commands: brew install ffmpeg
1Password CLI (optional, for credential integration): see 1Password docs
See CONTRIBUTING.md for development setup, code style guidelines, testing instructions, and pull request process.
This tool includes browser cookie extraction and fingerprint spoofing capabilities. They are intended for legitimate use cases — accessing your own authenticated content, automated testing, sites where you have authorization. Use responsibly.
MCP server not connecting? Run nab-mcp directly in your terminal to see errors. Verify the binary exists with which nab-mcp. If installed via cargo install nab, both nab and nab-mcp should be on your $PATH.
Cookie extraction failing? Grant Full Disk Access to your terminal in System Settings > Privacy & Security > Full Disk Access (macOS). Browser cookies are stored in protected directories. Use --cookies brave to target a specific browser. Background tools that must never show a Keychain authorization dialog can run NAB_KEYCHAIN_INTERACTION=never nab .... Plaintext cookies and credentials that macOS can provide silently still work; credentials that require approval are unavailable, and Nab fails closed instead of invoking a prompt-capable fallback.
ASR model not found? Run nab models fetch fluidaudio to download the model (~542 MB). The model directory is ~/.nab/models/. Use nab models list to see what's installed.
Fetch returning HTML instead of markdown? Some sites block automated access. Try nab fetch URL --cookies brave to use your browser session, or nab fetch URL --1password for sites that need login.
Fetch returning thin content from a JavaScript app? Default nab fetch stays local-first and HTTP-only. For pages that need DOM execution, configure an external CDP endpoint with NAB_BROWSER_CDP_WS or --browser-cdp-url, then run nab browser URL or nab fetch URL --render. Remote browser providers may receive the URL and rendered page content; local browser cookies are not automatically available to remote browsers.
YARA-X guard redacted a fetch? nab fetch and MCP fetch scan returned bodies by default before saving or returning content. NAB_YARA_ACTION=refuse blocks instead of redacting. NAB_YARA_BYPASS=1 is an audited emergency opt-out.
"too many open files" on watch? Increase your ulimit: ulimit -n 4096. The default macOS limit (256) is too low for many concurrent watches.
nab is part of a suite of MCP tools:
Tool | Description |
Universal MCP gateway — compact 12-15 tool surface replaces 100+ registrations | |
AI travel agent — 36 MCP tools for flights, hotels, ground transport | |
Web content extraction — fetch any URL with cookies + anti-bot bypass | |
macOS GUI automation — 34 MCP tools via Accessibility API |
nab is dual-licensed as of v0.9.0:
Scope | License | File |
Core fetch / analyze / watch / MCP server / public web fetching | MIT | |
Designated Enterprise Edition modules (authenticated reach + anti-bot) | PolyForm Noncommercial 1.0.0 |
EE-designated paths (every file carries // SPDX-License-Identifier: PolyForm-Noncommercial-1.0.0):
src/auth/ — 1Password, WebAuthn, and browser-cookie injection (premium authenticated reach)
src/fingerprint/ — browser fingerprint spoofing (anti-bot evasion)
src/waf/ — WAF challenge handling
src/site/ — per-site provider integrations (proprietary domain knowledge)
src/security/ — Secure Ingestion guard for stripping machine-targeted HTML directives and hidden metadata
crates/nab-yara-engine/ — fetch-time YARA-X signature guard for prompt injection, exfiltration, secrets, and obfuscation
What this means in practice:
Free for noncommercial use, modification, redistribution.
Commercial use of EE modules requires a separate commercial license.
Companies can buy a standard commercial-use license via GitHub Sponsors at EUR 500/month per named project.
See COMMERCIAL.md for business use, forks, wrappers, shared services, and managed-service deployments.
All releases prior to v0.9.0 remain entirely MIT and stay MIT forever.
Look up credentials in 1Password for a URL.
Searches 1Password for credentials matching the URL/domain. Returns credential info (username, TOTP availability) without exposing password.
Returns: Credential info if found.
| Name | Required | Description | Default |
|---|---|---|---|
| url | Yes |
| Name | Required | Description |
|---|---|---|
| domain | Yes | The queried domain |
| has_totp | Yes | Whether a TOTP credential is stored |
| username | No | Account username if found |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
The description adds useful behavioral context beyond the readOnlyHint annotation: it explains that passwords are not exposed and that credential info is returned if found. This helps set expectations without redundancy.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is three sentences: first states purpose, second explains behavior, third indicates return value. It is front-loaded, concise, and contains no filler.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's simplicity (one required parameter, readOnlyHint annotation, and existence of an output schema), the description fully covers purpose, behavior, and return value. No gaps.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
With 0% schema description coverage, the description compensates by explaining that the url parameter should be a URL or domain for credential lookup. This adds semantic meaning beyond the raw schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the verb 'look up' and the resource 'credentials in 1Password' for a URL. It specifies the returned items (username, TOTP availability) and notes no password exposure. This distinguishes the tool from siblings like login or fetch.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description implies use for retrieving credentials for a URL. However, it does not explicitly state when to use this tool versus alternatives like login or fetch, nor does it provide exclusions.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Benchmark fetching URLs with timing statistics.
Measures min/avg/max response times over multiple iterations.
Returns: Benchmark results with timing statistics.
| Name | Required | Description | Default |
|---|---|---|---|
| urls | Yes | ||
| iterations | Yes |
| Name | Required | Description |
|---|---|---|
| results | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Annotations indicate readOnly (no mutation) and openWorld (external dependencies). The description adds context about measuring min/avg/max response times and returning results. However, it does not disclose network behavior, potential timeouts, or data volume implications, but annotations reduce the burden.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is three short sentences, front-loading the core purpose. It avoids unnecessary detail, but the first and last sentences are somewhat redundant. Still, it is efficiently structured for quick understanding.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given two required parameters with no schema descriptions and a list of similar sibling tools, the description lacks detail on parameter formats and selection guidance. While it has an output schema, the description does not fully leverage it to explain the return structure. The tool's interface is not fully clarified.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema coverage is 0%; parameters have no descriptions. The description mentions 'URLs' and 'iterations' only broadly, without specifying format, constraints, or defaults. This is insufficient to guide correct use given the lack of schema details.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool's function: benchmarking URL fetching with timing statistics. It distinguishes from siblings like 'fetch' and 'fetch_batch' by specifying that this tool measures performance rather than just retrieving content. The action and resource are specific.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance is provided on when to use this tool versus alternatives. While 'benchmark' implies performance testing, the description does not compare it to 'fetch', 'fetch_batch', or other siblings, nor does it state prerequisites or exclusions.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Fetch a URL and convert to clean markdown for LLM consumption.
Content conversion (automatic by Content-Type):
HTML → clean markdown (boilerplate removed, links preserved)
PDF → markdown with headings and table detection (requires pdf feature)
JSON/plain text → passthrough
SPA data auto-extracted (NEXT_DATA, NUXT, APOLLO_STATE, etc.)
Network features:
HTTP/2 multiplexing, HTTP/3 (QUIC) with 0-RTT
TLS 1.3, Brotli/Zstd/Gzip decompression
Realistic browser fingerprints (Chrome/Firefox/Safari)
Browser cookie injection (Brave/Chrome/Firefox/Safari)
Diff mode (diff: true):
Compares current content against the previous snapshot for this URL
Returns only the changed sections (token-efficient for monitoring tasks)
First fetch caches the page; subsequent fetches return semantic diffs
Unchanged content returns a 5-token confirmation instead of full body
Focus mode (focus: query):
Keeps only sections relevant to the query (BM25 scoring)
Replaces dropped sections with '[N sections omitted]' markers
Diff markers are always preserved regardless of relevance
Token budget (max_tokens: N):
Structure-aware truncation preserving headings, code, and tables
Priority: title > code/tables > headings (30% cap) > body > blockquotes
Returns: Markdown-converted body with timing info (or diff when diff: true).
| Name | Required | Description | Default |
|---|---|---|---|
| url | Yes | ||
| body | Yes | ||
| diff | Yes | When true, return only changed content vs the previous snapshot. On first fetch the page is cached and full content is returned. On subsequent fetches only the semantic diff is returned, saving tokens for monitoring or change-detection workflows. | |
| focus | No | Natural-language query to focus extraction on relevant sections. When set, uses BM25 scoring to keep only the sections most relevant to the query, replacing omitted sections with count markers. Dramatically reduces token count for large documents when you know what you're looking for. | |
| cookies | No | ||
| headers | Yes | ||
| session | No | Named session for cookie persistence across calls. When set, nab uses an isolated per-session cookie jar so that `Set-Cookie` response headers from one call are automatically included on the next call with the same session name. Use this to maintain authenticated state across multiple `fetch` calls after a `login`. Session names: 1-64 chars, alphanumeric + hyphens + underscores. Sessions are created implicitly on first use and live for the process lifetime. Absent = stateless global client (no change). | |
| max_tokens | No | Maximum token budget for the returned content. When set, performs structure-aware truncation that preserves headings, code blocks, and tables before trimming body text. Uses priority scoring: title/summary first, then code/tables, then headings (capped at 30% of budget), then body text. |
| Name | Required | Description |
|---|---|---|
| url | Yes | The fetched URL |
| status | Yes | HTTP status code |
| content | Yes | Markdown-converted body content |
| has_diff | Yes | True when diff mode was requested and content changed since last snapshot |
| timing_ms | Yes | Round-trip time in milliseconds |
| content_type | No | Response Content-Type header |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Annotations (readOnlyHint: true) are consistent with read operation. Description adds extensive behavioral context: automatic content conversion per Content-Type, network features, diff mode caching, token budget truncation. No contradictions.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Well-structured with sections for content conversion, network features, modes. Every sentence adds value; no redundancy. Appropriate length given tool complexity.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Covers all major aspects: input, modes, return values (with output schema hinted). Handles complexity of 8 params and varied behaviors. Complete for an information retrieval tool.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema coverage is 50%, but description compensates by explaining all parameters in detail: diff caching, focus BM25 scoring, max_tokens priority, session persistence, and implied url/headers/body behavior. Adds meaning beyond schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
Description states 'Fetch a URL and convert to clean markdown for LLM consumption.' It clearly identifies the verb (fetch) and resource (URL), and distinguishes from siblings like fetch_batch and submit.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Provides implicit guidance via sibling tools (fetch_batch for multiple URLs, login for auth). Describes when to use diff and focus modes. Lacks explicit 'when not to use' but sufficient for most agents.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Fetch multiple URLs in parallel with HTTP/2 multiplexing.
Uses connection pooling and multiplexing for maximum efficiency. All URLs are fetched concurrently.
Returns: Results for each URL with timing.
| Name | Required | Description | Default |
|---|---|---|---|
| urls | Yes |
| Name | Required | Description |
|---|---|---|
| results | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
The description adds behavioral context beyond the readOnlyHint annotation, detailing concurrency, HTTP/2 multiplexing, connection pooling, and timing in results. No contradictions with annotations.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is concise with three sentences front-loading the main action and key details. Slightly longer than necessary but efficient overall.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the simple input schema and existence of an output schema, the description covers the basic purpose and concurrent behavior but lacks details on limits, error handling, or authentication, leaving some gaps for a complete understanding.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
With 0% schema description coverage, the description does not add any parameter-specific guidance (e.g., max URLs, format) beyond what the schema already provides, leaving the agent with minimal additional context.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states it fetches multiple URLs in parallel with HTTP/2 multiplexing, distinguishing it from the sibling 'fetch' tool which likely handles single URLs.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description implies usage for batch fetching but does not explicitly specify when to use this tool over alternatives (e.g., 'fetch' for single URLs) or provide any exclusions or prerequisites.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Generate realistic browser fingerprints.
Creates browser profiles for Chrome, Firefox, or Safari. Includes User-Agent, Sec-CH-UA headers, Accept-Language, platform info.
Returns: Generated fingerprint profiles.
| Name | Required | Description | Default |
|---|---|---|---|
| count | Yes | ||
| browser | No |
| Name | Required | Description |
|---|---|---|
| profiles | Yes |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Annotations already declare readOnlyHint=true and destructiveHint=false, so the description adds context about output contents but no additional behavioral traits like rate limits or side effects. The description aligns with annotations.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Very concise: three sentences front-loading purpose, listing included features, and describing returns. No wasted words.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the simple fingerprint generation task, output schema exists for return format, and annotations cover safety, the description provides enough context. It could mention any networking dependencies, but overall sufficient.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
Schema has 0% description coverage. Description mentions browser types ('Chrome, Firefox, Safari') hinting at the browser parameter but does not link it explicitly. The count parameter is not explained, and return wording implies multiple profiles but is vague.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states the tool generates realistic browser fingerprints, listing specific browsers and included headers. The purpose is unambiguous and distinguishes it from sibling tools like fetch or login.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
No guidance on when to use this tool over alternatives. The description only defines what it does, without mentioning context, prerequisites, or exclusions.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Auto-login to a website using 1Password credentials.
Detects login form, retrieves credentials from 1Password, fills and submits, handles MFA/2FA with TOTP. Returns the authenticated page content.
Requires: 1Password CLI (op) installed and authenticated.
Returns: Final page content after login (markdown-converted).
| Name | Required | Description | Default |
|---|---|---|---|
| url | Yes | ||
| cookies | No | ||
| session | No | Named session to store authenticated cookies in after login. When set, the login flow uses the session's isolated cookie jar. All `Set-Cookie` headers from the login flow are automatically stored in the jar and will be sent on subsequent `fetch` or `submit` calls that use the same session name — no manual cookie extraction needed. Session names: 1-64 chars, alphanumeric + hyphens + underscores. |
| Name | Required | Description |
|---|---|---|
| url | Yes | The login URL |
| status | Yes | Login result status (success/cancelled) |
| content | No | Markdown-converted page content after login |
| final_url | No | URL after login redirects |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
The description details the behavioral flow: detecting login form, retrieving credentials, filling and submitting, handling MFA/2FA, and returning page content. This goes beyond the annotations (readOnlyHint=false, openWorldHint=true) by explaining the side effects (credential retrieval, cookie storage via session parameter). However, it does not mention potential failure modes or fallback behavior.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is concise and well-structured, with the main purpose front-loaded. It uses bullet points for requirements and return value, making it easy to scan. Every sentence adds value without extraneous information.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (login with MFA, credential management) and the presence of an output schema, the description adequately covers the process, requirements, and return type. It could be more complete by addressing error handling or the scope of login form detection, but it provides sufficient context for an agent to use the tool effectively.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
With schema description coverage at only 33% (only session is described in the schema), the description fails to compensate for the missing parameter details. The url parameter is implied but not explicitly described, and the cookies parameter is not mentioned at all. This leaves ambiguity for the agent about the format and purpose of these parameters.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description clearly states 'Auto-login to a website using 1Password credentials,' specifying the verb (auto-login), resource (website), and scope (using 1Password). This distinguishes it from sibling tools like fetch (simple retrieval) and submit (form submission), as it handles the entire authentication flow including credential retrieval and MFA.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
The description provides clear usage context by outlining the prerequisites (1Password CLI installed and authenticated) and the process (detect form, fill, submit, handle MFA). It implicitly differentiates from alternatives by focusing on login with 1Password, though it could explicitly state when to use this tool over fetch or auth_lookup.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Submit a web form with smart field extraction.
Fetches a page, parses all forms, extracts hidden fields and CSRF tokens, merges user-provided fields, and submits via POST.
Use for: login forms, search forms, API interactions behind HTML pages.
Returns: Response body (markdown-converted) after form submission.
| Name | Required | Description | Default |
|---|---|---|---|
| url | Yes | ||
| fields | Yes | ||
| cookies | No | ||
| session | No | Named session for cookie persistence. When set, the form page fetch and the POST submission both use the session's cookie jar, preserving authentication state. See `fetch` `session` for full documentation. | |
| csrf_selector | No |
| Name | Required | Description |
|---|---|---|
| url | Yes | The submitted URL |
| status | Yes | HTTP status code |
| content | Yes | Markdown-converted response body |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
The description openly discloses the full workflow (fetching, parsing, extraction, merging, POST submission) and the return format (markdown-converted response body). Annotations already indicate non-read-only (readOnlyHint=false) and open-world behavior, so the description adds detail on what modifications occur (POST submission) without contradicting annotations.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
The description is concise (4-5 sentences), front-loads the core purpose, and uses a bullet-list style for uses and returns. Every sentence adds value without redundancy or filler.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given the tool's complexity (multi-step form handling, state mutation), the description covers purpose, behavior, use cases, and return format. The presence of an output schema reduces the need to detail return structure. It could mention potential errors or prerequisites (e.g., page must be accessible), but overall is fairly complete.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
With only 20% schema description coverage, the narrative must compensate. It explains that 'fields' holds user-provided fields and that 'csrf_selector' is used for CSRF token extraction, but does not detail 'cookies', 'session', or the exact syntax of fields array. The description provides moderate additional meaning beyond the sparse schema.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
The description starts with a specific verb-resource pair ('Submit a web form with smart field extraction'), clearly distinguishing it from sibling tools like fetch (fetching only) or login (authentication-specific). It details the multi-step process (fetch, parse, extract, merge, submit), making the tool's exact purpose immediately clear.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Use cases are explicitly listed ('login forms, search forms, API interactions behind HTML pages'), providing clear context. However, it does not advise when not to use this tool (e.g., when a simpler fetch or dedicated login tool would suffice), nor does it mention potential overlap with the 'login' sibling.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Run validation tests against real websites.
Tests: HTTP/2, HTTP/3, compression, fingerprinting, TLS 1.3, 1Password.
Returns: Validation results with timing.
| Name | Required | Description | Default |
|---|---|---|---|
No parameters | |||
| Name | Required | Description |
|---|---|---|
| duration_s | Yes | Total validation duration in seconds |
Does the description disclose side effects, auth requirements, rate limits, or destructive behavior?
Annotations declare readOnlyHint true, so description adds value by detailing tests and return format. No contradictions, but no further disclosure beyond annotations.
Agents need to know what a tool does to the world before calling it. Descriptions should go beyond structured annotations to explain consequences.
Is the description appropriately sized, front-loaded, and free of redundancy?
Three concise, front-loaded sentences: action, list, return. No wasted words.
Shorter descriptions cost fewer tokens and are easier for agents to parse. Every sentence should earn its place.
Given the tool's complexity, does the description cover enough for an agent to succeed on first attempt?
Given no params, good annotations, and existing output schema, description covers the tool's purpose and outputs fully.
Complex tools with many parameters or behaviors need more documentation. Simple tools need less. This dimension scales expectations accordingly.
Does the description clarify parameter syntax, constraints, interactions, or defaults beyond what the schema provides?
No parameters; baseline 4 applies as description need not compensate for missing param info.
Input schemas describe structure but not intent. Descriptions should explain non-obvious parameter relationships and valid value ranges.
Does the description clearly state what the tool does and how it differs from similar tools?
States it runs validation tests against real websites, listing specific tests (HTTP/2, HTTP/3, compression, fingerprinting, TLS 1.3, 1Password), distinguishing it from siblings like fetch or fingerprint.
Agents choose between tools based on descriptions. A clear purpose with a specific verb and resource helps agents select the right tool.
Does the description explain when to use this tool, when not to, or what alternatives exist?
Implies usage for running listed validation checks, but no explicit when-to-use or when-not-to-use vs. siblings like benchmark (similar performance focus) or fingerprint.
Agents often have multiple tools that could apply. Explicit usage guidance like "use X instead of Y when Z" prevents misuse.
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
v0.1.0auth_lookupbenchmarkfetchfetch_batchfingerprintloginsubmitvalidateScored across 8 tools
Each tool has a clearly distinct purpose: auth_lookup for credential lookup, benchmark for timing, fetch for single URL conversion, fetch_batch for parallel fetching, fingerprint for browser profiles, login for automated authentication, submit for form submission, and validate for testing. No two tools serve the same function, and descriptions provide ample detail to differentiate.
Tool names use snake_case and are generally descriptive, but there is inconsistency between verb-based names (fetch, fetch_batch, submit, validate) and noun-based names (auth_lookup, benchmark, fingerprint, login). However, the naming is still predictable and readable, with fetch_batch clearly extending fetch.
With 8 tools, the server covers all core web interaction tasks without being overwhelming. The count is appropriate for the domain of web scraping, automation, and testing, and each tool adds clear value.
The tool set covers a wide range of web interactions: fetching, batch processing, form submission, authentication, benchmarking, and validation. Minor gaps exist, such as explicit session management or cookie manipulation, but the core workflow is well-served, and agents can accomplish most tasks without missing critical operations.
Read any web page as clean Markdown for AI agents: fetch, search, metadata, links. SSRF-safe.
Scrape, crawl, map & search the web. Open-source, self-hostable Rust crawler & search for AI agents.
Web scraping for AI agents. Converts URLs to clean, LLM-ready Markdown with anti-bot bypass.
MCP server (stdio): fetch web pages as clean readable markdown via the AgentForge API