@vorionsys/mcp-serverofficial
A
licenseA
qualityD
maintenanceMCP server for AI-agent governance using trust scoring, behavioral signals, and pre-flight action checks.
10
23 npm
1
Apache 2.0

The PromptSpeak MCP Server provides a pre-execution governance layer for AI agents, intercepting and validating tool calls before they execute through a 9-stage pipeline.
Frame Validation: Validate agent actions (frames) at structural, semantic, chain, or full levels — individually (ps_validate) or in batch (ps_validate_batch) — before execution
Governed Execution: Run tool calls through the full pipeline (ps_execute, ps_execute_batch) with circuit breaking, drift prediction, hold checks, and security scanning; supports dry-run preview
Human-in-the-Loop Approvals: Automatically hold risky operations for manual review; list, approve (with optional argument modifications), or reject pending holds via ps_hold_list, ps_hold_approve, ps_hold_reject
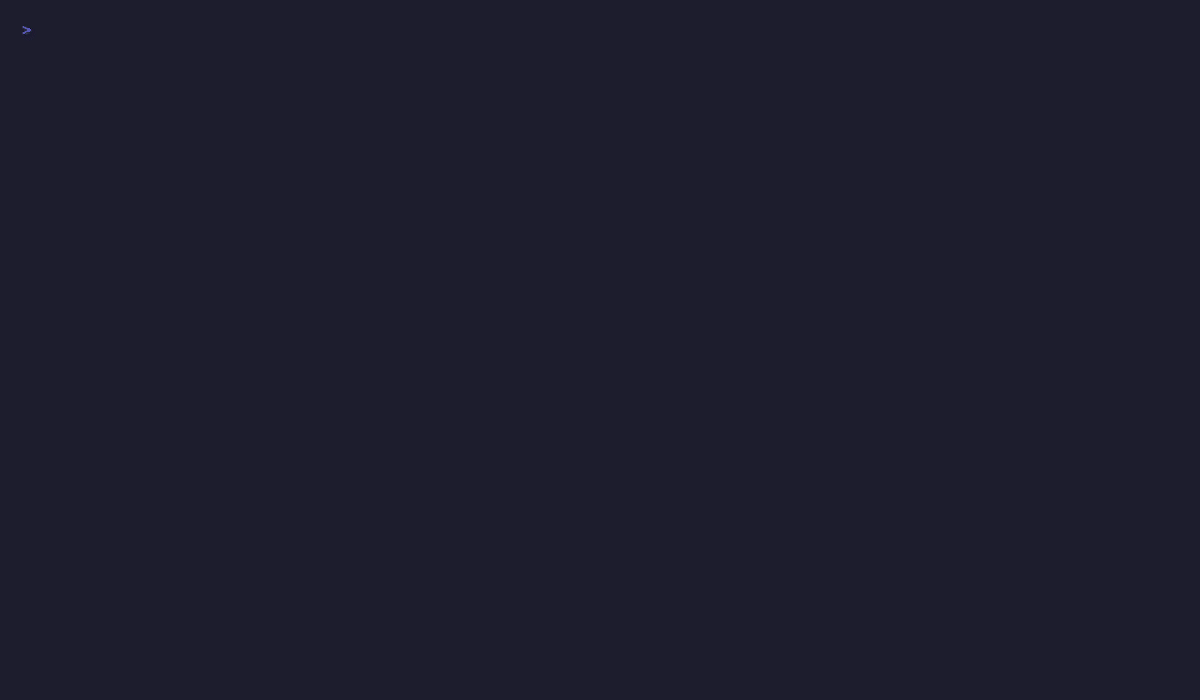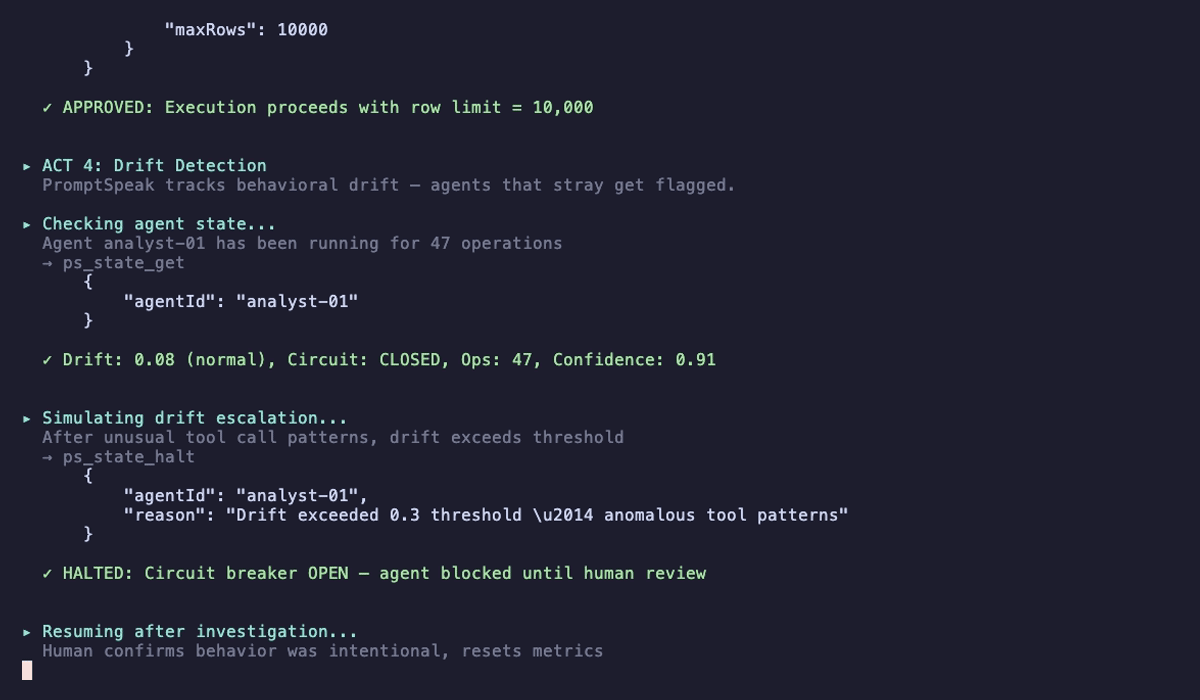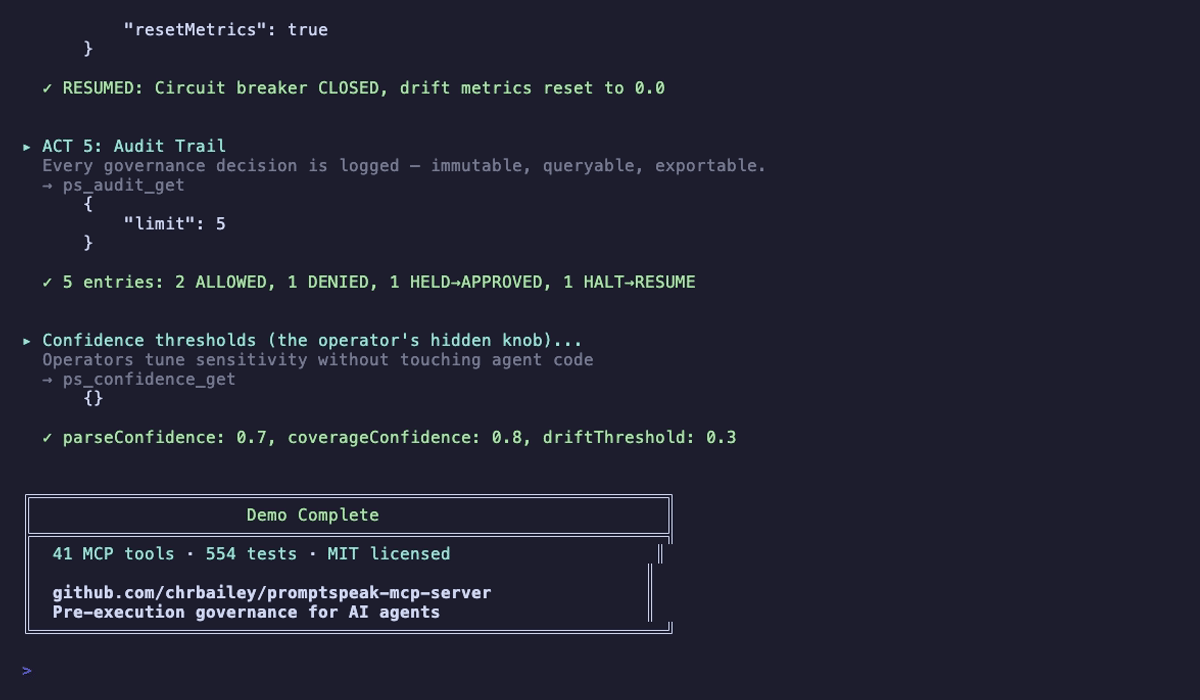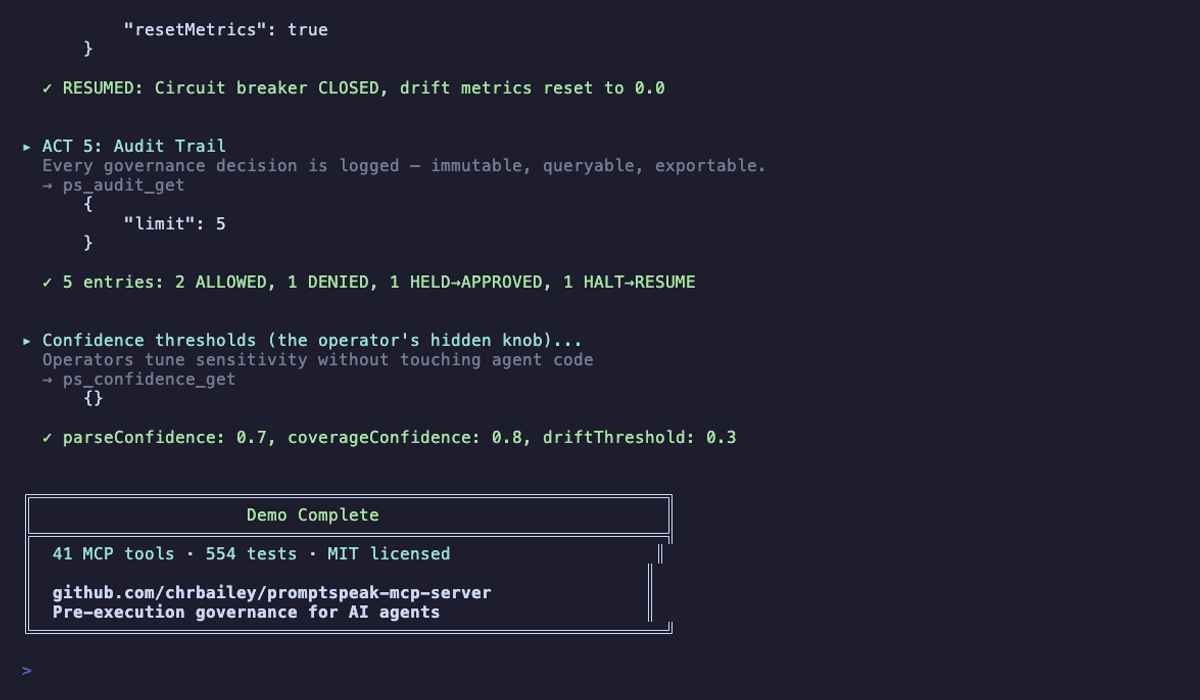
Agent Lifecycle & Drift Management: Halt, resume, reset, or recalibrate agents; monitor behavioral drift scores and history; automatically halt agents exceeding drift thresholds
Delegation Management: Create parent→child agent delegations with constrained permissions and inheritance rules; revoke or list active delegations
Security Scanning & Enforcement: Scan code for SQL injection, hardcoded secrets, insecure defaults, and more — with tiered enforcement (block on critical, hold on high, warn on medium, log on low)
Runtime Configuration: Set and activate policy overlays, tune confidence thresholds, and toggle pipeline feature flags at runtime
Symbol/Entity Registry: Create, read, update, delete, and bulk-import tracked entities (companies, people, events, tasks, etc.) with versioning, human verification workflows, and alternative explanation tracking
Audit Logging: Retrieve full audit trails of all tool calls attempted by agents, including blocked and allowed actions, with filtering
System Monitoring: View system-wide agent state, hold queue statistics, security pattern configuration, and performance metrics (latency, ops/sec)


Pre-execution governance for AI agents. Blocks dangerous tool calls before they execute.
AI agents call tools (file writes, API requests, shell commands) with no validation layer between intent and execution. A prompt injection, hallucinated argument, or drifting goal can trigger irreversible actions. PromptSpeak intercepts every MCP tool call, validates it against deterministic rules, and blocks or holds risky operations for human approval — in 0.1ms, before anything executes.
You run AI agents that call tools (MCP servers, function calling, tool use) and need a governance layer between the agent and the tools.
You need human-in-the-loop approval for high-risk operations (production deployments, financial transactions, legal filings).
You want to detect behavioral drift — an agent gradually shifting away from its assigned task.
You need an audit trail of every tool call an agent attempted, whether it was allowed or blocked.
You operate in a regulated domain (legal, financial, healthcare) where agent actions must be deterministically constrained.
Related MCP server: a2a-trustgate
Add to ~/.claude/settings.json (or project-level .claude/settings.json):
{
  "mcpServers": {
    "promptspeak": {
      "command": "npx",
      "args": ["promptspeak-mcp-server"]
    }
  }
}
Restart Claude Code. All 56 governance tools are immediately available.
Add to claude_desktop_config.json:
{
  "mcpServers": {
    "promptspeak": {
      "command": "npx",
      "args": ["promptspeak-mcp-server"]
    }
  }
}npm install promptspeak-mcp-servergit clone https://github.com/chrbailey/promptspeak-mcp-server.git
cd promptspeak-mcp-server
npm install && npm run build
npm startValidate that a PromptSpeak frame is structurally and semantically correct before using it. Frames encode governance constraints as symbol sequences — mode first, then domain, action, and entity.
// Tool call: ps_validate
{
  "name": "ps_validate",
  "arguments": {
    "frame": "⊕◊▶α",
    "validationLevel": "full"
  }
}
// Response
{
"valid": true,
"frame": "⊕◊▶α",
"parsedFrame": {
"mode": { "symbol": "⊕", "meaning": "strict" },
"domain": { "symbol": "◊", "meaning": "financial" },
"action": { "symbol": "▶", "meaning": "execute" },
"entity": { "symbol": "α", "meaning": "primary" }
},
"parseConfidence": 1.0,
"report": {
"valid": true,
"errors": [],
"warnings": [
{ "code": "ACTION_MISSING_DOMAIN", "message": "Consider adding domain context", "severity": "warning" }
]
},
"summary": { "errors": 0, "warnings": 1, "passed": 16 }
}Invalid frames return actionable suggestions:
// Tool call: validate a frame with conflicting modes
{
  "name": "ps_validate",
  "arguments": { "frame": "⊕⊖▶", "validationLevel": "semantic" }
}

// Response: blocked — strict + flexible modes conflict
{
  "valid": false,
  "summary": { "errors": 1, "warnings": 0, "passed": 10 },
  "suggestions": ["Remove either ⊕ (strict) or ⊖ (flexible) - cannot have both"]
}When an agent attempts a risky operation (high drift score, low confidence, security finding), the action is held for human review instead of executing. This is the full hold lifecycle: list, inspect, approve or reject.
Step 1: List pending holds
// Tool call: ps_hold_list
{
  "name": "ps_hold_list",
  "arguments": {}
}
// Response: one hold awaiting human review
{
"holds": [
{
"holdId": "hold_7k2m9x",
"agentId": "devops-agent",
"frame": "⊕◈▶α",
"tool": "deploy_to_production",
"severity": "high",
"reason": "drift_prediction",
"state": "pending",
"evidence": { "driftScore": 0.72, "predictedDrift": 0.85 }
}
],
"count": 1,
"expiredCount": 0
}Step 2: Approve with modifications (or reject)
// Tool call: ps_hold_approve — approve but downgrade to staging
{
  "name": "ps_hold_approve",
  "arguments": {
    "holdId": "hold_7k2m9x",
    "reason": "Reviewed — safe for staging, not production",
    "modifiedArgs": { "environment": "staging" }
  }
}
// Response
{
"success": true,
"decision": {
"holdId": "hold_7k2m9x",
"state": "approved",
"decidedBy": "human",
"reason": "Reviewed — safe for staging, not production"
},
"executionResult": { "success": true }
}To reject instead:
{
  "name": "ps_hold_reject",
  "arguments": {
    "holdId": "hold_7k2m9x",
    "reason": "Drift too high — recalibrate agent first",
    "haltAgent": true
  }
}
// Agent is halted (circuit breaker tripped) and the operation is denied.Scan code content for security issues before an agent writes it to disk. Critical findings block execution; high-severity findings are held for human review.
// Tool call: ps_security_scan
{
  "name": "ps_security_scan",
  "arguments": {
    "content": "const query = `SELECT * FROM users WHERE id = ${userId}`;\nconst API_KEY = 'sk-1234567890abcdef1234567890abcdef';"
  }
}
// Response: two findings — one critical (blocked), one critical (blocked)
{
"findings": [
{
"patternId": "sql-injection",
"severity": "critical",
"match": "SELECT * FROM users WHERE id = ${userId}",
"line": 1,
"context": "const query = `SELECT * FROM users WHERE id = ${userId}`;",
"suggestion": "Use parameterized queries or prepared statements instead of template literals"
},
{
"patternId": "hardcoded-secret",
"severity": "critical",
"match": "API_KEY = 'sk-1234567890abcdef1234567890abcdef'",
"line": 2,
"context": "const API_KEY = 'sk-1234567890abcdef1234567890abcdef';",
"suggestion": "Move secrets to environment variables or a secrets manager"
}
],
"scannedAt": "2026-03-19T12:00:00.000Z",
"contentLength": 98,
"patternsChecked": 10,
"enforcement": {
"blocked": [
{ "patternId": "sql-injection", "severity": "critical" },
{ "patternId": "hardcoded-secret", "severity": "critical" }
],
"held": [],
"warned": [],
"logged": []
}
}Use ps_security_gate instead of ps_security_scan to enforce the policy — it blocks on critical, holds high-severity for human review, and warns on medium:
// Tool call: ps_security_gate — scan AND enforce
{
  "name": "ps_security_gate",
  "arguments": {
    "content": "app.use(cors());\napp.listen(0.0.0.0, 3000);",
    "action": "write_file"
  }
}

// Response: held for review (insecure defaults = high severity)
{
  "decision": "held",
  "reason": "Security: 1 high-severity finding(s) held for review — insecure-defaults",
  "scan": { "findings": [{ "patternId": "insecure-defaults", "severity": "high", "line": 1 }] }
}Every tool call passes through this pipeline. If any stage fails, execution is blocked.
Agent calls tool
  │
  ├─ 1. Circuit Breaker ──── Halted agents blocked instantly (no further checks)
  ├─ 2. Frame Validation ─── Structural, semantic, and chain rule checks
  ├─ 3. Drift Prediction ─── Pre-flight behavioral anomaly detection
  ├─ 4. Hold Check ────────── Risky operations held for human approval
  ├─ 5. Interceptor ───────── Final permission gate (confidence thresholds)
  ├─ 6. Security Scan ─────── Scans write actions for vulnerabilities (see below)
  ├─ 7. Tool Execution ────── Only reached if all 6 pre-checks pass
  ├─ 8. Post-Audit ────────── Confirms behavior matched prediction
  └─ 9. Immediate Action ──── Halts agent if critical drift detected post-execution
Stages 1-6 are pre-execution — the tool never runs if any check fails. Stages 8-9 are post-execution — they detect drift and can halt the agent for future calls.
When an agent writes code (write_file, edit_file, create_file, patch_file), the content is scanned against 10 detection patterns before execution. Severity determines enforcement:
Severity | Enforcement | What it catches |
CRITICAL | Blocked — execution denied | SQL injection via template literals, hardcoded API keys/passwords/tokens |
HIGH | Held — queued for human review | Security-related TODOs, logging sensitive data, insecure defaults ( |
MEDIUM | Warned — logged, execution continues | Empty catch blocks, hedging comments ("probably works"), disabled tests |
LOW | Logged — no enforcement |
|
All claims below are backed by passing tests (104 tests across 5 test files):
Pattern detection works. Each of the 10 patterns is tested for true positives AND false positives. Example: api_key = "sk-1234567890abcdef" is caught; API_KEY = process.env.API_KEY is not. SQL injection catches \SELECT * FROM users WHERE id = ${id}` but not parameterized queries (db.query("SELECT * FROM users WHERE id = ?", [id])`).
Severity enforcement works. Critical findings block execution. High findings hold for review. Medium findings warn but allow. Tested end-to-end through the interceptor pipeline.
Only write actions are scanned. read_file and other non-write actions pass through without scanning, even if their arguments contain vulnerable code. Tested.
Runtime configuration works. Patterns can be enabled/disabled and severity can be changed at runtime via ps_security_config. A disabled pattern stops firing immediately. Changing a pattern from medium to critical makes it block instead of warn. Tested end-to-end.
Performance is fine. 100-line file scans complete in under 10ms. Tested.
Multiple findings in one file work. A file with 6 different vulnerability types correctly classifies each into the right severity bucket. Tested.
No hold queue integration for HIGH findings. FIXED. HIGH-severity security findings now create real holds in HoldManager via security_finding HoldReason. They appear in ps_hold_list and can be approved/rejected through the normal hold flow.
No auto-scan on ps_execute. The security scan only triggers in the interceptor's intercept() method for direct tool calls. If an agent uses ps_execute (the governed execution path), the scan runs only if the inner tool is a write action AND the content is passed as a top-level arg. Nested argument structures may bypass scanning. Why: ps_execute wraps tool calls in its own argument schema; the scanner checks proposedArgs.content, not deeply nested fields.
No file-path-based scanning. The scanner only examines content passed as arguments. It cannot scan files already on disk — it doesn't read from the filesystem. Why: The scanner is a pure function that takes a string. Adding filesystem access would change the security model.
Patterns are regex-based, not AST-aware. The patterns use regular expressions, which means they can't understand code structure. A hardcoded secret inside a test fixture or a SQL injection in a comment will still trigger. False positive rates range from 25-70% depending on the pattern (documented per-pattern). Why: AST parsing would add dependencies and complexity. Regex is fast and good enough for a governance layer that holds for human review rather than silently blocking.
Partial persistence. Holds and circuit breaker state now persist to SQLite (data/governance.db) and survive server restarts. However, pattern configuration changes (enable/disable, severity changes via ps_security_config) are still in-memory only and reset on restart. Why: Pattern config is lightweight and rarely changed; full config persistence would need a separate config store.
Tool | When to call it | What it does |
| Before executing any agent action | Validate a frame against all rules without executing |
| When checking multiple actions at once | Batch validation for efficiency |
| When an agent wants to perform a tool call | Full pipeline: validate → hold check → execute → audit |
| When previewing what would happen | Run full pipeline without executing the tool |
Tool | When to call it | What it does |
| When reviewing pending agent actions | List all operations awaiting human approval |
| When a held operation should proceed | Approve with optional modified arguments |
| When a held operation should be denied | Reject with reason |
| When tuning which operations require approval | Configure hold triggers and thresholds |
| When monitoring hold queue health | Hold queue statistics |
Tool | When to call it | What it does |
| When checking what an agent is doing | Get agent's active frame and last action |
| When monitoring overall system health | System-wide statistics |
| When an agent must be stopped immediately | Trip circuit breaker — blocks all future calls |
| When a halted agent should be allowed to continue | Reset circuit breaker |
| When clearing agent state | Full state reset |
| When investigating behavioral changes | Drift detection alert history |
Tool | When to call it | What it does |
| When an agent spawns a sub-agent | Create parent→child delegation with constrained permissions |
| When revoking a sub-agent's authority | Remove delegation |
| When auditing delegation chains | List active delegations |
Tool | When to call it | What it does |
| When changing governance rules at runtime | Set configuration key-value pairs |
| When reading current configuration | Get current config |
| When switching policy profiles | Activate a named configuration |
| When backing up configuration | Export full config as JSON |
| When restoring configuration | Import config from JSON |
| When tuning validation strictness | Set confidence thresholds |
| When checking current thresholds | Get current thresholds |
| When reconfiguring multiple thresholds | Batch threshold update |
| When toggling pipeline stages | Enable/disable specific checks |
| When checking which stages are active | Get feature flags |
Tool | When to call it | What it does |
| When registering a new entity (company, person, system) | Create symbol with type, metadata, and tags |
| When looking up an entity | Retrieve by ID |
| When entity data changes | Update metadata or tags |
| When browsing entities by type | List with optional type filter |
| When removing an entity | Delete by ID |
| When bulk-loading entities | Batch import |
| When monitoring registry health | Registry statistics |
| When displaying an entity | Format symbol for display |
| When confirming entity data is current | Mark symbol as verified |
| When auditing stale data | List symbols needing verification |
| When an entity has aliases | Add alternative identifier |
Tool | When to call it | What it does |
| When checking code for vulnerabilities | Scan content, return findings by severity |
| When enforcing security policy on writes | Scan + enforce: block/hold/warn/allow |
| When tuning detection patterns | List, enable, disable, change severity of patterns |
Tool | When to call it | What it does |
| When reviewing what happened | Full audit trail with filters |
src/
├── gatekeeper/       # 8-stage validation pipeline (core enforcement)
│   ├── index.ts      #   Pipeline orchestrator + agent eviction policy
│   ├── validator.ts  #   Frame structural/semantic/chain validation
│   ├── interceptor.ts#   Permission gate with confidence thresholds
│   ├── hold-manager.ts#  Human-in-the-loop hold queue
│   ├── resolver.ts   #   Frame resolution with operator overrides
│   └── coverage.ts   #   Coverage confidence calculator
├── drift/            # Behavioral drift detection
│   ├── circuit-breaker.ts  # Per-agent halt/resume
│   ├── baseline.ts         # Behavioral baseline comparison
│   ├── tripwire.ts         # Anomaly tripwires
│   └── monitor.ts          # Continuous monitoring
├── security/         # Security vulnerability scanning
│   ├── patterns.ts   #   10 detection patterns (regex-based)
│   └── scanner.ts    #   Scanner engine + severity classification
├── persistence/      # SQLite governance persistence
│   └── database.ts   #   Holds, decisions, circuit breakers (WAL mode)
├── symbols/          # SQLite-backed entity registry (11 CRUD tools)
├── policies/         # Policy file loader + overlay system
├── operator/         # Operator configuration
├── tools/            # MCP tool implementations
│   ├── registry.ts   #   29 core tools
│   ├── ps_hold.ts    #   5 hold tools
│   └── ps_security.ts#   3 security tools
├── handlers/         # Tool dispatch + metadata registry
├── core/             # Logging, errors, result patterns
└── server.ts # MCP server entry point (stdio transport)PromptSpeak adds governance to every tool call with sub-millisecond overhead. Benchmarked on Apple M2 Pro, Node.js 22, Vitest 4.0:
Percentile | Latency |
Average | 0.164ms |
P95 | 0.368ms |
P99 | 1.183ms |
Full execution path P95 | 0.074ms |
Operation | Rate |
Circuit breaker checks (1000 concurrent) | 6,173 ops/sec |
Hold creation | 55,556 holds/sec |
Hold approval/rejection | 200,000+/sec |
Mixed operations (halt + hold + allow) | 6,818 ops/sec |
Test | Result |
1000 concurrent blocked executions | 162ms total, all blocked correctly |
100 rapid halt/resume cycles | 100% correct state transitions |
500 agents with mixed states | 250 blocked, 250 allowed — zero misclassification |
Memory under sustained load (1000 ops) | Negative delta (-11.76 MB, GC reclaimed) |
Metric | Value |
Test count | 829 tests across 33 files |
Test duration | 1.11s total |
Categories | Unit, integration, stress, security, grammar |
Node.js >= 20.0.0
TypeScript 5.3+ (build from source)
No external services required — SQLite for symbols and governance persistence
deeptrend — Structured AI trend feed for autonomous agents. Curated from 14+ sources, synthesized via LLM Counsel, published every 6h as JSON Feed, RSS, and llms.txt. Designed as a data source for agent monitoring pipelines.
https://promptspeak.admin-as-a-service.com/privacy
PromptSpeak does not collect personal data, has no telemetry, and stores all governance data locally in SQLite. See the full policy at the link above.
https://promptspeak.admin-as-a-service.com/dpa
Standard data processing terms for platform integrations (e.g., Anthropic Connectors). PromptSpeak acts as a data processor; no sub-processors, no external data transmission.
MIT
Get audit log entries.
Inputs: since, action, limit.
Set multiple confidence thresholds at once.
Inputs: thresholds (required).
Get all confidence thresholds.
Inputs: no named parameters.
Set a confidence threshold. This is the hidden knob for operators.
Inputs: threshold (required), value (required).
Activate a registered policy overlay.
Inputs: overlayId (required).
Export current configuration for backup.
Inputs: no named parameters.
Get current configuration including active overlay and thresholds.
Inputs: no named parameters.
Import configuration from backup.
Inputs: data (required), expectedChecksum.
Register a new policy overlay.
Inputs: overlayId (required), overlay (required).
Delegate a task from parent agent to child agent. Enforces inheritance rules and constraint propagation.
Inputs: parentAgentId (required), childAgentId (required), parentFrame (required), childFrame (required), +2 more.
List delegations for an agent.
Inputs: agentId (required), role, status.
Revoke an active delegation.
Inputs: delegationId (required), parentAgentId (required), reason.
Execute an action under PromptSpeak frame governance. The gatekeeper validates and enforces constraints.
Inputs: agentId (required), frame (required), action (required), parentFrame.
Execute multiple actions under a single frame. Supports sequential or parallel execution with optional stop-on-failure.
Inputs: agentId (required), frame (required), actions (required), parentFrame, +2 more.
Check if an action would succeed without executing. Returns decision and coverage analysis.
Inputs: agentId (required), frame (required), action (required), parentFrame.
Get all feature flags.
Inputs: no named parameters.
Set a feature flag.
Inputs: flag (required), enabled (required).
Approve a held execution request. The operation will proceed with optional modifications.
Inputs: holdId (required), reason, modifiedFrame, modifiedArgs, +1 more.
Configure hold behavior and thresholds. Controls when operations are held for human review.
Inputs: action (required), config.
List all pending holds awaiting human approval. Returns holds for risky operations that were blocked pending review.
Inputs: agentId, includeExpired.
Reject a held execution request. The operation will not proceed.
Inputs: holdId (required), reason, haltAgent.
Get hold statistics and history.
Inputs: historyLimit.
Configure security detection patterns. List, enable, disable, or change severity of patterns.
Inputs: action (required), patternId, severity.
Scan code and enforce security policy. Blocks on critical findings, holds high-severity for review, warns on medium, logs low/info.
Inputs: content (required), action (required).
Scan code content for security vulnerabilities. Returns findings classified by severity (critical, high, medium, low, info).
Inputs: content (required), patterns.
Get drift history for an agent.
Inputs: agentId (required), since, limit.
Get current state of an agent including drift metrics and circuit breaker status.
Inputs: agentId (required).
Immediately halt an agent by opening its circuit breaker.
Inputs: agentId (required), reason (required).
Recalibrate agent drift baseline. Optionally provide a new baseline configuration.
Inputs: agentId (required), newBaseline.
Reset agent state. Can reset circuit breaker, drift metrics, and/or baseline.
Inputs: agentId (required), reason (required), resetCircuitBreaker, resetDriftMetrics, +1 more.
Resume a halted agent.
Inputs: agentId (required), reason (required), resetMetrics.
Get overall system state including all agents, operations, and drift alerts.
Inputs: no named parameters.
Add an alternative explanation to a symbol's findings.
CRITICAL for preventing false positives: When a pattern-based finding could have multiple explanations, document them here. Adding high-likelihood alternatives automatically reduces confidence in the original claim.
Examples:
"9 identical payments" → Alternative: "Monthly insurance premium financing"
"Large round numbers" → Alternative: "Negotiated contract amounts"
"Vendor with single customer" → Alternative: "Subsidiary company"
Inputs: symbolId (required), alternative (required), likelihood (required), added_by (required), +1 more.
Create a new directive symbol in the registry.
Symbol IDs follow the pattern:
Public companies: Ξ.{TICKER}.{PERIOD} (e.g., Ξ.NVDA.Q3FY25)
People: Ξ.I.{NAME}.{CONTEXT} (e.g., Ξ.I.JENSEN_HUANG.BIO)
Events: Ξ.E.{TYPE}.{ID} (e.g., Ξ.E.EARNINGS.NVDA.20241120)
Sectors: Ξ.S.{SECTOR}.{CONTEXT} (e.g., Ξ.S.SEMICONDUCTORS.2024)
Tasks: Ξ.T.{PROJECT}.{ID} (e.g., Ξ.T.PORTFOLIO_REVIEW.001)
Knowledge: Ξ.K.{DOMAIN}.{TOPIC} (e.g., Ξ.K.CHEMISTRY.WATER)
Queries: Ξ.Q.{DATASET}.{ID} (e.g., Ξ.Q.DEEPSEARCHQA.001)
Inputs: symbolId (required), who (required), what (required), why (required), +12 more.
Delete a symbol from the registry.
Inputs: symbolId (required), reason (required).
Format a symbol for inclusion in a prompt. Returns LLM-ready text.
Inputs: symbolId (required), format.
Retrieve a directive symbol by ID. Returns the full symbol with all grounding context.
Inputs: symbolId (required), version, include_changelog.
Bulk import symbols from external data (HuggingFace, JSON, etc.).
Inputs: source (required), data (required), category (required), id_prefix (required), +2 more.
List symbols with optional filtering.
Inputs: category, tags, created_after, created_before, +3 more.
List symbols that require human review.
Returns symbols flagged for review due to:
Accusatory claims without sufficient evidence
Missing alternative explanations
High-stakes claims (fraud, violations, diagnoses)
Low confidence scores
Use this to find claims that need human validation before action.
Inputs: claim_type, min_confidence, max_confidence, limit, +1 more.
Get statistics about the symbol registry.
Inputs: no named parameters.
Update an existing symbol. Creates a new version with updated hash.
Inputs: symbolId (required), changes (required), change_description (required), changed_by.
Record human verification of a symbol claim.
Use this tool to upgrade or dispute claims based on human review:
VERIFIED: Human expert has confirmed the claim is accurate
CORROBORATED: Additional evidence supports the claim
DISPUTED: Human reviewer found the claim to be incorrect or misleading
Important: Accusatory claims (fraud, violations) should be DISPUTED if they lack evidence or have plausible alternative explanations.
Inputs: symbolId (required), new_status (required), reviewer (required), new_confidence, +2 more.
Validate a PromptSpeak frame. Returns validation report with errors, warnings, and suggestions.
Inputs: frame (required), parentFrame, validationLevel, strict.
Validate multiple frames at once. Useful for validating delegation chains.
Inputs: frames (required), validationLevel, strict, stopOnFirstError.
Recent tool additions, removals, and schema changes observed during successful MCP inspections.
Loading tool schema changelog…
Scored across 45 tools
The tools have clear purposes within their categories, such as 'ps_confidence_get' vs. 'ps_confidence_set', but there is overlap in some areas. For example, 'ps_security_gate' and 'ps_security_scan' both involve security scanning, and 'ps_execute' and 'ps_execute_batch' share similar execution functions, which could cause confusion for an agent. However, descriptions help differentiate them to some extent.
All tool names follow a consistent 'ps_' prefix with a verb_noun pattern, such as 'ps_config_get' and 'ps_symbol_list'. There are no deviations in naming conventions, making the set predictable and easy to parse for agents.
With 45 tools, the count is excessive for a single server, making it feel heavy and potentially overwhelming. While the server covers a broad domain (PromptSpeak governance), the high number suggests poor scoping, as many tools could be consolidated or split into more focused servers.
The tool set provides comprehensive coverage for the PromptSpeak domain, including configuration, execution, delegation, security, state management, and symbol handling. It supports full CRUD operations for symbols and other resources, with no apparent gaps that would hinder agent workflows.
Pre-deploy governance for AI agents: posture scores, policies, budget cap checks, trust manifests.
Human-in-the-loop review and approval for AI agents. Audit trail, approval policies, native MCP.
Zero-secret MCP gateway for AI agents: risk-scored, audited calls with human-in-the-loop approval.
AI agent security, MCP 2026 schema & graph audits, <250ms guardrails, and compliance dossiers